The folding data is compiled from ICU's standard NFKC files plus Lucene's own tables, and when two files map the same character, the later file wins. Up to 8.x Lucene's tables came last, so they won. Since 9.0 they come first, so NFKC wins.
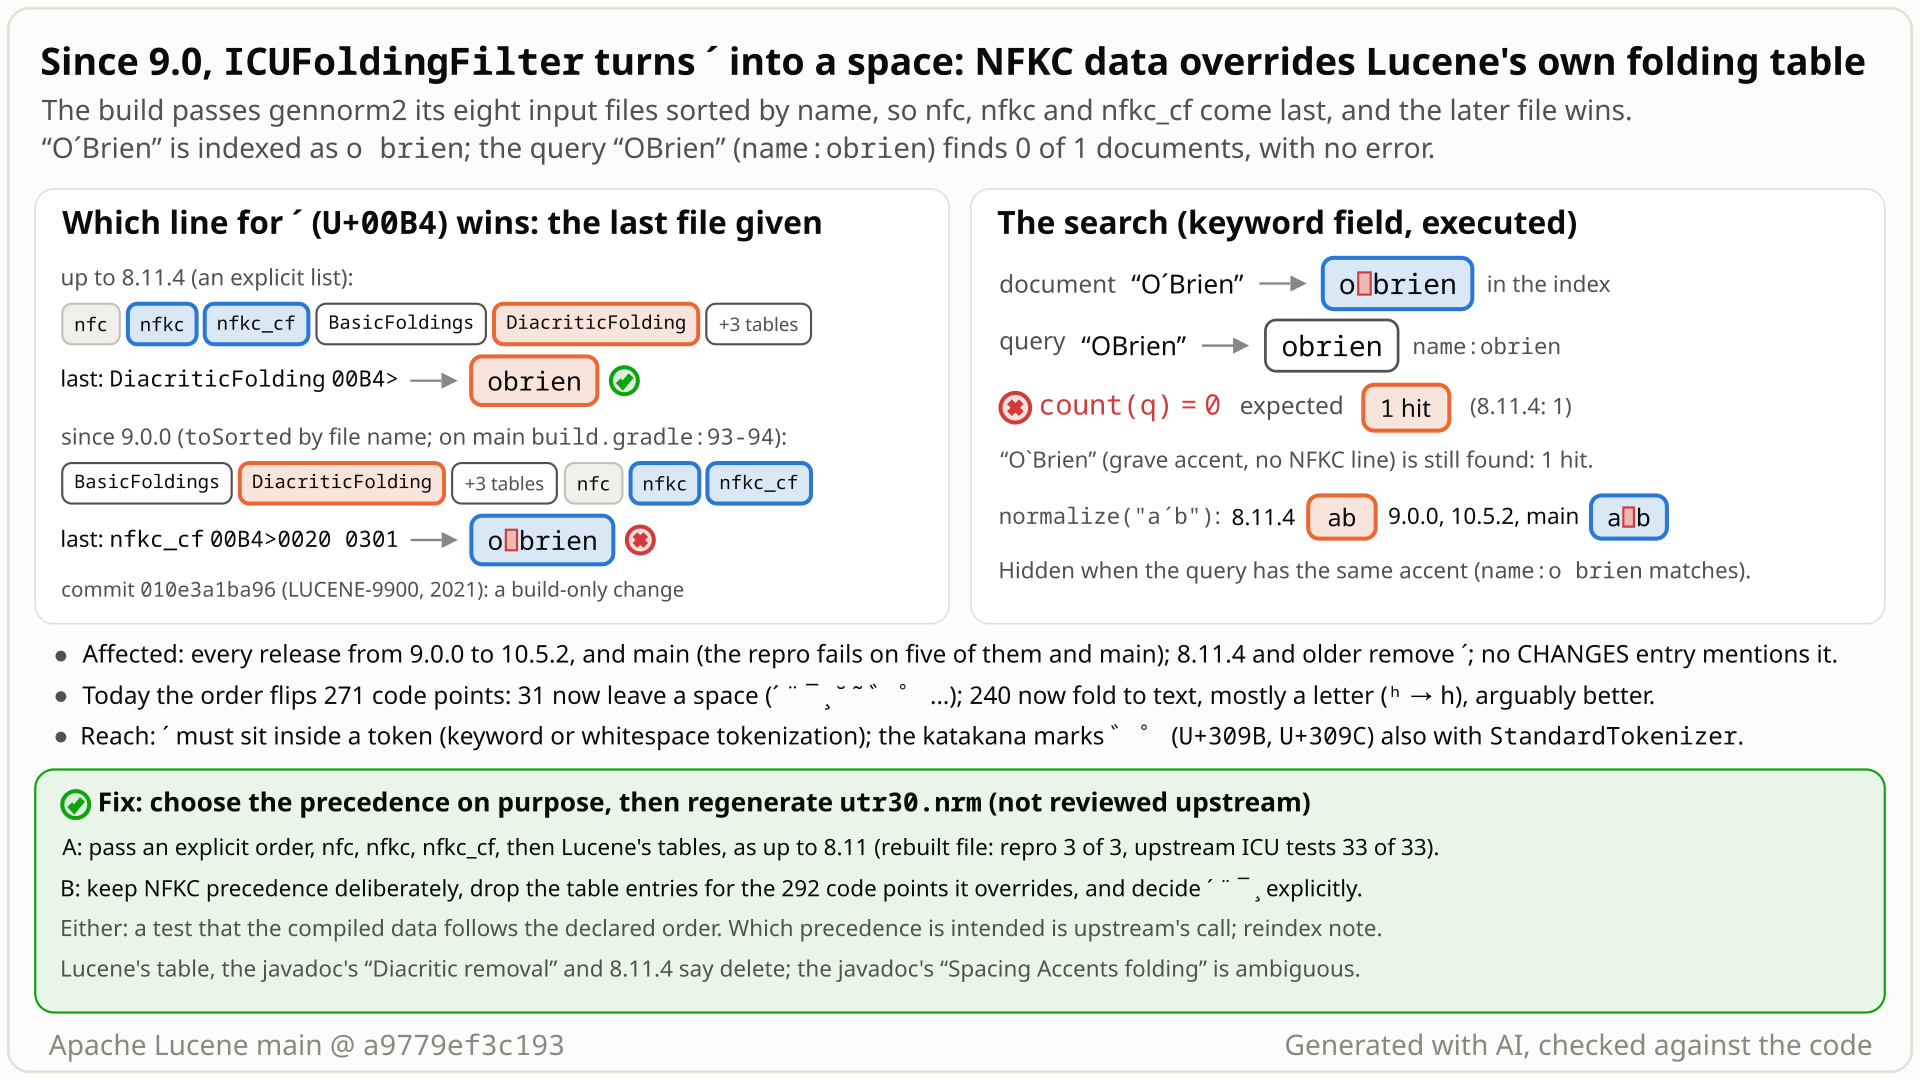
O´Brien. Select the still to open it at full size. Generated with AI, checked against the code.- You fold a keyword or whitespace-tokenized field with the default
ICUFoldingFilterand indexO´Brien, with an acute accent ´ (U+00B4) typed as an apostrophe. - You expect the term
obrien: Lucene's own table deletes ´ under "Remove diacritics", 8.11.4 givesobrien(older releases built the data in the same order), and the filter still deletes ` and ^, which the same rule lists. - You get
o brien, with a space inside the term, so it no longer matchesobrien. ¨ ¯ ¸ ˘ ˜ and 23 more spacing accents do the same; throughStandardTokenizer,カ゛becomesカ. - Why: ICU's gennorm2 compiles the folding data from ICU's 3 normalization files (nfc, nfkc, nfkc_cf) and Lucene's 5 tables, and a later file overrides an earlier one. Since 9.0.0 the build sorts the files by name, so Lucene's tables come first and NFKC's ´ -> space + accent wins.
- Net effect on main: Lucene's mappings for 292 code points are overridden, and 271 characters fold differently than under the pre-2021 order. About 240 of those are arguably better (modifier letters such as ʰ now fold to h instead of vanishing); the 31 that leave a space are not.
Users of the optional ICU module's ICUFoldingFilter, its factory or NORMALIZER with the default data, on 9.0.0 and later. The space appears when the accent stays inside a token: keyword or whitespace fields (O´Brien), or ゛ ゜ even with StandardTokenizer. Modifier letters such as ʰ changed too. Deterministic and silent; rare in practice.
Mechanism, terms and numbers682 words
ICUFoldingFilter folds with utr30.nrm, which the build compiles with ICU's gennorm2 from ICU's nfc.txt, nfkc.txt and nfkc_cf.txt and Lucene's five UTR#30 tables. When two files map the same character, the later file wins. Up to 8.11.4 the build passed the NFKC files first and Lucene's tables last; a 2021 build change (010e3a1ba96, LUCENE-9900, PR #61), meant to make regeneration incremental, sorts the files by name instead, which puts Lucene's tables first. Since 9.0.0 the NFKC mapping wins on all 292 code points both map; on main's data 271 of them fold differently than under the old order. Lucene's "Remove diacritics" rule deletes ´ ¨ ¯ ¸, but NFKC maps them to a space plus a combining mark, so with keyword or whitespace tokenization O´Brien is indexed as o brien, and through StandardTokenizer カ゛ becomes カ , while ` and ^ (no NFKC mapping) are still deleted. About 240 of the 271 changes (modifier letters such as ʰ -> h) are arguably improvements. Silent: no error, no release note, no test pins either behaviour. Restoring the documented order and keeping today's superscript and subscript folds changes 35 characters back and passes the module's tests.
utr30.nrm: the binary data behindICUFoldingFilter.NORMALIZER(ICUFoldingFilter.java:69-77). The build compiles it with ICU's gennorm2 from eight text files inlucene/analysis/icu/src/data/utr30/: ICU's standardnfc.txt,nfkc.txt,nfkc_cf.txt, and Lucene's UTR#30 tablesBasicFoldings.txt,DiacriticFolding.txt,DingbatFolding.txt,HanRadicalFolding.txt,NativeDigitFolding.txt.- Later file wins: ICU User Guide, "Mappings in one text file can override mappings in previous files of the same gennorm2 invocation." ICU's
nfkc.txt:14: "Use this file as the second gennorm2 input file after nfc.txt." - The conflict:
DiacriticFolding.txt:41maps ´ to nothing (00B4>, under "## Remove diacritics", rule[:Diacritic:] >);nfkc.txt:24maps it to space + combining acute (00B4>0020 0301), and the combining acute is then deleted, which leaves the space.
build.gradle:92-94sorts the inputs by file name ("gennorm generates file order-dependent output, so make it constant here.") and:122passes them in that order. Upper case sorts first: Lucene's five tables, thennfc,nfkc,nfkc_cf.- So for every character both sides map, NFKC's mapping wins: on main the stored mapping is NFKC's for all 288 conflicts whose two mappings differ (4 are identical); 271 of the 292 fold differently than Lucene's mapping would, 21 the same.
- From 2010 (LUCENE-1343) to the first gradle port (LUCENE-9767, February 2021) the build listed ICU's files first (
nfkc nfkc_cf, withnfcadded in front in 2012) and Lucene's tables last. Commit010e3a1ba96(LUCENE-9900, PR #61, 2021-04-02) replaced the list by the sort and committed the regeneratedutr30.nrm; it changed no source table. - The regeneration checksums store one hash per file and no order (the same commit created them), and no test asserts any of the changed characters, so nothing noticed.
| group | count | old order, today's data | sorted order (main) | real 8.11.4 file |
|---|---|---|---|---|
| spacing accents ´ ¨ ¯ ¸ ˘ ˙ ˚ ˛ ˜ ˝, Greek spacing accents, ゛ ゜, fullwidth macron | 29 | deleted | a space | deleted |
| U+2017 ‗, U+037A | 2 | deleted | a space (U+037A: space + ι) | deleted |
| U+FE4D..FE4F ﹍ ﹎ ﹏, U+0345 | 4 | deleted | _, ι | deleted |
| modifier letters ʰ ᵉ ᵐ ... | 236 | deleted (Mᵐᵉ -> m) | compatibility text, usually the base letter (Mᵐᵉ -> mme; U+1D2D -> ae, U+10787 -> dz) | 82 deleted, 36 as on main (U+1D9B..1DBE), 118 unchanged (newer than 8.x's Unicode data) |
and ^ are in the same rule but have no NFKC mapping, so they are still deleted: ab` -> ab, while a´b -> a b`.
The table compares two orders on today's data. The last column folds the same 271 code points with the real 8.11.4 utr30.nrm (ICU4J 62.1): main matches it on 36, the order-only fix on 117 (it restores the 8.x order, not the 8.x data), the recommended fix on 71.
Exposure and likelihood223 words
- Who is exposed.
ICUFoldingFilter,ICUFoldingFilterFactory(icuFolding) orICUFoldingFilter.NORMALIZERwith the default data, in the optionalanalysis-icumodule, on every release from 9.0.0 to 10.6.0 and main. Nothing to configure beyond choosing the filter; anything that wraps the filter gets the same terms. - Which text. A changed character must stay inside a token: keyword or whitespace tokenization (keyword-normalized fields; the factory's own javadoc example uses
WhitespaceTokenizerFactory,ICUFoldingFilterFactory.java:29-35) of an acute typed as an apostrophe (O´Brien,don´t) or another spacing accent between letters; the spacing katakana marks ゛ ゜ even withStandardTokenizerorICUTokenizer(カ゛->カ); modifier letters (ʰ, ᵉ) with any tokenizer that keeps them in the token (StandardTokenizerandICUTokenizerdo). The default tokenizers split at the Latin spacing accents (O´Brien->o,brienon main and 8.11.4). - What happens. The term differs from the accent-free spelling and from 8.x: a keyword field holding
o briendoes not matchobrien, and an index folded with 8.x disagrees with 9.x query folding on these characters. The same analyzer at index and query time hides most of it. - Scale. Deterministic, any index size, no error; each changed code point maps to at most two UTF-16 chars.
- How likely. Rare: no report was found in the searched sources since 9.0.0 (2021).
ICUFoldingFilter turns the spacing ACUTE ACCENT U+00B4 inside a term into a space, although Lucene's own UTR#30 table DiacriticFolding.txt removes it (since 9.0 the build lets the NFKC data override the table).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu;

import java.io.StringReader;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.KeywordTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestICUFoldingSpacingAcute extends BaseTokenStreamTestCase {

  public void testSpacingAcuteIsRemoved() throws Exception {
    Tokenizer tokenizer = new KeywordTokenizer();
    tokenizer.setReader(new StringReader("a´b"));
    // DiacriticFolding.txt maps U+00B4 ACUTE ACCENT to nothing: expected "ab", actual "a b"
    assertTokenStreamContents(new ICUFoldingFilter(tokenizer), new String[] {"ab"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-857/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/icu/build/libs/lucene-analysis-icu-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.icu.TestICUFoldingSpacingAcute
# the module(s) analysis-icu also need their third-party runtime jars
- Expected vs actual
- Expected:
a´b->ab; actual:a b(term 0 expected:<a[]b> but was:<a[ ]b>), with-eaand-da.
More files, environment, full output39 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<a[]b> but was:<a[ ]b>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.icu.TestICUFoldingSpacingAcute.testSpacingAcuteIsRemoved(TestICUFoldingSpacingAcute.java:30)- Lucene's own table deletes ´ ¨ ¯ ¸ ("Remove diacritics") and still deletes ` and ^; NFKC now overrides it on 292 code points.
- Releases 3.1.0 to 8.11.4 passed ICU's files first and Lucene's tables last.
- The 2021 change was a build cleanup; the only reply on the order came after the merge ("just my guess"); no release note mentions it.
The full argument284 words
Intent is not proven: the points below make an unintended precedence inversion likely, and the committers decide which folding semantics they want.
- Lucene's table says delete.
DiacriticFolding.txt:35-43: "## Remove diacritics", "# Rule: [:Diacritic:] >",005E>,0060>,00A8>,00AF>,00B4>,00B7..00B8>,02B0..034E>; the javadoc lists "Diacritic removal" (ICUFoldingFilter.java:33). rmuir on LUCENE-1343 (2010): CARET "folds to CIRCUMFLEX ACCENT, which should be deleted as its [:Diacritic:]". - The tables were designed to sit on top of NFKC. Headings such as "## Spacing Accents folding (done by kd)" (
BasicFoldings.txt:86) and a space rule that leaves out whatever NFKC_CF changes (:83); on LUCENE-3747 rmuir called the "additions to kd" sections "the mappings in utr30 minus what nfkc does". - The order was explicit for 11 years. The ant build (LUCENE-1343, 2010;
nfc.txtadded in front in 2012) and the first gradle port (LUCENE-9767, 2021-02-14) usednfc nfkc nfkc_cfthen Lucene's tables. - The change was treated as a pure build change.
010e3a1ba96touched only build files, two new checksum files and the binary (58,720 -> 59,200 bytes), no source table. In PR #61 dweiss asked: "gennorm seems to be order-sensitive - I changed the order to sorted file names ... Is this order somehow important? I can revert to what it was before but this way it's simpler." rmuir replied after the merge: "it is my understanding order doesnt matter ... this may cause a data file change even though semanticw are unchanged? just my guess", about chained mappings, not two files mapping one character. - Silent. No CHANGES or MIGRATE entry for 9.0.0; later ICU upgrades (#447, #13239, #14386, #15417) regenerated under the sorted order without mentioning it.
The devil's-advocate check306 words
The strongest case for "intended": the javadoc also lists "Spacing Accents folding", "Subscript folding" and "Superscript folding" and says text "is normalized to NFKC" (ICUFoldingFilter.java:47-49, :57); UTR#30 defines Spacing Accents folding as [KD] (space + mark) for 00AF, 00B4, 00B8, 02D8..02DD, ..., 309B..309C and Superscript folding as [KD] plus modifier letters, so today's output is what those foldings plus accent removal give, and 8.x's Mᵐᵉ -> m contradicted "Superscript folding". The order was discussed in review, and the file was regenerated twice since under the sorted order. Two more points weigh for keeping today's output: the text tables are not the public API and the javadoc specifies no precedence between files (at runtime the shipped utr30.nrm is the contract), and five years of stable 9.x-10.x output (33 release tags) plus the reindex cost make keeping it a legitimate compatibility choice.
What answers it: the PR merged with no answer on the order (its three reviews are comments with empty bodies); the only reply came four hours after the merge and rested on a guess that semantics were unchanged ("just my guess"), while the ICU page linked in that comment says the later file overrides; no comparison of the output is recorded in the PR or the later regenerations; nothing announced a change; the sorted order leaves Lucene's tables unable to override any mapping that NFKC also defines, which defeats their ability to tailor those; and one rule now gives two results (` ^ deleted, ´ ¨ ¯ ¸ -> space). The adjudication, the independent reproducer and the devil's advocate rejected the intended reading; a cross-model reviewer called the contract "genuinely ambiguous" but said a maintainer "cannot convincingly call the 2021 precedence change documented". It survives as a question of fix direction, which the recommended fix answers by keeping the superscript and subscript folds.
Recommended A2. Restore the order and keep today's superscript and subscript folds
Restore the documented gennorm2 order in build.gradle (NFKC files first, Lucene's tables last), and take superscript and subscript letters out of the "Remove diacritics" rule so they keep today's folds. Regenerated with the build's own task: 35 characters change, all back to 8.x; all repros and the 165 ICU module tests pass.
// lucene/analysis/icu/build.gradle (condensed): an explicit order instead of the name sort
def inputOrder = ["nfc.txt", "nfkc.txt", "nfkc_cf.txt", "BasicFoldings.txt",
    "DiacriticFolding.txt", "DingbatFolding.txt", "HanRadicalFolding.txt", "NativeDigitFolding.txt"]
def inputFiles = inputOrder.collect { name -> new File(utr30DataDir, name) }
inputs.property "gennorm2InputOrder", inputOrder.join(" ")

# lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt, then regenerateUtr30DataFiles
 ## Remove diacritics
-# Rule: [:Diacritic:] >
+# Rule: [[:Diacritic:]-[:Decomposition_Type=Super:]-[:Decomposition_Type=Sub:]] >
All options and trade-offs4 options · 1,194 words
Both order fixes were made with the build's own regenerateUtr30DataFiles task (it downloads and compiles the matching ICU4C) in a scratch worktree of a9779ef3c193 and run through gradle; options B and C were not run. Every option changes indexed terms for some characters, so it needs a CHANGES/MIGRATE note suggesting a reindex of fields that use ICUFoldingFilter.
A2. Restore the order and keep today's superscript and subscript folds (validated by the checks) (recommended)
Option A's build.gradle change (below), plus one rule line in DiacriticFolding.txt. With Lucene's tables last again, a character they do not map keeps its NFKC mapping, so taking superscript and subscript letters out of the deletion rule leaves them to NFKC, which folds them to their compatibility text (usually the base letter), as UTR#30's "Superscript folding" and "Subscript folding" (both in the javadoc, ICUFoldingFilter.java:48-49) describe. The regeneration rewrote that rule's generated range lines (+8/-12; +9/-13 with the rule line), the checksum file and utr30.nrm (61,776 -> 61,408 bytes).
New output against today: exactly 35 code points change, all back to 8.x (deleted): the 31 that leave a space (´ ¨ ¯ ¸ ˘ ˙ ˚ ˛ ˜ ˝, the Greek spacing accents, ゛ ゜, the fullwidth macron, U+2017, U+037A), U+FE4D..FE4F (_ today) and U+0345 (ι today). The 236 modifier letters keep today's folds (Mᵐᵉ -> mme). Against the real 8.11.4 file it matches on 71 of the 271 (these 35, and U+1D9B..1DBE, which 8.11.4 already folds like main); option A on 117.
// lucene/analysis/icu/build.gradle (condensed): an explicit order instead of the name sort
def inputOrder = ["nfc.txt", "nfkc.txt", "nfkc_cf.txt", "BasicFoldings.txt",
    "DiacriticFolding.txt", "DingbatFolding.txt", "HanRadicalFolding.txt", "NativeDigitFolding.txt"]
def inputFiles = inputOrder.collect { name -> new File(utr30DataDir, name) }
inputs.property "gennorm2InputOrder", inputOrder.join(" ")

# lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt, then regenerateUtr30DataFiles
 ## Remove diacritics
-# Rule: [:Diacritic:] >
+# Rule: [[:Diacritic:]-[:Decomposition_Type=Super:]-[:Decomposition_Type=Sub:]] >
Trade-offs
- It edits a generated rule, so it fixes the regression and also settles the superscript direction; reviewers may want the two in separate commits.
- It is a policy, not only an order repair: it exempts every character whose decomposition type is Super or Sub (some fold to two letters or to punctuation, such as U+107B7 ->
||), and later Unicode versions can add to that set. - U+FE4D..FE4F go back to deleted: Lucene's Underline line
FE4D..FE4F>005E(BasicFoldings.txt:95, copied from UTR#30) maps them to ^, which is then deleted; changing it to005Fwould keep_(not run). U+037A stays deleted, as in 8.x. - Indexed terms change for the 35 characters; no CHANGES entry is drafted.
What the checks validated
regenerateUtr30DataFilesaccepted the rule (ICU UnicodeSet syntax) and wrote the new lines, checksums and file; the other data files are unchanged.- Gradle: all of
:lucene:analysis:icu:test(18 classes, 165 tests including the new test and the finder's, 10 skipped, 0 failures),regenerateUtr30DataFilesChecksumCheck, and:lucene:analysis:icu:check -x test(google-java-format check, ecjLint, forbiddenApis) pass. - With the new
utr30.nrmfirst on the classpath of the stock main jars: the new test 4/4 with assertions on and off, the finder's 3/3, the independent reproducer's 9/9. - Exhaustive diffs over all code points: 35 against the shipped file, 236 (the modifier letters) against option A.
build.gradle +20/-3: an explicit list nfc.txt, nfkc.txt, nfkc_cf.txt, BasicFoldings.txt, DiacriticFolding.txt, DingbatFolding.txt, HanRadicalFolding.txt, NativeDigitFolding.txt; the order as a task input property, so it enters the regeneration checksums and a future change shows up as a checksum diff; and a doFirst check that fails a regeneration run if a *.txt file in the data directory is not in the list (it runs only when the task executes: a file missing from the list is not a task input, so adding one does not by itself trigger the task). Regenerated: checksum file and utr30.nrm (61,776 -> 60,608 bytes).
New output against today: exactly the 271 code points change, all to their result under the pre-2021 order (deleted); nothing else changes. That is the 8.x order, not the 8.x data: against the real 8.11.4 file it matches on 117 of the 271 and deletes 154 that 8.11.4 does not delete (36 that 8.11.4 folds like main, 118 newer than its Unicode data).
  // gennorm2 output depends on the order of its input files: when two files map the same code
  // point, the later file wins. The Unicode data comes first, in the order its headers ask for
  // (nfc.txt, nfkc.txt, nfkc_cf.txt), then Lucene's UTR#30 tables, so that they can override it.
  def inputOrder = [
    "nfc.txt",
    "nfkc.txt",
    "nfkc_cf.txt",
    "BasicFoldings.txt",
    "DiacriticFolding.txt",
    "DingbatFolding.txt",
    "HanRadicalFolding.txt",
    "NativeDigitFolding.txt"
  ]
  def inputFiles = inputOrder.collect { name -> new File(utr30DataDir, name) }
  ...
  inputs.property "gennorm2InputOrder", inputOrder.join(" ")
  ...
  doFirst {
    def unlisted = fileTree(dir: utr30DataDir, include: "*.txt").files.collect { it.name } - inputOrder
    if (!unlisted.isEmpty()) {
      throw new GradleException("Add these utr30 data files to the gennorm2 input order: " + unlisted)
    }
Trade-offs
Smallest change and the 8.x order, but it also deletes what today's order arguably improved: 236 modifier letters (2ᵉ -> 2, Mᵐᵉ -> m again; 154 of them were not deleted by 8.11.4 either), U+FE4D..FE4F and U+0345. Indexes built with 9.x-10.x see 271 code points change.
What the checks validated
- The regenerated
utr30.nrmis byte-identical to the finder's independent rebuild in the pre-2021 order with an older ICU4C (77.1); the data files are unchanged. - Gradle: the new test and the finder's, 7 run, 5 failed on stock and 0 failed with the fix; all of
:lucene:analysis:icu:test(165 tests, 10 skipped, 0 failures) and the checksum check pass. - With the new
utr30.nrmfirst on the classpath of the stock main jars: new test 4/4 (assertions on and off), finder's 3/3, independent reproducer's 9/9; the release probe prints the 8.11.4 outputs for its probe characters.
Keep NFKC last, sorted or explicit, remove Lucene's mappings for the 292 code points that NFKC overrides, and decide the spacing-accent, U+0345 and U+037A cases explicitly.
Trade-offs
No indexed term changes, which respects five years of stable 9.x-10.x output; but the five current tables (all sorted before nfkc_cf.txt) cannot override any NFKC mapping, so the 31 space-in-term cases would need a new override file that sorts after nfkc_cf.txt, or an explicit order that ends with a Lucene file (ICU lets a later file override an earlier one); and "Remove diacritics" stops meaning what it says for those characters.
Compute the winning mapping of every code point over all eight files in the declared order (the later file wins, also among Lucene's own tables) and assert that ICUFoldingFilter.NORMALIZER.getRawDecomposition(cp) equals it, as the hunt's translation validation did for the sorted order (0 mismatches) when it found the 292. Comparing each table line on its own does not work: BasicFoldings.txt:109-112 are overridden by DiacriticFolding.txt's generated deletion in either order, and 37 DingbatFolding digits by NativeDigitFolding.
Trade-offs
With the order of A or A2 declared, it should fail on today's file and pass on the fixed one (not run); under any option it catches the next silent order change. It needs the table files, or a list derived from them, at test time.
Search servers that expose this filter inherit the same 9.0 term change, so terms their users indexed before and after moving to Lucene 9 disagree on these characters.
An exhaustive check of the compiled folding data against Lucene's source tables: a model of the compiler's later-file-wins rule matched the shipped file on every code point (algorithmic Hangul aside) and showed NFKC overriding Lucene's mappings for 292 code points. On main's data the pre-2021 order changes 271 characters; the 2021 commit alone changed 118.
The method in full147 words
- Method (semi-formal): bounded-exhaustive translation validation of
utr30.nrmagainst its source tables, in the hunt's unit on the UTR#30 data. An independent model of gennorm2's precedence (inputs in the build's sorted order, a later file overrides an earlier one) matched gennorm2's own combined output and the shippedutr30.nrmon all 1,114,112 code points, 0 mismatches (the raw comparison with the shipped file skips the algorithmic Hangul syllables), and showed that 292 code points mapped by Lucene's tables are overridden by the nfc/nfkc/nfkc_cf data. - Attribution. The finder rebuilt
utr30.nrmwith gennorm2 in the sorted order (byte-identical to the shipped file) and in the pre-2021 order, and compared the two over all code points: 271 fold differently, all deleted under the old order. The same comparison of the files on either side of010e3a1ba96gives 118. - Then a public-API JUnit on the stock jars, and independent checkers (see "Independent checks").
No prior report found (searched 2026-10-28: three tool runs of 51 queries each over GitHub, commits, the Lucene lists, the JIRA archive, downstream trackers and the web; 48 manual searches; all 411 open PRs). The introducing PR's review asked whether the order matters; no output comparison is recorded.
Searches4 searches
Closest items: the introducing PR and its issue, the gradle port that spelled out the old order, a same-file duplicate fixed by hand in 2021, later ICU regenerations under the sorted order, and older discussions from before the change. GitHub search does not index diffs or binaries, so merged history and open PRs were read directly; private reports are invisible.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (three runs) | 2026-10-28 | 153 queries: GitHub issues/PRs, commits, downstream trackers, dev@/java-user@/issues@/commits@, the JIRA archive, the web (ICUFoldingFilter, utr30.nrm, gennorm2 order, DiacriticFolding, spacing accent, superscript, modifier letter, "folds to a space", LUCENE-9900/9767/10238) | no report; no high-overlap hit |
| Manual searches | 2026-10-28 | 22 GitHub (apache/lucene and three downstream search servers), 7 JQL over LUCENE and SOLR, 11 mailing-list, 8 web; 16 API and history reads (PR #61 review comments, later regeneration PRs) | no report |
| Open PRs and recent activity | 2026-10-28 | changed-file lists of all 411 open apache/lucene PRs; PRs and issues updated in the previous 48 hours | no PR changes the gennorm2 inputs or their order; the only ones touching these files are #16911 (deletes branch_10x wholesale) and #14389 (renames a CaseFolding output path in the old gradle/generation/icu.gradle) |
| Closest items (read) | 2026-10-28 | full threads | #61 / #10939 (LUCENE-9900, the introducing PR and issue), #10806 (LUCENE-9767, old order), #11274 / #447 (LUCENE-10238), #13239, #14386, #15417 (later regenerations), #4820 (LUCENE-3747), #2420 (LUCENE-1343), a 2013 solr-user thread (` and ¨ removed on 4.x), elastic/elasticsearch#23764 (2017, before the change) |
Introduced by 010e3a1ba96 (LUCENE-9900, PR #61, 2021-04-02), a build change that sorted the gennorm2 inputs; first released in 9.0.0. A behaviour change: every release from 3.1.0 to 8.11.4 passed Lucene's tables last. Affects 9.0.0 to 10.6.0 and main.
Versions tested7 rows
Introduced by 010e3a1ba96 "LUCENE-9900: Regenerate/ run ICU only if inputs changed (#61)" (dweiss, 2021-04-02; PR opened 08:26:43Z and merged 09:46:43Z the same day). It replaced the explicit list in gradle/generation/icu.gradle with the sorted file list and committed the regenerated utr30.nrm (58,720 -> 59,200 bytes); no source table changed. The code moved to lucene/analysis/icu/build.gradle in 2025 (#14764, #15377) unchanged. Every later ICU upgrade (ICU 70.1, 74.2, 77.1, 78.x) kept the sort; upstream main and branch_10_6 still have it.
Commit-level check: the 9.0.0 jars with the parent's utr30.nrm pass the finder's test 3 of 3, with the commit's they fail 2 of 3 (both files from ICU 68.2, assertions on and off).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 3 of 4 fail (assertions on and off, harness and gradle); finder's 2 of 3; the independent reproduction's 7 of 9 |
branch_10_6 4ae946e5a9b (10.6.0 RC1 revision) | affected | finder's test 2 of 3 fail, assertions on and off |
| 10.5.2, 10.0.0, 9.12.3, 9.1.0 | affected | fail (new test on 10.5.2: 3 of 4; finder's on all four) |
| 9.0.0 | first release | ships the commit's utr30.nrm byte for byte; new test 3 of 4 fail |
010e3a1ba96 vs its parent (their utr30.nrm on the 9.0.0 jars) | commit-level | parent 3 of 3 pass, commit 2 of 3 fail; 118 code points differ |
| 8.11.4, 8.8.1 | not affected | pass (new test 4 of 4 on 8.11.4); the 8.x line kept the old order |
| fix A2 / fix A on main | not affected | all repros pass; 165 ICU module tests, 0 failures |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication confirmed it after re-running it; a history step pinned the commit, and a credibility audit kept it. The cross-model reviews only read code: one "uncertain", one a procedural "not real", while separate runs reproduce it.
Checks and verdicts235 words
No cross-model review could execute code on this host. This doc's new test and both fix validations ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own public-API JUnit (9 tests): 7 fail on main (assertions on and off), 10.5.2, 9.12.3 and 9.0.0, 9 of 9 pass on 8.11.4; its own comparison of the two commit files finds the 118, all flipped to NFKC. |
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6) ran nothing and argued intent from the javadoc's "Spacing Accents folding"; separate runs fail on main, and a separate check of the two commit files gives ab before and a b after. |
| Cross-model intended-behaviour review | uncertain (low), reading only | "The contract is genuinely ambiguous ... cannot convincingly call the 2021 precedence change documented." |
| Intended-behaviour devil's advocate | real (high that the inversion was unintended) | Built the strongest intended case and rejected it; found the katakana case through the default tokenizers and the PR #61 exchange. |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's JUnit with a new seed: 7 of 9 fail, assertions on and off. |
| History step | regression since 9.0.0 | Commit-level A/B on the 9.0.0 jars and runs on nine versions. |
| Credibility audit | keep | Re-ran the finder's JUnit with a new seed (2 of 3 fail) and re-read the mechanism. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 495 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,444 words
- Registry title
- Since 9.0 the utr30.nrm build passes gennorm2 its inputs sorted by file name, so the standard NFKC data overrides Lucene's own UTR#30 folding tables and ICUFoldingFilter turns spacing accents such as ´ ¨ ¯ ¸ into a space inside the term instead of removing them, while ` and ^ are still removed
- Area
- analysis / icu (ICUFoldingFilter UTR#30 folding data: the gennorm2 input order of the utr30.nrm regeneration step in lucene/analysis/icu/build.gradle, and the shipped utr30.nrm)
- Priority
- Low, rank 497: This silent 9.0 folding regression in the opt-in ICUFoldingFilter only shows when a spacing accent sits inside a token, and using the same analyzer at index and query time mostly hides it.
- Impact class
- silent wrong results
- Impact note
- Applications that use the optional analysis-icu ICUFoldingFilter, ICUFoldingFilterFactory or ICUFoldingFilter.NORMALIZER with its default data (no setting needed) get, on 9.0.0 and later, a different folded term than Lucene's own tables specify and than 8.11.x produced for 271 code points: a spacing accent that the tokenizer keeps inside a token (an acute used as an apostrophe in 'O´Brien' with keyword or whitespace tokenization, or the spacing katakana marks ゛ ゜ with StandardTokenizer or ICUTokenizer) becomes a space inside the term ('o brien', 'カ '), so the term no longer matches its accent-free spelling or terms folded by 8.x; nothing throws, no scale is needed, about 240 of the 271 changes (modifier letters such as ʰ -> h) are arguably improvements, and any fix changes indexed terms and needs a reindex note.
- Summary
- You normalize a keyword field with ICUFoldingFilter and index 'O´Brien' (an acute accent used as an apostrophe); you expect the term 'obrien', because Lucene's own folding table DiacriticFolding.txt deletes U+00B4 along with the other spacing diacritics, as every release up to 8.11.x did and as the filter still does for ` and ^. Since 9.0.0 the term is 'o brien': a 2021 build change (LUCENE-9900) started passing the data files to the gennorm2 compiler sorted by file name, which puts the standard NFKC files last, and in gennorm2 a later file overrides an earlier one, so ´ ¨ ¯ ¸ ˘ ˜ and other spacing accents now become a space and 236 modifier letters fold to their base letter instead of being removed. The change was meant only to make regeneration incremental and its review assumed the order did not matter; 292 entries of Lucene's tables are now dead, and 271 code points fold differently.
- Introduced
- 010e3a1ba960ea0dcd7e5092073d2a55a21b0ac9 ('LUCENE-9900: Regenerate/ run ICU only if inputs changed (#61)', PR apache/lucene#61 by GitHub dweiss, JIRA LUCENE-9900 = #10939): a build-only change that replaced the explicit gennorm2 input list 'nfc.txt, nfkc.txt, nfkc_cf.txt, BasicFoldings.txt, DiacriticFolding.txt, DingbatFolding.txt, HanRadicalFolding.txt, NativeDigitFolding.txt' in gradle/generation/icu.gradle by the *.txt files sorted by name (upper-case names first, so Lucene's five tables now precede nfc, nfkc and nfkc_cf) and committed the regenerated utr30.nrm (58,720 -> 59,200 bytes); no data file changed [exec: commit-level A/B on the 9.0.0 jars, the parent's utr30.nrm blob 92a6919e37f and the commit's blob 6409b872edf (both ICU 68.2) prepended on the classpath: parent passes 3/3, commit fails 2 of 3, with -ea and -da] [read: git log -S finds the sort expression only in this commit and in the 2025 move 912e9066398 (#15377); on main it is lucene/analysis/icu/build.gradle:92-94, passed to gennorm2 at :115-122]. A regression: Lucene's tables were the last inputs from 2010 (LUCENE-1343 ant build, nfc.txt prepended by LUCENE-3747 in 2012) through the first gradle port (LUCENE-9767, 2021-02-14) and are the first inputs since (2021-04-02 (author date = commit date 2021-04-02T09:46:43Z; PR #61 opened 08:26:43Z and merged 09:46:43Z the same day))
- First affected version
- 9.0.0 [exec] (it ships the introducing commit's utr30.nrm blob 6409b872edf byte for byte); last unaffected release 8.11.4 [exec] (the 8.x line was built by the ant build with the old order and never got the commit); 8.8.1, the last release tagged before the commit date, is also unaffected [exec]
- Affected versions
- every release from 9.0.0 to 10.5.2 (git tag --contains 010e3a1ba96; their jars carry one of four utr30.nrm blobs, each regenerated at or after the commit with ICU 68.2, 70.1, 74.2 or 77.1, all four executed), the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) and main a9779ef3c193 [exec: the finder's JUnit fails 2 of 3 on 9.0.0 (-ea, -da; with the pre-9.1 test-framework imports), 9.1.0, 9.12.3 (-ea, -da), 10.0.0, 10.5.2 (-ea, -da), the branch_10_6 head (-ea, -da; analysis-icu compiled from the branch sources) and main (-ea, -da); the independent reproduction's JUnit fails 7 of 9 on main (-ea, -da), 10.5.2, 9.12.3 and 9.0.0] [read: upstream main 20ced71c1e6 has the same build.gradle sort and the same utr30.nrm blob as a9779ef3c193, and the branch_10_6 head 2763db11b0a the 10.5.2 blob]. Not affected: 8.11.4 and 8.8.1 [exec: pass 3/3 with -ea and -da; the independent reproduction's JUnit passes 9/9 on 8.11.4], every 8.x jar (old-order blobs 4ded6c97762 for 8.0.0-8.2.0 and 4c31f905077 for 8.3.0-8.11.4) [read], and the releases from 3.1.0 [read: the ant build used the explicit order with Lucene's tables last]. With the Unicode 13 data of 2021 the inversion changed 118 code points; with main's data the two orders differ on 271
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-28, read-only; the prior-report record plus the finder's scripted prior-report search, verdict new): no issue, PR, JIRA entry, mailing-list thread, downstream report or web page says that ICUFoldingFilter's output changed in 9.0, that spacing accents fold to a space inside a term, that modifier letters fold to letters instead of being removed, or that the gennorm2 input order inverts the precedence of Lucene's UTR#30 tables over nfc/nfkc/nfkc_cf. Not fixed upstream: build.gradle:92-94 still sorts on upstream main 20ced71c1e6 and on branch_10_6; no open PR touches the utr30 data or its build (411 open PRs' file lists scanned; #16911, the branch_10x decommission, touches the files only to retire that branch), and no apache/lucene PR or issue created or updated since 2026-10-26 concerns ICU. Related, not reports: #61 (the introducing PR; in its review GitHub dweiss asked whether the order matters and offered to revert, GitHub rmuir replied after the merge 'it is my understanding order doesnt matter ... this may cause a data file change even though semantics are unchanged? just my guess'; nobody compared folding output), #10939 (LUCENE-9900), #10806 (LUCENE-9767, the documented old order), #11274 / #447 (LUCENE-10238, a same-file override fixed by hand), #13239, #14386 and #15417 (later regenerations under the sorted order), #10960 (LUCENE-9921), #82 (LUCENE-9928), #2420 (LUCENE-1343), #4820 (LUCENE-3747), elastic/elasticsearch#23764 (2017, before the change: a standalone U+02C6 folding to an empty token was called expected behaviour)
- Lucene commit tested
- main
a9779ef3c193(repro harness, and gradle in a scratch worktree for both fixes); the release jars 8.8.1, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2; the branch_10_6 head4ae946e5a9b; theutr30.nrmfiles on either side of010e3a1ba96, each on the 9.0.0 jars.
- Finding record
lucene/analysis/icu/build.gradle:92-94 (at a9779ef3c193) ('// gennorm generates file order-dependent output, so make it constant here.'; fileTree(dir: utr30DataDir, include: "*.txt").asList().toSorted(Comparator.comparing { File f -> f.name })), :115-122 (gennorm2 -v -s utr30DataDir -o ... *(inputFiles.collect { it.name }))lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt:35-43 (at a9779ef3c193) ('## Remove diacritics', '# Rule: [:Diacritic:] >', 005E> 0060> 00A8> 00AF> 00B4> 00B7..00B8> 02B0..034E>)lucene/analysis/icu/src/data/utr30/nfkc.txt:14 (at a9779ef3c193) ('Use this file as the second gennorm2 input file after nfc.txt.'), :19 (00A8>0020 0308), :24 (00B4>0020 0301); nfkc_cf.txt:13 ('Use this file as the third gennorm2 input file after nfc.txt and nfkc.txt.'), :44, :50lucene/analysis/icu/src/data/utr30/BasicFoldings.txt:94-95 (at a9779ef3c193) (2017>005E, FE4D..FE4F>005E: dead since the sort, NFKC wins)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilter.java:23 (at a9779ef3c193) ('applying foldings from UTR#30'), :29 'Accent removal', :33 'Diacritic removal (including stroke, hook, descender)', :47 'Spacing Accents folding', :49 'Superscript folding', :66 (NORMALIZER from utr30.nrm)SECURITY.md lines 28, 30, 36, 42, 46, 50 (threat model and in-scope definition, as cited by the security record)
- The finding in 30 seconds
lucene/analysis/icu/build.gradle:92-94, :114-124 @ a9779ef3c193lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt:35-43, nfkc.txt:14, :24, nfkc_cf.txt:13, :50 @ a9779ef3c193lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilter.java:69-77 @ a9779ef3c193build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/regenerate/RegenerateTasksSupportPlugin.java:379-401 @ a9779ef3c193
- Who is affected
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilterFactory.java:29-35 @ a9779ef3c193
- Why it looks unintended
lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt:35-43, BasicFoldings.txt:83, :86 @ a9779ef3c193lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilter.java:33, :47-49, :57 @ a9779ef3c193
- Suggested fix
lucene/analysis/icu/src/data/utr30/BasicFoldings.txt:92-95 @ a9779ef3c193
- TestICUFoldingSpacingAcute.java (JUnit test):
repro/LFV-857/src/org/apache/lucene/analysis/icu/TestICUFoldingSpacingAcute.java(32 lines)
assets/LFV-857/bug.png(495 KB)