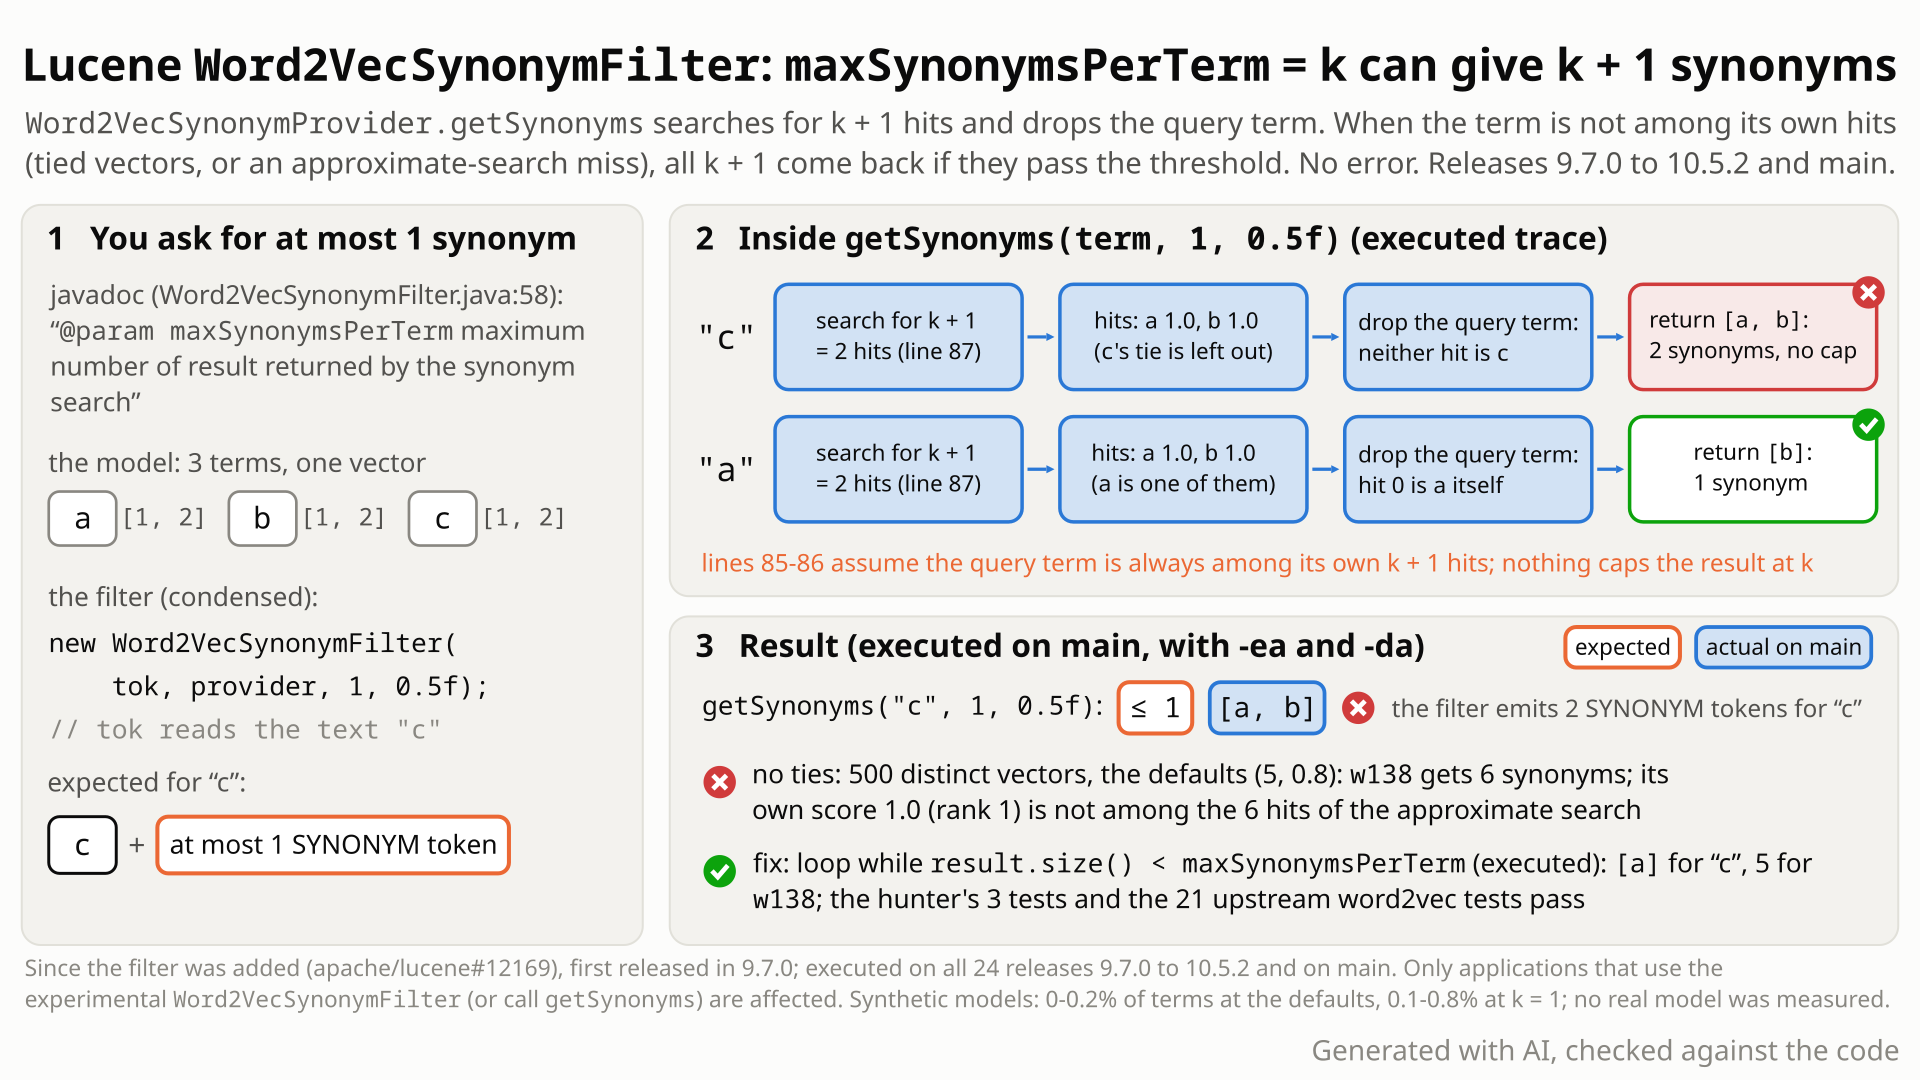
Word2VecSynonymFilter adds, for each word, the nearest words of a word2vec model as synonyms, found by an HNSW search over the model's vectors. maxSynonymsPerTerm caps how many. The provider asks for one neighbour more, as room for the query word itself, and gives that room back only when the query word is among the hits.
- Build a
Word2VecSynonymFilterwithmaxSynonymsPerTerm = 1over a model in which the wordsa,bandchave the same vector. The javadoc calls the value the "maximum number of result returned by the synonym search", so you expect at most 1 synonym per word. aandbget 1 synonym each, butcgets 2:[a, b]. The provider asks the HNSW graph for k + 1 = 2 neighbours, expectingcitself to be one of them and dropping it. Ties go to the lower ordinals here, so the 2 hits areaandb; both pass the threshold, nothing is dropped and both are kept.- No ties are needed. In a 500-word model of distinct vectors with the factory defaults (5 synonyms, threshold 0.8), the search for 6 hits stops before it reaches
w138itself, althoughw138is its own nearest neighbour (cosine 1.000; the best other word 0.923). All 6 hits pass the threshold, sow138gets 6 synonyms. - No error: the sixth synonym is the next-best hit (score 0.937 against a threshold of 0.8), so it silently joins the indexed terms or the query expansion on every occurrence of the word. A one-line cap on the result fixes it.
Applications that opt in to the experimental Word2VecSynonymFilter, with any model and the factory defaults. A small fixed set of words gets one extra synonym on every occurrence: about 0 to 0.2% of words at the defaults in synthetic clustered models, up to about 0.8% at maxSynonymsPerTerm = 1. Nothing fails.
Mechanism, terms and numbers733 words
Word2VecSynonymFilter (analysis-common, @lucene.experimental) expands each token with the nearest words of a word2vec model, found by Word2VecSynonymProvider.getSynonyms through an HNSW search over the model. The filter documents maxSynonymsPerTerm as the "maximum number of result returned by the synonym search". The provider searches for maxSynonymsPerTerm + 1 neighbours, because the query word is "always the nearest neighbour of itself", then drops the query word and every hit below minAcceptedSimilarity, and never caps the result. When the query word is not among the k + 1 hits and all of them pass the threshold, all of them are returned and emitted: three words with the same vector at k = 1 (c gets [a, b]), or, with distinct vectors and the factory defaults, a word that the search for k + 1 hits stops before reaching, although it is its own strict nearest neighbour (w138 of a 500-word clustered model gets 6 synonyms). The extra synonym is the next-best hit and passes the threshold; nothing fails. It has been there since the filter was added (#12169, first released in 9.7.0), fails on all 24 releases run and on main, and stopping the loop at k fixes it.
- Word2VecSynonymFilter (
org.apache.lucene.analysis.synonym.word2vec, analysis-common,@lucene.experimental; factory SPI nameWord2VecSynonym, defaultsmaxSynonymsPerTerm = 5,minAcceptedSimilarity = 0.8). For every input token it asks aWord2VecSynonymProviderfor synonyms and emits each as aSYNONYMtoken at the same position. - Word2VecSynonymProvider builds an HNSW graph over the model's normalised vectors once, then
getSynonyms(term, maxSynonymsPerTerm, minAcceptedSimilarity)searches it with the query word's own vector. Each hit has a score(1 + cosine) / 2. - HNSW search is approximate: it keeps the best
topKhits found so far and stops when no unexplored candidate can beat the worst of them (HnswGraphSearcher.java:177-186,:304-355), so a largertopKcan make it explore further (it is not a fixed-size beam), and it can miss true neighbours. That is accepted; returning more than the maximum is a different property.
getSynonymscallsHnswGraphSearcher.search(scorer, maxSynonymsPerTerm + 1, hnswGraph, null, Integer.MAX_VALUE)(Word2VecSynonymProvider.java:82-90), with the comment "When looking for the top-k it's always the nearest neighbour of itself so, we look for the top-k+1" (:85-86).- The loop over the hits keeps every hit that is not the query word and whose score is at least
minAcceptedSimilarity(:93-102). There is no cap atmaxSynonymsPerTerm. - When the query word is among the hits, at most k others remain. When it is not, all k + 1 remain if they pass the threshold, and
Word2VecSynonymFilteremits all of them (Word2VecSynonymFilter.java:95-99,:79-89). - Two legal inputs leave the query word out. Ties: at least k + 2 words with the same normalised vector; equal scores break towards the smaller ordinal (
NeighborQueue.java:95-96), but which tied word loses its own slot depends on the order in which the search collects them (in the 3-word repro at k = 1 it isc). Distinct vectors: the search for k + 1 hits stops before it reaches the query node.
| model, k, threshold | result |
|---|---|
a, b, c with vector {1, 2}; k = 1; 0.5 | a -> [b], b -> [a], c -> [a, b] (both score 1.0) |
| 500 distinct 16-dim vectors, 25 clusters; k = 5; 0.8 (factory defaults) | 499 words get at most 5; w138 -> [w136, w121, w127, w139, w135, w133] |
w138, exact top-7 by brute force | w138 1.0000 (itself), w131 0.9616, w136 0.9552, w121 0.9500, w127 0.9442, w139 0.9385, w135 0.9385 |
w138 with the fix | [w136, w121, w127, w139, w135] |
| same 500-word model, threshold 0.8, by k | overrunning words: 4 at k = 1, 3 at k = 2, 2 at k = 3, 1 at k = 4 and 5, 0 at k = 6 and 7 |
The search also misses w131, the true nearest other word; that is ordinary approximate recall. The bug is the sixth word, w133 (score 0.9366). The search for 7 hits (k = 6) finds w138 itself, so the search for 6 stops too early; w138 is not unreachable. The 500 vectors are pairwise distinct: every word's cosine with itself beats its best cosine with any other word by at least 0.0209.
Exposure and likelihood314 words
- Who. Applications that use
Word2VecSynonymFilter(directly, through its factory, or by SPI name, for example withCustomAnalyzer) or callWord2VecSynonymProvider.getSynonyms. The classes are@lucene.experimentaland opt-in. With any model and anymaxSynonymsPerTerm, the factory defaults included; which words are hit depends on the model. - Effect. For an affected word, every occurrence gets one synonym more than configured: the (k + 1)-th best hit of the search, a model word that still passes
minAcceptedSimilarity. Indexed terms or query expansions differ from what the setting promises; what that does to relevance depends on the application. No exception and no extra search work. - Scale. Deterministic per model as long as
HnswGraphBuilder.randSeedkeeps its default 42 (a public, mutable static field "public to expose for testing"; Lucene's core HNSW tests change it, no analysis-common test does), so the same words are affected every time. Measured on synthetic clustered models only (8 to 64 dimensions, 500 to 10,000 words; no real word2vec model was measured):- factory defaults (5, 0.8): 1 of 500 words (finder), 4 of 4,000 (independent reproducer), 0 to 2 of 10,000 in four 10,000-word models; 0 to 4 per model in 27 models of 1,000 to 4,000 words, non-zero in 8 of them;
maxSynonymsPerTerm = 1(threshold 0.8): 0.1% to 0.8% of words in the 27 models (at most 33 of 4,000), 0.2% to 0.55% in the finder's 2,000- and 10,000-word models.
- Ties. The tie trigger needs at least k + 2 words with one normalised vector (seven at the default k = 5); how often real models have that was not measured. The tie case is the smallest repro, the distinct-vector case the realistic one.
- How likely. Plausible within the opt-in feature: no special input is needed, but only a small fraction of words is affected, and the extra word looks like a reasonable synonym, so it is easy to miss.
The test shows that with three terms that share one vector, Word2VecSynonymProvider.getSynonyms(c, maxSynonymsPerTerm=1, 0.5f) returns two synonyms.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.synonym.word2vec;

import java.util.Collection;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;
import org.apache.lucene.util.TermAndVector;

public class TestWord2VecSynonymProviderMaxSynonyms extends LuceneTestCase {

  public void testTiedVectorsMaxOneSynonym() throws Exception {
    Word2VecModel model = new Word2VecModel(3, 2);
    for (String term : new String[] {"a", "b", "c"}) {
      model.addTermAndVector(new TermAndVector(new BytesRef(term), new float[] {1f, 0f}));
    }
    Word2VecSynonymProvider provider = new Word2VecSynonymProvider(model);
    Collection<TermAndBoost> synonyms = provider.getSynonyms(new BytesRef("c"), 1, 0.5f);
    assertTrue(
        "maxSynonymsPerTerm=1: expected at most 1 synonym of c, got "
            + synonyms.stream().map(s -> s.term().utf8ToString()).toList(),
        synonyms.size() <= 1);
  }
}
# in a copy of this finding's repro folder (repro/LFV-862/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.synonym.word2vec.TestWord2VecSynonymProviderMaxSynonyms
- Expected vs actual
- Expected: at most 1 synonym (
maxSynonymsPerTermis the "maximum number of result returned by the synonym search"); actual (-ea and -da): [a, b], because the k+1 HNSW search does not return the query term itself and nothing caps the result.
More files, environment, full output40 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: maxSynonymsPerTerm=1: expected at most 1 synonym of c, got [a, b]
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.analysis.synonym.word2vec.TestWord2VecSynonymProviderMaxSynonyms.testTiedVectorsMaxOneSynonym(TestWord2VecSynonymProviderMaxSynonyms.java:33)- The filter's javadoc calls
maxSynonymsPerTermthe "maximum number of result returned by the synonym search"; the PR's first draft said it ofgetSynonyms. - An upstream test sets 2 and expects exactly 2 synonyms, although 3 hits are searched.
- The code's comment says the extra hit is room for the query word. Missing neighbours is approximation; exceeding the maximum is not.
The full argument218 words
- Contract.
Word2VecSynonymFilter.java:58: "@param maxSynonymsPerTerm maximum number of result returned by the synonym search". The filter passes the value togetSynonyms(:95-96) and emits everything it gets back. - The provider's own contract, originally. In the first revision of #12169 (
2abb1ea6de1), aSynonymProviderinterface documentedgetSynonyms(BytesRef term, int maxSynonymsPerTerm, float minAcceptedSimilarity)with exactly this@param. The interface was removed in review as a single-implementation interface, and the sentence survived only on the filter constructor. - Upstream test.
TestWord2VecSynonymFilter.java:57-81:maxSynonymPerTerm = 2, expected outputaplus exactly the two SYNONYM tokensdande. The query word is among its hits there, so the test supports the bound but does not cover the self-miss case. It passes on stock and with both fixes. - The
+ 1is only room for the query word. The comment atWord2VecSynonymProvider.java:85-86says so; the factory validates the value as a positive count (Word2VecSynonymFilterFactory.java:72-76). - History. The #12169 review (33 review comments, 38 conversation comments) discussed thread safety, the visited limit,
BoostAttributeand the model reader, never the cap or a missing self-hit. No later commit, test, CHANGES or MIGRATE entry accepts k + 1 results. Silence in a review is weak evidence of intent; the contract, the code comment and the original javadoc carry the argument.
The devil's-advocate check190 words
The strongest not-a-bug case (the intended-behaviour devil's advocate): HNSW is approximate by design, so one more approximation artifact is acceptable; the @param may describe the kNN search size rather than the synonym count; getSynonyms has no javadoc and the package is experimental; equal vectors are rare in trained models; and the extra synonym passes the threshold, so it is harmless.
Why it fails: missing some true neighbours is accepted approximation, but returning more than an explicit maximum is a different property, and the code shows the + 1 exists only as room for the query word. Read as "the search size", the sentence is still broken, because the search is called with k + 1. The original interface javadoc ties the sentence to getSynonyms, and the upstream test treats it as the output count (in a case where the query word is among the hits). A read-only reviewer from another model family (OpenAI GPT-5.6) put it as: "Experimental status and approximate-neighbor semantics do not authorize violating an explicit output bound." Only a severity argument survives (one extra, plausible synonym), which is why the bug ranks low. Verdict: not intended.
Recommended A: stop the loop at maxSynonymsPerTerm
Stop the result loop once maxSynonymsPerTerm synonyms are collected (one condition plus a corrected comment). Hits come in score order, so the best k are kept, and nothing changes when the query word is among the hits. With it the word2vec and repro tests pass with assertions on and off, and the whole analysis-common test task passes.
              // The query vector is in the model, so it is usually its own nearest neighbour:
              // look for the top-k+1 and skip it below. It can be missing from the hits (tied
              // vectors, approximate search), so the loop below also stops after k synonyms.
              maxSynonymsPerTerm + 1,
              ...
      for (int i = 0; i < topDocs.scoreDocs.length && result.size() < maxSynonymsPerTerm; i++) {
All options and trade-offs3 options · 524 words
Two equivalent code fixes were built and run in a scratch worktree at a9779ef3c193; a larger alternative is listed without a run. A is recommended: the smallest change, and it does no extra work.
Add result.size() < maxSynonymsPerTerm to the loop condition in getSynonyms (Word2VecSynonymProvider.java:93) and correct the comment that says the query word is always among the hits.
              // The query vector is in the model, so it is usually its own nearest neighbour:
              // look for the top-k+1 and skip it below. It can be missing from the hits (tied
              // vectors, approximate search), so the loop below also stops after k synonyms.
              maxSynonymsPerTerm + 1,
              ...
      for (int i = 0; i < topDocs.scoreDocs.length && result.size() < maxSynonymsPerTerm; i++) {
Trade-offs
- For positive k (the factory rejects k <= 0; the filter constructor and
getSynonymsdo not check k), output changes only when the query word is missing from the hits; otherwise at most k others pass anyway. - With it,
cgets[a],w138gets[w136, w121, w127, w139, w135], and no word of the 500-word model overruns for any k from 1 to 7. - It does not touch the
+ 1itself, which overflows atInteger.MAX_VALUE(a separate bug with a search-size clamp as its fix); the two fixes compose.
What the checks validated
Gradle in a scratch worktree at a9779ef3c193, seed DEADBEEF: the word2vec test package plus the three repro classes, 7 classes, 30 tests, 0 failures, with assertions on and off (the 9 repro tests that fail on stock pass; the 21 upstream tests pass); the whole :lucene:analysis:common:test task with the three repro classes added, assertions on: 342 classes, 1,918 tests, 0 failures (18 skipped by the module itself); :lucene:analysis:common:check -x test with the fix and this doc's test added passes (google-java-format, ecj lint, forbidden APIs). Through the repro runner with the fixed file shadowed, this doc's test passes 2 of 2 with assertions on and off.
After the loop, while (result.size() > maxSynonymsPerTerm) { result.removeLast(); }. Same output as A; it builds one extra entry in the overrun case. Run: the word2vec package plus the three repro classes, assertions on, 30 tests, 0 failures. The same idea in the 9.7.0 code shape (the 9.7.0 file shadowed onto the 9.7.0 jars) passes the finder's test.
      while (result.size() > maxSynonymsPerTerm) {
        result.removeLast();
      }
Trade-offs
Equivalent to A; slightly more work in the overrun case. Not run on the whole module.
Pass acceptOrds that rejects the query word's ordinal to HnswGraphSearcher.search(scorer, k, ...) and drop the term comparison.
Trade-offs
States the intent directly, but Word2VecModel has no public term-to-ordinal lookup (it needs a package-private accessor), and the kept hits shrink from k + 1 to k, so the search stops earlier and results can change for every word, not only the overrunning ones. Not run. A wider search alone is not a fix: ties can still push the query word out.
Analyzers built by SPI name (for example with CustomAnalyzer) reach this filter as Word2VecSynonym and inherit the extra synonym; which words get it depends only on the configured model.
Semi-formal: a bounded-exhaustive comparison of the real provider with an exact-cosine reference, over every small model on a grid of vector directions (about 11 million checks), flagged results longer than maxSynonymsPerTerm, all with tied vectors. A second harness on clustered models of distinct vectors showed the overrun without ties; both were reduced to a public-API JUnit test.
The method in full175 words
Method: bounded-exhaustive translation validation (the hunt's "semi-formal" tier): the stock analysis-common jar against an exact-cosine reference of getSynonyms, with the oracles "getSynonyms returns at most maxSynonymsPerTerm" and "the filter emits at most maxSynonymsPerTerm SYNONYM tokens".
- Scope: every 2-D model of 2 to 4 words on a 30-degree direction grid in all insertion orders, 3-D multisets of 3 to 4 of 26 directions, k = 1 to 5, several thresholds.
- Result: 385,120 of 11,048,256 provider checks and 144 of 328,320 filter checks fail, all with tied vectors. Mutants of the other oracles were killed, so the comparison was not vacuous.
- A second harness on clustered models of 2,000 and 10,000 distinct random vectors showed the same overrun without ties: the search for k + 1 hits stops before it reaches the query word itself.
- Both were reduced to a public-API JUnit test on the stock main jar; an independent reproducer wrote its own test from the claim alone and checked by brute force that every overrunning word is its own strict nearest neighbour.
No prior report found (two prior-report tool runs plus manual searches of Lucene issues, PRs, commits, mailing lists, the JIRA archive, downstream projects and the web, 2026-10-28). The introducing PR #12169 and the open draft #12433 touch this code but never discuss the cap.
Searches5 searches
Registry verdict new: no issue, PR, review comment, commit, list post, downstream issue or web page reports that getSynonyms or the filter returns or emits maxSynonymsPerTerm + 1 synonyms (best-effort: first-page GitHub results, keyword-based list and JIRA search; one downstream query hit the search quota). Nearest items: #12169 (introduced the k + 1 search; its reviews covered thread safety, the visited limit and BoostAttribute); #12433 (open draft, similarity as boost in the filter, does not touch the provider loop); #12246 and #12257 (thread safety); #12366 (TermAndBoost location); #12529 (scorer refactor that kept the loop); #15704 (collection type). Open PRs #16847 and #16815 touch the provider file for other reasons. Three sibling bugs in the same package are tracked separately with their own fix sites: the unclamped maxSynonymsPerTerm + 1 search size, minAcceptedSimilarity compared with a score instead of a cosine, and a repeated model term that shifts later vectors.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; dev@, java-user@, issues@, commits@; JIRA archive; downstream; web | 2026-10-28 | prior-report tool, two runs: 24 GitHub issue/PR, 3 commit, 2 downstream, 20 list (with commits@) and 4 JIRA queries plus the 6 planned web queries; then 10 GitHub, 2 downstream, 9 list and 4 JIRA queries | no report; #12169 and #12433 are related only |
| web | 2026-10-28 | 8 general web searches: the 6 planned queries plus "Word2VecSynonymProvider" and a duplicate-vectors phrasing (raw results saved for the 6) | the #12168 issue page, the contributors' blog and slides, outside word2vec filters; no report of the defect |
| GitHub (all repositories; apache/lucene open and recent closed PRs) | 2026-10-28 | global search for Word2VecSynonymProvider; titles of all 410 open PRs; files of the 42 updated since 2026-10-25; 200 most recently updated closed PRs; issues since 2026-10-24 | only #12169, #12366, #12529 and draft #12433 |
| Review threads and history | 2026-10-28 | comments of #12168, #12169, #12246, #12257, #12366, #12433, #15704; the dev@ thread on moving TermAndBoost (a reply to the #12169 commit); the package's commits on main, branch_10x and branch_10_6; CHANGES.txt | nobody discusses the cap, the self-exclusion or tied vectors |
| apache/lucene PRs and issues, newest | 2026-10-28 | refresh: the 30 newest PRs (to #16926) and issues (to #16928) | nothing on word2vec or synonyms |
Present since the filter was added by #12169 (1f4f2bf5095, 2023-04-24); first released in 9.7.0, because the first backport was reverted before 9.6.0. The finder's test fails on all 24 releases from 9.7.0 to 10.5.2, on 10.6.0 (branch_10_6 4ae946e5a9b9) and on main; 9.6.0 has no such API.
Versions tested7 rows
Introduced by 1f4f2bf50957ad1a13c32d5351c7de77154953f1 "Introduced the Word2VecSynonymFilter (#12169)" (author @dantuzi, co-author Alessandro Benedetti, merged by @alessandrobenedetti, 2023-04-24; feature issue #12168). The + 1, the "nearest neighbour of itself" comment and the uncapped loop are original lines of that commit. Not a regression.
The branch_9x backport 53709ccaecc (2023-04-24) was reverted by 7e15a390688 the next day over thread safety, so 9.6.0 has no word2vec package, although CHANGES.txt lists GITHUB#12169 under 9.6.0. The re-backport 64b48b89b50 (2023-05-30) is first in 9.7.0; on the main line the first release is 10.0.0. Later commits on the provider (#12235, #12246, #12366, #12434, #12529, #12651, #13288, #15704) changed the search call, visited limit, collector, imports or result container, never the cap. The provider file is byte-identical in 9.12.3, 10.0.0, 10.5.2 and branch_10_6; main differs only by #15704. No commit on the package's main sources after #15704 (2026-02-26), up to upstream main (fetched 2026-10-28); two later commits only tidy its tests (#16028, #16255). The provider file as 1f4f2bf5095 added it, shadowed onto the 9.7.0 jars, fails the finder's test 3 of 3.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 2 of 2 through gradle and the repro runner, assertions on and off; the finder's and the independent tests fail too |
branch_10_6 4ae946e5a9b9 | finder's JUnit | fails 3 of 3 (4ae946e5a9b9 is newer than the local clone's origin/branch_10_6 2763db11b0a, its ancestor; the provider file is byte-identical in both) |
| 10.5.2, 9.12.3, 9.7.0 | affected | this doc's test fails 2 of 2 on the published jars (10.5.2 also with assertions off); the independent test fails 4 of 4 |
| 24 releases, 9.7.0 to 10.5.2 | finder's JUnit | fails 3 of 3 on every release, with the same messages (9.x with a one-accessor copy) |
1f4f2bf5095 (#12169, 2023) | introducing commit | its provider file, shadowed onto the 9.7.0 jars, fails 3 of 3; the 9.7.0 file plus a cap passes |
| 9.6.0 | API absent | no word2vec package; the test does not compile |
fix A on a9779ef3c193 | not affected | the word2vec and repro tests 30 of 30, assertions on and off; the whole analysis-common test task: 342 classes, 1,918 tests, 0 failures (18 skipped by the module itself) |
An independent reproducer, an intended-behaviour devil's advocate, a read-only cross-model review and an adjudication all found it real; the other cross-model review could not run any command and returned a procedural verdict. Every executed re-run failed on main with assertions on and off and passed with the fix.
Checks and verdicts299 words
Each check worked on its own; the registration check and a credibility audit re-ran the tests with fresh seeds, and this doc re-ran them through gradle on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder (exhaustive comparison, JUnit) | candidate | JUnit fails 3 of 3 on main (-ea, -da, scalar vector code), branch_10_6 and 24 releases; with the fix 3 of 3 pass and the 21 upstream word2vec tests pass. |
| cross-model review, refute lens | not real, low (procedural) | A reviewer from another model family (OpenAI GPT-5.6) could not run any command and says the verdict is not a technical refutation; a separate re-run of the repro fails 3 of 3. |
| independent reproducer | real | Own test fails 4 of 4 on main (-ea, -da, scalar), 10.5.2, 9.12.3 and 9.7.0; a brute-force check shows each overrunning word is its own strict nearest neighbour; its own cap fix passes. |
| cross-model review, intended lens | real, low (read-only) | Read only (no Java run, low confidence; it read main ea57360912ed): the intended argument is weak. Separate re-runs on a9779ef3c193 fail 3 of 3 and pass 3 of 3 with the fix. |
| intended-behaviour devil's advocate | real | Found the original getSynonyms javadoc in #12169's first revision and the cap-asserting upstream test; its probe shows w138 overruns for k = 1 to 5 and is found from k = 6. |
| adjudication | confirmed, high | Re-ran the independent test with a new seed: 4 of 4 fail with -ea and -da. |
| security screen | not security-sensitive | The model is trusted configuration (SECURITY.md line 42); the effect is one extra above-threshold synonym. |
| registry re-run and credibility audit | keep | Finder's test fails with -ea, the independent test with -da, on fresh seeds; the finder's test passes with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 501 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,225 words
- Registry title
- Word2VecSynonymProvider returns maxSynonymsPerTerm + 1 synonyms when the query term is not among its own k+1 HNSW hits (tied vectors or an approximate-search miss), so Word2VecSynonymFilter emits one synonym more than the documented maximum
- Area
- analysis-common / synonym.word2vec (Word2VecSynonymProvider.getSynonyms result cap; Word2VecSynonymFilter)
- Priority
- Low, rank 447: The experimental, opt-in Word2VecSynonymFilter adds one extra above-threshold synonym for a small fixed set of terms, a quality-only drift like the opt-in WordDelimiterGraphFilterFactory types row LFV-851.
- Impact class
- silent wrong results
- Impact note
- Only applications that opt in to the @lucene.experimental Word2VecSynonymFilter (or call Word2VecSynonymProvider.getSynonyms directly) are hit, with any model and the factory defaults (maxSynonymsPerTerm=5, minAcceptedSimilarity=0.8): for the terms whose own vector the k+1 HNSW search does not return (about 0-0.2% of terms at the defaults and 0.1-1.1% at maxSynonymsPerTerm=1 in the synthetic clustered models measured; no real model was measured), or that share their normalized vector with two or more other terms, every occurrence at index or query time silently gets exactly one extra synonym, the (k+1)-th best hit, which still passes minAcceptedSimilarity; ordinary scale; every release since 9.7.0.
- Summary
- You configure Word2VecSynonymFilter with maxSynonymsPerTerm=k, whose javadoc calls it the 'maximum number of result returned by the synonym search', so you expect at most k synonyms per token. Word2VecSynonymProvider.getSynonyms searches the HNSW graph for k+1 neighbours on the assumption that the query term is always its own nearest neighbour, drops only the query term and never caps the result, so when the term is not among the hits it returns all k+1. With three terms that share one vector and k=1, getSynonyms(c) returns [a, b] and the filter emits 2 SYNONYM tokens; with 4000 distinct clustered vectors and the factory defaults, 4 terms get 6 synonyms because the approximate search with a beam of 6 does not reach the query term itself, although it is its own strict nearest neighbour by a margin of more than 0.03.
- Introduced
- 1f4f2bf50957ad1a13c32d5351c7de77154953f1 on main (apache/lucene#12169 'Introduced the Word2VecSynonymFilter', feature issue #12168; author dantuzi, co-author Alessandro Benedetti, merged by alessandrobenedetti; first in 10.0.0) and its branch_9x backport 64b48b89b501 (committed 2023-05-30, author date 2023-04-24; first in 9.7.0; an earlier backport 53709ccaecc was reverted by 7e15a390688 on 2023-04-25) [read: git blame on main a9779ef3c193 attributes the comment 'it's always the nearest neighbour of itself', the '+ 1' (Word2VecSynonymProvider.java:85-87) and the result condition (:99) to 1f4f2bf5095; exec: the provider file exactly as 1f4f2bf5095 added it (one import line dropped) shadowed onto the 9.7.0 jars fails 3 of 3, and the 9.7.0 provider plus a final cap passes 3 of 3] (2023-04-24 (main 1f4f2bf5095); 2023-05-30 (branch_9x re-backport 64b48b89b50, author date 2023-04-24))
- First affected version
- 9.7.0 [exec] (the first release with the API; 9.6.0 has no synonym.word2vec package, the repro does not compile there [exec], although CHANGES.txt lists GITHUB#12169 under 9.6.0); first on the main line: 10.0.0 [exec]
- Affected versions
- Every release that has the API: 9.7.0 to 9.12.3 and 10.0.0 to 10.5.2, 24 releases [exec: the finder's JUnit fails 3 of 3 with the same messages on each with -ea, also with -da on 9.7.0, 9.12.3, 10.0.0 and 10.5.2; 9.x runs use an import-adapted copy because TermAndBoost has public fields there; the independent reproduction's JUnit compiles unchanged and fails 4 of 4 on 10.5.2, 9.12.3 and 9.7.0], the branch_10_6 head 4ae946e5a9b9 (10.6.0, released 2026-10-29) [exec] and main a9779ef3c193 [exec: -ea and -da, Panama and scalar vector providers; re-run at the registration check]. Not fixed upstream: the provider file is byte-identical in 9.12.3, 10.0.0, 10.5.2 and branch_10_6, main differs only by #15704 (collection type), and no commit on the package follows 7335eb0ad96 (#15704, author date 2026-02-26) on upstream main c5ab3e57b9b (2026-10-28) [read]. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only; refreshed at the registration check 2026-10-28): scripted prior-report search specs v1 and v2 (GitHub issue/PR, commit-message, downstream Elasticsearch/OpenSearch/Solr, dev@/java-user@/issues@/commits@ list, JIRA-archive and web queries), global GitHub search for Word2VecSynonymProvider (only apache/lucene #12169, #12366, #12529), titles of all 410 open apache/lucene PRs, file lists of the 42 open PRs updated since 2026-10-25, the 200 most recently updated closed PRs, issues created since 2026-10-24, the commit history of the package on main, branch_10x and branch_10_6, CHANGES.txt, the comments of #12168, #12169, #12246, #12257, #12366, #12433 and #15704, the dev@ thread on #12169, and 8 general web searches. Related, not this bug: #12169 (introduced the k+1 search; reviews discussed thread safety, visitedLimit and BoostAttribute, not the cap), #12433 (open draft, filter boost, does not touch the provider loop), #12246/#12257 (thread safety), #15704 (collection type). Refresh: the 30 newest PRs (to #16926) and issues (to #16928) contain nothing on word2vec or synonyms, and the last commit on the package is still 7335eb0ad96. Gaps: one downstream GitHub query (elastic/elasticsearch Word2VecSynonymFilter) and the search query hit GitHub's search rate limit; keyword search reads only the first page per query.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree: the word2vec test package plus three repro classes, stock and with fix A, assertions on and off; fix A on the whole analysis-common test task and its static checks; fix B on the package with assertions on); this doc's test through the repro runner on main (stock and with fix A shadowed, assertions on and off) and on the published 10.5.2, 9.12.3 and 9.7.0 jars; the finder's test on all 24 releases from 9.7.0 to 10.5.2, onbranch_10_64ae946e5a9b9and on main (the hunt, 2026-10-28). JDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:41 (@lucene.experimental), :70-104 (getSynonyms; '+ 1' at :87, comment :85-86, self-removal and threshold :98-100, no cap)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:37 (@lucene.experimental), :58 ('@param maxSynonymsPerTerm maximum number of result returned by the synonym search'), :95-99 (every returned synonym is buffered and emitted)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:41-42 (defaults 5 and 0.8), :72-76 (maxSynonymsPerTerm must be positive)lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymFilter.java:58-80 (synonymExpansion_oneCandidate_shouldBeExpandedWithTopKSynonyms: k=2, exactly 2 SYNONYM tokens)
- The finding in 30 seconds
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:41, 56-68, 70-104a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:37, 58, 79-89, 95-99a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:32-42a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/hnsw/HnswGraphSearcher.java:165-186, 304-355; NeighborQueue.java:95-96
- Who is affected
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:41, 60-67 (experimental; HnswGraphBuilder.randSeed); lucene/core/src/java/org/apache/lucene/util/hnsw/HnswGraphBuilder.java:60, 65-67 (default seed 42, public mutable static)a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:32-42 (experimental, SPI name, defaults)
- Why it looks unintended
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:58, 95-96a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:85-86a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:72-76a Lucene main checkout lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymFilter.java:57-81
- Suggested fix
a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/hnsw/HnswGraphSearcher.java:165-186, 348-350 (acceptOrds: explored but not collected)
- History
a Lucene main checkout lucene/CHANGES.txt:3564, 3593
- TestWord2VecSynonymProviderMaxSynonyms.java (JUnit test):
repro/LFV-862/src/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymProviderMaxSynonyms.java(38 lines)
A step-by-step picture of the repro's examples, made in parallel with this doc from the code at a9779ef3c193 and the executed repro output. The PNG is its summary frame.
assets/LFV-862/bug.png(501 KB)