- An
Automatonis a set of numbered states with labelled transitions. State 0 is always the start state; reaching an accept state at the end of the input means a match. - An automaton that matches nothing has the empty language. Lucene usually represents it with no states at all:
Automata.makeEmpty()returns one, and so do operations whose result matches nothing, such as intersecting "a" with "b". AutomatonToTokenStream.toTokenStreamturns an acyclic automaton into a token graph: states at the same distance from the start become one position, and each transition becomes a token. Before that, it checks that the start state has no incoming edges.
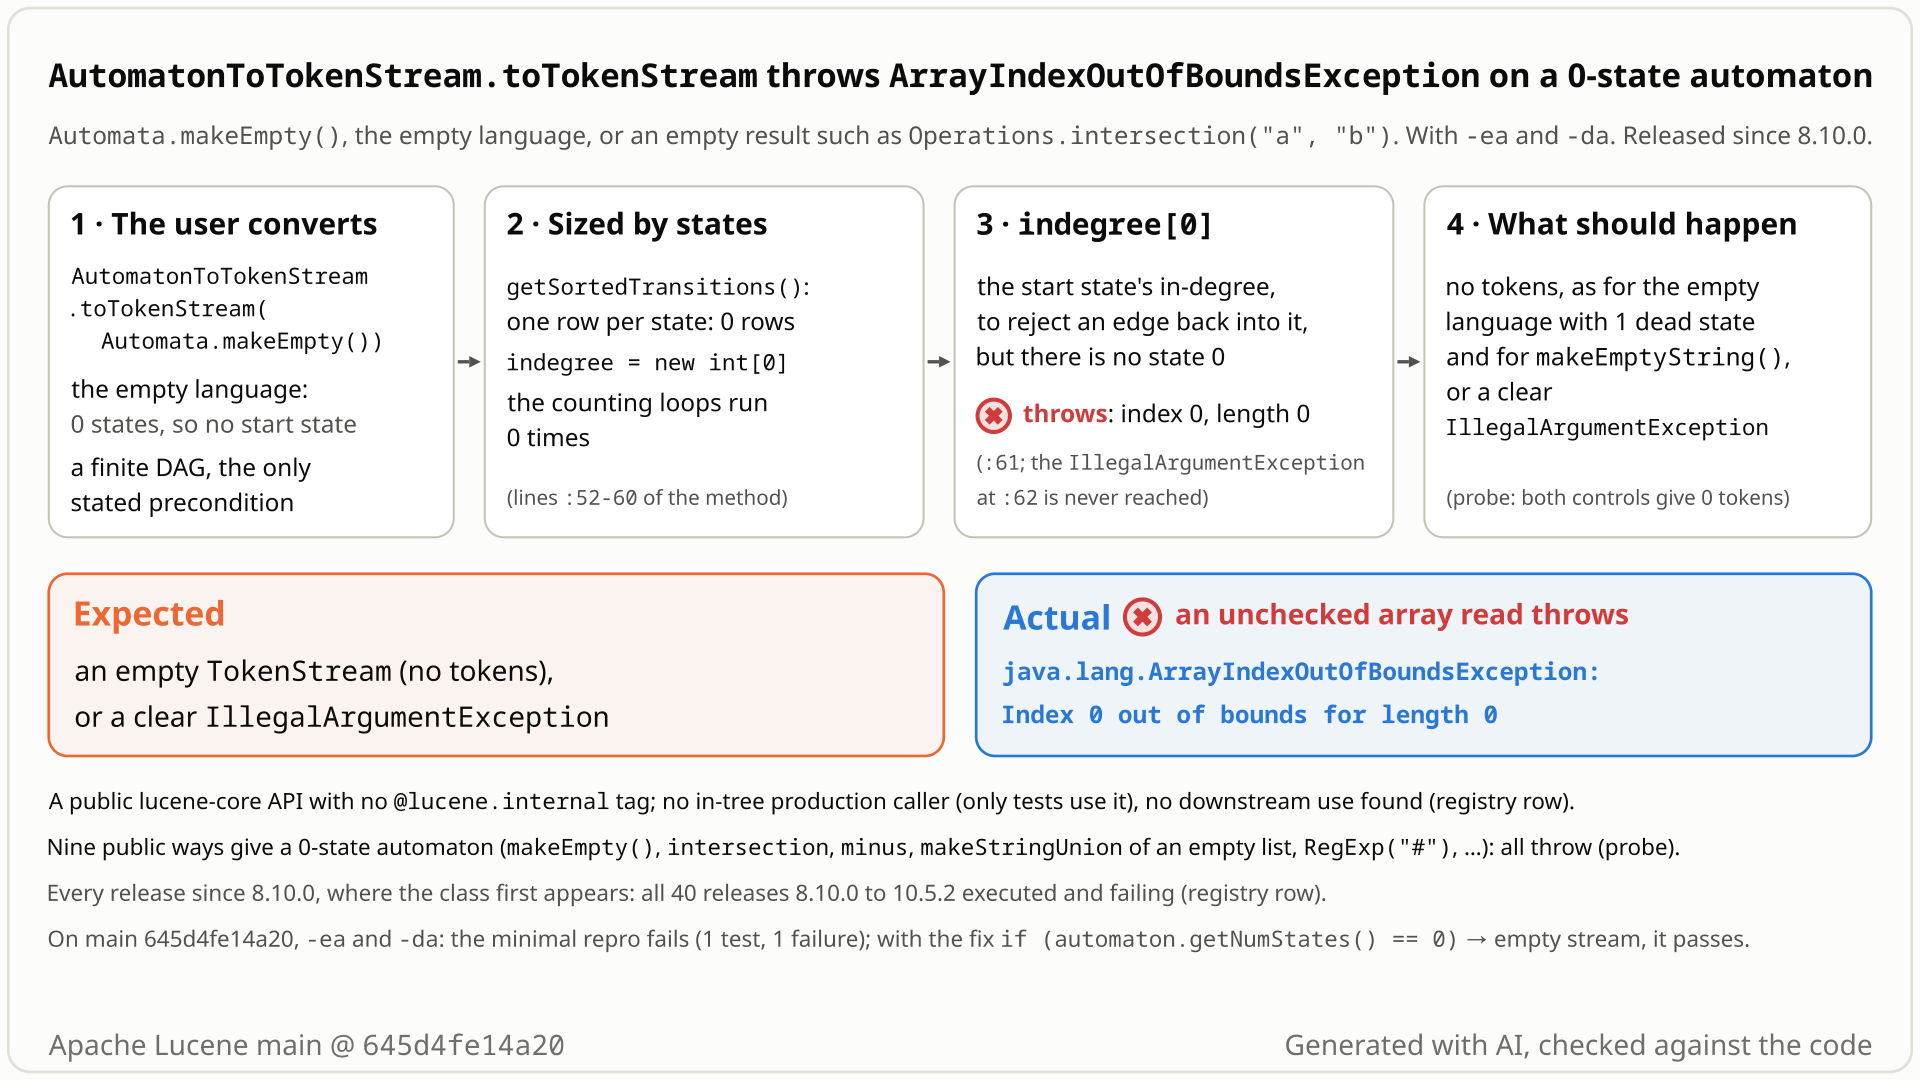
- Build an automaton that matches nothing, for example
Automata.makeEmpty()orOperations.intersection(Automata.makeString("a"), Automata.makeString("b")). Lucene represents both with 0 states. - Convert it with
AutomatonToTokenStream.toTokenStream(automaton). Its only stated precondition, a finite DAG, holds (the automaton has no cycles; that it also has no start state, which the method assumes, is not in the javadoc). - You expect a token stream with 0 tokens, which is what the method already returns for
Automata.makeEmptyString()and for the same empty language written as 1 non-accepting state. Or at least anIllegalArgumentException, which the method's own two input checks throw. - Instead it throws
ArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0, with assertions on and off. The method sizesint[] indegreeto the number of states, here 0, and then readsindegree[0]to check the start state (AutomatonToTokenStream.java:61). - This read has been there since the class was added in 8.10.0 (#157). No Lucene production code calls the converter, so only applications that call it themselves are hit.
Only applications that themselves call the public AutomatonToTokenStream.toTokenStream with an automaton that matches nothing, such as an empty string union or an empty intersection. No Lucene query, analyzer or index path calls it (only two test classes do), and no use was found in Solr, Elasticsearch or OpenSearch. That one call fails at once; nothing else breaks. Rare.
Mechanism, terms and numbers598 words
AutomatonToTokenStream.toTokenStream(Automaton) (lucene-core, public, no @lucene.internal or @lucene.experimental tag) turns an acyclic automaton into a token graph; its only stated precondition is "This requires the automaton be a finite DAG" (AutomatonToTokenStream.java:44, :46). Lucene's normal value for the empty language has no states: Automata.makeEmpty() ("a new (deterministic) automaton with the empty language", Automata.java:55-60), an empty makeStringUnion, RegExp #, and empty results of Operations.intersection, minus or removeDeadStates. For such an automaton the method sizes int[] indegree to the number of states, 0 (:52, :54), and reads indegree[0] at :61 to check that the start state has no incoming edges, without checking that a state exists, so the JVM throws ArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0 with assertions on and off. The same empty language written as one non-accepting state already gives a stream with 0 tokens, as does Automata.makeEmptyString(). The read dates from the class's introduction in #157 (LUCENE-9963, 8.10.0); every release since fails, and it is not fixed upstream. A 4-line guard that returns the empty-string stream for 0 states fixes it (validated); throwing a clear IllegalArgumentException is the alternative. Low impact: no Lucene production code calls the converter, and no downstream use was found.
Automaton(org.apache.lucene.util.automaton,@lucene.experimental): states are integers, "State 0 is always the initial state" (Automaton.java:37-38); transitions carry character ranges; accept states end a match.- Empty language: the automaton accepts no string at all. Lucene's usual form has 0 states:
Automata.makeEmpty()isnew Automaton()plusfinishState()(Automata.java:55-60), andOperations.isEmptycalls 0 states the "Common case" of the empty language (Operations.java:799-803). One non-accepting state with no transitions has the same language. AutomatonToTokenStream.toTokenStream(org.apache.lucene.analysis, lucene-core, public): "Nodes that have the same distance from the start are grouped together to form the position nodes for the TokenStream"; "This requires the automaton be a finite DAG" (AutomatonToTokenStream.java:40-47). It was added as a helper for theFlattenGraphFiltertests.
Transition[][] transitions = automaton.getSortedTransitions();(:52) has one row per state (Automaton.java:116-118): for 0 states, length 0.int[] indegree = new int[transitions.length];(:54): length 0. The loop that counts in-degrees (:56-60) runs 0 times.if (indegree[0] != 0)(:61) checks that the start state has no incoming edges and would throwIllegalArgumentException("Start node has incoming edges, creating cycle"). With no state 0, the read itself throwsArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0, before the check can run.- With 1 non-accepting state, the same empty language passes:
indegreeis[0], the check passes, the walk (:65-85) puts state 0 at position 0, there are no edges, and the stream has 0 tokens.makeEmptyString()(1 accepting state) takes the same path.
Automata.makeEmpty(): 0 states, indegree.length 0, exception. Nine public ways to a 0-state automaton all throw the same way: Automata.makeEmpty(), Automata.makeStringUnion of an empty list, RegExp # and a&b (with RegExp.ALL), Operations.intersection(makeString("a"), makeString("b")), Operations.minus of two equal languages, Automata.makeCharRange(5, 4), an empty Automaton.Builder, and Operations.removeDeadStates of one non-accepting state. Controls: the 1-dead-state form and makeEmptyString() give 0 tokens. These nine inputs and two controls ran on main (assertions on and off), 10.5.2 and 9.12.3 (assertions off), all with the same result. makeEmpty() also fails on 10.6.0 (the minimal test, assertions on), and makeEmpty() and the empty intersection fail on all 40 releases from 8.10.0 to 10.5.2 (assertions on), where the controls makeEmptyString() and makeString("abc") give 0 and 3 tokens.
Exposure and likelihood228 words
- Who is hit. Code that calls
AutomatonToTokenStream.toTokenStreamwith an automaton whose language is empty in its 0-state form, for example (illustrative, not found in any project) a helper that builds an automaton from a possibly empty list of strings withAutomata.makeStringUnion, or that intersects two automata and converts the result. - Who is not hit. No Lucene production code calls the converter: its only callers in the tree are the tests
TestAutomatonToTokenStream(core) andTestFlattenGraphFilter(analysis-common). A GitHub code search found 0 files in Elasticsearch, OpenSearch and Solr, and 53 files overall, all copies of Lucene. No query, analyzer, parser or index path reaches it. - What happens. One
ArrayIndexOutOfBoundsExceptionwhose message ("Index 0 out of bounds for length 0") points into the converter, not at the input. - What does not happen. No wrong tokens, no hang, no memory growth; the input automaton is not changed and nothing is written.
- Default vs opt-in, scale. Opt-in: only an application that uses this utility. No setting is involved, and data size plays no part: the trigger is exactly an automaton with 0 states. Deterministic, with assertions on and off.
- How likely. Rare. The class was added in #157 as test infrastructure for
FlattenGraphFilter(the reviewer called it "helpful infrastructure for future testing" and "a nice utility API"), and no report of this failure was found in the five years since 8.10.0.
One JUnit test on the public API: convert Automata.makeEmpty(). It accepts an empty stream or an IllegalArgumentException and fails only when the ArrayIndexOutOfBoundsException escapes. Deterministic, single thread, about 2 s; the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;
import org.apache.lucene.util.automaton.Automata;

public class TestAutomatonToTokenStreamZeroStates extends BaseTokenStreamTestCase {

  public void testMakeEmpty() throws Exception {
    // Automata.makeEmpty() is a finite DAG with 0 states (the empty language)
    TokenStream ts;
    try {
      ts = AutomatonToTokenStream.toTokenStream(Automata.makeEmpty());
    } catch (IllegalArgumentException acceptable) {
      return;
    } catch (ArrayIndexOutOfBoundsException e) {
      throw new AssertionError(
          "expected an empty TokenStream or IllegalArgumentException, got " + e, e);
    }
    assertTokenStreamContents(ts, new String[0]);
  }
}
cp TestAutomatonToTokenStreamZeroStates.java $LUCENE/lucene/core/src/test/org/apache/lucene/analysis/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.analysis.TestAutomatonToTokenStreamZeroStates -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- A
TokenStreamwith no tokens (as forAutomata.makeEmptyString()), or a clearIllegalArgumentException. - Observed
ArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0atAutomatonToTokenStream.java:61, with assertions on and off.
More files, environment, full output325 words
TestAutomatonToTokenStreamZeroStates calls AutomatonToTokenStream.toTokenStream(Automata.makeEmpty()). As the adjudication asked, it accepts either outcome a fix may choose: an empty stream (checked with assertTokenStreamContents) or an IllegalArgumentException. An ArrayIndexOutOfBoundsException is rethrown as an AssertionError that states expected and actual, with the original as its cause. Automata.makeEmpty() is the smallest input (0 states, 0 transitions). Public API only (it sits in org.apache.lucene.analysis next to AutomatonToTokenStream, by Lucene convention); no randomness of its own, so the seed does not matter (seeds DEADBEEF and 5EED1234 gave the same failure). It compiles on 9.1 and later (it needs org.apache.lucene.tests.analysis.BaseTokenStreamTestCase).
As the regression test: this same test, for example as a new method in TestAutomatonToTokenStream. Name the unused catch parameter _ instead of acceptable (Lucene's convention): ./gradlew :lucene:core:check runs an ecj lint that rejects an unused named exception parameter. With that one-word change the test still fails on stock main with assertions on and off, passes with fix A, and ./gradlew :lucene:core:check -x test passes with it as a new test file. If the maintainer picks option B, the test can become expectThrows(IllegalArgumentException.class, () -> AutomatonToTokenStream.toTokenStream(Automata.makeEmpty())). Once a fix is chosen, the committed test should assert that one behaviour rather than accept both.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); this test also fails on 10.6.0 and 9.12.3; every release from 8.10.0 to 10.6.0 is affected |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestAutomatonToTokenStreamZeroStates.java $LUCENE/lucene/core/src/test/org/apache/lucene/analysis/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.analysis.TestAutomatonToTokenStreamZeroStates -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestAutomatonToTokenStreamZeroStates > testMakeEmpty FAILED
    java.lang.AssertionError: expected an empty TokenStream or IllegalArgumentException, got java.lang.ArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:3799068DECC9FD1A]:0)
        at org.apache.lucene.analysis.TestAutomatonToTokenStreamZeroStates.testMakeEmpty(TestAutomatonToTokenStreamZeroStates.java:32)

        Caused by:
        java.lang.ArrayIndexOutOfBoundsException: Index 0 out of bounds for length 0
            at org.apache.lucene.analysis.AutomatonToTokenStream.toTokenStream(AutomatonToTokenStream.java:61)
            at org.apache.lucene.analysis.TestAutomatonToTokenStreamZeroStates.testMakeEmpty(TestAutomatonToTokenStreamZeroStates.java:28)

# gradle, main 645d4fe14a20, seed DEADBEEF, assertions off (the test with its catch parameter named _, same lines); the same with assertions on.
# 10.6.0: the same at AutomatonToTokenStream.java:60; 9.12.3: at :65.- The only documented precondition is a finite DAG;
Automata.makeEmpty()is documented as "a new (deterministic) automaton with the empty language". - The same empty language with 1 non-accepting state already returns an empty stream; only the 0-state form crashes.
- The method's two explicit input checks throw
IllegalArgumentException, which its tests assert; the crash happens on the first check's own line.
The full argument217 words
- Contract.
AutomatonToTokenStream.java:44: "This requires the automaton be a finite DAG.":46: "@param automaton automaton to convert. Must be a finite DAG to avoid infinite loops!" Nothing says the automaton must have a state. The class has no@lucene.internalor@lucene.experimentaltag (the automaton classes it takes,Automaton,AutomataandOperations, are@lucene.experimental). - A standard input.
Automata.makeEmpty(): "Returns a new (deterministic) automaton with the empty language." (Automata.java:55), with 0 states.Operations.isEmptytreats 0 states as the common empty case (Operations.java:799-803). - Representation, not language, decides the outcome. The same empty language as 1 dead state gives a stream with 0 tokens (executed); as 0 states it crashes.
- Its own validation throws
IllegalArgumentException. Its two explicit checks reject a start state with incoming edges (:61-63) and leftover cycles (:87-91) withIllegalArgumentException, and the upstream tests assert exactly that (TestAutomatonToTokenStream.java:105-120and:122-136,expectThrows(IllegalArgumentException.class, ...)). - Precedent. Lucene's own topological sort of automata (
org.apache.lucene.util.automaton, todayOperations.topoSortStates) got an explicit 0-state guard in LUCENE-6365 (ae4723e0b50, 2015, "fix buggy Operations.topoSort; add test"), todayOperations.java:1366-1368. - No sign of intent. The introducing PR #157 and LUCENE-9963 never mention empty or 0-state automata; no upstream test passes one; no CHANGES or MIGRATE entry.
The devil's-advocate check163 words
The strongest case for "not a bug" (the intended-behaviour checker's and the cross-model reviewers'): the javadoc builds positions from "distance from the start" (:42) and Automaton says "State 0 is always the initial state" (Automaton.java:37-38), so an automaton with no states has no start and could be read as outside the method's domain; and the class is a test-oriented helper.
Why it fails: nothing documents that precondition, while the documented one (a finite DAG) holds; the method already handles the same language when it has one dead state; an input the method does not accept should get the method's own IllegalArgumentException, not an index error from its validation line; and "test-oriented" bears on severity, not on validity, since the class is public API in the lucene-core jar. Residual: a maintainer may prefer to reject 0 states with an IllegalArgumentException rather than return an empty stream. That is a choice of fix (option B), and the repro accepts it.
Recommended A. Return the empty-string stream for 0 states
Return the empty-string stream when the automaton has no states: a 4-line getNumStates() == 0 guard at the top of toTokenStream. The 0-state form then behaves like the 1-dead-state form of the same language. With it the repro passes with assertions on and off, and the core analysis tests, TestFlattenGraphFilter and core's static checks pass.
--- a/lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java
+++ b/lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java
@@ -49,6 +49,10 @@
   public static TokenStream toTokenStream(Automaton automaton) {
     List<IntArrayList> positionNodes = new ArrayList<>();

+    if (automaton.getNumStates() == 0) {
+      // the empty language: no tokens (same stream as for the empty string)
+      return new TopoTokenStream(List.of(List.of()));
+    }
     Transition[][] transitions = automaton.getSortedTransitions();

     int[] indegree = new int[transitions.length];
All options and trade-offs2 options · 585 words
The choice is the maintainer's: this doc suggests A because the 0-state form then behaves like the 1-dead-state form of the same language; the cross-model fact check of the brief would make B the default, because it states the implicit start-state requirement and does not merge the empty language with the empty string. Both are validated; neither is shown to be better. Fix A was validated through gradle in a scratch worktree of 645d4fe14a20. Option B, the alternative the adjudication asked to offer, was validated with the fix shadowed into the stock jars only.
Before reading indegree, return the stream that the method already builds for makeEmptyString() and for the 1-dead-state form: one position layer with no edges.
--- a/lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java
+++ b/lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java
@@ -49,6 +49,10 @@
   public static TokenStream toTokenStream(Automaton automaton) {
     List<IntArrayList> positionNodes = new ArrayList<>();

+    if (automaton.getNumStates() == 0) {
+      // the empty language: no tokens (same stream as for the empty string)
+      return new TopoTokenStream(List.of(List.of()));
+    }
     Transition[][] transitions = automaton.getSortedTransitions();

     int[] indegree = new int[transitions.length];
Trade-offs
- The 0-state form of the empty language then behaves like its 1-dead-state form, which already returns this stream. No change for any automaton with at least one state.
- The stream is the one
makeEmptyString()gives, so it cannot tell the empty language from the empty string; that is already true for the 1-dead-state form. In the other direction,TokenStreamToAutomatonturns this stream into an automaton that accepts nothing (executed on the stream ofmakeEmptyString(), which is this stream). A cross-model reviewer suggested the code comment not imply that the two languages are the same in general. - Keep the one empty layer: with
List.of()(no layer),end()would callsetOffset(-1, -1), because it usesedgesByPos.size() - 1(:165-170, code reading).
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seedDEADBEEF, 2026-11-01: without the fix the repro fails with assertions on and off; with it, it passes with assertions on and off. - Every core test class in
org.apache.lucene.analysiswith the fix (TestAutomatonToTokenStream,TestGraphTokenizers, the repro and 19 more): 22 classes, 169 tests, 0 failures. TestFlattenGraphFilter(analysis-common), the other in-tree user of the converter: 25 tests, 0 failures../gradlew :lucene:core:check -x testwith the fix and the repro (catch parameter named_) as a new test file: passes (google-java-format, ecj lint of main and test code, forbidden APIs; error-prone skipped). The full Lucene test suite was not run.- Earlier, with the fix shadowed into the stock jars: the finder's repro with the upstream
TestAutomatonToTokenStream(9 tests), the independent reproducer's 6 tests and the minimal repro with assertions on and off pass.
Throw the method's own exception type with a message that names the cause, and document it in the javadoc.
+    if (automaton.getNumStates() == 0) {
+      throw new IllegalArgumentException("Automaton has no states (empty language)");
+    }
Trade-offs
- Explicit, and it does not equate the empty language with the empty string.
- The outcome still depends on the representation (1 dead state gives an empty stream, 0 states throws), so the javadoc should say that an automaton with no states is rejected, and callers must special-case empty languages before converting.
What the checks validated
- Shadowed into the stock
645d4fe14a20jars (standalone, assertions on): the minimal repro and the upstreamTestAutomatonToTokenStreampass, 7 tests, 0 failures. Not run through gradle.
No use of AutomatonToTokenStream was found in Elasticsearch, OpenSearch or Solr; an application that may pass an automaton that matches nothing can avoid the crash by checking automaton.getNumStates() == 0 before converting.
Semi-formal. An AI tool wrote a bounded-exhaustive model of the converter's documented construction to check its output on every small automaton. The model needs a start state; writing that precondition down showed that the code reads indegree[0] without checking that any state exists. A public-API JUnit test on the stock jars then showed the exception.
The method in full169 words
- Method: bounded-exhaustive translation validation, the hunt's semi-formal tier, in the hunt unit on token-graph and automaton conversion. The unit compared the stock jar's token graphs with an independent model of the documented construction over all small automata with at least one state (for example all 33,554,432 topologically numbered 5-state automata over {a, b}). In every automaton in scope the jar threw nothing other than
IllegalArgumentException. - The hint: the model needs a start state, so its precondition excluded 0 states; writing that down showed that the code reads
indegree[0]with no such check. - Witness: a JUnit test on the stock main jar (
makeEmpty(), an empty intersection, and amakeEmptyString()control) failed on both empty inputs while the control passed; a shadowed 4-line fix made it pass. - Later: an independent reproducer, an intended-behaviour devil's advocate, cross-model reviews and an adjudication checked it (2026-10-28); the history was checked by execution over 40 releases; the test was reduced to one test method (2026-10-29) and re-verified on main
645d4fe14a20.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the Lucene mailing lists, downstream projects or the web (about 170 distinct queries and reads, 2026-10-28; re-checked 2026-11-01). The closest item is #157, which introduced the class. Not fixed upstream as of 2026-11-01 (upstream main f815e679bf6).
Searches4 searches
Closest items, none a report of this bug: #157 / LUCENE-9963 (introduced the class; its review never mentions empty automata), #11002 (LUCENE-9963's own ArrayIndexOutOfBoundsException, in RollingBuffer via FlattenGraphFilter), #14224, #3791, #13707, #14211 and #13706 (0-state or empty automata in other Operations and Automata methods), #9391 (the inverse converter TokenStreamToAutomaton). Gaps: a search shows only that no report was found; private channels were not searched.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene and apache/lucene-solr issues, PRs and commits | 2026-10-28 | two scripted prior-report searches (46 issue/PR and 6 commit queries) and 24 manual GitHub searches (REST and GraphQL, the archived lucene-solr repository, all of GitHub); the changed files of all 410 open PRs; #157, #146, #11002 and #15704 read in full | no report; every hit naming the class is #157 or a commit notification |
| Mailing lists, JIRA archive, downstream, web | 2026-10-28 | 40 scripted and 24 direct list queries (dev@, java-user@, issues@, commits@); 8 scripted and 5 JQL JIRA queries; 4 downstream queries and a GitHub code search (Elasticsearch, OpenSearch, Solr); 10 web queries (a later repeat of the same 10 is not counted again) | no report; no downstream caller |
| Re-check | 2026-11-01 | all 79 apache/lucene issues and PRs updated since 2026-10-28 (62 PRs): titles and bodies, and every PR's changed files (no new keyword search) | nothing new; no PR changes AutomatonToTokenStream.java |
| Upstream main and branches | 2026-11-01 | file contents at main 2f424fd428d (2026-10-30) and f815e679bf6 (2026-11-01, GitHub contents API), branch_11x, branch_10_6 and the 10.6.0 tag | not fixed; the unguarded read is still there |
Introduced with the class in 8.10.0 by #157 (LUCENE-9963, 647255b4d29b, 2021-08-09). A probe fails on all 40 releases from 8.10.0 to 10.5.2, and the minimal test fails on 10.6.0, 9.12.3 and main. 8.9.0 has no such class. Never fixed.
Versions tested6 rows
Introduced by #157 (LUCENE-9963, GitHub glawson0, merged by mikemccand), squash commit 647255b4d29b ("LUCENE-9963 Improve FlattenGraphFilter's robustness when handling incoming token graphs with holes (#157)", 2021-08-09 UTC); 8.x backport apache/lucene-solr#2551 (75eba389297, 2021-08-16). git blame of lines 52-63 is all 647255b4d29b. Not a regression: in 8.10.0-9.12.3 an Operations.isFinite pre-check ran first, but it returned true for 0 states, so it did not stop the crash; #11813 (15f3743f02c, first released in 10.0.0) removed it without changing the outcome. Later commits (#13368, #13406, #13422, #13328, #15704) refactored other lines.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal repro fails with assertions on and off (standalone and gradle); passes with fix A |
| 10.6.0, 9.12.3 | affected | minimal repro fails (10.6.0 with assertions on at line 60, 9.12.3 with assertions off at line 65) |
| 8.10.0 to 10.5.2 (40 releases) | first affected 8.10.0 | the main() probe throws at the indegree[0] line on every one; the finder's JUnit fails on 8.10.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2 |
| 8.9.0 | class absent | no AutomatonToTokenStream in lucene-core (the probe does not compile) |
647255b4d29b (#157) | introducing commit | created the class with the unguarded indegree[0] read (git blame) |
upstream main 2f424fd428d and f815e679bf6 (2026-11-01), branch_11x, branch_10_6 | read | the same unguarded read (source read, not executed) |
Confirmed by an independent reproducer, an intended-behaviour devil's advocate, a reviewer from another model family (OpenAI GPT-5.6) and an adjudication (high confidence). A second cross-model review gave no usable verdict because it could not run any command. This doc's gradle run validated the fix.
Checks and verdicts313 words
Eight checks; none disputed the root cause.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Its own 6-test JUnit outside org.apache.lucene fails 3 of 6 on main with assertions on and off, on 10.5.2 and on 9.12.3 (makeEmpty(), minus of equal languages, removeDeadStates of a dead start); the 1-dead-state, makeEmptyString() and makeString("abc") controls pass; with the fix 6 of 6 pass. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium confidence | Rated the intended-behaviour argument weak and the inputs within the contract; separate runs of the finder's JUnit fail on main and 10.5.2. |
| intended-behaviour devil's advocate | real, low severity | Found 9 public ways to a 0-state automaton, all failing, and answered the "no start state", "test-only utility" and "a token stream cannot express the empty language" arguments. |
| cross-model review, refute lens (OpenAI GPT-5.6) | no usable verdict | It could not run any command, so its "not real, low" is procedural; a separate re-run of the repro failed. A supplementary read-only review of the evidence: real, high confidence, root cause and fix correct. |
| adjudication | confirmed, high confidence, crash | Re-ran the independent reproduction's JUnit with assertions on and off and the finder's with assertions on (fail); held that a fix may return an empty stream or throw an IllegalArgumentException. |
| audit | confirmed, low priority | Re-ran the finder's JUnit on main with assertions off (fails); "a real but very small robustness bug in a test-oriented utility". |
| minimal repro | verified | Reduced to one test on Automata.makeEmpty(); fails on main 645d4fe14a20 with assertions on and off, passes with the fix shadowed. |
| brief validation (gradle) | fix A validated | Repro fails on stock main with assertions on and off and passes with fix A; the core analysis tests, TestFlattenGraphFilter and core's static checks pass; fix B passes when shadowed into the stock jars. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 411 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,159 words
- Registry title
- AutomatonToTokenStream.toTokenStream throws ArrayIndexOutOfBoundsException ('Index 0 out of bounds for length 0') on a 0-state automaton, Lucene's standard empty-language value (Automata.makeEmpty(), or an empty Operations result such as intersection("a", "b"))
- Area
- core / analysis: AutomatonToTokenStream (automaton to token-graph conversion)
- Priority
- Low, rank 1144: It is the same loud 0-state ArrayIndexOutOfBoundsException as LFV-029 but in the test-oriented AutomatonToTokenStream converter with no production caller.
- Impact class
- crash
- Impact note
- Code that converts an automaton with the public lucene-core utility AutomatonToTokenStream.toTokenStream and passes an empty-language automaton in its 0-state form (Automata.makeEmpty(), Automata.makeStringUnion of an empty list, RegExp "#", or an empty result of Operations.intersection, minus or removeDeadStates) gets an ArrayIndexOutOfBoundsException instead of an empty stream or a clean IllegalArgumentException; the failure is immediate and loud, nothing is corrupted or persisted, no setting is involved, the converter has no in-tree production caller (tests only) and no downstream use was found, in every release since 8.10.0 (executed).
- Summary
- You convert an automaton whose language is empty, for example Automata.makeEmpty() or Operations.intersection(Automata.makeString("a"), Automata.makeString("b")), with AutomatonToTokenStream.toTokenStream, whose only stated precondition is a finite DAG. You expect a TokenStream with no tokens (what the same method already returns for Automata.makeEmptyString() and for the same empty language written with one dead state) or at least a clear IllegalArgumentException. Instead it throws ArrayIndexOutOfBoundsException 'Index 0 out of bounds for length 0', because these automata have 0 states and the method reads indegree[0], the in-degree of the start state, without checking that a state exists.
- Introduced
- 647255b4d29bb56ddcfdf44bdb6e7d5d0ca76a14 (apache/lucene#157, LUCENE-9963 'Improve FlattenGraphFilter's robustness when handling incoming token graphs with holes', author @glawson0, merged by @mikemccand), which created AutomatonToTokenStream as a helper for the FlattenGraphFilter tests with the unguarded 'if (indegree[0] != 0)' read and the 'new int[transitions.length]' allocation already in place; 8.x backport 75eba3892979 (apache/lucene-solr#2551, branch_8x) has the same read. [read: git blame -w -C -M of main lines 52-63 and git log --follow of the file; exec: 8.9.0 has no class, 8.10.0 fails]. Not a regression: the crashing lines never changed; the pre-10.0 Operations.isFinite pre-check did not catch the input (isFinite returns true for 0 states) and was removed by 15f3743f02c (#11813, first released in 10.0.0) without changing the outcome. (2021-08-09 (647255b4d29b, author date 2021-08-10 05:06:53 +0900 = 2021-08-09T20:06:53Z); 8.x backport 2021-08-16 (75eba389297))
- First affected version
- 8.10.0 [exec] (the first release with AutomatonToTokenStream; lucene-core 8.9.0 has no such class [exec: compile error]); 9.0.0 on the 9.x line
- Affected versions
- Every release that has the class (the 40 from 8.10.0 to 10.5.2, and 10.6.0), all executed and failing with the same exception at the indegree[0] line: 8.10.0, 8.10.1, 8.11.0-8.11.4, 9.0.0-9.12.3 (21 releases), 10.0.0-10.5.2 (12 releases) [exec: a core-only main() probe on each; the finder's JUnit fails 2 of 3 on 8.10.0 (-ea, -da), 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2 (-ea, -da)]; branch_10_6 head 4ae946e5a9b (10.6.0) [exec, -da]; main a9779ef3c193 [exec, -ea and -da]. The independent reproduction's own JUnit fails on main, 10.5.2 and 9.12.3; the intended-behaviour check's probe on main, 10.5.2 and 9.12.3. Not fixed upstream: the newest commit to the file on main is 7335eb0ad96 (#15704, author date 2026-02-26), and the file at main head c5ab3e57b9b (2026-10-28) is byte-identical to the tested one [read]. Not affected: 8.9.0 and earlier (class absent) [exec 8.9.0]. All runs with JDK 25 on aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading
- Upstream and prior reports
- none found (searched 2026-10-28, 187 recorded queries: two scripted prior-report searches with 114 queries (46 GitHub issue/PR, 6 commit, 4 downstream-repository, 40 mailing-list on dev@, java-user@, issues@ and commits@, 8 JIRA-archive, 10 web), 33 manual GitHub searches (REST and GraphQL over apache/lucene, the archived lucene-solr repository, downstream projects and all of GitHub), 24 mailing-list and 5 JIRA queries; the changed files of all 410 open apache/lucene PRs; the upstream commit history of the file on main, branch_10_6, branch_10x and branch_9x by author date; the conversations of #157, #146, #11002 and #15704 read in full). Every hit that names the class is #157 (LUCENE-9963, which introduced it) or a commit notification. Nearest items, not this bug: #11002 (an ArrayIndexOutOfBoundsException in RollingBuffer via FlattenGraphFilter, the bug #157 fixed), #14224, #3791, #13707, #14211 and #13706 (0-state or empty automata in other Operations and Automata methods), #9391 (the inverse converter TokenStreamToAutomaton). Recheck 2026-10-28 (read-only): a GraphQL search for AutomatonToTokenStream on apache/lucene returns only #157; none of the 11 open PRs created since 2026-10-26 touches an automaton or token-stream file; open #16816 changes AutomatonQuery, MultiTermQuery and FieldExistsQuery only; the newest commit to the file is still 7335eb0ad96 (author date 2026-02-26).
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone and through gradle; fix A in a scratch worktree with every core test class inorg.apache.lucene.analysis, analysis-common'sTestFlattenGraphFilterand core's static checks; fix B shadowed into the stock jars with the upstreamTestAutomatonToTokenStream. SHA-1-checked release jars: the minimal repro on 10.6.0 and 9.12.3; amain()probe on all 40 releases from 8.10.0 to 10.5.2 (8.9.0 has no such class).AutomatonToTokenStream.javais byte-identical at645d4fe14a20, the hunt commita9779ef3c193, upstream main2f424fd428d(2026-10-30),branch_11xand upstream mainf815e679bf6(2026-11-01) (read); the 10.6.0 tag differs only by an unrelated refactor.
- Finding record
lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java:40-47 (javadoc: 'This requires the automaton be a finite DAG', '@param automaton ... Must be a finite DAG to avoid infinite loops!'), :52-54 (indegree sized to transitions.length), :61 (unguarded indegree[0]), :62 (the IllegalArgumentException the line is meant to throw)lucene/core/src/java/org/apache/lucene/util/automaton/Automata.java:55-60 (makeEmpty: 'a new (deterministic) automaton with the empty language', 0 states); Automaton.java:37-38 ('State 0 is always the initial state')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java:40-47, :49-63, :65-91 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/automaton/Automaton.java:37-38, :43, :116-118; Automata.java:55-60; Operations.java:799-803 (at 645d4fe14a20)
- Who is affected
grep for AutomatonToTokenStream over lucene/ at 645d4fe14a20 (only the class, core TestAutomatonToTokenStream and analysis-common TestFlattenGraphFilter)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java:40-47, :61-63, :87-91 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/automaton/Automata.java:44, :55-60; Automaton.java:37-38, :43; Operations.java:56, :799-803, :1366-1368 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/analysis/TestAutomatonToTokenStream.java:105-136 (at 645d4fe14a20)
- Suggested fix
lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java:165-170 (TopoTokenStream.end, setOffset at :169, at 645d4fe14a20)
- Prior reports
a Lucene clone: git rev-parse <ref>:lucene/core/src/java/org/apache/lucene/analysis/AutomatonToTokenStream.java for 645d4fe14a20, origin/main 2f424fd428d, origin/branch_11x (blob 4f3a3aaf768), releases/lucene/10.6.0 and origin/branch_10_6 (blob 28493c168bc)
- History
lucene/CHANGES.txt (LUCENE-9963 under 8.10.0, at 645d4fe14a20)a Lucene clone: git diff releases/lucene/10.6.0 645d4fe14a20 -- AutomatonToTokenStream.java (only the #15704 refactor)
- TestAutomatonToTokenStreamZeroStates.java (JUnit, one test):
repro/LFV-865/src/org/apache/lucene/analysis/TestAutomatonToTokenStreamZeroStates.java(37 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-865/bug.png(411 KB)