To find a word's k synonyms, the provider asks the HNSW search for k + 1 hits (the word is its own nearest hit). It adds the 1 in int, never caps it at the model size, and the search reserves queues for every hit up front. So Integer.MAX_VALUE wraps to a negative size; huge values exhaust the heap.
- You give the filter a word2vec model: a list of words, each with a vector. For every token that is in the model, the filter adds the model's most similar words as synonyms at the same position.
- Two settings limit that:
minAcceptedSimilarity(default 0.8), how similar a synonym must be, andmaxSynonymsPerTerm(default 5), the most synonyms per token. - The similar words come from an HNSW nearest-neighbour search over the model's vectors. The search keeps its candidates in two priority queues sized for the number of hits it is asked for.
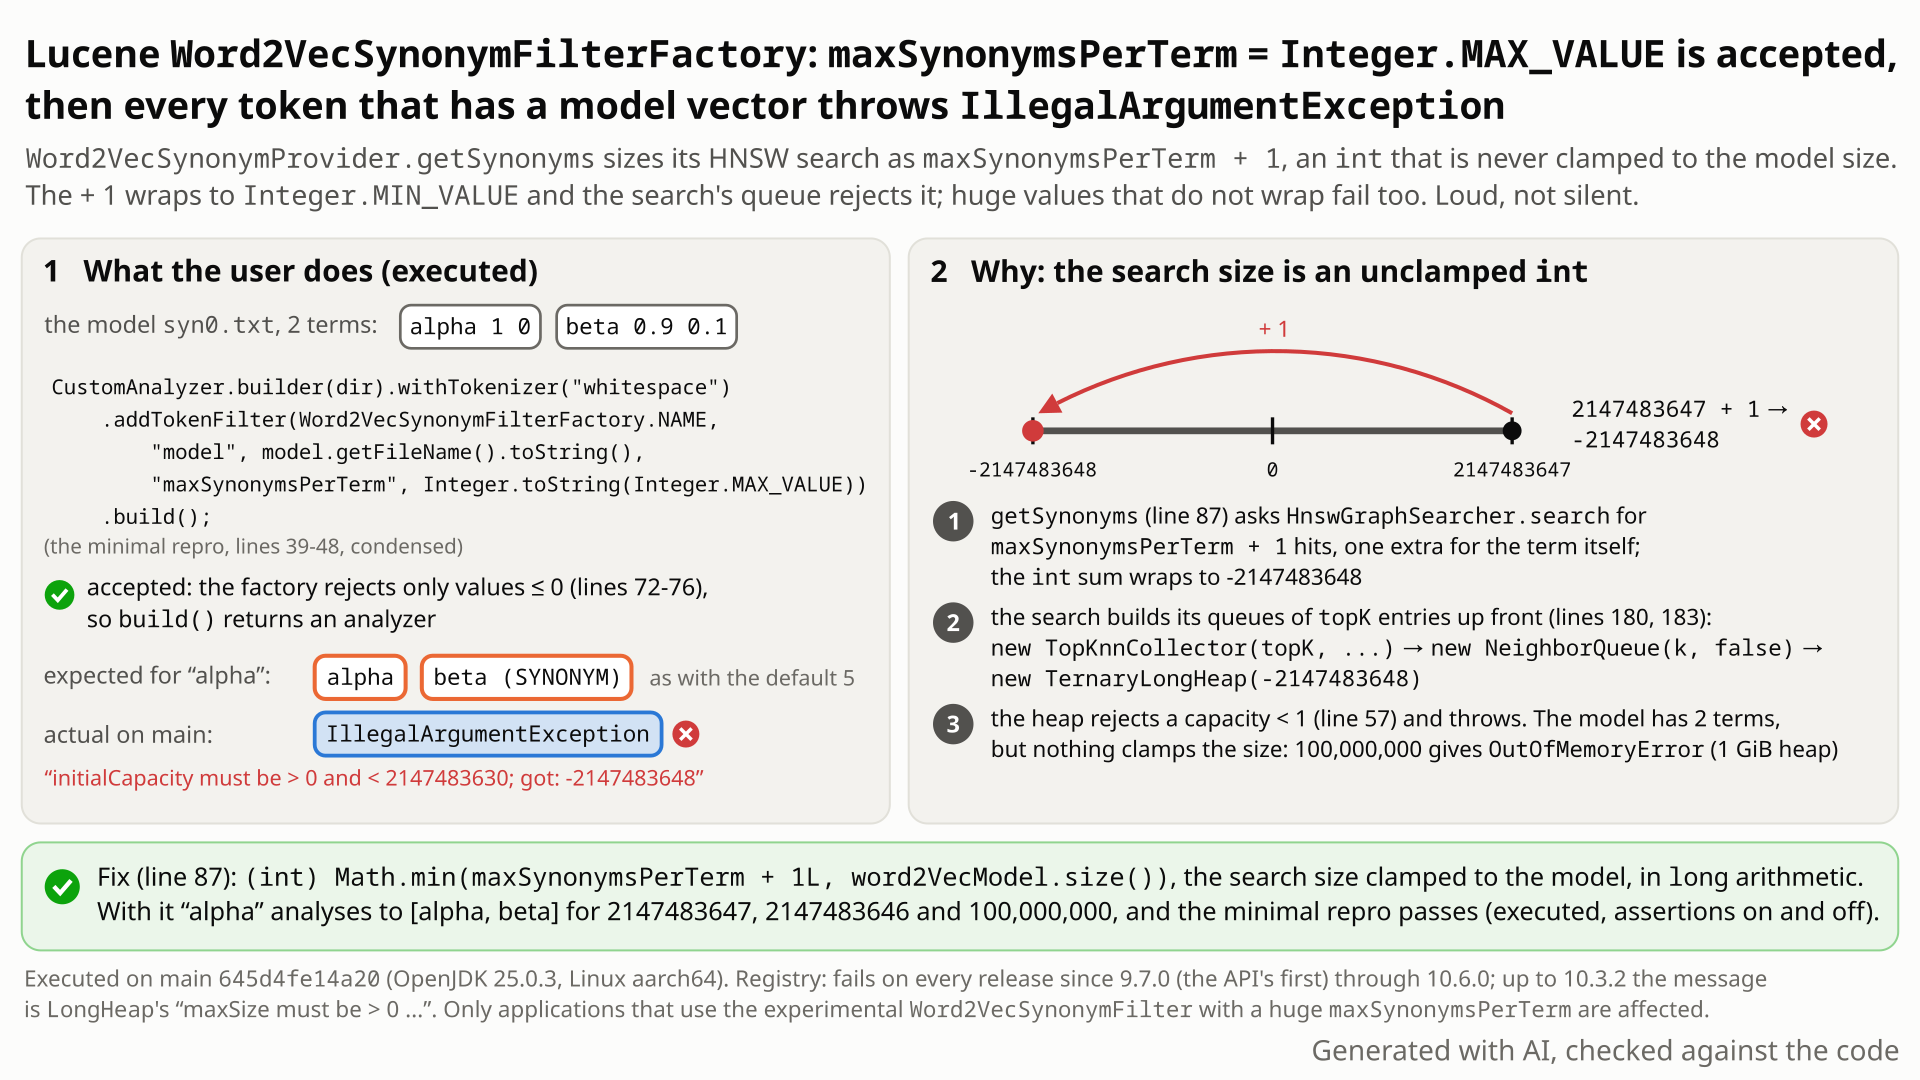
maxSynonymsPerTerm = 2,147,483,647, whose search size k + 1 wraps to -2,147,483,648 in an int, so the first in-model word throws. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
CustomAnalyzerwith theWord2VecSynonymfilter over a 2-word model,alpha= (1, 0) andbeta= (0.9, 0.1), and setmaxSynonymsPerTermto 2,147,483,647 (Integer.MAX_VALUE): "no count cap, the similarity threshold decides". The factory accepts it; it rejects only values <= 0. - You expect
alphato analyse to[alpha, beta]:betascores 0.9969 againstalpha(the provider uses (1 + cosine) / 2, and the cosine is about 0.994), above the default threshold 0.8, and that is what the defaultmaxSynonymsPerTermof 5 gives. - Instead the analyzer builds, and analysing
alphathrowsIllegalArgumentException: initialCapacity must be > 0 and < 2147483630; got: -2147483648. To find k synonyms the provider searches for k + 1 hits (the word is its own nearest hit), and 2,147,483,647 + 1 wraps in anintto -2,147,483,648. - The search reserves two queues of k + 1 entries before it starts, and nothing caps k + 1 at the model's 2 words. So values just below fail too: from 2,147,483,630 with the same exception, and from about 100 million at a 1 GiB heap with
OutOfMemoryError. - It fails at index and at query time, with assertions on and off, in every release that has the filter (9.7.0 to 10.6.0) and on main. Words without a vector, the default 5 and ordinary values never fail.
Applications that opt in to the experimental Word2VecSynonymFilter and set maxSynonymsPerTerm to Integer.MAX_VALUE (meant as "no cap") or to about 100 million or more (heap-dependent). Any model size, at index and at query time, from the first token that has a vector. The failure is loud: no wrong results, no index damage. The default 5 and ordinary values never fail.
Mechanism, terms and numbers670 words
Word2VecSynonymFilter (@lucene.experimental, since 9.7.0) adds, for every token that has a vector in a word2vec model, the model's most similar words as synonyms, at most maxSynonymsPerTerm of them (default 5) and only above minAcceptedSimilarity (default 0.8). Its factory rejects only maxSynonymsPerTerm <= 0, so Integer.MAX_VALUE, meant as "no count cap, let the threshold decide", builds an analyzer without complaint. On the first token that has a vector, Word2VecSynonymProvider.getSynonyms asks HnswGraphSearcher.search for maxSynonymsPerTerm + 1 hits (the query word is its own nearest hit). The sum is int arithmetic and is never capped at the model size, and the search allocates two queues of that many entries before it starts. At Integer.MAX_VALUE the + 1 wraps to -2,147,483,648 and the queue throws IllegalArgumentException: initialCapacity must be > 0 and < 2147483630; got: -2147483648; values from 2,147,483,630 throw the same exception without overflowing, and values from about heap-bytes/16 (1e8 at a 1 GiB heap) throw OutOfMemoryError, even for a 2- or 3-word model. The failure is loud and immediate, with no wrong results. It is in every release with the filter, 9.7.0 to 10.6.0, and on main 645d4fe14a20. Capping the search size at the model size, computed in long, fixes it; validated with gradle on 645d4fe14a20.
- Validation.
Word2VecSynonymFilterFactoryreads the value withgetInt(args, "maxSynonymsPerTerm", DEFAULT_MAX_SYNONYMS_PER_TERM)(Word2VecSynonymFilterFactory.java:53; the default is 5,:41) and rejects only<= 0: "maxSynonymsPerTerm must be a positive integer greater than 0. Found: ..." (:72-76). The factory is@lucene.experimentaland registered under the SPI nameWord2VecSynonym(:32-33,:39), soCustomAnalyzerand settings-driven analyzers reach it by name. - Per token.
Word2VecSynonymFilter.incrementTokencallsgetSynonyms(term, maxSynonymsPerTerm, minAcceptedSimilarity)for every token (Word2VecSynonymFilter.java:95-96). - The search size. Only a term that has a vector searches (
Word2VecSynonymProvider.java:78-79). ThenHnswGraphSearcher.search(scorer, maxSynonymsPerTerm + 1, hnswGraph, null, Integer.MAX_VALUE)(:83-90), under the comment "The query vector is in the model. When looking for the top-k it's always the nearest neighbour of itself so, we look for the top-k+1" (:85-86). The+ 1(:87) is plainintaddition (the shipped bytecode isiload_2, iconst_1, iadd), and nothing compares it withword2VecModel.size(). - Eager allocation. The static
HnswGraphSearcher.search(HnswGraphSearcher.java:177-186) buildsnew TopKnnCollector(topK, visitedLimit, null)(:180) andnew NeighborQueue(topK, true)(:183) before it searches; both create aTernaryLongHeap(topK)(TopKnnCollector.java:45,NeighborQueue.java:59-60). - The heap.
TernaryLongHeapthrowsIllegalArgumentExceptionfor a capacity< 1or>= ArrayUtil.MAX_ARRAY_LENGTH("Throw exception to prevent confusing OOME",TernaryLongHeap.java:57-63); otherwise it allocatesnew long[initialCapacity + 1](:66-68). Two such queues cost about 16 bytes per unit ofmaxSynonymsPerTerm, whatever the model size.
Boundary probes on main, assertions off, a 3-word model unless noted (the repro shows only the 2,147,483,647 row):
maxSynonymsPerTerm | first in-model token |
|---|---|
| 10, 1e7, 6e7 | works (one token: 46 ms at 1e7, 211 ms at 6e7; 1 GiB heap) |
| 1e8, 3e8, 2,147,483,628, 2,147,483,629 | OutOfMemoryError: Java heap space (1 GiB heap) |
| 1e8 / 1.5e8 | works, about 244 ms per token / OutOfMemoryError (2 GiB heap, earlier main) |
| 3e8 | OutOfMemoryError (4 GiB heap, earlier main) |
| 2,147,483,630 to 2,147,483,646 | IllegalArgumentException ... got: <k + 1>: no overflow, but at or above this JVM's ArrayUtil.MAX_ARRAY_LENGTH (2,147,483,631) |
| 2,147,483,647 | IllegalArgumentException ... got: -2147483648: the + 1 wraps |
| 6e7 / 1e8, 2,147,483,629 / 2,147,483,630 | the repro's 2-word model, through the factory, 1 GiB heap: works / OutOfMemoryError / IllegalArgumentException ... got: 2147483631 |
Tokens without a vector analyse fine, because no search runs. On 9.7.0 to 10.3.2 the message comes from LongHeap ("maxSize must be > 0 and < 2147483630; got: -2147483648"). The exact start of the IllegalArgumentException range depends on the JVM's maximum array length, and the OutOfMemoryError range on the heap: all thresholds are observations on one JVM and heap size. The rows at 2,147,483,629 and from 2,147,483,630 to 2,147,483,646 (3-word model) came from direct getSynonyms calls, endpoints only; single timings include building the analyzer.
Exposure and likelihood242 words
- Who is hit. Users of the
@lucene.experimentalWord2VecSynonymFilterwho configuremaxSynonymsPerTermasInteger.MAX_VALUE, the "no cap" value analysis-common itself uses as the default ofCapitalizationFilter'smaxWordCountandmaxTokenLength(CapitalizationFilter.java:34-35), or as any value from about 100 million up (heap-dependent). The default 5 and ordinary values (the upstream tests use at most 10) never fail. There is no evidence that anyone configures it this way (no public report). - Where. Index time and query-parse time, on the first token that has a vector, whatever the model size. Analyzers built by SPI name (
CustomAnalyzer, settings files) pass the value to the factory unchanged. - How it shows. An
IllegalArgumentExceptionthat names an internal heap and a negative capacity rather than the setting, or anOutOfMemoryError; both only after the analyzer was built without complaint. No wrong results and nothing written to the index. - A cost even when it works. Below the failure range every in-model token still allocates two queues sized by the setting rather than by the model: 1e7 is about 160 MB per token (arithmetic); one token took 46 ms on a 3-word model (a single timing that includes building the analyzer). The fix removes that too.
- How likely: rare (registry likelihood rare, priority low): only extremely large values trigger it (near
Integer.MAX_VALUE, or from about 100 million up, heap-dependent), and it shows on first use. No public report since 9.7.0 (2023) in a bounded search.
One JUnit method for lucene/analysis/common, public API only: a CustomAnalyzer with the Word2VecSynonym filter over a 2-word model and maxSynonymsPerTerm = Integer.MAX_VALUE, then assertAnalyzesTo on alpha. A rejection when the analyzer is built would also pass. Fixed input, single thread; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.synonym.word2vec;

import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;
import java.util.zip.ZipEntry;
import java.util.zip.ZipOutputStream;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.custom.CustomAnalyzer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestWord2VecLargeMaxSynonymsPerTerm extends BaseTokenStreamTestCase {

  public void testMaxIntMaxSynonymsPerTerm() throws Exception {
    Path dir = createTempDir();
    Path model = dir.resolve("max-synonyms-per-term-model.zip");
    try (ZipOutputStream zip = new ZipOutputStream(Files.newOutputStream(model))) {
      zip.putNextEntry(new ZipEntry("syn0.txt"));
      zip.write("2 2\nalpha 1 0\nbeta 0.9 0.1\n".getBytes(StandardCharsets.UTF_8));
    }
    Analyzer a;
    try {
      a =
          CustomAnalyzer.builder(dir)
              .withTokenizer("whitespace")
              .addTokenFilter(
                  Word2VecSynonymFilterFactory.NAME,
                  "model",
                  model.getFileName().toString(),
                  "maxSynonymsPerTerm",
                  Integer.toString(Integer.MAX_VALUE))
              .build();
    } catch (IllegalArgumentException rejectedAtConfiguration) {
      return;
    }
    try {
      assertAnalyzesTo(a, "alpha", new String[] {"alpha", "beta"});
    } catch (IllegalArgumentException e) {
      // expected: alpha plus its synonym beta (cosine 0.99), or a rejection at configuration time
      throw new AssertionError("expected [alpha, beta], got " + e, e);
    }
    a.close();
  }
}
cp $REPRO/TestWord2VecLargeMaxSynonymsPerTerm.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.synonym.word2vec.TestWord2VecLargeMaxSynonymsPerTerm -Ptests.seed=DEADBEEF
# fails the same way with -Ptests.asserts=false
- Expected
alphaanalyses to[alpha, beta], as with the defaultmaxSynonymsPerTermof 5, or the factory rejects the value when the analyzer is built.- Observed
- The analyzer builds, then analysing
alphathrowsIllegalArgumentException: initialCapacity must be > 0 and < 2147483630; got: -2147483648, with assertions on and off.
More files, environment, full output322 words
TestWord2VecLargeMaxSynonymsPerTerm (60 lines with the license header, one test method, package org.apache.lucene.analysis.synonym.word2vec like the upstream word2vec tests, but public API only). It writes a 2-word plain-text dl4j model (syn0.txt in a zip) into createTempDir(), builds the analyzer by SPI name and expects alpha to analyse to [alpha, beta]. If the factory rejected the value when the analyzer is built, the test would return early and pass, so a fix may take either route. Nothing depends on the seed.
This exact file ran unchanged on 9.7.0, 9.12.3, 10.0.0, 10.3.2, 10.4.0, 10.5.2, 10.6.0 and main (the other 18 releases ran the finder's longer test). It is also the regression test, except that :lucene:analysis:common:check rejects its named, unused catch parameter (ecj lint: the value of the exception parameter is not used) and accepts it written as _ (Lucene's convention on main); with _ the check passes, and the test passes with the fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also 10.6.0, 10.5.2, 10.4.0, 10.3.2, 10.0.0, 9.12.3 and 9.7.0 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the overflow does not depend on it; the 2,147,483,630 threshold comes from ArrayUtil.MAX_ARRAY_LENGTH, which depends on the JVM's array header size) |
cp $REPRO/TestWord2VecLargeMaxSynonymsPerTerm.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.synonym.word2vec.TestWord2VecLargeMaxSynonymsPerTerm -Ptests.seed=DEADBEEF
# fails the same way with -Ptests.asserts=false
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF (assertions on; -Ptests.asserts=false prints the same; module prefixes and the SeedInfo frame dropped)
TestWord2VecLargeMaxSynonymsPerTerm > testMaxIntMaxSynonymsPerTerm FAILED
    java.lang.AssertionError: expected [alpha, beta], got java.lang.IllegalArgumentException: initialCapacity must be > 0 and < 2147483630; got: -2147483648
        at org.apache.lucene.analysis.synonym.word2vec.TestWord2VecLargeMaxSynonymsPerTerm.testMaxIntMaxSynonymsPerTerm(TestWord2VecLargeMaxSynonymsPerTerm.java:56)

        Caused by:
        java.lang.IllegalArgumentException: initialCapacity must be > 0 and < 2147483630; got: -2147483648
            at org.apache.lucene.util.TernaryLongHeap.<init>(TernaryLongHeap.java:59)
            at org.apache.lucene.util.hnsw.NeighborQueue.<init>(NeighborQueue.java:60)
            at org.apache.lucene.search.TopKnnCollector.<init>(TopKnnCollector.java:45)
            at org.apache.lucene.util.hnsw.HnswGraphSearcher.search(HnswGraphSearcher.java:180)
            at org.apache.lucene.analysis.synonym.word2vec.Word2VecSynonymProvider.getSynonyms(Word2VecSynonymProvider.java:83)
            at org.apache.lucene.analysis.synonym.word2vec.Word2VecSynonymFilter.incrementToken(Word2VecSynonymFilter.java:96)
            ...
:lucene:analysis:common:test (FAILURE): 1 test, 1  failure

# 9.7.0 to 10.3.2 (LongHeap): IllegalArgumentException: maxSize must be > 0 and < 2147483630; got: -2147483648
# with the recommended fix: 1 test, 0 failures, assertions on and off- The factory checks this setting and accepts any value above 0; the javadoc calls it the "maximum number of result returned", nothing more.
- Lucene caps requested counts at what exists:
LeafReader.searchNearestVectorsdoesk = Math.min(k, size)before sizing the same collector. - Upstream tests pass 10 for 4- and 8-word models; nobody discussed large values when the
+ 1was added.
The full argument222 words
- Contract. The factory states the accepted domain in its own check: "maxSynonymsPerTerm must be a positive integer greater than 0" (
Word2VecSynonymFilterFactory.java:72-76);TestWord2VecSynonymFilterFactoryasserts only the rejection of 0 and -1. The filter javadoc: "@param maxSynonymsPerTerm maximum number of result returned by the synonym search" (Word2VecSynonymFilter.java:58), a cap on results, with no upper bound.package-info.java,CHANGES.txt:3610(GITHUB#12169, the only entry) andMIGRATE.mdsay nothing more. - A cap above the model size is an ordinary, tested input.
TestWord2VecSynonymFilterpasses 10 for an 8-word and a 4-word model (TestWord2VecSynonymFilter.java:85-97,:115-123). - Lucene caps requested counts, in the same kind of call.
LeafReader.searchNearestVectorsdoesk = Math.min(k, floatVectorValues.size())beforenew TopKnnCollector(k, ...)(LeafReader.java:288,:332,:376);IndexSearchercapsnumHits(IndexSearcher.java:597,:729). Where a setting drives an allocation, analysis code rejects too-large values when it is set:StandardTokenizer.setMaxTokenLengththrows aboveMAX_TOKEN_LENGTH_LIMIT(StandardTokenizer.java:98-99). - History. The
+ 1is in the first version (#12169,1f4f2bf5095, 2023); the 38 comments, 33 review comments and 5 review summaries (15 reviews, 5 with a summary) of #12169 do not discuss an upper bound, large values or overflow. - Why the tests never hit it. The word2vec tests use limits of at most 10, and
TestRandomChainsdraws randomintconstructor arguments from [-50, 50] only (TestRandomChains.java:176-179).
The devil's-advocate check276 words
The strongest "works as designed" case (the study's intended-behaviour checker, and the cross-model reviewer, which rated it "moderate"): the value is trusted configuration on an experimental filter; Integer.MAX_VALUE is not documented as an "unlimited" sentinel; maintainers have called a huge, eagerly allocated HNSW k a pattern to avoid (benwtrent on #11946: the queue "eagerly allocates a new long[heapSize]. This is VERY costly"; jpountz on #12679: k = Integer.MAX_VALUE "will not only run in O(maxDoc) time but also use O(maxDoc) memory. I don't think we should do this"); TestRandomChains bounds int arguments because the full range "could cause huge ram usage ... (e.g. allocate enormous arrays)"; and the failure is loud.
Why it fails: trust decides security, not validity (SECURITY.md:46: out-of-scope issues "are still valid bug reports and hardening suggestions"). A cap needs no sentinel: as a maximum, Integer.MAX_VALUE simply means no cap. The two maintainer remarks are about Lucene's own designs and about exactly the eager allocation the clamp removes; neither speaks to an accepted value overflowing into a negative capacity. The TestRandomChains TODO records a test gap (its neighbour TODO for char says "fix any filters that care to throw IAE instead"). And the error arrives at analysis time, after the analyzer was built, naming an internal heap. Verdict: not intended; the case reduces to severity, which is why the bug is Low priority.
Contested. An independent fact check by a reviewer from another model family (OpenAI GPT-5.6, reading only) judged it noise ("needs absurd parameters and then fails loudly"), at most low-priority hardening. The tie-breaker kept it: as a cap, Integer.MAX_VALUE is the plain "no cap" value, not an absurd one.
Recommended Cap the HNSW search size at the model size, computed in long
Cap the search size at the model size and add the 1 in long: (int) Math.min(maxSynonymsPerTerm + 1L, word2VecModel.size()), a one-line change in Word2VecSynonymProvider. Validated with gradle: the repro passes with assertions on and off, the word2vec tests and the whole analysis-common test task pass, and so does check once the test's unused catch parameter is named _.
              // The query vector is in the model. When looking for the top-k
              // it's always the nearest neighbour of itself so, we look for the top-k+1
              // never more than the model holds (also avoids int overflow of the + 1)
              (int) Math.min(maxSynonymsPerTerm + 1L, word2VecModel.size()),
All options and trade-offs3 options · 610 words
One fix was built and validated; two alternatives were considered and not built.
Cap the HNSW search size at the model size, computed in long (validated by the checks) (recommended)
In Word2VecSynonymProvider.getSynonyms (Word2VecSynonymProvider.java:87), pass (int) Math.min(maxSynonymsPerTerm + 1L, word2VecModel.size()) instead of maxSynonymsPerTerm + 1. The search can never return more hits than the model has words, so output is unchanged whenever maxSynonymsPerTerm + 1 fits in the model, and above that the extra queue room could never be filled. It removes the overflow and the allocation sized by the setting. The same pattern as LeafReader.searchNearestVectors (k = Math.min(k, size)).
              // The query vector is in the model. When looking for the top-k
              // it's always the nearest neighbour of itself so, we look for the top-k+1
              // never more than the model holds (also avoids int overflow of the + 1)
              (int) Math.min(maxSynonymsPerTerm + 1L, word2VecModel.size()),
Trade-offs
- Large models. With the clamp,
Integer.MAX_VALUEmeans "every word above the threshold", so each in-model token of a large model searches for the whole model: two queues of model-size entries (about 16 bytes per word) and a walk over most of the graph (arithmetic, not executed). Correct, but slow for models with millions of words; it is the cost of the request itself, and the same as setting the value to the model size today. - The sibling bug LFV-862 (the provider can return k + 1 synonyms when the query word is missing from its own hits) is not fixed by this; its fix caps the result loop, a different line, and the two compose.
What the checks validated
Gradle in a scratch worktree of 645d4fe14a20, OpenJDK 25.0.3: stock, the repro fails with assertions on and off (1 test, 1 failure each). With the fix:
- the repro passes, assertions on and off (1 test, 0 failures each);
- the word2vec test package with the repro: 5 classes, 22 tests, 0 failures, assertions on (seed DEADBEEF) and off (seed 5EED0866);
- the whole
:lucene:analysis:common:testtask with the repro added, assertions on: 340 classes, 1,910 tests, 0 failures (18 skipped by the module itself); :lucene:analysis:common:check -x test(google-java-format, ecj lint, forbidden APIs, license checks) with the fix and the repro, its catch parameter named_: passes (with the name used in the repro file,ecjLintTestrejects the unused exception parameter).
Earlier, the same clamp passed the independent reproduction's 4-test class (4 of 4) and the 21 upstream word2vec tests through the repro runner.
Not built. Gives a configuration-time error instead of an analysis-time one.
Trade-offs
The factory constructor does not know the model size (the model is loaded later, in inform), so the bound would be a fixed constant such as ArrayUtil.MAX_ARRAY_LENGTH - 2: that removes only the IllegalArgumentException range, not the OutOfMemoryError one, and it does not protect code that builds Word2VecSynonymFilter or calls getSynonyms directly (neither validates the value). Rejecting values above the model size instead would turn a sensible "no cap" setting into an error. Possible as an addition to the clamp, not instead of it.
Not built. Start the TopKnnCollector and NeighborQueue heaps small and let them grow.
Trade-offs
Would replace the up-front allocation sized by k with growth bounded by what the search actually collects, for every caller of HnswGraphSearcher.search (on a large graph the queues can still grow large), but would not fix the overflow at Integer.MAX_VALUE (the capacity is already negative when it arrives), and it touches the kNN hot path, so it needs benchmarks. Out of proportion for this bug.
Analyzers built from settings by SPI name (Word2VecSynonym, as CustomAnalyzer does) hand maxSynonymsPerTerm to the factory unchanged, so a configured 2147483647 fails there the same way.
While building a check that compares the provider's HNSW synonyms with an exact cosine reference, the finder read getSynonyms and saw the + 1 with no cap. A boundary probe through the factory confirmed it (5 and 1,000,000 work; 2,147,483,646 and 2,147,483,647 throw), and a public-API JUnit failed on the stock main jars.
The method in full130 words
Method: non-formal (a hunt unit for the word2vec synonym provider, 2026-10-28, main a9779ef3c193).
- Context. The unit built a translation-validation harness: the provider's HNSW-based synonyms against an exact cosine ranking over the same model.
- First signal. Reading
Word2VecSynonymProvider.getSynonymsfor that harness, the finder noticed that the k + 1 self-hit expression is plainintaddition and is never capped at the model size, while the factory accepts any positive value. - Probe. Through the factory on the stock jars:
maxSynonymsPerTerm5 and 1,000,000 return[alpha, beta]; 2,147,483,646 and 2,147,483,647 throwIllegalArgumentExceptionfromTernaryLongHeap. - JUnit. A public-API test then failed on main,
branch_10_6, 10.5.2, 10.0.0, 9.12.3 and 9.7.0, and an independent reproducer measured theOutOfMemoryErrorrange. The minimal-repro step reduced the test to one method over a 2-word model.
No prior report found (2026-10-28, rechecked 2026-10-31) in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream trackers or the web. Closest: #12169 introduced the code without discussing an upper bound; #11387 hit the same heap-capacity exception from k = 0 on the kNN query path (fixed 2022).
Searches5 searches
Related, not reports of this bug: #12169 and #12168 (the origin; nobody discussed an upper bound, large values or overflow); #11387 / LUCENE-10351, fixed by #580 in 2022 (the same heap-capacity exception, from k = 0 on a fully deleted segment, on the kNN query path); #12255 (NeighborQueue sizing for performance; no unbounded k); #11946, #12679 and #12579 (maintainers on the cost of a huge, eagerly allocated kNN k, general context); #15140 / #15163 (added TernaryLongHeap, the source of today's message); elastic/elasticsearch#154480 (an analogue: bounds MinHash filter parameters against OOM). Open PRs #16806, #16815 and #16847 edit HnswGraphSearcher.search or the provider but keep the topK sizing, so a fix PR may need a rebase; #12433 (open draft) touches the filter boost only. Tracking issue #16937 and its dev@ thread have no outside reply about word2vec. Gaps: GitHub search does not index PR diffs or inline review comments; some generic queries read only the first page; private reports cannot be seen.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits; downstream (Solr, Elasticsearch, OpenSearch) | 2026-10-28; rechecked 2026-10-31 | three scripted prior-report search runs (3 x 59 queries) and 26 manual GitHub searches, for example maxSynonymsPerTerm (0 results), "initialCapacity must be" (0), word2vec synonym, HNSW topK sizing | no report; only the related items above |
| Review threads and open PRs | 2026-10-28 to 2026-10-31 | 380 comments read (#12168, #12169, #12246, #12255, #12257 and the authors' fork PRs); the changed files of all 410 open PRs; every issue and PR updated since 2026-10-27 | no discussion of an upper bound; #16806, #16815, #16847 touch the code but keep the sizing |
| Mailing lists | 2026-10-28 to 2026-10-31 | dev@, java-user@, issues@ and commits@ through the tool (60 queries), 18 manual queries, 21 mails read | no report |
| JIRA archive | 2026-10-28 to 2026-10-31 | 6 LUCENE/SOLR queries plus 3 controls, and the tool's JIRA queries (the filter postdates the JIRA migration) | no report |
| Web | 2026-10-28 to 2026-10-31 | 13 web queries plus the authors' three blog posts | no report |
Introduced with the filter itself by #12169 (1f4f2bf5095, 2023-04-24); first release 9.7.0. Every release with the filter, 9.7.0 to 10.6.0 (25), and main fail the repro; only the message changed in 10.4.0, when the HNSW queue moved to TernaryLongHeap.
Versions tested6 rows
Introduced: 1f4f2bf5095 on main, "Introduced the Word2VecSynonymFilter (#12169)" (feature issue #12168; author Daniele Antuzi, co-author Alessandro Benedetti), 2023-04-24. Both halves, the unclamped + 1 and the <= 0-only check, are in the first version (git log -S, git blame). On branch_9x it shipped through the re-backport 64b48b89b50 (committed 2023-05-30); an earlier cherry-pick was reverted on 2023-04-25 and never released. 9.6.0 has no synonym.word2vec package.
Later edits around the call (#12235, #12246, #12366, #12434, #12529, #12651, #13288, #15704) changed the search API and the heap class but kept maxSynonymsPerTerm + 1 verbatim. NeighborQueue moved from LongHeap to TernaryLongHeap in #15163 (first in 10.4.0), which changed only the message. The OutOfMemoryError range was measured on main only; on older releases it follows from the same eager allocation. Not fixed upstream: no commit on the word2vec package, HnswGraphSearcher, TopKnnCollector, NeighborQueue or TernaryLongHeap from 645d4fe14a20 to 2f424fd428d (2026-10-30).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | this doc's repro fails through gradle, assertions on and off; also through the standalone runner (re-verifier and tie-breaker, new seeds) |
| 10.6.0, 10.5.2, 10.4.0 | affected | the repro fails (10.6.0 and 10.5.2 with -ea and -da): "initialCapacity must be > 0 and < 2147483630; got: -2147483648" (TernaryLongHeap) |
| 10.3.2, 10.0.0, 9.12.3, 9.7.0 | affected | the repro fails (9.7.0 with -ea and -da): "maxSize must be > 0 and < 2147483630; got: -2147483648" (LongHeap); a control with the default 5 passes on 9.7.0 |
| the other 18 releases from 9.8.0 to 10.5.1 | affected | the finder's longer test (3-word model, same value) fails on each |
| 9.6.0 | API absent | no synonym.word2vec package; the repro does not compile |
main 645d4fe14a20 + the clamp | not affected | the repro, the word2vec tests and the whole analysis-common test task pass |
An independent reproducer, a devil's advocate, an adjudication, a credibility audit, a re-verifier and a tie-breaker agree it is real; a reading-only review by another model family (OpenAI GPT-5.6) returned a procedural "not real, low" while agreeing on the root cause. This doc re-ran the repro on 645d4fe14a20 and validated the fix with gradle.
Checks and verdicts454 words
The only cross-model review was reading-only: it could not run any command, so it could not run Java. It returned a procedural "not real, low", agreed on the root cause and that the input is in contract, rated the intended-behaviour case "moderate", and called its verdict "not a substantive refutation"; a separate re-run of the repro on 10.5.2 executed and failed 1 of 1 with the same exception (it reproduced the bug).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Boundary probe through the factory; public-API JUnit fails on main, branch_10_6, 10.5.2, 10.0.0, 9.12.3 and 9.7.0; the clamp passes it and the 21 upstream word2vec tests. |
| Independent reproducer | real | Own 4-test JUnit (Integer.MAX_VALUE and Integer.MAX_VALUE - 1 through the factory, a direct provider call, a passing control with limit 10 above the model size) fails 3 of 4 on main, 10.5.2, 9.12.3 and 9.7.0; measured the OutOfMemoryError range at 2 GiB; the clamp passes 4 of 4. |
| cross-model review, refute lens | not real, low (procedural) | OpenAI GPT-5.6, reading-only; agrees on the root cause and that the input is in contract; "not a substantive refutation". |
| Intended-behaviour devil's advocate | real, low impact | Built the strongest "works as designed" case and showed it reduces to severity; OutOfMemoryError probe at 1 and 4 GiB. |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit with a new seed: 3 of 4 fail with assertions on and off. |
| credibility audit | keep | Re-ran with assertions off; checked the priority, the overlap with neighbouring findings and the security call. |
| re-verifier and tie-breaker | real | On 645d4fe14a20: the minimal test fails on main and 10.5.2 with -ea and -da (new seeds); the boundary probes re-run; the clamp passes the repro, the independent reproduction's class and the 21 upstream tests. |
| this doc | real; fix validated | Gradle in a fresh worktree of 645d4fe14a20: the repro fails stock and passes with the clamp, assertions on and off; module tests and check pass. |
| fact check of this doc | holds, after two wording fixes | The doc's gradle command on a clean copy of 645d4fe14a20 fails 1 of 1 with assertions on and off and passes with the fix; the runner fails on main, 9.7.0 and 10.6.0 and the default-5 control passes; on the 2-word model through the factory at a 1 GiB heap, 6e7 works, 1e8 and 2,147,483,629 run out of memory and 2,147,483,630 throws. |
| cross-model fact check | facts hold; judges it noise | OpenAI GPT-5.6, reading only, ran no Java. Confirms the mechanism, the version range and that it is not security-sensitive; its two wording errors were fixed and its six overclaims addressed. Judges the bug noise (see the counter-case above). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 530 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,252 words
- Registry title
- Word2VecSynonymFilterFactory accepts any positive maxSynonymsPerTerm, but Word2VecSynonymProvider sizes its HNSW search as maxSynonymsPerTerm + 1 with no clamp to the model size, so very large values (Integer.MAX_VALUE, where the + 1 overflows) make every in-model token throw IllegalArgumentException or OutOfMemoryError
- Area
- analysis-common / synonym.word2vec (Word2VecSynonymProvider.getSynonyms search size; Word2VecSynonymFilterFactory validation)
- Priority
- Low, rank 897: Integer.MAX_VALUE as the 'no limit' maxSynonymsPerTerm makes the experimental opt-in Word2VecSynonymFilter fail loudly on the first in-model token, the same MAX_VALUE-as-limit loud boundary class as LFV-182.
- Impact class
- crash
- Impact note
- Only applications that opt in to the @lucene.experimental Word2VecSynonymFilter and set maxSynonymsPerTerm very large are hit (Integer.MAX_VALUE, for example meant as 'no count limit', or roughly heap-bytes/16 and up): the analyzer builds, then every analysis of a token that has a model vector, at index time or query-parse time, throws IllegalArgumentException (values near Integer.MAX_VALUE, from 2147483630 on the JVM measured) or OutOfMemoryError (measured from 1e8 at a 1 GiB heap, 1.5e8 at 2 GiB, 3e8 at 4 GiB, on a 3-term model); the failure is loud, not silent; every release since 9.7.0.
- Summary
- You configure Word2VecSynonymFilterFactory with maxSynonymsPerTerm=2147483647 (Integer.MAX_VALUE), which its validation accepts ('must be a positive integer greater than 0'), to keep every synonym above minAcceptedSimilarity, and you expect those synonyms or a rejection at configuration time. The analyzer builds, but Word2VecSynonymProvider.getSynonyms passes maxSynonymsPerTerm + 1 (int arithmetic) as topK to HnswGraphSearcher.search, which wraps to Integer.MIN_VALUE, so the first token with a model vector throws IllegalArgumentException 'initialCapacity must be > 0 and < 2147483630; got: -2147483648' from TernaryLongHeap (on 9.7.0 to 10.3.2: 'maxSize must be > 0 ...' from LongHeap). Because the search size is never clamped to the model size and the search allocates its queues of topK entries up front, values close to Integer.MAX_VALUE fail the same way and values from roughly heap-bytes/16 up (1e8 at a 1 GiB heap) throw OutOfMemoryError, even for a 3-term model.
- Introduced
- 1f4f2bf50957ad1a13c32d5351c7de77154953f1 on main (apache/lucene#12169 'Introduced the Word2VecSynonymFilter', feature issue #12168; author dantuzi, co-author Alessandro Benedetti; first in 10.0.0) and its branch_9x re-backport 64b48b89b501 (committed 2023-05-30, author date 2023-04-24; first in 9.7.0; an earlier backport 53709ccaecc was reverted by 7e15a390688 on 2023-04-25) [read: git log -S'maxSynonymsPerTerm + 1' on the provider lists only this commit; git blame on main a9779ef3c193 attributes the '+ 1' line (Word2VecSynonymProvider.java:87) and the factory's '<= 0' check (Word2VecSynonymFilterFactory.java:72-76) to 1f4f2bf5095, and blame on the 9.7.0 tag to 64b48b89b50; both halves of the defect are in the first version; exec: fails on 9.7.0, the first release with the API] (2023-04-24 (main 1f4f2bf5095); 2023-05-30 (branch_9x re-backport 64b48b89b50, author date 2023-04-24))
- First affected version
- 9.7.0 [exec] (the first release with the API; 9.6.0 has no synonym.word2vec package, the repro does not compile there [exec]); first on the main line: 10.0.0 [exec]
- Affected versions
- Every release that has the API: 9.7.0 to 9.12.3 and 10.0.0 to 10.5.2, 24 releases [exec: the finder's JUnit (maxSynonymsPerTerm = Integer.MAX_VALUE) fails 1 of 1 on each with -ea, also with -da on 9.7.0, 9.12.3 and 10.5.2; the independent reproduction's JUnit fails 3 of 4 on 10.5.2, 9.12.3 and 9.7.0], the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) [exec] and main a9779ef3c193 [exec: -ea and -da; re-run at the registration check]. Still present, unchanged, on upstream main c5ab3e57b9b (2026-10-28), branch_10x 1309534296e and branch_10_6 2763db11b0a [read]. The exception text follows the core heap class (LongHeap 'maxSize must be > 0 ...' on 9.7.0 to 10.3.2, TernaryLongHeap 'initialCapacity must be > 0 ...' from 10.4.0) [exec]. The OutOfMemoryError range was measured on main only; on older releases it is inferred from the same eager queue allocation in HnswGraphSearcher.search [read]. All runs on aarch64 Linux with JDK 25. Not affected: 9.6.0 and earlier (API absent).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only; refreshed at the registration check 2026-10-28): scripted prior-report search specs v1, v2 and v3 (3 x 51 queries: GitHub issue/PR, commit-message, downstream Elasticsearch/OpenSearch/Solr, dev@/java-user@/issues@/commits@ list, JIRA-archive and web queries; 0 high hits), 30 manual read-only GitHub searches (maxSynonymsPerTerm: 0 results; '"initialCapacity must be"': 0), file lists of the open PRs, the 38 review comments of #12169, the bodies and comments of #12168, #12246, #12255 and #12257, the dev@ thread on #12169, and the upstream commit lists of the word2vec package, HnswGraphSearcher, TernaryLongHeap, TopKnnCollector and NeighborQueue. Related, not this bug: #12169 (introduced the unclamped + 1 and the '<= 0' check; nobody discussed an upper bound), #11387 / LUCENE-10351 (same heap-capacity exception family from an HNSW heap sized from k = 0 on the kNN query path, fixed in 2022), #12433 (open draft, filter boost only), #16815 and #16847 (open; touch the provider file and the static HnswGraphSearcher.search but keep the topK sizing, so a fix PR may need a rebase). Refresh: the 30 newest PRs (to #16926) and the 15 newest issues (to #16928) have nothing on word2vec or HNSW search sizing; the newest commits on the word2vec package (7335eb0ad96, author date 2026-02-26) and on HnswGraphSearcher.java (59df9e799ce, author date 2026-01-16) do not touch it. Gaps: the GitHub search API was rate-limited during the refresh (core API only); keyword search reads only the first page per query; review comments of old PRs other than #12169 were not read exhaustively.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; runs of 2026-10-31) through gradle in a fresh scratch worktree, with assertions on and off; the recommended fix was validated there (the repro, the word2vec test package with assertions on and off, the wholelucene/analysis/commontest task,:lucene:analysis:common:check -x test). The minimal repro also ran through a standalone runner on645d4fe14a20, 10.6.0, 10.5.2, 10.4.0, 10.3.2, 10.0.0, 9.12.3 and 9.7.0 (SHA-1-checked release jars); the hunt and its first checks ran on maina9779ef3c193, whose word2vec sources andHnswGraphSearcher.javaare identical.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:70-105 (getSynonyms; HnswGraphSearcher.search call :83-90 with 'maxSynonymsPerTerm + 1' at :87, no clamp to word2VecModel.size())lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:32 (@lucene.experimental), :53 (getInt maxSynonymsPerTerm, default 5), :72-76 (only <= 0 rejected)lucene/core/src/java/org/apache/lucene/util/hnsw/HnswGraphSearcher.java:177-183 (static search: new TopKnnCollector(topK, ...) at :180 and new NeighborQueue(topK, true) at :183, both sized up front); lucene/core/src/java/org/apache/lucene/util/TernaryLongHeap.java:56-63 (IllegalArgumentException for initialCapacity < 1 or >= ArrayUtil.MAX_ARRAY_LENGTH)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:58 ('@param maxSynonymsPerTerm maximum number of result returned by the synonym search'), :96 (getSynonyms call)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:32-33, (at 645d4fe14a20) 39, 41-42, 53, 72-76lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:58, (at 645d4fe14a20) 95-96lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:78-90 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/hnsw/HnswGraphSearcher.java:177-186; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopKnnCollector.java:45; lucene/core/src/java/org/apache/lucene/util/hnsw/NeighborQueue.java:59-60; lucene/core/src/java/org/apache/lucene/util/TernaryLongHeap.java:56-68lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:45-46, (at 645d4fe14a20) 99 (DOT_PRODUCT score vs minAcceptedSimilarity); lucene/core/src/java/org/apache/lucene/index/VectorSimilarityFunction.java:59-62; lucene/core/src/java/org/apache/lucene/util/VectorUtil.java:461-462 ((1 + x) / 2)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java:34-35; (at 645d4fe14a20) CapitalizationFilterFactory.java:107-108lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymFilter.java:97, (at 645d4fe14a20) 123 (limit 10)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:72-76; (at 645d4fe14a20) Word2VecSynonymFilter.java:58; lucene/CHANGES.txt:3610lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymFilter.java:85-97, (at 645d4fe14a20) 115-123; TestWord2VecSynonymFilterFactory.java:132-156lucene/core/src/java/org/apache/lucene/index/LeafReader.java:288, (at 645d4fe14a20) 332, 376; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:597, 729; lucene/core/src/java/org/apache/lucene/analysis/standard/StandardTokenizer.java:98-99lucene/analysis.tests/src/test/org/apache/lucene/analysis/tests/TestRandomChains.java:176-179, (at 645d4fe14a20) 184Lucene main 645d4fe14a20 SECURITY.md:46
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:96-100 (at 645d4fe14a20) (inform loads the model)
- TestWord2VecLargeMaxSynonymsPerTerm.java (lucene/analysis/common, 1 test):
repro/LFV-866/src/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecLargeMaxSynonymsPerTerm.java(60 lines)
assets/LFV-866/bug.png(530 KB)