A word2vec model is a list of words, each with a vector. Word2VecModel keeps the vectors in an array, one slot per added line, and finds a word's slot through a hash that numbers distinct words 0, 1, 2. A repeated word takes a slot but gets no number, so the two numberings drift apart.
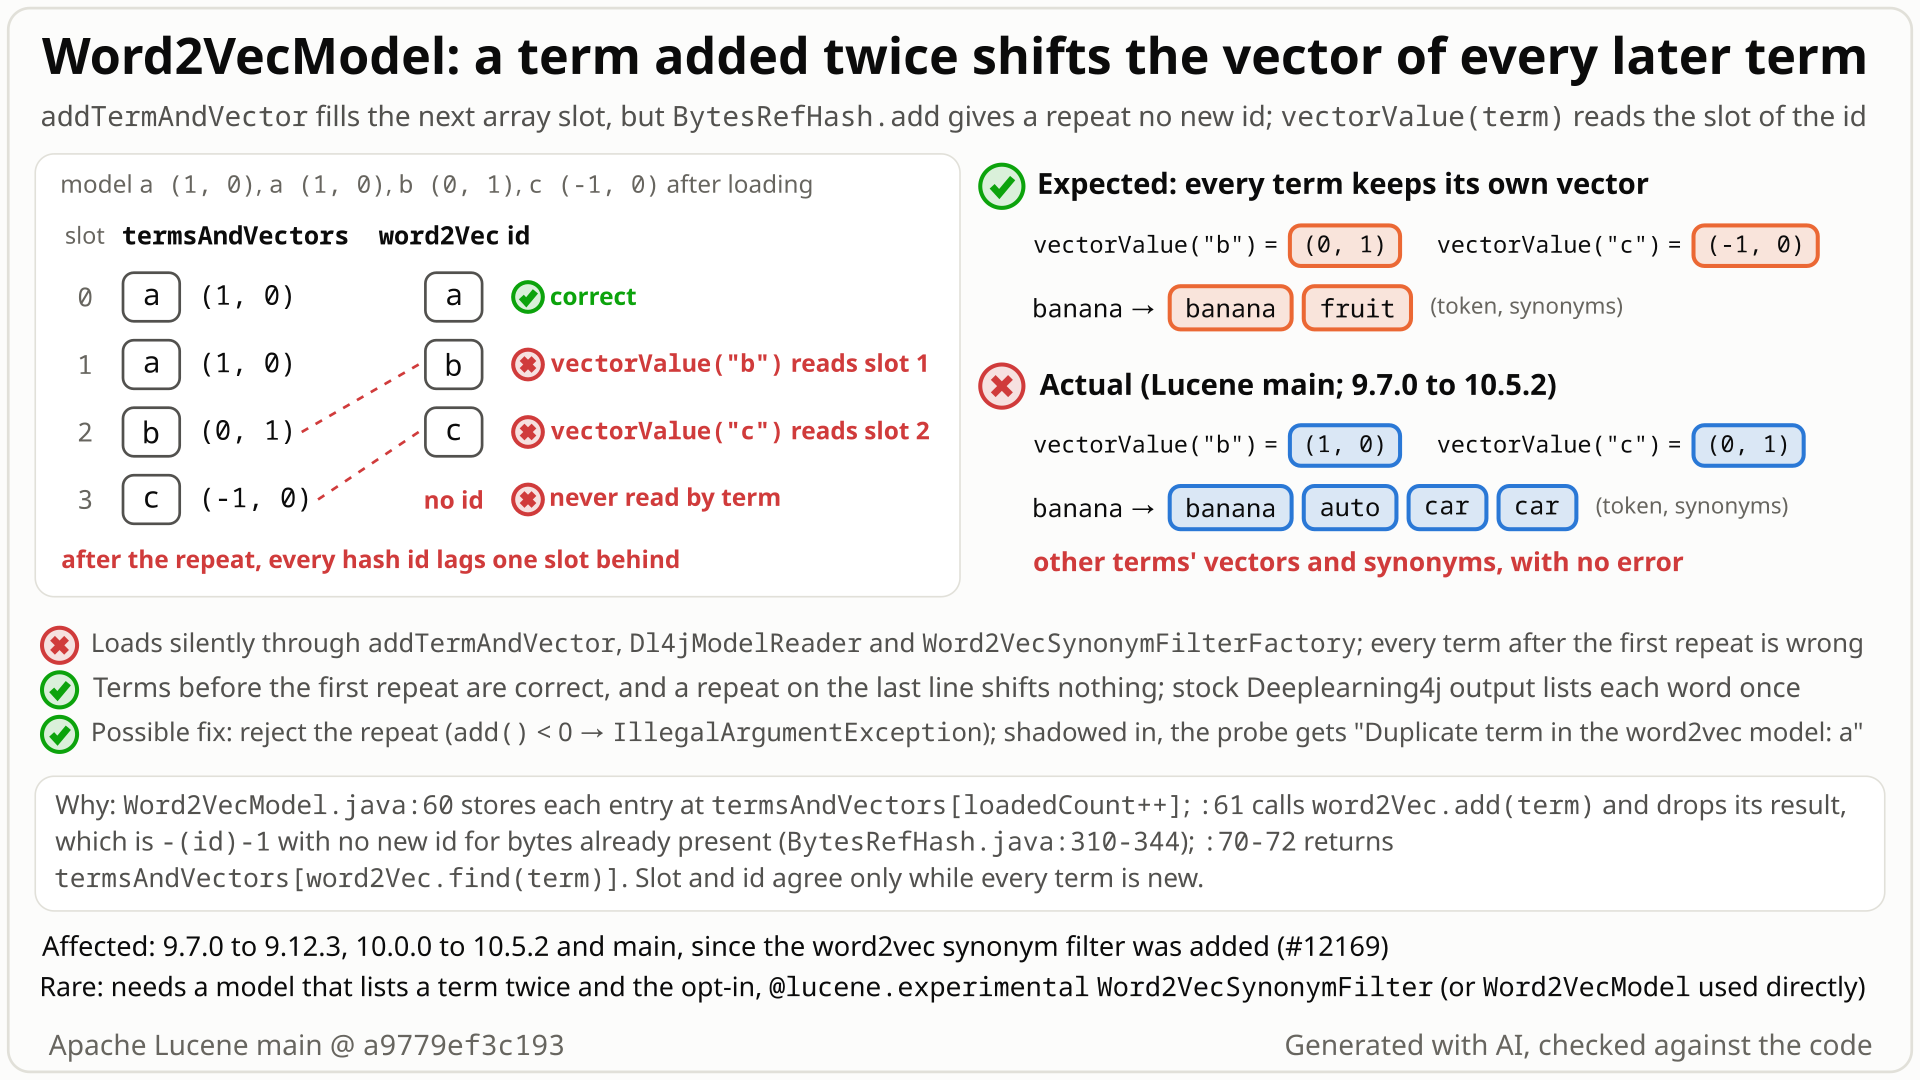
a, a, b, c model: array slots versus term-hash ids, and which vector each lookup returns after the repeat. Select the still to open it at full size. Generated with AI, checked against the code.- You build a
Word2VecModelfrom four lines,a (1,0),a (1,0)again,b (0,1)andc (-1,0), withaddTermAndVector. It accepts the repeat without any error or warning; a model file with a repeated word, such as the zip in step 4, also loads silently. - You expect each term to keep its own vector:
vectorValue("b")= (0,1) andvectorValue("c")= (-1,0). - Instead
vectorValue("b")= (1,0), a's vector, andvectorValue("c")= (0,1), b's. Each line gets the next array slot (0, 1, 2, 3), but the term hash numbers only new terms (a 0, b 1, c 2), and the lookup uses that number as the slot, so every term after the repeat reads one slot too early. - Through the filter with its defaults (5 synonyms, similarity 0.8), the model
car, car, auto, banana, fruitexpandsbananato[auto, car, car](cosines 0.20, 0 and 0 with banana) instead of[fruit](cosine 0.995). - Terms before the first repeat are fine, and a repeat on the last line shifts nothing; each further repeat shifts the later terms one more slot.
Only applications that opt in to the experimental Word2VecSynonymFilter, or use Word2VecModel directly, with a model that lists some term twice: a hand-built or converted model file, or code that calls addTermAndVector with a repeat. Stock Deeplearning4j output lists each word once. Every term after the repeat then gets another word's synonyms, silently.
Mechanism, terms and numbers715 words
Word2VecModel.addTermAndVector stores each entry at the next array slot (termsAndVectors[loadedCount++]) and calls BytesRefHash.add(term) without looking at its result (Word2VecModel.java:58-62 on main a9779ef3c193). vectorValue(BytesRef term) then reads the slot whose index is the term's hash id (:69-74). The two numbers agree only while every term is new: for a term that is already present, BytesRefHash.add allocates no id and returns -(id)-1, while the slot counter still advances. From then on, every later distinct term reads the slot one before its own line (one more slot back for each further repeat). For the model a (1,0), a (1,0), b (0,1), c (-1,0), vectorValue("b") returns (1,0) and vectorValue("c") returns (0,1). Through Word2VecSynonymFilterFactory with its defaults, a Deeplearning4j-format zip listing car, car, auto, banana, fruit loads without any error, and banana is expanded to [auto, car, car] instead of [fruit]. The trigger is a model that lists some term twice: a hand-built or converted model file, or code that calls addTermAndVector with a repeat; stock Deeplearning4j output lists each word once. Every release with the API is affected: 9.7.0 to 9.12.3, 10.0.0 to 10.6.0 and main.
- Word2vec model: a list of words, each with a vector.
Word2VecSynonymFilterlooks up a token's vector and emits the words whose vectors are nearest, found with an HNSW graph built over the model. - Slot: the position of an entry in
Word2VecModel's arraytermsAndVectors, one per added line. - Id: the number
BytesRefHashgives a distinct term: 0, 1, 2, ... in the order terms are first added.
addTermAndVector(Word2VecModel.java:58-62) normalizes the vector, stores the entry attermsAndVectors[loadedCount++]and callsword2Vec.add(term)without using the returned id.BytesRefHash.add(BytesRefHash.java:310-345) gives a new term the next id; for a term it already holds it allocates nothing and returns-(id)-1(javadoc:314-316).vectorValue(BytesRef term)(Word2VecModel.java:69-74) readstermsAndVectors[word2Vec.find(term)]: it uses the id as the slot.Word2VecSynonymProviderbuilds its graph over allsize()slots (Word2VecSynonymProvider.java:56-67;size()returns the header'sdictionarySize,Word2VecModel.java:86-88), takes the query vector fromvectorValue(term)(Word2VecSynonymProvider.java:78) and names each hit by slot withtermValue(id)(Word2VecSynonymProvider.java:97). So a later term is searched with the previous term's vector, while its own vector stays in the graph and can still come back as a synonym of other words.Dl4jModelReader.read()(Dl4jModelReader.java:64-81) adds every line of thesyn0file with no repeat check. Its only deliberate check is the vector dimension (:99-109). Other malformed files fail loudly but incidentally, with low-level exceptions: more lines than the header declares, fewer lines, or a plain-text first term shorter than 3 characters (StringIndexOutOfBoundsExceptionfrom the base64-prefix check,:73-75). So thea, a, b, cmodel loads from a file only with base64-encoded terms; the file example below usescar.
| line | slot written | add() returns | slot read by vectorValue(term) |
|---|---|---|---|
a (1,0) | 0 | 0 | a: slot 0, (1,0), correct |
a (1,0) | 1 | -1 (a already has id 0) | |
b (0,1) | 2 | 1 | b: slot 1, the second a, (1,0) |
c (-1,0) | 3 | 2 | c: slot 2, b's (0,1) |
When the capacity counts every line, as here, every index stays in bounds, so nothing fails. Each further repeat shifts the later terms one more slot.
| model | lookup or input | result on main | expected |
|---|---|---|---|
a (1,0), a (1,0), b (0,1), c (-1,0) | vectorValue("b"), vectorValue("c") | (1,0), (0,1) | (0,1), (-1,0) |
zip car, car, auto (0.98,0.2), banana (0,1), fruit (0.1,1), factory defaults (5, 0.8) | banana | [banana, auto, car, car] | [banana, fruit] |
red, red, green, lime, blue, navy through the filter (5, 0.8) | green, blue | [green, red, red], [blue, lime, green] | [green, lime], [blue, navy] |
pear, quince, pear, rhubarb | vectorValue("rhubarb") | pear's vector (quince, before the repeat, is correct) | rhubarb's |
In the banana row the synonyms are auto's nearest neighbours: cosines 0.20, 0 and 0 with banana, while fruit's is 0.995. The result is the same whether the 0.8 threshold applies to the cosine or to Lucene's (1 + cos) / 2 score. car appears twice because both lines got their own graph node; that comes from storing the repeat at all, not from the shift.
Exposure and likelihood280 words
- Who is hit. Users of the
@lucene.experimentalword2vec synonym support: theWord2VecSynonymfilter factory,Word2VecSynonymFilterwith aWord2VecSynonymProvider, orWord2VecModeldirectly. No default analyzer uses it. - The trigger. A model that lists some term twice, with at least one distinct term after it: a model file built or converted by hand or by a script (the reader accepts any
syn0file in Deeplearning4j's text layout; lower-casing a cased vocabulary while converting, which turnsCarandcarinto twocarlines, is one plausible way, not observed in a real file), or code that calls the publicaddTermAndVectorwith a repeat. - Not stock Deeplearning4j output. Its writer emits one line per vocabulary word, and Lucene's own sample model in the tests has 235 lines and 235 distinct words. Repeated words do occur in some word2vec-format files elsewhere: gensim's loader warns about them and keeps the first.
- What goes wrong. Every distinct term after the first repeat is looked up with another term's vector, so wherever the filter is configured (index or query time) it is expanded with that term's synonyms (the visible change can be small when the two vectors happen to be close). With one repeat early in a large vocabulary, that is almost the whole vocabulary. No error or warning.
- Not affected. Models with unique terms. Terms before the first repeat, and all terms when the only repeat is on the last line, keep their own vectors; the repeated line is still a graph node, so the repeated word can come back twice among other words' synonyms (the second
carabove). No index corruption and no exception; the only extra cost is one graph node per repeated line.
The test shows that after a term is added twice to a Word2VecModel, vectorValue of every later term returns the previous entry's vector (the repeat takes an array slot but gets no new BytesRefHash id).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.synonym.word2vec;

import java.util.Arrays;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;
import org.apache.lucene.util.TermAndVector;

public class TestWord2VecModelRepeatedTerm extends LuceneTestCase {

  public void testRepeatedTermKeepsLaterVectors() {
    Word2VecModel model = new Word2VecModel(3, 2);
    model.addTermAndVector(new TermAndVector(new BytesRef("a"), new float[] {1, 0}));
    try {
      model.addTermAndVector(new TermAndVector(new BytesRef("a"), new float[] {1, 0}));
    } catch (IllegalArgumentException rejectingTheRepeatIsAlsoCorrect) {
      return;
    }
    model.addTermAndVector(new TermAndVector(new BytesRef("b"), new float[] {0, 1}));
    float[] b = model.vectorValue(new BytesRef("b"));
    // expected b's own vector [0.0, 1.0]; actual a's vector [1.0, 0.0]
    assertTrue(
        "expected b's vector [0.0, 1.0], actual " + Arrays.toString(b),
        Arrays.equals(new float[] {0, 1}, b));
  }
}
# in a copy of this finding's repro folder (repro/LFV-867/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.synonym.word2vec.TestWord2VecModelRepeatedTerm
- Expected vs actual
- For the model [a(1,0), a(1,0), b(0,1)] expected
vectorValue("b")=[0.0, 1.0]; actual a's vector[1.0, 0.0], with-eaand-da(rejecting the repeat with IllegalArgumentException also passes).
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected b's vector [0.0, 1.0], actual [1.0, 0.0]
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.analysis.synonym.word2vec.TestWord2VecModelRepeatedTerm.testRepeatedTermKeepsLaterVectors(TestWord2VecModelRepeatedTerm.java:37)- The javadoc promises "the vectors for each word in dictionary", and an upstream test checks that
vectorValue(term)is that term's own vector. - No uniqueness rule is written, the damage hits terms listed once, and other malformed model files fail loudly.
- The introducing PR first used a
HashMap, correct for lookups; the switch toBytesRefHashdropped the idadd()returns.
The full argument268 words
- The contract. Class javadoc: "Word2VecModel is a class representing the parsed Word2Vec model containing the vectors for each word in dictionary" (
Word2VecModel.java:26-28). The upstream testTestWord2VecSynonymProvider.testModel_shouldReturnNormalizedVectors(TestWord2VecSynonymProvider.java:110-121) builds a model through the same public API and asserts thatvectorValue(term)is that term's normalized vector.BytesRefHash.adddocuments the negative return for bytes already present (BytesRefHash.java:314-316). - No precondition.
addTermAndVectorandvectorValue(BytesRef)have no javadoc; the constructor, the package doc, the factories,CHANGES.txtandMIGRATE.mdsay nothing about unique terms. - The damage falls on other terms. A repeat does not decide which of the two
avectors wins; it silently changesbandc, which are listed once. - Other malformed files fail loudly. A wrong vector dimension (the reader's one deliberate check) gives "Word2Vec model file corrupted"; more lines than the header declares give
ArrayIndexOutOfBoundsExceptionand fewer giveNullPointerExceptionwhen the provider is built (both incidental, low-level failures). Of the cases probed, only a repeat is silent. - History. The first revision of #12169 (
2abb1ea6de1, 2023-02-23) kept entries in aHashMap<BytesRef, TermAndVector>withput/get, so lookups stayed correct per term: a repeat replaced only that word's map entry (the last vector won), although both lines still took an array slot and a graph node. After a review question ("did you consider using BytesRefHash?"), PR commitbf712b90215(2023-04-05) switched toBytesRefHashand used the id as the slot without usingadd's return value. No comment on the PR or on issue #12168 discusses repeated terms. On the 9.7.0 jars, putting back only theHashMaplookup makes the hunt's tests pass.
The devil's-advocate check188 words
The case for "intended": a word2vec model is a dictionary with one vector per word, and Dl4jModelReader is documented to read "the file generated by the library Deeplearning4j" (Dl4jModelReader.java:34-36), which never repeats a word. The model is trusted configuration and the package is @lucene.experimental, so a file with a repeated word is malformed input: garbage in, garbage out.
Why it fails: no precondition is written anywhere, and Word2VecModel has a public constructor and a public addTermAndVector that upstream tests call directly. @lucene.experimental means the API may change, not that results are undefined. "Garbage in" would allow a wrong vector for the repeated word, not for every unrelated word after it. Other malformed files do fail loudly in the reader, and the PR's first revision looked up every term correctly despite repeats, so the shift is an accident of the BytesRefHash switch, not a design. A reviewer from another model family (OpenAI GPT-5.6) rated the case "moderate" and rejected it; the devil's advocate and the adjudication rejected it too. What survives is a severity point: the documented producer writes unique words, so the reach is low.
Recommended Reject a repeated term with IllegalArgumentException (recommended; validated)
Use the id that BytesRefHash.add returns and reject a repeated term with IllegalArgumentException, checking the capacity first so a failed call leaves the hash unchanged (+11/-1 in Word2VecModel.java). Validated: the repro passes with assertions on and off, and the whole analysis-common test task passes (1,911 tests, 0 failures).
  public void addTermAndVector(TermAndVector modelEntry) {
    modelEntry = modelEntry.normalizeVector();
    // check the capacity before add() changes the hash
    Objects.checkIndex(loadedCount, termsAndVectors.length);
    int termOrd = this.word2Vec.add(modelEntry.term());
    if (termOrd < 0) {
      // vectorValue(BytesRef) uses the hash id as the array slot, so a repeated term would shift
      // every later term onto the previous term's vector
      throw new IllegalArgumentException(
          "Duplicate term in word2vec model: " + modelEntry.term().utf8ToString());
    }
    assert termOrd == loadedCount;
    this.termsAndVectors[loadedCount++] = modelEntry;
  }
All options and trade-offs4 options · 771 words
Two options were built and validated in a scratch worktree of a9779ef3c193; A is recommended.
Use the id that BytesRefHash.add returns and throw when it is negative, so today's numbering (slot = id) holds. The capacity check runs before add, so a model that is already full leaves the hash unchanged; it throws IndexOutOfBoundsException, the superclass of the ArrayIndexOutOfBoundsException thrown today for too many lines. +11/-1 in Word2VecModel.java, including the java.util.Objects import.
  public void addTermAndVector(TermAndVector modelEntry) {
    modelEntry = modelEntry.normalizeVector();
    // check the capacity before add() changes the hash
    Objects.checkIndex(loadedCount, termsAndVectors.length);
    int termOrd = this.word2Vec.add(modelEntry.term());
    if (termOrd < 0) {
      // vectorValue(BytesRef) uses the hash id as the array slot, so a repeated term would shift
      // every later term onto the previous term's vector
      throw new IllegalArgumentException(
          "Duplicate term in word2vec model: " + modelEntry.term().utf8ToString());
    }
    assert termOrd == loadedCount;
    this.termsAndVectors[loadedCount++] = modelEntry;
  }
Trade-offs
- Loud and early, like the reader's handling of a wrong dimension; the message names the term. Through the factory the exception surfaces when the analyzer is built, and nothing is cached for that model name (
Word2VecSynonymProviderFactory.java:43-51caches only after a successful load). - Compatibility. A model file with a repeated word that loads today, with silently wrong synonyms, fails to load after the fix; the user has to remove the repeat. Direct callers of
addTermAndVectorthat add a repeat also start getting the exception, and a repeat added once the model is already full throws theIndexOutOfBoundsException, not the duplicateIllegalArgumentException, because the capacity check comes first. Worth a CHANGES entry.
What the checks validated
- stock: the repro fails 2 of 2 with assertions on and off; the word2vec test package (5 classes, 23 tests with the repro) fails only the repro's 2 tests;
- fix A: the repro passes 2 of 2 with assertions on and off; the word2vec package passes (23 tests, 0 failures); the whole
lucene/analysis/commontest task, repro included, runs 340 classes, 1,911 tests, 0 failures, 18 skipped (13 in hunspell classes that need external dictionaries);ecjLint,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestpass;tidychanges nothing; - the hunt's 3-test repro with fix A shadowed passes 3 of 3; the independent reproducer's test fails its 5 repeat tests with "Duplicate term in word2vec model: red" (or
pear), by design (they expect the first vector to be kept), and its 3 controls pass.
Store the entry at the id add returns, ignore a repeat, and let size() return word2Vec.size() so the HNSW graph and its ordinals cover exactly the distinct terms.
  public void addTermAndVector(TermAndVector modelEntry) {
    modelEntry = modelEntry.normalizeVector();
    int termOrd = this.word2Vec.add(modelEntry.term());
    if (termOrd < 0) {
      return; // repeated term: keep its first vector
    }
    this.termsAndVectors[termOrd] = modelEntry;
    loadedCount++;
  }

  @Override
  public int size() {
    return word2Vec.size();
  }
Trade-offs
- Loads such files the way gensim does (it keeps the first and warns), but silently: a later, different vector for the same word is dropped without notice.
size()changes from the header's count to the number of distinct terms. It has to: with the header count, the graph builder would read empty slots.- A truncated file with unique words (fewer lines than the header declares), which fails today with
NullPointerExceptionwhen the provider is built, then loads silently as a smaller model. - No capacity check before
add: one line too many still throwsArrayIndexOutOfBoundsException, but only afteraddhas given the term an id that has no slot.
What the checks validated
- fix B: the repro passes 2 of 2 (gradle, assertions on; classpath runner, assertions off); the word2vec package passes (23 tests, 0 failures, including
TestDl4jModelReader'ssize() == 235on Lucene's sample model);tidychanges nothing; - the hunt's 3-test repro, the independent reproducer's 8 tests and the second verifier's 3 tests pass with fix B shadowed. The whole module and the lint tasks were not run for B.
Store a repeat at -(id)-1, overwriting the first entry, with size() as in the keep-first option. The PR's first revision (HashMap.put) also let the last vector win for lookups, but it is not the same: it still wrote every line to the next array slot, kept size() at the header's count and named hits by slot, so both lines stayed graph nodes.
Trade-offs
Same as keep-first.
Reject repeats while reading the model file.
Trade-offs
Leaves direct callers of the public addTermAndVector exposed.
Only whoever supplies the model can trigger this, not document or query text; a product that accepts word2vec model files from its users should reject repeated words itself until a fix lands.
Code reading noticed that the array slot and the hash id can disagree, and a small probe on the stock jars confirmed it. An exhaustive comparison of the real classes with an exact reference over 321,075 small models then found 164,160 wrong lookups, all after a repeated term, and a public-API JUnit reproduced it.
The method in full195 words
Method: code reading plus a small executed probe (the hunt's non-formal tier; the hunt unit tagged it semi-formal because of the later exhaustive check).
- The hunt's planning read the word2vec classes, named the lead "duplicate model terms shift vectors", and a probe on the stock main jars showed a small model with a repeated term returning the wrong vector for both terms after the repeat.
- The hunt unit compared
Word2VecModel,Word2VecSynonymProviderandWord2VecSynonymFilteron the real jar with an exact reference written from the javadoc, over 321,075 small models: 49,635 with distinct names (2-D and 3-D direction grids) and 271,440 with names from {a, b, c}, vectors from 4 directions and lengths 2 to 5. Oracle "vectorValue(term)is a vector that was added for that term": 164,160 of 1,525,824 checks over all 321,075 models fail, every failure in a model where a name repeats before a later distinct name. - It then wrote a 3-test public-API JUnit that fails on the stock jar. An independent reproducer, a second verifier and an intended-behaviour devil's advocate confirmed it with their own tests, and a reviewer from another model family (OpenAI GPT-5.6, reading only) rated it real.
No prior report found (2026-10-28): the scripted prior-report search (51 queries over GitHub, the mailing lists, JIRA, downstream trackers and the web), 14 manual GitHub searches, the changed files of 150 open and recent PRs and 8 related threads read in full. The introducing PR #12169 never discusses repeated terms.
Searches4 searches
No report of this defect was found. Related items concern other parts of the word2vec package.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs, commits; downstream repositories; dev@, java-user@, issues@, commits@; JIRA archive; web | 2026-10-28 | scripted prior-report search: 16 issue/PR, 3 commit, 2 downstream, 20 mailing-list, 4 JIRA-archive and 6 web queries | no report; 165 distinct hits, every word2vec-specific hit read |
| GitHub, manual | 2026-10-28 | 14 searches: word2vec, Word2VecModel, Word2VecSynonymProvider, Word2VecSynonymFilter, dl4j, deeplearning4j, BytesRefHash "return value", ...; also apache/solr, OpenSearch and Elasticsearch | no report (0 hits in the three downstream repositories) |
| Open and recent PRs | 2026-10-28 | changed-file lists of 129 open PRs and of 21 PRs closed or updated since 2026-10-24; issues created since 2026-10-24; refreshed at the registration check (PRs to #16926, issues to #16928) | #16847 and #16815 make mechanical edits to Word2VecSynonymProvider.java only; #12433 (open draft) touches the filter and its factory; none touches Word2VecModel |
| Related threads (read in full) | 2026-10-28 | #12168, #12169, #12246, #12257, #12366, #12397, #12433, #15704; lists.apache.org (dev@, java-user@, users@solr); the feature authors' model-trainer issue tracker | #12169 introduced the BytesRefHash mapping without discussing repeats; the others concern thread safety, class moves, boosts and the synonym buffer |
Present since the word2vec package was added in #12169 (1f4f2bf5095, merged 2023-04-24; first release 9.7.0 through the re-applied backport 64b48b89b50). The tests fail on 9.7.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 and main; 9.6.0 has no word2vec classes. Not a regression; not fixed upstream.
Versions tested6 rows
Introduced by apache/lucene#12169 "Introduced the Word2VecSynonymFilter" (issue #12168; by @dantuzi, co-authored by Alessandro Benedetti), squash-merged to main on 2023-04-24 as 1f4f2bf5095. Inside the PR, commit bf712b90215 (2023-04-05) replaced the first revision's HashMap (2abb1ea6de1) with BytesRefHash. On branch_9x the first cherry-pick (53709ccaecc) was reverted the next day (7e15a390688), before 9.6.0, and re-applied as 64b48b89b50 (committed 2023-05-30), hence 9.7.0. CHANGES.txt lists GITHUB#12169 under 9.6.0, but the 9.6.0 release has no word2vec classes, so say "since 9.7.0 (10.0.0 on the 10.x line)". Later commits on Word2VecModel.java (3d86ff2e6a7, d8a81476262, 2f7da75b7d1, 6053e1e3137, the last on 2024-09-28) changed types and accessors, not this logic.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 2 of 2 (gradle and classpath runner, assertions on and off); the hunt's 3 tests fail 3 of 3; both fixes pass |
branch_10_6 build (10.6.0-SNAPSHOT at 4ae946e5a9b, the revision released as 10.6.0 on 2026-10-29) | affected | the hunt's tests fail 3 of 3 (-ea only) |
| 10.0.0 to 10.5.2 | affected | the hunt's tests fail 3 of 3 on 10.0.0 and 10.5.2 (-ea and -da); this doc's test fails 2 of 2 on 10.5.2; the file is the same blob in every 10.x tag |
| 9.7.0 to 9.12.3 | affected | the hunt's tests fail 3 of 3 on 9.7.0 and 9.12.3 (-ea and -da); this doc's test fails 2 of 2 on 9.7.0; the two method bodies are identical in every 9.x release from 9.7.0 |
| 9.7.0 with only the PR's first-revision HashMap lookup | counterfactual | the hunt's tests pass 3 of 3 |
| 9.6.0 and older | no API | compile error: no word2vec classes (0 files in the 9.6.0 tree) |
An independent reproducer, a second verifier with its own controlled JUnit, a cross-model reviewer (OpenAI GPT-5.6) and an intended-behaviour devil's advocate rated it real; an adjudication and a credibility audit re-ran it; this doc's gradle runs reproduce it and validate two fixes. The cross-model reviews could only read the code, not run it.
Checks and verdicts376 words
Every check ran on main a9779ef3c193 with JDK 25.0.3 unless noted.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own 8-test JUnit (5 repeat tests, 3 controls) from a package outside Lucene: 5 fail and the controls pass on main (-ea, -da), 10.5.2, 9.12.3 and 9.7.0; a keep-first shadow fix passes 8 of 8. |
| Second verifier | reproduced | Wrote and ran its own 3-test JUnit (TestWord2VecRepeat) on main with -ea and -da: the test with a repeat in the middle fails (every later term gets another entry's vector), and the two controls (distinct terms; a repeat on the last line) pass. It also re-ran the hunt's test (3 of 3 fail). |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, medium | Reading only (the reviewer could not run code and wrote no test): rated the bug real (medium) and the intended-behaviour case moderate, and rejected that case. A separate re-run of the hunt's test fails 3 of 3. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | procedural only | No command ran; the reviewer states that this is not a refutation. A separate re-run fails 3 of 3. |
| Intended-behaviour devil's advocate | real, not intended | Found the PR history (HashMap, then BytesRefHash) and showed with a probe that every other malformed model fails loudly. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with a new seed (-ea and -da: 8 run, 5 failed, controls pass). |
| Registration check and credibility audit | keep | Re-ran the hunt's and the independent reproduction's tests on main with fresh seeds (same failures) and the finder's patch (passes). |
| This doc | reproduced; fixes A and B validated | Gradle in a clean worktree: the new 2-test repro fails 2 of 2 on stock (assertions on and off) and passes with fix A and with fix B; with A, the word2vec package and the whole analysis-common test task (1,911 tests) pass and the lint tasks pass; with the fixes shadowed, the hunt's repro passes with either fix, and the independent reproducer's and the second verifier's tests pass with the keep-first fix (the reproducer's repeat tests expect the first vector to be kept, so they fail with the reject fix, by design). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 511 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,238 words
- Registry title
- Word2VecModel: a term added twice silently shifts the vector of every later term, so Word2VecSynonymFilter returns synonyms computed from other terms' vectors
- Area
- analysis-common / synonym.word2vec (Word2VecModel.addTermAndVector term-to-vector mapping; Dl4jModelReader; Word2VecSynonymProvider and Word2VecSynonymFilter as consumers)
- Priority
- Low, rank 386: Needs a model that repeats a term in the experimental Word2VecSynonymFilter.
- Impact class
- silent wrong results
- Impact note
- Only applications that opt in to the @lucene.experimental Word2VecSynonymFilter (or use Word2VecModel directly) with a model that lists some term twice are hit: a hand-built or converted model zip loaded through Dl4jModelReader / Word2VecSynonymFilterFactory, or application code that calls the public addTermAndVector with a repeat (the Deeplearning4j writer that Dl4jModelReader targets writes each word once, so stock Deeplearning4j models are not affected); the model then loads without any error, and every distinct term listed after the first repeat gets another term's vector, so its synonyms at index and query time come from a different word; ordinary scale; every release since 9.7.0.
- Summary
- You build a Word2VecModel in which one term appears twice, through the public addTermAndVector or by loading a Deeplearning4j-format zip with Dl4jModelReader or Word2VecSynonymFilterFactory, and you expect every term to keep its own vector, as the class javadoc ('containing the vectors for each word in dictionary') and the upstream test of vectorValue(term) say. addTermAndVector stores each entry at the next array slot but ignores that BytesRefHash.add gives no new id to a term it already holds, while vectorValue(term) looks the vector up by that id, so after the first repeat every later distinct term reads the slot of the term before it. For the model [a(1,0), a(1,0), b(0,1), c(-1,0)] vectorValue(b) returns a's vector and vectorValue(c) returns b's, and with the model [car, car, auto, banana, fruit] and the factory defaults 'banana' is expanded with the neighbours of 'auto' ([auto, car, car]) instead of [fruit], with no error or warning.
- Introduced
- 1f4f2bf50957ad1a13c32d5351c7de77154953f1 on main (apache/lucene#12169 'Introduced the Word2VecSynonymFilter', feature issue #12168; author dantuzi, co-author Alessandro Benedetti; squash-merged 2023-04-24; first in 10.0.0) and its branch_9x re-apply 64b48b89b501 (committed 2023-05-30, author date 2023-04-24; first in 9.7.0; an earlier cherry-pick 53709ccaecc was reverted by 7e15a390688 on 2023-04-25, before 9.6.0). Inside the PR the defect arrived with PR commit bf712b90215 (author date 2023-04-05), which replaced the first revision's HashMap<BytesRef,TermAndVector> put/get (2abb1ea6de1, correct per term) with BytesRefHash ids used as array slots while ignoring the return value of add() [read: git blame -w -M -C on the history clone, whose Word2VecModel.java is identical to a9779ef3c193's, attributes Word2VecModel.java:58, 60, 62, 69-72 and 74 to 1f4f2bf5095 and :59, 61, 66, 73 to 2f7da75b7d1 (record accessors only); exec: on the 9.7.0 jars, whose Word2VecModel.java is byte-identical to 1f4f2bf5095's, the finder's JUnit fails 3 of 3, and with only the term lookup restored to the PR's first-revision HashMap it passes 3 of 3, -ea and -da] (2023-04-24 (main 1f4f2bf5095); 2023-05-30 (branch_9x re-apply 64b48b89b50, author date 2023-04-24); PR-internal change bf712b90215 authored 2023-04-05)
- First affected version
- 9.7.0 [exec] (the first release with the word2vec package; 9.6.0 has no word2vec classes and the repro does not compile there [exec], although CHANGES.txt lists GITHUB#12169 under 9.6.0); first on the main line: 10.0.0 [exec]
- Affected versions
- Every release that has the API: 9.7.0 to 9.12.3 and 10.0.0 to 10.5.2 [exec: the finder's JUnit fails 3 of 3 on 9.7.0, 9.12.3, 10.0.0 and 10.5.2 with -ea and with -da; the independent reproduction's JUnit fails its 5 repeat tests (controls pass) on 10.5.2, 9.12.3 and 9.7.0 with -da; the intended-behaviour check re-ran 10.5.2 -da; read: the addTermAndVector and vectorValue(BytesRef) bodies are identical in 9.7.0 to 9.12.3 and the Word2VecModel.java blob 68fd3b5884b0 is identical in every 10.x tag], the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) [exec, finder], branch_10x 1309534296e3 [read: same blob] and main a9779ef3c193 [exec: -ea and -da; re-run at the registration check]. Not fixed upstream: the last commit on Word2VecModel.java on upstream main is 6053e1e3137 (#13779, 2024-09-28, no logic change) [read 2026-10-28]. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only; refreshed at the registration check 2026-10-28): a scripted prior-report search (16 GitHub issue/PR, 3 commit, 2 downstream Elasticsearch/OpenSearch/Solr, 20 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA-archive and 6 web queries), 14 manual GitHub searches, the file lists of 129 open PRs (128 updated since 2026-10-14 plus #12433) and of 21 PRs closed or updated since 2026-10-24, issues since 2026-10-24, the full threads of #12168, #12169, #12246, #12257, #12366, #12397, #12433 and #15704, lists.apache.org (also users@solr), the issues of the authors' model-trainer repository, 8 web searches and 1 page read. Related, not this bug: #12169 (introducing PR; a reviewer's BytesRefHash suggestion was adopted without using add()'s return value, repeated terms were never discussed), #12433 (open draft, filter boost, does not touch Word2VecModel), #16847 and #16815 (open, mechanical edits to Word2VecSynonymProvider.java only), #12246 and #12257 (thread safety), #15704 (filter collection type). Refresh: the newest PRs (to #16926) and issues (to #16928) contain nothing on word2vec, and the last commit on Word2VecModel.java is still 6053e1e3137 (2024-09-28). Gaps: the refresh's two search-API queries hit the shared GitHub rate limit; keyword search reads only the first page per query; the JIRA archive cannot hold a report because the feature postdates the 2022 migration.
- Lucene commit tested
- main
a9779ef3c193(gradle in a clean scratch worktree, and the hunt's classpath runner with-eaand-da); through the classpath runner also 10.5.2 and 9.7.0. The hunt's tests ran on 9.7.0, 9.12.3, 10.0.0, 10.5.2, a branch_10_6 build (10.6.0-SNAPSHOT at4ae946e5a9b,-eaonly) and main; 9.6.0 has no word2vec classes. OpenJDK 25.0.3, Linux aarch64, 2026-10-28.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecModel.java:26-30 (class javadoc 'containing the vectors for each word in dictionary', @lucene.experimental), :40-45 (public constructor), :58-62 (addTermAndVector: slot loadedCount++, add() result ignored), :69-74 (vectorValue(BytesRef): termsAndVectors[word2Vec.find(term)]), :86-88 (size() returns dictionarySize)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Dl4jModelReader.java:34-43 (reads 'the file generated by the library Deeplearning4j', @lucene.experimental), :64-81 (header sizes the model; every line is added, no repeat check)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:78 (query vector = vectorValue(term)), :97 (synonym = termValue(id))lucene/core/src/java/org/apache/lucene/util/BytesRefHash.java:310-344 (add: returns the new id, or -(id)-1 when the bytes are already present, and allocates no id then)lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymProvider.java:110-121 (testModel_shouldReturnNormalizedVectors: vectorValue(term) is that term's normalized vector)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecModel.java:26-30, (at a9779ef3c193) 58-62, 69-74, 76-78, 86-88lucene/core/src/java/org/apache/lucene/util/BytesRefHash.java:310-345 (at a9779ef3c193)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:56-68, (at a9779ef3c193) 78, 97-100; Dl4jModelReader.java:64-81, 93-115
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecModel.java:30; (at a9779ef3c193) Dl4jModelReader.java:34-44; Word2VecSynonymFilterFactory.java:32-42lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/word2vec-model.zip (at a9779ef3c193) (syn0.txt header 235, 235 lines, 0 repeated words; unzip -p | sort | uniq -d, 2026-10-28)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecModel.java:26-30, (at a9779ef3c193) 58-62, 69-74; Dl4jModelReader.java:34-44, 99-109lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecSynonymProvider.java:110-121 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/util/BytesRefHash.java:310-320 (at a9779ef3c193)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProviderFactory.java:40-53 (at a9779ef3c193)
- History
lucene/CHANGES.txt:3593 (at a9779ef3c193)
- TestWord2VecModelRepeatedTerm.java (JUnit test):
repro/LFV-867/src/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecModelRepeatedTerm.java(41 lines)
Made in parallel with this doc from the a, a, b, c example.
assets/LFV-867/bug.png(511 KB)