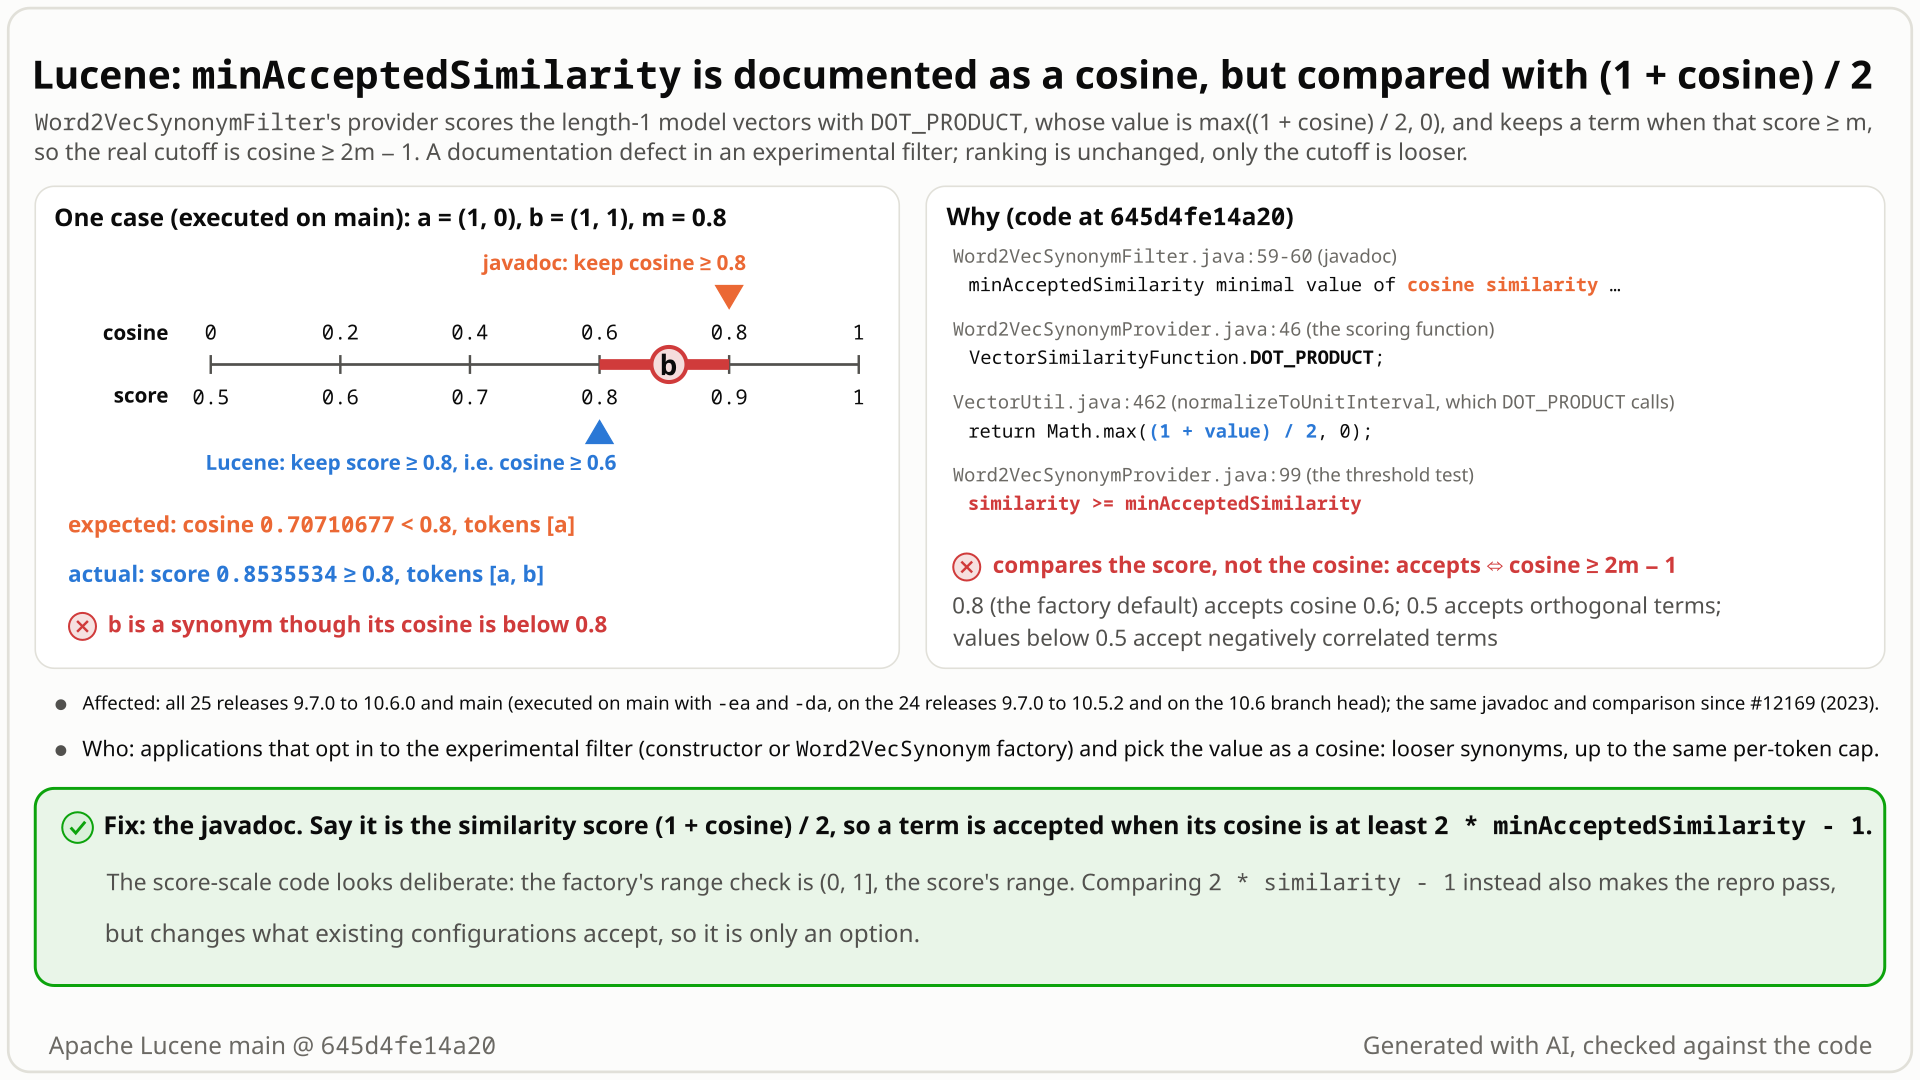
Word2VecModel makes every vector unit length, and Word2VecSynonymProvider scores neighbours with DOT_PRODUCT, whose score is (1 + cosine) / 2. It keeps a neighbour when that score is >= minAcceptedSimilarity (Word2VecSynonymProvider.java:94, :99), while the only javadoc of the value calls it a cosine (Word2VecSynonymFilter.java:59-60).
Word2VecSynonymFilter(analysis-common,@lucene.experimental, since 9.7.0) looks up each token in a word2vec model and adds the model's nearest terms as synonyms at the same position.- How near two terms are is the cosine similarity of their vectors: 1 for the same direction, 0 for unrelated (orthogonal), -1 for opposite.
- Lucene's
DOT_PRODUCTandCOSINEsimilarities return a score in [0, 1]: for unit vectorsDOT_PRODUCTreturns (1 + cosine) / 2, so cosine 1 scores 1, cosine 0 scores 0.5 and cosine -1 scores 0. minAcceptedSimilarity(factory default 0.8) is the cutoff: neighbours below it are not added.
- You add
Word2VecSynonymFilterwithminAcceptedSimilarity0.8, the factory default. Its javadoc says the value is the "minimal value of cosine similarity between the searched vector and the retrieved ones". - Your model has two terms, a = (1, 0) and b = (1, 1). Their cosine is 0.707, below 0.8, so you expect the input
ato come out alone. - Instead you get
[a, b]: the provider compares 0.8 with theDOT_PRODUCTscore of the unit-length vectors, (1 + 0.707) / 2 = 0.854. - In general a term passes when (1 + cosine) / 2 >= m, that is when cosine >= 2m - 1. At the default 0.8, terms down to cosine 0.6 become synonyms (0.61 passes, 0.59 does not); at 0.5, unrelated (orthogonal) terms pass; below 0.5, negatively correlated ones.
- Nothing fails: the extra synonyms are added silently, at index and at query time, in every release since 9.7.0.
Applications that opt in to the experimental filter (constructor or the Word2VecSynonym factory) and set the threshold as a cosine, or keep the default 0.8 believing it means cosine 0.8. They silently get neighbours with cosine in [2m - 1, m) as extra synonyms (within the maxSynonymsPerTerm limit), at index and query time, in every release since 9.7.0.
Mechanism, terms and numbers579 words
The only documentation of Word2VecSynonymFilter's minAcceptedSimilarity is the constructor javadoc: "minimal value of cosine similarity between the searched vector and the retrieved ones". Word2VecModel makes every vector unit length, and Word2VecSynonymProvider scores neighbours with VectorSimilarityFunction.DOT_PRODUCT, whose float score is max((1 + dot) / 2, 0); it keeps a neighbour when that score is >= the threshold. For unit vectors the dot product is the cosine, so the real cosine cutoff is 2m - 1: the factory default 0.8 admits cosine 0.6, 0.5 admits orthogonal terms, and lower values admit negatively correlated terms.
The score-scale code looks deliberate: the factory's range check is (0, 1], the score's range, and a co-author of the filter wrote "the vector similarity score is 0<=x<=1" in #12169. So this is a documentation defect: the proposed fix is a javadoc clarification, with a code change only as an option. It has been there since the filter's first commit and is in every release from 9.7.0 to 10.6.0 and on main.
- The javadoc says cosine.
Word2VecSynonymFilter.java:59-60: "@param minAcceptedSimilarity minimal value of cosine similarity between the searched vector and the retrieved ones". There is no other documentation of the value:Word2VecSynonymProvider.getSynonyms(:70-71) has no javadoc, the factory documents no parameters (Word2VecSynonymFilterFactory.java:29-34), and the package javadoc is one line. - Vectors are unit length.
Word2VecModel.java:58-59callsTermAndVector.normalizeVector(), which appliesVectorUtil.l2normalize(TermAndVector.java:34-38). So the dot product of two model vectors is their cosine. - The provider scores with DOT_PRODUCT.
Word2VecSynonymProvider.java:45-46setsSIMILARITY_FUNCTION = VectorSimilarityFunction.DOT_PRODUCT; the query scorer fromDefaultFlatVectorScorerreturnssimilarityFunction.compare(...)(DefaultFlatVectorScorer.java:246).VectorSimilarityFunction.java:59-62:DOT_PRODUCT.comparereturnsnormalizeToUnitInterval(dotProduct(v1, v2)), defined asMath.max((1 + value) / 2, 0)(VectorUtil.java:461-463). - The threshold is compared with that score.
Word2VecSynonymProvider.java:94takestopDocs.scoreDocs[i].score;:99keeps the term whensimilarity >= minAcceptedSimilarity;:100returns the same score as theTermAndBoostboost. - So a term is kept when (1 + cosine) / 2 >= m, that is cosine >= 2m - 1. In the repro, b's cosine 0.707 gives the score 0.854 >= 0.8.
- The factory fits the score scale.
Word2VecSynonymFilterFactory.java:42sets the default 0.8f;:68-71rejects values <= 0 or > 1, the range (0, 1] (aNaN, whichgetFloatparses withFloat.parseFloat, is not caught by this check).
| minAcceptedSimilarity m | what the javadoc suggests | real cosine cutoff 2m - 1 |
|---|---|---|
| 0.9 | cosine >= 0.9 | cosine >= 0.8 |
| 0.8 (factory default) | cosine >= 0.8 | cosine >= 0.6 |
| 0.7 | cosine >= 0.7 | cosine >= 0.4 |
| 0.5 | cosine >= 0.5 | cosine >= 0 (orthogonal terms pass) |
| 0.2 | cosine >= 0.2 | cosine >= -0.6 (negatively correlated terms pass) |
The closed form was proved with the Z3 SMT solver over the reals; over float32 the default 0.8f accepts exactly the dot products >= 0.6f, and at 0.5f rounding admits even tiny negative dot products. Executed checks agree: through the factory default, terms at cosine 0.75 and 0.61 are emitted and 0.59 is not; at 0.5 a term at cosine 0 is emitted; at 0.15 a term at cosine -0.6 is emitted.
The ranking of neighbours is the same under both readings (the score grows with the cosine); only the cutoff differs. The number of synonyms per token is still bounded by the provider's maxSynonymsPerTerm + 1 search (Word2VecSynonymProvider.java:83-90). The filter does not use the boost (Word2VecSynonymFilter.java:79-88); callers of getSynonyms see the score there.
Exposure and likelihood161 words
- Who. Users of
Word2VecSynonymFilterthrough its public constructor or the factory (SPI nameWord2VecSynonym, parameterminAcceptedSimilarity, default 0.8) who choose the threshold from the javadoc. - Default vs opt-in. Opt-in and
@lucene.experimental(Word2VecSynonymFilter.java:37,Word2VecSynonymFilterFactory.java:32); no default analyzer uses it. - What goes wrong. Weaker neighbours are injected as synonyms, within the
maxSynonymsPerTermlimit of the search: at the default, cosines 0.6 to 0.8; at 0.5, unrelated terms. Silent and deterministic. At index time the extra synonyms are written into the index, so correcting the threshold later needs a reindex. - Scale and age. Ordinary models and text; every release with the filter (9.7.0 to 9.12.3, 10.0.0 to 10.6.0) and main.
- Why upstream tests never noticed. Their vectors are either at cosine >= 0.99 or at score <= 0.887, never in the gap [2m - 1, m) where the two readings differ (the study's reading); with the comparison changed to the cosine scale all 21 upstream word2vec tests still pass.
One JUnit test, one method, deterministic: a two-term model, a = (1, 0) and b = (1, 1) (cosine 0.707), and the filter at 0.8. It asserts what the javadoc promises, that b is not a synonym of a. Public API plus the test framework's whitespaceMockTokenizer.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.synonym.word2vec;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;
import org.apache.lucene.util.BytesRef;
import org.apache.lucene.util.TermAndVector;

public class TestWord2VecMinAcceptedSimilarityCosine extends BaseTokenStreamTestCase {

  public void testTermBelowCosineThresholdIsNotASynonym() throws Exception {
    Word2VecModel model = new Word2VecModel(2, 2);
    model.addTermAndVector(new TermAndVector(new BytesRef("a"), new float[] {1, 0}));
    model.addTermAndVector(new TermAndVector(new BytesRef("b"), new float[] {1, 1}));
    Word2VecSynonymFilter filter =
        new Word2VecSynonymFilter(
            whitespaceMockTokenizer("a"), new Word2VecSynonymProvider(model), 10, 0.8f);
    // expected: b (cosine 0.71 < 0.8) is no synonym; actual: b added (score (1 + cos) / 2 = 0.85)
    assertTokenStreamContents(filter, new String[] {"a"});
  }
}
cp $REPRO/TestWord2VecMinAcceptedSimilarityCosine.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/
cd $LUCENE
./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.synonym.word2vec.TestWord2VecMinAcceptedSimilarityCosine -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
- Expected
- Per the javadoc (cosine 0.707 < 0.8), the stream for the input
ais just[a]. - Observed
[a, b]:TokenStream has more tokens than expected (expected count=1); extra token=b, since b's score (1 + 0.707) / 2 = 0.854 >= 0.8.
More files, environment, full output318 words
- Deterministic in practice. With two model vectors the HNSW search for
maxSynonymsPerTerm + 1= 11 neighbours is expected to return both whatever the seed (the seed only drives the graph's random levels); it ran with seedDEADBEEF, and assertions on and off fail the same way. - It transcribes the current javadoc. Under the recommended javadoc fix it does not pass; it becomes obsolete, because the documented contract becomes the score scale. Under the code alternative it passes unchanged.
- As a regression test for the javadoc fix (optional for a javadoc-only change): this same test with the expectation the clarified javadoc gives,
new String[] {"a", "b"}, and the comment "b: cosine 0.71 >= 2 * 0.8 - 1 = 0.6, score (1 + cos) / 2 = 0.85 >= 0.8, so b is a synonym". The run copy also renames the class toTestWord2VecMinAcceptedSimilarityScoreand the method totestThresholdIsComparedWithNormalizedScore; the body is otherwise the same. It passes with the javadoc fix, with assertions on and off; it pins the scale, so a silent change of the comparison would be caught. - Releases. The same file fails unchanged on the 9.7.0, 9.8.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 release jars; 9.6.0 has no word2vec package.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on the 9.7.0, 9.8.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp $REPRO/TestWord2VecMinAcceptedSimilarityCosine.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/word2vec/
cd $LUCENE
./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.synonym.word2vec.TestWord2VecMinAcceptedSimilarityCosine -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true
TestWord2VecMinAcceptedSimilarityCosine > testTermBelowCosineThresholdIsNotASynonym FAILED
    java.lang.AssertionError: TokenStream has more tokens than expected (expected count=1); extra token=b
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:9B455D092792C978]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at org.apache.lucene.test_framework@11.0.0-SNAPSHOT/org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:402)
        ...
        at org.apache.lucene.analysis.synonym.word2vec.TestWord2VecMinAcceptedSimilarityCosine.testTermBelowCosineThresholdIsNotASynonym(TestWord2VecMinAcceptedSimilarityCosine.java:33)
:lucene:analysis:common:test (FAILURE): 1 test, 1  failure
# -Ptests.asserts=false: the same failure
# javadoc fix (option A): changes no code; the same test expecting [a, b] passes
# code alternative (option B): BUILD SUCCESSFUL, 1 test- The only documentation of the value says "minimal value of cosine similarity" (
Word2VecSynonymFilter.java:59-60) and never mentions the normalization. - Lucene keeps the scales apart elsewhere:
VectorUtil.cosine"Returns the cosine similarity",normalizeToUnitIntervalturns it into "a normalized score", and the similarity queries call their threshold a "similarity score". - The score-scale code looks deliberate, so the fix is the javadoc, not the code.
The full argument246 words
- The only documentation names the other scale.
Word2VecSynonymFilter.java:59-60calls the value a "minimal value of cosine similarity" and says nothing about normalization; the factory andgetSynonymsadd nothing. - Lucene's own javadoc keeps the two scales apart.
VectorUtil.java:96:cosine()"Returns the cosine similarity between the two vectors" (the raw value in [-1, 1]).VectorUtil.java:452-459:normalizeToUnitInterval"Converts a dot product or cosine similarity value to a normalized score in the [0, 1] range ... using the formula: (1 + value) / 2".VectorSimilarityFunction.java:122:compare()"Calculates a similarity score".FloatVectorSimilarityQuery.java:49(and:76,:92,:105): "similarity score for result collection". No Lucene javadoc calls (1 + cosine) / 2 a "value of cosine similarity". - Since the first commit. The javadoc line, the choice of
DOT_PRODUCT, the comparison, the 0.8 default and the (0, 1] check all arrived together in1f4f2bf50957(#12169). The javadoc text and the comparison line are unchanged since; the code around them was refactored (for example #12434, #12529 and #15704 in the provider), and theDOT_PRODUCTscore was clamped at 0 in 9.9.0 (#12727) and later moved intonormalizeToUnitInterval(#15036), all without changing the (1 + dot) / 2 scale. - The hazard is known in general. In the review of #11946 (a 2022 kNN similarity-threshold PR, closed unmerged, a different API) a reviewer warned: "a dotProduct of 0.7 ... ACTUALLY means they want to limit the scores to .85 ((1 + dotProduct)/2). How is the user supposed to know that?"
The devil's-advocate check234 words
Strongest case for "leave it" (the study's intended-behaviour devil's advocate and a cross-model reviewer, OpenAI GPT-5.6): the score-scale code looks deliberate. The factory's range check (0, 1] is the score's range, not the cosine's [-1, 1]; a co-author (Alessandro Benedetti) wrote "the vector similarity score is 0<=x<=1" in #12169 (2023-03-22, about the boost); the open draft #12433 by the filter's author tests with normalized VectorSimilarityFunction.COSINE.compare values while calling them "the cosine similarity"; and Lucene itself labels VectorSimilarityFunction.COSINE, whose compare() returns the normalized score, "Cosine similarity" (VectorSimilarityFunction.java:77-80). In that vocabulary "cosine similarity" means Lucene's normalized cosine score, the API is experimental, and a committer could call the wording acceptable.
Why it fails: it rules out a code bug, which is why the proposal is a javadoc fix, but not the documentation defect. VectorSimilarityFunction.java:77-80 names a metric and adds "The similarity score is normalised to assure it is positive"; the filter javadoc names a value and never mentions normalization. The (0, 1] range does not tell a reader which scale applies, since it is also a natural range for a raw-cosine synonym cutoff (an independent Go port of the filter documents the 0.8 default as "the default minimum cosine similarity threshold"). The cross-model reviewer itself wrote: "A documentation clarification is warranted even if behavior remains unchanged." Confidence: high that the javadoc misdescribes the compared value, medium that a committer will want the change.
Recommended A. Clarify the javadoc (recommended)
Clarify the javadoc: the value is a similarity score, (1 + cosine) / 2 for the normalized model vectors, so a term is accepted when its cosine is at least 2m - 1 (0.8 means cosine 0.6). No behaviour change. Validated with gradle: the format check and javadoc render pass, and all word2vec tests pass.
   * @param maxSynonymsPerTerm maximum number of result returned by the synonym search
-  * @param minAcceptedSimilarity minimal value of cosine similarity between the searched vector and
-  *     the retrieved ones
+  * @param minAcceptedSimilarity minimal similarity score between the searched vector and the
+  *     retrieved ones. The model vectors are normalized and scored as (1 + cosine) / 2, so a term
+  *     is accepted when its cosine similarity is at least 2 * minAcceptedSimilarity - 1 (the
+  *     factory default 0.8 accepts cosine 0.6, 0.5 accepts orthogonal terms, and lower values also
+  *     accept negatively correlated terms)
   */
All options and trade-offs2 options · 594 words
Two options; both were applied in a scratch worktree of main 645d4fe14a20 and run with gradle. The javadoc fix is the proposal, because the score-scale code appears deliberate.
Say that the value is a similarity score, (1 + cosine) / 2 for the normalized model vectors, and give the equivalent cosine cutoff.
   * @param maxSynonymsPerTerm maximum number of result returned by the synonym search
-  * @param minAcceptedSimilarity minimal value of cosine similarity between the searched vector and
-  *     the retrieved ones
+  * @param minAcceptedSimilarity minimal similarity score between the searched vector and the
+  *     retrieved ones. The model vectors are normalized and scored as (1 + cosine) / 2, so a term
+  *     is accepted when its cosine similarity is at least 2 * minAcceptedSimilarity - 1 (the
+  *     factory default 0.8 accepts cosine 0.6, 0.5 accepts orthogonal terms, and lower values also
+  *     accept negatively correlated terms)
   */
Trade-offs
- No behaviour change, so no existing configuration moves; it uses the vocabulary of
VectorUtil.normalizeToUnitIntervaland of the similarity queries ("similarity score"). - It does not help users who already set a cosine value; they need (1 + c) / 2 for a cosine cutoff c.
- Optionally add the same sentence to the factory's class javadoc, where SPI users look, and to
getSynonyms(not run).
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seedDEADBEEF::lucene:analysis:common:checkGoogleJavaFormatand:lucene:analysis:common:renderJavadocpass, and the renderedWord2VecSynonymFilter.htmlshows the new text. - The word2vec tests (
org.apache.lucene.analysis.synonym.word2vec.*: the 21 upstream tests plus the minimal test in its clarified form, expecting[a, b]) pass, 22 tests, with assertions on; the clarified-form test passes with assertions off too. - The minimal test as written (the cosine reading) was not re-run with it: the fix changes only a comment, so it keeps failing as on stock main.
In Word2VecSynonymProvider.getSynonyms, compare 2 * similarity - 1 with the threshold, which makes the current javadoc true over the reals.
         // We remove the original query term
-        if (!synonym.equals(term) && similarity >= minAcceptedSimilarity) {
+        // DOT_PRODUCT scores unit vectors as (1 + cosine) / 2; the threshold is a cosine
+        float cosine = 2 * similarity - 1;
+        if (!synonym.equals(term) && cosine >= minAcceptedSimilarity) {
           result.addLast(new TermAndBoost(synonym, similarity));
Trade-offs
- Silently tightens every existing configuration (the default 0.8 would drop all neighbours between cosine 0.6 and 0.8), against the evident intent of the code; it would need a CHANGES entry as a behaviour change.
- The factory's range check (0, 1] would then forbid cutoffs at or below cosine 0; the boost stays on the score scale.
- Float caveat:
2 * similarity - 1is not exact in float32. For m = 0.8f a dot product of exactly 0.8f scores 0.9f, and 2 * 0.9f - 1 = 0.79999995f < 0.8f, so this option rejects a cosine equal to the threshold (333 of the 1000 values m = i / 1000, in a standalone float check). Comparing the score with (1 + m) / 2 instead accepts that case (not run against Lucene); over the reals the two are the same test.
What the checks validated
- Same worktree and seed: the minimal test passes with assertions off (1 test), and the word2vec tests including it pass with assertions on (22 tests);
checkGoogleJavaFormatpasses. - A standalone run agrees: with the change applied, the minimal test passes with assertions on and off, and the 21 upstream tests pass (2026-11-01). So no upstream test pins either scale.
Products that pass minAcceptedSimilarity through to their own users, for example in an analysis-chain configuration, inherit the misleading cosine wording and the looser cutoff.
Semi-formal. A hunt unit compared the real filter, over a bounded exhaustive set of small models and thresholds, with a reference written from the javadoc: the cosine oracle failed 3,530,652 of 9,136,266 checks while a score-scale oracle held in all of them. A Z3 proof then gave the closed form, cosine >= 2m - 1.
The method in full138 words
- Lead. The hypothesis came from code reading: the javadoc says cosine, the provider uses
DOT_PRODUCT. - Translation validation.
W2VExhaustiveTV.javadrove the real analysis-common jar over a bounded exhaustive space of small models and thresholds and checked each output against oracles written from the javadoc. "Every synonym has exact cosine >= minAcceptedSimilarity" failed 3,530,652 of 9,136,266 checks; "every synonym has score >= minAcceptedSimilarity" held in all of them. The harness was mutant-checked. - Proof. A Z3 script proved accept <=> cosine >= 2m - 1 over the reals and, over float32, that 0.8f accepts exactly the dot products >= 0.6f (10 of 10 queries as expected).
- Verification. A public-API JUnit, an independent reproducer, an intended-behaviour devil's advocate, an adjudication, a re-verification, a second adjudication and a cross-model reviewer (OpenAI GPT-5.6) followed; all agree on the behaviour and the root cause.
No prior report found (searched 2026-10-28, 201 queries; rechecked 2026-11-01): GitHub issues and PRs incl. the JIRA archive, commits, mailing lists, downstream projects, the web and open PRs. #11946 (2022, a different API) holds a reviewer's general warning about thresholds on the normalized score.
Searches4 searches
Read, not the same bug: #12169 (origin of the javadoc and the comparison; nobody discusses the threshold scale); #12433 (open draft, adds similarity-as-boost, calls the value "the cosine similarity" while its test uses normalized scores; does not touch the threshold); #11946 (closed 2022 kNN threshold PR); #12679 (similarity queries documented as "similarity score"); #16815 and #16847 (open, only mechanical changes in Word2VecSynonymProvider.java: #16815 a graph type change, in the import and the field; #16847 Math.toIntExact on the doc id); #15704 (the last commit on the package). An outside Go port copied the cosine wording; it reports nothing. Gaps: GitHub keyword search reads only the first page per query; parts of the web search and of the 2026-11-01 full-text search did not complete, so recent issues and PRs were also listed and blobs compared.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, incl. migrated JIRA) | 2026-10-28 and 2026-11-01 | a scripted prior-report search (201 queries, then 55 in a re-run) and 17 manual GitHub issue searches (2026-11-01): minAcceptedSimilarity, Word2VecSynonymFilter/Provider/Factory, word2vec, cosine, normalized, DOT_PRODUCT, threshold, javadoc, TermAndBoost; the threads of #12169, #12433 and #11946 | no report |
| Open PRs | 2026-10-28 and 2026-11-01 | titles of all 410 open PRs; changed files of the 144 updated since 2026-09-28 and of the 51 updated since 2026-10-27; the 80 issues and PRs created or updated since 2026-10-28 | none changes the javadoc or the comparison |
| Mailing lists and downstream projects | 2026-10-28 and 2026-11-01 | dev@, java-user@, issues@, commits@; Elasticsearch, OpenSearch, Solr; code search for minAcceptedSimilarity outside apache/lucene | no report |
| Web | 2026-10-28 and 2026-11-01 | the study's web search (partly incomplete), then 9 queries; the filter authors' blog posts re-read | nothing on the threshold scale |
In the filter's first commit, 1f4f2bf50957 (#12169, 2023-04-24); first released in 9.7.0 through the branch_9x re-backport 64b48b89b501. The repro fails on every release tested from 9.7.0 to 10.6.0 and on main; 9.6.0 has no word2vec package. Not fixed upstream.
Versions tested5 rows
- Introduced:
1f4f2bf50957"Introduced the Word2VecSynonymFilter (#12169)" (Daniele Antuzi, co-author Alessandro Benedetti, 2023-04-24; feature issue #12168), first released on the main line in 10.0.0; on branch_9x the re-backport64b48b89b501(committed 2023-05-30), first released in 9.7.0. An earlier backport53709ccaeccwas reverted by7e15a390688the next day, so 9.6.0 shipped without the package. Every part of the mismatch is in the first version: not a regression. - Later changes: none to the javadoc text, the comparison or the scale. The surrounding provider code was refactored (for example #12434, #12529, #15704). The 9.9.0 clamp of the
DOT_PRODUCTscore at 0 (#12727) changes only scores below 0, which matter only for a threshold <= 0: the factory rejects those, the constructor does not check the value. - Every later
CHANGES.txt(mainlucene/CHANGES.txt:3610) lists GITHUB#12169 under Lucene 9.6.0, but the 9.6.0 release has no word2vec classes; 9.7.0 is the first release with the filter. - Upstream: main
f815e679bf6c(2026-11-01) has the same filter, provider, factory, model,VectorSimilarityFunctionandVectorUtilblobs as645d4fe14a20.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, gradle and standalone, assertions on and off; passes with the code alternative |
| 10.6.0, 10.5.2, 10.0.0 | affected | minimal test fails (10.5.2 and 10.0.0 also with assertions off) |
| 9.12.3, 9.8.0 | affected | minimal test fails |
| 9.7.0 | first release | minimal test fails, assertions on and off |
| 9.6.0 | no API | compile error: no word2vec package |
Every check agrees on the behaviour: the study finder, an independent reproducer, a devil's advocate and the adjudication (category doc), a re-verification and a second adjudication, and a cross-model reviewer (OpenAI GPT-5.6), which said "uncertain" but wrote "A documentation clarification is warranted".
Checks and verdicts262 words
The study ran on main a9779ef3c193 and the cross-model review on ea57360912ed; the filter, provider, factory, model, VectorSimilarityFunction and VectorUtil blobs there are identical to 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| study finder (a hunt unit) | reproduced | Translation validation (cosine oracle fails 3,530,652 of 9,136,266 checks), Z3 closed form, public-API JUnit failing 3 of 3 on main and every release 9.7.0 to 10.5.2. |
| independent reproducer | real, doc | Own test fails 4 of 5 (control at 0.9 passes) on main, 10.5.2, 9.12.3 and 9.7.0, including the factory default with a DL4J model; 5 of 5 pass with a cosine-scale provider. |
| cross-model review | not real, procedural only | None of its three attempts could execute anything; the adjudication records that its static analysis agrees on the root cause and that it rated the intended-behaviour argument strong. |
| devil's advocate | real, doc, medium | Built the intended-behaviour case; it rules out a code bug, not the documentation defect. |
| adjudication | confirmed, doc, medium, Low | Re-ran the independent reproduction's test with a new seed, assertions on and off. |
| re-verification (2026-11-01) | real, doc | Minimal test fails on main and 10.5.2, assertions on and off; passes with the code alternative; 21 upstream tests pass. |
| cross-model review, refute lens | uncertain, medium | OpenAI GPT-5.6, executing: reproduced with its own test, root cause agrees, intended argument strong; "A documentation clarification is warranted even if behavior remains unchanged." |
| Second adjudication | real, doc | New seeds; a probe through CustomAnalyzer at the factory default pins the cutoff between cosine 0.59 and 0.61. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 446 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,262 words
- Registry title
- Word2VecSynonymFilter documents minAcceptedSimilarity as a cosine similarity, but Word2VecSynonymProvider compares it with the normalised score (1 + cosine) / 2, so the effective cosine cutoff is 2m - 1 (the default 0.8 accepts cosine 0.6, 0.5 accepts orthogonal terms, values below 0.5 accept negatively correlated terms); documentation defect, the javadoc fix is the default proposal
- Area
- analysis-common / synonym.word2vec (Word2VecSynonymFilter minAcceptedSimilarity javadoc vs Word2VecSynonymProvider threshold test)
- Priority
- Low, rank 1228: A documentation-only defect in the opt-in experimental Word2VecSynonymFilter whose javadoc leads users to a much looser cosine cutoff and weaker synonyms.
- Impact class
- minor
- Impact note
- Only applications that opt in to the @lucene.experimental Word2VecSynonymFilter (constructor or factory) and choose minAcceptedSimilarity as a cosine, as its only javadoc says, are misled: they get the looser cutoff cosine >= 2m - 1 (the factory default 0.8 admits cosine 0.6, 0.5 admits orthogonal terms, values below 0.5 admit negatively correlated terms), so more loosely related synonyms, still at most maxSynonymsPerTerm per token, are injected at index and query time; ordinary scale, no error, every release since 9.7.0; the code does what the authors intended, only the javadoc names the wrong scale.
- Summary
- You build Word2VecSynonymFilter with minAcceptedSimilarity 0.8 (the factory default), whose only documentation says it is the 'minimal value of cosine similarity between the searched vector and the retrieved ones', so you expect only model terms at cosine 0.8 or more as synonyms. Word2VecSynonymProvider compares the threshold with the DOT_PRODUCT score of the unit-length model vectors, which is (1 + cosine) / 2, so the real cosine cutoff is 2m - 1: at 0.8 a term at cosine 0.65 is emitted, at 0.5 an orthogonal term (cosine 0) is emitted, and at 0.2 a term at cosine -0.5 is emitted. The authors' intent points to the score scale (the factory accepts only (0, 1]), so the fix is a javadoc clarification, not a code change.
- Introduced
- 1f4f2bf50957ad1a13c32d5351c7de77154953f1 on main (apache/lucene#12169 'Introduced the Word2VecSynonymFilter', feature issue #12168; author dantuzi, co-author Alessandro Benedetti; first on the main line in 10.0.0) and its branch_9x re-backport 64b48b89b501 (committed 2023-05-30, author date 2023-04-24; first in 9.7.0; an earlier backport 53709ccaecc was reverted by 7e15a390688 on 2023-04-25) [read: git blame on main a9779ef3c193 attributes the javadoc line, DOT_PRODUCT, the comparison, the 0.8f default and the (0, 1] check to 1f4f2bf5095; git blame at the 9.7.0 tag names 64b48b89b50; git log --all -S on each of them lists only these commits and the revert]. Every part of the mismatch is in the first version; no later commit changed it. (2023-04-24 (main 1f4f2bf5095, author and commit date); 2023-05-30 (branch_9x re-backport 64b48b89b50, author date 2023-04-24))
- First affected version
- 9.7.0 [exec] (the first release with the API; 9.6.0 has no synonym.word2vec package and the repros do not compile there [exec]); first on the main line: 10.0.0 [exec]
- Affected versions
- Every release that has the API: 9.7.0 to 9.12.3 and 10.0.0 to 10.5.2, 24 releases [exec: the finder's JUnit fails 3 of 3 with the same messages on each with -ea, also with -da on 9.7.0, 9.12.3, 10.0.0 and 10.5.2; the independent reproduction's JUnit fails 4 of 5 (control passes) on 9.7.0, 9.12.3, 10.0.0, 10.5.2 and main], the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) [exec] and main a9779ef3c193 [exec: -ea and -da; re-run at the registration check]. Unchanged on upstream main c5ab3e57b9b (2026-10-28), branch_10x 1309534296e and branch_10_6 2763db11b0a: same javadoc, DOT_PRODUCT, comparison, 0.8f default and (0, 1] check [read]. The 9.9.0 clamp of DOT_PRODUCT to max((1 + dot) / 2, 0) (#12727) changes only scores below 0, which no accepted threshold reaches, and 9.7.0 and 9.8.0 fail the same way [exec]. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading, Z3
- Upstream and prior reports
- none found (searched 2026-10-28; refreshed at the registration check 2026-10-28): two scripted prior-report search runs (GitHub issue/PR, commit-message, downstream Elasticsearch/OpenSearch/Solr, dev@/java-user@/issues@/commits@ list, JIRA-archive and web queries; 201 queries), titles of all 410 open apache/lucene PRs and the file lists of the 144 updated since 2026-09-28, the review threads of #12169, #12433 and #11946, the dev@ thread on #12169, CHANGES.txt and the package history on main, branch_10x and branch_10_6. Related, not this bug: #12169 (origin of both the javadoc and the score comparison; nobody discussed the threshold scale), #12433 (open draft, adds similarity-as-boost, calls the value 'the cosine similarity' while its test uses normalised scores, does not report or change the mismatch), #11946 (closed unmerged 2022 kNN threshold PR whose reviewers noted that thresholds on the normalised score confuse users; background only, a different API that predates the filter), #12679 (similarity queries documented as 'similarity score'). Refresh: GitHub search for minAcceptedSimilarity, word2vec and Word2VecSynonymFilter finds nothing new; of the 14 PRs created and 54 PRs updated since 2026-10-26 (file lists read), none touches word2vec or synonym files except #16911 (decommissions branch_10x, deleting every file there), and #16790, #16914 and #16915 touch VectorUtil.java but not normalizeToUnitInterval or DOT_PRODUCT; the newest issues (to #16928, including another contributor's batch of javadoc-defect issues) contain nothing on word2vec; the last commit on the package is still 7335eb0ad96 (author date 2026-02-26); 2 web searches found nothing. Gaps: GitHub keyword search reads only the first page per query; 4 of the 6 general scale-confusion web queries of the second run did not complete.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28), through gradle in a scratch worktree (2026-11-01): the minimal test fails on stock main with assertions on and off; with the javadoc fix, its clarified form (expecting[a, b]) passes with assertions on and off and the 21 upstream word2vec tests pass; with the code alternative, the minimal test as written passes (assertions off; assertions on together with the 21 upstream tests); standalone, the same test on the 9.7.0, 9.8.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 release jars (9.6.0 has no word2vec package). Upstream mainf815e679bf6c(2026-11-01) has the same code.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:37 (@lucene.experimental), :59-60 ('@param minAcceptedSimilarity minimal value of cosine similarity between the searched vector and the retrieved ones')lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:45-46 (SIMILARITY_FUNCTION = DOT_PRODUCT), :94 (similarity = topDocs score), :99-100 (similarity >= minAcceptedSimilarity; the same score becomes TermAndBoost.boost)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:42 (DEFAULT_MIN_ACCEPTED_SIMILARITY = 0.8f), :68-71 ('must be in the range (0, 1]')lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecModel.java:59 (every vector is normalised, so dot = cosine)lucene/core/src/java/org/apache/lucene/index/VectorSimilarityFunction.java:59-62 (DOT_PRODUCT.compare = normalizeToUnitInterval(dot)), :77-82 (COSINE javadoc 'Cosine similarity ... The similarity score is normalised to assure it is positive')lucene/core/src/java/org/apache/lucene/util/VectorUtil.java:461-463 (normalizeToUnitInterval = max((1 + value) / 2, 0)), :96 (cosine 'Returns the cosine similarity', raw value)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:37, 53-61, 79-88, 95-96 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProvider.java:45-46, 70-71, 80-100 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:29-34, 42, 54-55, 68-71 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecModel.java:58-59; lucene/core/src/java/org/apache/lucene/util/TermAndVector.java:34-38 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/VectorSimilarityFunction.java:59-62; lucene/core/src/java/org/apache/lucene/util/VectorUtil.java:461-463; lucene/core/src/java/org/apache/lucene/codecs/hnsw/DefaultFlatVectorScorer.java:246 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:222-224 (getFloat = Float.parseFloat; at 645d4fe14a20)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilter.java:37; Word2VecSynonymFilterFactory.java:32, 39, 42, 54-55 (at 645d4fe14a20)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/VectorUtil.java:96, 452-463; lucene/core/src/java/org/apache/lucene/index/VectorSimilarityFunction.java:77-82, 122; lucene/core/src/java/org/apache/lucene/search/FloatVectorSimilarityQuery.java:49, 76, 92, 105 (at 645d4fe14a20)
- History
lucene/CHANGES.txt:3581, 3610
- TestWord2VecMinAcceptedSimilarityCosine.java:
repro/LFV-870/src/org/apache/lucene/analysis/synonym/word2vec/TestWord2VecMinAcceptedSimilarityCosine.java(35 lines)
assets/LFV-870/bug.png(446 KB)