Thai text often spells Sara Am (ำ) as two pieces, Nikhahit (ํ) + Sara Aa (า), sometimes with a tone mark between them. ThaiNormalizer glues the pieces back, but not when a second slip (an extra tone mark, or a look-alike of Sara Aa) sits inside them.
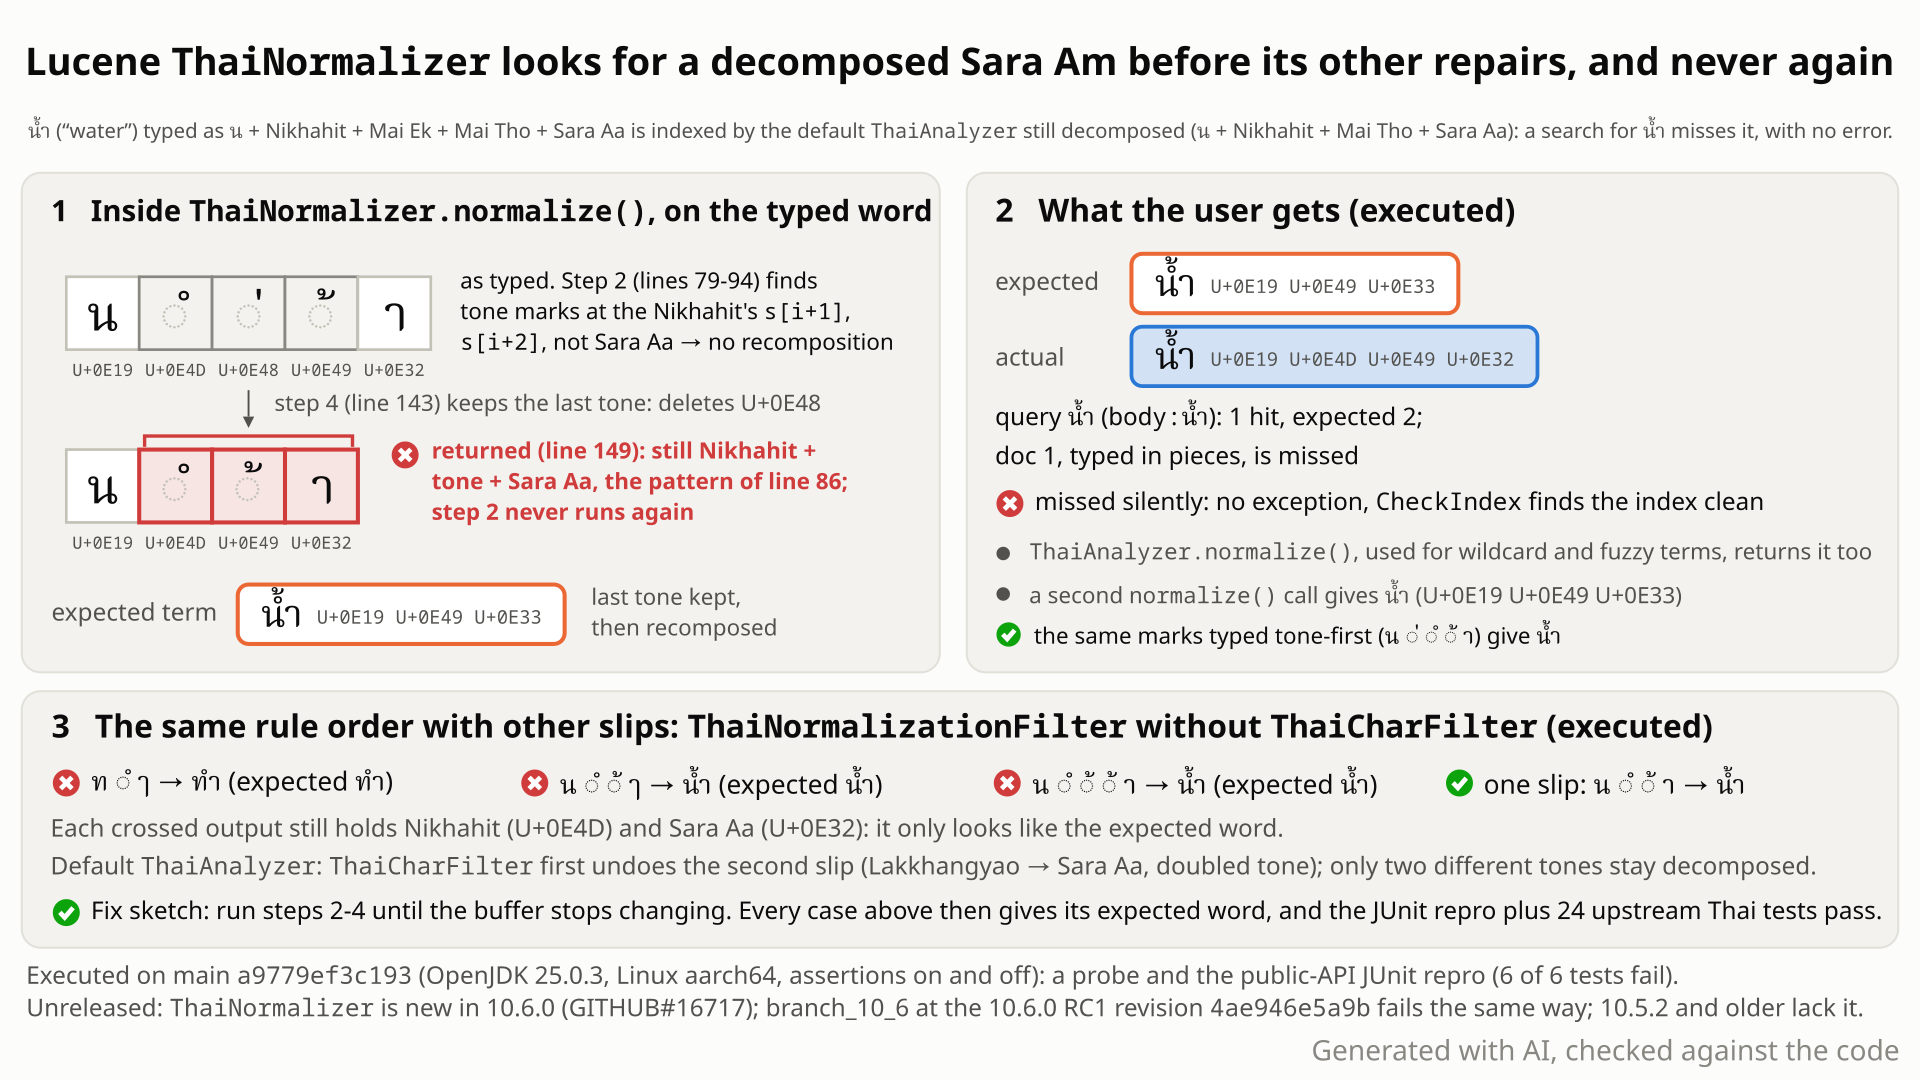
ThaiAnalyzer handles น้ำ typed as Nikhahit + two tone marks + Sara Aa, why step 2 misses the decomposed Sara Am and step 4 leaves นํ้า, and the other slips with the same cause. Select the still to open it at full size. Generated with AI, checked against the code.- You index two documents with the default
ThaiAnalyzer: "drink water cold" with น้ำ ("water", U+0E19 U+0E49 U+0E33) typed cleanly, and with น้ำ typed as น + Nikhahit + Mai Ek + Mai Tho + Sara Aa: a decomposed Sara Am with a wrong tone mark typed before the right one. - You expect both to index the term น้ำ.
ThaiNormalizersays it recomposes Nikhahit + tone mark + Sara Aa into Sara Am, and its own test keeps the last of two different tone marks. ATermQueryfor น้ำ should find 2 documents. - You get 1. The typed word is indexed as นํ้า (U+0E19 U+0E4D U+0E49 U+0E32), still Nikhahit + tone + Sara Aa, and
Analyzer.normalize, which Lucene's classic query parser uses for prefix, wildcard and fuzzy terms, returns the same. The same five characters with Mai Ek typed first give น้ำ. - Why: the recomposition test runs once, on the characters as typed. After the Nikhahit it sees Mai Ek and then Mai Tho where it needs Sara Aa, and fails; the last step then removes Mai Ek, which leaves exactly the pattern, and nothing tests again. A second
normalize()call would fix it. - Without
ThaiCharFilter(the filter on its own), two more shapes fail the same way: ท + Nikhahit + Lakkhangyao gives ทํา instead of ทำ, and Mai Tho typed twice inside the decomposed form gives นํ้า.
Thai-language indexes on 10.6 code. The default ThaiAnalyzer is hit only by Nikhahit + two different tone marks + Sara Aa (or Lakkhangyao in its place); ThaiNormalizationFilter alone (as in the factory's javadoc example) also by Nikhahit + Lakkhangyao and a doubled tone mark. The word gets a different term, so a query for the clean word misses it. Rare.
Mechanism, terms and numbers793 words
ThaiNormalizer (new in 10.6.0 with ThaiNormalizationFilter, which the default ThaiAnalyzer uses from 10.6.0) documents that it recomposes a decomposed Sara Am, Nikhahit + optional tone mark + Sara Aa, into Sara Am. It also converts Lakkhangyao to Sara Aa, removes a repeated tone mark and keeps the last of two different tone marks. It runs these rules as single forward passes: the recomposition test looks at the next characters as typed, a Lakkhangyao is converted only when the loop reaches it, and an extra tone mark is removed only in the last step. Nothing tests for a decomposed Sara Am again, so a second typo inside one leaves the decomposed form in the output. Through the default analyzer, น้ำ ("water") typed as น + Nikhahit + Mai Ek + Mai Tho + Sara Aa is indexed as นํ้า, and a TermQuery for น้ำ finds 1 of 2 documents; the same marks with Mai Ek first give น้ำ. With the filter on its own, ท + Nikhahit + Lakkhangyao and a doubled tone mark inside the decomposed form fail too. It is deterministic, raises no error and is in 10.6.0 (released 2026-10-29 from the RC1 revision). Re-running the rules while a decomposed Sara Am is left fixes it; all Thai and analysis-module tests pass with that change.
- Sara Am
ำ(U+0E33) is one vowel character. Typists often enter it as Nikhahitํ(U+0E4D) followed by Sara Aaา(U+0E32); with a tone mark (Mai Ek่U+0E48, Mai Tho้U+0E49) the tone is often typed between the two pieces. This is the decomposed Sara Am. Issue #16716, which proposed the class, calls it "often typed". - Lakkhangyao
ๅ(U+0E45) looks like Sara Aa; the class converts it to Sara Aa unless it follows Ru or Lu. - The example word is น้ำ, "water": No Nu
นU+0E19, Mai Tho U+0E49, Sara Am U+0E33.
- Step 2 of
ThaiNormalizer.normalizeis one forward pass (ThaiNormalizer.java:68-109). At a Nikhahit it tests whether the next character is Sara Aa, or the next two are a tone mark and Sara Aa (:79-94), on the characters as typed. - A Lakkhangyao after the Nikhahit becomes Sara Aa only when the loop reaches it (
:103-108), after the test has failed: ท ํ ๅ leaves step 2 as ท ํ า. - With น ํ ่ ้ า the test sees Mai Ek, Mai Tho and fails. Step 4 (
:135-147) then keeps the last of the two tone marks ("If two different consecutive tone marks appear, keep the last one",:142), or drops a repeated one (:137-141), and leaves น ํ ้ า. normalizereturns after step 4 (:149): the decomposed Sara Am that steps 2-4 produced stays. Callingnormalizeon its own output recomposes it.- With Mai Ek typed first (น ่ ํ ้ า) the test at the Nikhahit sees Mai Tho + Sara Aa and recomposes; step 4 then drops Mai Ek, giving น้ำ. So the result depends on the order the marks were stored in.
- In the default
ThaiAnalyzer,ThaiCharFilterruns first (ThaiAnalyzer.java:119-128). It converts the Lakkhangyao (ThaiCharFilter.java:149-154) and drops a repeated identical tone mark (:97-103), so those two shapes reach the token filter as a plain decomposed Sara Am, which it recomposes. The char filter has no keep-last-tone rule and its own recomposition needs exactly one tone mark (:126-136), so Nikhahit + two different tone marks + Sara Aa reachesThaiNormalizerunchanged. With a Lakkhangyao in place of the Sara Aa, the char filter converts it and leaves both tone marks, so the same shape arrives.
| input | ThaiNormalizer | second call | ThaiAnalyzer.normalize |
|---|---|---|---|
| น้ำ 0E19 0E49 0E33 (clean) | 0E19 0E49 0E33 | same | 0E19 0E49 0E33 |
| นํ้า 0E19 0E4D 0E49 0E32 (one typo, control) | 0E19 0E49 0E33 | same | 0E19 0E49 0E33 |
| 0E19 0E4D 0E48 0E49 0E32 (two tones after Nikhahit) | 0E19 0E4D 0E49 0E32 | 0E19 0E49 0E33 | 0E19 0E4D 0E49 0E32 |
| 0E19 0E4D 0E48 0E49 0E45 (two tones, Lakkhangyao for Sara Aa) | 0E19 0E4D 0E49 0E32 | 0E19 0E49 0E33 | 0E19 0E4D 0E49 0E32 |
| 0E19 0E48 0E4D 0E49 0E32 (same marks, Mai Ek first) | 0E19 0E49 0E33 | same | 0E19 0E49 0E33 |
| 0E19 0E4D 0E49 0E49 0E32 (Mai Tho twice) | 0E19 0E4D 0E49 0E32 | 0E19 0E49 0E33 | 0E19 0E49 0E33 |
| 0E19 0E4D 0E49 0E45 (Lakkhangyao for Sara Aa) | 0E19 0E4D 0E49 0E32 | 0E19 0E49 0E33 | 0E19 0E49 0E33 |
| ทํๅ 0E17 0E4D 0E45 | 0E17 0E4D 0E32 | 0E17 0E33 | 0E17 0E33 |
An index-and-query probe with the default analyzer indexed only the two-tone form: a query for the clean word found 0 documents, a query typed with the same typo found 1.
Exposure and likelihood342 words
- Who is exposed. Thai-language indexes on 10.6.0 (released 2026-10-29), main or branch_10_6 (no earlier release has the class):
- the default
ThaiAnalyzer: only Nikhahit + two different tone marks + Sara Aa (or a Lakkhangyao in its place, which the char filter turns into Sara Aa), a wrong tone mark typed and then the right one without deleting the first, in a word typed with the decomposed Sara Am; ThaiNormalizationFilterwithoutThaiCharFilter: the factory's javadoc example (ThaiTokenizerFactory+ThaiNormalizationFilterFactory, no char filter), a custom chain withthaiNormalizationafter, for example, a whitespace tokenizer, or a search server that exposes the filter on its own. Here Nikhahit + Lakkhangyao and a doubled tone mark inside the decomposed form fail too.
- the default
- What happens. The typed word is indexed as a different term from the clean word, so a query for the clean word misses the document (1 of 2 documents found in the repro).
Analyzer.normalize, which Lucene's classic query parser (QueryParserBase) uses for prefix, wildcard and fuzzy terms, returns the same unnormalized form. - Scale. Deterministic, any index size; no error, no exception, the index stays valid.
- How likely. Rare: it needs two typing anomalies inside one character cluster, and each anomaly on its own is normalized correctly. The hunt's bounded check covered 824,691 inputs over a 21-symbol alphabet: every input of 1 to 5 symbols that starts with one of four initial characters (ก, น, ฤ or the leading vowel เ), plus every input of up to 3 symbols (all inputs of up to 5 symbols would be 4,288,305). 1,134 of them have a unique normal form under the model's encoding of the javadoc rules, pass its simplified well-formedness check, and keep a decomposed Sara Am; 12 of them reach
ThaiAnalyzer.normalize. Over the same inputs, everyThaiAnalyzer.normalizeoutput that keeps a decomposed Sara Am (16) comes from Nikhahit followed by two different tone marks. - Timing. Released in 10.6.0 (2026-10-29): indexes built with 10.6.0 keep the wrong terms for the affected words until reindexed, even after a fix.
The test shows that the default ThaiAnalyzer (ThaiNormalizer) leaves a decomposed Sara Am in place when two different tone marks sit inside it: น + Nikhahit + Mai Ek + Mai Tho + Sara Aa is not recomposed to น้ำ ("water").
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.th;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestThaiSaraAmTwoTones extends LuceneTestCase {

  public void testDecomposedSaraAmWithTwoTones() throws Exception {
    try (Analyzer analyzer = new ThaiAnalyzer()) {
      // expected: Sara Am recomposed (U+0E19 U+0E49 U+0E33); actual: U+0E19 U+0E4D U+0E49 U+0E32
      assertEquals(
          "\u0E19\u0E49\u0E33",
          analyzer.normalize("f", "\u0E19\u0E4D\u0E48\u0E49\u0E32").utf8ToString());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-873/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.th.TestThaiSaraAmTwoTones
- Expected vs actual
ThaiAnalyzer.normalizeshould give U+0E19 U+0E49 U+0E33; actual U+0E19 U+0E4D U+0E49 U+0E32 (still Nikhahit + Sara Aa), with-eaand-da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<น[้ำ]> but was:<น[ํ้า]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.th.TestThaiSaraAmTwoTones.testDecomposedSaraAmWithTwoTones(TestThaiSaraAmTwoTones.java:27)- The output นํ้า is exactly what the javadoc says the class recomposes: "Nikhahit U+0E4D + optional tone mark + Sara Aa U+0E32"; the upstream test
testSaraAmDecompositionuses that very string as its input. - The same five characters with Mai Ek typed first are normalized to น้ำ.
- No test, commit or discussion limits the rules to one typo per cluster.
The full argument189 words
- The output is the documented input form. "Recomposes decomposed Sara Am (Nikhahit U+0E4D + optional tone mark + Sara Aa U+0E32) into canonical Sara Am (U+0E33)" (
ThaiNormalizer.java:29-30). The result นํ้า is Nikhahit + one tone mark + Sara Aa. - The upstream tests.
testSaraAmDecompositionasserts นํ้า -> น้ำ (TestThaiNormalizer.java:40-41);testConsecutiveDifferentTonesasserts "When multiple different tone marks are typed, keep the last one" (:66-69). MIGRATE.md's 10.6 Thai section names "decomposed Sara Am (น+ํ+้+า)" as text 10.6 analyzes differently (lucene/MIGRATE.md:768). - Keystroke order decides the result. Mai Ek typed before the Nikhahit gives น้ำ, and so does the precomposed two-tone form; the code even has a dedicated rule for the tone-first order (
:96-101). - The javadoc list is not an execution order. Dangling-mark removal is listed last (
:38) but runs before step 2 (:63-66); issue #16716 lists the same rules in another order, deduplication first. - No record of a limitation. PR #16717 has no reviews and one thank-you comment; #16716 has no comments; no upstream test combines two anomalies in one cluster.
The devil's-advocate check190 words
The checkers built the strongest case for "intended": the javadoc is a list of best-effort repairs and promises no idempotence; its pattern allows one optional tone mark, so Nikhahit + two tone marks + Sara Aa is not literally the documented pattern; keep-last-tone is stated only in a code comment (ThaiNormalizer.java:142) and a test; and two typos in one cluster could be out of scope for "common orthographic variations" (:24).
Why it fails: the class itself emits the documented pattern, the one its own test treats as input to repair; the same marks in another stored order give a different term; and nothing in the javadoc, tests or history limits the rules to one anomaly per cluster. That makes a bug reading persuasive, not certain: a maintainer could still call combined anomalies an enhancement. The independent reproducer, the devil's advocate, the works-as-designed review and the adjudication rejected the case; the refute review said "not real (low)" only on procedure (it ran no command; it rated the intended case moderate and asked for a re-run), so it was discounted. The case survives as a priority argument (Low).
Recommended A. Run steps 2-4 again while a decomposed Sara Am is left
Re-run steps 2-4 of ThaiNormalizer.normalize while the buffer still holds Nikhahit + (tone) + Sara Aa (+24 lines, one file). Only tokens whose output today keeps a decomposed Sara Am change (the whole token is re-run); no allocation. Validated: the new tests, all Thai and analysis-module tests, check, and the bounded check (1,134 mismatches to 0).
All options and trade-offs3 options · 1,058 words
Option A was applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; option B is the finder's sketch, run through the repro harness and once through gradle; option C was not run.
Steps 2-4 move unchanged into a private normalizeMarks(s, len); normalize repeats it while hasDecomposedSaraAm(s, len) finds Nikhahit + Sara Aa or Nikhahit + tone mark + Sara Aa.
What it changes, by construction. The first pass is today's code, so a token's output differs from today only when today's output for that token still contains a decomposed Sara Am (the loop test also catches tone + Nikhahit + Sara Aa, which contains Nikhahit + Sara Aa). Each extra pass recomposes at least one, which deletes a character, so the loop ends after at most len extra passes. That bounds the passes, not the time: each pass includes step 3, whose scans repeat until nothing moves, so on long tokens its cost can grow with the square of the token length, as it does today. A token without a leftover decomposed Sara Am costs one extra linear scan; nothing is allocated.
Within an affected token, every part is re-run. The extra pass runs all of steps 2-4 on the whole token, so it can also change a part unrelated to the Sara Am: ThaiNormalizer.normalize on ฤๅ่ followed by ทํๅ (0E24 0E45 0E48 0E17 0E4D 0E45) gives 0E24 0E48 0E45 0E17 0E4D 0E32 today and 0E24 0E48 0E32 0E17 0E33 with fix A: the Lakkhangyao of the Ru pair becomes Sara Aa too. The bounded check (5 symbols) has no room for both patterns, so it cannot show this.
New output. Every failing row of the table gives น้ำ or ทำ, through ThaiNormalizer and ThaiAnalyzer.normalize. The malformed ฤๅ่ on its own (Ru + Lakkhangyao + Mai Ek, not claimed) keeps today's ฤ่ๅ.
    // Steps 2-4 can leave a decomposed Sara Am behind: step 2 tests for it on the characters as
    // typed, but converts a following Lakkhangyao only after that test, and step 4 removes a
    // repeated or extra tone mark between Nikhahit and Sara Aa. Run them again while one is left.
    // Each extra pass recomposes at least one, which shortens the buffer, so the loop ends.
    do {
      len = normalizeMarks(s, len);
    } while (hasDecomposedSaraAm(s, len));
    return len;
  }

  /** Steps 2-4: compositions, canonical reordering and deduplication. */
  private static int normalizeMarks(char[] s, int len) {
    // Step 2: ... (unchanged through the final "return len;")

  /** Nikhahit + Sara Aa, or Nikhahit + tone mark + Sara Aa. */
  private static boolean hasDecomposedSaraAm(char[] s, int len) {
    for (int i = 0; i + 1 < len; i++) {
      if (s[i] == '\u0E4D'
          && (s[i + 1] == '\u0E32'
              || (i + 2 < len && isToneMark(s[i + 1]) && s[i + 2] == '\u0E32'))) {
        return true;
      }
    }
    return false;
  }
Trade-offs
- Targets this bug only: other cases where a later step creates an earlier step's pattern keep today's output when they are alone in a token, such as the malformed Ru + Lakkhangyao + tone class, where step 3 moves the tone mark between Ru and Lakkhangyao; in a token that also holds a leftover decomposed Sara Am they change too (example above).
- Does not fix the sibling
ThaiCharFilterbug (LFV-876), which has the same design at another fix site. - Indexed terms change only for tokens whose output today keeps a decomposed Sara Am; with 10.6.0 released (2026-10-29), those would need reindexing (a MIGRATE note). No CHANGES entry is drafted; no benchmark was run.
What the checks validated
- Gradle in a scratch worktree of
a9779ef3c193: the Thai tests (56 upstream plus the 4 new ones) pass 60 of 60 with assertions on and off (stock: the 4 new ones fail); all of:lucene:analysis:common:testwith assertions on, 1,913 tests, 18 skipped, 0 failures;check -x testpasses (google-java-format, ecjLint, forbiddenApis);tidychanges nothing. - Shadowed into the repro harness: the new test 4 of 4, the finder's JUnit 6 of 6 and the reproducer's 9 of 9 pass.
- The hunt's bounded check (824,691 inputs):
ThaiNormalizertypo-input mismatches 1,756 to 622, with the decomposed-Sara-Am classes (864 + 270) at 0 and only the unclaimed Ru + Lakkhangyao + tone class left;ThaiAnalyzer.normalize734 to 722, the 12 two-tone inputs at 0; noThaiAnalyzer.normalizeoutput with a decomposed Sara Am is left (stock: 16). - All of the above ran on main only: branch_10_6 (
4ae946e5a9b) has a byte-identicalThaiNormalizer.java, but fix A was not built or tested there.
B. Iterate steps 2-4 until the buffer stops changing (the finder's sketch) (validated by the checks)
The same method split, with a do { copy; steps 2-4 } while (changed) loop that compares the buffer with a copy (of the hunt).
Trade-offs
- More general: it removes every typo-input mismatch of the bounded check (1,756 to 0), including the Ru + Lakkhangyao + tone class, where it turns ฤๅ่ into ฤ่า (Ru + tone + Sara Aa), breaking up the Ru + Lakkhangyao pair that the Lakkhangyao rule exists to keep; whether that is wanted is a separate question.
- Allocates a copy of the token on every call. It terminated on every input of the bounded check, but no simple argument bounds the passes, and a fixed two passes would not be enough (in the bounded check, 4 inputs, all Ru + Lakkhangyao + Nikhahit, need 3 changing calls of the stock normalizer).
- Not formatted or run through
check(one comment line is 111 characters).
What the checks validated
- Through the repro harness: the finder's JUnit with
TestThaiNormalizer,TestThaiAnalyzerandTestThaiNormalizationFilterFactory, 30 tests, 0 failures; the reproducer's JUnit 9 of 9. - Gradle in the scratch worktree: the Thai tests with assertions on, 60 of 60.
- The bounded check: typo-input mismatches 1,756 to 0.
Convert a Lakkhangyao and collapse repeated or extra tone marks before the Sara Am test in step 2.
Trade-offs
No extra pass, but it changes the rule order for every input, must repeat the Ru/Lu exception, and step 3 can still move marks afterwards. Not executed.
Search servers built on Lucene that expose ThaiAnalyzer or the thaiNormalization filter inherit the same term mismatch once they ship 10.6; their adoption threads report no defect.
A bounded-exhaustive check of ThaiNormalizer against its javadoc's rules, written as a rewriting system, over 824,691 inputs (up to 5 symbols of a 21-symbol alphabet starting with one of four initial characters, plus all inputs up to 3 symbols). 1,134 with a unique normal form under the model kept a decomposed Sara Am; iterating the normalizer fixed them all.
The method in full237 words
- Method (semi-formal): bounded-exhaustive translation validation of the stock main jar, in the hunt's unit on the 10.6 Thai normalizers. The javadoc's rules were encoded as a string-rewriting system (the model's reading of the javadoc, not a Lucene contract); for 824,691 inputs over a 21-symbol alphabet (every input of 1 to 5 symbols that starts with one of four initial characters, ก, น, ฤ or the leading vowel เ, plus every input of up to 3 symbols; all inputs of up to 5 symbols would be 4,288,305) the reference computed all normal forms by exhaustive rewriting, and the real
ThaiNormalizerwas compared with them. - Signal. 1,756 inputs with a unique normal form under the model, passing its simplified well-formedness check, got an output that one of the class's own rules still rewrites: 864 + 270 in this decomposed-Sara-Am class, 622 in a malformed Ru + Lakkhangyao + tone class that is not claimed. Iterating the stock normalizer to a fixed point removed every mismatch. Through
ThaiAnalyzer.normalize, 12 inputs of the class remained, all with two different tone marks. - First lead. A planning probe before the unit, a bounded idempotence check over 333,453 inputs, had found 4,632 inputs whose output changes on a second call, for example ก ํ ๅ -> กํา -> กำ.
- Then reading the code gave the mechanism, and the finder wrote the public-API JUnit and the fixed-point sketch; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-28: 103 tool queries over GitHub, commits, the Lucene lists, the JIRA archive, downstream trackers and the web, 32 manual GitHub searches, all 410 open PRs and every issue and PR updated since 2026-09-25).
Searches4 searches
Closest items: the introducing issue and PR, the MIGRATE.md Thai section (a single-tone example that works), another Thai class's bug, and downstream adoption threads. GitHub search tokenizes Thai script poorly, so every issue and PR body updated since 2026-09-25 was scanned; comments were read only on the Thai threads; some search-API calls were rate-limited and retried.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (two runs) | 2026-10-28 | 103 queries: 32 GitHub issue/PR, 6 commit, 4 downstream, 40 mailing-list (dev@, java-user@, issues@, commits@), 8 JIRA archive, 13 web | no report; the high hits are the introducing issue, PR and commit |
| GitHub (manual) | 2026-10-28 | 32 searches over apache/lucene, Elasticsearch, OpenSearch, Solr and Lucene.NET; the changed-file lists of all 410 open apache/lucene PRs; titles and bodies of all 388 issues and PRs updated since 2026-09-25 | no report; no open PR touches the Thai classes except #16911, which deletes branch_10x |
| Commits | 2026-10-28 | commits API for ThaiNormalizer.java on main, branch_10_6 and branch_10x, plus local history | only the introducing commit e64ae25dcd8 and its backport |
| Closest items (read) | 2026-10-28 | full threads | #16716 / #16717 (introducing issue and PR, nothing on rule order or combined anomalies), #16770 (MIGRATE.md, single-tone example), #16736 (ThaiTokenizer user dictionary), #16911 (open, deletes branch_10x), OpenSearch#23151 and elasticsearch#160853 / #160854 (adoption, no defect) |
Introduced with the class by #16717 (e64ae25dcd8, 2026-09-27; backport 405116dd0e1 to branch_10_6), not a regression. First released in 10.6.0 (2026-10-29): 10.5.2 and older lack the class; the 10.6.0 RC1 revision 4ae946e5a9b, released as 10.6.0, fails.
Versions tested5 rows
Introduced by #16717 "Add ThaiCharFilter, ThaiNormalizationFilter, and ThaiNormalizer (#16716)" (author Kamthorn Krairaksa, merged by @rmuir), main commit e64ae25dcd8, author date 2026-09-27T21:09:27Z; backport 405116dd0e1 to branch_10_6 and branch_10x on 2026-09-28. git blame -L 79,147 gives all 69 lines to that commit; ThaiNormalizer.java is unchanged since, up to upstream main c5ab3e57b9b (2026-10-28).
Release status. CHANGES.txt lists GITHUB#16717 under 10.6.0 "New Features". 10.6.0 was released on 2026-10-29 from RC1 (revision 4ae946e5a9b). The branch_10_6 runs used snapshot jars built at that revision, not the RC artifacts. The hunt rates it Low; target branches are the maintainers' call.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193, 7cecf795236 | affected | the new test 4 of 4 fail (harness and gradle, assertions on and off); the finder's 6 of 6; the independent reproduction's 8 of 9 with the control passing |
branch_10_6 4ae946e5a9b (10.6.0 RC1 revision) | affected | the finder's 6 of 6 fail with assertions on and off; the independent reproduction's 8 of 9 with assertions off |
e64ae25dcd8 (the four Thai classes over the 10.5.2 jars) | introducing commit | 6 of 6 fail; with only ThaiNormalizer replaced by the fix sketch, 6 of 6 pass |
| 10.5.2, 9.12.3 | no such class | compile error: ThaiNormalizer and ThaiNormalizationFilter do not exist |
fix A on main a9779ef3c193 | not affected | the new test, the finder's and the independent reproduction's JUnit pass; all Thai and analysis-module tests pass |
An independent reproducer (own 9-test JUnit), an intended-behaviour devil's advocate, a works-as-designed review by a reviewer from another model family, an adjudication and a credibility audit all judged it real; the reproducer, the devil's advocate, the adjudication and the audit re-ran it on main. A refute review said "not real" only because it could not run code.
Checks and verdicts245 words
The cross-model reviews were reading-only; each was followed by a separate re-run of the repro (fails). This doc's own test and fix validation ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6): it ran no command and no Java and asked for a re-run. A separate run re-ran the repro: 6 of 6 fail. |
| Independent reproducer | real | Own public-API JUnit (9 tests, a single-anomaly control): 8 of 9 fail with the control passing, on main with assertions on and off and on branch_10_6; 9 of 9 pass with the fix sketch. |
| Works-as-designed review | real (low), reading only | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens: nothing excludes combined anomalies, and the output is the documented decomposed pattern. Separate runs fail 6 of 6. |
| Intended-behaviour devil's advocate | real (medium) | Rated the works-as-designed case moderate and rejected it; found that the tone-first order and the precomposed two-tone form normalize fully, and that only the two-tone form reaches the default analyzer. |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's JUnit with assertions off (8 of 9 fail, control passes); its probe shows each failing output changing on a second call. |
| Credibility audit | keep | Re-ran the finder's JUnit (6 of 6 fail) and added an index-and-query probe: a query for the clean word finds 0 documents, the tone-first order normalizes fully. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 498 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,483 words
- Registry title
- ThaiNormalizer looks for a decomposed Sara Am before it converts Lakkhangyao or removes an extra tone mark, so its output can still be the decomposed form (Nikhahit + tone + Sara Aa), and the default ThaiAnalyzer indexes น้ำ ('water') typed with two tone marks inside a decomposed Sara Am as a different term
- Area
- analysis-common / Thai (ThaiNormalizer.normalize rule order; ThaiNormalizationFilter, the 'thaiNormalization' factory and the default ThaiAnalyzer as consumers; new in 10.6.0)
- Priority
- Low, rank 482: In the default ThaiAnalyzer since 10.6.0, a word typed with two anomalies inside one decomposed Sara Am (such as an extra tone mark) is silently indexed as a different term, so a query for the clean spelling misses it; each anomaly on its own is normalized correctly.
- Impact class
- silent wrong results
- Impact note
- Thai-language indexes on 10.6.0 (released 2026-10-29; branch_10_6 at the release revision 4ae946e5a9b) and main are hit when a word carries two typing anomalies inside one decomposed Sara Am: through the default ThaiAnalyzer only Nikhahit + two different tone marks + Sara Aa reaches the term (ThaiCharFilter repairs the other forms first), while ThaiNormalizationFilter used without the char filter (a setup the factory's javadoc example shows; verified with a whitespace tokenizer) also leaves Nikhahit + Lakkhangyao and a doubled tone mark inside the decomposed form; the term then differs from the clean spelling's, so a query for the clean word misses the document and Analyzer.normalize returns the same unnormalized form for prefix, wildcard and fuzzy terms, deterministically at any index size, with no error and a well-formed index.
- Summary
- You index Thai text with the default ThaiAnalyzer (or ThaiNormalizationFilter) in which the word น้ำ ('water') is typed with a decomposed Sara Am and an extra tone mark inside it, น + Nikhahit + Mai Ek + Mai Tho + Sara Aa, and you expect the term น้ำ, because ThaiNormalizer documents that it recomposes Nikhahit + tone + Sara Aa into Sara Am and (per its code comment and upstream test) keeps the last of two different tone marks. ThaiNormalizer tests for the decomposed Sara Am in one forward pass over the raw characters, before it converts a following Lakkhangyao and before its last step removes the extra or repeated tone mark, and it never checks again, so the output is นํ้า (U+0E19 U+0E4D U+0E49 U+0E32), still the decomposed form; a query for น้ำ misses the document, while a second normalize() call, or the same two tone marks typed in the other order, gives น้ำ. When the token filter runs without ThaiCharFilter, ท + Nikhahit + Lakkhangyao likewise gives ทํา instead of ทำ, and a doubled tone mark inside the decomposed form gives นํ้า.
- Introduced
- e64ae25dcd894019125d0a0bd723133b633b009e on main (apache/lucene#16717 'Add ThaiCharFilter, ThaiNormalizationFilter, and ThaiNormalizer (#16716)', closes feature issue #16716, author kamthorn, merged by rmuir; 0 reviews, 1 comment) and its backport 405116dd0e10a4921d8269bfaa7b74c69992f3e6 (branch_10_6 and branch_10x, committed 2026-09-28T15:36:16Z, same author date). Born with the class, not a regression: the single-pass rule order is in the first and only commit of ThaiNormalizer.java [read: git blame -L 79,147 ThaiNormalizer.java gives 69 of 69 lines from e64ae25dcd8 on main a9779ef3c19 and from 405116dd0e1 on branch_10_6; parent e357029271b has no ThaiNormalizer.java; exec: the four Thai classes taken verbatim from e64ae25dcd8 and compiled over the 10.5.2 release jars fail 6 of 6, and the same hybrid with only ThaiNormalizer swapped for the fix sketch passes 6 of 6] (2026-09-27 (author date 2026-09-27T21:09:27Z, i.e. 2026-09-28T04:09:27+07:00; merged to main at the same time); backport 405116dd0e1 committed 2026-09-28)
- First affected version
- 10.6.0 (released 2026-10-29) is the first release. The 10.6.0 RC1 (rev 4ae946e5a9b, released as 10.6.0 on 2026-10-29) contains it: the finder JUnit fails 6 of 6 with -ea and -da and the independent reproduction's fails 8 of 9 with -da on 10.6.0-SNAPSHOT jars built at that revision [exec; the RC artifacts themselves were not run]. 10.5.2, 9.12.3 and every earlier release lack the API [exec: compile error, ThaiNormalizer and ThaiNormalizationFilter not found]
- Affected versions
- main / 11.0.0-SNAPSHOT since e64ae25dcd8 [exec: 7cecf795236 -ea fails 6 of 6; a9779ef3c193: the finder JUnit fails 6 of 6 with -ea and -da in the finder's, the independent reproduction's, the cross-model review's and the intended-behaviour check's runs, and the independent reproduction's own JUnit fails 8 of 9 with -ea and -da (the adjudication's -da run of it too); re-run at the registration check 2026-10-28: -ea 6 of 6, -da 6 of 6, the independent reproduction's JUnit -da 8 of 9 with its control passing; read: upstream main c5ab3e57b9b (2026-10-28) has the identical ThaiNormalizer.java blob 5ce1c08fa7b5]; branch_10_6 since 405116dd0e1 [exec at head 4ae946e5a9b, the 10.6.0 RC1 revision: finder 6 of 6 with -ea and -da, the independent reproduction 8 of 9 with -da]; branch_10x [read: same backport and blob; read at 657014b3c57, its last code revision; the branch was retired on 2026-10-29 by #16911 (48cf3f515d6) and now holds only a README]. In no release before 10.6.0: 10.5.2, 9.12.3 and older lack the class [exec: compile error]. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only; refreshed at the registration check 2026-10-28): two scripted prior-report searches (103 queries: 32 GitHub issue/PR, 6 commit, 4 downstream, 40 mailing-list queries over dev@, java-user@, issues@ and commits@, 8 JIRA-archive and 13 web queries), 32 manual GitHub searches (apache/lucene plus Elasticsearch, OpenSearch, Solr and Lucene.NET), the changed-file lists of all 410 open apache/lucene PRs, the titles and bodies of all 388 issues and PRs updated since 2026-09-25, the commits API for ThaiNormalizer.java on main, branch_10_6 and branch_10x, and the full threads of #16716, #16717, #16720, #16722, #16736, #16770, opensearch-project/OpenSearch#23151 and elastic/elasticsearch#160853 and #160854. Related, not this bug: #16716 / #16717 (introducing issue and PR; nobody discusses rule order, combined anomalies or idempotence), #16770 (MIGRATE.md Thai section; its decomposed Sara Am example has one tone mark, which normalizes correctly), #16736 (ThaiTokenizer user-dictionary failure, other class), #16911 (merged 2026-10-29, emptied branch_10x), OpenSearch#23151 and elasticsearch#160853 / #160854 (downstream adoption and backward-compatibility threads, no defect report). Refresh: the 25 newest PRs (to #16926) and 15 newest issues (to #16928) contain nothing on Thai analysis, and the only commit on ThaiNormalizer.java on upstream main is still e64ae25dcd8. Gaps: GitHub search tokenizes Thai script poorly (mitigated by the body scan); comments were read only on the Thai threads; several search-API queries hit the shared rate limit and were retried after a back-off.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): the new 4-test class through the repro harness (assertions on and off) and through gradle in a scratch worktree with-Ptests.asserts=trueandfalse, stock and with fix A, plus all of:lucene:analysis:common:testandcheck -x testwith fix A; the worktree was removed afterwards. The finder's 6-test JUnit on main7cecf795236anda9779ef3c193and on branch_10_64ae946e5a9b(the 10.6.0 RC1 revision, snapshot jars); the introducing commit's classes over the 10.5.2 jars; 10.5.2 and 9.12.3 (class absent). The hunt's bounded check (824,691 inputs) stock and with fix A. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiNormalizer.java:23-38 (class javadoc rule list; :29-30 Sara Am recomposition, :31-32 Lakkhangyao, :37 deduplication, :38 dangling marks), :63-66 (dangling marks removed before step 2), :68-109 (step 2 single forward pass; :79-94 recomposition tests the raw s[i+1], s[i+2]; :103-108 Lakkhangyao converted only when the loop reaches it), :135-147 (step 4 deduplication and keep-last-tone at :142-145, no recomposition afterwards)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-109 (createComponents: ThaiTokenizer, LowerCaseFilter, DecimalDigitFilter, ThaiNormalizationFilter, ThaiRepeatFilter, StopFilter), :112-117 (normalize uses ThaiNormalizationFilter), :121-128 (ThaiCharFilter for indexing and normalization)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiNormalizationFilterFactory.java:23-40 (javadoc example: ThaiTokenizerFactory + ThaiNormalizationFilterFactory without the char filter; SPI name 'thaiNormalization'; @since 10.6.0)lucene/analysis/common/src/test/org/apache/lucene/analysis/th/TestThaiNormalizer.java:34 (testSaraAmDecomposition), :66-67 (testConsecutiveDifferentTones, 'keep the last one')lucene/MIGRATE.md:766-770 (10.6 Thai section; decomposed Sara Am example with one tone mark)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiNormalizer.java:29-32, :37, :68-109 (:79-94, :96-101, :103-108), :135-147 (:137-146), :149 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:97-103, :126-136, :149-154 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-109, :111-117, :119-128 @ a9779ef3c193
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiNormalizationFilterFactory.java:23-35 (javadoc example without a char filter), :40 (SPI name) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-128 @ a9779ef3c193lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:646, :656, :712, :729 (Analyzer.normalize for wildcard, prefix, fuzzy) @ a9779ef3c193
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiNormalizer.java:24, :29-30, :38, :63-66, :96-101, :142 @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/th/TestThaiNormalizer.java:34-45 (testSaraAmDecomposition), :66-69 (testConsecutiveDifferentTones) @ a9779ef3c193lucene/MIGRATE.md:757-770 (10.6 Thai section; :768)
- History
lucene/CHANGES.txt:446, :475, :480 (10.6.0 New Features, GITHUB#16717)
- TestThaiSaraAmTwoTones.java (JUnit test):
repro/LFV-873/src/org/apache/lucene/analysis/th/TestThaiSaraAmTwoTones.java(32 lines)
assets/LFV-873/bug.png(498 KB)