IndriAndQuery should return the documents that match at least one clause. With a phrase or doc-values range clause next to another clause, it also returns documents that only pass that clause's cheap candidate step.
- Some queries are costly to check per document. Their scorer offers a
TwoPhaseIterator: a cheapapproximation(), a superset of the matches, andmatches(), the exact check for the current document. - For a phrase, the approximation is "has all the words" and
matches()checks their positions. For a slow doc-values range, the approximation is "has a value" andmatches()checks the range. - Code that walks an approximation must call
matches()before it counts a document as a hit. The coreDisjunctionScorer, whichBooleanQueryuses for SHOULD clauses, does.
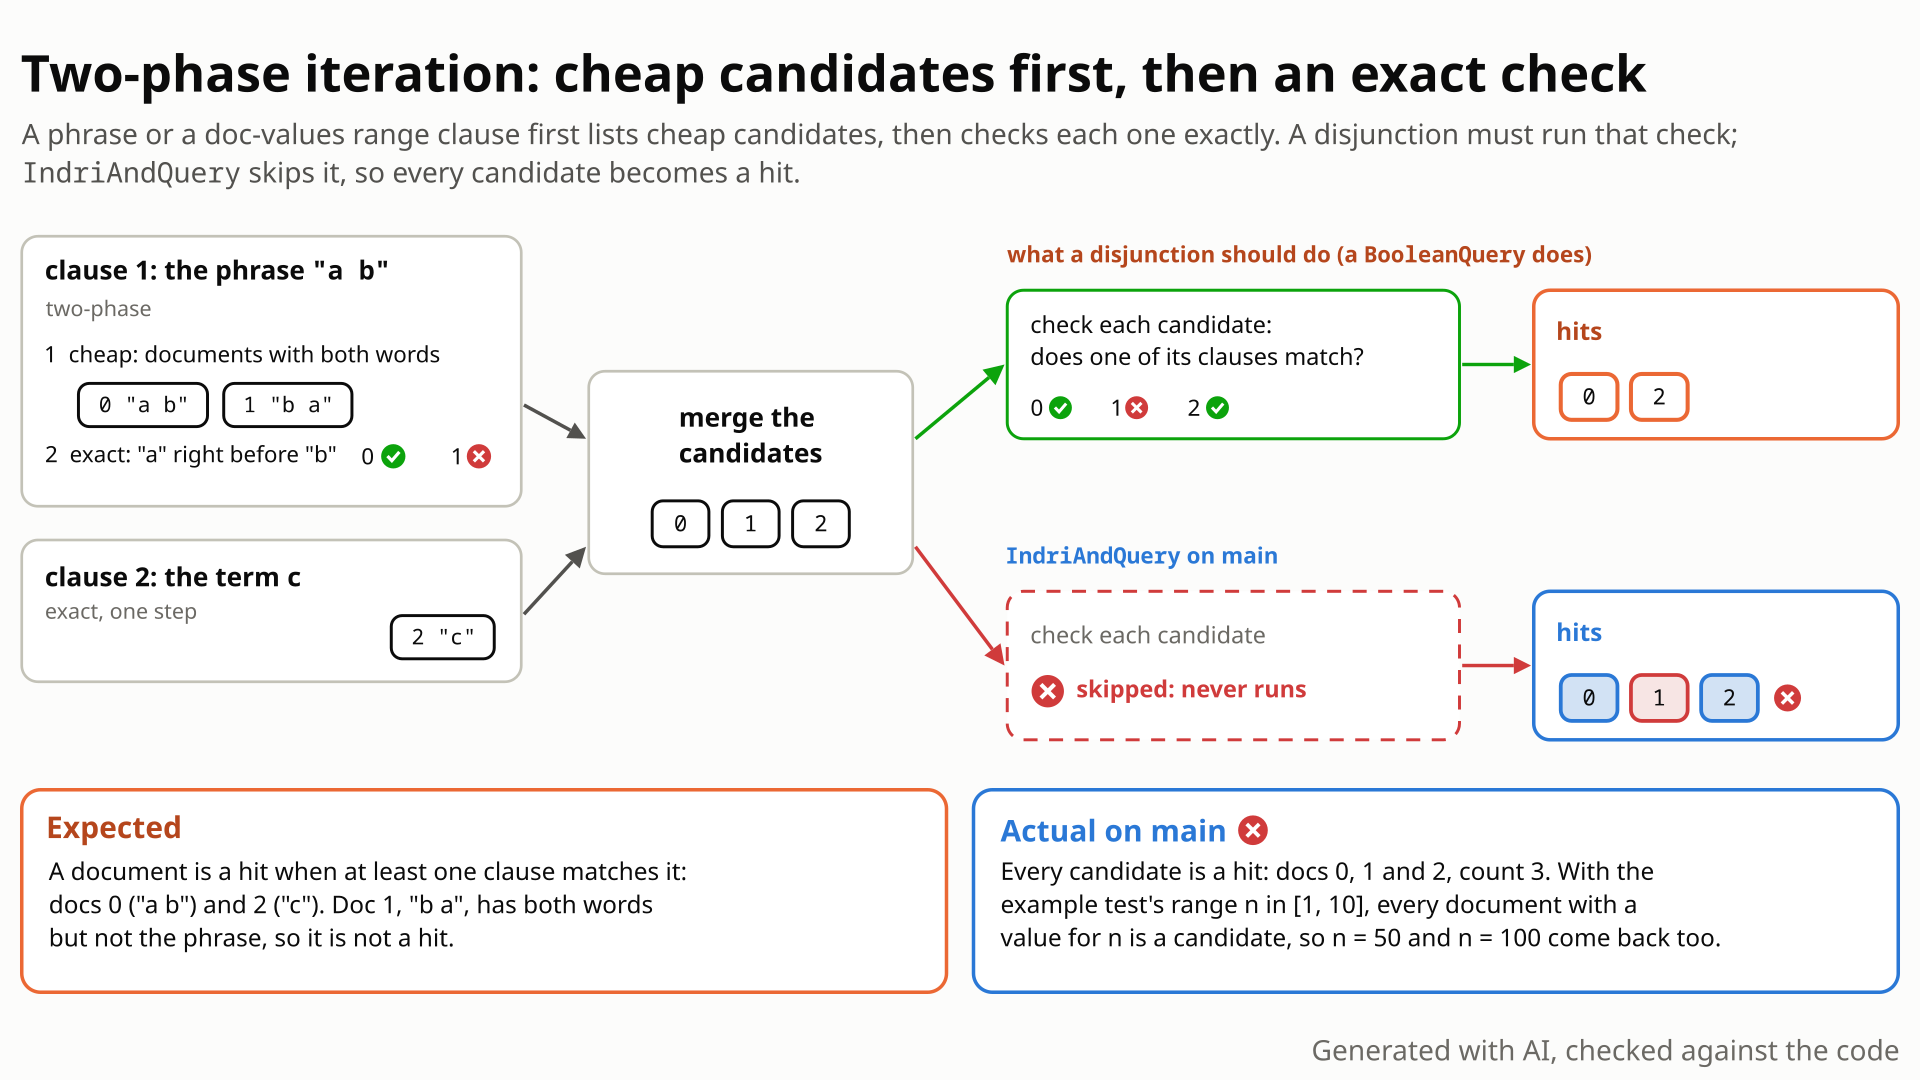
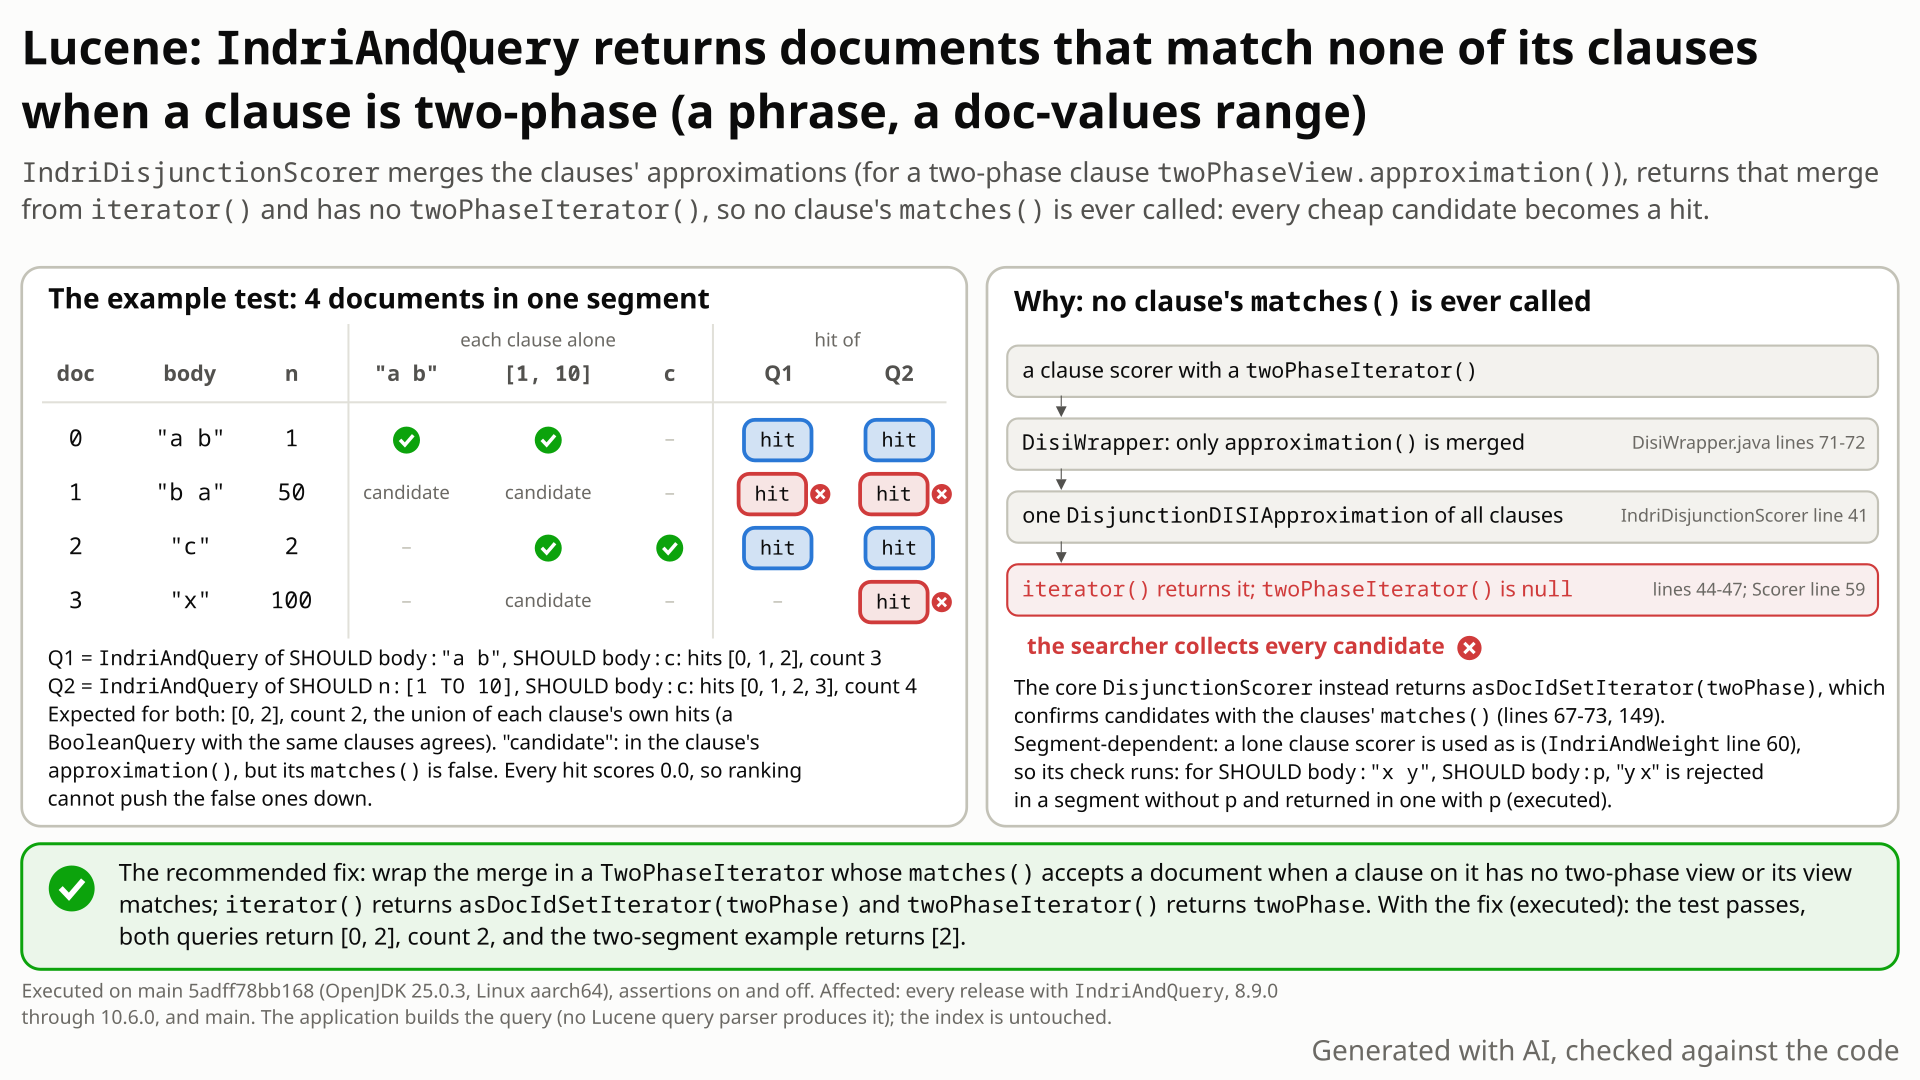
IndriDisjunctionScorer iterates, the matches() call that never happens, and the hits that come back, for the phrase "a b" and for the range n:[1 TO 10], each next to body:c. Select the still to open it at full size. Generated with AI, checked against the code.- Index three documents: doc 0 with the doc-values field
n=1, doc 1 withn=50, doc 2 withbody=cand non. - Search
IndriAndQuerywith two SHOULD clauses, the doc-values rangen:[1 TO 10]and the termbody:c. You expect docs 0 and 2, which aBooleanQuerywith the same clauses returns. - Instead you get docs 0, 1 and 2, and
count()says 3: doc 1 (n=50) matches neither clause. All three hits score 0.0. A phrase does the same: on "a b", "b a", "c", "x", the phrase "a b" next tobody:creturns "b a" too. - Why: a range or phrase query checks a document in two steps, a cheap candidate step (has a value, has all the words) and the exact
matches().IndriDisjunctionScorermerges the candidate steps of its clauses and never callsmatches(). - It happens only in segments where two or more clauses have a scorer, so the same document can be a hit in one segment and not in another.
Applications that build IndriAndQuery themselves (a public core API that no Lucene parser creates) with a phrase, doc-values range or other two-phase clause next to another clause. Default settings, any index size. Hits and count() are wrong with no error, every hit scores 0.0 (clause types tested), and the answer can change when segments flush or merge.
Mechanism, terms and numbers688 words
IndriAndQuery should return the documents that match at least one of its clauses ("matches documents matching combinations of subqueries", IndriAndQuery.java:22). When two or more clauses have a scorer in a segment, IndriAndWeight scores them with an IndriAndScorer, an IndriDisjunctionScorer (IndriAndWeight.java:47-65). That scorer wraps each clause scorer in a DisiWrapper, whose approximation for a two-phase clause is twoPhaseView.approximation() (DisiWrapper.java:69-73), merges those approximations in a DisjunctionDISIApproximation (IndriDisjunctionScorer.java:36-41) and returns the merge from iterator() (:44-47) without a twoPhaseIterator(). Nobody ever calls a clause's matches(), so every document in a phrase clause's "has all the words" set or a doc-values range's "has a value" set (for a field without a skip index, the default) becomes a hit. In the three-document repro the range n:[1 TO 10] next to body:c returns [0, 1, 2], count() 3, instead of [0, 2]; all hits score 0.0, and no error is raised. A segment where only one clause has a scorer uses that scorer directly and is exact, so the result depends on which documents share a segment. Present since the Indri classes were added (LUCENE-9537, first released in 8.9.0), in every release to 10.6.0 and on main 5adff78bb168.
- Two-phase clauses. A
TwoPhaseIterator'smatches()"needs to be checked in order to know whether the returned doc ID actually matches" (TwoPhaseIterator.java:23-27).PhraseScorerreturns one (PhraseScorer.java:51-52); so does the slow doc-values range without a skip index (TwoPhaseIterator.asDocIdSetIterator(DocValuesRangeIterator.forRange(...)),lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:152-163). - Scorer choice.
IndriAndWeight.getScorercollects the non-null clause scorers; a single one is returned as is, two or more are wrapped innew IndriAndScorer(subScorers, ...)(IndriAndWeight.java:47-65), a subclass ofIndriDisjunctionScorer(IndriAndScorer.java:26). - The defect. The
IndriDisjunctionScorerconstructor wraps every clause scorer innew DisiWrapper(scorer, false)(IndriDisjunctionScorer.java:36-40); for a two-phase scorer the wrapper'sapproximationistwoPhaseView.approximation()(DisiWrapper.java:69-73). It merges them withnew DisjunctionDISIApproximation(wrappers, Long.MAX_VALUE)(:41), "a disjunction of the approximations of the provided iterators" (DisjunctionDISIApproximation.java:26-28), and returns that fromiterator()(:44-47). It does not overridetwoPhaseIterator(), so it inheritsreturn null(Scorer.java:58-60). - Nobody filters. A consumer that sees no two-phase view treats
iterator()as exact:DefaultBulkScorerusesscorer.iterator()whentwoPhaseIterator()is null (Weight.java:236-243). Executed on the repro's index: the query's scorer is anIndriAndScorer,twoPhaseIterator()is null, anditerator()yields[0, 1, 2]. - What the core does.
DisjunctionScorerbuilds the same merge but, when any sub-scorer is two-phase, wraps it in aTwoPhase(DisjunctionScorer.java:42-63), returnsTwoPhaseIterator.asDocIdSetIterator(twoPhase)fromiterator()and exposes it fromtwoPhaseIterator()(:66-78); itsmatches()accepts a document only when a sub-scorer without a two-phase view is on it or a two-phase view matches (:118-157). - Scores cannot hide it.
IndriAndScorer.scoreDocadds only children that areIndriScorers (IndriAndScorer.java:47-62); term, phrase and doc-values scorers are not, so the score is 0 (:64-65) for real and false hits alike. That all-zero scoring is a separate, already-discussed issue (#10577); here it only means ranking cannot push the false hits down. - Segment dependence. Because of step 2, a segment where only the two-phase clause has a scorer is exact. Executed with two segments,
{n=50}and{n=50}, {body=c}: the first segment uses the range's own scorer and its n=50 document is not returned; the second uses anIndriAndScorerand its identical n=50 document is returned (hits[1, 2];BooleanQuerygives[2]).
| query on {n=1}, {n=50}, {body=c} | hits | count |
|---|---|---|
n:[1 TO 10] alone | [0] | 1 |
body:c alone | [2] | 1 |
BooleanQuery SHOULD of both | [0, 2] | 2 |
IndriAndQuery SHOULD of both | [0, 1, 2], all score 0.0 | 3 |
IndriAndQuery, recommended fix | [0, 2] | 2 |
The finder's four-document test ("a b" n=1, "b a" n=50, "c" n=2, "x" n=100) gives [0, 1, 2], count 3, for [SHOULD body:"a b", SHOULD body:c] and [0, 1, 2, 3], count 4, for [SHOULD n:[1 TO 10], SHOULD body:c], where only [0, 2] match, on every version run from 8.9.0 to main.
Exposure and likelihood396 words
- Who is hit. Code that calls
new IndriAndQuery(List<BooleanClause>)(public, inorg.apache.lucene.search); outside tests onlyIndriAndQuery.javaandIndriAndWeight.javamention the class, so no parser or other Lucene code builds it. - Trigger. Two or more clauses with a scorer in the same segment, at least one of them two-phase. Executed with
PhraseQuery,SortedNumericDocValuesField.newSlowRangeQueryandNumericDocValuesField.newSlowRangeQuery. By reading, not run, any clause whose scorer returns aTwoPhaseIteratortakes the same path, for exampleMultiPhraseQuery, theSortedNumericDocValuesFieldandNumericDocValuesFieldnewSlowSetQuery, and theSortedDocValuesFieldandSortedSetDocValuesFieldnewSlowRangeQuery. TheSortedDocValuesFieldandSortedSetDocValuesFieldnewSlowSetQuerydo not get this far: they return a rewrite-onlyTermInSetQuery, and sinceIndriAndWeightnever rewrites its clauses (IndriAndWeight.java:41-44) they throwUnsupportedOperationException, a separate defect (LFV-299). All runs use SHOULD clauses only;IndriAndWeightignores the clauses'Occur, a separate defect (LFV-871). - Default vs opt-in. A plain
IndexWriterConfigandIndexSearcher, no skip index; assertions on or off; opt-in only in choosingIndriAndQuery. The runs used the test framework's randomized codec (seed DEADBEEF:Asserting(Lucene104)); by reading, the path depends on the scorers, not on the codec. - Size. Every document in the two-phase clause's approximation becomes a hit (in each segment where another clause also has a scorer): for a doc-values range on a field without a skip index (the default), every document with any value in the field; for a phrase, every document that has all its words (from the mechanism). With a skip index the candidates are instead every document of each skip block whose value range overlaps the query, documents with no value included (
SkipBlockRangeIterator.java:67-87; by reading, not run).count()agrees with the wrong hits, so totals and paging are wrong too. - Silent and unstable. No exception; all hits score 0.0 (with the clause types tested); whether a document is returned depends on which documents share its segment, so results can change after a flush or merge.
- Bounded. An enclosing
BooleanQueryFILTER still restricts every hit, deleted documents never appear, and every extra hit lies in some clause's approximation (an executed bounds probe, 4 of 4 checks pass with assertions on and off). The index is never changed. - Why tests missed it. Upstream
TestIndriAndQueryuses only plainTermQueryclauses: both tests call the two-argumenttq()(TestIndriAndQuery.java:113-114,:130-131); a boostedtq(f, t, b)helper exists (:151-154) but is never called.
One JUnit test in lucene/core, public API only: three documents in a ByteBuffersDirectory, IndriAndQuery(SHOULD n:[1 TO 10], SHOULD body:c), and one assertion that the hits are docs 0 and 2. Fixed data and query, single thread. It fails on main with assertions on and off, and on the 10.6.0 and 9.12.3 release jars.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.util.Arrays;
import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.SortedNumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIndriAndQueryTwoPhaseClause extends LuceneTestCase {

  public void testHitsMatchAtLeastOneClause() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (long n : new long[] {1, 50}) {
          Document doc = new Document();
          doc.add(new SortedNumericDocValuesField("n", n));
          w.addDocument(doc);
        }
        Document doc = new Document();
        doc.add(new StringField("body", "c", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        Query query =
            new IndriAndQuery(
                List.of(
                    new BooleanClause(
                        SortedNumericDocValuesField.newSlowRangeQuery("n", 1, 10), Occur.SHOULD),
                    new BooleanClause(new TermQuery(new Term("body", "c")), Occur.SHOULD)));
        List<Integer> hits =
            Arrays.stream(new IndexSearcher(reader).search(query, 10).scoreDocs)
                .map(hit -> hit.doc)
                .sorted()
                .toList();
        // doc 0 (n=1) matches the range, doc 2 matches body:c; doc 1 (n=50) matches neither
        assertEquals(List.of(0, 2), hits);
      }
    }
  }
}
cp $REPRO/TestIndriAndQueryTwoPhaseClause.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestIndriAndQueryTwoPhaseClause -Ptests.seed=DEADBEEF
# also with -Ptests.asserts=false
- Expected
- Hits
[0, 2]: doc 0 (n=1) is in the range and doc 2 hasbody:c. - Observed
expected:<[0, 2]> but was:<[0, 1, 2]>: doc 1 (n=50, no body) is returned, with assertions on and off.
More files, environment, full output246 words
The test fixes the directory, the documents, the query and the searcher (a plain IndexSearcher); the test framework still picks its environment per seed (seed DEADBEEF ran with codec=Asserting(Lucene104), locale=nl-CW); seed C0FFEE (run with assertions off) gives the same message as DEADBEEF. The field has no skip index, so the range clause takes its two-phase path: its candidates are the documents with an n value (docs 0 and 1), and its matches() would keep only doc 0. The test needs org.apache.lucene.tests.*, so it compiles against 9.1.0 and later.
The same bug with a phrase clause ("b a" returned for the phrase "a b") goes through the same lines; the finder's four-document test, described in the full explanation above, shows it on every version from 8.9.0 to main.
Suggested regression test: this same test, as one method in TestIndriAndQuery or as its own class.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT); also the 10.6.0 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (the only platform run; pure Java logic) |
# main 5adff78bb168, gradle, seed DEADBEEF, -Ptests.asserts=false (assertions on: the same failure)
TestIndriAndQueryTwoPhaseClause > testHitsMatchAtLeastOneClause FAILED
    java.lang.AssertionError: expected:<[0, 2]> but was:<[0, 1, 2]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:25136116A809E31E]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.junit.Assert.assertEquals(Assert.java:146)
        at org.apache.lucene.search.TestIndriAndQueryTwoPhaseClause.testHitsMatchAtLeastOneClause(TestIndriAndQueryTwoPhaseClause.java:61)
:lucene:core:test (FAILURE): 1 test, 1  failure

# 10.6.0 and 9.12.3 release jars, -da: the same 'expected:<[0, 2]> but was:<[0, 1, 2]>'
# with the recommended fix on main: 1 test, 0 failures (assertions on and off)Scorer#iteratoris "a DocIdSetIterator over matching documents"; only aTwoPhaseIteratormay over-match, and itsmatches()"needs to be checked".IndriAndQuery"matches documents matching combinations of subqueries"; upstream tests expect exactly the clauses' matches, and the coreDisjunctionScorercallsmatches().- A hit with n=50 for the range
[1, 10], and hits that change with segment layout, break those contracts.
The full argument141 words
- Contracts.
Scorer.java:33-34: "Return a DocIdSetIterator over matching documents".TwoPhaseIterator.java:23-27: after the approximation moves,matches()"needs to be checked in order to know whether the returned doc ID actually matches".IndriAndQuery.java:22: "A Query that matches documents matching combinations of subqueries". - Tests.
TestIndriAndQuery.testSimpleQuery1asserts "2 docs should match" for[george, washington],testSimpleQuery2"all docs should match" (TestIndriAndQuery.java:111-144). - The author's description. "We iterate through all documents that that [sic] have a posting for at least one of the search terms" (cammiemw, lucene-solr#2097 r555482275, 2021-01-12). On #10577 (2020-09-22) Cameron VandenBerg, the feature's author, wrote: "For the IndriDisjuctionScorer, I was using Lucene's DisjunctionScorer as an example for implementing the docID function."
- The core counterpart confirms matches (
DisjunctionScorer.java:42-78,:118-157). - Precedent. #7477 (LUCENE-6418, "SpanNot sometimes forgets to call matches() on excl approximation") was fixed as a bug in 2015.
The devil's-advocate check242 words
Strongest case for "misuse". The Indri code was designed for term clauses and nested IndriAndQuery clauses only: the PR's first javadoc read "combinations of {@link TermQuery}s or other IndriAndQuerys"; mikemccand asked on the introducing PR "it looks like we are only supporting TermQuery and other IndriAndQuery clauses ... If so, should we check/enforce this?" (lucene-solr#2097 r532221029, 2020-11-29); jpountz later proposed on #11194 that IndriAnd and IndriOr "only accept instances of IndriQuery as opposed to Query". Read that way, a phrase or range clause is outside the design.
Why it fails. The day after that review comment, the PR commit 8e784de47c27 ("Addressed first set of git pull request comments", 2020-11-30) changed the javadoc to "combinations of subqueries", and no check was added. The reviewer pinged once more on 2020-12-14 and the thread has no reply. The public constructor accepts any BooleanClause (IndriAndQuery.java:25-27), no javadoc, CHANGES or MIGRATE text warns about two-phase clauses, and the restriction proposed on #11194 was never made. Even under an Indri "candidate set" reading, returning n=50 for the range [1, 10] breaks the Scorer#iterator and TwoPhaseIterator contracts above, and the same document is a hit in one segment and not in another. Whether maintainers prefer the scorer fix or a restrictive one (rejecting such clauses, or a move to the sandbox) is their call. Verdict: a defect. Not security: the application builds the query, it is a disjunction rather than a restriction, and enclosing filters still apply.
Recommended Expose a TwoPhaseIterator that confirms a clause match
Give IndriDisjunctionScorer a TwoPhaseIterator when any clause is two-phase, as DisjunctionScorer does: matches() accepts the document if some clause on it has no two-phase view or its view matches, and iterator() returns TwoPhaseIterator.asDocIdSetIterator(twoPhase). With it the repro passes and the whole core org.apache.lucene.search test package passes (216 classes, 2,351 tests, 0 failures).
All options and trade-offs3 options · 662 words
The recommended fix was applied to a scratch worktree of 5adff78bb168 and run through gradle; the other options were not run.
In the IndriDisjunctionScorer constructor, note whether any DisiWrapper has a twoPhaseView; if so, build a TwoPhaseIterator over the DisjunctionDISIApproximation whose matches() walks approximation.topList() and returns true at the first wrapper with no two-phase view or whose view matches. iterator() returns TwoPhaseIterator.asDocIdSetIterator(twoPhase) and twoPhaseIterator() returns twoPhase; with no two-phase clause nothing changes. +36/-2 lines in IndriDisjunctionScorer.java.
private final DisjunctionDISIApproximation approximation;
private final TwoPhaseIterator twoPhase; // null when no clause is two-phase

// constructor, after building the approximation:
if (hasTwoPhase) {
  final DisjunctionDISIApproximation approx = this.approximation;
  this.twoPhase =
      new TwoPhaseIterator(approx) {
        @Override
        public boolean matches() throws IOException {
          for (DisiWrapper w = approx.topList(); w != null; w = w.next) {
            if (w.twoPhaseView == null || w.twoPhaseView.matches()) {
              return true;
            }
          }
          return false;
        }

        @Override
        public float matchCost() {
          float cost = 0;
          for (DisiWrapper w : wrappers) {
            cost += w.matchCost;
          }
          return cost;
        }
      };
} else {
  this.twoPhase = null;
}

@Override
public DocIdSetIterator iterator() {
  return twoPhase == null ? approximation : TwoPhaseIterator.asDocIdSetIterator(twoPhase);
}

@Override
public TwoPhaseIterator twoPhaseIterator() {
  return twoPhase;
}
Trade-offs
- The same check the core
DisjunctionScorer.TwoPhasemakes; queries with term clauses only are unchanged. When some clause is two-phase, the newmatches()runs on every document of the merged approximation and stops at the first wrapper on it with no two-phase view or a matching view. UnlikeDisjunctionScorer.TwoPhase, which checks the exact clauses first (DisjunctionScorer.java:123-143), it may call a two-phase clause'smatches()on a document an exact clause already matches; same result, but a reviewer may want that order. matchCostis a plain sum of the clauses' costs, a rough upper bound;DisjunctionScoreruses a cost-weighted average (DisjunctionScorer.java:48-61), which a reviewer may prefer.- Scoring caveat:
IndriAndScorer.scoreDoctreats anIndriScorerchild as present when itsdocID()equals the document (IndriAndScorer.java:49-58), so a nestedIndriAndQuerychild standing on an unconfirmed candidate would still be scored as present. With today's all-zero scores that changes nothing; the next option closes it. - The open, stale PR #463 would need the same change if it is ever revived: it changes only the superclass of
IndriDisjunctionScorer(+2/-2) and adds anIndriOrScorerthat extends it.
What the checks validated
- Gradle, scratch worktree of
5adff78bb168with the repro test added, seed DEADBEEF: stock, the repro fails with-Ptests.asserts=trueandfalse; with the fix it passes both ways. - With the fix:
TestIndri*plus the repro, 3 tests, 0 failures; the whole coreorg.apache.lucene.search.*test package (with its subpackages), 216 classes, 2,351 tests, 0 failures, 0 errors, 49 skipped. :lucene:core:checkGoogleJavaFormatpasses with the fix.- Earlier runs with the same change: the bounded-exhaustive check lost exactly its 119 hits that match no clause (6,708 checks) and gained no miss; the independent reproducer's five cases and the finder's test pass.
- Not run: the full Lucene test suite, and any platform other than Linux aarch64 with OpenJDK 25.0.3.
On top of the first option, have IndriAndScorer.scoreDoc treat a child with a two-phase view as present only when its match on this document was confirmed. Not run.
Trade-offs
Makes scores of nested Indri queries exact once Indri scoring is non-zero. More code: the confirmation must be remembered, because matches() may be called at most once per document (TwoPhaseIterator.java:96-101). No visible effect while all Indri scores are 0.
Validate in the IndriAndQuery constructor that every clause is a (boosted) TermQuery or an IndriQuery, as asked in the 2020 review and proposed on #11194. Not run.
Trade-offs
Stops the wrong hits by refusing phrase and range clauses: it breaks callers that pass them today and takes phrase matching away from Indri queries, while the scorer fix is small. Not recommended.
Downstream products are affected only if they build IndriAndQuery with phrase or doc-values clauses; issue searches of Elasticsearch, OpenSearch and Solr for IndriAndQuery found nothing.
While writing a Z3 model of how IndriAndQuery decides which documents match, reading IndriDisjunctionScorer showed that it never calls matches(). A Z3 query then produced a hit that matches no clause, and a bounded-exhaustive check of the real jar found 119 such hits in 6,708 cases, all gone with the fix.
The method in full156 words
Method: semi-formal. The hypothesis came from code reading while modelling IndriDisjunctionScorer for a Z3 model of IndriAndQuery matching (2026-10-28, main a9779ef3c193). A Z3 query for "a hit that matches none of its clauses" is satisfiable when two or more clause scorers are present in a segment and one is two-phase, and unsatisfiable with a single scorer, with no two-phase clause, and with the fix.
A bounded-exhaustive translation validation of the real core jar then compared the jar with the model: 258 SHOULD-only clause lists over 3 terms and 3 phrases, 13 documents, 2 segment layouts, 6,708 checks, 0 model mismatches; 119 hits matched none of their clauses (92 in one layout, 27 in the other). With the fix applied to the jar's classes, exactly those 119 hits disappeared and no miss appeared. A public-API JUnit (the finder's four-document test) confirmed it on the stock jars; this doc's minimal test is a smaller version of it.
No earlier report of this defect found in Lucene issues and PRs (with the JIRA archive), commits, open PRs, the mailing lists or Elasticsearch, OpenSearch and Solr (searched 2026-10-28, re-run 2026-11-03). Two related items, #11194 and a 2020 review question, discuss Indri design and allowed clause types, not wrong hits.
Searches4 searches
Related prior items, each about a different matter:
- #11194 (LUCENE-10157, open feature issue): jpountz wanted the Indri code in the sandbox to "leave us more time to think more about how this could be integrated with dynamic pruning, two-phase iteration, the similarity API, etc." (2022-01-05) and later proposed accepting only
IndriQueryclauses (2022-01-11). An API-placement and design discussion: it reports no wrong hits and does not say thatIndriDisjunctionScorerskipsmatches(). - lucene-solr#2097 r532221029 (mikemccand, 2020-11-29, on the introducing PR): asked whether only
TermQueryandIndriAndQueryclauses are supported and whether to enforce that. A question about which clause types are allowed; it does not describe what happens with a two-phase clause. - #10577 (LUCENE-9537, the introducing feature issue "Add Indri Search Engine Functionality to Lucene"): a later comment (jpountz, 2021-11-23) reports that every matching document scores 0, because
IndriAndScoreronly scoresIndriScorerchildren. A scoring matter; it does not mention extra hits ormatches(). - PR #463 (open, stale, LUCENE-10157): changes only the superclass of
IndriDisjunctionScorer(+2/-2 lines) and adds anIndriOrScorerthat extends it, keeping the approximation-only iterator, so if merged the same defect would reachIndriOrQuery.IndriWeightedSum, still in the PR title, was removed from the PR in its commit20e8c9c1c7(2022-01-10). A feature PR; it does not mention the missingmatches()call. - #7477 (LUCENE-6418, fixed 2015): the same class of bug in
SpanNot, a precedent.
Related findings on this site, with separate fix sites: LFV-875 (explain of a non-hit reports a match, IndriAndWeight.explain) and LFV-871 (clause Occur ignored). Limits: keyword search only, so "not found" does not prove that no report exists; one JIRA query of the search script failed; private channels are not searchable.
| Where | When | How | Found |
|---|---|---|---|
| GitHub, commits, mailing lists, JIRA archive, downstream (search script) | 2026-11-03 | 45 queries: 16 GitHub issue/PR on apache/lucene, 3 commit, 2 downstream (Elasticsearch, OpenSearch, Solr), 20 mailing-list (dev@, java-user@, issues@, commits@), 4 JIRA archive (1 failed) | 511 distinct hits, 0 with high term overlap; the 15 medium ones are general TwoPhaseIterator items, none about Indri |
| GitHub (apache/lucene, lucene-solr, Elasticsearch, OpenSearch, Solr) | 2026-11-03 | 20 manual GitHub searches and reads: every issue and PR mentioning Indri; IndriDisjunctionScorer, IndriAndQuery, 'Indri two-phase', 'Indri phrase'; Indri items updated since 2026-10-28; open PRs naming IndriDisjunctionScorer; last commits to the file on main, branch_11x and branch_10_6 | issues #11194, #10577, #4033, #2614 and PRs #463, #15818, none reporting this; 0 results for the class names; last commit to the file 54283150a81 (2026-06-14) |
| GitHub, JIRA archive, mailing lists, web, open PRs | 2026-10-28 | about 260 queries and reads, including the changed files of all 410 open apache/lucene PRs and of the 51 PRs closed since 2026-10-14 | no report; related design remarks only (#11194, lucene-solr#2097 r532221029) |
| GitHub (apache/lucene issues and PRs) | 2026-11-03 | last re-check while revising this page: IndriDisjunctionScorer, IndriAndQuery, 'Indri twoPhaseIterator', 'Indri matches approximation' (further queries rate-limited); PR #463 files and commits read | 0 results for each query; PR #463 confirmed as a feature PR (see above) |
Introduced with the Indri classes by LUCENE-9537 (9cc5c9b7983, 2021-01-29) and first released in 8.9.0. Executed on 8.9.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2, 10.6.0 and main; not fixed upstream.
Versions tested8 rows
9cc5c9b7983 ("LUCENE-9537: Add initial Indri search engine functionality to Lucene", cammiemw, PR apache/lucene-solr#2097, author date 2021-01-29; issue now #10577) added the Indri classes, backported to branch_8x as a6125fb9385. That commit already had new DisiWrapper(scorer), new DisjunctionDISIApproximation(this.subScorers) and iterator() { return approximation; }, and no Indri class has ever had a twoPhaseIterator(). The later commits to the file (#13440, #14023, #14052, #16255) are mechanical, so this is not a regression. 8.8.2 has no IndriAndQuery. Upstream (read 2026-11-03): the last commit to IndriDisjunctionScorer.java on main and branch_11x is 54283150a81 (2026-06-14), on branch_10_6 dc49e0cb5eb (2024-12-16).
| Version or commit | Verdict | Result |
|---|---|---|
| 8.8.2 | no API | no IndriAndQuery; the test does not compile |
| 8.9.0 | first release | the finder's test fails (-ea, -da): [0, 1, 2] and [0, 1, 2, 3] where [0, 2] match |
| 8.11.4, 9.0.0 | affected | the finder's test fails, same hits |
| 9.1.0, 9.12.3, 10.0.0, 10.5.2 | affected | the finder's test fails (10.5.2 with -ea and -da); the minimal test fails on 9.12.3 (-da) |
10.6.0 (4ae946e5a9b9) | affected | the minimal test fails (-da), same message as main |
main a9779ef3c193, e1faeba08bde | affected | the finder's test fails, -ea and -da |
main 5adff78bb168 | affected | the minimal test fails, gradle and standalone, assertions on and off |
main 5adff78bb168 + two-phase fix | fix | the minimal test passes; core search package: 216 classes, 2,351 tests, 0 failures |
An independent reproducer, reading-only cross-model reviews, an intended-behaviour review and an adjudication all found it real (one review said not real only because it could not run code); it still reproduces on main e1faeba08bde, and this doc's runs reproduced it and validated the fix through gradle.
Checks and verdicts343 words
Every executed check reproduced the extra hits; every control (each clause alone, a BooleanQuery with the same SHOULD clauses, term-only Indri queries) agreed that these documents do not match.
| Check | Verdict | What it found |
|---|---|---|
| finder (Z3 model, bounded check of the real jar, four-document JUnit) | reported | 6,708 checks, 0 model mismatches, 119 hits that match no clause, all removed by the fix; the JUnit fails on main, branch_10_6, 10.5.2, 9.12.3 and back to 8.9.0. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real, procedural only | Could not run code, so it voted not real on procedure only; it agreed on the root cause, wrote that the static evidence strongly favours a genuine silent-wrong-results defect, and added the nested-scoring caveat. |
| independent reproducer | real | Own five-case JUnit outside org.apache.lucene, oracle a BooleanQuery with the same SHOULD clauses: 4 of 5 fail on main, 10.5.2 and 9.12.3 (two phrases [0, 1, 2, 3] instead of [0, 2]; NumericDocValuesField range [0, 1, 2, 3, 4] instead of [0, 2, 4]; segment dependence; scorer contract); the term-only control passes; 5 of 5 pass with the fix. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Rated the 'Indri candidate set' argument weak; a separate executed control (IndriAndQuery against BooleanQuery SHOULD) fails on main and passes with the fix. |
| intended-behaviour review | real | Built the design-scope case (term and nested Indri clauses only, the 2020 review question) and rejected it; its own test fails on main and 10.5.2. |
| adjudication | confirmed (high) | Re-ran the independent reproducer's test with a new seed: 4 of 5 fail; with the fix 5 of 5 pass. |
| re-run on newer main | still reproduces | The finder's test fails 1 of 1 with -ea and -da on main e1faeba08bde (2026-11-02). |
| this doc (minimal test, gradle fix validation, diagnostics) | real; fix validated | The minimal test fails on main 5adff78bb168 (-ea and -da with seed DEADBEEF, -da with C0FFEE), 10.6.0 and 9.12.3; passes with the fix; the core search package passes with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 512 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,459 words
- Registry title
- IndriAndQuery returns documents that match none of its clauses when a clause uses two-phase iteration (PhraseQuery, doc-values range queries), because IndriDisjunctionScorer iterates the clauses' approximations and never calls TwoPhaseIterator.matches()
- Area
- search / IndriAndQuery (IndriDisjunctionScorer iteration over two-phase clauses)
- Priority
- Medium, rank 64: Since 8.9 the opt-in IndriAndQuery silently returns extra hits when a phrase or doc-values range clause is combined with another clause; that changes hits, where LFV-744 only changes scores.
- Impact class
- silent wrong results
- Impact note
- Applications that build an IndriAndQuery (a rarely used core query that no Lucene query parser produces) with two or more clauses that have a scorer in the same segment, at least one of them two-phase (PhraseQuery, MultiPhraseQuery, doc-values range or set queries), get extra hits and an inflated count(): every document in that clause's approximation (all phrase terms present but not the phrase, or any value in the doc-values field) is returned, scoring the same as the real hits, with no error; default codec, IndexWriterConfig and searcher, any index size, -ea and -da, every release since 8.9.0; whether a document is returned depends on which other documents share its segment; the index is untouched.
- Summary
- You build an IndriAndQuery from SHOULD clauses, for example the phrase "a b" plus the term c, or a doc-values range n in [1, 10] plus the term c, and expect the documents that match at least one clause, as its javadoc ('matches documents matching combinations of subqueries') says. Instead it also returns documents that are only cheap candidates of the phrase or range clause: 'b a' (both terms, no phrase) in the phrase case and the documents with n=50 and n=100 in the range case, and count() agrees with the wrong hits (3 instead of 2, and 4 instead of 2, in the 4-document repro). IndriDisjunctionScorer walks the approximations of its two-phase clauses and never runs their exact matches() check; a segment where only one clause has a scorer is exact, so the same document can be rejected in one segment and returned in another.
- Introduced
- 9cc5c9b7983cf181280e18819f8516dc16ccf1ef (LUCENE-9537 'Add initial Indri search engine functionality to Lucene', author cammiemw, apache/lucene-solr#2097, feature issue now apache/lucene#10577), released through its branch_8x backport a6125fb938553fe2cd8cd035b8ffb329a7a1a288 (same author date) [read: git blame of 'iterator() { return approximation; }' on main and git log -G twoPhaseIterator over the Indri classes in the full-history clone find nothing else; exec: affected on 8.9.0, API absent on 8.8.2]; not a regression: the later commits d0d2aa274fb (#13440), f9869b54d54 (#14023), bc341f2b3e6 (#14052) and 54283150a81 (#16255) are mechanical and keep the approximation-only iterator (2021-01-29)
- First affected version
- 8.9.0 [exec] (first on the main line: 9.0.0 [exec]); the API does not exist before 8.9.0 [exec: the repro does not compile on 8.8.2, cannot find symbol IndriAndQuery]
- Affected versions
- Every release that has the class: 8.9.0 to 8.11.4, 9.0.0 to 9.12.3 and 10.0.0 to 10.5.2, 41 releases, plus 10.6.0 (the branch_10_6 head 4ae946e5a9b9, released 2026-10-29). [exec] finder JUnit (or its 8.x/9.0 variant, which differs only in two test-framework imports) fails with the same wrong hits on 8.9.0 (-ea and -da), 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da), branch_10_6 head 4ae946e5a9b9 (-da) and main a9779ef3c193 (-ea and -da, re-run at the registration check); the independent reproduction's own JUnit fails on main, 10.5.2 and 9.12.3, the intended-behaviour check's own JUnit on main and 10.5.2. [read] the other releases: the code is unchanged in this respect between the executed versions (10.0.0, before #14023/#14052, and 10.5.2, after them, give the same hits); upstream main c5ab3e57b9ba (2026-10-28) unchanged, the last commit on IndriDisjunctionScorer.java is 54283150a81 (author date 2026-06-14, typo check). Not applicable to 8.8.2 and earlier: no IndriAndQuery. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading; also reached by exhaustive check
- Upstream and prior reports
- related items only, no report of this defect (re-checked 2026-11-03; searched 2026-10-28 and refreshed the same day): no issue, PR, review comment, commit, JIRA entry, mailing-list thread, downstream issue or web page reports that an IndriAndQuery with a phrase, doc-values or other two-phase clause returns documents that match none of its clauses, or that IndriDisjunctionScorer never calls TwoPhaseIterator.matches() (three scripted prior-report searches, 160 queries over GitHub issues/PRs and commits, Elasticsearch/OpenSearch/Solr, dev@/java-user@/issues@/commits@ and the JIRA archive; 33 manual GitHub searches; changed-file scans of all 410 open apache/lucene PRs and of the 51 PRs closed since 2026-10-14; 40 REST reads; 5 list queries and 3 threads read; 2 JIRA queries; 10 web queries). Related, design remarks only, none reporting wrong hits: jpountz on apache/lucene#11194 (2022-01-05) said a sandbox would leave time to think about how the Indri code 'could be integrated with dynamic pruning, two-phase iteration, the similarity API'; mikemccand's unanswered review question lucene-solr#2097 r532221029 (2020-11-29, re-pinged r542490017) whether only TermQuery and IndriAndQuery clauses are supported and whether to enforce it; jpountz's 2022-01-11 proposal on #11194 to accept only IndriQuery clauses (never done). Related, not this bug: #10577 (all scores 0, a scoring defect), open stale PR #463 (rewrites IndriDisjunctionScorer but keeps the approximation-only iterator), open PR #11928 (DisjunctionDISIApproximation refactor), #11290/#469/#669 (smoothingScore removal); #7477 (LUCENE-6418, SpanNot forgot to call matches(), fixed 2015) is a precedent of the same defect class. Refresh the same day: a GitHub search for Indri PRs returns only #463 and #15818 (unrelated) and for issues #11194, #10577, #4033, #2614; none of the 15 PRs created since 2026-10-26 (up to #16926) is about Indri by title; no 'two-phase' issue created since 2026-10-20; the last upstream commit on IndriDisjunctionScorer.java is 54283150a81 (author date 2026-06-14). Not fixed anywhere.
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT), 2026-11-03: the minimal test with the standalone JUnit runner (-eaand-dawith seed DEADBEEF,-dawith C0FFEE) and through gradle in a scratch worktree (assertions on and off), stock and with the recommended fix, plusTestIndri*and the whole coreorg.apache.lucene.searchtest package with the fix; the 10.6.0 and 9.12.3 release jars (-da); scratch diagnostics forcount(), the scorer's shape and a two-segment layout. Earlier runs of the finder's four-document test: 8.9.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2, the branch_10_6 head4ae946e5a9b9(= 10.6.0) and maina9779ef3c193ande1faeba08bde. Every Indri, scorer and iterator source file involved is identical in all three main commits;SortedNumericDocValuesRangeQuery.javachanged aftera9779ef3c193only in its index-sort shortcut (#16893), which these tests do not reach. Only Linux aarch64 and OpenJDK 25.0.3 were run.
- Finding record
lucene/core/src/java/org/apache/lucene/search/IndriDisjunctionScorer.java:23-28 (class javadoc 'The Indri implementation of a disjunction scorer'), :31 and :41 (DisjunctionDISIApproximation over DisiWrappers of all sub-scorers), :44-47 (iterator() returns the approximation; no twoPhaseIterator() override)lucene/core/src/java/org/apache/lucene/search/DisiWrapper.java:69-75 (approximation = twoPhaseView.approximation() for a two-phase scorer); lucene/core/src/java/org/apache/lucene/search/DisjunctionDISIApproximation.java:27 ('a disjunction of the approximations of the provided iterators'); lucene/core/src/java/org/apache/lucene/search/DisjunctionScorer.java:80-98 (the core disjunction's TwoPhase calls twoPhaseView.matches())lucene/core/src/java/org/apache/lucene/search/IndriAndWeight.java:47-65 (getScorer: a lone clause scorer is returned as is, two or more are wrapped in IndriAndScorer); lucene/core/src/java/org/apache/lucene/search/IndriAndQuery.java:22 (javadoc 'A Query that matches documents matching combinations of subqueries'), :25-27 (public constructor, no validation); lucene/core/src/java/org/apache/lucene/search/IndriAndScorer.java:44-55 (scoreDoc compares each child's docID() with the doc: nested-child caveat)lucene/core/src/java/org/apache/lucene/search/Scorer.java:33-43 ('Return a DocIdSetIterator over matching documents'), :45-58 (twoPhaseIterator)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/IndriDisjunctionScorer.java:28-47, IndriAndWeight.java:47-65, IndriAndScorer.java:26, :44-69, DisiWrapper.java:69-77, DisjunctionDISIApproximation.java:26-28, DisjunctionScorer.java:42-78, :118-157, Scorer.java:33-60, TwoPhaseIterator.java:23-27, PhraseScorer.java:51-52, Weight.java:230-243 (main 5adff78bb168)lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:124-163 (main 5adff78bb168)
- Who is affected
grep -rln IndriAndQuery lucene/ at main 5adff78bb168 (outside tests: IndriAndQuery.java, IndriAndWeight.java)lucene/core/src/test/org/apache/lucene/search/TestIndriAndQuery.java:111-154 (main 5adff78bb168)lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:210, DocValuesRangeIterator.java:82-85, SkipBlockRangeIterator.java:67-87, IndriAndWeight.java:41-44, Query.java:67-69; lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesSetQuery.java:111-154, SortedSetDocValuesRangeQuery.java:160-163, SortedDocValuesField.java:126-127, SortedSetDocValuesField.java:130-131 (main 5adff78bb168)
- Minimal repro
lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesRangeQuery.java:124-163, :182-195 (no skip index: count -1, two-phase path; main 5adff78bb168)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/Scorer.java:33-34, TwoPhaseIterator.java:23-27, IndriAndQuery.java:22-27, DisjunctionScorer.java:42-78, :118-157 (main 5adff78bb168)lucene/core/src/test/org/apache/lucene/search/TestIndriAndQuery.java:111-144 (main 5adff78bb168)https://github.com/apache/lucene-solr/pull/2097#discussion_r532221029, #discussion_r542490017, #discussion_r555482275https://github.com/apache/lucene/issues/10577 (Cameron VandenBerg, 2020-09-22); https://github.com/apache/lucene/issues/11194 (jpountz, 2022-01-05 and 2022-01-11); https://github.com/apache/lucene/issues/7477
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/DisjunctionScorer.java:42-78, :118-157, IndriAndScorer.java:44-69, TwoPhaseIterator.java:96-101 (main 5adff78bb168)
- Prior reports
https://github.com/apache/lucene/issues/11194; https://github.com/apache/lucene-solr/pull/2097#discussion_r532221029; https://github.com/apache/lucene/pull/463; https://github.com/apache/lucene/issues/7477https://github.com/apache/lucene/issues/10577 (jpountz comment, 2021-11-23); gh api repos/apache/lucene/pulls/463/files and /commits (read 2026-11-03)
- Diagrams
lucene/core/src/java/org/apache/lucene/search/IndriDisjunctionScorer.java:36-47, DisiWrapper.java:69-73, IndriAndWeight.java:47-65 (main 5adff78bb168)
- TestIndriAndQueryTwoPhaseClause.java (lucene/core test, one method):
repro/LFV-874/src/org/apache/lucene/search/TestIndriAndQueryTwoPhaseClause.java(65 lines)
A step-by-step picture of the finder's four-document test (a phrase query and a range query, each next to body:c) on main 5adff78bb168, made from the code at that commit and the executed runs; the PNG is the summary still. The minimal repro is a three-document version of its range case.
assets/LFV-874/bug.png(512 KB)