Thai words with two of the documented typos in one character cluster keep one typo, and the word splitter glues them to their neighbours.
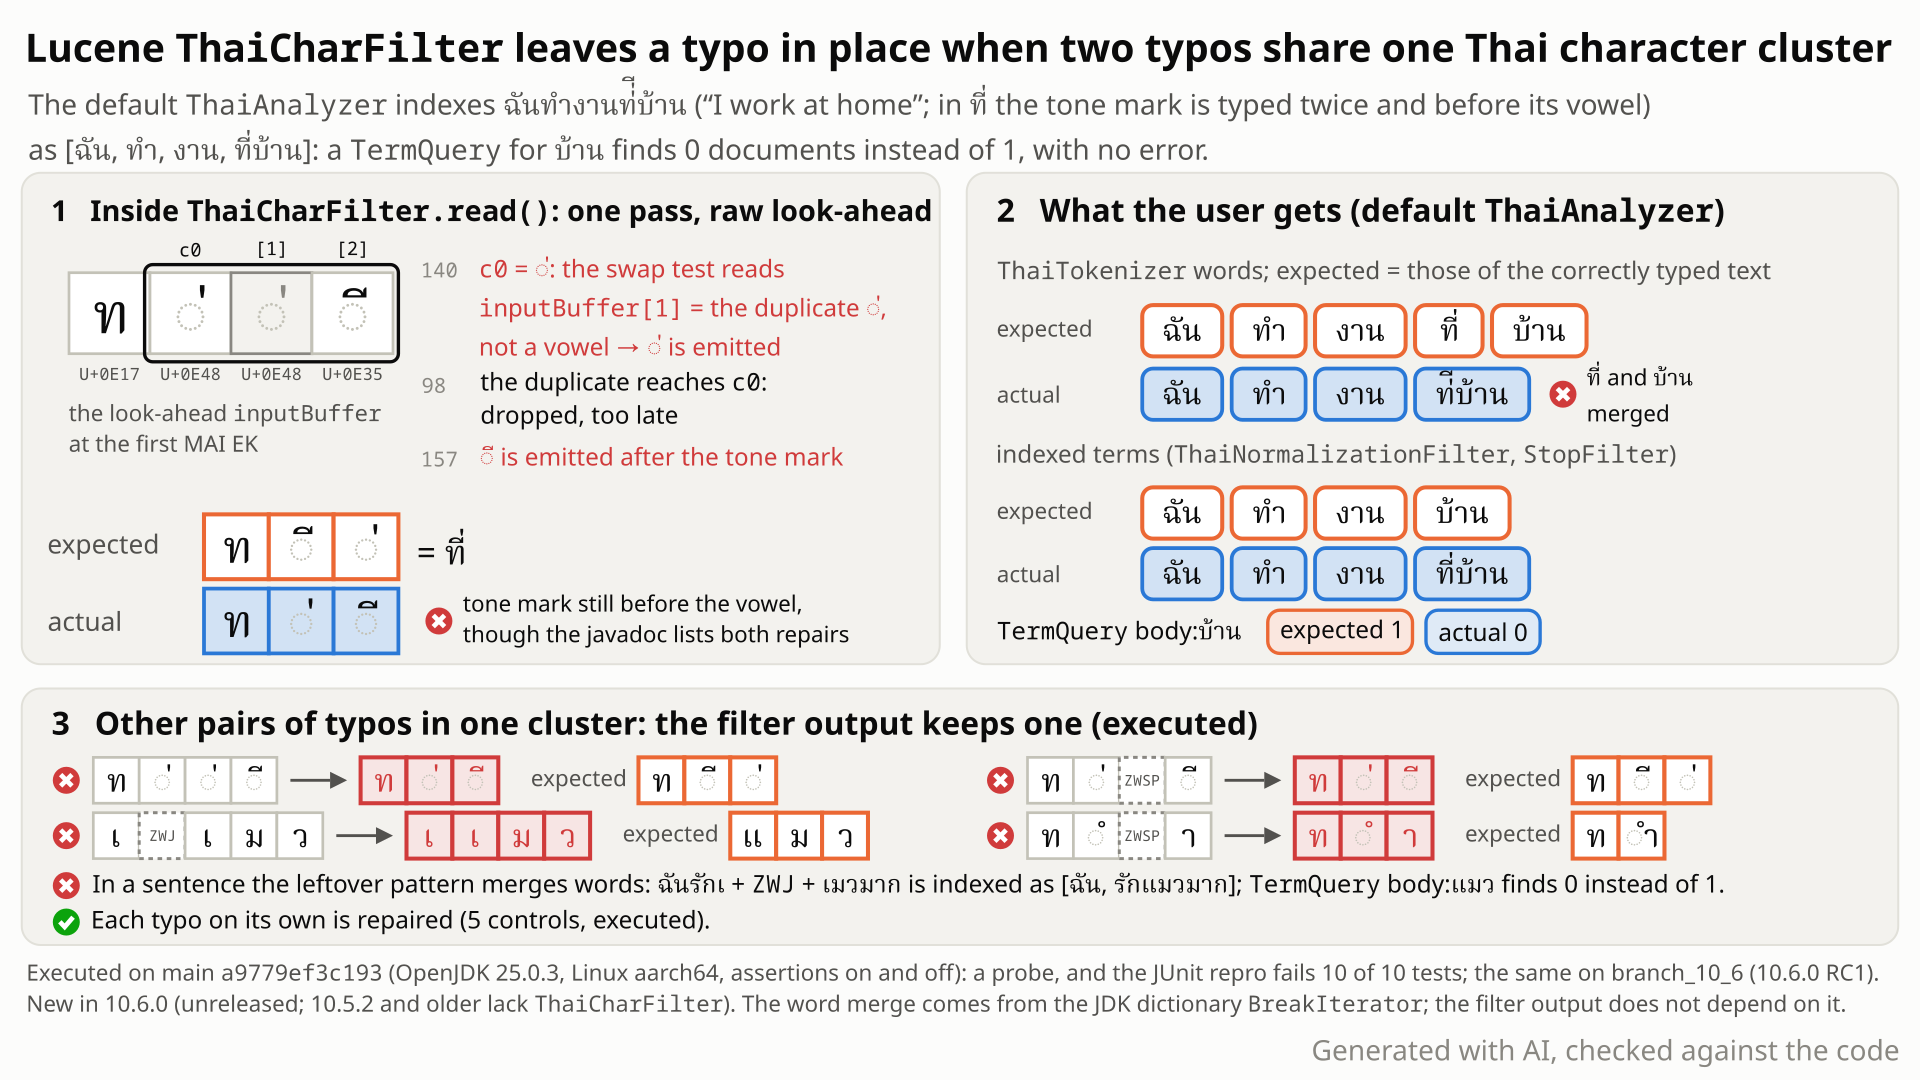
read() does with ท ่ ่ ี, one loop turn at a time, next to a single typo, and how the leftover pattern makes ThaiAnalyzer glue ที่ to บ้าน. Select the still to open it at full size. Generated with AI, checked against the code.- Index ฉันทำงานที่บ้าน ("I work at home") with the default
new ThaiAnalyzer(). It gives the terms [ฉัน, ทำ, งาน, บ้าน] (ที่, "at", is a stop word).ThaiCharFiltercleans the text before the word splitter sees it. - Type ที่ with one typo: the tone mark twice (ที่่) or before its vowel (ท่ี). The char filter fixes either one, and you still get [ฉัน, ทำ, งาน, บ้าน].
- Now make both typos at once: ท + ่ + ่ + ี. You expect the same four terms, and a search for บ้าน to find the document.
- Instead the filter outputs ท่ี: it tests "tone before vowel" while the second ่ still sits between them, drops that duplicate one step later and never re-tests the pair. The word splitter then merges: [ฉัน, ทำ, งาน, ที่บ้าน], and a
TermQueryfor บ้าน finds 0 documents instead of 1. - An invisible zero-width joiner between the two Sara E of แ does the same: ฉันรักเ+ZWJ+เมวมาก ("I love cats a lot") gives [ฉัน, รักแมวมาก] instead of [ฉัน, รัก, แมว]. No error; each typo on its own is fixed.
Thai fields on the default ThaiAnalyzer or the thai char filter, in 10.6.0 (released 2026-10-29), main and branch_10_6. It takes two documented typos in one character cluster, so it is expected to be rare; then a word and its correctly typed neighbour become one term, silently, at index and query time.
Mechanism, terms and numbers651 words
ThaiCharFilter, new in 10.6.0 and applied by the default ThaiAnalyzer before tokenization, exists because Thai typos such as a double Sara E or a zero-width character stop the JDK dictionary BreakIterator from finding word boundaries. It fixes each documented typo on its own. But it makes one pass and tests its multi-character rules (double Sara E, decomposed Sara Am, tone mark before an above/below vowel) on the raw next characters, while zero-width removal and deduplication act only on the character at the front of its buffer. When a zero-width character or a second copy of a tone mark sits inside such a pattern, the pattern is never rewritten, and the word splitter merges the word with its neighbour: a correctly typed neighbour such as บ้าน becomes unfindable. Silent, deterministic, in 10.6.0 (released 2026-10-29).
- Tone marks Mai Ek
่(U+0E48) and Mai Tho้(U+0E49) sit above a consonant, after any above/below vowel such as Sara Iiี(U+0E35): ที่ is ท + ี + ่. Typing the tone before the vowel (ท่ี) or twice (ที่่) is among the "common keyboard typing errors" the issue that proposed the class lists. - Sara Ae
แ(U+0E41) can be typed as two Sara Eเเ(U+0E40 U+0E40), which look the same. Sara Amำ(U+0E33) is often typed decomposed, as Nikhahitํ(U+0E4D) + Sara Aaา(U+0E32). - Zero-width characters (ZWSP U+200B, ZWJ U+200D, ...) are invisible, so a stray one is easy to miss.
- The JDK's Thai dictionary BreakIterator finds word boundaries; any of these slips can make it miss one and glue words together.
ThaiCharFilterrepairs the text first, character by character, so that it does not.
| input | output | expected |
|---|---|---|
| ท ่ ่ ี (tone twice and before the vowel) | ท่ี (tone still before the vowel) | ที่ |
| ท ่ ZWSP ี | ท่ี | ที่ |
| เ ZWJ เ ม ว | เเมว (double Sara E kept) | แมว |
| ท ํ ZWSP า | ทํา (decomposed Sara Am kept) | ทำ |
| each typo alone: ท่ี, ที่่, เเมว, ทํา, ส ZWSP ดี | ที่, ที่, แมว, ทำ, สดี | same |
Through new ThaiAnalyzer(): ฉันทำงานท่่ีบ้าน gives [ฉัน 0-3, ทำ 3-5, งาน 5-8, ที่บ้าน 8-16] instead of [ฉัน, ทำ, งาน, บ้าน]; ฉันรักเ+ZWJ+เมวมาก gives [ฉัน 0-3, รักแมวมาก 3-14] instead of [ฉัน, รัก, แมว]; ฉันทํ+ZWSP+างานที่บ้าน gives [ฉัน, ทำงานที่บ้าน] instead of [ฉัน, ทำ, งาน, บ้าน]. A TermQuery for บ้าน or แมว finds 0 documents instead of 1. A second pass of the char filter cleans every char-filter row.
ThaiCharFilter.read() (ThaiCharFilter.java:71-162) looks at the first character of a buffer of up to 4 characters (the current one and up to 3 ahead) and tries, in order: drop it if it is zero-width (:89-95); drop it if it is a diacritic equal to the last character emitted (:97-103); join a double Sara E (:105-113); recompose Sara Am (:115-137); swap a tone with the above/below vowel after it (:139-147); else emit it. The joining, recomposing and swapping rules read the raw next one or two characters. The cleaning rules only run when a character reaches the front, after the character before it has been decided and emitted, and nothing revisits a character already emitted.
Trace for ท ่ ่ ี: ท is emitted. The first ่ is at the front; the next character is the second ่, not a vowel, so no swap; ่ is emitted. The second ่ reaches the front, equals the last emitted character, and is dropped. ี is emitted after the first ่. Output ท ่ ี. For เ ZWJ เ, the join rule sees ZWJ next and emits เ; ZWJ is dropped; the second เ is emitted. For ํ ZWSP า, the Sara Am rule sees ZWSP and emits ํ.
Inside the merged token the spelling looks clean (ที่บ้าน) because ThaiNormalizationFilter runs after the tokenizer; the word boundary is already lost.
Exposure and likelihood329 words
- Who is exposed. Every Thai field that uses
new ThaiAnalyzer()(it wraps the reader inThaiCharFilterfor indexing and forAnalyzer.normalize()), and custom chains that put onethaichar filter (SPI name ofThaiCharFilterFactory) before a dictionary-based word tokenizer such as thethaitokenizer, as the factory's javadoc example does. No option is involved. - What it takes. Two of the documented typos in one character cluster: a tone mark typed twice and before its above/below vowel, or a zero-width character between two Sara E, between a tone and its vowel, or inside a decomposed Sara Am. Each typo alone is fixed. Likelihood: expected to be rare, because two typos must meet in one cluster (a judgement; no frequency was measured).
- What breaks. The affected word and a neighbour become one term, so queries for either word miss the document. Queries go through the same analyzer, so a query matches the merged term only if its text produces the same merge. No error and valid offsets;
IndexWriteraccepted all 30,000 random strings of a security probe (noCheckIndexwas run); deterministic at any index size. - How often in a bounded space. Over 824,691 inputs over 21 symbols (every string of up to 5 symbols that starts with ก, น, ฤ or เ, plus every string of up to 3 symbols), 3,633 inputs made of a clean word plus documented typos keep a pattern the filter's own rules rewrite (approximate: the reference uses a simplified Thai cluster grammar). Over all 813,615 strings of length 1-5 over 15 symbols, removing the zero-width characters changes today's output on 13,282, and typing one diacritic twice changes it on 4,813 of 85,236 checks.
- Not a regression. 10.5 had no char filter, and the raw JDK segmentation merges the lead sentence too. It is an incomplete new feature, found before its first release.
- JDK dependence. The word merge depends on the JDK's Thai dictionary
BreakIterator(all runs OpenJDK 25.0.3); the char-filter outputs do not.
The test shows that ThaiCharFilter, given a tone mark typed twice and before its above vowel (ท + Mai Ek + Mai Ek + Sara Ii), drops the duplicate but does not reorder the remaining tone mark, although its javadoc lists both rules.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.th;

import java.io.StringReader;
import java.io.StringWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestThaiCharFilterRepeatedToneBeforeVowel extends LuceneTestCase {

  public void testRepeatedToneBeforeVowel() throws Exception {
    StringWriter out = new StringWriter();
    new ThaiCharFilter(new StringReader("ท\u0E48\u0E48\u0E35")).transferTo(out);
    // tone mark typed twice and before its vowel: expected ท + SARA II + MAI EK, actual ท + MAI EK + SARA II
    assertEquals("ท\u0E35\u0E48", out.toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-876/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.th.TestThaiCharFilterRepeatedToneBeforeVowel
- Expected vs actual
- Expected
ท\u0E35\u0E48(ที่); actualท\u0E48\u0E35(JUnit:expected:<ท[ี่]> but was:<ท[่ี]>), with-eaand-da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<ท[ี่]> but was:<ท[่ี]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.th.TestThaiCharFilterRepeatedToneBeforeVowel.testRepeatedToneBeforeVowel(TestThaiCharFilterRepeatedToneBeforeVowel.java:29)- The javadoc says the filter exists because such typos make the BreakIterator merge adjacent words (
ThaiCharFilter.java:27-30); this is that merge. - Zero-width removal and deduplication come first in the javadoc and the code, so no documented rule order explains the output.
- A second pass of the filter gives the clean word, and so does
ThaiNormalizerfrom the same PR for ท่่ี.
The full argument309 words
- Purpose (
ThaiCharFilter.java:27-30): "Applying normalization before tokenization is critical for Thai, because typographic anomalies (such as two consecutive Sara E characters instead of Sara Ae, or zero-width characters) prevent the dictionary-based BreakIterator from locating word boundaries, causing multiple adjacent words to be mistakenly merged into one token." - Rules (
:32-43): removes zero-width characters, replaces double Sara E with Sara Ae, recomposes decomposed Sara Am, deduplicates consecutive repeated diacritics and tone marks, reorders a misplaced tone mark before an above/below vowel. Each lead output still holds a pattern that one of the multi-character rules (double Sara E, Sara Am, reordering) rewrites. - No documented order explains it. Zero-width removal is first in the javadoc and the code; deduplication is before the reordering in both. In ท่่ี the literal input already contains "tone + above vowel" (่ ี) and the output still does. What does explain it is the code's per-position priority: at each position the first matching rule wins and a rejected pair is not re-tested. That is how the code works; no javadoc, test or PR comment says a rule may be skipped because a character between its two halves is about to be deleted.
- MIGRATE.md (10.5 to 10.6) lists decomposed Sara Am, doubled Sara E, repeated or misordered tone marks and zero-width characters together as input 10.6 now analyzes differently.
- Tests. The upstream
TestThaiCharFilterchecks each typo alone, including ฉันรักเเมวมาก -> [ฉัน, รัก, แมว, มาก], the sentence whose ZWJ variant merges;testRandomchecks offsets, not normalization. No test asserts today's two-typo output; #16716 / #16717 never discuss rule order. - Concession. Two other sub-cases depend on order: Lakkhangyao after Nikhahit (ทํๅ) and a doubled tone inside a decomposed Sara Am (นํ้้า). Read as passes in the javadoc's list order they stay decomposed, and
ThaiNormalizeragrees. They are not the lead, and they overlap the sibling ThaiNormalizer bug (LFV-873).
The devil's-advocate check163 words
The strongest case for "works as designed" (the cross-model reviewer and the intended-behaviour checker): the class is a bounded, single-pass typo corrector; its javadoc lists separate repairs and promises neither idempotence nor repair of two typos in one cluster; the upstream tests check one typo at a time; the code's per-position first-match priority explains every output; and the raw JDK segmentation (the pre-10.6 path, no char filter) merges these inputs too.
Why it fails for the lead cases: no documented order explains the output, and the per-position priority is how the code works, not a documented limit; the filter itself deletes the zero-width character or the duplicate and then leaves a pattern its own rule rewrites; the result is the merge the class says it exists to prevent, on the upstream test sentence plus one invisible character; ThaiNormalizer from the same PR normalizes the same inputs (except the ZWJ one: it documents removing only ZWSP and ZWNJ); and nothing documents a single-typo limit.
Recommended Run the one-character rules in a first stage (recommended, validated)
Run zero-width removal, deduplication and the Lakkhangyao rule in a small first-stage char filter, so the multi-character rules see cleaned look-ahead (+61/-1). The new test, all 63 Thai tests and the analysis-common suite pass. In an exhaustive check of short strings, an added zero-width character or a repeated mark no longer changes the output (today: 13,282 and 4,813 cases).
public ThaiCharFilter(Reader in) {
  // the one-character rules run first, so read() matches its
  // multi-character patterns against cleaned look-ahead
  super(new SingleCharRules(in));
}

private static final class SingleCharRules extends BaseCharFilter {
  // read(): drop U+200B/U+200C/U+200D/U+FEFF and a diacritic equal to the
  // previous char (addOffCorrectMap), map U+0E45 to U+0E32 unless after
  // U+0E24/U+0E26; read(char[], int, int) loops over read()
}
All options and trade-offs4 options · 680 words
One fix (A) was built and validated through gradle and an exhaustive differential; B is untested, C is a workaround, D only documents the limit.
Wrap the input, in the constructor, in a private BaseCharFilter that removes zero-width characters, drops a diacritic that repeats the previous character and replaces Lakkhangyao with Sara Aa (unless after Ru or Lu). read() is unchanged: its join, recompose and reorder rules now see cleaned characters. Its own copies of the cleaning rules stay; deduplication still matters after a tone/vowel swap (ก่ั่ั). Each stage keeps its own offset map and CharFilter.correctOffset chains into the inner one (CharFilter.java:72-77). The idea is the finder's sketch, cleaned up.
public ThaiCharFilter(Reader in) {
  // the one-character rules run first, so read() matches its
  // multi-character patterns against cleaned look-ahead
  super(new SingleCharRules(in));
}

private static final class SingleCharRules extends BaseCharFilter {
  // read(): drop U+200B/U+200C/U+200D/U+FEFF and a diacritic equal to the
  // previous char (addOffCorrectMap), map U+0E45 to U+0E32 unless after
  // U+0E24/U+0E26; read(char[], int, int) loops over read()
}
Trade-offs
- Also recomposes the two order-dependent sub-cases (ทํๅ -> ทำ, นํ้้า -> น้ำ), where
ThaiNormalizerkeeps the decomposed form today (LFV-873); fixing that bug the same way keeps the two classes in agreement. - Residual: interleaved repeats (ก่ั่ั) and two different tone marks before one vowel still change on a second pass; no documented rule covers two different tone marks.
- Terms change only for inputs with such a typo pair; 10.6.0 (released 2026-10-29) has the class, so indexes built with it, with snapshots or with the RC hold the merged terms and need reindexing for those words after the fix (a MIGRATE note).
- One more
Readerlayer with a per-characterread(); no benchmark was run.
What the checks validated
- Gradle, scratch worktree of
a9779ef3c193, seed 876C0A10: all 10 Thai test classes (63 tests): stock 6 failures (the new test), fix A 0 with assertions on and off; the whole:lucene:analysis:common:testtask with fix A: 340 classes, 1,916 tests, 18 skipped, 0 failures;check -x testaftertidy: pass (google-java-format, ecjLint, forbiddenApis, license checks). - Repro harness on main, fix A shadowed: the new test 7/7 (
-ea,-da), the finder's 10/10 (-ea), the independent reproducer's 9/9 (-da). - Exhaustive differential, stock vs fix A, all 813,615 strings of length 1-5 over 15 symbols: outputs differ on 36,718; on 36,654 of them a second stock pass still changes the stock output, and the other 64 (three or more Sara E around a zero-width character) get what stock gives without the zero-width character. Removing zero-width characters changes the output on 13,282 inputs with stock, 0 with fix A; typing one diacritic twice changes it on 4,813 of 85,236 checks with stock, 0 with fix A. In this space fix A is never less stable than stock (a second pass changes 6,888 fix outputs, all also unstable with stock; stock has 42,588). Offsets valid for every input, both versions.
- The hunt's bounded check with the finder's sketch (same rules): typo-input mismatches 3,633 -> 51.
Apply the three one-character rules in fillBuffer(), in the same class. Not run.
Trade-offs
Offset corrections are keyed by output offset, which is not known when a character is buffered (a later contraction can shift it), so the deletions must be recorded later; more intricate than a second stage.
new ThaiCharFilter(new ThaiCharFilter(reader)), or two thai char filters in a custom chain. Two chained filters give the clean output for all five char-filter inputs of the independent reproducer.
Trade-offs
Twice the work; not complete (732 inputs of the bounded check need 3 changing passes); ThaiAnalyzer is final, so users either rebuild its chain or wrap it in an AnalyzerWrapper whose wrapReader and wrapReaderForNormalization add a second ThaiCharFilter (not run).
Say in the javadoc that only one typo per character cluster is repaired.
Trade-offs
Keeps the word merges the class exists to prevent.
Elasticsearch exposes the class as its thai char filter (elastic/elasticsearch#160853), so products that ship Lucene 10.6 with it inherit the word merges.
A bounded-exhaustive check compared the real filter with a reading of its javadoc rules on 824,691 short strings over 21 symbols: 3,633 typo inputs kept a pattern the filter's own rules rewrite, and iterating the filter removed all of them. A sentence-level check then showed the word merge.
The method in full221 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier), a hunt unit on Thai normalizers, planned from two probes (an idempotence check of ThaiNormalizer and a char-filter versus normalizer differential).
- The documented rules were encoded as a string-rewriting system; the reference computes every normal form of each input by exhaustive rewriting. The stock filter was compared with it on 824,691 inputs over 21 symbols (including a surrogate pair): every string of up to 5 symbols that starts with ก, น, ฤ or เ, plus every string of up to 3 symbols; with identical counts with assertions on and off.
- 3,633 inputs made of a clean word plus documented typos, whose documented result is unique, got an output that one of the filter's own rules still rewrites. Iterating the filter to a fixed point brought these 3,633 to 0, which pointed at the single-pass look-ahead.
- A second leg applied every single and paired typo to 16 real sentences and ran them through the stock
ThaiAnalyzer: every leftover of the char filter's own rules (104 variants) came from a pair of typos; no single typo the char filter documents left one. (Single typos of rules that onlyThaiNormalizerdocuments can merge words too; out of scope here.) - The finder then wrote a public-API JUnit on the stock main jar (10 of 10 fail).
No prior report found in GitHub issues, PRs and commits, all 410 open PRs, the dev@, java-user@ and issues@ lists, the JIRA archive or downstream trackers (searched 2026-10-28).
Searches4 searches
Nobody has reported or fixed this upstream. The closest items introduce, document, adopt or discuss adopting the class.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-28 | five runs of a scripted prior-report search (about 50 queries) plus manual searches on each Thai class name and on Sara Am, Sara E, Nikhahit, Lakkhangyao, zero width and tone mark; every item of the last 48 hours (#16907-#16928); the changed-file lists of all 410 open PRs; the commit history of ThaiCharFilter.java on main, branch_10_6 and branch_10x | no report; no open PR touches the Thai package |
| Related items (read) | 2026-10-28 | the full threads | #16716 / #16717 (origin; no discussion of rule order or combined typos), #16770 (MIGRATE.md, single-typo examples), #16722 (backport, reindexing), #16736 (other Thai class), #16911 (open, deletes branch_10x) |
| Downstream | 2026-10-28 | Elasticsearch, OpenSearch and Solr repositories | elastic/elasticsearch#160853 (merged) exposes the class; elastic/elasticsearch#160854 / #163675 and opensearch-project/OpenSearch#23151 are open and are about adopting it or keeping the pre-10.6 defaults; none reports a defect |
| Mailing lists and JIRA | 2026-10-28 | about 56 queries over dev@, java-user@, issues@ and commits@; 11 JIRA-archive queries; 9 web queries (one in Thai script) | nothing; the class postdates the JIRA migration |
Born with the class in #16717 (e64ae25dcd8, 2026-09-27) and its backport to branch_10_6 and branch_10x; in 10.6.0 (released 2026-10-29 from the RC1 revision). Not a regression: 10.5 had no char filter, and the raw JDK segmentation merges the lead sentence too.
Versions tested5 rows
Introduced by apache/lucene#16717, "Add ThaiCharFilter, ThaiNormalizationFilter, and ThaiNormalizer (#16716)" (closes #16716; author Kamthorn Krairaksa), main commit e64ae25dcd8, 2026-09-27 21:09 UTC; backport 405116dd0e1 on branch_10_6 and branch_10x (2026-09-28). git blame gives all of read() to it; the only later change edits the @since tag (c73e2e4aad13 / 82287bdc7e9).
Released: branch_10_6 4ae946e5a9b, the 10.6.0 RC1 revision, was released as 10.6.0 on 2026-10-29. The bug shipped in 10.6.0 and can be fixed in a later 10.6.x or 10.7.0.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | finder's test 10/10 fail (-ea, -da); independent reproducer's 8/9 (control passes); new test 6/7 |
branch_10_6 4ae946e5a9b (10.6.0 RC1 revision) | affected | finder's test 10/10 fail (-ea, -da), snapshot jars built at that revision |
e64ae25dcd8 (#16717) sources over the main jars | introducing commit | 10/10 fail (-ea, -da); the fix-sketch shadow passes, so the shadow replaced the class |
| branch_10x | by history | same backport, no later change (not executed) |
| 10.5.2, 9.12.3 and older | not affected | the class does not exist (compile error) |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication confirmed it on main with assertions on and off; a cross-model reviewer (OpenAI GPT-5.6) rated it real in a reading-only review.
Checks and verdicts297 words
The independent reproduction and the intended-behaviour check each wrote their own test; the adjudication re-ran the independent reproduction's and the finder's. The cross-model reviewer could not run code, so both of its reviews are reading-only.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6): no command ran and it ran no Java, so it could not vote real. A separate run re-ran the repro: fails 10 of 10. |
| Independent reproducer | real | Own metamorphic JUnit (adding a zero-width character or a second tone mark must not change the output; single-typo control): 8 of 9 fail on main with assertions on and off. Two chained filters give the clean output. Added the tone + ZWSP + vowel case. |
| Cross-model works-as-designed review | real (medium), reading only | A reviewer from the same model family (OpenAI GPT-5.6), with an intended-behaviour lens, in a separate reading-only session that also saw the independent reproduction's and the intended-behaviour check's results: rated the single-pass-corrector case moderate and rejected it for the zero-width and repeated-tone cases. |
| Intended-behaviour devil's advocate | real (medium-high) | Own JUnit fails 4 of 6; its controls for the two order-dependent sub-cases pass. Showed that ThaiNormalizer normalizes the lead inputs and that the raw JDK segmentation (a pure-JDK BreakIterator run, the pre-10.6 path) merges too. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's suite (-ea, -da) and the finder's; limited the claim to the zero-width and repeated-tone-before-vowel cases. |
| Credibility audit | keep | Own main() repro on main matches; prior art refreshed; score and security confirmed. |
| Bug-doc fix validation | fix A validated | Gradle in a scratch worktree (Thai suites, the module, check -x test) and the exhaustive stock-versus-fix differential. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 474 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,477 words
- Registry title
- ThaiCharFilter tests its multi-character rules (double Sara E, decomposed Sara Am, tone mark before an above/below vowel) on the raw look-ahead characters, before its own zero-width removal and deduplication have run on them, so a zero-width character or a repeated tone mark inside such a pattern leaves the anomaly in the output and the default ThaiAnalyzer merges the word with its neighbours
- Area
- analysis-common / Thai (ThaiCharFilter.read single-pass look-ahead; the 'thai' char filter factory and the default ThaiAnalyzer as consumers; new in 10.6.0)
- Priority
- Low, rank 481: In the 10.6.0 ThaiCharFilter used by the default ThaiAnalyzer, words silently merge with their neighbours only when two documented typos fall in one character cluster.
- Impact class
- silent wrong results
- Impact note
- Thai-language indexes on 10.6.0 (released 2026-10-29; branch_10_6 at the RC1 revision 4ae946e5a9b), main and branch_10x that use the default ThaiAnalyzer or the 'thai' char filter are hit when one character cluster carries two of the typos the filter documents fixing, for example a tone mark typed twice and before its vowel (ท่่ี for ที่) or a zero-width character between the two Sara E of แ or inside a decomposed Sara Am: the char filter output keeps the anomaly, the JDK dictionary BreakIterator then merges the word with its neighbours, and a query for a merged word (บ้าน, แมว) misses the document, deterministically at any index size, with no error and a well-formed index; each typo on its own is handled.
- Summary
- You index Thai text with the default ThaiAnalyzer, which runs ThaiCharFilter before the tokenizer, and expect a word typed with two of the typos the filter documents fixing (ที่ with its tone mark typed twice and before the vowel, ท่่ี, or แมว written as two Sara E with an invisible zero-width joiner between them) to be indexed like the clean word, because the filter's javadoc says it removes zero-width characters, deduplicates repeated tone marks, reorders a tone mark typed before an above/below vowel, joins double Sara E and recomposes decomposed Sara Am precisely so that the BreakIterator does not merge adjacent words. ThaiCharFilter makes one pass and tests its multi-character patterns against the raw next characters, while zero-width removal and deduplication act only on the character at the front of its buffer, after the earlier character has already been emitted, so the output still holds the tone-before-vowel, double Sara E or decomposed Sara Am sequence (ท่ี, เเมว, ทํา), which a second pass of the same filter would clean. The BreakIterator then merges words: ฉันทำงานท่่ีบ้าน is indexed as [ฉัน, ทำ, งาน, ที่บ้าน] instead of [ฉัน, ทำ, งาน, บ้าน], ฉันรักเ + ZWJ + เมวมาก as [ฉัน, รักแมวมาก], and a TermQuery for บ้าน or แมว finds 0 documents.
- Introduced
- e64ae25dcd894019125d0a0bd723133b633b009e on main (apache/lucene#16717 'Add ThaiCharFilter, ThaiNormalizationFilter, and ThaiNormalizer (#16716)', closes feature issue #16716, author kamthorn; one comment, no review comments) and its backport 405116dd0e1 (branch_10_6 and branch_10x, committed 2026-09-28T15:36:16Z, same author date). Born with the class, not a regression [read: git blame of ThaiCharFilter.read() (lines 87-160) and of ThaiAnalyzer.initReader / initReaderForNormalization (lines 119-127) gives only e64ae25dcd8; the only later change to ThaiCharFilter.java, c73e2e4aad13 on main / 82287bdc7e9 on 10.x, edits the @since tag; the parent e357029271b3 has no ThaiCharFilter; exec: the e64ae25dcd8 ThaiCharFilter.java and ThaiAnalyzer.java compiled over the main a9779ef3c193 jars fail 10 of 10 with -ea and -da, while a control with the fix-sketch ThaiCharFilter shadowed over the same jars passes 10 of 10, which shows that the shadow replaces the jar class] (2026-09-27 (author date 2026-09-28T04:09:27+07:00 = 2026-09-27T21:09:27Z; merged to main at the same time); backport 405116dd0e1 committed 2026-09-28)
- First affected version
- 10.6.0 (released 2026-10-29) is the first release. The 10.6.0 RC1 (rev 4ae946e5a9b, released as 10.6.0 on 2026-10-29) contains it: the finder JUnit fails 10 of 10 with -ea and -da on 10.6.0-SNAPSHOT jars built at that revision [exec; the RC artifacts themselves were not run]. 10.5.2, 9.12.3 and every earlier release lack the class [exec: compile error, ThaiCharFilter not found]
- Affected versions
- main / 11.0.0-SNAPSHOT since e64ae25dcd8 [exec: a9779ef3c193 -ea and -da fail 10 of 10 for the finder JUnit, 8 of 9 for the independent reproduction's (control passes), 4 of 6 for the intended-behaviour check's (controls pass), and in the adjudication's re-runs; re-runs 2026-10-28: -ea 10 of 10, -da 10 of 10, the independent reproduction's -da 8 of 9; read: upstream main has no commit on ThaiCharFilter.java after the @since edit (GitHub commits API, 2026-10-28)]; branch_10_6 since 405116dd0e1 [exec at head 4ae946e5a9b, the 10.6.0 RC1 revision: 10 of 10 with -ea and -da]; branch_10x [read: same backport and @since commit, no later change; read at 657014b3c57, its last code revision; the branch was retired on 2026-10-29 by #16911 (48cf3f515d6) and now holds only a README]; the introducing commit e64ae25dcd8 [exec as a source shadow over the main jars: 10 of 10, -ea and -da]. In no release before 10.6.0: 10.5.2, 9.12.3 and older lack the class [exec: compile error]. All runs on Linux aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only; refreshed at the registration check 2026-10-28): five scripted prior-report searches (the finder's GitHub/commit/downstream/mailing-list/JIRA run and web leg, two follow-up runs of 51 queries each and a web ingest including a Thai-script query), manual GitHub searches for ThaiCharFilter, ThaiNormalizer, ThaiNormalizationFilter, zero width, Sara Am, Sara E, tone mark and Thai normalization, all 22 apache/lucene items created in the last 48 h (#16907-#16928), the changed-file lists of all 410 open apache/lucene PRs, the commits API for ThaiCharFilter.java on main, branch_10_6 and branch_10x, the contributor's fork, lists.apache.org dev@, java-user@ and issues@, the JIRA archive (the class postdates the JIRA migration), and the full threads of #16716, #16717, #16722, #16736, #16770, elastic/elasticsearch#160853, #160854 and #163675 and opensearch-project/OpenSearch#23151. Related, not this bug: #16716 / #16717 (introducing issue and PR; nobody discusses rule order or combined anomalies), #16770 (MIGRATE.md Thai section, single-anomaly examples), #16722 (backport and reindex discussion), #16736 (ThaiTokenizer user dictionary, other class), #16911 (merged 2026-10-29, emptied branch_10x), OpenSearch#23151 and elasticsearch#160853 / #160854 / #163675 (downstream adoption and backward-compatibility threads, no defect report). Refresh: GitHub search 'repo:apache/lucene Thai updated:>=2026-10-26' returns 0 items, 'ThaiCharFilter' only #16716 / #16717, no open PR created since 2026-10-26 (#16907-#16926) is about Thai, and the newest commit on ThaiCharFilter.java on main and branch_10_6 is still the @since edit. Gaps: GitHub search tokenizes Thai script poorly; web search covers only indexed pages.
- Lucene commit tested
- main
a9779ef3c193through gradle in a scratch worktree (removed afterwards): a new 7-test class with all 10 Thai test classes (stock: 6 of 63 fail; fix A: 0, assertions on and off), fix A with the whole:lucene:analysis:common:testtask (340 classes, 1,916 tests, 18 skipped, 0 failures) andcheck -x test(pass (google-java-format, ecjLint, forbiddenApis, license checks)); through the repro harness on main, stock: the new test, the finder's and the independent reproduction's JUnit (-ea,-da); with fix A: the new test (-ea,-da), the finder's (-ea) and the independent reproduction's (-da); an exhaustive stock-versus-fix differential over 813,615 short strings; the finder's test onbranch_10_64ae946e5a9b(the 10.6.0 RC1 revision) and on the introducing commit's sources; 10.5.2 and 9.12.3 lack the class. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:23-48 (class javadoc; :27-30 purpose, :32-43 rule list), :89-95 (zero-width removal on inputBuffer[0] only), :97-103 (deduplication on inputBuffer[0] only), :105-113 (double Sara E tests the raw inputBuffer[1]), :115-137 (Sara Am recomposition tests the raw inputBuffer[1..2]), :139-147 (tone/vowel swap tests the raw inputBuffer[1]), :149-154 (Lakkhangyao on c0 only)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-107 (createComponents), :119-127 (initReader and initReaderForNormalization wrap the input in ThaiCharFilter); lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilterFactory.java:34-40 (SPI name 'thai', @since 10.6.0)lucene/MIGRATE.md 10.5-to-10.6 Thai section (decomposed Sara Am, doubled Sara E, repeated or misordered tone marks and zero-width characters analyzed differently; single-anomaly examples)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:27-43 (javadoc), :71-162 (read), :89-154 (the six rules), :181-190 (fillBuffer) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:100-109 (createComponents: ThaiNormalizationFilter after the tokenizer), :119-128 (initReader, initReaderForNormalization)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:119-128; lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilterFactory.java:23-40 @ a9779ef3c193
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:27-43 @ a9779ef3c193lucene/MIGRATE.md:766-770 (Thai section)lucene/analysis/common/src/test/org/apache/lucene/analysis/th/TestThaiCharFilter.java:32-87 (one typo per test), :93-108 (ฉันรักเเมวมาก), :116-132 (testRandom)
- Suggested fix
lucene/core/src/java/org/apache/lucene/analysis/CharFilter.java:72-77 (correctOffset chaining)lucene/core/src/java/org/apache/lucene/analysis/AnalyzerWrapper.java:102-114, :140-147 (wrapReader / wrapReaderForNormalization run before the wrapped analyzer's initReader)
- TestThaiCharFilterRepeatedToneBeforeVowel.java (JUnit test):
repro/LFV-876/src/org/apache/lucene/analysis/th/TestThaiCharFilterRepeatedToneBeforeVowel.java(31 lines)
assets/LFV-876/bug.png(474 KB)