HTMLStripCharFilter removes tags and keeps the text between them. A < that is never closed by > is not a tag, so it is kept when the text goes on: a < b c stays a < b c. Only when the text ends right after the name is the pending <name thrown away.
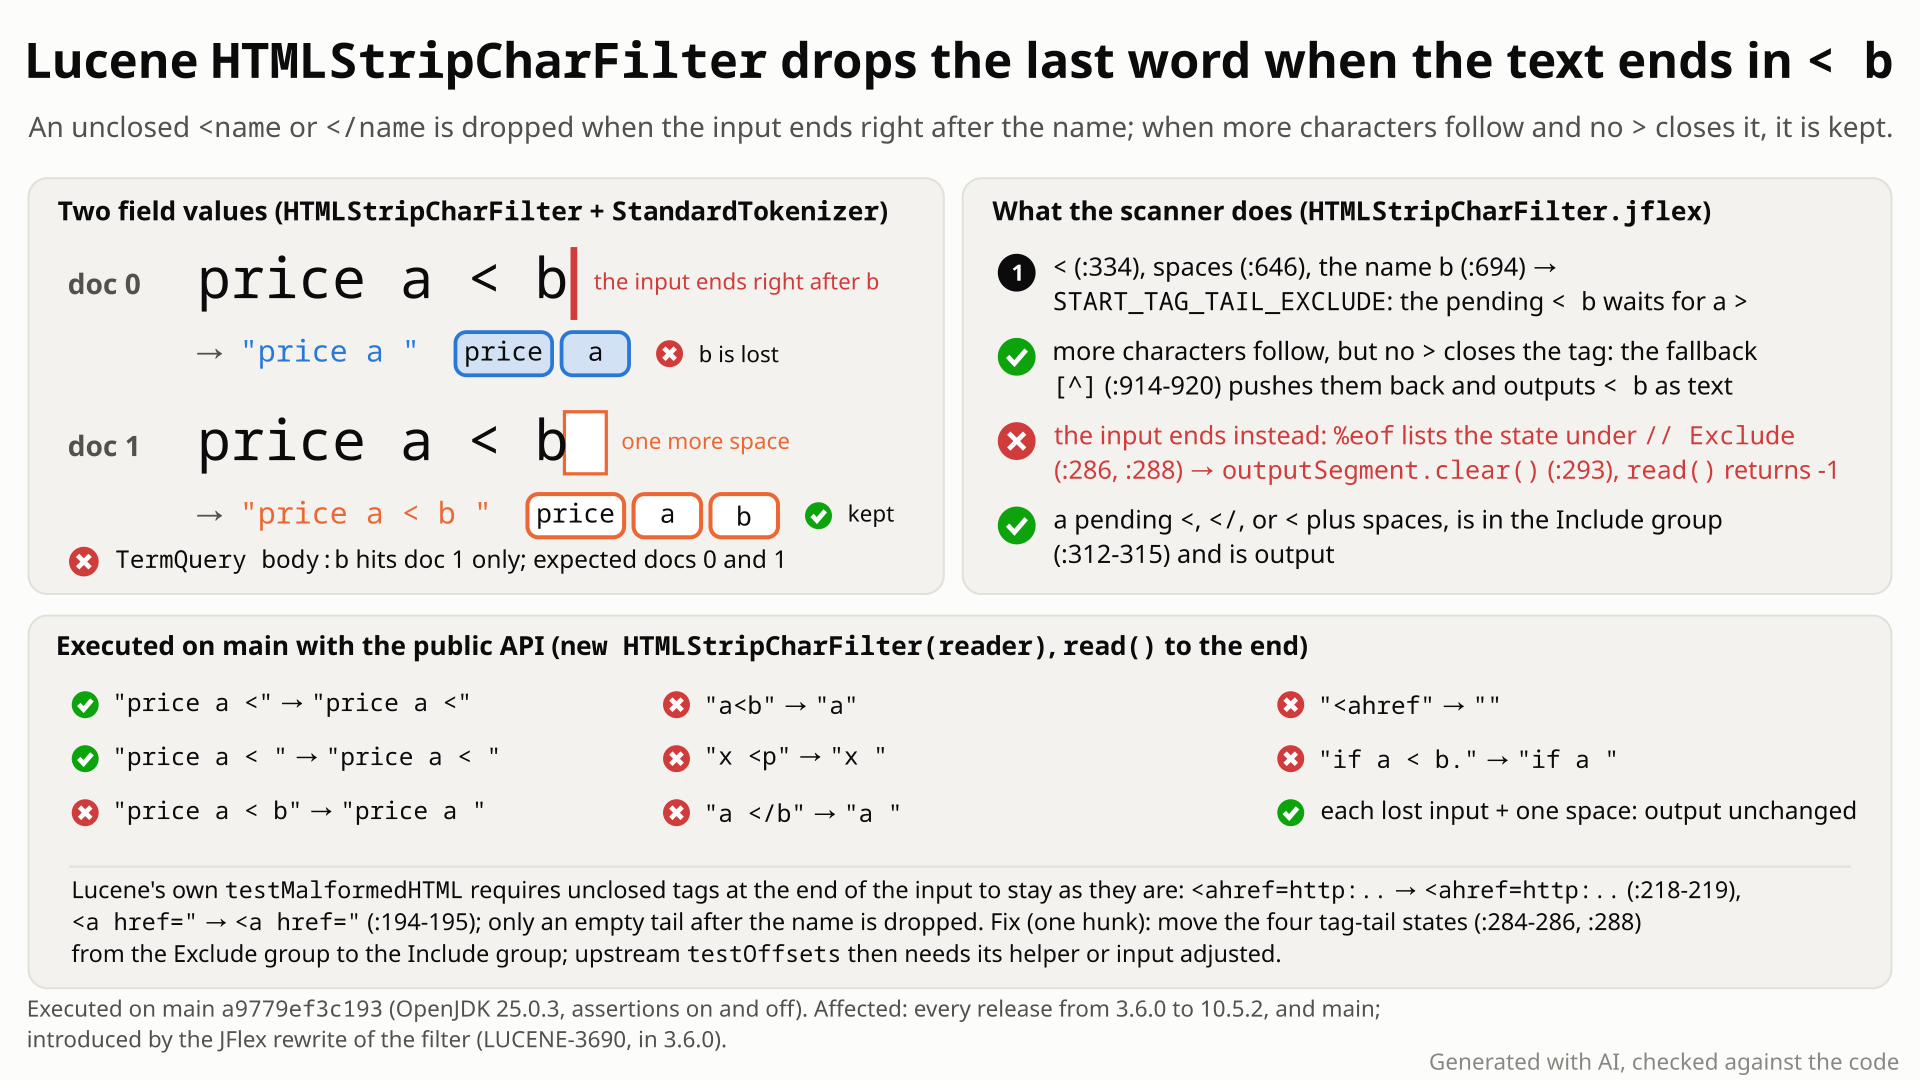
price a < b through HTMLStripCharFilter: what one more space changes, what happens when the text ends right after b, and other endings next to Lucene's own tests. Select the still to open it at full size. Generated with AI, checked against the code.- Index the text
price a < b(a plain comparison, no HTML) throughHTMLStripCharFilterandStandardTokenizer. - You expect the tokens
[price, a, b]. That is whatprice a < b(one trailing space) gives, andprice a < b cgives[price, a, b, c]: an unclosed<with no>is kept as text. - You get
[price, a]: the filter returnsprice a. ATermQueryforbfinds 1 of the 2 documents, with no error. - Why: when the text ends, the scanner is still inside the unfinished tag
< b, and its end-of-input switch throws that pending text away. If the text goes on after the name and no>closes the tag, a fallback rule outputs it unchanged. - Other endings lose text the same way:
a<bgivesa,x <pgivesx,a </bgivesa,for i<ngivesfor i,if a < b.givesif a.
Anyone who strips HTML with HTMLStripCharFilter, directly, through the htmlStrip factory or a search server's char filter built on it, at default settings and any index size. It hits values or queries that end in < [space] name or </ name, such as a < b or for i<n: the last word silently goes missing from the index.
Mechanism, terms and numbers719 words
HTMLStripCharFilter outputs an unclosed tag-like construct as text: a < b c strips to a < b c, and Lucene's own testMalformedHTML requires <ahref=http:.. and <a href=" at the end of the input to come out unchanged. But when the input ends right after the tag name, with no character after it, the scanner's end-of-input switch drops the pending <name: a < b strips to a , price a < b is analyzed as [price, a] and a TermQuery for b misses the document, while price a < b (one trailing space) gives [price, a, b]. It has been this way since the JFlex rewrite in 3.6.0 (2012); the filter it replaced kept the text. No exception and no offset error was seen; what is lost is the pending <name at the end of a value or query, usually one word. A one-hunk grammar change fixes it; one upstream test input needs a one-character change.
- Pending segment: when the scanner sees
<, it keeps the characters it reads in a buffer until it knows whether they form a tag. A closed tag is removed (or replaced by a newline for block elements); anything else is given back as text. - Tag-tail state: the scanner state after
<(optionally whitespace or/) and a tag name, waiting for attributes and the closing>. The grammar has six, three after<and three after</(HTMLStripCharFilter.jflex:48-49); four of them matter here:START_TAG_TAIL_EXCLUDE(inline elements such asa,b),START_TAG_TAIL_SUBSTITUTE(any other name, such asp) and the matchingEND_TAG_TAIL_EXCLUDEandEND_TAG_TAIL_SUBSTITUTEafter</. The other two,START_TAG_TAIL_INCLUDEandEND_TAG_TAIL_INCLUDE, are for names listed inescapedTags. - Name:
[:_\p{ID_Start}] [-.:_\p{ID_Continue}]*(HTMLStripCharFilter.jflex:69), sob.andi-nare one name each, and a digit cannot start one (a < 5is never a tag).
<starts the pending segment (HTMLStripCharFilter.jflex:334-339); whitespace or/may follow (:645-649); a name moves to a tag-tail state (:693-712for start tags,:591-609for end tags).- In a tag-tail state the only rule is the tail that ends in
>(:714-745,:611-641). If more input follows but no>completes the tag, the shared fallback rule (:914-922) pushes the character back and outputs the pending<nameunchanged. - If the input ends while the scanner is still in a tag-tail state, JFlex runs the
%eofblock (:275-323). It lists the four tag-tail states in its "Exclude" group (:284-288), which clears the pending segment. The generated scanner has the same switch inzzDoEOF()(HTMLStripCharFilter.java:6133-6185). Nameis matched greedily, so a following name character (the.ofb.) only makes the name longer. Any other character either completes the tag with a tail ending in>(stripped) or, with no>, triggers the fallback of step 2. So the scanner is still in a tag-tail state at end of input only when the input ends right after the (longest) name: the Exclude grouping changes the output in exactly that case.- The states one step earlier (
<,</,<) and the escaped-tag tails are in the "Include" group (:306-318), which outputs the pending segment. Soa <anda <are kept,a < bis not, anda < bis.
| input | output | the same input + one space |
|---|---|---|
a < b | a | a < b |
a<b | a | a<b |
x <p | x | x <p |
a </b | a | a </b |
<ahref | (empty) | <ahref |
for i<n | for i | for i<n |
if a < b. | if a | if a < b. |
a<script | a | a<script |
Kept at end of input: a <, a < , a </, a < 5, a < b c, <ahref=http:.., <a href=", and a name listed in escapedTags (one of the two *_INCLUDE states).
A state-table model parsed from the grammar (22 states) finds exactly 5 states whose end-of-input action differs from what they do when more input follows: these 4, and the character-reference tail, whose end-of-input leniency is commented ("At end of file, allow char refs without semicolons", :298) and tested.
Exposure and likelihood316 words
- Who is exposed. Applications that strip HTML with
HTMLStripCharFilter: directly, through thehtmlStripSPI factory (for example in aCustomAnalyzer), or through a search server's char filter built on it (Solr'ssolr.HTMLStripCharFilterFactory; other servers call theirshtml_strip; not run on a downstream product). No Lucene analyzer adds it by default, so it is opt-in, but it is stock and needs no non-default setting. - What happens. The last word of the value is not indexed, so a term query for it misses the document. No error, and no offset error was seen (the final offset was right in every case of the hunt's bounded sweeps).
- What it takes. A field value or query string that ends exactly in
<[whitespace] name or</name with no>: plain-text comparisons (a < b,for i<n,if x<y), or text cut off inside a tag (...<b, where losing the fragment does little harm). By reading (not run), each value of a multi-valued field has its own end, and a query string is hit the same way when it goes through the full analysis chain. Deterministic; index size does not matter, and no non-default setting is needed (a name listed inescapedTagsis kept). - How much is lost. The pending
<nameat the very end: one JFlexName, usually one word. A name may contain-,.,:,_and digits, so a tokenizer can split it:price a < foo-bargives[price, a], whileprice a < foo-bargives[price, a, foo, bar]. - Versions. Reproduced on 21 releases and snapshots from 3.6.0 to 10.5.2 plus main, and on a
branch_10_6build at4ae946e5a9b(10.6.0); the end-of-input grouping is unchanged in the history between them. - How likely. Rare: such endings are a small share of real fields, and no report of it was found.
HTMLStripCharFilter drops an unclosed < name when the input ends right after the name, but outputs it as text when any character follows.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.charfilter;

import java.io.Reader;
import java.io.StringReader;
import java.io.StringWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHTMLStripUnclosedTagAtEnd extends LuceneTestCase {

  public void testUnclosedTagAtEndOfInputIsKept() throws Exception {
    StringWriter out = new StringWriter();
    try (Reader r = new HTMLStripCharFilter(new StringReader("a < b"))) {
      r.transferTo(out);
    }
    // expected the unclosed "< b" output as text (as for "a < b " or "a < b c"), actual "a "
    assertEquals("a < b", out.toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-878/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.charfilter.TestHTMLStripUnclosedTagAtEnd
- Expected vs actual
- Expected:
a < b->a < b(asa < b->a < b); actual:a(expected:<a [< b]> but was:<a []>), with-eaand-da.
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<a [< b]> but was:<a []>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.charfilter.TestHTMLStripUnclosedTagAtEnd.testUnclosedTagAtEndOfInputIsKept(TestHTMLStripUnclosedTagAtEnd.java:32)- Lucene's
testMalformedHTMLkeeps unclosed tags with attributes at the end of the input (<ahref=http:..stays), yet<ahrefis dropped. - One space after the name keeps the text, as does a pending
<or<at the end. - The Solr Reference Guide documents the filter for non-HTML input (
if a<b then print a;); its predecessor kept these inputs.
The full argument313 words
- Lucene's tests keep unclosed tags with an attribute part at end of input.
testMalformedHTMLmaps<a href="to<a href="(TestHTMLStripCharFilter.java:194-195) and<ahref=http:..to<ahref=http:..(:218-219): unclosed start tags that run to the end of the input, kept. No test covers a bare<nameat the end; it is inconsistent with these recovery cases.testCDATAlabels its unclosed<!cases "unclosed angle bang - all input is output" (:502,:508; added by SOLR-5983 in 2014, which fixed another end-of-input bug in the same switch). - The scanner keeps it in the neighbouring cases. Mid-text the fallback rule outputs the unclosed tag (
HTMLStripCharFilter.jflex:914-922); at end of input the Include group outputs a pending<,</or<(:306-318). Whether the name is dropped depends only on whether the input ends right after it, which is hard to defend for plain text (a committer may still see dropping a truncated<divas useful). - Documented for non-HTML input (in the Solr Reference Guide, not in Lucene's javadoc). The Solr Reference Guide's
HTMLStripCharFilterFactorysection: "TIP: The input need not be an HTML document. The filter removes only constructs that look like HTML. If the input doesn't include anything that looks like HTML, the filter won't remove any input." Its example table mapsif a<b then print a;to itself; cut afterb, the filter returnsif a(if x<ygivesif x). The same page documents the one intended end-of-input special case, the optional;of a final entity reference; nothing similar exists for tags. - History. The Solr 3.5.0 filter that the 2012 rewrite (LUCENE-3690) replaced keeps all these inputs. The LUCENE-3690 thread (41 comments on JIRA; 40 in the GitHub mirror) never discusses tags at end of input.
- No javadoc contract either way. The class only "attempts to strip out HTML constructs".
The devil's-advocate check253 words
The intended-behaviour checker built the strongest case for "intended": (a) the %eof block lists every state by hand, and the Exclude/Include split for tag tails reads like "a tag in progress at end of input is markup: strip it unless escaped"; (b) for < directly followed by a letter, browsers agree: the HTML tokenizer's eof-in-tag rule turns a<b into a, and for HTML cut off mid-tag (<p>Hello</p><div) dropping the fragment avoids a junk token; (c) Lucene treats < X > as a tag by design (x < X > gives x \n; LUCENE-5943, Not A Problem), so "< b is not a tag in HTML" is not Lucene's model; (d) upstream testOffsets passes only because the trailing < X is dropped.
Why it fails: the drop depends only on whether the input ends right after the (longest) name, while Lucene's tests keep the tag when an attribute part follows (<ahref=http:.., <a href="). Browsers also drop <b c and <a href=" at end of input, which Lucene and its tests keep, so browser parity is not the filter's model. LUCENE-5943 is about closed tags. And testOffsets depends on the drop only through its helper, which pairs the n-th output X with the n-th input X: its input predates the rewrite (the old filter output it unchanged), and it passes today only because both the X inside < X > and the trailing < X are removed. Argue from Lucene's own consistency, not from browsers.
Recommended A. Treat the four tag-tail states like their neighbours at end of input
Move the four tag-tail states from the end-of-input "Exclude" group to the "Include" group (one hunk in the grammar), regenerate the scanner, and rename the tag in testOffsets' third input from < X > to < Y >. Validated: the new tests pass, all of :lucene:analysis:common:test passes (1,915 tests, 0 failures) and check -x test passes.
All options and trade-offs3 options · 936 words
Option A was applied in a scratch worktree of main a9779ef3c193, the scanner was regenerated with the build's own regenerateHTMLStripCharFilter task, and the tests were run with assertions on and off. Options B and C are alternatives a committer may raise; neither was run.
A. Treat the four tag-tail states like their neighbours at end of input (validated by the checks) (recommended)
In the %eof switch of HTMLStripCharFilter.jflex, remove START_TAG_TAIL_EXCLUDE, START_TAG_TAIL_SUBSTITUTE, END_TAG_TAIL_EXCLUDE and END_TAG_TAIL_SUBSTITUTE from the Exclude group and add them to the Include group, then regenerate the scanner (./gradlew :lucene:analysis:common:regenerateHTMLStripCharFilter, which also updates the generated-source checksums).
In TestHTMLStripCharFilter#testOffsets, change the third input from X < &zz >X &# < X > < &l > &g < X to X < &zz >X &# < Y > < &l > &g < X. Its helper finds the n-th X of the input by indexOf and compares it with the corrected offset of the n-th X in the output; the input has four X's (offsets 0, 9, 16, 32). Today the X at 16 (inside the tag < X >) and the trailing X at 32 are both removed, so only 0 and 9 are checked. With the fix, the trailing X is output at its correct offset 32, and the helper pairs it with the stripped X at 16: expected:<16> but was:<32>. With < Y > the helper checks 0, 9 and 32.
--- a/lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex
+++ b/lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex
@@ -281,11 +281,7 @@
     case STYLE_COMMENT:
     case SINGLE_QUOTED_STRING:
     case DOUBLE_QUOTED_STRING:
-    case END_TAG_TAIL_EXCLUDE:
-    case END_TAG_TAIL_SUBSTITUTE:
-    case START_TAG_TAIL_EXCLUDE:
-    case SERVER_SIDE_INCLUDE:
-    case START_TAG_TAIL_SUBSTITUTE: { // Exclude
+    case SERVER_SIDE_INCLUDE: { // Exclude
       // add (length of input that won't be output) [ - (substitution length) = 0 ]
       cumulativeDiff += (int) (yychar - inputStart);
       // position the correction at (already output length) [ + (substitution length) = 0 ]
@@ -309,6 +305,12 @@
     case NUMERIC_CHARACTER:
     case END_TAG_TAIL_INCLUDE:
     case START_TAG_TAIL_INCLUDE:
+    // An unclosed tag at end of input is output as text, as it is when the input goes on
+    // after the tag name without a closing >
+    case END_TAG_TAIL_EXCLUDE:
+    case END_TAG_TAIL_SUBSTITUTE:
+    case START_TAG_TAIL_EXCLUDE:
+    case START_TAG_TAIL_SUBSTITUTE:
     case LEFT_ANGLE_BRACKET:
     case LEFT_ANGLE_BRACKET_SLASH:
     case LEFT_ANGLE_BRACKET_SPACE: {        // Include
--- a/lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java
+++ b/lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java
@@ -356,7 +356,9 @@
     doTestOffsets("X & X ( X < > X");

     // test backtracking
-    doTestOffsets("X < &zz >X &# < X > < &l > &g < X");
+    // the X inside "< Y >" would be stripped, and doTestOffsets pairs the n-th output X with the
+    // n-th input X
+    doTestOffsets("X < &zz >X &# < Y > < &l > &g < X");
   }

   static void assertLegalOffsets(String in) throws Exception {
Trade-offs
- Output changes only for values that end right after a tag name. HTML cut off inside a tag (
...<div) now keeps<divas text, as...<div clalready does today. - Offsets: the Include branch adds no correction, because all pending input is output; in the hunt's bounded sweep with the fix the final offset was correct in every case, and only the documented character-reference tail still differs from mid-text (that sweep ran the finder's hand-patched scanner, whose grammar change is the same as fix A's except for its comments).
- A test-side alternative (not run): keep the
testOffsetsinput and make the helper check that each outputXmaps to anXof the input at a strictly increasing offset. That changes the helper for all three inputs.
What the checks validated
- The 3 new tests and the standalone JUnit pass; the
charfilterpackage tests pass 69 of 69 with assertions on and off (stock: 5 fail). - All of
:lucene:analysis:common:testwith assertions on: 1,915 tests, 18 skipped, 0 failures. :lucene:analysis:common:check -x testpasses (generated-source checksums, google-java-format, ecjLint, forbiddenApis; run with the standalone JUnit file moved out, as it is not part of the patch).- The regenerated scanner changes only in
zzDoEOF()(12 changed lines; the DFA tables are identical; 428,378 to 428,514 bytes). - With the grammar fix and the original
testOffsetsinput,testOffsetsfailsexpected:<16> but was:<32>; the changed input passes on stock main and with the fix (the helper's logic run on both). - A plain-Java probe on the fixed classes (first run, same grammar change) keeps every input of the table (
a < b,<ahref,if a < b.,<p>Hello</p><divends in<div).
In the %eof Exclude branch, output the pending segment when its second character is whitespace (< b, </ b) and keep dropping <b.
Trade-offs
Fixes the plain-text form a < b and keeps today's drop of a truncated <div, which a committer may prefer; the existing tests do not force A over B. It matches browsers for < directly followed by a letter, but keeps the inconsistency the tests contradict (<ahref dropped while <ahref and <ahref=http:.. are kept) and adds a special case to the switch. testOffsets needs the same change, because its trailing < X has a space.
Make the end of input also consume <name ... when a tail was read.
Trade-offs
Contradicts the testMalformedHTML gold values (<ahref=http:.., <a href="), the "all input is output" rule for unclosed <!, and SOLR-2328 (Won't Fix), where the maintainers declined to strip a mid-text unclosed tag; the shared fallback rule would need to know about end of input.
Search servers that expose this class, such as Solr as solr.HTMLStripCharFilterFactory or other servers as an html_strip char filter built on it, would lose the same trailing word (inferred from the shared class; not run on a downstream product).
A public-API probe of the filter showed a < b turning into a while a < b kept its text. A model of the scanner's end-of-input states, parsed from the grammar, then flagged exactly this case, and a sweep of 70.6 million short strings found violations in exactly the predicted states.
The method in full206 words
- First signal (a probe, not a formal method). A planning probe on the stock main jar, using only the public API, stripped prefixes of
x< notatag more text here and more wordsand a hand-listed set of inputs, and showedx< notgivingxanda < bgivinga, whilex< notatag mandx < y zwere kept. - State-table model. A model parsed from the real
.jflexcovered all 22 exclusive lexical states, with one obligation: a state whose mid-text failure gives the pending input back must also output it at end of input. It flagged exactly 5 states: the 4 tag-tail states and the documented character-reference tail. - Bounded-exhaustive sweep. On the stock jar, with a metamorphic oracle (appending
" "or" z "must not change the earlier output): 36,012,942 strings over 18 symbols up to length 6, and 34,636,832 strings over a 32-token grammar up to length 5, each stripped 3 times. Violations occurred in exactly those 5 states and in none of the 16 other reached states, with 0 final-offset errors. With the fix, only the character-reference tail remains. - The finder then wrote the public-API JUnit, the fix and the version runs; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-28): GitHub issues and PRs, the changed files of all open PRs, JIRA, the Lucene and Solr lists, downstream trackers and the web. Closest: SOLR-5983, another end-of-input fix in the same switch, and SOLR-2328, where maintainers kept mid-text unclosed tags as text.
Searches6 searches
Nothing describes this bug. GitHub search matches terms, so a report that only said "my last word is missing" without naming the filter could have been missed.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (three runs) | 2026-10-28 | the finder's run (40 queries) and two follow-up runs (59; 40) over apache/lucene issues and PRs, commits (3 queries in each of the first two runs), downstream trackers, the dev@, java-user@, issues@ and commits@ lists and JIRA; 50 + 219 + 206 = 475 hits | no report |
| GitHub (manual) | 2026-10-28 | per the follow-up, the 44 apache/lucene issues and PRs a search for HTMLStripCharFilter returned, every title triaged (a later search also gave 44); class, state and symptom terms; apache/solr, Elasticsearch, OpenSearch, Lucene.NET; per the follow-up, the changed-file lists of all 410 open apache/lucene PRs; the commit log of the .jflex | no report; only #13157 (open, test-only, attribute values) touches the charfilter tests |
| JIRA and list archives | 2026-10-28 | LUCENE and SOLR JIRA: the HTMLStripCharFilter and HTMLStripCharFilterFactory result sets (22, 14 and 38 issues) triaged by title; LUCENE-3690's 41 comments grepped for end of input, EOF, unclosed, truncated, trailing, incomplete; lists.apache.org (Lucene and Solr lists) for the class names with last, end, less, missing, lost, unclosed, truncated | no report |
| Web | 2026-10-28 | 5 queries | no relevant hit |
| Re-checks | 2026-10-28 (twice) | issues and PRs created since 2026-10-26; newest PRs | nothing new; #16927 (JFlex-skeleton javadoc typo) is unrelated |
| Closest items (read) | 2026-10-28 | full threads | SOLR-5983 (2014, unclosed CDATA at end of input, same switch), SOLR-2328 (Won't Fix: the maintainers declined to strip a mid-text unclosed tag), #7005 / LUCENE-5943 (closed tags stripped by design), #4764 / LUCENE-3690 (the rewrite) |
Introduced by the JFlex rewrite LUCENE-3690 (f3a363708ff, 2012-01-22; backport d387ae60fcf), first released in 3.6.0. The same six result lines on every one of the 21 tested targets from 3.6.0 to 10.5.2 and main; the Solr 3.5.0 filter it replaced keeps the text. Not fixed upstream.
Versions tested6 rows
Introduced by LUCENE-3690 (#4764), "Re-implemented HTMLStripCharFilter as a JFlex-generated scanner", by sarowe: trunk f3a363708ff (2012-01-22, svn r1234452) and the branch_3x backport d387ae60fcf (2012-01-24), which shipped in 3.6.0. Svn era, no PR.
Not a recent regression. Present since the first Lucene implementation in 3.6.0 (against the Solr 3.5.0 filter it replaced, it was a behaviour change). Four later commits edited the %eof block (LUCENE-3913 comments, SOLR-5983 empty-segment guard, LUCENE-5770 isRead(), LUCENE-10239 an (int) cast); none moved a case label, so the releases between the tested ones are expected to behave the same. The later behaviour fixes #11724 (9.9.0) and #15756 (10.5.0) touch attribute rules only; runs on both sides give the same output. The latest upstream commit to the grammar, 02014a6245d3 (#15756, authored 2026-03-03 UTC), leaves %eof untouched.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | 3 new tests: 2 fail through gradle (assertions on and off); standalone JUnit 3 of 3 fail; probe drops 6 of 6 |
branch_10_6 build at 4ae946e5a9b (10.6.0, released 2026-10-29) | affected | standalone JUnit 3 of 3 fail (assertions on) |
| 10.5.2, 9.12.3 | affected | standalone JUnit 3 of 3 fail (assertions on and off); probe drops 6 of 6 |
| 9.1.0 | affected | standalone JUnit 3 of 3 fail (assertions on) |
| 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 10.0.0, 10.4.0, 10.5.0 | affected | probe drops 6 of 6 inputs, the same six result lines (3.6.x ran a variant of the probe for the 3.6 constructor; 8.11.4 ran from the release jar) |
Solr 3.5.0 HTMLStripCharFilter (the predecessor) | predecessor | probe keeps all 6 inputs (a < b stays a < b) |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication and a credibility audit each re-ran it on main and confirmed it. A reviewer from another model family judged it real with an intended-behaviour lens; its refute review said "not real" only because it could not run any command.
Checks and verdicts312 words
Every verdict below re-ran a repro on main a9779ef3c193 except the reading-only cross-model reviews, for which separate runs re-ran the repro (fails).
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only, two runs. It could run no command, so it voted not real on procedure; it said this is procedural, not a refutation, and that the inputs are normal public-API input. Its intent argument is answered in "Why it is a bug". A separate run re-ran the repro: fails 3 of 3. |
| Independent reproducer | real | Own 5-test JUnit written from the claim: 3 defect tests fail, 2 controls pass, on main (assertions on and off), 10.5.2 (on and off) and 9.12.3; 18 of 18 metamorphic violations; a port of the pre-2012 filter keeps all the text. |
| Works-as-designed review | real (medium) | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens, reading only, on a copy without other verdicts: real, intended argument moderate; a separate run re-ran the repro: fails. |
| Intended-behaviour devil's advocate | real (moderate) | Built the strongest intended case and rejected it; reproduced on main (on and off) and 10.5.2; found the Solr Reference Guide's non-HTML example. |
| Adjudication | confirmed (medium), severity Low | Re-ran the independent reproduction's JUnit on clean main with a new seed, assertions on and off: 3 of 5 fail, controls pass. Residual doubt: no javadoc contract, and the grouping is deliberate code unchanged since 2012. |
| Credibility audit | keep | Re-ran the standalone JUnit on main with assertions off and a new seed: 3 of 3 fail; score and security confirmed. |
| Fix validation (this doc) | fix A passes | Gradle in a scratch worktree: stock 5 of 69 charfilter tests fail; fix A 0 of 69, the whole module 0 of 1,915, check -x test passes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 455 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,295 words
- Registry title
- HTMLStripCharFilter drops an unclosed '<name' or '</name' when the input ends right after the name, but outputs the same text when any character follows it, so 'a < b' indexes only 'a'
- Area
- analysis / HTMLStripCharFilter (JFlex grammar: the %eof end-of-input switch for the start- and end-tag tail states; also the 'htmlStrip' char filter SPI)
- Priority
- Medium, rank 130: Since 3.6.0, stock HTMLStripCharFilter silently drops the last word of any value or query that ends in an unclosed '<name' or '</name' (such as 'a < b'), but it loses at most that one word and needs an uncommon ending.
- Impact class
- silent wrong results
- Impact note
- Applications that strip HTML with HTMLStripCharFilter (directly, through the 'htmlStrip' factory, or through a downstream html_strip char filter; no Lucene analyzer adds it by default), at default settings and at any index size, silently lose the last word of a field value or query string that ends in '<' [whitespace] Name or '</' Name with no '>' (plain-text comparisons such as 'a < b' or 'for i<n', or text cut inside a tag), so a term query for that word misses the document; at most that one trailing word is lost, with no exception and correct offsets.
- Summary
- You run 'price a < b' through HTMLStripCharFilter and StandardTokenizer and expect [price, a, b], which is what you get for 'price a < b ' (one trailing space) or 'price a < b c'. Instead you get [price, a]: when the input ends right after '<' [whitespace] Name or '</' Name with no '>', the end-of-input handler throws the pending text away, while anywhere else the same unclosed construct is output as text, as the upstream tests require for '<ahref=http:..' at end of input. A TermQuery for 'b' therefore misses the document; other shapes are 'a<b' -> 'a', 'x <p' -> 'x ', 'a </b' -> 'a ' and 'if a < b.' -> 'if a ' ('.' is a name character).
- Introduced
- f3a363708ff95f28b5f29fe2cc27c1cd9fd0fca9 (trunk, svn r1234452, 'LUCENE-3690: Re-implemented HTMLStripCharFilter as a JFlex-generated scanner', by GitHub sarowe; issue LUCENE-3690 = apache/lucene#4764; no PR, svn era) and its branch_3x backport d387ae60fcf7ecb65596b756a0f8fc79923d0370 (svn r1235308), the commit that shipped in 3.6.0 [read: git log -L of the %eof block in the full-history clone: START_TAG_TAIL_EXCLUDE/SUBSTITUTE and END_TAG_TAIL_EXCLUDE/SUBSTITUTE sit in the Exclude group from f3a363708ff on (jflex lines 289-293 there, 292-296 in the 3.6.0 tag, 284-288 on main); the later edits ada9780484e (LUCENE-3913, comments), 2acbcd08ccc (SOLR-5983, empty-segment guard), b2071884216 (LUCENE-5770, isRead()) and af831d28105 (LUCENE-10239, int cast) moved no case label] [exec: the replaced Solr 3.5.0 filter keeps the text, 3.6.0 drops it]. Wrong from the first release of the JFlex filter, not a later regression (2012-01-22 (trunk f3a363708ff, authored and committed 2012-01-22T05:20:46Z); branch_3x backport d387ae60fcf 2012-01-24)
- First affected version
- 3.6.0 [exec] (the first release of org.apache.lucene.analysis.charfilter.HTMLStripCharFilter, from the branch_3x backport; on the trunk line the first tag is 4.0.0-alpha; its predecessor, Solr 3.5.0's org.apache.solr.analysis.HTMLStripCharFilter, keeps the text [exec])
- Affected versions
- every release from 3.6.0 to 10.6.0 (10.6.0 executed as the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193. [exec] the follow-up's version-neutral probe (only HTMLStripCharFilter; oracle: appending one space may only append one space) drops 6 of 6 inputs, with byte-identical output, on 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.2 and main (21 targets, both sides of the later fixes #11724 and #15756); the finder's JUnit fails 3 of 3 on 9.1.0 (-ea), 9.12.3 and 10.5.2 (-ea and -da), branch_10_6 head 4ae946e5a9b (-ea) and main (-ea and -da); the independent reproduction's JUnit fails 3 of 5 on main and 10.5.2 (-ea and -da) and 9.12.3 (-ea); the intended-behaviour check reproduced on main (-ea, -da) and 10.5.2 (-da); re-runs on main 2026-10-28. [read] the releases in between, because the %eof case grouping is unchanged since f3a363708ff
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-28, read-only:, re-check; the prior-report record, verdict new): three scripted prior-report searches (40, 59 and 40 queries over apache/lucene issues and PRs, commits, downstream trackers, the dev, java-user, issues and commits lists and JIRA; 0 same-bug hits among 475 hits), direct GitHub searches over apache/lucene (all 44 HTMLStripCharFilter issues and PRs triaged), apache/solr, Elasticsearch, OpenSearch and Lucene.NET, the changed-file lists of all 410 open apache/lucene PRs (only #13157, test-only and about attribute values, touches the charfilter tests), the upstream commit log of the .jflex (latest 02014a6245d3, #15756, authored 2026-03-03, %eof untouched), LUCENE and SOLR JIRA (the 41-comment LUCENE-3690 thread has no end-of-input discussion), lists.apache.org and 5 web searches. Nearest items, none about this bug: SOLR-5983 (2014: an end-of-input assertion for unclosed CDATA fixed in the same %eof switch, which added 'unclosed angle bang - all input is output' tests and left the tag-tail grouping alone), SOLR-2328 (Won't Fix 2017: a mid-text unclosed tag kept as text, as intended), #7005 (LUCENE-5943, Not A Problem: closed tags are stripped by design) and #4764 (LUCENE-3690, the rewrite). Re-check: no apache/lucene issue or PR mentioning HTMLStrip created since 2026-10-26, only #16927 (open, an unrelated JFlex-skeleton javadoc typo) updated since 2026-10-27, and no open PR created since 2026-10-26 touches analysis/common
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: three newTestHTMLStripCharFiltermethods and the hunt's standalone JUnit with assertions on and off (stock: 5 of the 69charfilterpackage tests fail; fix A: all pass), fix A with all of:lucene:analysis:common:test(1,915 tests, 0 failures) andcheck -x test, the scanner regenerated by the build's own task; the worktree was removed afterwards. The standalone JUnit on 9.1.0, 9.12.3, 10.5.2 and abranch_10_6build at4ae946e5a9b; amain()probe on 21 targets from 3.6.0 to main and on the Solr 3.5.0 predecessor; the independent checkers' tests on main, 10.5.2 and 9.12.3; OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:30-32 (at a9779ef3c193) (class javadoc: 'A CharFilter that wraps another Reader and attempts to strip out HTML constructs.'), :275-296 (%eof switch, 'Exclude' group: END_TAG_TAIL_EXCLUDE, END_TAG_TAIL_SUBSTITUTE, START_TAG_TAIL_EXCLUDE, START_TAG_TAIL_SUBSTITUTE clear the pending text), :297-305 (CHARACTER_REFERENCE_TAIL, 'At end of file, allow char refs without semicolons'), :306-318 ('Include' group: BANG, CDATA, AMPERSAND, NUMERIC_CHARACTER, *_TAG_TAIL_INCLUDE, LEFT_ANGLE_BRACKET, LEFT_ANGLE_BRACKET_SLASH, LEFT_ANGLE_BRACKET_SPACE output the pending text), :643-649 and :693-712 ('<', optional whitespace, a Name enters START_TAG_TAIL_*), :914-922 (mid-text fallback: yypushback and output inputSegment verbatim)lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.java (at a9779ef3c193) (generated zzDoEOF, same switch)lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:152 (at a9779ef3c193) testMalformedHTML, :194-195 ('<a href=\"' -> '<a href=\"'), :218-219 ('<ahref=http:..' -> '<ahref=http:..'), :336-359 (doTestOffsets helper and testOffsets input 'X < &zz >X &# < X > < &l > &g < X'), :474 and :502 (testCDATA, 'unclosed angle bang - all input is output')
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:30-32 (class javadoc), :48-49 (the six tag-tail states), :69 (Name), :275-323 (%eof; Exclude :284-288, CHARACTER_REFERENCE_TAIL :297-305, Include :306-318), :334-339, :574-641, :643-712, :714-745, :914-922 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.java:6133-6185 (zzDoEOF) @ a9779ef3c193
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilterFactory.java:42 (NAME = "htmlStrip") @ a9779ef3c193
- Why it looks unintended
lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:152, :194-195, :218-219 (testMalformedHTML), :336-359 (doTestOffsets, testOffsets), :474, :502, :508 (testCDATA), :619-621 (char-reference end of input) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:30-32, :298, :306-318, :914-922 @ a9779ef3c193
- Suggested fix
lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:336-359 @ a9779ef3c193
- TestHTMLStripUnclosedTagAtEnd.java (JUnit test):
repro/LFV-878/src/org/apache/lucene/analysis/charfilter/TestHTMLStripUnclosedTagAtEnd.java(34 lines)
assets/LFV-878/bug.png(455 KB)