DoubleDocValuesStats collects count, min, max, sum, mean and variance of a double doc-values field, one value at a time, through DocValuesStatsCollector or, since 10.5.0, DocValuesStatsCollectorManager.
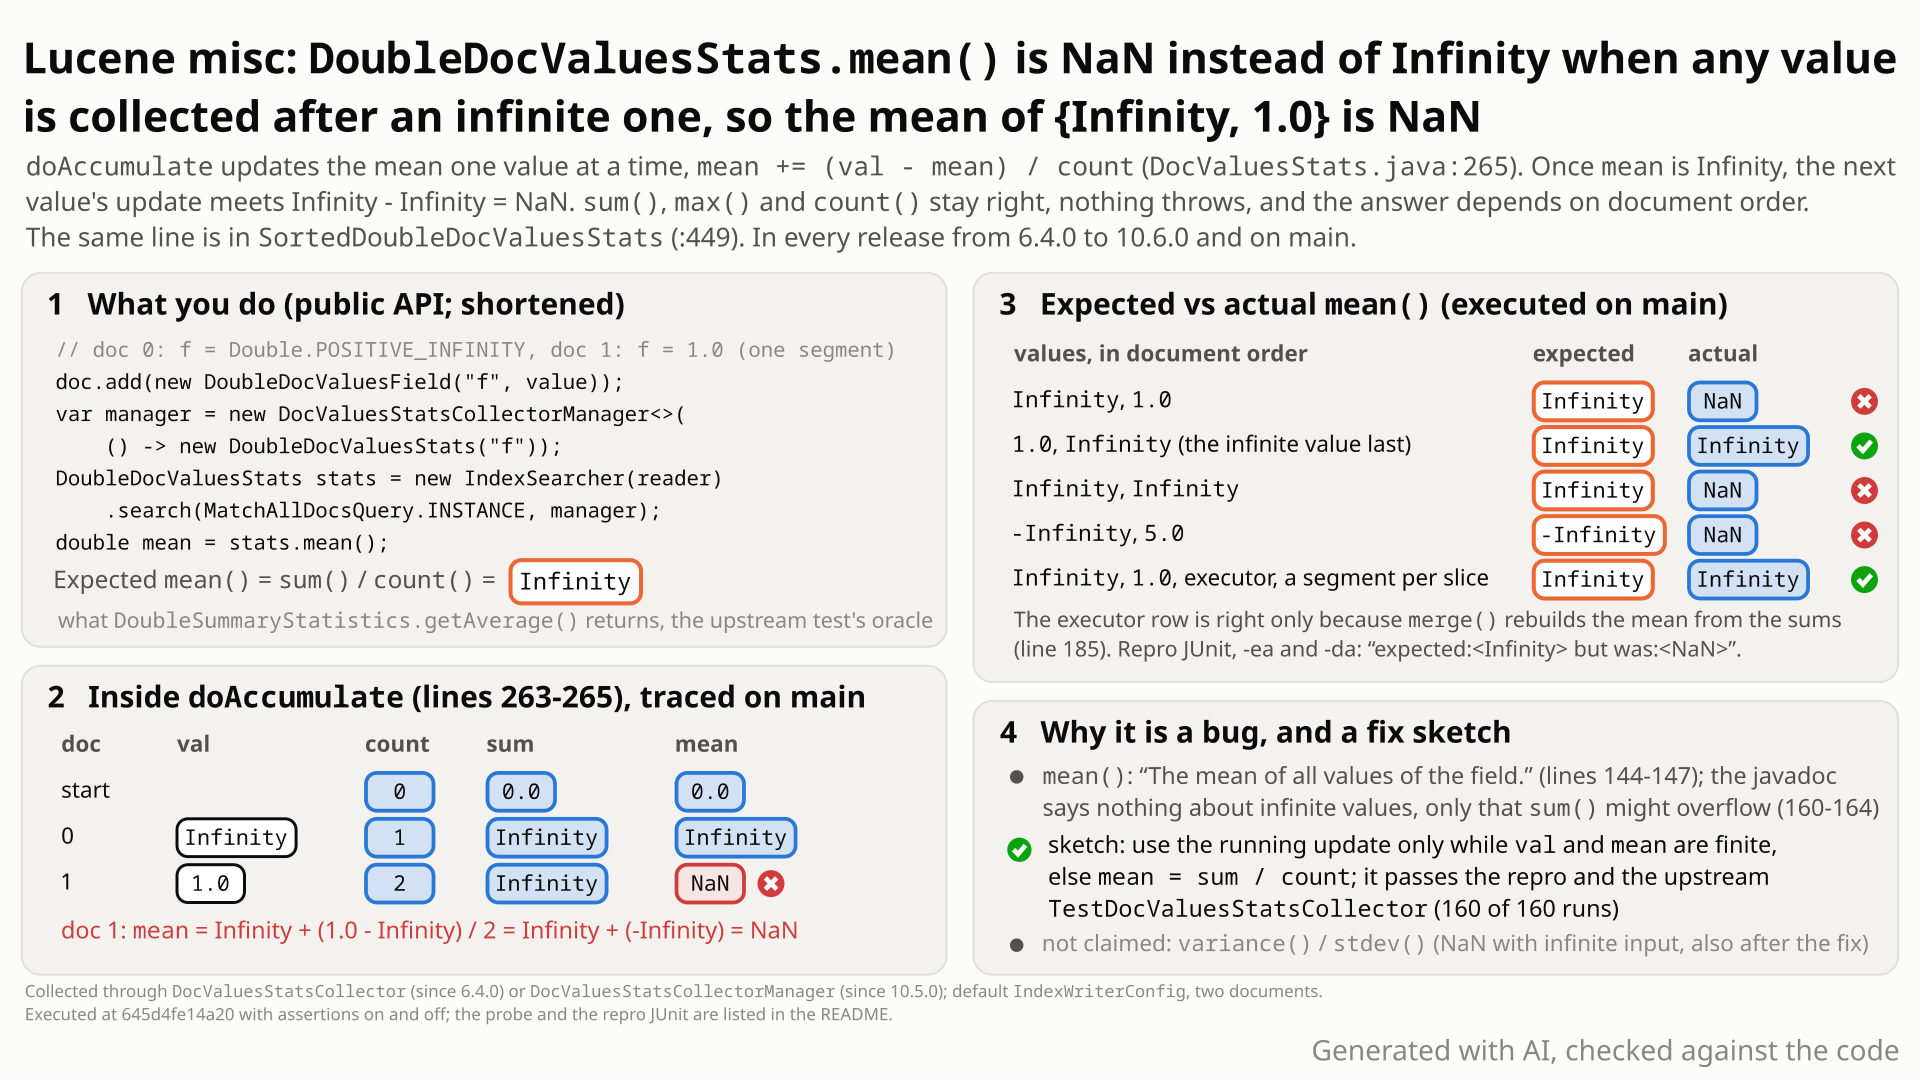
- Index two documents with a
DoubleDocValuesFieldf: doc 0 = +Infinity, doc 1 = 1.0. Summarize the field withDocValuesStatsCollectorManagerandDoubleDocValuesStatson a plainIndexSearcher. - You expect
mean()= +Infinity, because (+Infinity + 1.0) / 2 = +Infinity. That issum() / count()of the same object, and whatDoubleSummaryStatistics, the upstream test's reference formean(), returns. - Instead
mean()is NaN, whilecount()= 2,sum()= +Infinity andmax()= +Infinity. The mean is updated one value at a time,mean += (val - mean) / count: after doc 0 it is Infinity, and doc 1 gives Infinity + (1.0 - Infinity) / 2 = Infinity - Infinity = NaN. - The answer depends on document order: {1.0, +Infinity} gives +Infinity, and {+Infinity, +Infinity} gives NaN. Since 10.5.0 a searcher that puts the segments in different slices (for example an executor with one segment per slice) can return +Infinity for the same index, because
merge()rebuilds the mean from the sums.
Applications that summarize a double doc-values field with the lucene/misc DoubleDocValuesStats or SortedDoubleDocValuesStats, when the field holds +Infinity or -Infinity and another value is collected after it. Default settings; two documents suffice. Infinite stored values are unusual and the classes are rarely used, so the priority is low.
Mechanism, terms and numbers686 words
DocValuesStats.DoubleDocValuesStats and SortedDoubleDocValuesStats (lucene/misc) document mean() as "The mean of all values of the field." and update it one value at a time with mean += (val - mean) / count. Once a value is +Infinity or -Infinity the running mean is infinite, and the next value computes Infinity - Infinity: the mean of {+Infinity, 1.0} is NaN, while sum() and max() of the same object are +Infinity and sum() / count() is +Infinity. {1.0, +Infinity} gives +Infinity, {+Infinity, +Infinity} gives NaN, and since 10.5.0 a searcher that puts the segments in different slices can return +Infinity for the same index. In the executed runs nothing throws. Every release from 6.4.0 (where the classes appeared) to 10.6.0 is affected.
- Per value.
accumulate(doc)incrementscountand callsdoAccumulate(count)for each collected document with a value (DocValuesStats.java:63-70). - The running update (
DoubleDocValuesStats.doAccumulate,DocValuesStats.java:255-267):
   sum += val;
   double oldMean = mean;
   mean += (val - mean) / count;               // :265
   variance += (val - mean) * (val - oldMean);
SortedDoubleDocValuesStats.doAccumulate does the same for each value of a document, with ++valuesCount and mean += (val - mean) / valuesCount (:443-450).
- Worked steps for {+Infinity, 1.0}. Value 1:
mean = 0 + (Inf - 0) / 1 = Inf. Value 2:(1.0 - Inf) / 2 = -Inf, somean = Inf + (-Inf) = NaN. For {+Inf, +Inf} the second step isInf + (Inf - Inf) / 2 = Inf + NaN = NaN. Once NaN, the mean stays NaN. If the infinite value comes last ({1.0, +Inf}), the last step is1.0 + (Inf - 1.0) / 2 = Inf, the right answer. - What stays right.
sum(:263) andmax(:257-259) are +Infinity andcountis 2. - Why an executor can disagree (10.5.0 and later).
DocValuesStatsCollectorManager.reduce()merges every collector's stats into a fresh object (DocValuesStatsCollectorManager.java:58-68). The first merge copies the mean unchanged (DocValuesStats.java:175-181); each later merge rebuilds it as(sum() + otherStats.sum()) / totalCount(:184-185; sorted variant:353-355), which keeps +Infinity. A plainIndexSearcherhas one slice for all segments (IndexSearcher.java:226-231), so one collector and the running mean; with one segment per slice, {+Inf} and {1.0} land in different collectors and the merge gives +Infinity. This is a question of slice layout, not of the executor alone: by default an executor groups up to 5 small segments (up to 250,000 documents) into one slice (IndexSearcher.java:106-108,:323-325), so two small segments still share one collector; the executed manager tests overrideslices()to give each segment its own slice.
- On a plain searcher: {+Inf, +Inf} -> NaN; {-Inf, 5.0} -> NaN (expected -Infinity); {1.0, +Inf} -> +Infinity while {+Inf, 1.0} -> NaN;
SortedDoubleDocValuesStatsover docs {+Inf}, {1.0} -> NaN and over one doc {+Inf, +Inf} -> NaN; {Inf, 1, 2} -> NaN, {1, 2, Inf} -> +Infinity, {Inf} -> +Infinity; {Inf, -Inf} -> NaN, which is right. - With an executor and one segment per slice (forced by overriding
slices()), two segments {+Inf} and {1.0}: +Infinity, while the plain searcher gives NaN for the same index.
- Not part of this bug:
variance()/stdev()(NaN with infinite input, before and after a fix); the finite overflow {Double.MAX_VALUE, -Double.MAX_VALUE} -> mean -Infinity (the same line, extreme magnitudes); the initial min/max values (LFV-155). SortedDoubleDocValuesStatsdecodes raw double bits (Double.longBitsToDouble,:436), as the upstream test writes them; for positive values raw andNumericUtilssortable bits are identical, so the positive examples do not depend on that choice. The single-valuedDoubleDocValuesFieldcase is the clean trigger.- Within one document,
SortedDoubleDocValuesStatssees the values sorted byLong.compareof their stored bits (SortedNumericDocValues.java:22), not in insertion order. With raw double bits +Infinity sorts after every positive finite value, so one document {+Inf, 1.0} is collected as 1.0, +Inf and is right (by reading); one document {+Inf, +Inf} gives NaN, and so does one document {-Inf, 1.5}, since negative values sort first (the harness re-run).
Exposure and likelihood196 words
- Who is exposed. Users of these classes through
DocValuesStatsCollector(every release since 6.4.0) orDocValuesStatsCollectorManager(10.5.0 and later), with the defaultIndexWriterConfig, codec and searcher, whenever the field holds an infinite value (an overflowed computation stored as is, or an explicit sentinel) and the same collector collects another value after it: a later document in doc-id order or, for the sorted variant, a later value of the same document. - Effect. Silent wrong result:
mean()is NaN instead of +Infinity or -Infinity, and anything computed from it is NaN too. Which answer you get depends on document order and, since 10.5.0, on the slice layout (one slice versus one segment per slice; with an executor the default slicing still groups up to 5 small segments into one slice). In the executed runs: no exception, no hang, and the stats classes only read the index. - Not affected. The infinite value collected last by its collector; values that mix +Infinity and -Infinity (NaN is right there); the long variants;
count(),sum()and, in these examples,max()(with only non-positive valuesmax()has its own bug, LFV-155). - Releases. Every release from 6.4.0 to 10.6.0 and main. Priority low.
One JUnit test method in lucene/misc, public API: two documents (+Infinity, then 1.0), the default IndexWriterConfig, a plain IndexSearcher. Deterministic, one thread; the same result with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.misc.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.DoubleDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.misc.search.DocValuesStats.DoubleDocValuesStats;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDocValuesStatsInfiniteMean extends LuceneTestCase {

  public void testMeanOfInfinityThenOne() throws Exception {
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (double value : new double[] {Double.POSITIVE_INFINITY, 1.0}) {
          Document doc = new Document();
          doc.add(new DoubleDocValuesField("f", value));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        DoubleDocValuesStats stats =
            new IndexSearcher(reader)
                .search(
                    MatchAllDocsQuery.INSTANCE,
                    new DocValuesStatsCollectorManager<>(() -> new DoubleDocValuesStats("f")));
        // expected: mean of {+Infinity, 1.0} is +Infinity (= sum() / count()); actual: NaN
        assertEquals(Double.POSITIVE_INFINITY, stats.mean(), 0.0);
      }
    }
  }
}
cp $REPRO/TestDocValuesStatsInfiniteMean.java $LUCENE/lucene/misc/src/test/org/apache/lucene/misc/search/
cd $LUCENE && ./gradlew :lucene:misc:test --tests TestDocValuesStatsInfiniteMean -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
- Expected
mean()= +Infinity, the mean of +Infinity and 1.0 (=sum()/count()).- Observed
mean()= NaN:AssertionError: expected:<Infinity> but was:<NaN>, with assertions on and off.
More files, environment, full output186 words
The two documents go into one segment at close() in insertion order, and a plain IndexSearcher uses one collector. The seed still randomizes the test framework's environment: the default codec, which new IndexWriterConfig() inherits, the directory implementation, the similarity, the locale and the time zone. The wrong mean comes from the stats class's arithmetic, and both seeds run fail the same way (DEADBEEF with codec Lucene104, C0FFEE with Asserting(Lucene104)). The test needs DocValuesStatsCollectorManager, so it compiles on 10.5.0 and later; on older releases the same check runs through IndexSearcher#search(Query, Collector) with a DocValuesStatsCollector.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; pure Java arithmetic) |
cp $REPRO/TestDocValuesStatsInfiniteMean.java $LUCENE/lucene/misc/src/test/org/apache/lucene/misc/search/
cd $LUCENE && ./gradlew :lucene:misc:test --tests TestDocValuesStatsInfiniteMean -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
TestDocValuesStatsInfiniteMean > testMeanOfInfinityThenOne FAILED
    java.lang.AssertionError: expected:<Infinity> but was:<NaN>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:867C5475491EFF6]:0)
        ...
        at org.apache.lucene.misc.search.TestDocValuesStatsInfiniteMean.testMeanOfInfinityThenOne(TestDocValuesStatsInfiniteMean.java:48)
:lucene:misc:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false, on the standalone runner (-ea, -da) and on the 10.6.0 release jars (-ea, -da)
# with the recommended fix: :lucene:misc:test (SUCCESS)mean()is documented as "The mean of all values of the field."; the only numeric caveat is thatsum()might overflow.- The class contradicts itself:
sum(),max()andmerge()give +Infinity, and the upstream test checksmean()againstDoubleSummaryStatistics, which gives +Infinity. - The answer depends on document order, and {+Infinity, +Infinity} gives NaN.
The full argument142 words
- Contract.
mean(): "The mean of all values of the field." (DocValuesStats.java:144-147,:306-309), with no restriction to finite values. The only numeric caveat is onsum(): "Note that if the values are large, thesummight overflow." (:160-163,:327-330). - The upstream test's oracle.
TestDocValuesStatsCollectorchecksmean()againstDoubleSummaryStatistics.getAverage()(:199-202,:318-322), which returns +Infinity for these values; the test only indexes the finite positive values 1, 2, 3, ... (:159-211). - Legal input.
DoubleDocValuesFieldstores any double withDouble.doubleToRawLongBits(DoubleDocValuesField.java:38-40), and Lucene's ownTestDocValuesQueries#testDocValueQueryWhenFieldNameIsAlsoUsedForPointsindexesDouble.NEGATIVE_INFINITYandDouble.POSITIVE_INFINITYinto it (TestDocValuesQueries.java:1021-1048). - History. LUCENE-7590 (#8641) introduced the running update; the only numeric limit discussed was sum overflow ("Should we care about overflow, or only document it?"), never NaN or infinity. The #15653 review does not mention non-finite values either.
The devil's-advocate check209 words
Strongest case (the intended-behaviour check, the adjudication): the running update is the textbook online (Welford-style) recurrence for a running mean and variance. Apache Commons Math 3.6.1 uses the same recurrence in its storeless Mean and documents: "Note that Double.NaN may also be returned if the input includes NaN and / or infinite values." In a reference run its SummaryStatistics.getMean() returns exactly Lucene's values, order dependence included, and its DescriptiveStatistics / StatUtils.mean() return NaN for any input with an infinity. Lucene's javadoc does not spell out IEEE semantics, IndexSearcher#search(Query, CollectorManager) is @lucene.experimental, and finite means already differ by rounding between the serial and the executor path.
Why it fails: none of that is in Lucene (no javadoc caveat, test, CHANGES or MIGRATE entry, or review comment), and Lucene's own code and test point to +Infinity (sum(), max(), merge(), the DoubleSummaryStatistics oracle). An order-dependent answer, and NaN for {+Inf, +Inf}, is an artifact of Infinity - Infinity. NaN versus +Infinity is not rounding, and the serial failure needs no experimental API: it reproduces through the plain DocValuesStatsCollector on 9.12.3 and earlier. Verdict: not intended, a defect. A maintainer may still prefer a javadoc caveat; it would have to cover the order dependence and the executor disagreement.
Recommended Fall back to sum / n once the running mean is not finite
In both double doAccumulate methods, keep the running update while the mean is finite, else use mean = sum / n and variance = NaN (+16/-4). Inputs whose running mean stays finite keep today's results; after a finite overflow of the mean, later values get sum / n, not NaN. The test and all lucene/misc tests pass with it.
       sum += val;
       double oldMean = mean;
-      mean += (val - mean) / count;
-      variance += (val - mean) * (val - oldMean);
+      if (Double.isFinite(mean)) {
+        mean += (val - mean) / count;
+        variance += (val - mean) * (val - oldMean);
+      } else {
+        // once the mean is infinite, (val - mean) can be Infinity - Infinity = NaN
+        mean = sum / count;
+        variance = Double.NaN;
+      }
All options and trade-offs4 options · 905 words
Two code fixes were built and run in scratch worktrees of 645d4fe14a20 with gradle; they differ in the guard and in the wording of the new comment. A javadoc-only change and an always-sum / count mean were considered and not built.
While the running mean is finite the update is today's: a finite mean plus an infinite step is the right +Infinity or -Infinity (NaN for a NaN value). Only after the mean has become non-finite does the next value use sum / n, the formula merge() uses. For the infinity examples above that is the DoubleSummaryStatistics answer in either document order, and in the independent reproduction's manager test the plain and the one-segment-per-slice searcher agree. It is only as good as sum: once finite values near Double.MAX_VALUE have overflowed sum, sum / n can be NaN. The same change goes into SortedDoubleDocValuesStats with valuesCount.
       sum += val;
       double oldMean = mean;
-      mean += (val - mean) / count;
-      variance += (val - mean) * (val - oldMean);
+      if (Double.isFinite(mean)) {
+        mean += (val - mean) / count;
+        variance += (val - mean) * (val - oldMean);
+      } else {
+        // once the mean is infinite, (val - mean) can be Infinity - Infinity = NaN
+        mean = sum / count;
+        variance = Double.NaN;
+      }
Trade-offs
- Inputs whose running mean stays finite (finite values not near +/-
Double.MAX_VALUE) take today's path, so their results do not change. When finite values do overflow the running mean, later values now getsum / ninstead of NaN: {MAX_VALUE, -MAX_VALUE, 1.0} gives 0.3333333333333333, asDoubleSummaryStatisticsdoes, where stock gives NaN. In the finder's exhaustive harness all 2,044 stock cases with NaN for a finite exact mean change: 1,972 become right and 72 become +/-Infinity; no result that stock gets right changes. variancebecomes NaN once the mean is non-finite, which is what stock already returns.- One
Double.isFinitecheck per value; no benchmark was run. - Not covered: the finite overflow {Double.MAX_VALUE, -Double.MAX_VALUE} -> -Infinity, as on stock; and values collected after finite values have overflowed
sumand an infinity of the other sign has followed (72 harness cases still give NaN where the exact mean is an infinity, e.g. MAX_VALUE, MAX_VALUE, -Infinity, -0.0, wheresumis already NaN when the last value arrives).
What the checks validated
- gradle, stock + test: fails with assertions on and off; + this fix: the test passes.
- gradle, + this fix: all
lucene/misctests, 317 tests (9 skipped), 0 failures, assertions on; the test andTestDocValuesStatsCollectorfor 10 iterations (90 tests), 0 failures, assertions off;checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainpass. - Standalone runner with the patched file shadowed: the test (assertions on and off), the independent reproduction's serial test (7 tests: the sorted variant, {-Inf, 5.0}, the order dependence) and manager test (plain versus a one-segment-per-slice executor searcher), and upstream
TestDocValuesStatsCollectorfor 20 iterations (160 tests) pass. - A plain-Java model of the recurrences over 9 inputs: the
DoubleSummaryStatisticsanswer on 5 of the 6 inputs with an infinity; on {MAX_VALUE, MAX_VALUE, -Infinity} it keeps stock's -Infinity, the exact answer, whereDoubleSummaryStatisticsand the alternative give NaN. - The finder's exhaustive harness with this fix shadowed (re-run by the fact check): SDOUBLE 0 serial mean mismatches; DOUBLE 3,186, all from finite values near +/-
Double.MAX_VALUE(72 NaN where the exact mean is an infinity, 3,114 finite overflow), against 39,734 on stock. Not run: the full Lucene test suite, nightly tests, benchmarks.
The same change with if (Double.isFinite(val) && Double.isFinite(mean)), so an infinite value arriving while the mean is finite also takes the sum / n branch.
Trade-offs
Same answers on all the tests, but only as good as sum: when finite values have already overflowed sum (values near Double.MAX_VALUE) and an infinity of the other sign follows, it gives NaN: {MAX_VALUE, MAX_VALUE, -Infinity} -> NaN, where stock and the recommended fix give -Infinity (DoubleSummaryStatistics gives NaN too). Shown by the plain-Java model and through the Lucene class in the harness re-run: 348 cases with NaN where the exact mean is an infinity, against 72 for the recommended fix.
What the checks validated
- gradle: all
lucene/misctests (317, 9 skipped, 0 failures, assertions on); the test andTestDocValuesStatsCollectorfor 10 iterations (assertions off);:lucene:misc:check -x test. - The independent reproduction's serial and manager tests pass with it shadowed.
Document on mean() that the result may be NaN when the values include an infinity or NaN, as Apache Commons Math does. Not built.
Trade-offs
Smallest change, but it leaves the order dependence ({1.0, +Inf} gives +Infinity), NaN for {+Inf, +Inf} and the serial-versus-executor disagreement, and it documents an answer that differs from DoubleSummaryStatistics, the reference the upstream test uses.
Drop the running mean for mean(). Not built and not modelled.
Trade-offs
It is the formula merge() already uses and removes the order dependence for the infinity examples, but the sum itself overflows for large finite values ({Double.MAX_VALUE, Double.MAX_VALUE} would give +Infinity instead of Double.MAX_VALUE; DoubleSummaryStatistics gives Infinity there too), finite results change by rounding, and variance still needs the running mean.
An application that reports this mean shows NaN instead of Infinity for such a field, depending on document order; in these examples count(), sum() and max() stay right.
A bounded-exhaustive check: a harness ran the real stats classes over small double alphabets (NaN, zeros, infinities, 1.5, -2.5, plus extreme finite values for the plain variant) on every index of 1-3 segments, serially and with 1-3 slices, against an exact reference. Means of NaN where the reference is an infinity stood out; a public-API JUnit followed.
The method in full194 words
Method: bounded-exhaustive translation validation (semi-formal), a hunt unit (never-named public API sweep: facet, join, grouping, misc). The harness DvStatsExhaustive.java runs the real DoubleDocValuesStats and SortedDoubleDocValuesStats over small value alphabets (DOUBLE: NaN, +/-0.0, +/-Infinity, Double.MIN_VALUE, +/-Double.MAX_VALUE, 1.5, -2.5; SDOUBLE: NaN, -0.0, +/-Infinity, 1.5, -2.5) on every index of 1-3 segments (DOUBLE: 153,439 indexes, 879,571 searches; SDOUBLE: 112,140 indexes, 490,056 searches), serially and through DocValuesStatsCollectorManager under 1-3 slices and an intra-segment split, against an exact reference with IEEE semantics for non-finite values. On stock, 34,648 of the 39,734 DOUBLE serial mean mismatches and all 22,040 SDOUBLE ones are NaN where the reference is an infinity; the other 5,086 DOUBLE ones are the finite overflow near +/-Double.MAX_VALUE (not part of this bug). With the recommended fix SDOUBLE has no serial mean mismatch and DOUBLE keeps 72 NaN-for-infinity cases, all after finite values near Double.MAX_VALUE had overflowed sum, plus 3,114 finite-overflow cases; with the finder's sketch, 348 and 3,114. (The split by kind is the fact check's re-run of the unchanged harness.) The finder then wrote a public-API JUnit on the stock main jars; this doc's test is a one-method form of it.
No prior report found: 93 queries on 2026-10-28 (GitHub issues, PRs and commits, four mailing lists, the JIRA archive, downstream repositories, the web), refreshed on 2026-10-30. Related: #8641 (LUCENE-7590) introduced the running update, #15653 added merge(); neither discusses non-finite values.
Searches4 searches
Related, not reports of this bug: #8641 / LUCENE-7590 (introduced the running update; the only numeric caveat discussed was sum overflow); #15653 (added DocValuesStatsCollectorManager and merge(); nothing on non-finite values); #12342, #3347 and #15873 (NaN or infinity in vector similarity, function-query scores and the grouping maxScore). LFV-155 and LFV-882 are the hunt's own unfiled rows on the same file, with different fix sites.
Search caveats: the one-word GitHub queries (mean, variance) read only the first 50 results; the open-PR file check read the first 100 files of each PR (full lists for 3 of the 4 larger PRs; the API capped #16911, the 7,630-file branch_10x removal, at 3,000 files).
| Where | When | How | Found |
|---|---|---|---|
| GitHub (apache/lucene issues, PRs, commits; apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch; all of GitHub) | 2026-10-28 | a scripted prior-report search (51 queries incl. lists, JIRA and web) and 42 manual searches: the class names, "running mean", Welford, "Infinity - Infinity", mean()/stdev() NaN; #8641 (42 comments) and #15653 (41 review comments) read in full; git log -S over the full history | no report; #8641 and #15653 are related |
| Open apache/lucene PRs | 2026-10-28 | changed-file lists of all 410 open PRs | none touches a DocValuesStats file |
| Mailing lists and JIRA archive | 2026-10-28 | dev@, java-user@, issues@, commits@ and the JIRA archive through a scripted prior-report search; the list threads that matched read in full | no report |
| Refresh | 2026-10-30 | issue and PR searches for DocValuesStats, DoubleDocValuesStats, SortedDoubleDocValuesStats, DocValuesStatsCollector, "DocValuesStats NaN/Infinity/mean", "mean NaN Infinity", "running mean infinity", "Infinity - Infinity"; the files of the 8 open PRs created since 2026-10-28; the file's history on main and branch_10_6 | no new item; the last commit on DocValuesStats.java is still #15653 |
Present since the classes were added by LUCENE-7590 (ad7152ad473, 2016, first released in 6.4.0); the update line is unchanged since. #15653 (10.5.0) added the merge() path that gets +Infinity. Executed and failing on 14 releases from 6.4.0 to 10.6.0 and on main.
Versions tested6 rows
LUCENE-7590 "Add DocValues statistics helpers" (shaie; JIRA patch workflow, GitHub mirror #8641): ad7152ad473 on master and 7269c484a4a on branch_6x (authored 2016-12-11, committed 2016-12-14) created DoubleDocValuesStats with the running update; 944b8e07f55 / 63a5cd00173 (2016-12-17) gave SortedDoubleDocValuesStats the same update. git blame -C -C -M and git log -L on DocValuesStats.java:265 and :443-450 lead back to these commits; only comment re-wrapping (2cbf261032d) and the package move to org.apache.lucene.misc.search (d1110394e9c, 9.0.0) touched them since. #15653 "Introduce DocValuesStatsCollectorManager" (gaobinlong, co-author javanna, 0210af757c5, merged 2026-05-19, first in 10.5.0) added merge(), which rebuilds the mean from the sums; it did not cause the NaN. Not a regression and not fixed upstream.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the test fails, assertions on and off (gradle and standalone) |
10.6.0 (release jars, built at 4ae946e5a9b) | affected | the test fails, assertions on and off |
| 10.5.0, 10.5.2 | affected | the history probe returns NaN; the finder's manager test also shows serial NaN versus executor +Infinity |
| 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.4.0 | affected | the history probe returns NaN for {+Inf, 1.0}, {+Inf, +Inf} and the sorted variant; the controls are right |
| 6.3.0 | API absent | no DocValuesStats (compile error) |
with the fix (main 645d4fe14a20) | not affected | the test and all lucene/misc tests pass |
The finder, the independent reproduction, the intended-behaviour check, an adjudication (confirmed, medium) and a credibility audit rate it real, as does the intended-lens cross-model review (the cross-model review, reading only); the refute-lens review, also reading only, returned a procedural "not real" with no substantive refutation.
Checks and verdicts360 words
Every AI tool check re-ran a repro on the stock jars. The reviewer from another model family (OpenAI GPT-5.6) could not execute code in either lens; its execution evidence is a separate re-run of the finder's repro. The adjudication's medium confidence reflects that a maintainer may prefer a javadoc caveat, not doubt about the behaviour.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Bounded-exhaustive harness: on stock, 34,648 DOUBLE and all 22,040 SDOUBLE serial mean mismatches are NaN where the reference is an infinity (the other 5,086 DOUBLE ones are finite overflow near Double.MAX_VALUE); with the recommended fix SDOUBLE has none and DOUBLE keeps 72, all after sum overflowed. JUnit fails 2 of 2 on main (-ea, -da), branch_10_6 and 10.5.2; its collector-only form fails on 10.4.0, 9.12.3 and 9.1.0. |
| cross-model review, refute lens | not real, low, procedural only | It could not run code; root cause agreed, inputs in contract, intended-behaviour argument weak. A separate run re-ran the repro: fails. |
| Independent reproducer | real | Own public-API JUnits: serial 6 of 7 fail on main (-ea, -da), 10.5.2 and 9.12.3; the manager test 1 of 1 on main and 10.5.2; all pass with the fix. |
| Cross-model review, intended lens | real, medium (reading only) | Intended-behaviour argument weak; a separate run re-ran the finder's JUnit: 2 of 2 fail. |
| Devil's advocate | real, medium-high | Re-ran the repro on main, 10.5.2 and 9.12.3; weighed the Apache Commons Math precedent against Lucene's own javadoc, code and test, and the order dependence. |
| adjudication | confirmed, medium | Fresh seed: the independent reproduction's serial (6 of 7) and manager (1 of 1) JUnits fail with -ea and -da. |
| Follow-up and audit | keep | History probe on 12 releases and main; prior-report search; re-runs with fresh seeds; audit round 4 re-ran two JUnits (the hunt's record). |
| this doc's runs | reproduced, fixes validated | The one-method test on main 645d4fe14a20 (gradle and standalone, -ea, -da) and the 10.6.0 jars; both fixes with all lucene/misc tests; the independent reproduction's tests with each fix shadowed; a plain-Java model of the recurrences. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 557 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,457 words
- Registry title
- DoubleDocValuesStats and SortedDoubleDocValuesStats (lucene/misc) return mean() = NaN instead of +/-Infinity when any value is collected after an infinite value, so the mean of {+Infinity, 1.0} is NaN while the mean of {1.0, +Infinity} is +Infinity
- Area
- misc / DocValuesStats double statistics (DocValuesStatsCollector, DocValuesStatsCollectorManager)
- Priority
- Low, rank 581: The mean() of the niche misc DoubleDocValuesStats wrongly becomes NaN only when the field holds an infinite value and more values are collected after it, so it is a Low infinity edge case.
- Impact class
- silent wrong results
- Impact note
- Applications that summarize a double doc-values field with the lucene/misc DoubleDocValuesStats or SortedDoubleDocValuesStats, through DocValuesStatsCollector (every release since 6.4.0) or DocValuesStatsCollectorManager (10.5.0 and later), get mean() = NaN instead of +Infinity or -Infinity whenever the field holds an infinite value and another value of the same collector (slice) is collected after it, with the default IndexWriterConfig, codec and searcher on as few as two documents; count(), sum(), min() and max() stay right, nothing throws, the index is untouched, and since 10.5.0 a searcher with an executor can return +Infinity for the same index (variance() and stdev() are NaN with infinite input before and after a fix and are not part of the claim).
- Summary
- You collect statistics for a double doc-values field with DocValuesStats.DoubleDocValuesStats (or SortedDoubleDocValuesStats) and expect mean(), documented as 'the mean of all values of the field', to be +Infinity for the values {+Infinity, 1.0}: that is sum()/count(), and it is what java.util.DoubleSummaryStatistics, the oracle of the upstream test, returns. Instead mean() is NaN, because the running update mean += (val - mean) / count computes Infinity - Infinity as soon as the running mean is infinite and another value arrives; {+Infinity, +Infinity} also gives NaN, while sum() and max() report +Infinity. The answer depends on document order ({1.0, +Infinity} gives +Infinity) and, since 10.5.0, on the searcher: with an executor and one segment per slice, DocValuesStatsCollectorManager rebuilds the mean from the sums and returns +Infinity.
- Introduced
- ad7152ad4739 (master, 'LUCENE-7590: add DocValuesStatsCollector', by shaie; JIRA LUCENE-7590, migrated as apache/lucene#8641; pre-GitHub patch workflow, no PR): DoubleDocValuesStats was created with mean += (val - mean) / count; the release line got it through the branch_6x commit 7269c484a4a0 (a re-commit after 43f4f7a2795 was reverted by e09ef681e4d); SortedDoubleDocValuesStats got the same update per value in 944b8e07f557 (master) / 63a5cd00173f (branch_6x) [read: git blame -C -C -M and git log -L on main DocValuesStats.java:265 and :443-450 in the history clone; the lines are unchanged since, apart from comment re-wrapping in 2cbf261032d and the package move d1110394e9c; exec: release level only, 6.3.0 has no such API (compile error) and 6.4.0 fails; no commit-level build]; 0210af757c54 (#15653 'Introduce DocValuesStatsCollectorManager', by gaobinlong, co-author javanna, merged 2026-05-19, released in 10.5.0) added merge(), which rebuilds the mean as (sum + otherSum) / n: the source of the serial-versus-executor disagreement only, not of the NaN [read; exec on 10.5.0, 10.5.2 and main] (2016-12-11 (authored; committed to master and branch_6x 2016-12-14, DoubleDocValuesStats); 2016-12-17 (SortedDoubleDocValuesStats); 2026-05-19 (#15653, the executor path that disagrees))
- First affected version
- 6.4.0 [exec] (6.3.0 has no DocValuesStats [exec: compile error; lucene-misc-6.3.0.jar has no DocValuesStats classes]); the serial-versus-executor disagreement since 10.5.0 [exec] (10.4.0 has no DocValuesStatsCollectorManager [exec: compile error])
- Affected versions
- every release from 6.4.0 to 10.5.2, the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) and main a9779ef3c193. [exec] the follow-up's history probe (public-API main(): {+Inf, 1.0} and {+Inf, +Inf} with DoubleDocValuesStats, docs {+Inf},{1.0} with SortedDoubleDocValuesStats, plus controls) returns NaN, NaN, NaN on 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.2 and main (-ea and -da) while the controls are right, and returns +Infinity three times with the fix shadowed on main; the history step's manager JUnit fails 2 of 2 on 10.5.0, 10.5.2 and main; the finder's JUnit fails 2 of 2 on main (-ea and -da), branch_10_6 4ae946e5a9b and 10.5.2, and its collector-only form (repro/src-pre105) 1 of 1 on 10.4.0, 9.12.3 and 9.1.0; the independent reproduction's serial JUnit fails 6 of 7 on main (-ea and -da), 10.5.2 and 9.12.3 and its manager JUnit 1 of 1 on main (-ea and -da) and 10.5.2; the intended-behaviour check re-ran the finder's repro on main (-ea and -da), 10.5.2 and 9.12.3; all runs on JDK 25, also for releases that predate it. [read] the running-mean lines are present and unchanged at every release tag read; releases between the executed ones were not run one by one, and the 8.9-8.11 tags are not in the local history clone (8.11.4 was executed from release jars). 10.6.0 (released 2026-10-29) is affected: the doc's repro fails on its release jars with -ea and -da [exec]. Not fixed upstream: DocValuesStats.java was last changed by #15653 on main, branch_10x, branch_10_6, branch_9x and branch_9_12 (follow-up prior-report record, read 2026-10-28; upstream main re-checked 2026-10-28).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-28, follow-up prior-report record verdict new, 93 recorded queries: a scripted prior-report search 51 (16 GitHub issue/PR queries on apache/lucene, 3 commit, 2 downstream-repo, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 6 web) and 42 manual (GitHub issue, PR and commit searches over apache/lucene, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch and all of GitHub; the changed files of all 410 open apache/lucene PRs; the 22 issues and PRs created since 2026-10-26; #8641 with all 42 comments; #15653 with its 41 review comments; list threads read in full; git log -S over the full history); the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches found nothing either; refreshed 2026-10-28 for this row: GitHub PR search for DocValuesStats returns only #15653 and issue search only #2065, #10880 and #8641, none of the 15 PRs created since 2026-10-26 touches DocValuesStats, and the last commit on DocValuesStats.java on upstream main is still 0210af757c5 (#15653, author and commit date 2026-05-19)); not fixed upstream; related, not reports of this bug: #8641 / LUCENE-7590 (introduced the running update; the only numeric caveat discussed was sum overflow), #15653 (added the manager and merge(); its review never mentions non-finite values), #12342, #3347 / LUCENE-2271 and #15873 (NaN or infinity in other classes); gaps: the one-word GitHub queries (mean, variance) read only the first 50 results, the open-PR file check reads the first 100 files of each PR (full lists for the 4 larger PRs, the branch-removal PR #16911 capped by the API at 3000 files), and the web results were generic
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28): the one-method repro through gradle in a scratch worktree and through the standalone runner, assertions on and off, stock and with both fixes; the 10.6.0 release jars (assertions on and off). The hunt, the verifiers and the follow-up ran on maina9779ef3c193, which has the samelucene/miscsearch sources; the follow-up's history probe ran on 12 releases from 6.4.0 to 10.5.2. Upstream main on 2026-10-30 (716d6f216f52) has not changedDocValuesStats.javasince #15653.
- Finding record
lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStats.java:144-147 and :306-309 (mean(): 'The mean of all values of the field.'), :160-164 (sum(): the only numeric caveat, 'the sum might overflow'), :182-186 and :350-356 (merge(): combinedMean = (sum() + otherStats.sum()) / total), :255-267 (DoubleDocValuesStats.doAccumulate: sum += val; mean += (val - mean) / count), :436-452 (SortedDoubleDocValuesStats.doAccumulate: the same per value with ++valuesCount)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStats.java:63-70, :144-147, :175-185, :255-267, :306-309, :353-355, :433-452a Lucene main checkout (645d4fe14a20) lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStatsCollectorManager.java:58-68a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106-108, :218-231, :323-325, :357-378a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/SortedNumericDocValues.java:22
- Minimal repro
a Lucene main checkout (645d4fe14a20) lucene/test-framework/src/java/org/apache/lucene/tests/util/SetupAndRestoreStaticEnv.java:214, :230; lucene/core/src/java/org/apache/lucene/index/LiveIndexWriterConfig.java:138
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStats.java:144-147, :160-163, :185, :306-309, :327-330a Lucene main checkout (645d4fe14a20) lucene/misc/src/test/org/apache/lucene/misc/search/TestDocValuesStatsCollector.java:159-211, :318-322a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/document/DoubleDocValuesField.java:38-40a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/TestDocValuesQueries.java:1021-1048a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:742-750
- TestDocValuesStatsInfiniteMean.java (lucene/misc, one test):
repro/LFV-879/src/org/apache/lucene/misc/search/TestDocValuesStatsInfiniteMean.java(52 lines)
It is made in parallel with this doc; every on-screen value comes from the code at 645d4fe14a20 or the diagram's executed probe. Its fix panel shows the finder's sketch (guard on the value and the mean, the second option above); the recommended fix guards on the mean only, and both were run.
assets/LFV-879/bug.png(557 KB)