With an executor, IndexSearcher searches groups of segments (slices) in parallel, and the manager merges one stats object per slice. The merge rebuilds the mean from the slices' long sums, which wrap silently past Long.MAX_VALUE, instead of using the slices' own means, which are right.
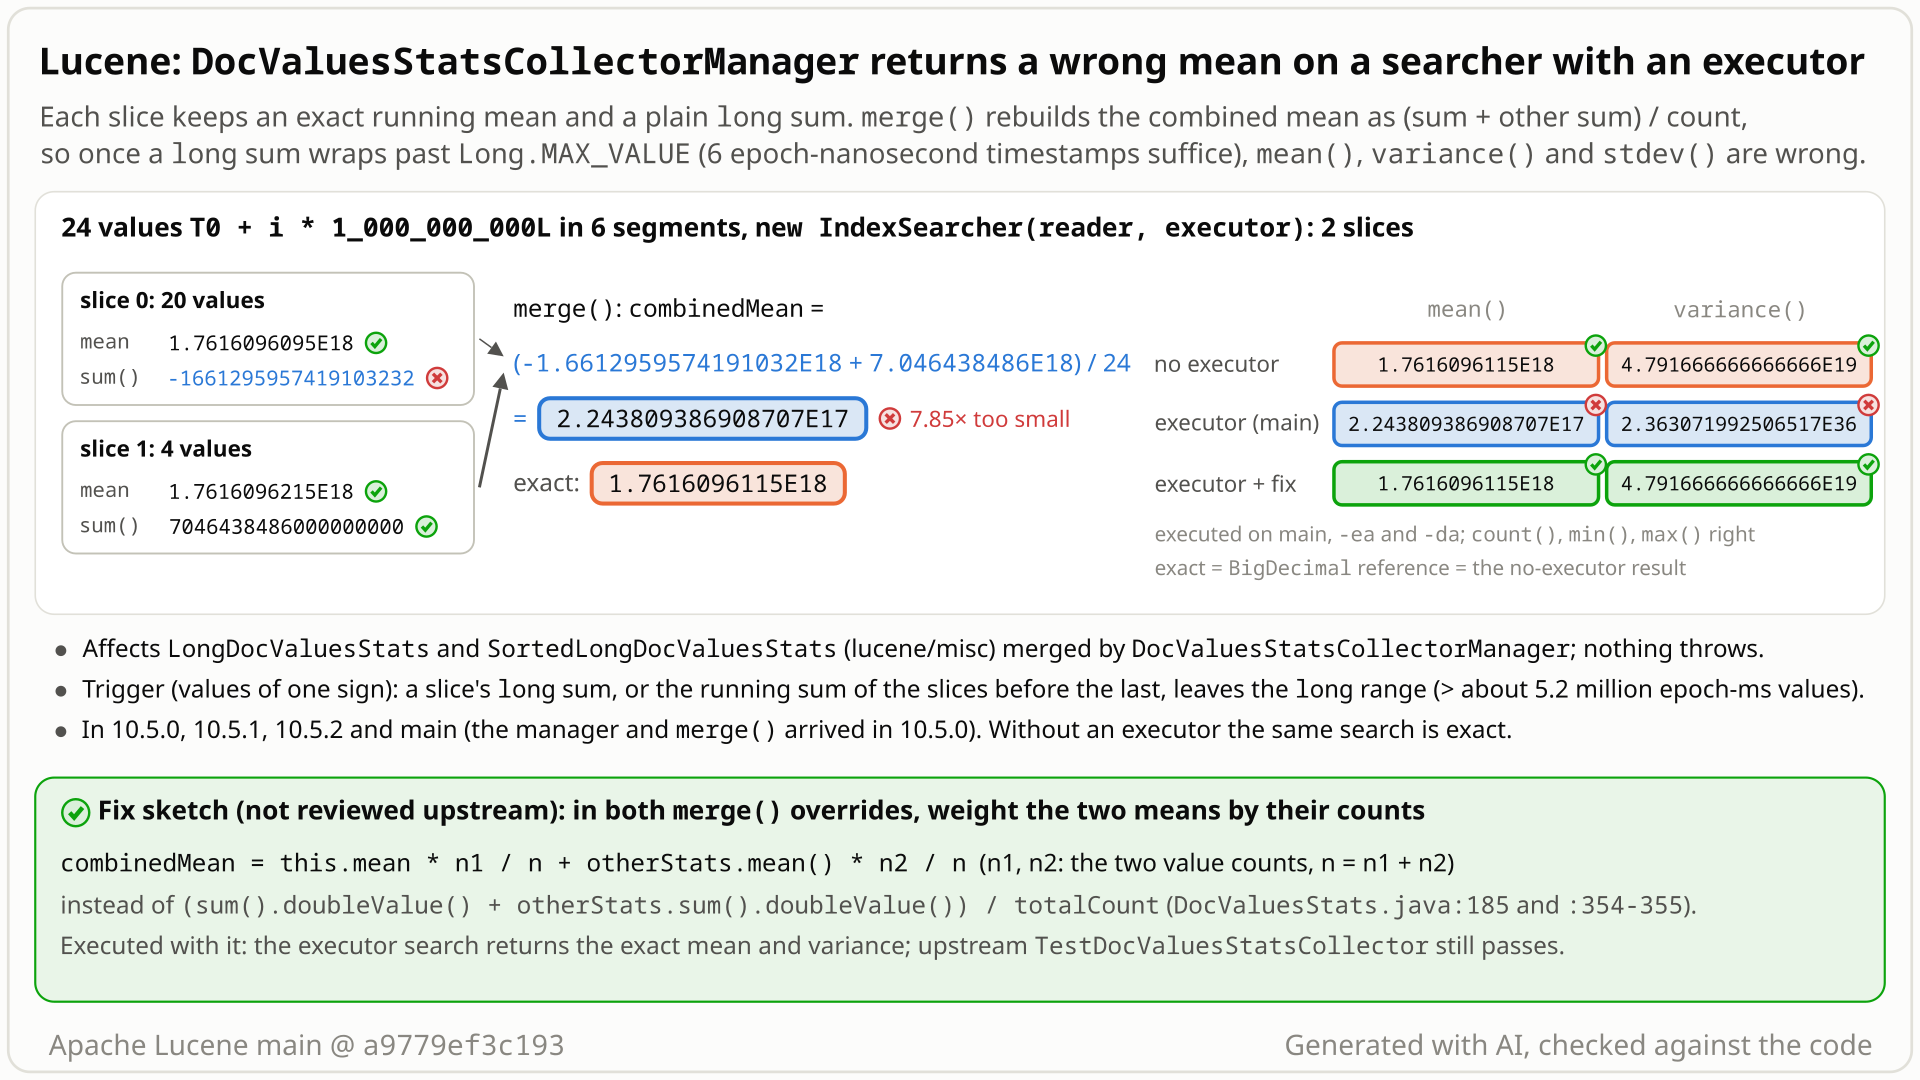
merge() divides the wrapped long sums and returns 2.24E17 instead of 1.76E18; without an executor the mean is exact. Select the still to open it at full size. Generated with AI, checked against the code.- You index 24 epoch-nanosecond timestamps (about 1.76e18 each, one per second) in 6 segments and compute
LongDocValuesStatswithDocValuesStatsCollectorManager, as its javadoc shows, onnew IndexSearcher(reader, executor). - You expect
mean()= 1.7616096115E18, the value the same search returns onnew IndexSearcher(reader). - The executor splits the 6 segments into 2 slices of 20 and 4 values. Each slice's running mean is right, but its
longsum is not: the 20 values add up to 3.52e19, pastLong.MAX_VALUE(9.22e18), and the sum wraps to -1.66e18. merge()ignores the slices' means and computes (sum + other sum) / count = (-1.66e18 + 7.05e18) / 24 = 2.243809386908707E17, about 8x too small.variance()is 2.36E36 instead of 4.79E19. No error;count(),min()andmax()are right.- The result depends on the slicing: 4 one-segment slices of 6 values give -5.44E17, and a single slice gives the exact mean.
Applications on 10.5.0 or later that compute LongDocValuesStats or SortedLongDocValuesStats through DocValuesStatsCollectorManager on a searcher with an executor, over large long values: epoch-nanosecond timestamps overflow at the 6th value, epoch-millisecond ones only beyond about 5.2 million values. Values below about 4.29e9 in magnitude cannot, on a single-valued field. The wrong statistics are silent.
Mechanism, terms and numbers666 words
DocValuesStatsCollectorManager (lucene/misc, new in 10.5.0) computes LongDocValuesStats or SortedLongDocValuesStats once per slice and merges the slices with DocValuesStats.merge(). The merge rebuilds the mean as (sum() + other.sum()) / n, with n the combined number of values, and for the long classes sum() is a plain long that wraps silently past Long.MAX_VALUE, as its javadoc warns. With large but ordinary values the merged mean is wrong once a sum it reads has wrapped: 24 epoch-nanosecond timestamps in 6 segments give mean() = 2.243809386908707E17 instead of 1.7616096115E18, and another slicing of the same values gives -5.44E17. variance() and stdev() are wrong too. A searcher without an executor returns the exact mean, because serial collection keeps a running mean that never reads the sum. count(), missing(), min() and max() stay right and nothing throws. Affected: 10.5.0, 10.5.1, 10.5.2, 10.6.0 (branch_10_6 4ae946e5a9b9) and main; 10.4.0 and older have no manager and no merge().
- Slice: a group of segments that one thread searches. Without an executor a searcher has one slice (
IndexSearcher.java:226-231); with one,slices()sorts the segments by size and closes a slice once it has 5 segments or more than 250,000 documents, and a segment of more than 250,000 documents gets a slice of its own (:106-108,:323-324,:341-390). A slice of small segments can so hold up to about 500,000 documents. - Collector manager: creates one collector per slice, then reduces them into one result.
DocValuesStatsCollectorManager.reducestarts from a fresh stats object and callsmerge()once per collector (DocValuesStatsCollectorManager.java:60-68).
- Collecting a value (
DocValuesStats.java:217-229) adds it toprivate long sum(sum += val,:225) and updates a running mean,mean += (val - mean) / count, and a running sum of squared deviations (:226-228). The running mean never reads the sum, so each slice's mean is right. NumericDocValuesStats.mergecomputes the combined mean from the sums (:184-185):double combinedMean = (sum().doubleValue() + otherStats.sum().doubleValue()) / totalCount;ForLongDocValuesStatsthe sum is alongthat has wrapped.SortedNumericDocValuesStats.mergedoes the same overvaluesCount(:353-355).- The pooled variance (
:186-193) adds(mean - combinedMean)^2 * countfor both sides, so a wrong combined mean also makesvariance()andstdev()wrong. LongDocValuesStats.mergethen adds the sums aslongs (:237-240), so the merged sum keeps wrapping. One slice is always exact: the first merge only copies it (:175-181). With 2 or more non-empty slices and values of one sign, the final mean is wrong exactly when the last slice's sum, or the running sum of the slices merged before it, leaves the long range: in the 6-slice row below no slice overflows, the running sum does. With mixed signs the wraps can cancel (slices[MAX, MAX]and[MIN, MIN]give the exact mean -0.5), and a merge that read a wrapped sum can leave a wrong variance under a right final mean.
24 documents, ts = 1,761,609,600,000,000,000 + i * 1,000,000,000 for i = 0..23 (2025-10-28T00:00:00Z plus one second per document). The true sum is 42,278,630,676,000,000,000, about 4.6 times Long.MAX_VALUE. Exact mean 1.7616096115E18, variance 4.79E19, stdev 6.92E9 (6.9 seconds).
| segments | searcher | slices | mean() | variance() |
|---|---|---|---|---|
| 6 x 4 | new IndexSearcher(reader) | 1 | 1.7616096115E18 | 4.79E19 |
| 6 x 4 | new IndexSearcher(reader, executor) | 2 (20 + 4 values) | 2.243809386908707E17 | 2.36E36 |
| 6 x 4 | one segment per slice | 6 (4 values each) | 2.243809386908707E17 | 2.84E36 |
| 4 x 6 | new IndexSearcher(reader, executor) | 1 | 1.7616096115E18 | 4.79E19 |
| 4 x 6 | one segment per slice | 4 (6 values each) | -5.4423339771369395E17 | 7.68E36 |
In every row count() is 24, min() and max() are right, and sum() is 5385142528580896768 (the true sum modulo 2^64; its javadoc says it "might overflow"). In the 2-slice row the 20-value slice's sum, 35,232,192,190,000,000,000, wraps twice to -1,661,295,957,419,103,232; the 4-value slice's sum, 7,046,438,486,000,000,000, fits; (-1.661e18 + 7.046e18) / 24 = 2.2438e17. SortedLongDocValuesStats on a LongField gives the same 2.243809386908707E17 with the default slicing.
Exposure and likelihood397 words
- Who is hit. Users of the lucene/misc statistics through
DocValuesStatsCollectorManageron anIndexSearcherbuilt with an executor, in 10.5.0 or later. The manager is the usage the class javadoc shows (DocValuesStatsCollectorManager.java:27-34), andIndexSearcher.search(Query, Collector), the only route before 10.5.0, is deprecated in favour ofsearch(Query, CollectorManager)(IndexSearcher.java:634-638). The route is opt-in:CollectorManager,search(Query, CollectorManager)and the executor constructors are@lucene.experimental(CollectorManager.java:42;IndexSearcher.java:199,:216,:748), and the stats classes live in lucene/misc. The defaultIndexWriterConfig, codec and slicing suffice; the repro setsNoMergePolicyonly to fix the segment count. - The trigger (values of one sign; mixed signs can cancel). The reduce merges 2 or more slices that have values, and one slice's long sum, or the running long sum of the slices merged before the last one, leaves the long range.
- Epoch-nanosecond timestamps (about 1.76e18): the 6th value overflows; 5 x 1.76e18 = 8.8e18 still fits.
- Epoch-millisecond timestamps (about 1.76e12): a slice of small segments (at most about 500,000 documents) cannot overflow its own sum; a single segment of more than about 5.24 million values, which gets a slice of its own, can; and the running sum overflows once the slices merged before the last one hold more than about 5.24 million values (9.22e18 / 1.76e12), for example 21 slices of 250,000 values.
- Small values cannot trigger it on a single-valued field: an index holds at most
IndexWriter.MAX_DOCS= 2,147,483,519 documents (IndexWriter.java:208), and that many values of magnitude at most 4,294,967,554 (Long.MAX_VALUE / MAX_DOCS) fit in a long. Typical prices or counts are far below that.
- What goes wrong.
mean(),variance()andstdev()are silently wrong, far too small or negative depending on the slicing.count(),missing(),min()andmax()are right; the index and the matched documents are unaffected. - Hard to notice. The same query gives the exact mean without an executor, and also with one when everything fits in one slice. Tests with small values or small indexes pass.
- Not part of this bug.
DoubleDocValuesStatsuses the same formula, so two values nearDouble.MAX_VALUEin two partitions giveInfinity(the logged example splits one segment into two slices); extreme. The fix removes that overflow but changes other non-finite double results (see the fixes).SortedNumericDocValuesStats.variance()divides by documents, not values (DocValuesStats.java:312-315), which the upstream test pins.
The test shows that DocValuesStatsCollectorManager with LongDocValuesStats on an IndexSearcher with an executor returns a wrong mean() once a slice's long sum wraps (6 one-doc segments of the value 2e18, default slicing 5 + 1).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.misc.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.misc.search.DocValuesStats.LongDocValuesStats;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDocValuesStatsMergedMean extends LuceneTestCase {

  public void testMeanWithExecutor() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
        for (int i = 0; i < 6; i++) {
          Document doc = new Document();
          doc.add(new NumericDocValuesField("f", 2_000_000_000_000_000_000L));
          w.addDocument(doc);
          w.flush();
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        // 6 one-doc segments; with an executor the default slicing gives slices of 5 and 1
        LongDocValuesStats serial =
            new IndexSearcher(reader)
                .search(
                    MatchAllDocsQuery.INSTANCE,
                    new DocValuesStatsCollectorManager<>(() -> new LongDocValuesStats("f")));
        LongDocValuesStats withExecutor =
            new IndexSearcher(reader, Runnable::run)
                .search(
                    MatchAllDocsQuery.INSTANCE,
                    new DocValuesStatsCollectorManager<>(() -> new LongDocValuesStats("f")));
        assertEquals(serial.mean(), withExecutor.mean(), 1e-9 * serial.mean());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-882/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/misc/build/libs/lucene-misc-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.misc.search.TestDocValuesStatsMergedMean
- Expected vs actual
- Expected the executor mean to equal the serial mean
2.0E18; actual:-1.0744573456182586E18, with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<2.0E18> but was:<-1.0744573456182586E18>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:555)
       org.junit.Assert.assertEquals(Assert.java:685)
org.apache.lucene.misc.search.TestDocValuesStatsMergedMean.testMeanWithExecutor(TestDocValuesStatsMergedMean.java:57)merge()promises statistics "as if they had been collected together";mean()has no overflow caveat, onlysum()does.- The same index and query give 1.76E18, 2.24E17 or -5.44E17 depending on the executor and slicing; serial collection is exact.
- The upstream tests use small values (at most about 500); the review of the change adding
merge()never discussed overflow.
The full argument255 words
- The contract.
merge(): "After the call, this instance reflects the combined statistics of both segments as if they had been collected together." (DocValuesStats.java:76-83).mean(): "The mean of all values of the field." (:144-147,:306-309), with no caveat. Onlysum()warns: "Note that if the values are large, thesummight overflow." (:160-164,:327-331). - History. The wrapping long sum and its caveat date from LUCENE-7590 (
295cab7216c, 2016-12-15), next to a running mean that never used it (ad7152ad473, 2016-12-11). In that issue (#8641) the author asked "Should we care about overflow, or only document it?" about the sum; there was no merge then. #15653 (0210af757c54, 10.5.0) addedmerge()with the sum-based mean, the first code that makesmean()depend on the sum. Its review (41 inline comments) discusses generics, visibility, adoubleValue()precision issue in the min/max comparison and thesum()accessor, never an overflowing sum in the mean. - Tests.
TestDocValuesStatsCollectorruns the manager onnewSearcher(which may add an executor) with small sequential long values: 1 to at most 100 intestDocsWithLongValues(TestDocValuesStatsCollector.java:105-118,:134-138), and 1 to at most about 500 (up to 100 documents with 1-5 values each) intestDocsWithMultipleLongValues(:213-228,:246-250). Neither can reach an overflow. - Execution-dependent results. The same index and query give 1.76E18, 2.24E17 or -5.44E17 depending on whether the searcher has an executor and how segments fall into slices.
merge()promises collection-equivalent statistics, and the serial path is exact.
The devil's-advocate check258 words
The strongest case for "intended": sum() documents that it may overflow, and java.util.LongSummaryStatistics.getAverage(), which the upstream tests use as their mean oracle (TestDocValuesStatsCollector.java:145-148, :256-260), is (double) getSum() / getCount() with an unchecked long sum ("This implementation does not check for overflow of the count or the sum"). For the repro data getAverage() is exactly 2.243809386908707E17, the concurrent result. Read that way, a wrapping sum-based mean is the JDK's own semantics. A maintainer could add that the concurrent route is @lucene.experimental and lives in lucene/misc, that a double near 1.76e18 is only accurate to 256, and that the deprecated single-collector route still gives the exact mean.
Why it fails: Lucene's mean has never had those semantics. Serial collection, the only route before 10.5.0 and still the route without an executor, returns the exact mean for the same data, and mean() has no overflow caveat. The concurrent result is not even the JDK value in general: it changes with the slicing (-5.44E17 for 4 slices of 6, exact for 1 slice). The tests' oracle is a convenience for values of at most about 500 and asserts nothing about overflow, and merge() promises statistics "as if they had been collected together". An error of about 1.5e18, or a negative mean of positive timestamps, is not rounding, and the experimental tag warns that the API "might change in incompatible ways in the next release", not that results may be wrong. The argument supports a low priority or better documentation, not the current result. Verdict: not intended, a defect.
Recommended Combine the count-weighted per-slice means (for the long classes)
In both merge() overrides, combine the two slices' running means weighted by their counts instead of dividing the summed long sums (+7/-2 in DocValuesStats.java). Validated: the repro passes, TestDocValuesStatsCollector passes 160 of 160 over 20 iterations, the whole misc module passes (317 tests), and lint is clean.
int totalCount = this.count() + otherStats.count();
// weight the two means instead of dividing the summed sums: a long sum may have overflowed
double combinedMean =
    this.mean * ((double) this.count() / totalCount)
        + otherStats.mean() * ((double) otherStats.count() / totalCount);
// SortedNumericDocValuesStats.merge: the same with valuesCount
All options and trade-offs4 options · 729 words
One fix was built and validated with gradle; the alternatives are sketches. sum() and its documented overflow stay as they are in every option except C.
Combine the count-weighted per-slice means (for the long classes) (validated by the checks) (recommended)
In NumericDocValuesStats.merge and SortedNumericDocValuesStats.merge, compute combinedMean = mean1 * (n1 / n) + mean2 * (n2 / n) from the running means, which do not depend on the wrapped sum and are accurate to double precision (not exact), instead of (sum1 + sum2) / n. The pooled variance formula is unchanged and becomes right with the right mean. Land it with a decision on the double side effect (trade-offs).
int totalCount = this.count() + otherStats.count();
// weight the two means instead of dividing the summed sums: a long sum may have overflowed
double combinedMean =
    this.mean * ((double) this.count() / totalCount)
        + otherStats.mean() * ((double) otherStats.count() / totalCount);
// SortedNumericDocValuesStats.merge: the same with valuesCount
Trade-offs
- Precision. The merged mean is as accurate as the per-slice running means, about the serial path's precision, not exact: the 4-slice probe prints 1.7616096114999997E18, and for the extreme slices
[MAX, MAX]and[MIN, MIN]the fix gives 0.0 where the exact (and stock) mean is -0.5, because both slice means round to ±2^63. The merged variance agrees with the exact one to about 2.5e-8 relative in the 6-slice probe (4.7916667861E19 vs 4.7916666667E19), from rounding of means near 1.76e18. - Double classes. They share
NumericDocValuesStats.merge. The weighted form keeps an infinite partial mean infinite and removes theDouble.MAX_VALUEoverflow of the summed sums. But it passes on each slice's running mean, and the double running mean has a separate bug: it becomesNaNwhen a value follows an infinite one, which the summed sums hid in some slicings. In the bounded-exhaustive double run the multi-slice mean mismatches go from 23,850 to 53,914 with this fix (its logged examples are "got NaN want Infinity"); the serial ones stay 39,734. Nor does the fix make the concurrent double mean equal the serial one: one segment[+Infinity, 0.0]givesNaNserially, two slices[+Infinity]and[0.0]giveInfinity, with and without the fix. Treat this as a condition for landing: fix that running mean in the same change, or say in the PR that non-finite double results change and that the running-mean bug is separate. - Cost and compatibility. Two multiplications and one more division instead of two
doubleValue()calls per merge; no API or state change.
What the checks validated
- Gradle, lucene/misc only, scratch worktree of
a9779ef3c193, seedDEADBEEF: the repro passes 2 of 2 with-Ptests.asserts=trueand=false(stock: 2 of 2 fail);TestDocValuesStatsCollectorpasses 160 of 160 with-Ptests.iters=20(stock: 8 of 8); the whole:lucene:misc:testhas 24 classes, 317 tests, 0 failures, 9 skipped;tidymakes no change;ecjLintMain,ecjLintTest,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestpass. - Classpath runner: the independent 4-test file passes 4 of 4 (
-da); the probe prints the exact mean for 2, 4 and 6 slices. - Bounded-exhaustive runs: 0 mismatches for the long classes (56,162 and 102,639 without the fix), over every index of 1-3 segments with 1-2 documents each (at most 4 documents, 3 for the sorted class), values from fixed sets with
Long.MIN_VALUEandLong.MAX_VALUE, every partition of the segments into slices and one intra-segment split.
The same idea in the form Chan et al. use for pooled statistics; it may round a little less when the two means are close (not measured here).
Trade-offs
Not validated here. For the double classes an infinite this.mean, or two equal infinite means, gives NaN (inf - inf), while a finite this.mean with an infinite other mean stays infinite, so NumericDocValuesStats.merge needs a guard.
Track the sum without wrapping, as two longs or a BigInteger once it overflows, and keep the sum-based mean.
Trade-offs
Also fixes sum(), but changes the state and cost of every stats object, and sum()'s overflow is documented behaviour, not this bug. Not validated.
Extend the sum() caveat to mean(), variance() and stdev().
Trade-offs
Not recommended: the values are wrong by orders of magnitude, depend on the slicing, and the serial path is exact.
Downstream, this matters where a product acts on these statistics, such as dashboards, quotas or anomaly detection; the matched documents and count(), min() and max() are unaffected.
Bounded-exhaustive testing ran all six DocValuesStats classes through DocValuesStatsCollectorManager on the stock jar over every index of 1-3 segments with 1-2 documents, special values and every slicing, against an exact reference. Every long-class mismatch was a multi-slice mean or variance; a public-API JUnit then reproduced it.
The method in full160 words
Method: bounded-exhaustive translation validation (the semi-formal tier). A hunt unit sweeping public APIs that no earlier study had named (facet, join, grouping, misc) ran a harness against the stock main jar.
- A planning probe first saw an epoch-nanosecond mean of -5.44e17 instead of 1.76e18 on a searcher with an executor.
- The harness then ran all six
DocValuesStatsclasses throughDocValuesStatsCollectorManageragainst an exactBigDecimalreference, over every index of 1-3 segments with 1-2 documents each (also with a deleted document) and every value choice from alphabets withLong.MIN_VALUE,Long.MAX_VALUEand an epoch-nanosecond timestamp: no executor, every set partition of the segments into slices, and an intra-segment split. - Long class: 43,720 indexes and 249,424 checks, 56,162 mismatches. Sorted long class: 47,649 indexes and 207,753 checks, 102,639 mismatches. All are mean or variance under a multi-slice reduce; none is serial or one-slice; none remains with the fix.
- It was then reduced to a public-API JUnit with the default
IndexSearcher(reader, executor)slicing.
No prior report found (2026-10-28): 88 recorded queries over GitHub issues, PRs and commits, the mailing lists, JIRA, downstream trackers and the web, refreshed the same day. The closest items are #15653, which added merge() and whose review never discussed overflow, and #8641, which documented the sum() overflow in 2016.
Searches4 searches
Verdict: new; not fixed upstream. The searched public sources hold no report, discussion or fix of this.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs, commits; downstream trackers; dev@, java-user@, issues@, commits@; JIRA archive | 2026-10-28 | scripted prior-report search, 49 queries | no report; #15653 and #8641 as related items |
| GitHub, manual | 2026-10-28 | 28 reads and searches: file scans of all open PRs and of the 650 closed PRs updated since 2026-05-03; #15653 with its 41 inline review comments; #8641 with its 42 comments | no report; #16847 (open draft) is the only open PR touching a DocValuesStats file, test only |
| JIRA REST, list archives, full git history, web | 2026-10-28 | 2 JIRA queries (LUCENE, SOLR), 2 list-archive reads, git log -S combinedMean and --grep DocValuesStats, 5 web queries | no report |
| Refresh | 2026-10-28 | PR search for DocValuesStats; issue search for overflow; PRs created since 2026-10-26; last commit on the two files | only #15653; last upstream commit on DocValuesStats.java is still 0210af757c54 |
Introduced in 10.5.0 by #15653 (0210af757c54, merged 2026-05-19), which added the manager and merge(). Fails on 10.5.0, 10.5.1, 10.5.2, 10.6.0 (branch_10_6 4ae946e5a9b9) and main; 10.4.0 and older have no manager, and their single-collector route is exact. Not fixed upstream.
Versions tested5 rows
Introduced by #15653 "Introduce DocValuesStatsCollectorManager" (@gaobinlong, co-authored by @javanna), merged 2026-05-19 as 0210af757c54 on main and 1833c658f063 on branch_10x (CHANGES entry under 10.5.0). git blame attributes the combinedMean lines, the variance merge and the long sum += other.sum() to it; the sum-based formula was in the PR's first commit (2026-02-02). The wrapping long sum is older (LUCENE-7590, 2016), but before #15653 mean() never read it, and there was no way to merge two stats objects.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the repro fails 2 of 2 (gradle and classpath runner, -ea and -da); the fix passes |
branch_10_6 4ae946e5a9b9 | affected | fails 2 of 2, same values |
| 10.5.0, 10.5.1, 10.5.2 | affected | fail 2 of 2, mean 2.243809386908707E17 on each |
| 10.4.0, 9.12.3 | no manager | the repro does not compile; one DocValuesStatsCollector on an executor searcher gives the exact mean and variance, with sum() wrapped |
upstream main c5ab3e57b9ba | source only | the same code; not executed |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication reproduced it with their own runs; reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; a credibility audit re-ran it; this doc's gradle runs reproduce it and validate the fix.
Checks and verdicts259 words
Every verdict below rests on executed runs except the cross-model reviews, which could only read code; separate runs re-ran the repro (2 of 2 failed).
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own 4-test JUnit outside the package fails 3 of 4 on main (-ea, -da), 10.5.0 and 10.5.2, and 30 of 40 over 10 iterations; found the running-reduce trigger (3 slices of 4 values, no slice overflows); its own fix passes. |
| Cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (low), procedural | Could not execute anything; root cause agreed, inputs in contract, intended-behaviour argument weak; no substantive refutation. |
| Cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Intended-behaviour argument weak; root cause agreed from reading; could not run anything; a separate run re-ran the repro (2 of 2 fail). |
| Intended-behaviour devil's advocate | real (high) | Built the LongSummaryStatistics case and rejected it because the result depends on the slicing; re-ran the repro on main and 10.5.2. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test on main with -ea and -da (3 of 4 fail each); severity Medium. |
| Registration check and credibility audit | keep | Re-ran the repro with a fresh seed (A0D17004, -da; the registration check's re-runs used DEADBEEF and D0551E03-05); same failures; refreshed the prior-art search. |
| This doc | reproduced, fix validated | Gradle in a clean scratch worktree: the repro fails 2 of 2 stock and passes with the fix; misc module 317 tests pass with the fix; lint clean. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 484 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,378 words
- Registry title
- DocValuesStatsCollectorManager merges LongDocValuesStats and SortedLongDocValuesStats (lucene/misc) through their wrapping long sum(), so on a searcher with an executor mean(), variance() and stdev() are silently wrong (for example about 8x too small, or negative) once a slice's long sum or the reduce's running long sum passes Long.MAX_VALUE, as 6 epoch-nanosecond timestamps do, while the same search without an executor is exact
- Area
- misc / DocValuesStats long statistics (DocValuesStatsCollectorManager concurrent reduce)
- Priority
- Low, rank 337: Needs the opt-in misc DocValuesStats route on a searcher with an executor.
- Impact class
- silent wrong results
- Impact note
- Applications that summarize a long or sorted-numeric long doc-values field with the lucene/misc LongDocValuesStats or SortedLongDocValuesStats through DocValuesStatsCollectorManager (10.5.0 and later) on an IndexSearcher with an executor get a wrong mean(), variance() and stdev() whenever the reduce merges 2 or more non-empty collectors and the long sum of one slice, or the running long sum of the slices merged before the last one, leaves the long range: 6 or more epoch-nanosecond timestamps (about 1.76e18 each), or more than about 5.2 million epoch-millisecond timestamps; the default IndexWriterConfig, codec and executor slicing suffice (the repro uses 24 documents in 6 segments); count(), missing(), min() and max() stay right, nothing throws, the index is untouched, and a searcher without an executor returns the exact mean for the same index.
- Summary
- You index ordinary large long values, for example 24 epoch-nanosecond timestamps in 6 segments, compute LongDocValuesStats (or SortedLongDocValuesStats) with DocValuesStatsCollectorManager exactly as its class javadoc shows on new IndexSearcher(reader, executor), and expect mean() = 1.7616096115E18, 'the mean of all values of the field' and the value the same search without an executor returns, because merge() promises 'the combined statistics of both segments as if they had been collected together'. Instead mean() is 2.243809386908707E17 (about 8x too small; other slicings give a negative mean) and variance() and stdev() are wrong too, because merge() recomputes the combined mean as (sum + otherSum) / count from long sums that have wrapped past Long.MAX_VALUE, while serial collection keeps a running mean that never reads the sum. Only sum() is documented as possibly overflowing; count(), min() and max() stay right.
- Introduced
- 0210af757c54 (main, 'Introduce DocValuesStatsCollectorManager (#15653)', by gaobinlong, co-authored by javanna; backport 1833c658f063 on branch_10x): it added DocValuesStatsCollectorManager and merge() with combinedMean = (sum().doubleValue() + otherStats.sum().doubleValue()) / n, a formula already in the PR's first commit 88f84b033918 (2026-02-02); the wrapping long sum is older (LUCENE-7590, 295cab7216c, 2016-12-15, documented 'might overflow') but before #15653 mean() and variance() came only from the running update and never read it [read: git blame in the history clone attributes the merge lines DocValuesStats.java:184-195, :353-366, :236-240 and :414-418 to 0210af757c54; exec: the repro fails on 10.5.0 and does not compile on 10.4.0] (2026-05-19 (author and commit date of 0210af757c54 and of the backport 1833c658f063; PR #15653 opened 2026-02-02))
- First affected version
- 10.5.0 [exec] (10.4.0 and older have no DocValuesStatsCollectorManager and no merge() [exec: the repro does not compile on 10.4.0 and 9.12.3]; their only route, one DocValuesStatsCollector, gives the exact mean [exec control on 9.12.3 and 10.4.0])
- Affected versions
- 10.5.0, 10.5.1 and 10.5.2, the branch_10_6 head 4ae946e5a9b9 (10.6.0, released 2026-10-29) and main a9779ef3c193. [exec] the finder's JUnit fails 2 of 2 on 10.5.0, 10.5.1, 10.5.2 (-ea and -da), branch_10_6 and main (-ea and -da); the independent reproduction's JUnit fails 3 of 4 on 10.5.0, 10.5.2 and main (-ea and -da); the intended-behaviour check re-ran the finder's repro on main (-ea and -da) and 10.5.2 (-da); all runs on JDK 25. Not affected: 10.4.0, every earlier 10.x and all 9.x (no merge() and no manager: the repro does not compile on 10.4.0 and 9.12.3, and a control that passes one DocValuesStatsCollector to an executor searcher passes 2 of 2 on 9.12.3, 10.4.0 and 10.5.2, with sum() wrapped and mean() and variance() exact). [read] Not fixed upstream: DocValuesStats.java and DocValuesStatsCollectorManager.java were last changed by #15653 on main (origin/main c5ab3e57b9ba, re-checked 2026-10-28), branch_10x, branch_10_6 and branch_10_5.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-28, follow-up prior-report record verdict new, 88 recorded queries: a scripted prior-report search 49 (20 GitHub issue/PR queries on apache/lucene, 3 commit, 2 downstream-repo, 20 mailing-list, 4 JIRA-archive) and 39 manual (28 GitHub API reads and searches, including file scans of all open apache/lucene PRs and of the 650 closed PRs updated since 2026-05-03, #15653 with its 41 inline review comments and #8641 with its 42 comments; 2 JIRA REST queries on LUCENE and SOLR; 2 list-archive reads; 2 git log runs over the full history; 5 web queries); the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches found nothing either; refreshed 2026-10-28 for this row: GitHub issue and PR search for DocValuesStats returns only #15653, #10880, #8641 and #2065, none of the 15 PRs and 7 issues created since 2026-10-26 is about DocValuesStats, and the last commit on DocValuesStats.java and DocValuesStatsCollectorManager.java on upstream main c5ab3e57b9ba is still 0210af757c54 (#15653, author date 2026-05-19)); not fixed upstream; related, not reports of this bug: #15653 (introduced merge(); its review discusses generics, visibility, the precision of a doubleValue() min/max comparison and sum() casts, never the long sum overflowing into the mean), #8641 / LUCENE-7590 (asked 'Should we care about overflow, or only document it?' about sum, which led to the sum() caveat, when mean() was a running mean and there was no merge), #12892 (the umbrella issue of #15653), #16847 (the only open PR touching a DocValuesStats file, test only), #240, #2065 and #10880; gaps: one GitHub search burst hit the shared rate limit and was re-run after the reset, one-word queries read only the first result pages, open-PR scans read the first 100 files of each PR (full lists for the 4 larger ones), closed unmerged PRs not updated since 2026-05-03 were not file-scanned (the code did not exist before 2026-05-19 except in #15653), the web results were generic, and private security reports cannot be searched
- Lucene commit tested
- main
a9779ef3c193(gradle in a clean scratch worktree, and the hunt's classpath runner with-eaand-da); through the classpath runner also 10.5.2 and 10.5.0 (10.4.0: compile error, no manager). The hunt's runs add 10.5.1,branch_10_64ae946e5a9b9, and a single-collector control on 9.12.3, 10.4.0 and 10.5.2. Upstream mainc5ab3e57b9bahas the same code (read only).
- Finding record
lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStats.java:76-83 (merge() javadoc: 'as if they had been collected together'), :144-147 and :306-309 (mean(): 'The mean of all values of the field.'), :160-164 and :327-331 (sum(): 'if the values are large, the sum might overflow'), :184-194 and :353-365 (combinedMean from sum().doubleValue(); pooled variance from it), :210, :225, :239, :381, :398, :417 (long sum += val and sum += other.sum()), :226-228 and :399-405 (serial running mean, independent of the sum), :314 (sorted variance divides by documents)lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStatsCollectorManager.java:24-34 (class javadoc usage with LongDocValuesStats) and :60-68 (reduce merges every collector into a fresh stats object)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106-108 and :323-324 (default executor slicing: at most 5 segments and 250,000 documents per slice), :633-638 (search(Query, Collector) deprecated in favour of the CollectorManager path)lucene/misc/src/test/org/apache/lucene/misc/search/TestDocValuesStatsCollector.java:111-118 and :145-148 (long values 1..100; LongSummaryStatistics.getAverage() as the mean oracle)
- The finding in 30 seconds
lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStats.java:184-193, 217-229, 237-240, 353-365 @ a9779ef3c193lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStatsCollectorManager.java:60-68lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106-108, 226-231, 323-324, 341-390
- Who is affected
lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStatsCollectorManager.java:24-34; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:634-638lucene/core/src/java/org/apache/lucene/search/CollectorManager.java:42; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:199, 216, 341-390, 748; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:208 (MAX_DOCS)
- Why it looks unintended
lucene/misc/src/java/org/apache/lucene/misc/search/DocValuesStats.java:76-83, 144-147, 160-164, 306-309, 327-331lucene/misc/src/test/org/apache/lucene/misc/search/TestDocValuesStatsCollector.java:105-118, 134-138, 145-148, 213-228, 246-250, 256-260build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:502 (the lucene.experimental tag text)
- History
a Lucene clone: git tag --contains 1833c658f063 (10.5.0, 10.5.1, 10.5.2)lucene/CHANGES.txt:881, 986
- TestDocValuesStatsMergedMean.java (JUnit test):
repro/LFV-882/src/org/apache/lucene/misc/search/TestDocValuesStatsMergedMean.java(61 lines)
Made in parallel with this doc from the same 24-timestamp example; the values on screen come from an executed probe on main a9779ef3c193.
assets/LFV-882/bug.png(484 KB)