HyphenationCompoundWordTokenFiltersplits compound words using a hyphenation grammar: an XML file of TeX-style patterns such as.an3k, where the letters are the key and the digits are hyphenation values. Lucene ships no grammars; its docs point to the OFFO project, and the TeX hyphenation project publishes the current pattern lists.- The patterns are stored in a
TernaryTree: one node per character, in arrays that start with 2,048 slots and grow by 2,048. A key's unshared rest is kept as one "compressed tail" node; inserting a key that shares letters with a tail splits it, one new node per shared letter.
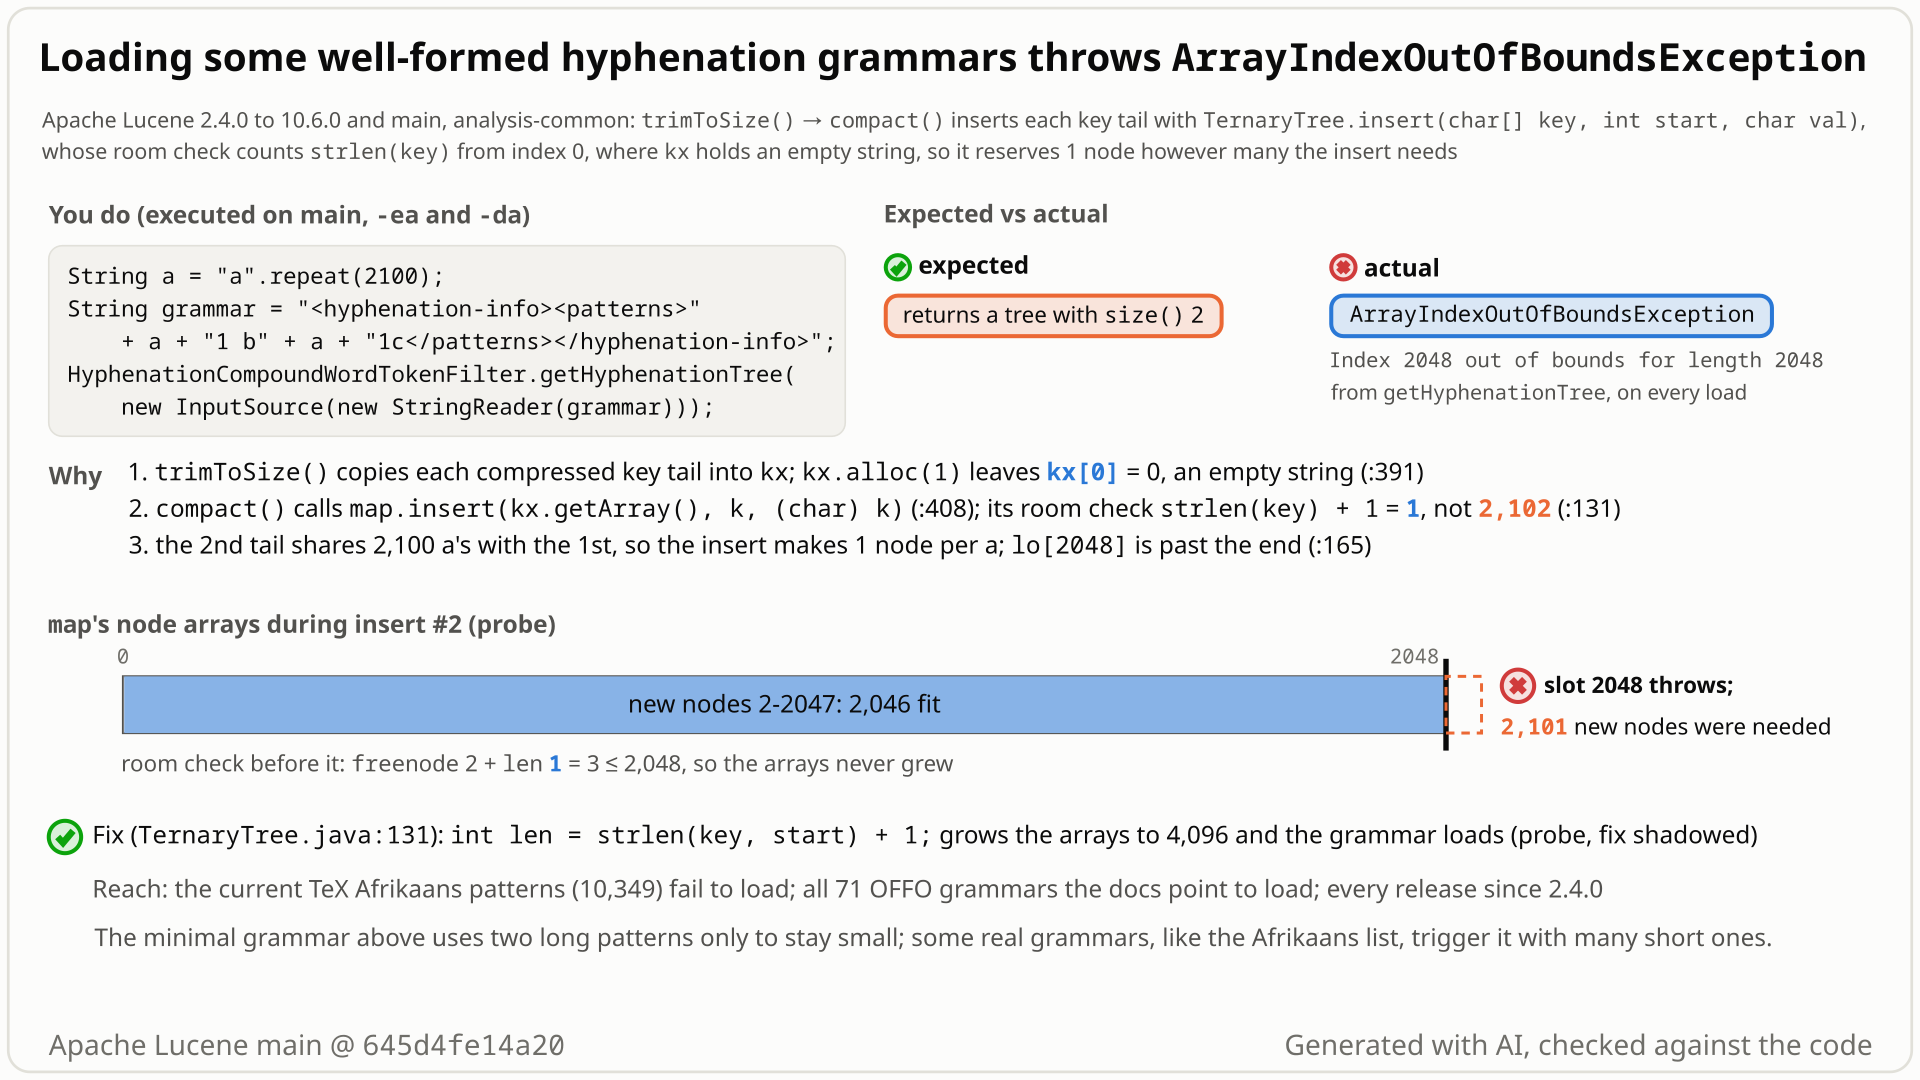
- You load a hyphenation grammar for
HyphenationCompoundWordTokenFilterwithgetHyphenationTree(...)or the factory'shyphenatorfile, for example the current TeX Afrikaans list of 10,349 patterns. You expect a tree: it builds 20,457 nodes while loading, and the class javadoc speaks of "room for about 65000 nodes". - You get
ArrayIndexOutOfBoundsException: Index 2048 out of bounds for length 2048on every load, and the filter cannot be built. All 71 OFFO grammars the Lucene docs link to load without this exception; of 75 current TeX lists only Afrikaans fails this way. - Why: loading ends with
trimToSize(), which copies every stored key tail into a helper tree with 2,048 node slots. Before each insert,insert(char[] key, int start, char val)reservesstrlen(key) + 1slots, counted from index 0 instead ofstart. Index 0 of this key array is always an empty string, so it always reserves 1 slot. - Tiny example: two patterns that share a 2,100-letter tail. The first tail takes 1 slot (next free slot: 2). The second needs 2,101 new slots, but the check sees 2 + 1 <= 2,048 and grows nothing, so writing slot 2,048 throws. Counting from
startreserves 2,101 slots, the arrays grow to 4,096 first, and the grammar loads.
Users of the opt-in HyphenationCompoundWordTokenFilter, directly or through its factory, whose grammar has the triggering shape, such as one built from the current TeX Afrikaans patterns. That grammar fails on every load and the analyzer cannot be built. It fails loudly at setup and returns no tree. Rare: every grammar the Lucene docs link to loads without this exception.
Mechanism, terms and numbers1,035 words
HyphenationTree.loadPatterns (used by both HyphenationCompoundWordTokenFilter.getHyphenationTree overloads and by the factory's hyphenator file) ends with TernaryTree.trimToSize(), which de-duplicates the tree's stored key tails through a helper TernaryTree in compact(). Those inserts go through insert(char[] key, int start, char val), whose capacity check reserves strlen(key) + 1 node slots counted from index 0, while the insert itself works from key[start]. In compact()'s key array index 0 is always an empty string, so the check always reserves one slot. When one insert needs more new nodes than are left before the end of a 2,048-slot block, it writes past the arrays and loading fails with ArrayIndexOutOfBoundsException: Index 2048 out of bounds for length 2048.
The current TeX Afrikaans patterns (10,349) trigger it; all 71 OFFO grammars the Lucene docs link to load without this exception. The failure is loud and at setup time, and the loaders return no tree. Every release from 2.4.0 (2008) to 10.6.0, and main, is affected. The one-line fix, strlen(key, start) + 1, is the bound the String overload already uses.
- Arrays grow in blocks.
BLOCK_SIZE = 2048(:96);init()allocateslo,hi,eq,scwith 2,048 slots and setsfreenode = 1(:102-111). - Each public insert grows the arrays first, if needed. The
Stringoverload reserveskey.length() + 1, "maximum number of nodes that may be generated" (:120). Thechar[]overload reservesstrlen(key) + 1(:131), andstrlen(key)isstrlen(key, 0)(:251-253), but the insert works fromkey[start](:135,:140). - The recursive insert has no check of its own. It creates up to one node per character from
start, plus one: a new branch node (:145) or a decompression node (:164) per level, recursing withstart + 1(:197). - In Lucene's source the only caller with
start > 0isTernaryTreeitself (the overload is public, so outside code could pass one).trimToSize()(:382-396) makes a key vector withkx.alloc(1)(:391), sokx[0]is the empty string, and a helperTernaryTree map(:392).compact()(:398-418) copies each new tail tokxat an offsetk >= 1and callsmap.insert(kx.getArray(), k, (char) k)(:408).strlen(kx.getArray())is 0, so the check always reserves 1 slot, and the helper's arrays grow only whenfreenodeis exactly at the block end. - Reached on every grammar load:
getHyphenationTree(InputSource)callsloadPatterns(HyphenationCompoundWordTokenFilter.java:180; theStringoverload wraps its file name,:166-168), the factory loads itshyphenatorfile that way (HyphenationCompoundWordTokenFilterFactory.java:119), andloadPatternscallstrimToSize()(HyphenationTree.java:109).
Patterns a x 2100 + 1 and b + a x 2100 + 1c give the keys a x 2100 and b + a x 2100 + c. After balance() the main tree stores the compressed tails a x 2100 and a x 2100 + c, which compact() copies to kx at k = 1 and k = 2102.
- Insert 1 (
k = 1): the check reserves0 + 1 = 1slot; the empty helper stores the tail as one compressed node;freenodegoes from 1 to 2. - Insert 2 (
k = 2102): the check reserves 1 slot;2 + 1 <= 2048, so nothing grows. The tail shares 2,100 letters with the first, so the insert splits one node per shared letter (2,101 new nodes needed). After 2,046 recursive calls it takes slot 2,048 andlo[pp] = lo[p](:165) throws. - Full stack:
getHyphenationTree:180->loadPatterns:109->trimToSize:393->compact:414->compact:408->insert(char[], int, char):135-> 2,046 xinsert:197->insert:165. - With
strlen(key, start) + 1: insert 1 reserves 2,101 slots (1 + 2101 > 2048), the arrays grow to 4,096, insert 2 (2,102 reserved) fits,freenodeends at 2,103, and the grammar loads.
Real grammars get there with short tails: when the helper's freenode sits a few slots before 2,048 (or 4,096, ...), an insert that needs more new nodes than the slots left overruns, because only 1 was reserved. The Afrikaans list throws at :146, a new branch node at slot 2,048.
| grammar | stock | with the fix |
|---|---|---|
| the 2-pattern grammar above (the repro) | Index 2048 out of bounds for length 2048 | loads |
the same 2 patterns in a DTD-valid file (DOCTYPE + <classes>) | the same exception | loads; hyphenate() finds the break before c |
| current TeX Afrikaans list, 10,349 patterns (builds 20,457 nodes) | the same exception | loads, all 10,349 values right |
OFFO af.xml + the 7 ASCII-apostrophe patterns the TeX list adds | the same exception | loads all 10,349 patterns |
| 1,310 random 4-8-letter patterns (the finder's test) | the same exception | loads, every value right |
| all 71 OFFO grammars | load without this exception (2, the Norwegian ones, lose patterns: LFV-897) | load, identical size() |
| the other 74 current TeX lists | not this exception (4 fail with StackOverflowError, 2 lose patterns: separate problems, LFV-897) | - |
The repro, DTD-valid and Afrikaans rows ran on 645d4fe14a20; the others on main a9779ef3c193, whose compound/ sources are identical. The TeX project publishes plain pattern lists; the hunt wrapped them in a patterns-only XML file, which Lucene's loader accepts (its parser does not validate). The bundled hyphenation.dtd also asks for <classes>, which none of the 71 OFFO 2.2 grammars has either. These runs check loading and findPattern values only: without classes hyphenate() knows no letters, so end-to-end hyphenation with the fix was checked only on the DTD-valid file. No unmodified OFFO grammar hits this exception; OFFO af.xml does only with the 7 TeX patterns added.
The pattern count alone does not decide it; the grammar's shape and where the boundaries fall do. Random 2-6-letter grammars failed 0 of 80 times at up to 2,000 patterns, 6 of 20 at 3,000, 11 of 20 at 5,000 and 14 of 20 at 8,000. A given grammar fails or loads the same way every time: balance() rebuilds the tree from sorted keys first, so pattern order does not matter.
Exposure and likelihood370 words
- Who is exposed. Applications that use
HyphenationCompoundWordTokenFilterwith a tree from eithergetHyphenationTreeoverload orHyphenationTree.loadPatterns, orHyphenationCompoundWordTokenFilterFactory(itshyphenatorgrammar is mandatory). No Lucene analyzer uses the filter by default. - What it takes. A well-formed grammar whose compressed key tails make one insert into
compact()'s helper tree need more new nodes than are left before a 2,048-slot boundary. Known real trigger: the current TeX Afrikaans list. For custom grammars there is only one measurement, a random generator of 2-6-letter patterns: none of 80 grammars failed at up to 2,000 patterns, 6 of 20 at 3,000, 11 of 20 at 5,000; how often real custom grammars hit it is not measured. - What happens.
ArrayIndexOutOfBoundsExceptionfrom the loader on every load of that grammar (the hyphenation package has noassertstatements; the repro fails the same with assertions on and off); the message does not say why.getHyphenationTreeand the factory return no tree, so nothing is indexed wrong. One case differs: code that callsloadPatternson its own tree, catches the exception and keeps the object holds a half-compacted tree (TernaryTree.java:410has already re-pointed visited nodes, but the key array is replaced only at:394); on the repro grammar it reportssize()2, butfindPatternof the first pattern returns an empty string. - Scale. Far below the documented size: the helper fails at 2,048 slots, and the whole Afrikaans tree builds 20,457 nodes while loading (18,848 after
balance()), about a third of the javadoc's "about 65000". - How likely. Rare: all 71 OFFO grammars load without this exception, of 75 current TeX lists only Afrikaans hits this exception, and the recorded searches found no report of it in Lucene or in the other copies of this code.
- Workaround. No setting avoids it, and factory users can only change the grammar (for Afrikaans, OFFO's
af.xmlwithout the 7 newer patterns loads). Code that builds the tree itself can load it into aHyphenationTreesubclass whosetrimToSize()only callsbalance(), and pass that tree to the filter's public constructor. This is unofficial and skips the compaction (more memory); it loads the repro grammar, the Afrikaans list and 9 of 9 failing random grammars with every value right.
One JUnit test, public API only: it loads a 2-pattern grammar whose patterns share a 2,100-letter tail through getHyphenationTree(InputSource) and checks only that loading succeeds. The long tail is a shortcut that makes one insert cross the 2,048-slot boundary; real grammars get there through thousands of short patterns.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.compound;

import java.io.StringReader;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.xml.sax.InputSource;

public class TestHyphenationGrammarLongPatternsLoad extends LuceneTestCase {

  public void testTwoPatternsSharingA2100LetterTailLoad() throws Exception {
    String a = "a".repeat(2100);
    String grammar =
        "<hyphenation-info><patterns>" + a + "1 b" + a + "1c</patterns></hyphenation-info>";
    try {
      HyphenationCompoundWordTokenFilter.getHyphenationTree(
          new InputSource(new StringReader(grammar)));
    } catch (Throwable t) {
      // Expected: the 2-pattern grammar loads; actual: trimToSize() -> compact() throws AIOOBE.
      throw new AssertionError("loading a 2-pattern grammar threw " + t, t);
    }
  }
}
./gradlew :lucene:analysis:common:test --tests "org.apache.lucene.analysis.compound.TestHyphenationGrammarLongPatternsLoad" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
- Expected
- The 2-pattern grammar loads and
getHyphenationTreereturns a tree. - Observed
- Loading throws
ArrayIndexOutOfBoundsException: Index 2048 out of bounds for length 2048atTernaryTree.insert(TernaryTree.java:165), with assertions on and off.
More files, environment, full output242 words
Copy the file into lucene/analysis/common/src/test/org/apache/lucene/analysis/compound/ and run the command. The test is deterministic (no randomness; the framework's randomization does not touch this path). Pass -Ptests.asserts explicitly, because by default the build picks it from the seed. It is the suggested regression test as it stands.
For a 2-pattern grammar the shared tail must be at least 2,046 letters (2,045 loads); 2,100 leaves a margin. The test's grammar has only a <patterns> element, which Lucene's loader accepts; with a DOCTYPE and <classes>aA bB cC</classes> added it validates against the bundled hyphenation.dtd and fails the same way, assertions on and off. With short realistic patterns the same crossing takes on the order of a thousand patterns or more (the finder's 1,310, or the 10,349-pattern TeX Afrikaans list, the real-world trigger). Long patterns are not typical.
| lucene | main 645d4fe14a20; also the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
./gradlew :lucene:analysis:common:test --tests "org.apache.lucene.analysis.compound.TestHyphenationGrammarLongPatternsLoad" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true (the same with false)
TestHyphenationGrammarLongPatternsLoad > testTwoPatternsSharingA2100LetterTailLoad FAILED
    java.lang.AssertionError: loading a 2-pattern grammar threw java.lang.ArrayIndexOutOfBoundsException: Index 2048 out of bounds for length 2048
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:8FE4FEC642477207]:0)
        at org.apache.lucene.analysis.compound.TestHyphenationGrammarLongPatternsLoad.testTwoPatternsSharingA2100LetterTailLoad(TestHyphenationGrammarLongPatternsLoad.java:34)

        Caused by:
        java.lang.ArrayIndexOutOfBoundsException: Index 2048 out of bounds for length 2048
            at org.apache.lucene.analysis.compound.hyphenation.TernaryTree.insert(TernaryTree.java:165)
            at org.apache.lucene.analysis.compound.hyphenation.TernaryTree.insert(TernaryTree.java:197)
            ... (the JVM keeps the top 1,024 frames by default; the full stack has 2,046 frames at TernaryTree.java:197)

# with the recommended fix, assertions on and off: the test passes
BUILD SUCCESSFUL- The
Stringoverload of the same method reserveskey.length() + 1slots, "maximum number of nodes that may be generated"; only thechar[]overload leavesstartout of its bound. - In Lucene's source,
compact()is the only caller that passesstart > 0, on every grammar load. loadPatternsdocuments onlyIOExceptionfor parse failures, and the grammar is well-formed.
The full argument206 words
- The check exists to grow the arrays before an insert, and its sibling does it right (
TernaryTree.java:120vs:131). Thechar[]overload passesstartto the recursive insert (:135), which measures the key from there (:140); only the bound ignores it. - No misuse by applications. In Lucene's source the only caller with
start > 0isTernaryTree.compact()(:408; the overload is public, so outside code could pass one), reached fromloadPatternson every load. The otherchar[]caller passesstart = 0(HyphenationTree.java:384). - No documented limit.
loadPatternsdocuments only "IOException In case the parsing fails" (HyphenationTree.java:95-100),getHyphenationTreeonlyIOException. The class javadoc's "room for about 65000 nodes" (:44) is a design note, not a contract, and the helper fails at 2,048. Lucene'schar[]overload has no javadoc; Apache FOP's copy documentsstartas "offset into key array". - Tests. Upstream tests load only small grammars (
da_UTF8.xml, 7,352 bytes, and two files of about 1 KB), far below 2,048 helper nodes; none asserts anything about this exception. - Precedent. A data-dependent failure in this package was fixed as a bug before: LUCENE-8124 (#9172, hyphenation values of 7 or more), fixed in 7.3.
The devil's-advocate check217 words
The strongest case for "intended": the code is an import from Apache FOP, unchanged in Lucene since 2008 and the same in FOP today; the class javadoc says patterns are "usually small (from 2 to 5 characters)"; every OFFO grammar the docs link to loads without this exception, so the code works for the documented grammars; and the minimal test needs 2,100-letter patterns in a patterns-only file. The cross-model reviews of the hunt rated this case weak and verifiers rejected it; a later cross-model fact check of this doc rated it moderate.
Why it fails: age shows the path was rarely exercised, not that it is intended. The docs offer OFFO as a place to find grammars ("You can find the XML based grammar files at ..."), not as the only allowed input. A published list fails, and so does a grammar of 1,310 random 4-8-letter patterns, fewer than the javadoc's "from 5000 to 15000 hyphenation patterns" per language. The long test patterns are only a shortcut to the same boundary; a file that validates against the bundled DTD fails the same way, and the OFFO 2.2 grammars are patterns-only too. A capacity check that ignores the offset its own method uses is an oversight. Expect a maintainer to call the reach narrow, not the behaviour intended.
Recommended A. Count the key from start in the capacity check
In TernaryTree.insert(char[] key, int start, char val), reserve strlen(key, start) + 1 slots instead of strlen(key) + 1: the bound the String overload already uses. It runs only while a grammar loads. Validated: the repro passes, and so does every compound/hyphenation suite, with assertions on and off.
   public void insert(char[] key, int start, char val) {
-    int len = strlen(key) + 1;
+    int len = strlen(key, start) + 1;
     if (freenode + len > eq.length) {
       redimNodeArrays(eq.length + BLOCK_SIZE);
     }
All options and trade-offs3 options · 543 words
Option A was applied in scratch worktrees of main 645d4fe14a20 and run through gradle; the worktrees were removed afterwards. Option B was run only through the repro harness on the hunt's commit; option C was not run.
One line in TernaryTree.java:131. The recursive insert creates at most one node per character from start, plus one, so strlen(key, start) + 1 is the right bound; start == 0 callers are unchanged.
   public void insert(char[] key, int start, char val) {
-    int len = strlen(key) + 1;
+    int len = strlen(key, start) + 1;
     if (freenode + len > eq.length) {
       redimNodeArrays(eq.length + BLOCK_SIZE);
     }
Trade-offs
- No cost on the analysis path: only grammar loading inserts into the tree.
- Not covered (untested, out of scope):
redimNodeArraysgrows by one 2,048-slot block per insert, so a single key needing more than about 2,000 new nodes could still overflow, in either overload (option C). Option A is deliberately scoped to this bug, not general long-key hardening. - The separate 16-bit key-offset bug in the same class (LFV-897) is not fixed by this and still reproduces with it.
What the checks validated
- Gradle in a scratch worktree of main
645d4fe14a20, seed DEADBEEF (this doc): stock, the repro fails; with the fix, the repro and every upstreamorg.apache.lucene.analysis.compound.*suite (TestCompoundWordTokenFilter,TestHyphenationCompoundWordTokenFilterFactory,TestDictionaryCompoundWordTokenFilterFactory,TestPatternParser) pass, assertions on and off (5 classes, 26 tests, 0 failures each way). - An earlier gradle run the same day, also on
645d4fe14a20: all of:lucene:analysis:common:testwith the fix (340 classes, 1,910 tests, 18 skipped, 0 failures), and:lucene:analysis:common:check -x test(google-java-format, ecjLint, forbiddenApis) with the fix and the test file added. - In the repro harness: the finder's 1,310-pattern JUnit, an independent 4-test JUnit and the real TeX Afrikaans list (10,349 patterns, 0 wrong values) pass with it, and so do 25 random scale runs and 2.4.0 with the same line changed.
FOP-2569 (Apache FOP, open since 2016, a different report) carries a 2020 patch that adds if (freenode + strlen(key, start) > eq.length) redimNodeArrays(...) at the top of the recursive insert. Applied alone to Lucene main it also makes the finder's and an independent reproducer's tests pass.
Trade-offs
It re-checks capacity at every level of every insert to compensate for a bound that stays wrong at :131. In FOP it is part of a larger change, which also widens the node pointers to int, that was never applied: its author, Chris Bowditch, wrote that "the unit tests are failing and so it needs more work" and later "I never applied the patch". Fixing the bound is the root-cause fix.
On top of A, let both public overloads grow to at least freenode + len, e.g. redimNodeArrays(Math.max(eq.length + BLOCK_SIZE, freenode + len)).
Trade-offs
Closes the long-key gap noted under A; not needed for this bug. It does not lift the 16-bit char node and key offsets (:66-72, :90-92, :151, :410), so trees grown past 65,535 slots run into LFV-897.
Products that let an operator pick the grammar file, as in the factory's own hyphenator="hyphenator.xml" example, see this as an analyzer that fails to start; document and query text cannot trigger it, because analysis only reads the finished tree.
A bounded-exhaustive check of TernaryTree, through its public subclass HyphenationTree, against a reference map found no mismatch in 3,305,820 checks over 9,723 small insert sequences. Its scale phase with a few thousand random keys then threw at slot 2,048 or 4,096 while compacting. Code reading found the bound; loading 75 real pattern lists found Afrikaans.
The method in full146 words
- Method (semi-formal): bounded-exhaustive translation validation on the stock main jars, public API only, in a sweep of analysis-common APIs no earlier hunt had named. Every insert sequence of depth 3 or less (9,723 of them) over 21 keys (including a lone high surrogate), checked after insert, clone, balance and
trimToSizeagainst aTreeMap: 3,305,820 find/knows checks, 0 mismatches. - Signal. A scale phase with 2,000-6,000 random keys threw
ArrayIndexOutOfBoundsExceptionat exactly 2,048 or 4,096 insidetrimToSize. The finder traced it to the capacity check by reading the code. - Reach. The finder loaded 75 current TeX pattern lists through
getHyphenationTree: only Afrikaans hits this exception. A devil's-advocate checker then loaded all 71 OFFO grammars (all load) and showed that OFFO'saf.xmlplus the 7 newer TeX patterns fails. - The finder's public-API JUnit used 1,310 random patterns; the repro was later minimized to one 2-pattern test.
No prior report found (GitHub issues, PRs, commits and code, JIRA LUCENE, SOLR and FOP, the Lucene and FOP lists, the web; refreshed 2026-10-30). Closest: Apache FOP's open FOP-2569, a different defect whose unapplied patch would also hide this one.
Searches5 searches
Not the same bug: #2243 (LUCENE-1166, the 2008 import), #9172 (LUCENE-8124, values of 7 or more, fixed in 7.3), SOLR-1316 (a 2009 remark on the 65K-node limit), #4120, #14624, #9180 and elastic/elasticsearch#13935 (decompounding output). FOP-2569 reports a StackOverflowError and the 16-bit pointer limit in FOP's copy (the LFV-897 problem); nobody there mentions a start offset, compact() or trimToSize. A 2020-07-20 comment there also shows an ArrayIndexOutOfBoundsException ("Array index out of range: 103894") from hyphenate() on a de-DE grammar past 65,535 nodes: a lookup failure on an oversized tree (LFV-897 territory), not this load failure at 2,048 slots, but a maintainer searching FOP-2569 for the exception name will find it. No indexed GitHub code-search result, and no copy inspected by hand, has the fixed line; it is unfixed in Apache FOP, iText 5 and 7, OpenPDF and the Lucene.NET port. Upstream main 2f424fd428da (2026-10-30) still has the line, none of the 30 newest open PRs touches analysis/compound, and none of the 40 issues and PRs created since 2026-10-27 is about hyphenation or the compound filters. Gaps: searches cannot prove absence; private reports cannot be searched. The fact checks by an independent reviewer from another model family (OpenAI GPT-5.6) read FOP-2569 as a partial overlap and argued for novelty "known"; it stays "new" because FOP-2569 reports a different defect (the one in LFV-897) and nobody there describes this failure; its patch masks it only as a side effect.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (the finder's run and three follow-up variants) | 2026-10-28 | code terms, user-level terms (factory, PatternParser, decompounder, OFFO, hyph-utf8) and internal names (compact, balance, BLOCK_SIZE): 45 + 51 + 59 + 49 queries over GitHub issues, PRs and commits, downstream repositories, the Lucene lists, JIRA and the web | no report; 0 high-rated hits |
| GitHub (manual) and GitHub code search | 2026-10-28 | apache/lucene, Lucene.NET, Apache FOP, OpenPDF: class, symptom and method phrasings; code search for the fixed line; the file lists of the 100 most recently updated open apache/lucene PRs | no report; no indexed or hand-inspected copy has the fixed line; only #16911 (branch_10x decommission, since merged) listed the file |
| JIRA (LUCENE, SOLR, FOP) and the FOP lists | 2026-10-28 | TernaryTree, HyphenationTree, trimToSize, ArrayIndexOutOfBoundsException; fop-dev, fop-users, fop-commits | FOP-2569 (a different defect, code-only overlap) and SOLR-1316; list threads only about StackOverflowError |
| Web | 2026-10-28 | 19 queries (Elasticsearch, OpenSearch, Solr, Lucene.NET, FOP, Afrikaans) | no report |
| GitHub API, apache/lucene (refresh for this doc) | 2026-10-30 | issue/PR searches TernaryTree, HyphenationTree, HyphenationCompoundWordTokenFilter, hyphenation ArrayIndexOutOfBoundsException, trimToSize hyphenation, hyphenation grammar load; file lists of the 30 newest open PRs (#16872 to #16952); upstream main's TernaryTree.java and the commits under analysis/compound; every issue and PR created since 2026-10-27 and the four class/term searches over items updated since then (redone after the first request hit the API rate limit) | nothing related (TernaryTree: only #4950, System.out.println); main 2f424fd428da still has the line; last compound commit #16680 (2026-09-28); 40 issues/PRs created since 2026-10-27, none about hyphenation; 0 hits for the term searches |
Since 2.4.0 (2008): LUCENE-1166 (7a27cdcbc901) copied the hyphenation classes, with this line, from Apache FOP, whose current code still has it. Executed on the introducing commit, 16 releases from 2.4.0 to 10.5.2, the 10.6.0 jars and main: all fail; the other release tags have the same code (source scan of all 139 that ship it). Never fixed.
Versions tested6 rows
Introduced by 7a27cdcbc901 (svn r657027, 2008-05-16, "LUCENE-1166: Added token filter for decomposing compound words"; JIRA LUCENE-1166 is GitHub #2243; no PR). The class javadoc says it "has been taken from the Apache FOP project"; the capacity check came with the copy, and FOP's current trunk has the same line. When it entered FOP was not traced.
Release history. First release 2.4.0 (2008-10); 2.3.2 and earlier have no hyphenation package. All 139 release tags that ship TernaryTree (2.4.0 to 10.6.0) have the same line, the same kx.alloc(1) and map.insert(kx.getArray(), k, (char) k), and the trimToSize() call in loadPatterns. No later commit changed the capacity check, trimToSize() or compact(): git log -L130,136 lists only 7a27cdcbc901, and git blame puts TernaryTree.java:130-136 and :382-418 on it. The 27 later commits on the file are moves (LUCENE-1728, LUCENE-2444, LUCENE-3965), reformatting (LUCENE-9570, #16713) and small cleanups elsewhere in the class (e.g. LUCENE-2000, LUCENE-3877, #12404). Upstream main 2f424fd428da (2026-10-30) still has the line.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the one-test repro fails through gradle and the harness, assertions on and off; passes with the fix |
| 10.6.0, 10.5.2 (release jars) | affected | the one-test repro and the Afrikaans list fail (assertions off); the finder's JUnit fails on 4ae946e5a9b9, the commit the 10.6.0 tag peels to, and on 10.5.2 |
main a9779ef3c193, 9.12.3 | affected | the finder's and an independent JUnit fail (on a9779ef3c193 with assertions on and off, on 9.12.3 with assertions on); the TeX Afrikaans list fails to load on both with assertions off, and on 9.12.3 the version-portable main() also fails with assertions off |
| 10.0.0, 9.0.0, 8.11.4, 8.0.0, 7.7.3, 6.6.6, 5.5.5, 4.10.4, 4.0.0, 3.6.2, 3.0.3, 2.9.4, 2.4.1 | affected | a version-portable main() with the 1,310-pattern grammar fails; its 200-pattern control loads |
2.4.0 and the introducing commit 7a27cdcbc901 | first | the same failure; 2.4.0 with the one-line fix passes |
| 2.3.2 | API absent | no compound/hyphenation package; the repro does not compile |
A cross-model review, an independent reproducer, a second cross-model review, a devil's advocate, an adjudication, a re-run, a credibility audit and fact checks in two rounds all confirmed it; every executed check reproduced it. This doc re-ran the repro on 645d4fe14a20 and validated the fix through gradle.
Checks and verdicts570 words
The hunt's checks ran on main a9779ef3c193 (the cross-model refute review on ea57360912ed); the compound/ sources are identical at both and at 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6), executing: its own JUnit fails (the small-grammar control passes) and passes with the fix; root cause and fix agree; intended-behaviour argument weak. |
| Independent reproducer | real | Own 4-test JUnit: 2 of 4 fail on main (assertions on and off), 10.5.2 and 9.12.3 (4,000 keys inserted with start = 1; generated 3,000- and 4,000-pattern grammars); the String and start = 0 controls pass. The Afrikaans list fails on main, 10.5.2, 9.12.3 and 8.11.4. With the fix: 4 of 4 pass, Afrikaans loads with 0 wrong values. |
| Cross-model review, intended lens | real (medium) | The same OpenAI GPT-5.6 reviewer, reading only: intended argument weak, root cause agrees, inputs in contract; a separate re-run failed on main. |
| Intended-behaviour devil's advocate | real (high); reach narrower than the first title | Built and rejected the works-as-designed case; all 71 OFFO grammars load, OFFO af.xml plus 7 TeX patterns fails; re-runs fail on main (assertions on and off) and 10.5.2. |
| Adjudication | confirmed (high) | Re-ran the independent reproducer's test (2 of 4 fail, assertions on) and the finder's (fails, assertions off); the former passes 4 of 4 with the fix. Scope of the claim: some well-formed grammars fail, not ordinary grammars, and the trigger is a boundary crossing, not a pattern count. |
| Registration check and credibility audit | reproduces; keep | Re-ran the finder's JUnit on a clean checkout with assertions on and off (fails) and with the fix shadowed (passes); re-read the code; refreshed the prior-art search. |
| Repro minimization | one test, fails | Reduced to one 2-pattern test on 645d4fe14a20: fails with assertions on and off, passes with the fix shadowed; a deep-stack probe recorded the full call path. |
| Fact checks of the earlier doc | real; corrections applied | One re-ran the gradle command on a fresh worktree of 645d4fe14a20, the harness repro on main and the 10.6.0 and 10.5.2 jars, an instrumented copy of TernaryTree and the real Afrikaans list; the other, an independent reviewer from another model family (OpenAI GPT-5.6), checked the records. Both confirmed the bug, mechanism, fix and security call; their corrections are carried into this doc. |
| Fact checks of the rewritten doc | real; corrections applied | One re-ran the gradle command in a fresh worktree of 645d4fe14a20 (fails with assertions on and off; with the fix it passes with every compound suite), the harness on main and the 10.6.0 and 10.5.2 jars, its own replica of compact() and the real Afrikaans list, and found the exact minimum shared tail (2,046 letters). The other, the OpenAI GPT-5.6 reviewer, checked the records: bug, root cause and fix real; intended case moderate; it argued for novelty "known" (see Prior reports) and noted that the test files do not follow the bundled DTD, after which a DTD-valid variant was run (fails the same way). |
| Fix validation (this doc) | fix validated | Harness on 645d4fe14a20: the repro fails with assertions on and off and passes with the fix shadowed. Gradle in a scratch worktree of 645d4fe14a20: the repro fails stock; with the fix it and every compound/hyphenation suite pass, assertions on and off (26 tests, 0 failures each way). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 414 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,532 words
- Registry title
- Loading some well-formed hyphenation grammars (e.g. the current TeX Afrikaans patterns) throws ArrayIndexOutOfBoundsException, because TernaryTree.insert(char[], int, char) sizes its node arrays with strlen(key) instead of strlen(key, start)
- Area
- analysis-common / compound hyphenation (TernaryTree.compact via HyphenationTree.loadPatterns and HyphenationCompoundWordTokenFilter)
- Priority
- Low, rank 613: It is a loud, deterministic load-time crash in the opt-in compound hyphenation filter that hits one real public grammar and corrupts nothing, so it heads the loud opt-in crash rows next to LFV-650.
- Impact class
- crash
- Impact note
- Hits applications that use the opt-in HyphenationCompoundWordTokenFilter (directly, through getHyphenationTree or HyphenationTree.loadPatterns, or through the factory's hyphenator file) with a grammar whose compacted key tails make the helper map in TernaryTree.compact() cross a 2048-node block boundary inside a multi-node insert: loading that grammar then always throws ArrayIndexOutOfBoundsException at analyzer construction, with -ea and -da and no scale needed, so the filter cannot be built from it; the known real-world trigger is the current TeX Afrikaans pattern list (10,349 patterns), while all 71 OFFO grammars the Lucene docs point to load fine; the failure is loud and at setup time, with no wrong decompounding output, in every release from 2.4.0 to 10.6.0 and on main.
- Summary
- You load a well-formed FOP-format hyphenation grammar with HyphenationCompoundWordTokenFilter.getHyphenationTree (or HyphenationTree.loadPatterns, or the factory's hyphenator file) and expect it to load, as the TernaryTree javadoc's 'room for about 65000 nodes' suggests. For some grammars, for example the current TeX Afrikaans patterns or the repro's 1,310 random 4-8-letter patterns, loading instead throws ArrayIndexOutOfBoundsException: Index 2048 out of bounds for length 2048 from TernaryTree.insert, called by compact() during trimToSize(). The cause: insert(char[] key, int start, char val) reserves room for strlen(key) + 1 nodes counted from index 0 instead of from start, and its only caller with start > 0, compact(), passes a key array whose index 0 is an empty string, so it reserves one node and a multi-node insert that crosses the 2048-node block boundary writes past the arrays; with strlen(key, start), the bound the String overload already uses, every failing grammar loads with all values right.
- Introduced
- 7a27cdcbc901cd5e5ebb44065e3158866156dc08 (svn r657027), LUCENE-1166 / #2243 'A tokenfilter to decompose compound words' (pre-GitHub, no PR; CHANGES 2.4.0: 'LUCENE-1166: Decomposition tokenfilter for languages like German and Swedish') [read: git blame -w -M -C, git log -L130,136 and git log -S in the full-history clone; release boundary executed]. The patch copied the hyphenation classes, TernaryTree included, from Apache FOP (the class javadoc says so), and the defective line came with that copy; Apache FOP's current TernaryTree still has it. When it entered FOP was not traced. (2008-05-16 (author and commit date 2008-05-16T12:22:50Z); first released in 2.4.0 (2008-10))
- First affected version
- 2.4.0 [exec] (the first release containing 7a27cdcbc901: the version-portable main() repro fails there, and passes with the one-line fix shadowed; the introducing commit's own sources fail the same way). 2.3.2 and earlier are not affected because the API is absent [exec: compile error, no compound/hyphenation package].
- Affected versions
- Every release from 2.4.0 to 10.5.2 (all 138 release tags that ship TernaryTree have the same line and the same loadPatterns -> trimToSize -> compact call path [read: tag scan]), 10.6.0 (executed as the branch_10_6 head 4ae946e5a9b9), branch_10x and main a9779ef3c193; no upstream fix. [exec: the main() repro fails on the introducing commit's own code and on 2.4.0, 2.4.1, 2.9.4, 3.0.3, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea; also -da on 9.12.3, 10.5.2 and main); the finder's JUnit fails on 9.12.3, 10.5.2, branch_10_6 4ae946e5a9b9 and main (-ea and -da); the independent reproduction's JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3, and the real TeX Afrikaans list fails to load on main, 10.5.2, 9.12.3 and 8.11.4] [read: upstream main c5ab3e57b9b, branch_10x 1309534296e and branch_10_6 2763db11b0a have the same line].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-28, plus the finder's run and the independent reproduction's, the intended-behaviour check's and the adjudication's checks, all read-only; refreshed in the registration check): three scripted prior-report searches (code terms, user-level terms, internal names; GitHub issues, PRs and commits, downstream repositories, the Lucene lists, JIRA, web; none rated high) plus the finder's 45-query run; manual GitHub searches (TernaryTree, TernaryTree insert, HyphenationTree trimToSize, hyphenation ArrayIndexOutOfBoundsException, loadPatterns exception, hyphenation patterns, everything created in the last 48 h) on apache/lucene, Lucene.NET, Apache FOP and OpenPDF; GitHub code search (no copy of the class anywhere has the fixed line); JIRA LUCENE, SOLR and FOP; the FOP dev, users and commits lists; 19 web queries (Elasticsearch, OpenSearch, Solr, Lucene.NET, FOP, Afrikaans). No issue, PR, commit, JIRA entry, list thread or downstream report describes this bug. Closest item, code only: Apache FOP's open FOP-2569 (2016) reports a different defect in FOP's copy (StackOverflowError and the 16-bit pointer limit, the latter is LFV-897), and its unapplied 2020 patch adds, without explanation, a per-recursion capacity check that would also avoid this failure (applied alone to Lucene main, both repros pass) while leaving the defective line unchanged. Others, not the same bug: #2243 (LUCENE-1166, the original import), #9172 (LUCENE-8124, values >= 7, fixed in 7.3), SOLR-1316 (a 2009 remark on the 65K-node limit), #4120, #14624, #9180, elastic/elasticsearch#13935. Not fixed: upstream main c5ab3e57b9b still has the line; the last commit under analysis/compound is #16680 (author date 2026-09-28, CompoundWordTokenFilterBase only); of the 100 most recently updated open PRs only #16911 ('Decommission branch 10x', which deletes all branch_10x files) lists TernaryTree.java; the refresh (the 40 newest PRs, up to #16926, with the file lists of the 9 newest open PRs other than #16911; issues updated since 2026-10-26, up to #16928; the 'TernaryTree' issue search, still 1 hit, #4950) found nothing related. The same line is unfixed in Apache FOP main, iText 5 and 7, OpenPDF and the Lucene.NET port. Gaps: searches cannot prove absence; private reports are not searchable.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28), OpenJDK 25.0.3, Linux aarch64 (the only platform run). Gradle in a scratch worktree (removed afterwards), seed DEADBEEF: stock, the one-test repro fails; with the one-line fix it passes together with everyorg.apache.lucene.analysis.compound.*suite, assertions on and off (and, in an earlier run the same day, all of:lucene:analysis:common:testand the module's static checks). Harness: the one-test repro on645d4fe14a20(assertions on and off; passes with the fix shadowed) and on the 10.6.0 and 10.5.2 release jars; the same 2 patterns in a file that validates against the bundledhyphenation.dtdon645d4fe14a20(fails, assertions on and off; loads with the fix shadowed); the real TeX Afrikaans list on645d4fe14a20and the 10.6.0 jars, and in the hunt on maina9779ef3c193(identicalcompound/sources), 10.5.2, 9.12.3 and 8.11.4; the finder's and an independent reproducer's JUnits on maina9779ef3c193, 10.5.2 and 9.12.3; a version-portablemain()on the introducing commit and 16 releases from 2.4.0 to 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/TernaryTree.java:44 ('room for about 65000 nodes'), :96 (BLOCK_SIZE = 2048), :118-128 (insert(String, char): len = key.length() + 1, 'maximum number of nodes that may be generated'), :130-136 (insert(char[], int, char): len = strlen(key) + 1 at :131), :139-140 (recursive insert works from key[start]), :382-396 (trimToSize: kx.alloc(1) at :391), :398-418 (compact: map.insert(kx.getArray(), k, (char) k) at :408) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/HyphenationTree.java:96-115 (loadPatterns documents only IOException 'In case the parsing fails'; calls trimToSize() at :109); lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/HyphenationCompoundWordTokenFilter.java:166-182 (getHyphenationTree(String|InputSource) -> loadPatterns at :180); lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/HyphenationCompoundWordTokenFilterFactory.java:38 ('hyphenator' mandatory, 'path to the FOP xml hyphenation pattern'), :88, :119
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/TernaryTree.java:39-46 (javadoc: 5000-15000 patterns, 'usually small', 'room for about 65000 nodes'), :96 (BLOCK_SIZE), :102-111 (init), :113-117 (compressed branches), :118-128 (String overload, :120), :130-136 (char[] overload, :131, :135), :139-206 (recursive insert: :140, :145, :164-165, :197), :251-253 (strlen(a) = strlen(a, 0)), :382-396 (trimToSize, kx.alloc(1) at :391), :398-418 (compact, map.insert at :408) @ 645d4fe14a20lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/HyphenationTree.java:101-115 (loadPatterns; trimToSize at :109), :384 (classmap.insert with start 0); .../compound/HyphenationCompoundWordTokenFilter.java:166-182 (:180); .../compound/HyphenationCompoundWordTokenFilterFactory.java:108-123 (:119); .../compound/package-info.java:88-96 (grammars not bundled; OFFO) @ 645d4fe14a20git diff a9779ef3c193 645d4fe14a20 -- lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/: empty
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/HyphenationCompoundWordTokenFilterFactory.java:38-39 ('hyphenator (mandatory)'), :119; .../compound/HyphenationCompoundWordTokenFilter.java:150 (public constructor taking a HyphenationTree) @ 645d4fe14a20grep at 645d4fe14a20: outside the compound package only module-info.java and TestRandomChains.java name HyphenationCompoundWordTokenFilter or HyphenationTree (no default analyzer uses it)grep -n '\bassert\b' over lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/*.java at 645d4fe14a20: no hits
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/TernaryTree.java:39-46, :118-136, :140, :408 @ 645d4fe14a20lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/HyphenationTree.java:95-100, :384; .../compound/HyphenationCompoundWordTokenFilter.java:159-176; .../compound/package-info.java:88-96 @ 645d4fe14a20lucene/analysis/common/src/test/org/apache/lucene/analysis/compound/ (da_UTF8.xml 7,352 bytes, hyphenation-LUCENE-8124.xml 1,112 bytes, hyphenation-LUCENE-8183.xml 928 bytes); lucene/analysis.tests/.../TestRandomChains.java:270-281 (loads da_UTF8.xml) @ 645d4fe14a20
- Suggested fix
Apache FOP JIRA FOP-2569, comments by Chris Bowditch of 2020-06-15 and 2020-08-06, read-only REST GET on 2026-10-30lucene/analysis/common/src/java/org/apache/lucene/analysis/compound/hyphenation/TernaryTree.java:66-72, :90-92, :130-136, :151, :300-314 (redimNodeArrays), :410 @ 645d4fe14a20
- Independent checks
the item paths above
- TestHyphenationGrammarLongPatternsLoad.java (one test):
repro/LFV-894/src/org/apache/lucene/analysis/compound/TestHyphenationGrammarLongPatternsLoad.java(37 lines)
assets/LFV-894/bug.png(414 KB)