A CSV line is split at commas outside quotes, and a quoted field loses its enclosing quotes. CSVUtil.parse does that for every field followed by a comma but forgets the last field of the line. Kuromoji's user dictionary puts the part-of-speech last.
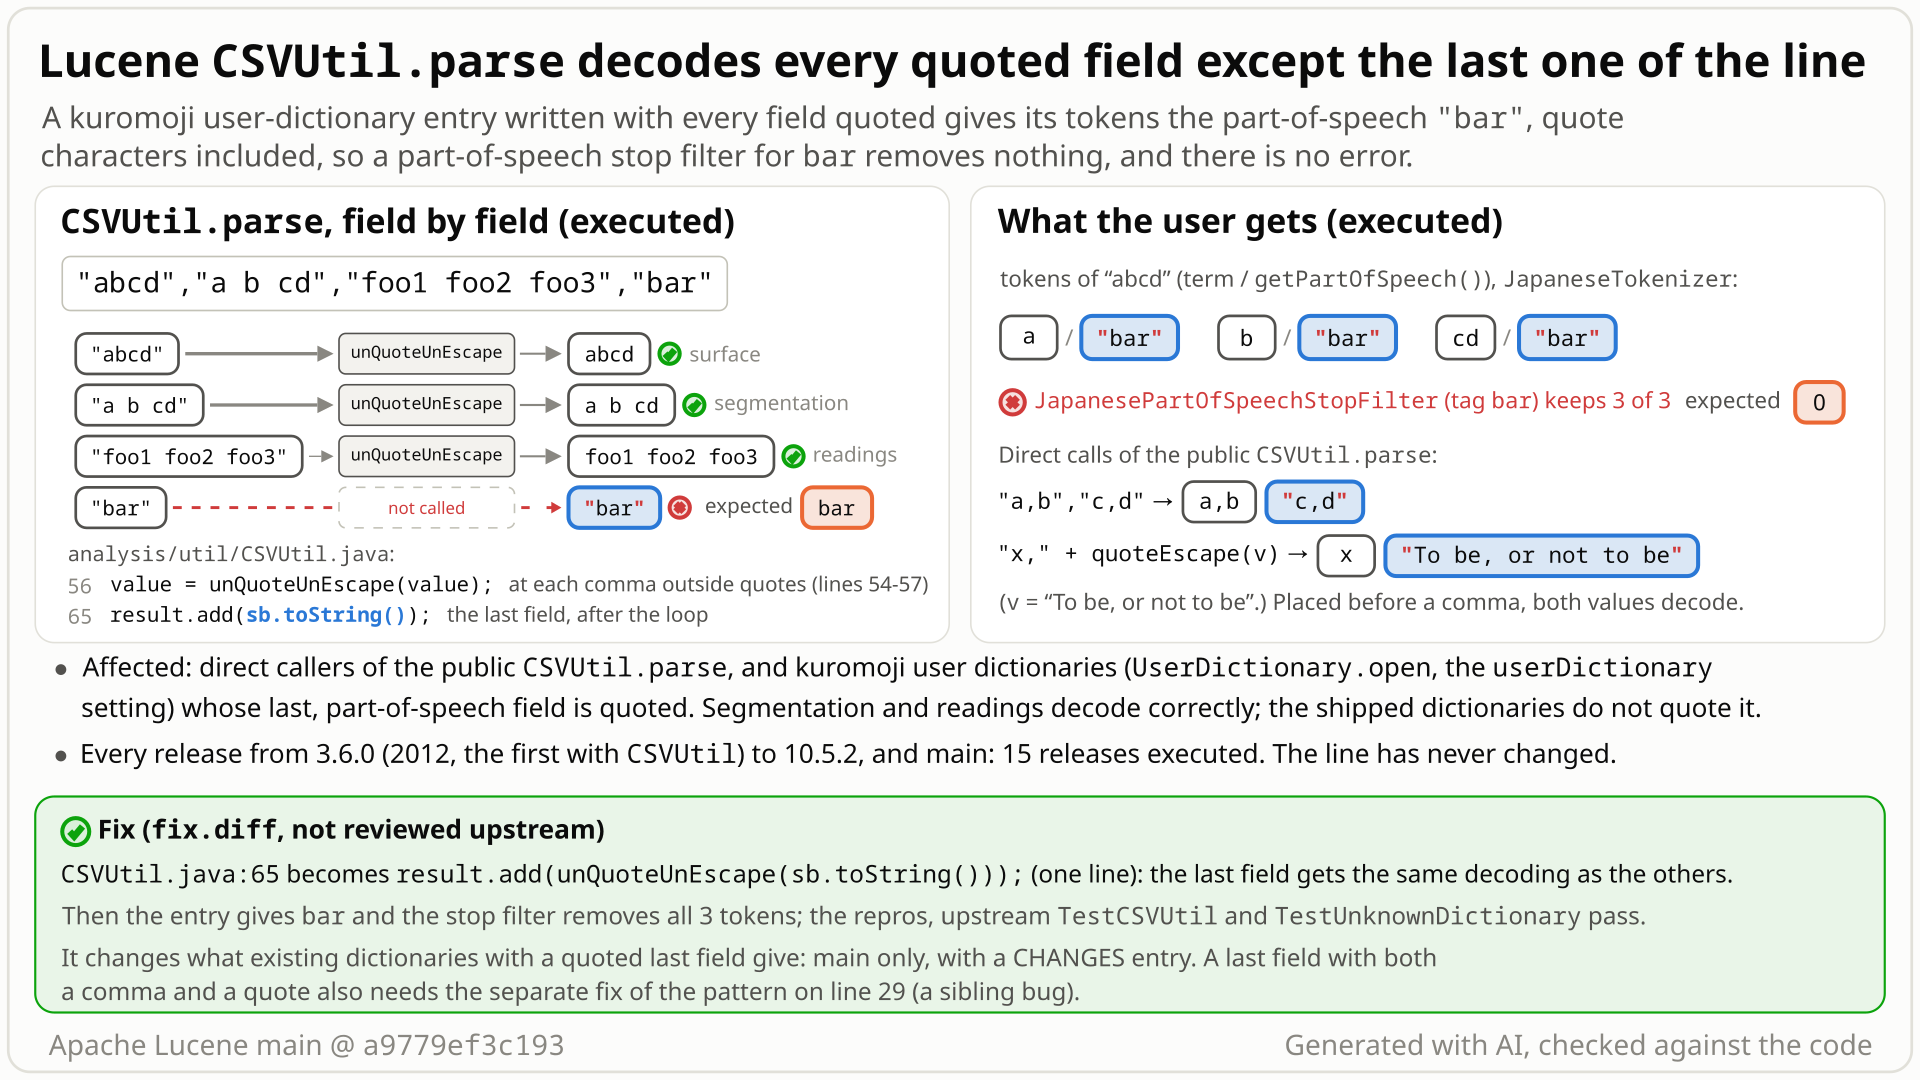
- Write a kuromoji user-dictionary entry with every field quoted, as a CSV tool that quotes all fields would: the upstream test entry
abcd,a b cd,foo1 foo2 foo3,barbecomes"abcd","a b cd","foo1 foo2 foo3","bar". - You expect it to behave like the unquoted entry:
abcdsplits intoa,b,cdwith readingsfoo1,foo2,foo3and part-of-speechbar, and aJapanesePartOfSpeechStopFilterwith stop tagbarremoves all 3 tokens. - You get the right terms and readings, but all 3 tokens report the part-of-speech
"bar", quotes included, and the stop filter removes 0 of 3. No error. - The cause is one line of
CSVUtil.parse: a field that ends at a comma goes throughunQuoteUnEscape(CSVUtil.java:56), the last field is added as is (:65). The part-of-speech is the last of the 4 fields. On its own,parse("\"p,q\",\"p,q\",\"p,q\"")returns[p,q, p,q, "p,q"].
Kuromoji users whose custom user dictionary quotes the part-of-speech, because the tag contains a comma or because a CSV tool quoted every field, on every release since 3.6.0, and direct callers of CSVUtil.parse. Tags get literal quotes silently; exact-tag logic such as part-of-speech stop filters stops matching. Rare; the shipped system dictionary has no quotes.
Mechanism, terms and numbers564 words
CSVUtil (public, in the exported package org.apache.lucene.analysis.util of analysis-common) is Lucene's "Utility class for parsing CSV text". Its parse splits a line at commas outside quotes and decodes each field that ends at such a comma (enclosing quotes removed, "" turned into "), but adds the last field without decoding. The same quoted value therefore decodes in the first or a middle position and keeps its quotes in the last: parse("\"p,q\",\"p,q\",\"p,q\"") returns [p,q, p,q, "p,q"], and parse does not decode its own encoder's output (quoteEscape) when it is the last field.
Kuromoji's UserDictionary.open, used by JapaneseTokenizerFactory's userDictionary option, reads every line with parse and takes the part-of-speech from the fourth and last field. An entry written with every field quoted gives tokens whose part-of-speech is "bar" with the quotes, while surface, segmentation and readings decode; a JapanesePartOfSpeechStopFilter with stop tag bar then removes nothing. A part-of-speech that contains a comma has to be quoted, so it keeps its quotes too; the only way around it is an undocumented trick, a trailing comma (an empty fifth field, which UserDictionary ignores). The line dates from the 2012 Kuromoji donation; every release from 3.6.0 to 10.6.0 and main is affected. The fix is one line.
CSVUtil: "Utility class for parsing CSV text" (CSVUtil.java:23), a public final class in the exported packageorg.apache.lucene.analysis.util(analysis-commonmodule-info.java:88), not marked internal.parseis "Parse CSV line", "@param line line containing csv-encoded data", "@return Array of values" (:35-40);quoteEscapeis "Quote and escape input value for CSV" (:94) and wraps any value that holds a comma in quotes (:101-103).- Kuromoji user dictionary: a text file of lines
surface,segmentation,readings,part-of-speech(layout commentUserDictionary.java:58; the test fileuserdict.txt), loaded byUserDictionary.open(Reader)or theuserDictionaryoption ofJapaneseTokenizerFactory(JapaneseTokenizerFactory.java:143-155). Its entries override the system dictionary for matching text.
parsewalks the line once and togglesinsideQuoteat every"(CSVUtil.java:46-52).- At a comma outside quotes it decodes the field:
value = unQuoteUnEscape(value); result.add(value);(:54-58).unQuoteUnEscapestrips enclosing quotes when the field matches^"([^"]+)"$and turns""into"(:75-92). - After the loop it adds the rest of the line:
result.add(sb.toString());(:65). That is the last field, never decoded. UserDictionary.opencallsCSVUtil.parse(line)for each line (UserDictionary.java:67) and storesString pos = values[3];(:100), the last of the 4 fields, next to each segment's reading (:130).getPartOfSpeechreturns it unchanged.JapanesePartOfSpeechStopFilterkeeps a token unlessstopTags.contains(pos)(:44), an exact match, so"bar"does not matchbar.
| input | expected | stock (main, 10.5.2, 9.12.3) | with the fix |
|---|---|---|---|
parse("\"p,q\",\"p,q\",\"p,q\"") | [p,q, p,q, p,q] | [p,q, p,q, "p,q"] | [p,q, p,q, p,q] |
parse("\"x\",\"bar\"") | [x, bar] | [x, "bar"] | [x, bar] |
parse("x," + quoteEscape("To be, or not to be ...")) | [x, To be, or not to be ...] | the value with its quotes | [x, To be, or not to be ...] |
control: parse(quoteEscape("To be, or not to be ...") + ",x") | decoded | decoded | decoded |
user dictionary "abcd","a b cd","foo1 foo2 foo3","bar", text abcd | a/foo1/bar, b/foo2/bar, cd/foo3/bar | a/foo1/"bar", b/foo2/"bar", cd/foo3/"bar" | as expected |
same entry, stop tag bar | 0 tokens kept | 3 tokens kept | 0 tokens kept |
| control: the entry unquoted | bar; 0 kept with the stop tag | same | same |
Exposure and likelihood355 words
- Who is exposed. (a) Kuromoji users with a custom user dictionary (opt-in:
JapaneseTokenizerFactory'suserDictionaryoption,UserDictionary.open, or aJapaneseAnalyzerbuilt with one) whose part-of-speech field is quoted. (b) Any direct caller of the publicCSVUtil.parsewhose data quotes the last field. - What the damage looks like. The part-of-speech tag carries literal quotes, with no error. Segmentation, readings and matching are right, so tokenization looks fine. Anything that compares tags exactly sees a different tag:
JapanesePartOfSpeechStopFilter(also insideJapaneseAnalyzer,JapaneseAnalyzer.java:112) keeps tokens it should drop, and code readingPartOfSpeechAttributegets"bar". - Only an undocumented workaround. A part-of-speech that contains a comma has to be quoted (unquoted, the comma splits the field), and as the last field it keeps its quotes (
"tagA,tagB"comes back with its quotes). The one way around it is a trailing comma: the quoted part-of-speech is then followed by a comma, soparsedecodes it, andUserDictionaryignores the empty fifth field (it reads onlyvalues[0..3]and checks no field count,UserDictionary.java:95-100). On stock main,abcd,a b cd,foo1 foo2 foo3,"tagA,tagB",gives the part-of-speechtagA,tagB, and the stop tagtagA,tagBremoves all 3 tokens. Nothing documents this, and it works only because of the same position rule. - How likely. Rare: the upstream test dictionary leaves the last field unquoted, the system dictionary shipped in the kuromoji jar has no quote character in any field, and nobody has reported it since 2012.
- Scale. One line reproduces it; assertions on and off behave the same; nothing depends on index size or concurrency.
- Not affected. The kuromoji system dictionary (an enumeration of all 392,127 words on main finds no quote character in any field); nori's runtime user dictionary, which splits on whitespace. The kuromoji and nori
TokenInfoDictionaryBuilderalso callparseand would be affected only by a custom dictionary source that quotes its last field; kuromoji'swritePosDictre-parsesquoteEscapeoutput whose last part is the inflection form, so it is wrong when that field holds a comma or a quote;UnknownDictionaryBuilderappends,*,*before parsing, so the source's last field is decoded. None of these builder paths was run.
The test shows that CSVUtil.parse unquotes every quoted field except the last one of the line: parse("\"x\",\"bar\"") decodes the first field but returns the last one raw.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.util;

import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCSVUtilQuotedLastField extends LuceneTestCase {

  public void testQuotedLastFieldIsUnquoted() {
    // expected [x, bar]; actual [x, "bar"]: the first field is unquoted, the last keeps its quotes
    assertArrayEquals(new String[] {"x", "bar"}, CSVUtil.parse("\"x\",\"bar\""));
  }
}
# in a copy of this finding's repro folder (repro/LFV-895/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.util.TestCSVUtilQuotedLastField
- Expected vs actual
- Expected
[x, bar]; actual[x, "bar"](the last field keeps its quotes), with-eaand-da.
More files, environment, full output50 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => arrays first differed at element [1]; expected:<[bar]> but was:<["bar"]>
       org.junit.internal.ComparisonCriteria.arrayEquals(ComparisonCriteria.java:78)
       org.junit.internal.ComparisonCriteria.arrayEquals(ComparisonCriteria.java:28)
       org.junit.Assert.internalArrayEquals(Assert.java:534)
       org.junit.Assert.assertArrayEquals(Assert.java:285)
       [...]
     Caused by: org.junit.ComparisonFailure: expected:<[bar]> but was:<["bar"]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
       org.junit.internal.ExactComparisonCriteria.assertElementsEqual(ExactComparisonCriteria.java:8)
       org.junit.internal.ComparisonCriteria.arrayEquals(ComparisonCriteria.java:76)
[...]parsealready decodes every quoted field that a comma follows (CSVUtil.java:56); no CSV dialect decodes by position, and nothing documents or tests the exception.- The javadoc promises "csv-encoded data";
parsedoes not decodequoteEscape's own output as the last field. - A committer suggested the format is meant to be "CSV with '#' comments"; their example quotes the last field (LUCENE-7635).
The full argument306 words
- Contract. "Utility class for parsing CSV text" (
CSVUtil.java:23);parse: "@param line line containing csv-encoded data", "@return Array of values" (:35-40);quoteEscape: "Quote and escape input value for CSV" (:94), which wraps values with a comma in quotes. No javadoc literally promises RFC 4180 orparse(quoteEscape(v)) == v; the case rests on the class's own decoding of every other field. - Tests.
TestCSVUtiltests onlyquoteEscape(3 tests, added by SOLR-9413). Every in-treeparsecall in tests uses unquoted lines (kuromoji and noriTestUnknownDictionary), and the kuromojiuserdict.txthas no quote characters. Nothing pins the quotes on the last field. - History. The line came with the 2012 Kuromoji donation and never changed: six later commits edited
parse, none touched it, and no branch ever had the fix. The comparable one-lineCSVUtilomission (quoteEscapediscarding the result ofString.replace) was reported (#6913 / LUCENE-5851) and fixed as a bug (SOLR-9413). - Committers on the format. In LUCENE-7635 (#8686, 2017) hossman wrote that "it seems like the intent of the UserDict format is to be \"CSV with '#' comments\"", with the example line
"quoted#sharp",other,"quoted,stuff", whose last field is quoted. It was a tentative reading in a discussion about '#' comments and says nothing about how the last field is decoded. In LUCENE-8596 (#9642) msokolov called a user-dictionary parsing limitation "a real problem we should fix" and fixed it on main with a CHANGES note. - What is not claimed. Quote-only values (
quoteEscapewrites them without enclosing quotes, which is not valid RFC 4180) and empty quoted fields: in CSVUtil's dialect""isquoteEscape's encoding of one quote, which RFC 4180 reads as an empty field. A quoted field that also holds a quote keeps its enclosing quotes in every position; that is the sibling defect LFV-889.
The devil's-advocate check182 words
The strongest "intended" case (rated moderate by the intended-lens review from another model family; also argued by the devil's-advocate verifier): CSVUtil began in 2012 as a narrow helper for MeCab dictionary lines, whose last field is never quoted in stock data; its javadocs are one line each and claim no RFC 4180; the raw append survived 14 years, a nori copy and two package moves without a report; the separate atilika/kuromoji project, by the original Kuromoji authors, has the same omission and its tests quote only non-last fields; and a change may break callers that rely on the raw last field.
Why it fails: the class itself decodes quoted fields in every other position, so a narrow dialect cannot explain a rule that depends only on position. Age and the inherited copy show the case was never exercised, not that it was meant: nothing documents, tests or comments on keeping the quotes, and no Lucene code relies on the raw last field. Compatibility decides how a fix ships (main, with a CHANGES entry, as LUCENE-8596 did), not whether this is a bug.
Recommended Decode the last field with unQuoteUnEscape
Decode the last field like every other one: result.add(unQuoteUnEscape(sb.toString())); at CSVUtil.java:65. The repro, TestCSVUtil, the kuromoji and nori suites and all 1,912 analysis-common tests pass. It changes parsed values of existing lines whose last field is quoted, so target main with a CHANGES entry.
-    result.add(sb.toString());
+    result.add(unQuoteUnEscape(sb.toString()));
All options and trade-offs3 options · 864 words
Option A is the bug's own fix. Option B adds LFV-889's recommended parse-only fix for the separate unquote defect (a quoted field that also holds a quote, in any position); it was checked with the standalone runner only. Do not use the regex ^"(.*)"$ for LFV-889: it breaks the one-quote encoding "" that quoteEscape writes. Add the new tests (or their cases in TestCSVUtil and kuromoji's TestUserDictionary) with whichever is chosen.
Line 65 of CSVUtil.java gets the call that line 56 already makes for every comma-terminated field (+1/-1). The finder's fix.
-    result.add(sb.toString());
+    result.add(unQuoteUnEscape(sb.toString()));
Trade-offs
- The smallest change, and
parseno longer depends on position. - It changes the parsed value of lines whose last field is quoted (the quotes go) or holds a doubled quote: an unquoted
x,a""bnow givesa"b, asa""b,xalready gives in the first position. Kuromoji part-of-speech tags of such entries change; indexed terms change only where the tag decides something (a part-of-speech stop filter, or code that turns tags into terms), and those fields need a reindex. Main with a CHANGES entry, as LUCENE-8596 did; a backport is debatable. - With A,
x,""gives[x, "], the one quote that"",xalready gives in the first position: in CSVUtil's dialect""is howquoteEscapewrites one quote. A leaves the sibling LFV-889: a quoted field that also holds a quote keeps its enclosing quotes in every position (x,"say ""hi"""gives[x, "say "hi""]), and LFV-889's tests still fail 4 of 9. In the finder's bounded model with A, the round-trip law fails only for values with both a comma and a quote (10,110 of 35,140 field lists, down from 26,700).
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: both new tests fail on stock (3 of 3 and 2 of 3, assertions on and off) and pass with the fix;org.apache.lucene.analysis.util.*(9 suites, 35 tests,TestCSVUtilincluded) plus the whole kuromoji (31 suites, 198 tests) and nori (13 suites, 87 tests) suites: 320 tests, 0 failures, 11 skipped, with assertions on (seed 5EED0895) and off (seed 5EED0896); the whole:lucene:analysis:common:test: 340 suites, 1,912 tests, 0 failures, 18 skipped;checkGoogleJavaFormatpasses for both modules. - Standalone runner with the fix shadowed: 3 of 3 and 3 of 3 pass with
-eaand-da; earlier the finder's, the independent reproducer's, the cross-model reviewer's and the devil's advocate's tests passed with the same line. An independent fact check repeated the 320-test set with new seeds in both modes and the format check, with the same result.
Option A plus LFV-889's recommended parse-only change to unQuoteUnEscape (its independent reproducer's sketch): strip the enclosing quotes only when the field ends with a quote and begins with an odd run of quotes, then unescape. quoteEscape doubles every quote, so an unenclosed value has only even runs and "" stays one quote. Then x,"say ""hi""" gives [x, say "hi"], while x,"" and "",x keep the one-quote reading ([x, "], [", x]).
     // Unquote
     if (result.indexOf('\"') >= 0) {
-      Matcher m = QUOTE_REPLACE_PATTERN.matcher(original);
-      if (m.matches()) {
-        result = m.group(1);
+      // quoteEscape doubles every quote, so an unenclosed value has only even-length quote runs;
+      // an enclosed value starts with an odd-length run (the enclosing quote plus doubled quotes).
+      int lead = 0;
+      while (lead < result.length() && result.charAt(lead) == QUOTE) {
+        lead++;
+      }
+      if (result.length() >= 2
+          && (lead & 1) == 1
+          && result.charAt(result.length() - 1) == QUOTE) {
+        result = result.substring(1, result.length() - 1);
       }
...
-    result.add(sb.toString());
+    result.add(unQuoteUnEscape(sb.toString()));
Trade-offs
It changes the output for quoted fields that hold a quote, in every position, so it needs its own CHANGES note and is LFV-889's decision too. The sketch leaves QUOTE_REPLACE_PATTERN and the Matcher import unused. Do not use the finder's first sketch for LFV-889, the regex ^"(.*)"$, instead: it reads "" as an empty field, so "",x gives [, x] instead of [", x], and the round-trip law then fails for 3,578 field lists, 2,316 of them in non-last fields that pass on stock; LFV-889's judge says it must not be proposed.
What the checks validated
Standalone runner on a9779ef3c193 with the combined source shadowed (not gradle, not the module suites, not format-checked): the brief's tests pass 3 of 3 and 3 of 3 with -ea and -da; LFV-889's own tests pass 9 of 9 (4 of 9 fail on stock and with A alone); the finder's bounded model finds 0 of 35,140 round-trip mismatches and 1,713 of 18,304 RFC 4180 reference mismatches, all of the quoted-empty or escaped-quote shape, where RFC 4180 reads "" differently from CSVUtil's dialect.
Say so in the parse javadoc. Not run.
Trade-offs
Changes no output, but documents a position-dependent rule that no CSV writer produces, leaves a part-of-speech with a comma decodable only through the trailing-comma trick, and contradicts quoteEscape's own output.
Search servers and applications that let operators upload a kuromoji user dictionary inherit the wrong tags; a CSV export that quotes every field is the likely trigger.
A bounded-exhaustive comparison of the real CSVUtil with an RFC 4180 reference parser (all 87,381 lines of up to 8 symbols) and with its own round-trip law (35,140 field lists) showed quoted fields decoded before a comma but returned raw at the end of the line. Public-API tests then reproduced it.
The method in full264 words
Method: bounded-exhaustive translation validation on the stock main jars (the study's "semi-formal" tier). A hunt unit, a sweep of public analysis-common APIs that no earlier hunt had named, 2026-10-28.
- Reference check: all 87,381 lines of up to 8 symbols over {a, comma, quote, U+10400} (18,304 valid under RFC 4180) were parsed by the stock
CSVUtiland by a reference parser. All 5,811 mismatches are quoted fields. In the last field the stock code returns the field raw: plain 2,814 (this bug alone), empty 449 and escaped quote 962. The empty and escaped-quote shapes also mismatch in non-last fields (1,122 and 464), where RFC 4180 and CSVUtil's dialect read""differently or the sibling LFV-889 applies, so only the plain count is this bug's. - Round-trip check:
parse(join(quoteEscape(f_i))) == fieldsover 35,140 field lists. The classes "last field with a comma" (8,295) and "last field with a comma and a quote" (4,206, which also needs LFV-889's fix) come from this bug; the last-field quote-only class (8,295) comes fromquoteEscape's unenclosed encoding of quote-only values and is not claimed (the cross-model reviewer's correction). - Re-run for this doc with the fixes shadowed: option A alone leaves only the round-trip failures of values with both a comma and a quote (10,110, LFV-889) and reference mismatches of the same two shapes in every position (2,997); A plus LFV-889's parse-only fix leaves 0 round-trip failures and 1,713 reference mismatches, all where RFC 4180 reads
""differently from CSVUtil's dialect. - Then an AI finder wrote the public-API JUnits, and independent AI tools reproduced, reviewed, judged and audited it (see the checks).
No prior report found (search of 2026-10-28): 147 logged queries over GitHub issues, PRs and commits, downstream projects, mailing lists, JIRA and the web, plus all 410 open PRs. Related items concern other CSVUtil and user-dictionary defects.
Searches4 searches
Nothing reports that CSVUtil.parse leaves a quoted last field quoted, or that a quoted kuromoji part-of-speech keeps its quotes. Upstream main c5ab3e57b9ba, branch_10x and branch_10_6 still have the line; the last commit to CSVUtil.java is #16056 (2026-05-14).
Related, not the same bug: #8686 (LUCENE-7635; a 2017 comment uses a quoted last field as an example without noticing the defect), #9642 (LUCENE-8596, '#' in user dictionaries), #6569 / #6913 / SOLR-9413 (quoteEscape ignored the String.replace result; fixed 2016), #4770 (LUCENE-3696, speed), #12389 / #12390 / #12773 / #12774 (the 2023 class move). The separate atilika/kuromoji project has the same omission in its own parser and no report of it either. The sibling regex defect LFV-889 has a partial overlap there (atilika/kuromoji fixed its copy of the regex in 2015); this bug has none.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, the old lucene-solr repository), commits | 2026-10-28 | two runs of a scripted prior-report search (16 issue/PR and 3 commit queries each: class and method names, unQuoteUnEscape, user dictionary and quotes, part-of-speech and commas, last field) and 31 manual searches | no report; the one high-overlap hit, #8686, is a different defect |
| Open PRs | 2026-10-28 | the changed files of all 410 open apache/lucene PRs; refreshed for the 37 updated since 2026-10-26 | only #16911 (decommissions branch_10x, deleting every file) lists CSVUtil.java or kuromoji UserDictionary.java |
| Mailing lists and JIRA | 2026-10-28 | 20 list queries per tool run plus 25 manual ones over dev@, java-user@, issues@ and Solr lists; JIRA LUCENE and SOLR | no report |
| Downstream repositories and the web | 2026-10-28 | Solr, Elasticsearch, Lucene.NET and atilika/kuromoji on GitHub, all of GitHub for "CSVUtil.parse"; 18 web searches, one in Japanese | no report; an Elasticsearch PR that calls CSVUtil.parse on user-dictionary rules does not discuss quoting |
Present since CSVUtil was added with the Kuromoji donation (cd372bdc8383, LUCENE-3305, 2012-01-12), first released in 3.6.0; the line never changed through two package moves. It reproduces on 15 releases from 3.6.0 to 10.5.2, 10.6.0 (branch_10_6 4ae946e5a9b9) and main; 3.5.0 has no CSVUtil.
Versions tested6 rows
Introduced by cd372bdc8383 "LUCENE-3305: add Kuromoji Japanese morphological analyzer" (svn trunk r1230748, 2012-01-12, committed by rmuir from the Kuromoji code donation, migrated as apache/lucene#4378; no PR in the svn era), backported to branch_3x as 8c9485fb6642 (2012-01-14). Six later commits edited parse (LUCENE-3696, LUCENE-4362, LUCENE-5512, LUCENE-9570, #12390, #16056); none touched the last-field line. The class lived in kuromoji (org.apache.lucene.analysis.ja.util) for 3.6.0-9.8.0, had a nori copy (org.apache.lucene.analysis.ko.util, dictionary builders only) in 7.4.0-9.8.0 that fails the same way, and moved to analysis-common (org.apache.lucene.analysis.util) in 9.9.0 (#12390 / #12774). All 126 release tags 3.6.0-10.5.2 in the history clone carry the unfixed line.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's tests fail 3 of 3 and 2 of 3 (gradle and standalone, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the brief's tests fail 3 of 3 and 2 of 3 with assertions on (10.5.2 also with assertions off, in the fact check); the finder's tests fail too |
branch_10_6 4ae946e5a9b9 | affected | the CSV probe and the finder's CSV test fail (no kuromoji jar in that jar set) |
| 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.4.0, 7.7.3, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 10.0.0 | affected | the version-independent CSV probe fails (4 of 4 checks keep the quotes, controls pass); the kuromoji probe fails on all but 3.6.2 and 7.4.0 (not run); 7.4.0-9.8.0 also the nori copy |
| 3.5.0 | API absent | no CSVUtil and no kuromoji module |
| main + fix | fixed | all tests and probes pass |
An independent reproducer, a devil's advocate, an adjudication and reviews by another model family (which ran their own tests) all found it real; the adjudication confirmed it with high confidence. A registry re-run, an audit, this doc's own runs and an independent fact check reproduced it with new seeds.
Checks and verdicts451 words
Every check wrote or ran its own test against the stock jars, with assertions on and off unless noted.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnits fail on main (-ea, -da), 10.5.2 and 9.12.3: CSV 2 of 2, kuromoji 1 of 1; on branch_10_6 the CSV test fails 2 of 2 (the kuromoji test was not run there). The CSV test still fails 2 of 2 with the sibling's regex sketch applied; both pass with the one-line fix. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6) ran its own JUnit on main ea57360912ed (analysis sources identical to a9779ef3c193) and 10.5.2; root cause and fix agree; it corrected the round-trip claim (quote-only values dropped). |
| Independent reproducer | real | Own JUnits fail 4 of 5 (CSV) and 1 of 2 (kuromoji) on main, 10.5.2 and 9.12.3; the controls pass; with the fix its tests, upstream TestCSVUtil and kuromoji TestUnknownDictionary pass. |
| Cross-model review, intended lens | real (high) | OpenAI GPT-5.6: the intended-behaviour argument is moderate and rejected; its own tests fail with assertions on, on main (CSV and kuromoji), 10.5.2 and 9.12.3 (CSV), and separate re-runs fail on main with assertions off too; they pass with the fix. |
| Devil's advocate | real | Own 6-test JUnit fails 3 of 6 on main and 10.5.2, including the stop filter removing nothing; the controls pass; 6 of 6 with the fix; found the LUCENE-7635 comment and the external parser. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's tests: 4 of 5 and 1 of 2 fail, 5 of 5 pass with the fix. |
| security assessment | not security-sensitive | Only dictionary or configuration text reaches the parser, which SECURITY.md treats as trusted; the effect is a wrong string value. |
| registry re-run and audit | keep | The finder's tests fail again with new seeds (-ea and -da); an own probe shows the same value decoded first and middle, raw last; all pass with the fix. |
| this doc's runs | reproduced; fix validated | New tests through gradle and the standalone runner on main, 10.5.2 and 9.12.3; the fix validated against the module suites. |
| fact checks of this doc | reproduced; wording errors fixed | Independent fact checks (one by another model family, OpenAI GPT-5.6) re-read the claims against the code. One re-ran the doc's gradle command (assertions on and off, plus a new seed) and the standalone runner with new seeds on main, 10.5.2 and 9.12.3: same failures; option A passed the 320-test set again. They found the trailing-comma workaround and a wrong option B (the regex that breaks the one-quote encoding); both are fixed in this version. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 506 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,403 words
- Registry title
- CSVUtil.parse decodes every quoted field except the last one of the line, so a quoted last field (for example the part-of-speech of a kuromoji user-dictionary entry) keeps its quote characters
- Area
- analysis-common / util CSVUtil (CSV line parsing for the kuromoji user dictionary and the kuromoji/nori dictionary builders)
- Priority
- Low, rank 519: A quoted last field in the opt-in kuromoji user dictionary keeps its quotes but only corrupts the part-of-speech tag on rare input.
- Impact class
- silent wrong results
- Impact note
- Hits direct callers of the public CSVUtil.parse (exported package org.apache.lucene.analysis.util) and kuromoji users whose user dictionary (UserDictionary.open, or the JapaneseTokenizerFactory userDictionary resource) quotes the last, part-of-speech field, for example because the part-of-speech contains a comma (which can only be written quoted) or because a CSV tool quoted every field: with otherwise default settings, -ea and -da, and no scale, every token of such an entry reports the part-of-speech with literal quote characters ("bar" with the quotes instead of bar) and no error, so exact-tag consumers such as JapanesePartOfSpeechStopFilter do not match it (the intended-behaviour check ran this); segmentation and readings are decoded correctly, the shipped dictionaries do not quote the last field, and nori's runtime UserDictionary does not use CSVUtil.
- Summary
- You parse a CSV line whose last field is quoted, for example CSVUtil.parse("x," + CSVUtil.quoteEscape("To be, or not to be")), or load a kuromoji user dictionary written with every field quoted, and expect the quoted value to be decoded the same way as in any other position, as parse does for every field followed by a comma. Instead the last field comes back raw, enclosing quotes and doubled inner quotes included: parse("\"a,b\",\"c,d\"") returns [a,b, "c,d"], and the dictionary line "abcd","a b cd","foo1 foo2 foo3","bar" yields tokens whose part-of-speech is "bar" with the quotes. The cause is one line: parse passes each comma-terminated field through unQuoteUnEscape (CSVUtil.java:56) but adds the final field as sb.toString() (:65).
- Introduced
- cd372bdc8383 (LUCENE-3305 'add Kuromoji Japanese morphological analyzer', committed by rmuir from the Kuromoji code donation, migrated as apache/lucene#4378; svn trunk r1230748, svn era with no GitHub PR; branch_3x backport 8c9485fb6642, r1231536; first in the repository on the svn feature branch lucene3305 as bee8224c049c, which is not an ancestor of main) [read: git blame -w -M -C -C -C on main attributes CSVUtil.java:65 to cd372bdc8383; git log -L on parse lists six later changes (354a3be78f3 LUCENE-3696, ded01621a42 LUCENE-4362, 3b67b174932 LUCENE-5512, 7f8b7ffbcad LUCENE-9570, 30db2170484 #12390, dbf0d1426f1 #16056), none of which touches the last-field append; git log --all -G'unQuoteUnEscape\(sb' finds no branch that ever had the fix; exec: 3.5.0 has no CSVUtil, 3.6.0 fails] (2012-01-12 (trunk commit cd372bdc8383, author date = commit date, svn era); 2012-01-14 (branch_3x backport 8c9485fb6642); 2012-01-03 (feature branch bee8224c049c))
- First affected version
- 3.6.0 [exec] (first release with CSVUtil, then org.apache.lucene.analysis.ja.util.CSVUtil in the kuromoji module; 3.5.0 [exec] has no CSVUtil and no kuromoji module, so there is no earlier unaffected release; on the trunk line 4.0.0-alpha, 4.0.0 executed)
- Affected versions
- every release from 3.6.0 to 10.5.2, branch_10_6 4ae946e5a9b9 (10.6.0, released 2026-10-29) and main a9779ef3c193; not fixed upstream. [read] all 126 release tags 3.6.0-10.5.2 in the full-history clone carry the unfixed line in every CSVUtil copy (8.9.0-8.11.4 are not tagged there; 8.11.4 was executed from release jars); upstream main c5ab3e57b9ba, branch_10x and branch_10_6 still have it (the last CSVUtil.java commit is #16056, author date = commit date 2026-05-14). [exec] the follow-up's portable main() probes (CSVUtil: 4 of 4 bug checks keep the quotes on the last field, 2 controls pass; kuromoji: an all-quoted user-dictionary line gives the part-of-speech "bar" with quotes on every token, the unquoted control gives bar) fail on 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.4.0, 7.7.3, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 (CSVUtil only) and main, and pass with the fix shadowed on main; from 7.4.0 to 9.8.0 the nori copy org.apache.lucene.analysis.ko.util.CSVUtil (used only by nori's dictionary builders) fails its 3 checks too. The finder's JUnits fail on main (-ea and -da), branch_10_6, 10.5.2, 10.0.0, 9.12.3 and 9.9.0 (they do not compile on 8.11.4, which predates the analysis.util package and the tests.* framework); the independent reproduction's fail on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's on main (-ea and -da) and 10.5.2. The class lived in kuromoji (ja.util) for 3.6.0-9.8.0 and in analysis-common (org.apache.lucene.analysis.util) from 9.9.0 (#12390/#12774), each move carrying the line unchanged.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-28, read-only; refreshed in the registration check): two scripted prior-report searches (each 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list and 4 JIRA queries plus web; 370 and 61 distinct hits, 1 and 0 rated high by keyword overlap, the high one #8686, read in full, a different defect) and 45 manual queries (147 in all), plus the finder's run (44 queries, 3,517 hits) and the independent reproduction's, the intended-behaviour check's and the adjudication's searches. No issue, PR, review comment, commit message, mailing-list post, JIRA entry, downstream report or web page says that CSVUtil.parse leaves a quoted last field quoted, or that a quoted kuromoji user-dictionary part-of-speech keeps its quotes. Closest items, none the same bug: #8686 (LUCENE-7635, '#' in a user dictionary; hossman's 2017 comment uses a line whose last field is quoted as an example and does not notice the defect), #9642 (LUCENE-8596, '#' handling fix, main only), #6569 (LUCENE-5506, open) and #6913 (LUCENE-5851) with SOLR-9413 (quoteEscape ignored the String.replace result; fixed 2016), #4770 (LUCENE-3696, build speed), #12389/#12390/#12773/#12774 (the 2023 class move). The predecessor project atilika/kuromoji's DictionaryEntryLineParser.parseLine still appends its last field raw (the same omission, not reported there either). Not fixed: CSVUtil.java:65 is unchanged on upstream main c5ab3e57b9ba (head, author date 2026-10-28), branch_10x and branch_10_6; the last commits to CSVUtil.java and to kuromoji UserDictionary.java are #16056 (dbf0d1426f13, author date = commit date 2026-05-14). Of all 410 open apache/lucene PRs only #16911 (decommission of branch_10x, which deletes the whole tree) lists CSVUtil.java; refresh: the file lists of all 37 open PRs updated since 2026-10-26 (3,233 file entries) show only #16911 touching CSVUtil.java, TestCSVUtil.java or kuromoji UserDictionary.java (all three 'removed'), and no apache/lucene issue or PR created since 2026-10-26 mentions kuromoji or CSV. Gaps: GitHub search returns at most 50 results per query; private reports are not searchable.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-28) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars (the brief's tests); version-independentmain()probes on 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.4.0, 7.7.3, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.5.2, branch_10_64ae946e5a9b9and main (follow-up). The fix was validated with gradle ona9779ef3c193. Upstream mainc5ab3e57b9bahas the sameCSVUtil.java(read, not executed).
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/util/CSVUtil.java:23 (class javadoc), :29 (QUOTE_REPLACE_PATTERN), :35-40 (parse javadoc), :54-57 (comma-terminated fields unquoted), :65 (last field added raw), :75-92 (unQuoteUnEscape), :94-105 (quoteEscape)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:52-75 (open), :58 (layout comment 'text, segmentation, readings, POS'), :67 (CSVUtil.parse per line), :100 (pos = values[3])lucene/analysis/common/src/java/module-info.java:88 (exports org.apache.lucene.analysis.util)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/util/CSVUtil.java:23, (at a9779ef3c193) :29, :35-40, :46-52, :54-58, :65, :75-92, :94-105lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:52-76 (at a9779ef3c193) (open; :58 layout comment; :67 parse), :100 (pos = values[3]), :130lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserMorphData.java:58-59, (at a9779ef3c193) :91-110lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapanesePartOfSpeechStopFilter.java:36-45; (at a9779ef3c193) JapaneseTokenizerFactory.java:36-50, :143-155lucene/analysis/common/src/java/module-info.java:88 (at a9779ef3c193)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/userdict.txt (at a9779ef3c193) ('Silly entry')
- Who is affected
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:143-155; (at a9779ef3c193) JapaneseAnalyzer.java:56-57, :108-116lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:95-100; (at a9779ef3c193) ja/dict/TokenInfoDictionaryBuilder.java:73; ja/dict/UnknownDictionaryBuilder.java:66; ja/dict/TokenInfoDictionaryEntryWriter.java:76-84, :226; lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryBuilder.java:68; ko/dict/UnknownDictionaryBuilder.java:66; ko/dict/TokenInfoDictionaryEntryWriter.java:181-186
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/util/CSVUtil.java:23, (at a9779ef3c193) :35-40, :54-58, :65, :94-105lucene/analysis/common/src/test/org/apache/lucene/analysis/util/TestCSVUtil.java:25-50; (at a9779ef3c193) lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/dict/TestUnknownDictionary.java:41-55; lucene/CHANGES.txt:8993GitHub, read-only (2026-10-28): apache/lucene issue #8686 (hossman's comment, LUCENE-7635), issue #9642 (msokolov's comments, LUCENE-8596)
- Suggested fix
GitHub, read-only (2026-10-28): apache/lucene issue #9642 (msokolov: fix on main with CHANGES, no 8.x backport)
- TestCSVUtilQuotedLastField.java (JUnit test):
repro/LFV-895/src/org/apache/lucene/analysis/util/TestCSVUtilQuotedLastField.java(27 lines)
A light, step-by-step picture of the repro, made in parallel with this doc from executed runs on main a9779ef3c193 and the code.
assets/LFV-895/bug.png(506 KB)