LMDirichletSimilarity scores a hit by how much more often the term occurs in the document than in the whole field. Its smoothing parameter mu may be any finite value >= 0, and at exactly 0 the arithmetic breaks.
- Collection model. For each term,
LMDirichletSimilarityuses P, the term's share of all tokens in the field: P = (occurrences + 1) / (tokens + 1). A document scores above 0 when the term is more frequent in it (tf / dl) than P; otherwise it gets 0, as the class javadoc says. - mu is the Dirichlet smoothing amount (default 2000): how strongly a document's counts are pulled toward the collection model. Smaller mu means less smoothing. Both constructors accept any finite mu >= 0.
- The score of one hit is
log(1 + tf / (mu * P)) + log(mu / (dl + mu)), then clamped:score > 0 ? score : 0.
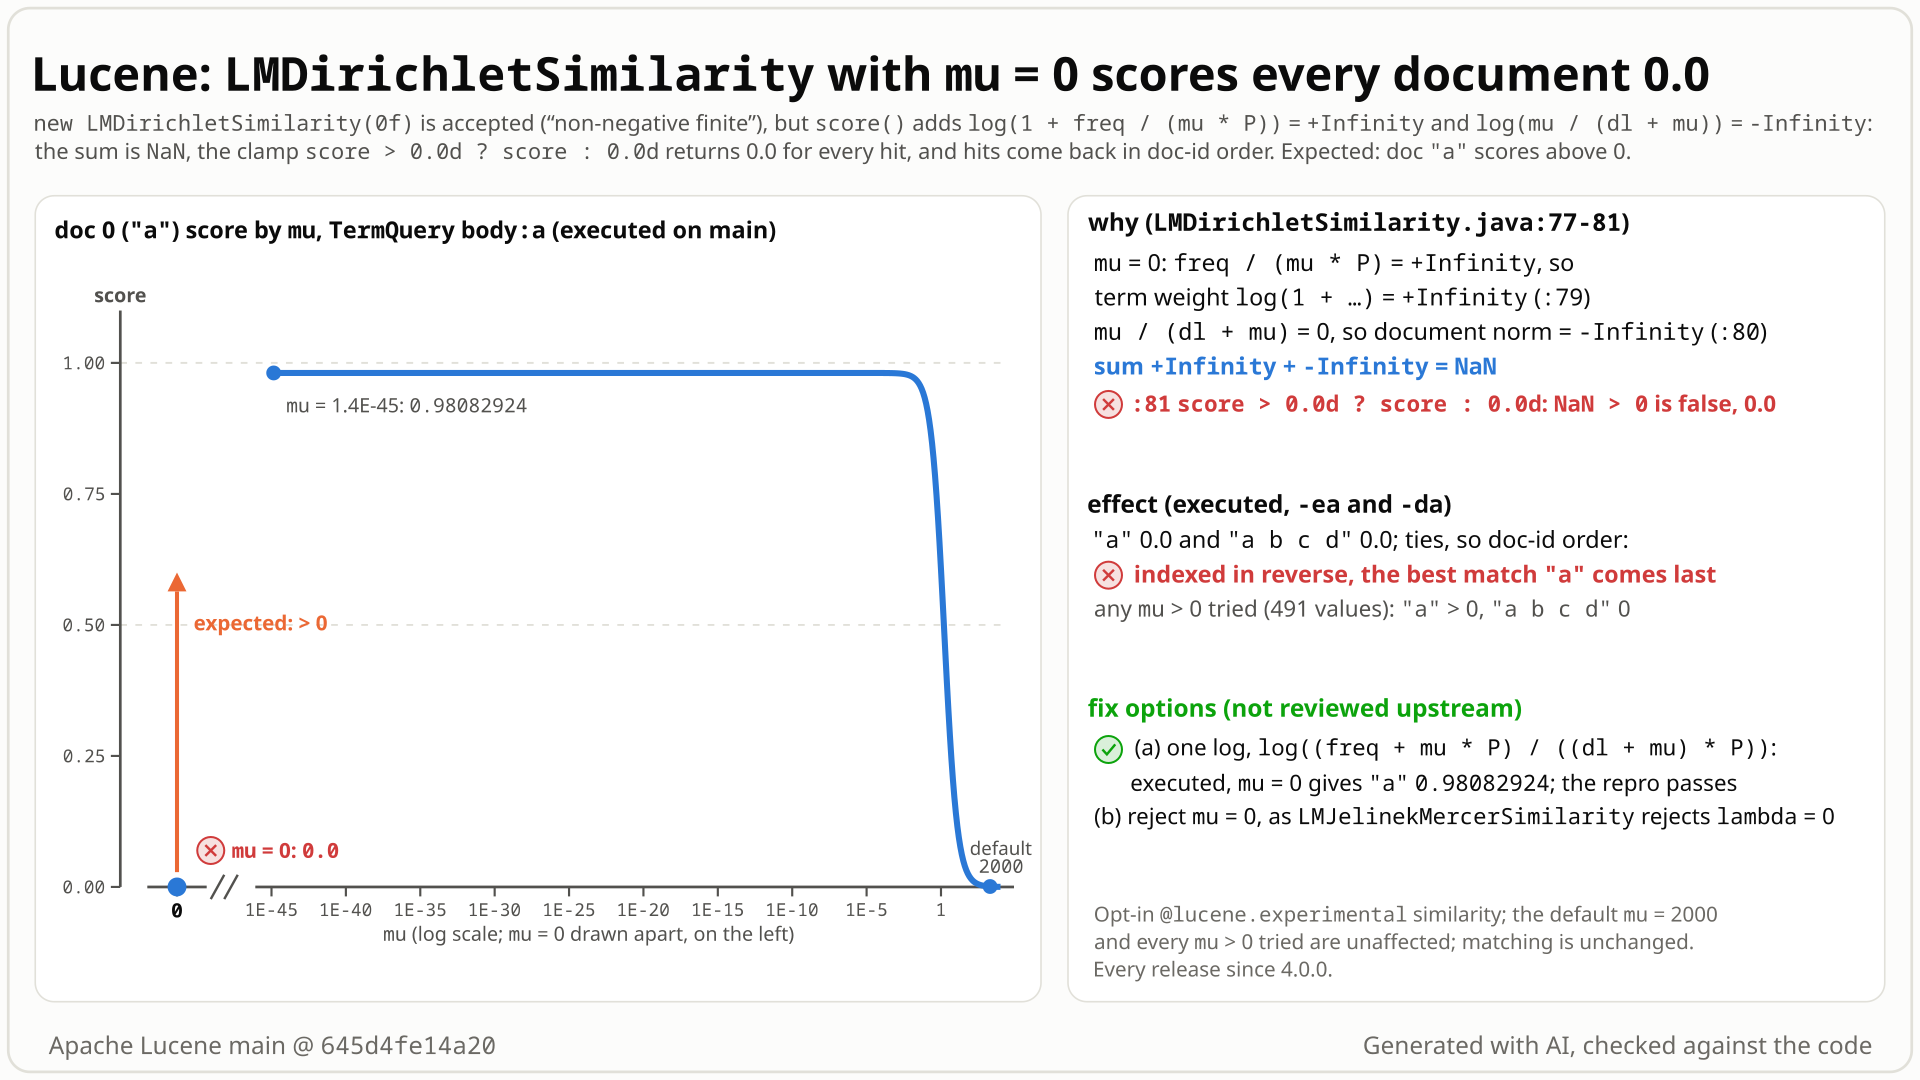
- You index three documents, "a", "a b c d" and "b c", with
new LMDirichletSimilarity(0f), which the constructor accepts ("must be a non-negative finite value"), and searchbody:a. - You expect doc "a" (every token is "a", far above the collection model P = 3/8) to score above 0, as it does for every positive mu tried: 8.3e-4 at the default 2000, 0.606 at mu = 1, 0.98083 at the smallest positive float.
- Instead both hits score 0.0. At mu = 0,
log(1 + 1 / (0 * P))is +Infinity andlog(0 / (1 + 0))is -Infinity; their sum is NaN, and the clampscore > 0 ? score : 0returns 0. - Every hit of every term ties at 0.0, so the default score-sorted search returns them in doc-id order: index the same documents in reverse and the best match "a" comes last. No error;
explain()shows Infinity and -Infinity under a 0.0 total.
Only applications that opt into the experimental LMDirichletSimilarity and set mu to exactly 0, for example to try the unsmoothed model or as the first point of a smoothing sweep; then every query on that field loses its ranking. Which documents match is unchanged; the default mu = 2000 and every positive mu in a realistic range work.
Mechanism, terms and numbers714 words
LMDirichletSimilarity validates its smoothing parameter and accepts any finite mu >= 0, and Lucene's own test uses mu = 0 as the "minimum value". At mu = 0, score() computes log(1 + freq / (mu * P)) + log(mu / (dl + mu)) = log(+Infinity) + log(0) = +Infinity + -Infinity = NaN, and the clamp score > 0.0d ? score : 0.0d, written for the paper's negative scores, turns that NaN into 0.0. Every hit of every term on the field then scores 0.0 and comes back in doc-id order (the default collector breaks ties by doc id), with no error; explain() shows Infinity = term weight and -Infinity = document norm under a 0.0 total. Every positive mu tried ranks normally, from Integer.MAX_VALUE (the largest value upstream's test uses) down to Float.MIN_VALUE, which gives the finite mu -> 0 limit log(tf / (dl * P)); only absurd values from about 1e17 up also zero the scores, through double rounding, a separate limit. The bug is as old as the class (added in 2011, first released in 4.0.0-ALPHA, 2012) and is in every release up to 10.6.0 and in main. It is opt-in and low-impact: an @lucene.experimental similarity at one boundary value. Two fixes were validated: compute the score as one log, which is finite at mu = 0 for any P > 0 (always so with the default collection model), or reject mu = 0 the way LMJelinekMercerSimilarity rejects lambda = 0.
LMDirichletSimilarity.java:76-82:
double score =
    stats.getBoost()
        * (Math.log(1 + freq / (mu * ((LMStats) stats).getCollectionProbability()))   // :79
            + Math.log(mu / (docLen + mu)));                                            // :80
return score > 0.0d ? score : 0.0d; // :81- mu = 0 is accepted. Both constructors throw only when mu is negative or not finite ("must be a non-negative finite value",
:49-52and:58-61); -1 and NaN are rejected, 0 is not. - First log (
:79). Every hit has freq > 0 and P > 0, sofreq / (0 * P)is +Infinity andlog(1 + Infinity)is +Infinity. - Second log (
:80).0 / (dl + 0)is 0 andlog(0)is -Infinity. - Sum. +Infinity + -Infinity is NaN (IEEE 754); the boost keeps it NaN.
- Clamp (
:81).NaN > 0.0dis false, so the method returns 0.0, for every hit of every term on the field. The clamp was written for the paper's negative scores (class javadoc,:30-32); it also swallows the NaN. - explain() (
:96-107,:117-125) prints the two logs as children,Infinity = term weight, computed as log(1 + freq /(mu * P))and-Infinity = document norm, computed as log(mu / (dl + mu)), under0.0 = score(LMDirichletSimilarity, freq=1.0).
For mu > 0 the two logs equal one log, log((freq + mu * P) / ((dl + mu) * P)). For P > 0 its denominator stays positive at mu = 0, where it equals log(freq / (dl * P)): for doc "a", log(1 / 0.375) = 0.98083. The smallest positive mu values already return that value (mu = 1e-10 and Float.MIN_VALUE both give 0.98082924, from 8.0.0, when score() moved to double). Only the order of operations fails at the boundary.
| mu | doc "a" (tf/dl = 1) | doc "a b c d" (tf/dl = 0.25, below P) |
|---|---|---|
| 2000 (default) | 8.325702E-4 | 0.0 |
| 1 | 0.6061358 | 0.0 |
| 0.001 | 0.9802047 | 0.0 |
Float.MIN_VALUE (1.4E-45) | 0.98082924 | 0.0 |
| 0 | 0.0 | 0.0 |
"a b c d" scores 0.0 at every mu: that is the documented clamp. Indexed in reverse ("b c", "a b c d", "a"), mu = 0 returns "a b c d" first and "a" last, both at 0.0, while Float.MIN_VALUE and 2000 return "a" first. A second probe with four documents shows the same for the three-argument constructor and for the disjunction a OR b.
A Z3 model checked the arithmetic for all legal inputs (the single-log identity and limit in real arithmetic, IEEE binary64 at mu = +0.0), and a bounded-exhaustive run of the stock jar found mu = 0 scoring 0 in 963,900 of 963,900 cases, 276,714 of them with a positive limit.
Exposure and likelihood260 words
- Who. Opt-in only: applications that choose
LMDirichletSimilarity(marked@lucene.experimental) and set mu to exactly 0. Then every query on that field scores every hit 0.0. - Downstream. Solr's
LMDirichletSimilarityFactoryreadsmufrom the schema and calls the constructor with no extra check, and Elasticsearch and OpenSearch pass a configured mu to the constructor too (read in their source, not run). There a configuration value of 0 is enough. - Silent. No exception, and the similarity logs nothing; the same documents match, only with score 0.0 (tied hits in doc-id order with the default collector). The one hint is explain()'s Infinity and -Infinity children.
- Not affected. The default mu = 2000 and, from 8.0.0 on, every positive mu in a realistic range: tried from
Float.MIN_VALUEup toInteger.MAX_VALUE, the largest value upstream's test uses (its comment:// we just limit the test to "reasonable" mu values but don't enforce this anywhere,TestLMDirichletSimilarity.java:37-40). Only absurd values from about 1e17 up zero the scores too: the arguments of the logs round to 1 in double (doc "a": 2.220446E-16 at 1e16, 0.0 at 1e17 and above), in the current and in the single-log form alike; that is a separate precision limit, not this bug. Before 8.0.0score()ran in float, so a tiny mu such asFloat.MIN_VALUEmisbehaved as well; mu = 1e-10 works in every release. - Nothing is written to the index. Scores are computed at search time, so a fixed jar corrects existing indexes.
- How likely: rare. No earlier report was found since the class first shipped in 4.0.0-ALPHA (2012).
One JUnit test on the public API: three documents, new LMDirichletSimilarity(0f), TermQuery body:a; it asserts that the top hit, doc "a", scores above 0. Deterministic, single thread, no use of random(); it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.similarities;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestLMDirichletMuZero extends LuceneTestCase {

  public void testMuZeroScoresBestMatchAboveZero() throws Exception {
    LMDirichletSimilarity sim = new LMDirichletSimilarity(0f);
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig(new StandardAnalyzer()).setSimilarity(sim))) {
        for (String text : new String[] {"a", "a b c d", "b c"}) {
          Document doc = new Document();
          doc.add(new TextField("body", text, Field.Store.NO));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        searcher.setSimilarity(sim);
        TopDocs td = searcher.search(new TermQuery(new Term("body", "a")), 10);
        // expected: doc "a" (tf/dl = 1, above the collection model P = 3/8) scores > 0; actual: 0.0
        assertTrue(
            "doc " + td.scoreDocs[0].doc + " scores " + td.scoreDocs[0].score + ", expected > 0",
            td.scoreDocs[0].score > 0f);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests TestLMDirichletMuZero -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- Doc "a" (tf/dl = 1, above P = 3/8) scores above 0, as it does for every positive mu tried (0.98082924 at the smallest positive float).
- Observed
AssertionError: doc 0 scores 0.0, expected > 0, with assertions on and off: both hits score 0.0.
More files, environment, full output275 words
Public API only; the test sits in org.apache.lucene.search.similarities next to TestLMDirichletSimilarity but needs no package access. It asserts only "above 0", not a value, because no document promises the mu -> 0 limit. It does not show the ranking effect (the top hit is "a" because it has the lowest doc id); the reversed-order probe in the full explanation does.
Regression test: this same test; it passes with fix A. With fix B the same setup becomes expectThrows(IllegalArgumentException.class, () -> new LMDirichletSimilarity(0f)).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with fix A: passes. Also fails on the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; pure Java double arithmetic, specified by IEEE 754) |
cp $REPRO/TestLMDirichletMuZero.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/similarities/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestLMDirichletMuZero -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, seed DEADBEEF, assertions on (off: the same failure)
TestLMDirichletMuZero > testMuZeroScoresBestMatchAboveZero FAILED
    java.lang.AssertionError: doc 0 scores 0.0, expected > 0
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:7533574B2D94FB58]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.search.similarities.TestLMDirichletMuZero.testMuZeroScoresBestMatchAboveZero(TestLMDirichletMuZero.java:52)
1 test completed, 1 failed

# explain(body:a, doc 0) at mu = 0, same index
0.0 = weight(body:a in 0) [LMDirichletSimilarity], result of:
  0.0 = score(LMDirichletSimilarity, freq=1.0), computed as boost * (term weight + document norm) from:
    0.0 = mu
    Infinity = term weight, computed as log(1 + freq /(mu * P)) from:
      1.0 = freq, number of occurrences of term in the document
      0.375 = P, probability that the current term is generated by the collection
    -Infinity = document norm, computed as log(mu / (dl + mu))
    1.0 = dl, length of field
0.375 = collection probability- The constructors accept 0 ("non-negative finite"), and Lucene's own test uses mu = 0 as its "minimum value".
- The javadoc gives 0 to documents with fewer occurrences than the collection model predicts; doc "a" has far more (tf/dl 1, P 3/8).
- The clamp was written for negative scores; #9058 asks to "issue IAE ... rather than silently screw up later".
The full argument340 words
- The input is accepted on purpose. The constructors define the legal range in their own message, "must be a non-negative finite value" (
LMDirichletSimilarity.java:49-52,:58-61), andTestLMDirichletSimilarity.java:30-31runs mu = 0 as the "minimum value". - The documented zero case is a different one.
LMDirichletSimilarity.java:30-32: "The formula as defined the paper assigns a negative score to documents that contain the term, but with fewer occurrences than predicted by the collection language model. The Lucene implementation returns {@code 0} for such documents." Doc "a" has more occurrences than predicted, and still gets 0. - No discussion found of what mu = 0 scores. The range came from a generic rule, Robert Muir on LUCENE-7997 (#9045, 2017): "for unbounded parameters (such as normalization c, smoothing parameter mu) we treat them the same as BM25's k1 and just ensure non-negative/finite in the range check, and test the range of 0..Integer.MAX_VALUE". No comment in that thread discusses the scores at mu = 0.
- The clamp was written for negative scores. On LUCENE-3357 (#4430, 2011) David Mark Nemeskey chose option "2. if (score < 0) return 0" for Dirichlet's negative scores, and in the same thread Robert Muir wrote "we should fix the Nan/Inf score problems". Writing it as
score > 0is what turns NaN into 0. - Upstream's stated rule opposes the outcome. Robert Muir on LUCENE-8010 (#9058, 2017): "We should issue IAE if a parameter is out of range rather than silently screw up later".
- Why upstream's own mu = 0 test passes.
BaseSimilarityTestCasechecks that scores are finite, non-negative, monotone and equal to explain(); a constant 0.0 passes all of them, andCheckHits.verifyExplanationdoes not compare a "computed as ... from:" explanation with the sum of its children (pattern atCheckHits.java:375;combined = valueat:494-496), so the Infinity and -Infinity children are never checked against the 0.0 total. - The sister class rejects its endpoint. The same LUCENE-7997 commit made
LMJelinekMercerSimilarityreject its no-smoothing value: "lambda must be in the range (0 .. 1]" (LMJelinekMercerSimilarity.java:53-54,:61-62).
The devil's-advocate check147 words
The strongest case for "intended": a Dirichlet prior needs mu > 0; mu = 0 is "no smoothing", outside the model the class is named after, and the paper's rank formula is undefined there. Upstream has tested mu = 0 since 2017, the clamp is documented, the class is experimental, and no complaint was found in the 15 years since the class was written (2011; first released 2012).
Why it fails: that argues for a different fix (reject mu = 0, as Jelinek-Mercer does), not for accepting the value and then silently scoring every hit 0. The passing test shows only that the test cannot see the problem. Rarity and the experimental tag lower the priority; they do not make the output intended. The cross-model reviews rated the argument "moderate" and agreed on the root cause and that the input is legal. Verdict: not intended, a defect.
Recommended Compute the score as one log, and explain that formula
Compute the score as one log, log((freq + mu * P) / ((dl + mu) * P)): equal to the two logs for mu > 0, and finite at mu = 0 whenever P > 0 (always so with the default model). The repro and 30 similarity test classes pass. Also validated: reject mu = 0, as LMJelinekMercerSimilarity rejects lambda = 0.
@Override
protected double score(BasicStats stats, double freq, double docLen) {
  double p = ((LMStats) stats).getCollectionProbability();
  // log(1 + freq / (mu * P)) + log(mu / (dl + mu)) written as a single log: it stays finite at
  // mu = 0, where the two terms are +Infinity and -Infinity and their sum is NaN
  double score = stats.getBoost() * Math.log((freq + mu * p) / ((docLen + mu) * p));
  return score > 0.0d ? score : 0.0d;
}
All options and trade-offs2 options · 879 words
Both options remove the silent all-zero ranking, and no document promises either; let upstream choose. Both were built and run with gradle in a scratch worktree of 645d4fe14a20 (OpenJDK 25.0.3, seed DEADBEEF, 2026-10-31).
In score() (LMDirichletSimilarity.java:76-82) replace the two logs by one (+7/-16 lines with explain()). In explain() the term weight and document norm children, Infinity and -Infinity at mu = 0, go; the leaves mu, freq, P and dl stay, and the description becomes computed as boost * log((freq + mu * P) / ((dl + mu) * P)) from:.
@Override
protected double score(BasicStats stats, double freq, double docLen) {
  double p = ((LMStats) stats).getCollectionProbability();
  // log(1 + freq / (mu * P)) + log(mu / (dl + mu)) written as a single log: it stays finite at
  // mu = 0, where the two terms are +Infinity and -Infinity and their sum is NaN
  double score = stats.getBoost() * Math.log((freq + mu * p) / ((docLen + mu) * p));
  return score > 0.0d ? score : 0.0d;
}
Trade-offs
- Same scores for mu > 0, up to rounding. A probe over every encodable document length (norm bytes 1-255), freq 1..min(dl, 200) and a grid of collection probabilities (6,715,472 cases per mu) compared both formulas, re-implemented in Java doubles with boost 1 and cast to float as
SimilarityBasedoes: at the default mu = 2000, 105 of 2,787,361 positive scores differ, all below 1e-8, where the two-log form cancels; at mu = 1 and 0.001, 48 and 68 differ, all below 1e-7; at mu = 1e6, 223 differ (all at scores up to 3.2e-4) and 3 near-zero scores cross the clamp. In this sampled grid the differences sit among near-zero scores; a query boost scales them, so this is not a proof that no ranking changes. - mu = 0 then scores
log(freq / (dl * P)), the mu -> 0 limit every tiny mu already gives (doc "a": 0.98082924). That value is a choice for upstream; no document promises it. - Finite at mu = 0 only for a finite P > 0. The default collection model always gives 0 < P <= 1 (
LMSimilarity.java:151).CollectionModelis a public interface whosecomputeProbabilitymay return any double; a custom model that returns P = 0 gets +Infinity at mu = 0 with the fix (stock: 0.0), the same +Infinity the stock code already gives it at every mu > 0 (run atFloat.MIN_VALUE, 1 and 2000). Requiring P > 0 would be a separate question for upstream. - explain() text changes for every mu; anything that parses "term weight" or "document norm" sees a difference.
- No API change. It keeps the accepted range and upstream's mu = 0 test case; whether it suits a bugfix release is upstream's call (some scores change slightly for mu > 0, and the explain() text changes). One
Math.logper hit instead of two (not benchmarked). - Variant (not run): keep the two logs and handle only
mu == 0aslog(freq / (docLen * p)): bit-identical for mu > 0, at the cost of a branch inscore()and inexplain().
What the checks validated
Scratch worktree of 645d4fe14a20, gradle, OpenJDK 25.0.3, seed DEADBEEF (2026-10-31):
- stock: the minimal test fails with assertions on and off;
- with the fix: the minimal test passes with assertions on and off;
org.apache.lucene.search.similarities.*andTestCombinedFieldQueryin core,TestCombinedFieldQueryin sandbox andTestSpanSimilarityin queries, 5 iterations each: 30 classes, 740 test runs, 0 failures;checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestfor core pass;- explain at mu = 0 on the repro index:
0.98082924 = score(LMDirichletSimilarity, freq=1.0), computed as boost * log((freq + mu * P) / ((dl + mu) * P)) from:with children mu 0.0, freq 1.0, P 0.375, dl 1.0; mu = 1e-3 and 2000 give the stock values 0.9802047 and 8.325702E-4; - earlier, the study's score-only version passed
TestLMDirichletSimilarityandTestSimilarityBase(145 tests, 5 iterations) and every verifier's repro.
Both constructors check mu <= 0 and say "must be a positive finite value"; TestLMDirichletSimilarity drops its mu = 0 case (its "minimum value" becomes Float.MIN_VALUE).
if (Float.isFinite(mu) == false || mu <= 0) {
  throw new IllegalArgumentException(
      "illegal mu value: " + mu + ", must be a positive finite value");
}
Trade-offs
- Loud instead of silent, in line with
LMJelinekMercerSimilarity(lambda in (0 .. 1]) and with the rule on #9058 ("issue IAE if a parameter is out of range rather than silently screw up later"). - A behaviour change: code or configurations that pass mu = 0 today get an exception when the similarity is built, so it may suit main (11.0) better than a 10.x bugfix release.
- Tiny positive mu stays accepted and keeps its scores; mu = 0 is the only value whose meaning changes.
- The regression test becomes
expectThrowson the constructor.
What the checks validated
Same worktree and command: the minimal test now stops at the constructor with IllegalArgumentException: illegal mu value: 0.0, must be a positive finite value; the same suites without the repro: 29 classes, 735 test runs, 0 failures. Format and lint checks were not run for this option.
Downstream, Solr's LMDirichletSimilarityFactory, Elasticsearch and OpenSearch pass a configured mu straight to the constructor (read in their source, not run), so there a mu = 0 setting in the schema or index settings alone triggers it.
An idea from a cross-model ideation round (an independent model from another family, OpenAI GPT-5.6) led to a probe of the real jar: mu = 0 scored 0.0, the next float up 1.0132525. A continuity sweep over 62 similarity parameter boundaries found it the only true jump; a Z3 model and an exhaustive check of 963,900 cases confirmed it.
The method in full225 words
Method: non-formal first signal (the hunt's tier for a finding whose first evidence is an executed single-case probe), confirmed by semi-formal and formal checks.
- Ideation. In a cross-model ideation round, an independent model from another family (OpenAI GPT-5.6) suggested checking the mu -> 0 limit of the Dirichlet similarity. Its probe on the stock main jar printed mu = 0 score 0.0 against 1.0132525 at the next positive float; it was first misread as clean because the probe exits 0, and caught on a re-run.
- Continuity sweep. A reference-free sweep of the real jar over 62 similarity families at the edges of their accepted parameter ranges (28,272 cases) isolated
LMDirichletSimilarityat mu = 0 as the only true discontinuity. - Z3 model. 9 obligations, 0 mismatches: the two-log form equals the single log for mu > 0, and mu = +0.0 gives NaN before the clamp and +0.0 after it for every legal input.
- Bounded-exhaustive check of the stock jar. mu = 0 scores 0 in 963,900 of 963,900 cases, 276,714 of them with a positive limit;
Float.MIN_VALUEequals the closed-form limit in all of them. - JUnit. A public-API test then failed 2 of 2 on main with assertions on and off; the minimal repro above keeps the substance of one of its checks (the best match must score above 0) on a smaller, 3-document index.
No prior report found: GitHub issues and PRs (including the JIRA archive), commits, mailing lists, downstream trackers and the web, searched on 2026-10-28 and again on 2026-10-31. Related items set the range, the clamp or the formula, but none discusses mu = 0.
Searches3 searches
- Closest items, none a report of this bug: #9045 (LUCENE-7997, made mu = 0 legal and tested it under a generic range rule, without discussing its scores); #9058 (LUCENE-8010, core similarities should not return NaN; the "issue IAE" remark); #4430 (LUCENE-3357) and #4033 (LUCENE-2959), where the clamp came from, for negative scores; #8530 (LUCENE-7478, writes the two logs as one, as a formula question); #8532 (LUCENE-7480, open, the missing-term component); elastic/elasticsearch#15345 and #15397 (all-zero scores at mu = 2500 on a tiny index, from the documented negative-score clamp) and #29015 (lists LMDirichletSimilarity among similarities that may return 0).
- Open PRs: javadoc PRs #16916 and #16949 are open in this package and do not touch this file.
- Limits: GitHub issue search does not index file paths (hence the path scans); list search is keyword-based; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive, apache/solr, apache/lucene-solr, Elasticsearch, OpenSearch, Anserini, Pyserini) | 2026-10-28 | five scripted prior-report search runs (40, 146, 319, 21 and 13 hits, 0 with high overlap), manual searches, and the changed files of all 410 open apache/lucene PRs and the 200 most recently updated closed ones | no report; only the related items listed above |
| Mailing lists (dev@, java-user@, issues@, commits@, Solr lists), LUCENE and SOLR JIRA, web | 2026-10-28 | tool and direct list queries, JIRA REST, web and Q&A-site searches | no report |
| GitHub, lists, JIRA, web (fresh round) | 2026-10-31 | four tool runs (151 queries), 26 manual apache/lucene and 14 downstream queries, 6 PR listings, path scans of 408 open and 200 recent closed PRs, 15 list, 5 JIRA and 11 web queries | no report; issues and PRs #16929-#16955 are not about Dirichlet; no PR changes score(); the newest commit on the file is still dab731175c8 (2024-10-04) |
As old as the class: added in 2011 (cfaf91c7398, LUCENE-2959) and first released in 4.0.0-ALPHA; the 2017 range check (LUCENE-7997) made mu = 0 explicitly legal. Executed on all 131 GA releases from 4.0.0 to 10.6.0 and on main: all affected.
Versions tested8 rows
Introduced by cfaf91c7398 (2011-09-11, "LUCENE-2959: add state of the art ranking to Lucene", svn r1169470; issue LUCENE-2959, mirrored as #4033), the merge of the flexscoring branch from JIRA patches, with no PR. Its first version of the class already sums the two logs and clamps with score > 0.0f ? score : 0.0f. On the branch, the two-log formula came first (8f73f80d1d7, LUCENE-3220 / #4293, 2011-07-15, where mu = 0 gave NaN), then the clamp (93bf76506b4, LUCENE-3357 / #4430, 2011-08-20), which turned that NaN into 0. Not a regression.
Later: 42717d5f4bb (LUCENE-7997 / #9045, 2017-10-24, first in 8.0.0) moved score() to double and added the "non-negative finite" check and the mu = 0 test case; dab731175c8 (#13845, 2024-10-04) added the discountOverlaps constructor with the same check and is the last commit on the file. Before 8.0.0 the constructors checked nothing, so mu = 0 was accepted without any stated range; it is explicitly legal input from 8.0.0 on. The file is the same blob at 10.5.2, 10.6.0, main 645d4fe14a20 and upstream main 2f424fd428d.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (gradle and standalone); passes with fix A |
| 10.6.0, 10.5.2 | affected | minimal test fails with assertions on and off (release jars, SHA-1 checked) |
9.12.3, 10.0.0, branch_10_6, main a9779ef3c193 | affected | the study's longer public-API tests fail 2 of 2 |
| 4.0.0 to 10.6.0 (all 131 GA releases) | affected | a main() port of the minimal test: mu = 0 scores 0.0 in 131 of 131; the control mu = 1e-10 gives 0.98082924 (the port gives StandardAnalyzer an explicit empty stop set, because before 8.0 its default stop set drops "a") |
| 4.0.0-ALPHA, 4.0.0-BETA | affected | the port, assertions on and off: the same values |
| before 8.0.0 | float era | mu = 0 scores 0 as everywhere; there a tiny mu such as Float.MIN_VALUE misbehaves too (score() ran in float); mu = 1e-10 works |
| 3.6.2 and earlier | no class | no org.apache.lucene.search.similarities package; the port does not compile |
fix A / fix B on 645d4fe14a20 | not affected | A: the repro and 30 test classes pass; B: mu = 0 is rejected at construction, 29 test classes pass |
An independent reproducer, a devil's-advocate verifier, an adjudication, a credibility audit and a tie-breaker reproduced it (main, 10.6.0, 10.5.2, 9.12.3; assertions on and off). Read-only reviews by OpenAI GPT-5.6 agreed on the root cause but could not run code. This doc's gradle run confirms the repro and both fixes.
Checks and verdicts368 words
No cross-model review could run code; all execution evidence comes from the Claude-family AI tools and separate runs.
| Check | Verdict | What it found |
|---|---|---|
| Finder (Z3 model, bounded-exhaustive check, JUnit) | candidate | Z3: 9 obligations, 0 mismatches; stock jar: mu = 0 scores 0 in 963,900 of 963,900 cases (276,714 with a positive limit); the 2-test JUnit fails 2 of 2 on main with assertions on and off, 20 of 20 with 10 iterations; the single-log fix passes it and 145 upstream tests. |
| Intended-behaviour review (OpenAI GPT-5.6, read-only) | real (low) | Could not execute; root cause agrees, input in contract, intended argument moderate; a separate re-run fails 2 of 2. |
| Independent reproducer | real | Own public-API JUnit (scorer level and end to end) fails 2 of 2 on main with assertions on and off, on 10.5.2 and on 9.12.3; passes with the fix. |
| Refute reviews (OpenAI GPT-5.6, three attempts, read-only) | not real on procedure only (low) | None could start a command; each agreed on the root cause and that mu = 0 is legal input; separate re-runs fail on main (assertions on and off) and on 10.5.2, and pass with the fix. |
| Intended-behaviour devil's advocate | real (high; medium on the fix) | Repro fails on main and 10.5.2; Jelinek-Mercer rejects lambda = 0 and Indri's single-log form is finite at mu = 0; traced the history of the range and the clamp. |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's JUnit with seed 1DEC0DE5: fails 2 of 2 with the same values. |
| Credibility audit | keep | Re-ran both JUnits with new seeds, assertions on and off; score and security rating checked. |
| Current-main reproducer and tie-breaker (2026-10-31) | real | Minimal test fails on main 645d4fe14a20, 10.6.0 and 10.5.2 with assertions on and off; a framework-free probe shows all-zero scores in doc-id order for both constructors and a OR b; javap confirms the clamp branch. |
| This doc (gradle, scratch worktree) | real; both fixes pass | Stock fails with assertions on and off; fix A passes the repro, 30 classes (740 runs) and the core format and lint checks; fix B passes 29 classes (735 runs); a float-score probe quantifies fix A's rounding changes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 333 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,308 words
- Registry title
- LMDirichletSimilarity accepts mu = 0, but then every document scores 0: log(1 + tf/(mu*P)) + log(mu/(dl+mu)) becomes +Infinity + -Infinity = NaN, and the 'score > 0' clamp turns NaN into 0
- Area
- search / similarities (LMDirichletSimilarity)
- Priority
- Low, rank 721: Setting the opt-in, experimental LMDirichletSimilarity to the accepted boundary value mu = 0 silently zeroes every score, which is the same opt-in degenerate-parameter profile as SweetSpot hyperbolicTf (LFV-750).
- Impact class
- silent wrong results
- Impact note
- Low priority: applications on any release since 4.0.0 (and main) that choose the opt-in, @lucene.experimental LMDirichletSimilarity and set mu to exactly 0, a value both constructors accept and upstream's own test uses, get 0.0 for every hit of every term on that field, so results come back in doc-id order with no error; which documents match is unchanged, the default mu = 2000 and every mu > 0 are unaffected, and no special data or scale is needed.
- Summary
- You configure LMDirichletSimilarity with mu = 0, which both constructors accept ('must be a non-negative finite value') and which upstream's TestLMDirichletSimilarity uses as its 'minimum value'. You expect documents that contain the query term more often than the collection model predicts to get a positive score and be ranked, as they are for every mu > 0 down to Float.MIN_VALUE, where the score already equals its finite mu -> 0 limit log(tf/(dl*P)). Instead score() computes log(1 + tf/0) + log(0/dl) = +Infinity + -Infinity = NaN, the 'score > 0 ? score : 0' clamp returns 0.0, and every hit scores 0.0, so the best match can come back last; explain() shows 'Infinity = term weight' and '-Infinity = document norm' under a 0.0 total.
- Introduced
- cfaf91c73981 (LUCENE-2959 / #4033, svn r1169470: the merge of the flexscoring branch into trunk, from JIRA patches, no PR) [read: git blame -w --ignore-rev 2d6ad2fee6d on main's score() shows only cfaf91c7398 and 42717d5f4bb; git log --all and git merge-base --is-ancestor in the full-history clone]. The two pieces were written on the flexscoring branch, which is not on main's ancestry: the two-log formula in 8f73f80d1d7 (LUCENE-3220 / #4293, 2011-07-15; mu = 0 gave NaN) and the clamp in 93bf76506b4 (LUCENE-3357 / #4430, 2011-08-20; it turned that NaN into 0). 42717d5f4bb (LUCENE-7997 / #9045, 2017-10-24, first in 8.0.0) added the 'non-negative finite value' check, which admits mu = 0, and the mu = 0 test case, and kept both logs and the clamp. Not a regression. (2011-09-11 (cfaf91c7398, author date; branch commits 2011-07-15 and 2011-08-20; constructor check admitting 0: 2017-10-24))
- First affected version
- 4.0.0-ALPHA [exec] (the first release with LMDirichletSimilarity; first GA release 4.0.0 [exec]; 3.6.2 and earlier have no such class [exec: compile error, jar listings 3.0.3..3.6.2])
- Affected versions
- every release that has the class: 4.0.0-ALPHA and all 130 GA releases 4.0.0..10.5.2 [exec: the history probe prints 'RESULT: BUG' on each, -ea; also -da on 4.0.0, 8.0.0 and 10.5.2], 4.0.0-BETA [read: per-tag source check]; the candidate JUnit fails 2 of 2 on 9.12.3, 10.0.0, 10.5.2 and main, the independent reproduction's own JUnit fails 2 of 2 on 9.12.3 and 10.5.2 [exec]; the branch_10_6 head 4ae946e5a9b (10.6.0-SNAPSHOT) [exec]; main a9779ef3c193 [exec: -ea and -da; re-run at the registration check]. Before 8.0.0 score() ran in float and mu = Float.MIN_VALUE is degenerate too (one hit Infinity, the others 0), so the contrast with a tiny positive mu holds cleanly from 8.0.0; mu = 1e-10 gives the finite limit in every release [exec]. Not fixed upstream: the last commit on the file is dab731175c8 (#13845, author and committer date 2024-10-04) on main and its backport cbd8b5218ad on branch_10_6 [read, commits API, 2026-10-28]. All runs on JDK 25 (aarch64 Linux).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, 2026-10-28, read-only; refreshed at the registration check 2026-10-28: 'gh search prs --repo apache/lucene LMDirichlet' 0 hits, none of the issues and PRs created since 2026-10-26 (#16907-#16928) is about Dirichlet or the LM similarities, and the commits API shows no change to LMDirichletSimilarity.java after dab731175c8, author date 2024-10-04): five scripted prior-report searches (40, 146, 319, 21 and 13 hits, 0 high) over GitHub issues and PRs, commit messages, downstream trackers, dev@/java-user@/issues@/commits@ and Solr lists, LUCENE and SOLR JIRA and the web; manual gh searches over apache/lucene, apache/solr, apache/lucene-solr, elastic/elasticsearch, opensearch-project/OpenSearch, castorini/anserini and castorini/pyserini; the changed-path lists of all 410 open apache/lucene PRs and of the 200 most recently updated closed or merged PRs; JIRA REST, list and Stack Overflow searches. Related, not this bug: #9045 / LUCENE-7997 (added the non-negative check and the mu = 0 test under a generic range rule, no word on its scores), #9058 / LUCENE-8010 (core similarities should not return NaN), #4430 / LUCENE-3357 (origin of the clamp, for negative scores), #8530 / LUCENE-7478 (the single-log identity, as a formula question), #8532 / LUCENE-7480 (open, missing-term component), elastic/elasticsearch#15345 and #15397 (all-zero scores at mu = 2500 from the documented negative-score clamp) and #29015 (warning that LMDirichlet may return 0); open PRs in the package (#16916, #14433, #16847, #463) do not touch LMDirichletSimilarity.java
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off through gradle in a scratch worktree (2026-10-31) and through a standalone runner (2026-10-29 and 2026-10-31); with fix A it passes, together with 30 similarity-related test classes (740 runs) and the core format and lint checks; with fix B the same suites pass. The 10.6.0 and 10.5.2 release jars: the minimal test fails with assertions on and off. Amain()port of the test: all 131 GA releases from 4.0.0 to 10.6.0, 4.0.0-ALPHA and 4.0.0-BETA are affected.LMDirichletSimilarity.javais identical at upstream main2f424fd428d(2026-10-30) [read].
- Finding record
lucene/core/src/java/org/apache/lucene/search/similarities/LMDirichletSimilarity.java:30-32 (at a9779ef3c193) (class javadoc: the paper's formula gives a negative score to documents with fewer occurrences than the collection model predicts; Lucene returns 0 for such documents), :34 (@lucene.experimental), :46-54 and :57-63 (constructors: 'illegal mu value ... must be a non-negative finite value', mu = 0 accepted), :65-73 (default mu 2000), :76-82 (score: two separate logs, clamp 'score > 0.0d ? score : 0.0d' at :81), :96-107 (explain: mu, term weight log(1 + freq/(mu * P)), document norm log(mu/(dl + mu)))lucene/core/src/test/org/apache/lucene/search/similarities/TestLMDirichletSimilarity.java:28-47 (at a9779ef3c193) (mu = 0 'minimum value', Float.MIN_VALUE 'tiny value'); SECURITY.md:42 (configuration values are trusted as given), :48-50 (in-scope reports)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/similarities/LMDirichletSimilarity.java:30-32 (at 645d4fe14a20) (class javadoc), :34 (@lucene.experimental), :49-52 and :58-61 (constructor checks), :76-82 (score; :79 and :80 the two logs, :81 the clamp), :96-107 and :117-125 (explain)lucene/core/src/java/org/apache/lucene/search/similarities/LMSimilarity.java:151 (at 645d4fe14a20) (DefaultCollectionModel P = (totalTermFreq + 1) / (numberOfFieldTokens + 1))lucene/core/src/java/org/apache/lucene/search/similarities/SimilarityBase.java:186 (at 645d4fe14a20) ((float) of score())
- Who is affected
lucene/core/src/java/org/apache/lucene/search/similarities/LMDirichletSimilarity.java:34 (at 645d4fe14a20) (@lucene.experimental), :65-73 (default mu 2000)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/similarities/LMDirichletSimilarity.java:30-32, (at 645d4fe14a20) :49-52, :58-61lucene/core/src/test/org/apache/lucene/search/similarities/TestLMDirichletSimilarity.java:30-31 (at 645d4fe14a20) (minimum value mu = 0), :34-35 (tiny value Float.MIN_VALUE)lucene/core/src/java/org/apache/lucene/search/similarities/LMJelinekMercerSimilarity.java:53-54, (at 645d4fe14a20) :61-62lucene/test-framework/src/java/org/apache/lucene/tests/search/CheckHits.java:375 (at 645d4fe14a20) (COMPUTED_FROM_PATTERN)lucene/test-framework/src/java/org/apache/lucene/tests/search/CheckHits.java:437-438 (at 645d4fe14a20) (computedOf), :494-496 (combined = value)
- TestLMDirichletMuZero.java (one test, public API):
repro/LFV-902/src/org/apache/lucene/search/similarities/TestLMDirichletMuZero.java(58 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and an executed probe of the real jar: the plotted scores by mu, the explain() output and the reversed-order ranking.
assets/LFV-902/bug.png(333 KB)