Grouped search can record the first pass's hits and replay them in the second pass. The cache has one documented limit; since #16247 it is enforced per slice of a concurrent searcher.
- Grouped search runs the query twice: the first pass finds the top groups, the second collects the top documents inside them.
setCaching(maxDocs, cacheScores)orsetCachingInMB(mb, cacheScores)makes the first pass record its hits (4 bytes per document, 8 with scores) so the second pass can replay them. If more hits than the limit match, the cache is purged and the second pass runs the query again.- An
IndexSearcherwith an executor splits the segments into slices (by default at most 5 segments, closing a slice once it passes 250,000 documents) and asks aCollectorManagerfor one collector per slice.
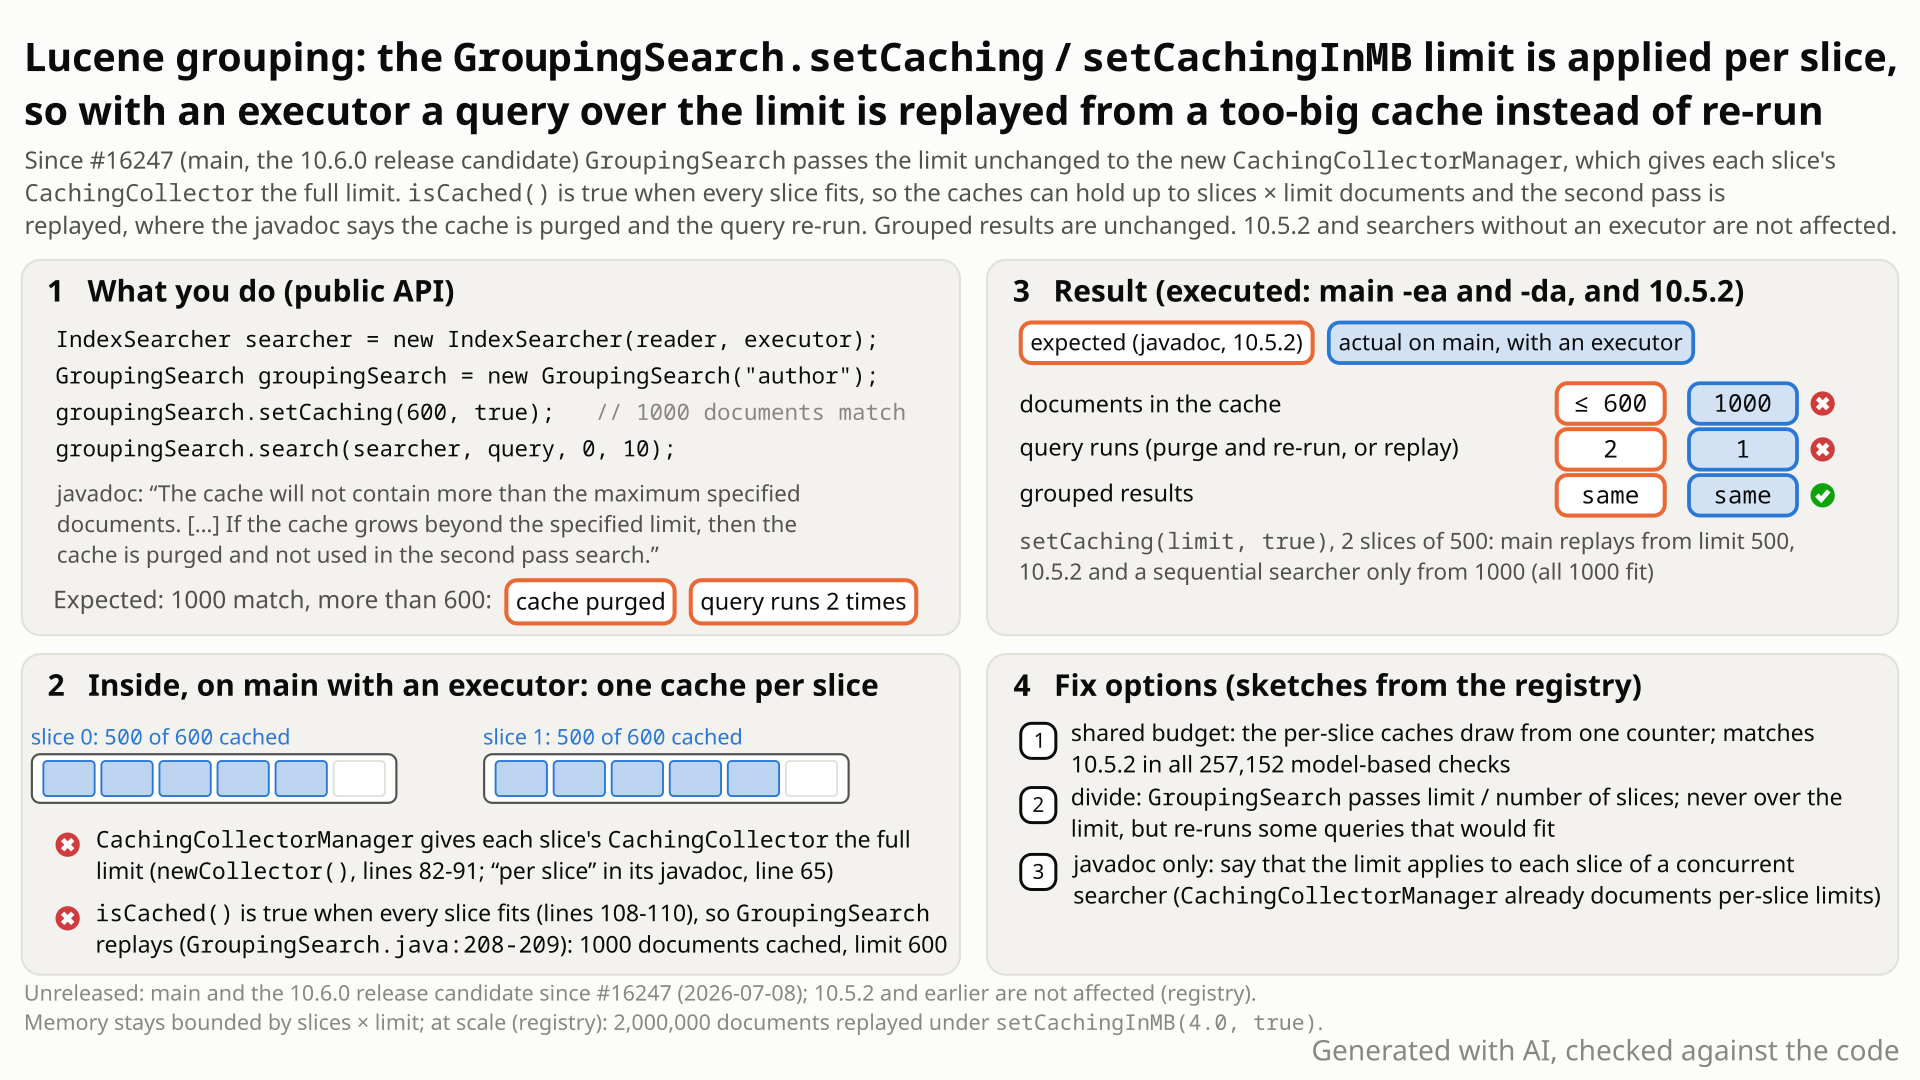
- Index 1,000 documents in 10 segments of 100, all matching
body:match. Group them by author withGroupingSearchand turn on the second-pass cache withsetCaching(600, true): keep at most 600 hits, and if more match, purge the cache and run the query again. - Search through an
IndexSearcherwith an executor; default slicing makes 2 slices of 500 documents. You expect what the javadoc says and 10.5.2 does: 1,000 is over 600, so the query runs twice. - Instead it runs once: since #16247,
GroupingSearchhands the 600 toCachingCollectorManager, which gives each slice its own 600-document cache. Each slice holds 500, neither overflows, and the second pass is replayed from 1,000 cached documents. - Same groups, no error; what breaks is the bound: up to slices x limit. With the package docs'
setCachingInMB(4.0, true), a match-all over 2,000,000 documents in 6 slices was replayed from caches holding all 2,000,000 hits (16,000,000 bytes at the collector's 8 bytes per hit) against a 4,194,304-byte limit. - A searcher without an executor, and 10.5.2, still purge and re-run. The first affected release is 10.6.0 (released 2026-10-29).
Applications that turn on GroupingSearch caching (the package docs' example uses setCachingInMB(4.0, true)) and give their IndexSearcher an executor, on an index with more than one slice. Results stay correct; per grouped search the cache can hold up to slices x the limit, about 3.8x in the scale run. 10.6.0 (released 2026-10-29) and main only.
Mechanism, terms and numbers511 words
GroupingSearch.setCaching and setCachingInMB promise one bound for the second-pass cache: it "will not contain more than the maximum specified documents", and if it grows beyond the limit it "is purged and not used in the second pass search". Since #16247 (10.6.0 and main), GroupingSearch passes that limit unchanged to the new CachingCollectorManager, which applies it to each slice. With an IndexSearcher that has an executor, a query is replayed whenever no single slice exceeds the limit, whatever the total, and the caches together can hold up to (number of slices) x the limit. Search results are unchanged. 10.5.2 and any searcher without an executor behave as documented.
setCachingInMB: "The cache will not grow over a specified limit in MB. ... If the cache grows beyond the specified limit, then the cache is purged and not used in the second pass search."setCaching: "The cache will not contain more than the maximum specified documents",@param maxDocsToCache"The maximum number of documents the cache is allowed to hold" (GroupingSearch.java:240-272). Unchanged since LUCENE-3778 (2012), identical in 10.5.2.
- One
CachingCollectorenforces one limit across all segments it sees: each segment gets the remaining budget, the cache is purged when a segment's hits exceed it, and each finished segment's hits are subtracted (CachingCollector.java:80-96,:188-212). GroupingSearchnow wraps its first pass innew CachingCollectorManager<>(firstRoundManager, cacheScores, maxCacheRAMMB, maxDocsToCache)and runssearcher.search(query, cachingManager)(GroupingSearch.java:167-173); the second pass replays whencachingManager.isCached(), else re-runs the query (:207-212).IndexSearcher.search(Query, CollectorManager)callsnewCollector()once per slice (IndexSearcher.java:750-755,:771). Each call creates aCachingCollectorwith the full limit (CachingCollectorManager.java:82-91; javadoc: "the maximum number of documents to cache per slice",:64-66).isCached()is true when every per-slice cache is intact (CachingCollectorManager.java:103-111). So the query is replayed exactly when no slice exceeds the limit, and the caches together hold up to slices x limit.- Without an executor,
IndexSearchermakes one slice of all segments (IndexSearcher.java:218-232), so the old rule holds. Before #16247,GroupingSearchused oneCachingCollectorwith the deprecatedsearch(Query, Collector), which ignores the executor (10.5.2GroupingSearch.java:151-161,IndexSearcher.java:644-651).
10 segments of 100 matching documents, default slicing: 2 slices of 5 segments. Each slice's cache starts with 600, holds 500 and ends with 100 left; both are intact, so isCached() is true and the second pass replays 1,000 cached documents. On a searcher without an executor the single cache runs out of budget in the seventh segment and is purged, and the query runs again.
setCachingInMB(4.0, true) (package-info.java:89) is 524,288 documents per slice (CachingCollector.java:307-314). A multi-segment default slice holds at most 500,000 documents (IndexSearcher.java:340-385), so on an index whose segments all hold at most 524,288 documents no slice can overflow: every grouped query that finds a group is replayed from caches holding all of its hits, however many it matches (a search that finds no group returns before the second pass, GroupingSearch.java:193-195).
Exposure and likelihood159 words
- Opt-in twice. Caching is off by default, and so is the executor. Within that usage default slicing suffices; no unusual parameter is needed.
- Effect. The memory bound the application sized becomes slices x limit per grouped search (still bounded: each slice cache purges at the limit), and a query over the limit is replayed instead of re-run whenever every slice fits. Silent: no error, same results.
- Scale. 16 segments x 125,000 documents, 6 default slices,
setCachingInMB(4.0, true): a match-all query was replayed from 2,000,000 cached documents = 16,000,000 bytes of doc IDs and scores at the collector's 8 bytes per hit (computed from the hit count, not measured as heap) against the 4,194,304-byte limit on main and the release candidate; 10.5.2 purged the cache and re-ran the query. - Releases. 10.6.0 (released 2026-10-29 from RC1) is the first affected release.
- Likelihood: plausible. Concurrent search is common and 10.6.0 makes grouped search concurrent;
GroupingSearchcaching itself is a little-used opt-in.
The test shows that with an executor searcher (6 one-doc segments, default slicing = 2 slices of 5 + 1 docs), GroupingSearch.setCaching(5, true) replays the first-pass cache although 6 docs were cached, because the limit is applied per slice (#16247).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.grouping;

import java.io.IOException;
import java.util.concurrent.atomic.AtomicInteger;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.ScoreMode;
import org.apache.lucene.search.Weight;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestGroupingSearchCacheLimit extends LuceneTestCase {

  public void testCacheLimitAppliesToWholeSearch() throws IOException {
    IndexWriterConfig iwc = new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      for (int i = 0; i < 6; i++) {
        Document doc = new Document();
        doc.add(new SortedDocValuesField("group", new BytesRef("g")));
        w.addDocument(doc);
        w.flush(); // 6 one-doc segments; default slicing gives 2 slices (5 + 1 docs)
      }
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        AtomicInteger queryRuns = new AtomicInteger();
        IndexSearcher searcher =
            new IndexSearcher(reader, Runnable::run) {
              @Override
              public Weight createWeight(Query query, ScoreMode scoreMode, float boost)
                  throws IOException {
                queryRuns.incrementAndGet();
                return super.createWeight(query, scoreMode, boost);
              }
            };
        new GroupingSearch("group")
            .setCaching(5, true)
            .search(searcher, new MatchAllDocsQuery(), 0, 10);
        assertEquals(
            "6 docs match, over the cache limit of 5: the cache must be purged and the query re-run",
            2,
            queryRuns.get());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-910/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.grouping.TestGroupingSearchCacheLimit
- Expected vs actual
- Expected: the cache is purged and the query re-run (2 query runs, as the setCaching javadoc says and 10.5.2 does); actual:
expected:<2> but was:<1>(-ea and -da).
More files, environment, full output51 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: 6 docs match, over the cache limit of 5: the cache must be purged and the query re-run expected:<2> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.search.grouping.TestGroupingSearchCacheLimit.testCacheLimitAppliesToWholeSearch(TestGroupingSearchCacheLimit.java:63)setCaching's javadoc, unchanged since 2012: the cache "will not contain more than the maximum specified documents" and is purged past the limit. Nothing about slices.- Same call: re-run on a plain searcher, replay with an executor; #16247, CHANGES and MIGRATE never mention it.
- In #15795, javanna and gaobinlong (#16247's reviewer and author) fixed a slice-multiplied memory limit in another class.
The full argument217 words
- The contract is unchanged. The
GroupingSearchsetter javadoc (GroupingSearch.java:240-272) comes from LUCENE-3778 (89b55566d83, 2012, first released in 4.0.0), was only reformatted since, and is identical in 10.5.2. It names one limit and the purge rule. - Behaviour depends on the executor. The finder's test runs the same
GroupingSearchover the same reader on a sequential searcher (purged and re-run: 2 executions) and on one with an executor (replayed: 1 execution). - Never discussed. #16247's description, 1 issue comment, 22 reviews and 39 inline comments say nothing on the limit, slices or memory; its CHANGES entry (
CHANGES.txt:543-545, 10.6.0 Improvements) says it parallelizes search; MIGRATE is silent. - Earlier precedent (as javanna pointed out on #15795). In
MemoryAccountingBitsetCollectorManager(merged 2026-06-04), javanna asked: "if it is not shared, the memory limit becomes the number of collectors * the number of slices which is very different from the single threaded search scenario?" gaobinlong, who later wrote #16247, agreed ("we should keep the scope consistent between concurrent search and single threaded search") and shared one tracker. Close precedent in another class, not a decision aboutGroupingSearch. - No test pins per-slice semantics for GroupingSearch.
TestCachingCollectorManagersearches only with limits 0 andInteger.MAX_VALUE(other values appear only in its constructor argument checks);TestGroupingSearchandTestGroupingnever assert the limit under slicing.
The devil's-advocate check206 words
The strongest case (the intended-behaviour check and the cross-model reviews: moderate): CachingCollectorManager is new, @lucene.experimental, and documents its limits as per slice (CachingCollectorManager.java:24-31, :64-66); the rewritten package-info says it caches documents "per segment slice" (package-info.java:53-58); and #13943 made the top-hits threshold count per slice. GroupingSearch itself (GroupingSearch.java:44) and the IndexSearcher constructors that take an executor (IndexSearcher.java:199, :216) are @lucene.experimental too. So GroupingSearch may simply have inherited per-slice semantics.
Why it fails for GroupingSearch: its own javadoc, the API the user calls, is unchanged and promises one bound; the per-slice wording sits on a different, new class; the package-info sentence describes one cache per slice, not a limit that multiplies; #13943's threshold is a lower bound, which per-slice counting still meets, while this is an upper bound, which it breaks; and #15795 shows the same reviewer and author treating a slice-multiplied limit as a mistake in another class. Experimental status allows a change, but the javadoc still describes the old bound and neither #16247 nor CHANGES says it changed. The intended-behaviour check rated the intended case moderate for CachingCollectorManager and weak for GroupingSearch. Upstream may still keep per-slice semantics and fix only the javadoc.
Recommended One shared budget for all slices of a search (validated with targeted tests)
Give all slices of one search a shared budget: CachingCollectorManager gets a whole-search mode in which the per-slice caches draw from one counter and purge when it runs out, and GroupingSearch uses it (3 files, +64/-4). The test passes; the core caching tests and the grouping module pass, assertions on and off.
@@ NoScoreCachingLeafCollector#collect (CachingCollector.java)
   public void collect(int doc) throws IOException {
+    if (docs != null && sharedRemaining != null && sharedRemaining.getAndDecrement() <= 0) {
+      // the limit shared by all caches of one search is used up: purge this cache
+      invalidate();
+    }
@@ GroupingSearch#groupByFieldOrFunction
-              firstRoundManager, cacheScores, maxCacheRAMMB, maxDocsToCache);
+              firstRoundManager, cacheScores, maxCacheRAMMB, maxDocsToCache, true);
All options and trade-offs3 options · 566 words
One code fix was validated in a scratch worktree of 645d4fe14a20 with gradle; a simpler conservative variant was built and run; a javadoc-only change is the option upstream may prefer.
CachingCollectorManager gets a constructor flag limitAppliesToWholeSearch; when set, it holds one AtomicInteger initialised to the limit (MB converted to documents as CachingCollector does), each per-slice CachingCollector takes one unit per collected document and purges itself when the budget is used up, and GroupingSearch passes true. isCached() and replay are unchanged, so one purged slice makes the whole search re-run, as in 10.5.2. The finder's sketch, re-indented for google-java-format.
@@ NoScoreCachingLeafCollector#collect (CachingCollector.java)
   public void collect(int doc) throws IOException {
+    if (docs != null && sharedRemaining != null && sharedRemaining.getAndDecrement() <= 0) {
+      // the limit shared by all caches of one search is used up: purge this cache
+      invalidate();
+    }
@@ GroupingSearch#groupByFieldOrFunction
-              firstRoundManager, cacheScores, maxCacheRAMMB, maxDocsToCache);
+              firstRoundManager, cacheScores, maxCacheRAMMB, maxDocsToCache, true);
Trade-offs
- One atomic decrement per collected document while the cache is live: a shared, contended counter under many threads. Reserving the budget in chunks (for example when a leaf buffer grows) would avoid it; not built.
- It restores the cached-document count and the replay decision, not a strict cap on peak allocation: each leaf buffer starts at up to 128 entries and grows by
ArrayUtil.oversize(CachingCollector.java:42,:170,:195-197; refinement by the root-cause reviewer). - A slice that finished before another used up the budget keeps its arrays until the manager is dropped; they are never replayed.
- API shape: a new public constructor with a boolean. Upstream could instead make the shared budget its only behaviour and drop the "per slice" javadoc (not run).
What the checks validated
- Stock + test: fails with assertions on and off (gradle).
- + fix: the test passes with assertions on and off; core
TestCachingCollector,TestCachingCollectorManager,TestIndexSearcher,TestMultiCollector,TestMultiCollectorManager(38 tests, 1 skipped) and the wholelucene/groupingmodule (15 suites with the new test, 57 tests), 0 failures, assertions on and off. :lucene:core:check :lucene:grouping:check -x test(checkGoogleJavaFormat, ecjLint, forbiddenApis) passes after one re-indent.- Earlier, by the finder: the bounded-exhaustive model-based test with this fix matches the whole-search rule in all 257,152 checks, 0 result mismatches.
- Not run: the full test suite, nightly tests, a benchmark.
GroupingSearch passes limit / max(1, searcher.getSlices().length) to the manager (1 file, +7/-1).
Trade-offs
Smallest change and never over the limit, but conservative: with uneven hits across slices it re-runs queries that fit the whole-search limit (48,208 of 257,152 model-based checks), and setCaching(n) with n below the slice count becomes 0 per slice, so every search with at least one hit re-runs the query (a search with no hits returns before the second pass, GroupingSearch.java:193-195).
What the checks validated
The test, the grouping module (57 tests) and TestCachingCollector* (8 tests) pass, assertions on.
Say in the setCaching / setCachingInMB javadoc that the limit applies to each slice of a concurrent IndexSearcher. Upstream may well choose this.
Trade-offs
Leaves memory at up to slices x limit and the replay decision dependent on the executor; the repro test would then be wrong and should not be added.
An application that sizes setCaching or setCachingInMB to a heap budget and searches with an executor should plan for up to slices x that budget per grouped search on 10.6.0 until this is fixed.
A review of what changes in 10.6.0: #16247 read against the unchanged setCaching javadoc, then a cross-version probe that re-ran on 10.5.2 and replayed on main and the release candidate. It was reduced to a public-API JUnit and characterised with a bounded-exhaustive model-based test of the real jars and an SMT model of the cache bound.
The method in full173 words
- First signal (planning, release-change review of 10.6.0). Reading #16247 against the
GroupingSearchjavadoc, then a probe: 1,000 matching documents in 4 segments, one segment per slice, a 4-thread executor;setCaching(300, true)andsetCaching(999, true)replay on main and branch_10_6 but re-run on 10.5.2, and a sequential searcher re-runs on all three. - Hunt unit. Reduced it to a public-API JUnit with default slicing, then a bounded-exhaustive differential model-based test of the real jars against two executable models (whole-search rule from the javadoc, per-slice rule): 346 indexes, 4,592 slicings, limits 0..13 as documents and as MB,
cacheScoresfalse and true, 257,152 checks. Main and the release candidate follow the per-slice rule in every check and replay over the limit in 33,888; 10.5.2 follows the javadoc in every check; cached results equal uncached ones everywhere. - SMT model (Z3). Per-slice caching holds at most slices x limit documents, the bound is reached, and one slice equals the whole-search rule.
- The model-based test and the SMT model came after the first signal, so the finding counts as non-formal.
No prior report found (2026-10-28: three automated searches of 51-57 queries over GitHub, commits, the Lucene lists, JIRA, downstream trackers and the web; 40 manual GitHub searches; open PRs' changed files; the 10.6.0 RC1 vote thread), refreshed 2026-10-29. Closest: #15795, where the same mistake was fixed in another class.
Searches5 searches
The searches found no report that the GroupingSearch limit became per slice, and nobody raised it on the 10.6.0 RC1 vote thread. #15795's review exchange (javanna and gaobinlong) is related context, not a report: a different class, fixed before merge.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene; apache/solr, Elasticsearch, OpenSearch) | 2026-10-28 | three scripted prior-report searches (51-57 queries each: identifiers and contract wording, memory and concurrency symptoms, CachingCollector and GroupingSearch history) and 40 manual searches | no report; related: #16247 (introducing), #15795 (same mistake in another class, fixed), #16385, #16379, #12892, #9588, #5438, #4175, #10401, #4851 |
| Open apache/lucene PRs | 2026-10-28 | changed files of the 190 open PRs updated since 2026-06-11 (412 open) | apart from #16911, which deletes every file on branch_10x to decommission that branch, none touches CachingCollectorManager.java; #16847, #14996, #15210 touch GroupingSearch.java or CachingCollector.java, not the limit |
| dev@, java-user@, issues@, commits@ lists and JIRA | 2026-10-28 | list searches; the 10.6.0 RC1 vote and feature-freeze threads read | no report; the vote thread's 9 +1 votes (the release manager's and 8 replies) do not mention grouping or caching |
| GitHub refresh | 2026-10-29 | git ls-remote; issue and PR searches for CachingCollectorManager and "GroupingSearch setCaching" (three more phrasings rate-limited) | nothing new; main still 645d4fe14a20, branch_10_6 still 4ae946e5a9b9, no 10.6.0 tag |
| GitHub (independent fact check) | 2026-10-29 | the three rate-limited phrasings ("grouping cache slice", "setCachingInMB", "GroupingSearch cache limit"), "GroupingSearch setCaching" without a date filter, open PRs updated since 2026-10-28, git ls-remote | nothing new ("setCachingInMB" finds only #5691 of 2012); main and branch_10_6 unchanged, no 10.6.0 tag |
Introduced by #16247 (gaobinlong, merged 2026-07-08; main 3afffeef5a8, branch_10x d60e550b47f), which is in 10.6.0 (released 2026-10-29). No earlier release is affected: 9.12.3, 10.0.0, 10.4.0 and 10.5.0 to 10.5.2 pass; at commit level #16247 fails and its parent passes.
Versions tested5 rows
The broken contract dates from LUCENE-3778 (89b55566d83, 2012, 4.0.0). Every release through 10.5.2 ran GroupingSearch's first pass through one CachingCollector on the sequential search(Query, Collector) path, which ignores the executor. #16247 moved it onto the per-slice manager without dividing or sharing the limit and without changing the javadoc. Of GroupingSearch.java, CachingCollector.java, CachingCollectorManager.java and the grouping package-info.java, only #16385, #16508 and #16292 changed anything since #16247, and in those files only package-info.java; their other changes, and #16379, #16516 and #16779, are elsewhere in lucene/grouping and do not touch the cache limit.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the one-method test fails, 1 run instead of 2, assertions on and off |
branch_10_6 4ae946e5a9b9 (10.6.0 RC1) | affected | this doc's test and the finder's test fail, assertions on and off |
main 3afffeef5a8 (#16247) vs its parent 6f3c1d7ad69 | bisect | #16247 fails, its parent passes (finder's test, -ea and -da, javac builds differing only by the #16247 diff) |
| 10.5.2, 10.5.1, 10.5.0, 10.4.0, 10.0.0, 9.12.3 | not affected | the finder's test passes (release jars): the query is re-run with and without an executor; 10.5.1 and 10.5.2 were cut from branch_10_5 and contain neither commit |
| 4.0.0 to 9.0.0 | read | the same single-CachingCollector, sequential shape (not executed) |
Cross-model reviews (executed), independent verifiers and an adjudication rate it real; the intended-behaviour case is moderate for CachingCollectorManager and weak for GroupingSearch. This doc's one-method test fails on main and the release candidate and passes on 10.5.2 and 10.0.0.
Checks and verdicts357 words
Every check ran code. The cross-model reviews used an independent reviewer from another model family (OpenAI GPT-5.6) on main ea57360912ed, where the relevant classes are identical to 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | JUnit fails 2 of 2 on main and the release candidate (-ea, -da), passes on 10.5.2, 10.4.0, 10.0.0; model-based test (257,152 checks); SMT model; scale run; two fix sketches. |
| cross-model refute and intended reviews | real, high; intended case moderate | The refute reviewer's JUnit (whole-search limit) fails on main ea57360912ed (-ea, -da) and passes on 10.5.2. The intended reviewer's JUnit pins the observed per-slice behaviour, so it passes on main and fails on 10.5.2: the same difference, asserted the other way round. |
| Independent reproducer | real | Own JUnit, a different observable (postings pulls): 3 of 4 fail on main and the release candidate, 10.5.2 and 9.12.3 pass; direct count of 1,000 documents in 2 intact caches against a limit of 600. |
| Root-cause review | real, high | Traced two collectors each given the full 600 budget; the shared-budget fix restores the 10.5.2 decision (not a strict cap on peak allocation). |
| Devil's advocate | real | Re-ran the finder's test; intended case moderate for the manager, weak for GroupingSearch. |
| adjudication | confirmed, high | The independent reproduction's test with a new seed: fails on main (-ea, -da) and the release candidate, passes on 10.5.2. |
| this doc | as above | One-method test on main (gradle and standalone, -ea, -da), jars built from the RC1 commit, 10.5.2 and 10.0.0; the shared-budget fix (test, core caching tests, grouping module, static checks) and the divide alternative. |
| fact checks of this doc | holds up; wording fixes applied | A separate AI tool re-ran the documented gradle command on a clean 645d4fe14a20 worktree (fails as shown, assertions on and off), the standalone test on main, the RC1-commit jars, 10.5.2 and 10.0.0, and both fixes; an independent reviewer from another model family (OpenAI GPT-5.6, read-only) re-checked the text. Their wording and precision points are resolved in the hunt's record. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 599 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,487 words
- Registry title
- GroupingSearch.setCaching / setCachingInMB limit is applied per slice since #16247 (10.6.0 regression): with an IndexSearcher that has an executor, a query matching more documents than the limit is replayed from per-slice caches holding up to slices x limit instead of being purged and re-run (results unchanged)
- Area
- grouping / GroupingSearch two-pass caching x search / CachingCollectorManager (new in 10.6.0) under a concurrent IndexSearcher
- Priority
- Low, rank 734: This 10.6.0 regression in opt-in GroupingSearch caching under an executor lets the cache hold up to slices times the documented limit while results stay correct, which is milder than LFV-923's unbounded clause-limit bypass and worse than LFV-348's 1.29x, so it goes between them.
- Impact class
- minor
- Impact note
- Hits only applications that enable GroupingSearch caching (setCaching or setCachingInMB; the grouping package documentation's own example is setCachingInMB(4.0, true)) and search through an IndexSearcher with an executor over an index with more than one slice (default slicing: more than 5 segments, or a segment above 250,000 docs); search results stay correct, but the second-pass cache can hold up to (number of slices) x the limit and an over-limit query is replayed instead of re-run (scale run: 2,000,000 cached docs = 16,000,000 bytes of doc ids and scores under the 4 MB setting, 6 default slices); memory stays bounded by slices x limit because each slice cache still purges at the limit, no scale is needed to trigger it, and it is in 10.6.0 (released 2026-10-29) and main only.
- Summary
- You enable caching for a grouped search with GroupingSearch.setCaching(600, true) (or setCachingInMB) and search through an IndexSearcher that has an executor, and expect what the unchanged javadoc says and what 10.5.2 and a sequential searcher do: the cache holds at most the limit, and when the query matches more it is purged and the second pass re-runs the query. Instead, since #16247 GroupingSearch hands the limit to the new CachingCollectorManager, which applies it to each slice separately, so with 1000 matching documents over 2 slices each slice cache stays under 600, the caches hold all 1000 documents, and the second pass is replayed (the query runs once instead of twice). Results are the same; what breaks is the documented memory bound and the replay decision, and the cache can reach (number of slices) x limit.
- Introduced
- 3afffeef5a8d3bcbdcff9f2376e1c5a357764197 (main; apache/lucene#16247 'Introduce CachingCollectorManager to parallelize search when using CachingCollector', author gaobinlong, approved by javanna, merged 2026-07-08T09:27:54Z) and d60e550b47f (branch_10x, same author date and patch-id 1ae55a44eb1c; branch_10_6 forks from branch_10x at 3e416dce059, 2026-10-15, and contains it) [exec: the finder JUnit passes at the parent 6f3c1d7ad69 and fails at 3afffeef5a8 with -ea and -da, in plain javac builds from the full-history clone that differ only by the #16247 diff]. The GroupingSearch caching contract it breaks dates from 89b55566d83 (LUCENE-3778, 2012, first released in 4.0.0) and is unchanged except for reformatting (LUCENE-9570). (2026-07-08 (author date of 3afffeef5a8 on main and of d60e550b47f on branch_10x))
- First affected version
- 10.6.0 (released 2026-10-29: the branch_10_6 head 4ae946e5a9b, RC1, fails [exec]; main from 3afffeef5a8 [exec]); no earlier release is affected (9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.1 and 10.5.2 pass [exec]; 4.0.0-10.5.2 [read])
- Affected versions
- [exec] main a9779ef3c193 (-ea and -da; re-run at the registration check 2026-10-28: 2 run, 2 failed, seed DEADBEEF), the introducing commit 3afffeef5a8 (-ea, -da) and the branch_10_6 head 4ae946e5a9b = 10.6.0 RC1 (-ea, -da; re-run at the registration check: 2 of 2 fail) are affected; not affected [exec]: 10.5.2 (-ea, -da; re-run at the registration check: 2 of 2 pass), 10.5.1, 10.5.0, 10.4.0, 10.0.0, 9.12.3 and the parent commit 6f3c1d7ad69. [read] every release from 4.0.0 to 10.5.2 ran GroupingSearch's first pass through one CachingCollector in the sequential search(Query, Collector) loop, which ignores the executor, so the limit covered the whole search (10.5.1 and 10.5.2 were cut from branch_10_5 and contain neither commit). All runs used JDK 25 on aarch64 Linux. Not fixed upstream: no commit on main (head c5ab3e57b9ba) or branch_10_6 (head 4ae946e5a9b9) touches GroupingSearch.java, CachingCollectorManager.java, CachingCollector.java or IndexSearcher.java since 2026-10-20, and no open PR touches the limit [read, 2026-10-28].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new; searched 2026-10-28, read-only; finder's own run; refresh 2026-10-28): three scripted prior-report searches (55, 57 and 51 queries over GitHub issues, PRs and commits, Solr, Elasticsearch and OpenSearch, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; no hit reports the bug), manual GitHub searches, the changed files of every open apache/lucene PR updated since 2026-06-11 and again of the 46 updated since 2026-10-26, commits on main, branch_10x and branch_10_6 touching the files, the 10.6.0 RC1 vote and feature-freeze threads on dev@ (no mail mentions grouping or caching, read through 2026-10-28), and full reads of #16247 (body, 1 issue comment, 22 reviews, 39 inline review comments: nothing on the limit, slices or memory), #15795, #15936, #16379, #16385, #16508 and #12892. Related context, not reports: in #15795 (MemoryAccountingBitsetCollectorManager, merged 2026-06-04) javanna noted that a per-slice tracker makes 'the memory limit ... the number of collectors * the number of slices' and gaobinlong agreed and shared one tracker, a different class fixed before merge; #16385's package-info says the manager caches 'per segment slice' without addressing the limit; #9588 (LUCENE-8542) is about per-slice collector memory in general; #5438 and #4175 concern single-collector limits. Open PRs #16847, #14996 and #15210 touch GroupingSearch.java or CachingCollector.java but not the limit; none touches CachingCollectorManager.java.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28, upstream main on 2026-10-29): the one-method repro test through gradle in a scratch worktree and through the standalone runner, assertions on and off, stock, with the shared-budget fix and with the divide-by-slices alternative; jars built from branch_10_64ae946e5a9b9(the 10.6.0 RC1 commit, 10.6.0-SNAPSHOT); the 10.5.2 and 10.0.0 release jars (Maven Central, SHA-1 checked). The hunt's earlier runs used maina9779ef3c193(finder, verifiers, adjudication, follow-up history runs from 9.12.3 to main and the #16247 commit and its parent) and mainea57360912ed(the cross-model reviews); every cited source file is identical in both and at645d4fe14a20.
- Finding record
lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:167-176 (at a9779ef3c193) (the limit is passed unchanged to new CachingCollectorManager(firstRoundManager, cacheScores, maxCacheRAMMB, maxDocsToCache); first pass through searcher.search(query, cachingManager)), :207-212 (replay when cachingManager.isCached(), else re-run), :240-272 (setCachingInMB / setCaching javadoc: 'The cache will not grow over a specified limit in MB' / 'The cache will not contain more than the maximum specified documents ... If the cache grows beyond the specified limit, then the cache is purged and not used in the second pass search'; '@param maxDocsToCache The maximum number of documents the cache is allowed to hold')lucene/core/src/java/org/apache/lucene/search/CachingCollectorManager.java:25-31 (at a9779ef3c193) (class javadoc: one CachingCollector per slice), :61-67 ('@param maxRAMMB the maximum RAM in MB to use per slice cache', '@param maxDocsToCache the maximum number of documents to cache per slice'), :82-91 (newCollector: one CachingCollector with the full limit per call), :103-111 (isCached: every per-slice cache intact)lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:184-221 (at a9779ef3c193) (each CachingCollector enforces only its own budget; postCollect subtracts a leaf's documents from that collector's maxDocsToCache), :307-313 (MB to documents: 4 bytes per document, 8 with scores)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:750-772 (at a9779ef3c193) (search(Query, CollectorManager) calls newCollector() once per slice), :106-108 and :324 (default slicing: MAX_DOCS_PER_SLICE 250,000, MAX_SEGMENTS_PER_SLICE 5)lucene/grouping/src/java/org/apache/lucene/search/grouping/package-info.java:53-58 (at a9779ef3c193) (CachingCollectorManager 'caches all collected documents (and optionally scores) per segment slice'), :89 (example setCachingInMB(4.0, true))lucene/CHANGES.txt:533-535 (at a9779ef3c193) (10.6.0 Improvements, GITHUB#16247: 'Introduce CachingCollectorManager to parallelize search when using CachingCollector'; nothing on the limit)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:167-176, :193-195, :207-212, :240-272a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollectorManager.java:24-31, :61-67, :82-91, :103-111a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:25-34, :80-96, :188-212, :307-314a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106-108, :218-232, :324, :340-385, :750-755, :771a Lucene main checkout (645d4fe14a20) lucene/grouping/src/java/org/apache/lucene/search/grouping/package-info.java:53-58, :89a Lucene clone releases/lucene/10.5.2 GroupingSearch.java:151-161, :179-183; IndexSearcher.java:644-651
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/grouping/src/java/org/apache/lucene/search/grouping/package-info.java:83-90
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:240-272; lucene/core/src/java/org/apache/lucene/search/CachingCollectorManager.java:24-31, :48, :64-66; lucene/grouping/src/java/org/apache/lucene/search/grouping/package-info.java:53-58; lucene/CHANGES.txt:543-545, :2094-2095a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/TestCachingCollectorManager.java (searches with limits 0 and Integer.MAX_VALUE only, :38, :53, :72; :90-97 are constructor argument checks)a Lucene main checkout (645d4fe14a20) lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:44; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:199, :216 (@lucene.experimental)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:42, :170, :195-197
- TestGroupingSearchCacheLimit.java (JUnit test):
repro/LFV-910/src/org/apache/lucene/search/grouping/TestGroupingSearchCacheLimit.java(70 lines)
It is made in parallel with this doc; every on-screen value comes from the code at 645d4fe14a20 (and 10.5.2 for the code before #16247) or the diagram's executed probe.
assets/LFV-910/bug.png(599 KB)