A Monitor matches incoming documents against stored queries; HighlightsMatch.MATCHER also returns where each query matched, as hits with positions and character offsets. Some analyzers stack two tokens of different lengths at one position, and then two different hits share their positions.
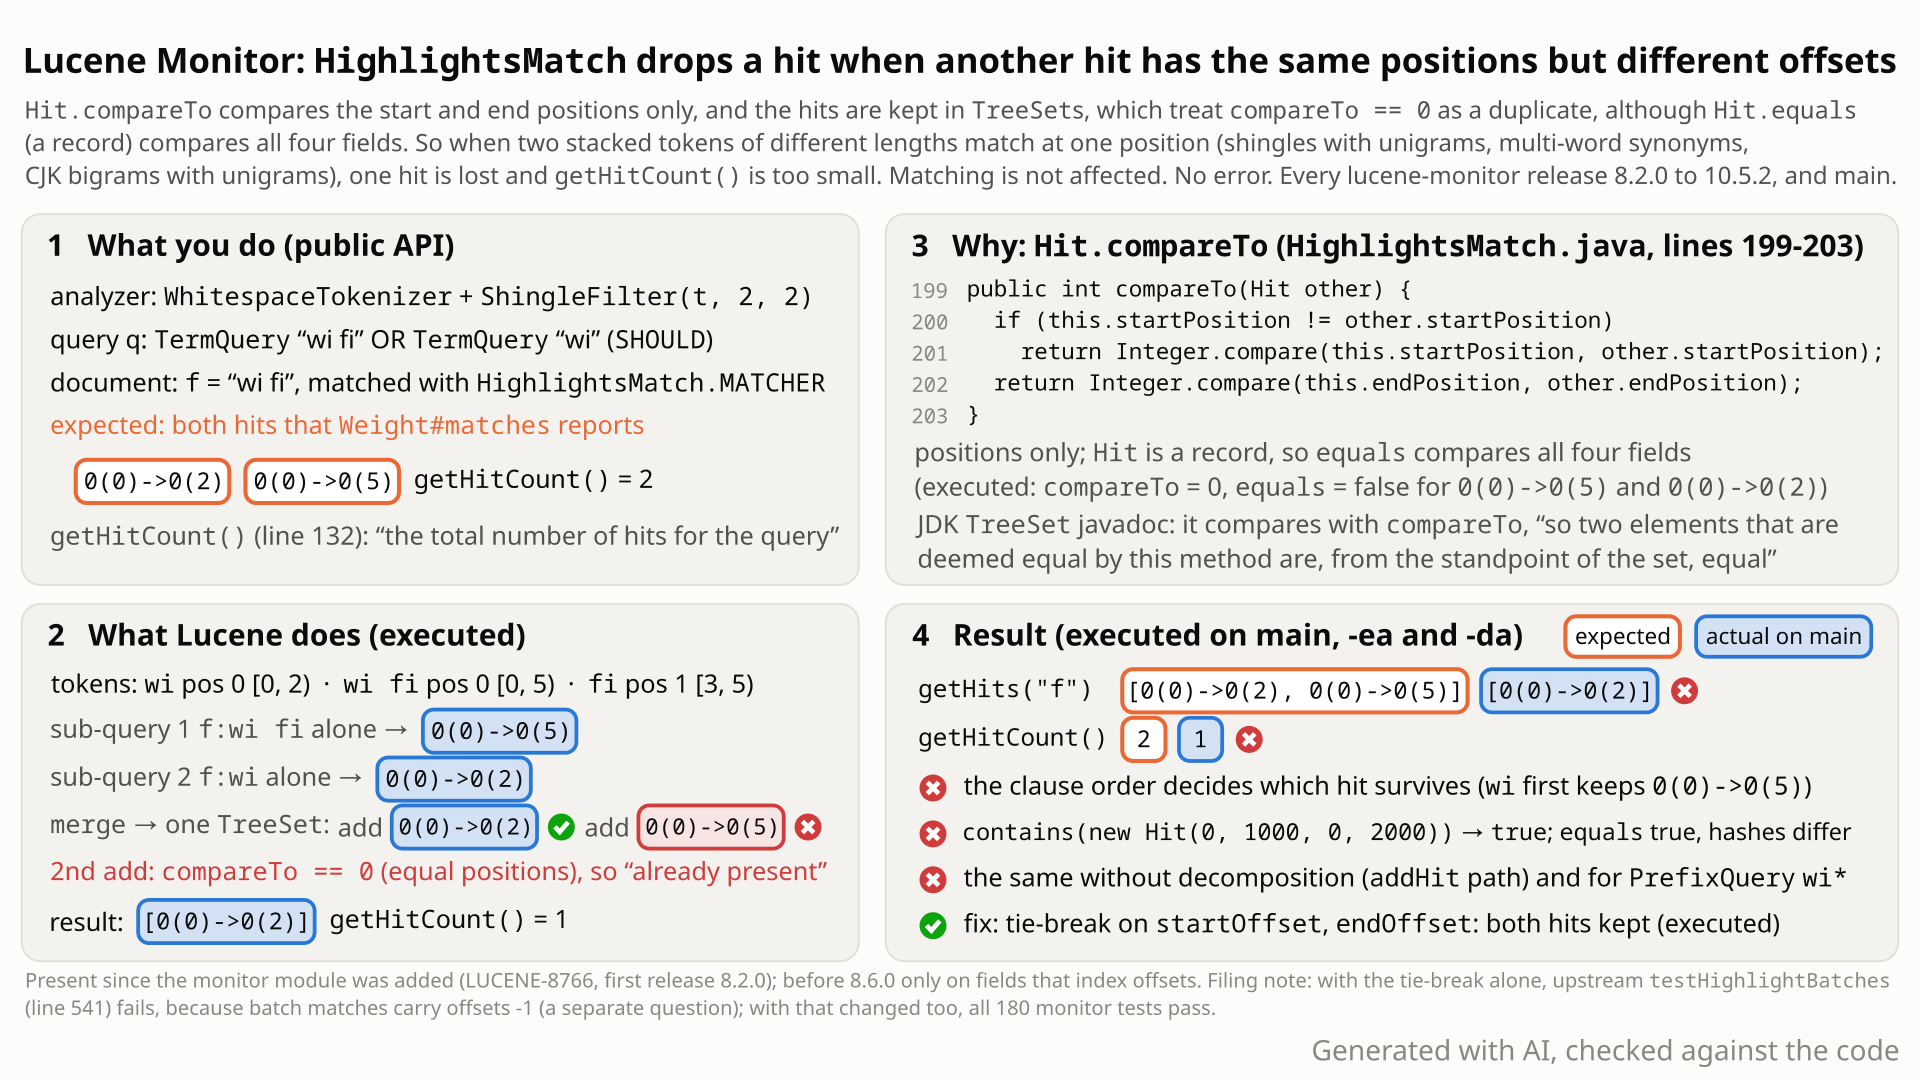
wi fi OR wi), what Lucene does (both sub-query hits merged into one TreeSet, where the second add is dropped because compareTo is 0), why (Hit.compareTo compares positions only) and the result on main: 2 hits expected, 1 kept. Select the still to open it at full size. Generated with AI, checked against the code.- You build a
Monitorwhose analyzer adds two-word shingles (ShingleFilter(2, 2), unigrams kept). The textwi fithen has the tokenswi(characters 0-2) andwi fi(characters 0-5) at the same position, 0. - You register
wi OR "wi fi"and match the documentwi fiwithHighlightsMatch.MATCHER. You expect the two hits thatWeight#matchesreports,0(0)->0(2)and0(0)->0(5)(startPosition(startOffset)->endPosition(endOffset)), andgetHitCount()= 2. - Instead
getHits("f")is[0(0)->0(2)]andgetHitCount()is 1, silently. A multi-word synonym does the same: withguinea pig => cavy, the queryguinea OR cavykeepscavy(characters 0-10) and losesguinea(0-6). - The cause: the hits are kept in a
TreeSet, which treats two elements as the same whencompareToreturns 0, andHit.compareTocompares positions only.Hit.equals(a record over all four numbers) says the two hits differ. - The same comparator makes
getHits("f").contains(new Hit(0, 2, 0, 4))true for a set holding only0(0)->0(2), and makes two matches with different hitsequalswhile their hash codes (4564, 6480) differ. Which queries match is unaffected.
lucene-monitor applications that match with HighlightsMatch.MATCHER and analyse with stacked tokens of different lengths: ShingleFilter with unigrams, multi-word SynonymGraphFilter rules with FlattenGraphFilter, CJKBigramFilter with unigrams. Each time a query matches two such tokens, one highlight span is lost and getHitCount() is one too low. One document suffices; matching itself is unaffected.
Mechanism, terms and numbers649 words
HighlightsMatch.MATCHER reports, for every stored query that matches a document, the hits that Weight#matches finds, as Hit(startPosition, startOffset, endPosition, endOffset) records per field. It keeps them in a TreeSet, and Hit.compareTo compares the start and end positions only, although Hit is a record whose equals and hashCode use all four fields. Analyzers that stack tokens of different lengths at one position (ShingleFilter with unigrams, multi-word synonyms through SynonymGraphFilter and FlattenGraphFilter, CJKBigramFilter with unigrams) produce two different hits with equal positions, because the index stores no position length; when a query matches both, the set keeps one. For wi fi with shingles and the query wi OR "wi fi", Weight#matches reports [0(0)->0(2), 0(0)->0(5)] and HighlightsMatch returns [0(0)->0(2)], getHitCount() 1, with no error. Which hit survives depends on clause order. The same comparator makes getHits(field).contains(...) ignore offsets and lets two matches with different hits be equals while their hash codes differ. Which queries match is not affected. The fix is a tie-break on offsets in compareTo; with it alone, one upstream batch test fails because a batch reports offsets -1 for TextField, so the test must index offsets (or the batch path must change).
- Monitor: Lucene's reverse search module (
lucene-monitor). You register queries, thenmonitor.match(doc, matcher)tells you which of them match a document. The matcher decides what you get back;HighlightsMatch.MATCHERreturns aHighlightsMatchper matching query with its hits per field. - Hit:
HighlightsMatch.Hit(startPosition, startOffset, endPosition, endOffset), a public record (HighlightsMatch.java:189). It prints asstartPosition(startOffset)->endPosition(endOffset):0(0)->0(5)is position 0 to 0, characters 0 to 5. The hits come fromWeight#matches(HighlightsMatch.java:49-95). - Stacked tokens: tokens at the same position.
ShingleFilter(2, 2)keeps unigrams by default, sowi figiveswi[0,2),wi fi[0,5) andfi[3,5);wiandwi fiare both at position 0. A multi-word synonymguinea pig => cavy(original kept, flattened for indexing) putscavy[0,10) onguinea[0,6). The index stores no position length, so both hits of a pair span position 0 to 0; only the offsets tell them apart.
addHitputs every hit into aTreeSetper field:hits.computeIfAbsent(field, _ -> new TreeSet<>()).add(new Hit(...))(HighlightsMatch.java:176-179).Hit.compareTocomparesstartPosition, thenendPosition, and stops (HighlightsMatch.java:199-203). For0(0)->0(2)and0(0)->0(5)it returns 0.- A
TreeSetdecides that an element is already present whencompareToreturns 0 (its javadoc: "two elements that are deemed equal by this method are, from the standpoint of the set, equal"), so the second hit is dropped, althoughequalssays the two differ. - The default query decomposer splits
wi OR "wi fi"into two queries; when both match,CandidateMatcher.addMatchmerges their matches throughHighlightsMatch.merge(CandidateMatcher.java:75-85,HighlightsMatch.java:65-67,:142-151), which copies the hits into a newTreeSetand drops the same hit. Without decomposition, the oneWeight#matchescall loses it inaddHit. getHits(field)returns a read-only view of thatTreeSet(:125-129), socontainsanswers throughcompareToand ignores offsets;HighlightsMatch.equalscompares the hit maps (:159) and ignores offsets too, whilehashCode(:164-169) includes them.
On main a9779ef3c193: shingles, wi OR "wi fi" on wi fi: expected [0(0)->0(2), 0(0)->0(5)], got [0(0)->0(2)], getHitCount() 1. Synonym guinea pig => cavy, guinea OR cavy on guinea pig: expected [0(0)->0(6), 0(0)->0(10)], got [0(0)->0(10)]. PrefixQuery wi* over shingles keeps [0(0)->0(5)]. CJKBigramFilter with unigrams on 東京, PrefixQuery 東: Weight#matches gives 0(0)->0(1) and 0(0)->0(2), HighlightsMatch keeps 0(0)->0(2). The matches for wi and wi (hits 0(0)->0(2) and 0(2)->0(4)) are equals, with hash codes 4564 and 6480. Which hit survives depends on clause order (SHOULD(shingle, unigram) keeps 0(0)->0(2), SHOULD(unigram, shingle) keeps 0(0)->0(5)) and, in decomposed queries, on hash iteration order; the loss happened for every seed tried.
Exposure and likelihood255 words
- Who is exposed. Applications that use the monitor with
HighlightsMatch.MATCHER, for example to show which words of an incoming document matched a stored query, and whose analyzer stacks tokens of different lengths at one position. Every time a stored query matches two such stacked tokens in one document (a word and its multi-word synonym, a prefix query that matches a unigram and a shingle, a disjunction of both), one hit is silently dropped andgetHitCount()is one too low. - Opt-in on both sides. The caller picks the matcher on every
Monitor.matchcall (Monitor.java:218,:240; the other standard matchers areQueryMatch.SIMPLE_MATCHER,ScoringMatch.DEFAULT_MATCHERandExplainingMatch.MATCHER), and the analysis chain is the application's.HighlightsMatch.MATCHERis one of the module's documented standard matchers, not an expert API. - No scale needed. One document, one query, one stacked pair. Single documents, batches whose fields index offsets (a batch of plain
TextFielddocuments reports offsets -1, so its stacked hits are identical), and both the plain and the decomposed query paths are affected. - Not affected. Which queries match a document; the simple, scoring and explaining matchers; hits whose offsets are not recorded (-1), which are truly identical.
- Contract fallout.
getHits(field).contains(...)cannot detect wrong offsets (upstream's own offset assertions are affected), andHighlightsMatchobjects that areequalscan have different hash codes, which breaks hash-based collections. - How likely. Rare: it needs the matcher, a stacking analyzer and a query that matches two stacked tokens. Nobody has reported it since the
TreeSetwas introduced in 2015. Priority Low.
The test shows that Monitor's HighlightsMatch drops one of two hits at the same positions with different offsets, because HighlightsMatch.Hit.compareTo ignores offsets and the hits are kept in a TreeSet.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.monitor;

import java.io.IOException;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.shingle.ShingleFilter;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHighlightsMatchStackedHits extends LuceneTestCase {

  public void testUnigramAndShingleAtSamePosition() throws IOException {
    Analyzer shingles =
        new Analyzer() {
          @Override
          protected TokenStreamComponents createComponents(String fieldName) {
            Tokenizer t = new WhitespaceTokenizer();
            return new TokenStreamComponents(t, new ShingleFilter(t, 2, 2));
          }
        };
    Query q =
        new BooleanQuery.Builder()
            .add(new TermQuery(new Term("f", "wi")), Occur.SHOULD)
            .add(new TermQuery(new Term("f", "wi fi")), Occur.SHOULD)
            .build();
    try (Monitor monitor = new Monitor(shingles)) {
      monitor.register(new MonitorQuery("q", q));
      Document doc = new Document();
      doc.add(new TextField("f", "wi fi", Field.Store.NO));
      HighlightsMatch m = monitor.match(doc, HighlightsMatch.MATCHER).matches("q");
      // expected 2 hits, 0(0)->0(2) "wi" and 0(0)->0(5) "wi fi"; actual 1
      assertEquals(m.getHits("f").toString(), 2, m.getHitCount());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-915/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/monitor/build/libs/lucene-monitor-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.monitor.TestHighlightsMatchStackedHits
- Expected vs actual
- Expected 2 hits for
f:wi OR f:"wi fi"(two TermQuery clauses, the second on the shingle term) on "wi fi" withShingleFilter(2,2)(unigram 0(0)->0(2) and shingle 0(0)->0(5)); actual:getHitCount()is 1 (expected:<2> but was:<1>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: [0(0)->0(5)] expected:<2> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.monitor.TestHighlightsMatchStackedHits.testUnigramAndShingleAtSamePosition(TestHighlightsMatchStackedHits.java:56)Hitis a record whoseequalsuses all four numbers, andgetHitCount()promises "the total number of hits for the query".- The deliberate dedup was tested only on fully identical hits, which the fix still merges; the survivor depends on clause order.
- Upstream tests check hits via
getHits(...).contains(new Hit(...))16 times; none of them can catch a wrong offset today.
The full argument347 words
- Contract text.
Hitis a public record over(startPosition, startOffset, endPosition, endOffset)(HighlightsMatch.java:181-189).getHits(): "a map of hits per field" (:105-110);getHitCount(): "the total number of hits for the query" (:131-140). The package doc saysHighlightsMatch#MATCHERreturns "the matching queries along with the matching terms for each query" (package-info.java:46-47); the dropped hit is a different matched term covering different text. No javadoc explicitly promises that every distinctWeight#matcheshit is kept: the expectation rests on the record'sequals, this wording and the JDK contracts, a strong reading rather than a quoted guarantee. - JDK contracts.
Comparablestrongly recommends a natural ordering consistent with equals because sorted sets "behave 'strangely'" otherwise; theTreeSetjavadoc says a set with an inconsistent ordering "fails to obey the general contract of the Set interface";Set.containsandObject.hashCodeare specified throughequals. - Tests.
TestHighlightingMatcherasserts exact hits withgetHits(...).contains(new HighlightsMatch.Hit(...))16 times (14 onFIELD, 2 on"field1"/"field2"at lines 108-109; for example line 63,Hit(3, 10, 3, 14)). The tests treat offsets as part of a hit, but these assertions cannot catch a wrong offset today: they fail when no hit has the expected positions, never when only the offsets differ; the batch assertion at line 541 does not even hold (a batch returns offsets -1 forTextField), and nobody could notice.testIdenticalMatches(lines 182-198) is the deliberate dedup: the same term asMUSTandSHOULD, hits identical in positions and offsets,getHitCount()1; it passes with the fix. - History. In Luwak, the library the module was imported from,
compareTowas already position-only while hits lived in lists; commit95e9eaf5b6(2015, "Decompose DisjunctionQueries, and ensure highlights are only reported once") switched toTreeSets with only the identical-hit test.Hit.equalswas hand-written over all four fields, and flaxsearch/luwak#87 (2016) added ahashCode"compatible with the existing equals()". The donation (LUCENE-8766) and the record conversion (#13328, 10.0.0) kept all of it. No CHANGES, MIGRATE or javadoc text says that hits with equal positions are merged.
The devil's-advocate check198 words
The intended-behaviour checker built the strongest case for "dedup by position is the design": the class javadoc says it "contains the hit positions of a matching Query" (HighlightsMatch.java:36); the position-keyed TreeSet was added on purpose; Comparable only recommends consistency with equals; core's DisjunctionMatchesIterator also orders by position (DisjunctionMatchesIterator.java:197-206); and the index has no position length anyway.
Why the evidence weighs against it: the dedup commit targeted hits reported twice by decomposed clauses, which are identical in positions and offsets and stay merged with the fix (its test is no longer decomposed today, because QueryDecomposer keeps a MUST plus SHOULD query whole, QueryDecomposer.java:93-95, but it still checks that identical hits merge); the author made offsets part of a hit's identity (equals, then hashCode); the survivor depends on clause order, which no dedup policy (such as "keep the widest span") would do; and the result breaks the Set and equals/hashCode contracts and blinds the module's own offset assertions. No document promises distinct same-position hits, so this is a judgement on the evidence. The checker rated the argument weak, a cross-model reviewer moderate; the adjudication confirmed the bug with high confidence.
Recommended A1. Tie-break on offsets in Hit.compareTo, and make testHighlightBatches index offsets
Break position ties in Hit.compareTo by startOffset, then endOffset (+6/-1), so the TreeSets keep hits that differ in offsets and still merge identical ones. Pair it with a small test change: testHighlightBatches must index offsets, because a batch reports -1 offsets for TextField. Validated: the new test passes, and all 185 monitor tests pass.
     public int compareTo(Hit other) {
       if (this.startPosition != other.startPosition)
         return Integer.compare(this.startPosition, other.startPosition);
-      return Integer.compare(this.endPosition, other.endPosition);
+      if (this.endPosition != other.endPosition)
+        return Integer.compare(this.endPosition, other.endPosition);
+      // consistent with equals: the hit TreeSets must not drop a hit that differs in offsets only
+      if (this.startOffset != other.startOffset)
+        return Integer.compare(this.startOffset, other.startOffset);
+      return Integer.compare(this.endOffset, other.endOffset);
     }
All options and trade-offs5 options · 727 words
Two variants of the same one-method fix were built and run through gradle; they differ only in how they handle the one upstream test that the fix exposes. The other options were not built.
A1. Tie-break on offsets in Hit.compareTo, and make testHighlightBatches index offsets (validated by the checks) (recommended)
Hit.compareTo keeps comparing start and end positions, then compares startOffset and endOffset (+6/-1 in HighlightsMatch.java). With this alone, TestHighlightingMatcher.testHighlightBatches fails at line 541, assertTrue(m1.getHits(FIELD).contains(new HighlightsMatch.Hit(1, 4, 2, 16))): a TextField document matched in a batch of two or more documents is indexed with its own field type and gets offsets -1, while a single document goes through a MemoryIndex that records offsets. Today the assertion passes only because contains ignores offsets. The test change gives the test's three batch documents a field type that indexes offsets, so the asserted hits are what the batch really returns (all three: a batch must have one schema).
+      // a batch is indexed with the documents' own field types, so index offsets to get them back
+      FieldType withOffsets = new FieldType(TextField.TYPE_NOT_STORED);
+      withOffsets.setIndexOptions(IndexOptions.DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS);
       Document doc1 = new Document();
-      doc1.add(newTextField(FIELD, "the cell biology count", Field.Store.NO)); // matches
+      doc1.add(new Field(FIELD, "the cell biology count", withOffsets)); // matches
       Document doc2 = new Document();
-      doc2.add(newTextField(FIELD, "nope", Field.Store.NO));
+      doc2.add(new Field(FIELD, "nope", withOffsets));
       Document doc3 = new Document();
-      doc3.add(newTextField(FIELD, "biology text", Field.Store.NO));
+      doc3.add(new Field(FIELD, "biology text", withOffsets));
(plus the imports of FieldType, TextField and IndexOptions.)
     public int compareTo(Hit other) {
       if (this.startPosition != other.startPosition)
         return Integer.compare(this.startPosition, other.startPosition);
-      return Integer.compare(this.endPosition, other.endPosition);
+      if (this.endPosition != other.endPosition)
+        return Integer.compare(this.endPosition, other.endPosition);
+      // consistent with equals: the hit TreeSets must not drop a hit that differs in offsets only
+      if (this.startOffset != other.startOffset)
+        return Integer.compare(this.startOffset, other.startOffset);
+      return Integer.compare(this.endOffset, other.endOffset);
     }
Trade-offs
Hitis public andComparable: its natural ordering gains a tie-break, but only among hits with equal positions, which cannot coexist in aHighlightsMatchtoday.getHitCount()andgetHits(field)report one more hit at each stacked position: the point of the fix, but visible; a CHANGES entry under bug fixes fits.- Hits without recorded offsets (-1) stay identical and are still merged, so fields without offsets keep today's counts.
- The test change leaves the batch question open: whether a batch should record offsets for
TextFieldis a separate, disputed behaviour.
What the checks validated
- Stock
a9779ef3c193: the new test fails 4 of 4 with assertions on and off. With the tie-break: 4 of 4 pass. - Tie-break alone:
TestHighlightingMatcher20 tests, 1 failure (testHighlightBatches, line 541). - Tie-break + test change: all of
:lucene:monitor:testwith assertions on, 33 classes, 185 tests (181 existing, 4 new), 1 skipped, 0 failures; the new test andTestHighlightingMatcherwith assertions off, 24 tests, 0 failures;:lucene:monitor:check -x test(google-java-format, ecjLint, forbiddenApis) passes. The test change alone on stock:TestHighlightingMatcher20 of 20 pass. - Earlier, in the hunt: the finder's test, the independent reproducer's 5 tests, the devil's advocate's 3 probes and the version-portable check (also on 8.2.0) pass with the same tie-break;
testIdenticalMatchesstill passes, so identical hits are still merged.
Instead of changing the test, make the batch path index positions with offsets, as the single-document path does (a sketch from the separate batch-offsets candidate: +87/-2 in DocumentBatch.java); testHighlightBatches stays as it is.
Trade-offs
Bigger, and it settles a separate question on the way: TextField's field type indexes positions but not offsets, and that batch behaviour is already described in the open apache/solr#2382. Better raised separately, after A1.
What the checks validated
- Tie-break + batch change: all of
:lucene:monitor:testwith assertions on, 185 tests, 1 skipped, 0 failures.
Not built.
Trade-offs
Fixes the loss and the contracts, but drops the position-sorted iteration order that getHits() users get today.
Not built.
Trade-offs
Still needs a comparator consistent with equals for the Set and equals/hashCode contracts, invents semantics, and still loses a matched term.
Not built.
Trade-offs
Leaves the lost terms, the Set contract break and the equals/hashCode inconsistency in place.
Applications that render monitor highlights show one span too few at such positions; the open Solr integration of the monitor (apache/solr#2382) uses HighlightsMatch.
A hunt comparing the monitor's batch matching with single-document matching noticed, by reading the upstream batch test, that its offset assertion could never fail, and traced that to Hit.compareTo. The finder reduced it to a public-API test with Weight#matches as the reference; independent checkers then reproduced it with their own tests.
The method in full157 words
Method: code reading (the registry's "non-formal" tier). A hunt unit compared Monitor.match(Document[]) with Monitor.match(Document). While reading TestHighlightingMatcher.testHighlightBatches, the finder saw that its assertion on offsets (line 541) could never fail, and traced that to Hit.compareTo and the TreeSet.
- The finder wrote a public-API JUnit with
Weight#matcheson aMemoryIndexas the reference (shingles,wi OR "wi fi"), which fails on main with and without assertions, onbranch_10_6and 10.5.2, and passes with the tie-break. - It replayed the upstream monitor suite with the tie-break in its own harness: 179 of 180 pass, the one failure being
testHighlightBatches(the batch-offsets behaviour); 180 of 180 together with the batch change. (The 185 tests in the fix section come from a separate gradle run of the whole module, 181 existing tests plus the 4 new ones; the two counts are not comparable.) - Independent checks followed (see "Independent checks"), then a version sweep and this doc's gradle validation.
No prior report found (searched 2026-10-28): GitHub issues, PRs and commits, every open PR by changed files, the LUCENE JIRA archive, the Lucene mailing lists, the pre-donation Luwak repository, downstream projects and the web. The nearest item, flaxsearch/luwak#87 (2016), made Hit.hashCode match equals and never mentioned compareTo.
Searches5 searches
No issue, PR, review comment, commit, JIRA ticket, list thread or downstream report describes Hit.compareTo ignoring offsets or HighlightsMatch dropping a hit whose positions equal another hit's. Searches cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (GitHub, commits, downstream repos, lists, JIRA, web) | 2026-10-28 | 16 GitHub issue/PR queries, 3 commit queries, 2 downstream-repo queries, 20 queries over dev@, java-user@, issues@ and commits@, 4 JIRA-archive queries, 6 web queries; comments of the top 15 hits read; the finder's earlier 45-query run | 209 distinct hits (1,441 in the earlier run), none this bug |
| GitHub apache/lucene (manual) | 2026-10-28, refreshed | more than 20 gh searches: HighlightsMatch, "HighlightsMatch.Hit", monitor compareTo, monitor highlight offsets, label:module:monitor, HighlightingMatcher, getHitCount, compareTo "inconsistent with equals", monitor synonym, monitor shingle; issues and PRs created since 2026-10-24 | only #12406 and #13109 (other topics); nothing new since 2026-10-24 |
| Open PRs | 2026-10-28 | every open PR by its changed files | only #16847 touches HighlightsMatch.java, for an unrelated loop bound |
| Pre-donation repository flaxsearch/luwak | 2026-10-28 | highlight, compareTo, offsets, duplicate hits, synonym, shingle, Hit | luwak#87 (hashCode consistent with equals, 2016); commit 95e9eaf5b6 (introduced the TreeSet, 2015); luwak#143 (batch offsets); none reports this bug |
| Downstream and lists | 2026-10-28 | apache/solr, Elasticsearch, OpenSearch, Lucene.NET, lucene-grep; lists.apache.org; LUCENE JIRA archive | solr#2382 uses HighlightsMatch (batch offsets only); nothing else relevant |
Present since the monitor module was added (LUCENE-8766, 251dbe7cea8, 2019; first release 8.2.0); the position-only TreeSet comes from the Luwak library (2015). Releases 8.2.0 to 10.6.0 and main are affected (8 releases, branch_10_6 at the 10.6.0 RC1 revision and main run, the others by unchanged code); before 8.6.0 only fields that index offsets show it. Not fixed upstream.
Versions tested7 rows
Introduced by 251dbe7cea8 on master and b8773d13ad8 on branch_8x, both "LUCENE-8766: Add monitor subproject" (2019-06-13; issue #9811, review PR apache/lucene-solr#648 by @romseygeek, committed directly), the import of the Luwak library; git blame and git log -L attribute compareTo, merge and addHit to it. In Luwak, commit 95e9eaf5b6 (2015-10-05) had switched the hit lists to TreeSets while compareTo stayed position-only. The compareTo body and both TreeSet uses are the same in the tags 8.2.0, 8.8.1, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and on main; 8.8.2-8.11.3 have no tag in the history clone and are inferred. Every later edit to the file is cosmetic or API-only, including the record conversion (#13328, 10.0.0), which kept equality over all four fields. On 8.2.0-8.5.2 a single document was indexed with IndexWriter, so a plain TextField had offsets -1, the stacked hits were identical and nothing observable was lost; LUCENE-9314 (8.6.0) moved single documents to a MemoryIndex with offsets. The last upstream commit to the file is b59848c7049 (2026-04-02, a refactor).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193, branch_10_6 | affected | new gradle test 4 of 4 fail (assertions on and off); hunt test fails on main and branch_10_6; portable check 5 of 5 fail |
| 10.0.0, 10.5.2 | affected | portable check 5 of 5 fail (10.5.2 also without assertions); hunt test and independent reproducer fail on 10.5.2 |
| 9.0.0, 9.12.3 | affected | portable check 5 of 5 fail; independent reproducer 5 of 5 fail on 9.12.3 |
| 8.6.0, 8.11.4 | affected | portable check 5 of 5 fail; from 8.6.0 a plain TextField shows the loss too |
| 8.2.0, 8.5.2 | offsets fields only | portable check 5 of 5 fail with a field that indexes offsets; a plain TextField had offsets -1, so the merged hits were identical |
| 8.1.1 and earlier | no monitor module | the module did not exist |
| tie-break fix on 8.2.0 and main | not affected | portable check 5 of 5 pass; new gradle test 4 of 4 pass on main |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication each re-ran it and confirmed it; a reviewer from another model family (OpenAI GPT-5.6, reading only) called it real in its intended-behaviour review, while its refute review could not run any command and named no flaw. A credibility audit kept it, and this doc's gradle run validated the fix.
Checks and verdicts340 words
Every check ran on main a9779ef3c193 with JDK 25 on Linux aarch64 unless stated; the GPT reviews read ea57360912ed, 7 commits earlier, none of them under lucene/monitor. Neither GPT review executed Java; a separate run re-ran the finder's test each time (it failed).
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own 5-test JUnit in another package with another reference (Weight#matches on an IndexWriter index with offsets): 5 of 5 fail on main with and without assertions, 10.5.2 and 9.12.3; 5 of 5 pass with its own tie-break; upstream TestHighlightingMatcher 20 of 20 stock, 19 of 20 with the tie-break. |
| Cross-model review, refute lens | not real (low), procedural | OpenAI GPT-5.6: No command ran (two attempts), so it returned the default "not real (low)"; it named no flaw and rated the intended-behaviour argument moderate, then weak. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, blind, reading only: root cause agrees, inputs in contract, intended argument moderate; "fix fixes it" false only on the strict reading that the tie-break alone breaks testHighlightBatches. The verifier's own probe showed the clause-order survivor and the contains and equals/hashCode symptoms. |
| Intended-behaviour devil's advocate | real (medium-high) | Built the "dedup by position is the design" case and rejected it; its probe (equals/hashCode, CJK bigrams, clause order) fails 3 of 3 on main with and without assertions and on 10.5.2, and passes with the fix. |
| Adjudication | confirmed (high) | Re-ran the independent reproducer: 5 of 5 fail with and without assertions, 5 of 5 pass with only the tie-break. |
| Credibility audit | keep | Re-ran the finder's test (assertions on, new seed) and the reproducer (assertions off, new seed): both fail; impact class and score kept. |
| This doc's fix validation | fix validated | Gradle in a scratch worktree: new test 4 of 4 fail on stock and pass with the fix; all 185 monitor tests pass with the fix and the test change, and with the fix and the batch change; module check passes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 595 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,360 words
- Registry title
- Monitor HighlightsMatch drops a hit when another hit has the same positions but different offsets (for example shingles or multi-word synonyms), because HighlightsMatch.Hit.compareTo ignores offsets
- Area
- monitor / HighlightsMatch hit set (Hit.compareTo used as TreeSet identity)
- Priority
- Low, rank 479: Opt-in Monitor HighlightsMatch drops a highlight span at each stacked-token position while matching stays correct, the same output-only Monitor profile as LFV-856.
- Impact class
- silent wrong results
- Impact note
- Hits lucene-monitor applications that match with HighlightsMatch.MATCHER and analyse with stacked tokens of different lengths at one position (ShingleFilter with unigrams, multi-word synonyms through SynonymGraphFilter plus FlattenGraphFilter, CJKBigramFilter with unigrams): whenever two such tokens both match, getHits(field) and getHitCount() silently lose one of the two distinct hits that Weight#matches reports, for single documents and batches and on both the addHit and the decomposer merge path, with no error and no scale needed; which queries match is not affected, and the SIMPLE and scoring matchers are not involved.
- Summary
- You register a query such as wi OR "wi fi" (or the prefix query wi*, or guinea OR cavy with a 'guinea pig => cavy' synonym rule) in a Monitor whose analyzer stacks tokens at one position, match a document with HighlightsMatch.MATCHER, and expect both hits that Weight#matches reports: for 'wi fi' with ShingleFilter(2,2) and unigrams these are 0(0)->0(2) for 'wi' and 0(0)->0(5) for 'wi fi'. Instead HighlightsMatch keeps only one of them and getHitCount() is 1, because Hit.compareTo compares start and end positions only and the hits are kept in TreeSets, which treat compareTo == 0 as a duplicate, although Hit's own equals (a record over all four fields) says the two hits differ. Which hit survives depends on clause order, and the same root cause makes getHits(field).contains(...) ignore offsets and lets HighlightsMatch.equals return true for two objects whose hashCodes differ.
- Introduced
- 251dbe7cea8126cb7ecadc921ba444c63d06c618 on master and b8773d13ad8e249a045862249bf476c30a444461 on branch_8x (both 'LUCENE-8766: Add monitor subproject', the import of the Luwak library; issue apache/lucene#9811, review PR apache/lucene-solr#648, committed directly; the branch_8x commit shipped in 8.2.0) [read: git blame -w -M -C at 7cecf795236 and git log -L on compareTo attribute compareTo, merge and addHit to 251dbe7cea81; every later edit to the file is cosmetic or API-only, including the record conversion 942065cc3e7 (#13328, 10.0.0), which kept equality over all four components]. Pre-Lucene origin: Luwak commit 95e9eaf5b6 (2015-10-05, 'Decompose DisjunctionQueries, and ensure highlights are only reported once') switched the hit lists from ArrayList to TreeSet while compareTo stayed position-only [read, GitHub API] (2019-06-13 (251dbe7cea8 authored and committed; b8773d13ad8 committed the same day); 2015-10-05 for the Luwak TreeSet change before the donation)
- First affected version
- 8.2.0 [exec] (the first lucene-monitor release; there is no earlier good Lucene version). On 8.2.0-8.5.2 a single document was indexed through IndexWriter, so the loss shows there only for fields that index offsets; from 8.6.0 (LUCENE-9314, MemoryIndex with offsets) it also shows with a plain TextField
- Affected versions
- Every lucene-monitor release, 8.2.0 to 10.5.2 (57 releases per Maven Central metadata), 10.6.0 (the branch_10_6 head 4ae946e5a9b, the RC1 revision) and main a9779ef3c193. [exec] The version-portable history repro (5 tests, offsets-indexed field, Weight#matches on an IndexWriter index as reference) fails 5 of 5 on 8.2.0 (-ea, -da), 8.5.2, 8.6.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 (-ea, -da) and main (-ea, -da), its 2 controls pass on 8.2.0, 9.12.3, 10.5.2 and main, and the compareTo tie-break alone turns 8.2.0 and main into 5 of 5 pass; seeds 716DB29A012ECD30, 5F754D1745C2048A, 1, 2 and 3 on 8.6.0 and main also fail 5 of 5; the finder's JUnit fails on main (-ea, -da), branch_10_6 and 10.5.2, the independent reproduction's on main (-ea, -da), 10.5.2 and 9.12.3, the intended-behaviour check's probe on main (-ea, -da) and 10.5.2. [read] The other releases by code identity (the compareTo body and both TreeSet uses are unchanged in every release tag checked). Plain TextField on single documents: 8.6.0 and later [exec]; on 8.2.0-8.5.2 such a document carried offsets -1 and the collapsed hits were truly identical [exec]. Not applicable before 8.2.0 (no monitor module). Not fixed upstream: the last upstream commit to HighlightsMatch.java is b59848c7049 (2026-04-02, instanceof refactor) and upstream main c5ab3e57b9ba (2026-10-28) has no commit to lucene/monitor since 2026-10-20 [read, 2026-10-28]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (searched 2026-10-28, read-only; candidate the prior-report record, verdict new): scripted prior-report searches (16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA-archive queries, 6 web queries; 209 distinct hits, plus the finder's earlier 45-query run with 1,441 hits), more than 20 manual gh searches on apache/lucene (HighlightsMatch, HighlightsMatch.Hit, monitor compareTo, monitor highlight offsets, label:module:monitor, HighlightingMatcher, getHitCount, compareTo 'inconsistent with equals', ...), every open PR scanned by changed files, the pre-donation flaxsearch/luwak repo, apache/solr, Elasticsearch, OpenSearch, Lucene.NET, the LUCENE JIRA archive, lists.apache.org and the web; the independent reproduction, the intended-behaviour check and the adjudication each searched again. Nearest items, none the same bug: flaxsearch/luwak#87 (2016, added a Hit.hashCode consistent with equals over all four fields; nobody mentioned compareTo or the TreeSet), Luwak commit 95e9eaf5b6 (2015, introduced the TreeSet; not a report), flaxsearch/luwak#143 and apache/solr#2382 (batch offsets, the sibling candidate), #12406 and #13109 (use HighlightsMatch, other topics), #9811 (the donation, no discussion of Hit ordering). The only open PR that touches HighlightsMatch.java, #16847, changes an unrelated loop bound. Refresh 2026-10-28: 'repo:apache/lucene HighlightsMatch' still returns only #12406 and #13109; 'monitor highlight offsets' only #7093 (unrelated); none of the 18 PRs and 7 issues created since 2026-10-26 touches lucene/monitor or HighlightsMatch; no commit to lucene/monitor since 2026-10-20 (upstream main c5ab3e57b9ba).
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree, removed afterwards: the new test class on stock (4 of 4 fail, assertions on and off) and with thecompareTotie-break (4 of 4 pass);TestHighlightingMatcherwith the tie-break alone (1 failure,testHighlightBatchesline 541); all of:lucene:monitor:testwith the tie-break and the test change (185 tests, 1 skipped, 0 failures) and with the tie-break and the batch-offsets change (185, 0 failures);:lucene:monitor:check -x test. The hunt's and the verifiers' JUnit tests on main (assertions on and off),branch_10_6, 10.5.2 and 9.12.3; a version-portable check on 8.2.0, 8.5.2, 8.6.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main. JDK 25, Linux aarch64.
- Finding record
lucene/monitor/src/java/org/apache/lucene/monitor/HighlightsMatch.java:199-203 (at a9779ef3c193) (Hit.compareTo: startPosition, then endPosition only), :189 (public record Hit(int startPosition, int startOffset, int endPosition, int endOffset) implements Comparable<Hit>), :176-179 (addHit: computeIfAbsent(field, _ -> new TreeSet<>()).add(new Hit(...))), :142-151 (merge: TreeSet per field), :153-168 (HighlightsMatch.equals/hashCode over the hits map), :36 (class javadoc 'contains the hit positions of a matching Query'), :106 ('a map of hits per field'), :132 ('the total number of hits for the query')
- The finding in 30 seconds
lucene/monitor/src/java/org/apache/lucene/monitor/HighlightsMatch.java:176-179 (at a9779ef3c193) (addHit, TreeSet), :189 (record Hit), :199-203 (compareTo), :142-151 (merge), :65-67 (resolve), :125-129 (getHits(field)), :153-169 (equals/hashCode), :49-95 (MATCHER, buildMatch)lucene/monitor/src/java/org/apache/lucene/monitor/CandidateMatcher.java:75-85 (at a9779ef3c193) (addMatch calls resolve)
- Who is affected
lucene/monitor/src/java/org/apache/lucene/monitor/Monitor.java:218, (at a9779ef3c193) :240 (match takes a MatcherFactory); package-info.java:35-48 (the matcher types: QueryMatch#SIMPLE_MATCHER, ScoringMatch#matchWithSimilarity, ExplainingMatch#MATCHER, HighlightsMatch#MATCHER); ScoringMatch.java:49-50 (DEFAULT_MATCHER)
- Why it looks unintended
lucene/monitor/src/java/org/apache/lucene/monitor/HighlightsMatch.java:36 (at a9779ef3c193) (class javadoc), :105-110, :131-140 (getHits/getHitCount javadoc), :181-189 (record Hit)lucene/monitor/src/java/org/apache/lucene/monitor/package-info.java:46-47 (at a9779ef3c193)lucene/monitor/src/test/org/apache/lucene/monitor/TestHighlightingMatcher.java:63, (at a9779ef3c193) :77, :182-198 (testIdenticalMatches), :108-109, :541 (16 getHits(...).contains(new Hit(...)) assertions, 14 on FIELD)lucene/core/src/java/org/apache/lucene/search/DisjunctionMatchesIterator.java:197-206 (at a9779ef3c193)lucene/monitor/src/java/org/apache/lucene/monitor/QueryDecomposer.java:93-95 (at a9779ef3c193) (a MUST plus SHOULD query is kept whole)
- Suggested fix
lucene/monitor/src/java/org/apache/lucene/monitor/DocumentBatch.java:87 (at a9779ef3c193) (batch: IndexWriter with the documents' field types), :108 (single document: MemoryIndex(true, true))lucene/monitor/src/test/org/apache/lucene/monitor/TestHighlightingMatcher.java:541 (at a9779ef3c193)
- TestHighlightsMatchStackedHits.java (JUnit test):
repro/LFV-915/src/org/apache/lucene/monitor/TestHighlightsMatchStackedHits.java(59 lines)
Summary card (bug.png), made in parallel with this doc from the diagram's own probe on main a9779ef3c193.
assets/LFV-915/bug.png(595 KB)