A similarity-threshold vector query can carry a filter, which it runs. But its visit() only says "I am a leaf", so the clause-counting visitor never sees the filter's clauses. The filter is checked only on its own, so the clauses of several filters are never added up.
- QueryVisitor. Every Lucene query has a
visit(QueryVisitor)method that should walk the whole query tree: "Recurse through the query tree, visiting any child queries." Tools use it to collect terms, estimate memory or count clauses. - The clause limit. Before searching,
IndexSearcherwalks the rewritten query with a counting visitor and throwsTooManyNestedClauseswhen the total goes pastmaxClauseCount(1,024 by default; strictly, at the 1,026th counted clause), however the clauses are nested. - Vector similarity queries.
FloatVectorSimilarityQueryandByteVectorSimilarityQuery(@lucene.experimental, since 9.10.0) return every document whose vector is similar enough to a target. An optional filter, anyQuery, restricts which documents qualify.
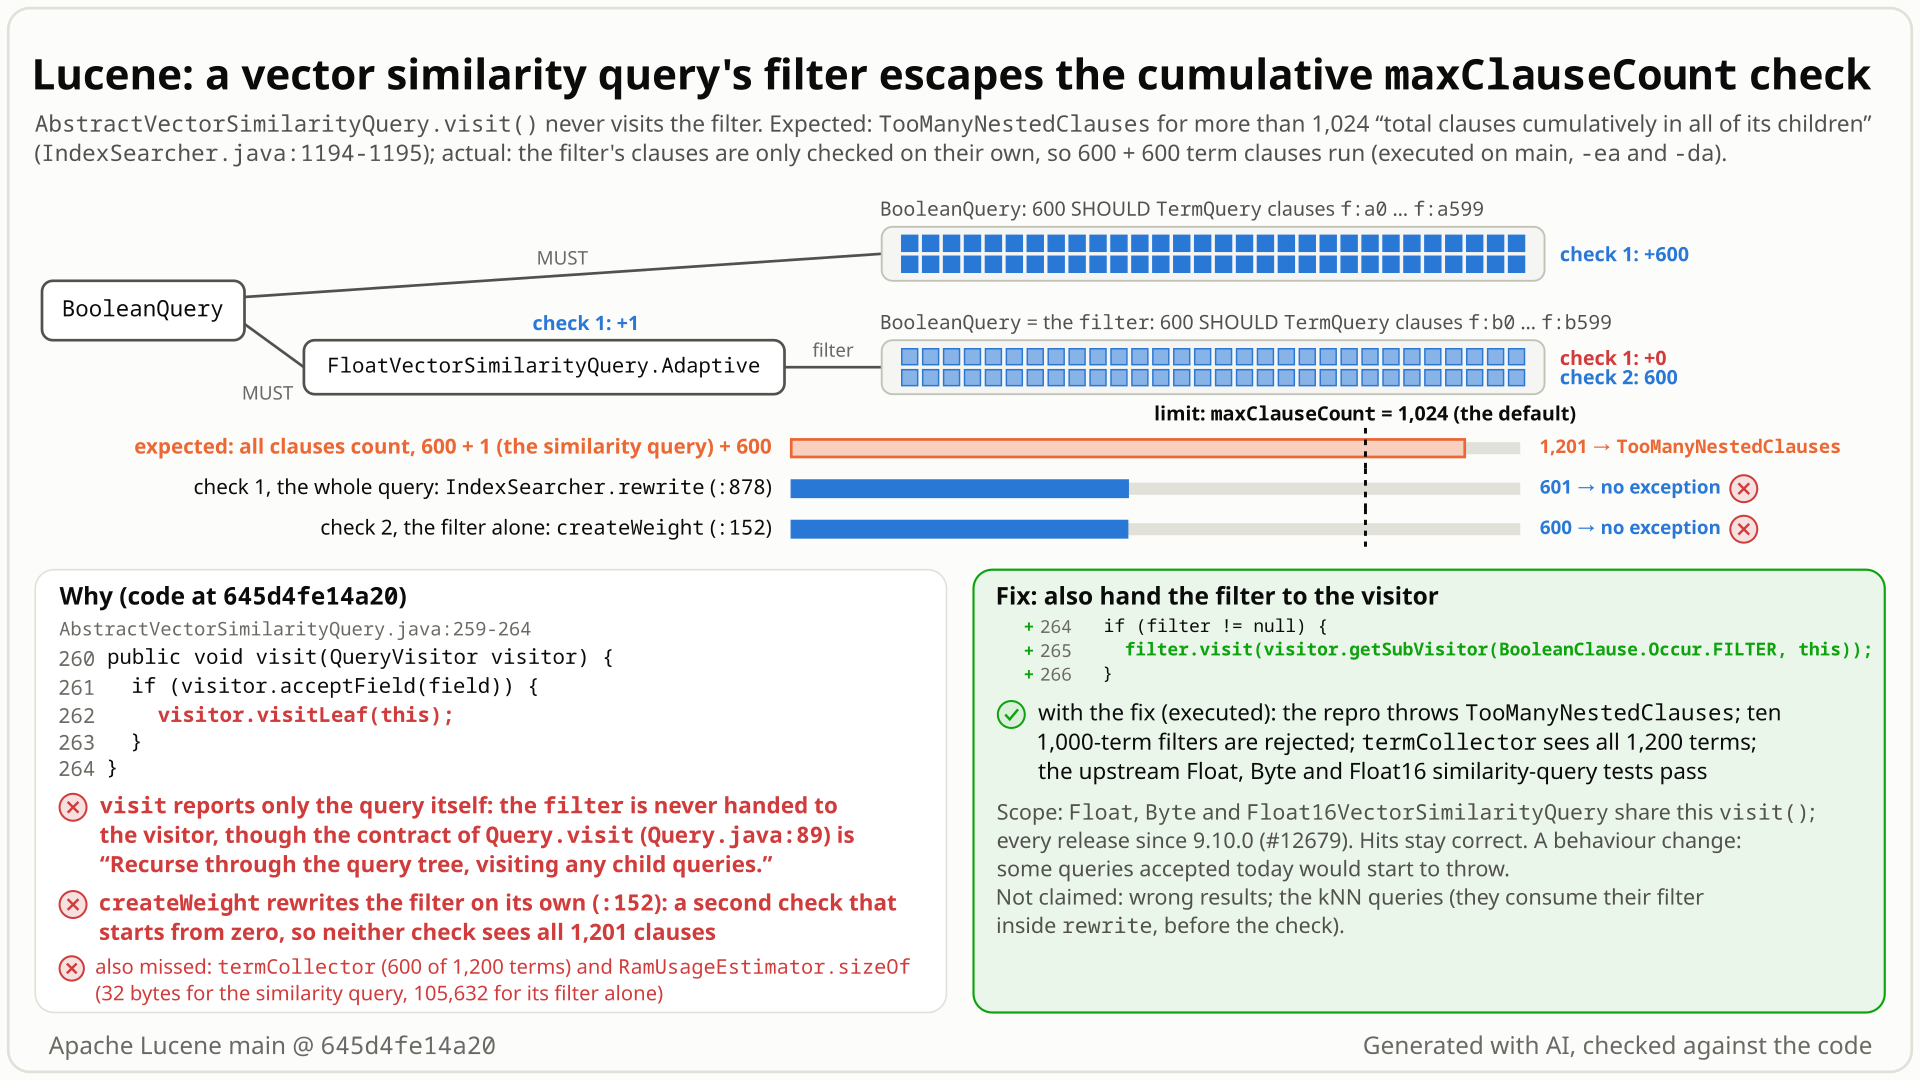
sizeOf(query, 32); the term count is over the whole query. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
BooleanQuerywith two MUST clauses: a disjunction of 600 term queries, and aFloatVectorSimilarityQuerywhose filter is another 600-term disjunction. That is 1,200 term clauses. Search it with a plainIndexSearcherand the defaultmaxClauseCountof 1,024. - You expect
TooManyNestedClauses, the limit on "total clauses cumulatively in all of its children". Move the 600 filter terms into a sibling FILTER clause and that is what you get: the check counts 1,201. - Instead the search runs. The similarity query's
visit()reports itself as one leaf and never visits its filter, so the check counts 601: the 600 terms plus 1. - The filter still runs and is checked, but alone:
createWeightrewrites it separately, against a fresh budget of 1,024. Each filter is capped, but filters never add up: 10 similarity queries with 1,000-term filters each are accepted. - Other visitors miss it too:
QueryVisitor.termCollectorfinds 0 of the filter's 600 terms, andRamUsageEstimator.sizeOfreports 1,024 bytes instead of 701,824. A 3-line fix tovisitrestores all three.
Applications that put a filter on the experimental vector similarity queries and count on maxClauseCount to bound the whole query, or that inspect such queries with a visitor (term extraction, a term-extracting highlighter, RamUsageEstimator.sizeOf). The default searcher and limit apply. Hits stay correct; the visible effect is a missing exception, so it goes unnoticed.
Mechanism, terms and numbers569 words
FloatVectorSimilarityQuery, ByteVectorSimilarityQuery and, on the unreleased 11.x line (main and branch_11x), Float16VectorSimilarityQuery (all @lucene.experimental) take an optional filter and execute it in createWeight, but the visit() they inherit from AbstractVectorSimilarityQuery only calls visitor.visitLeaf(this). IndexSearcher's cumulative clause check walks the rewritten query with a visitor, so it never counts the filter's clauses; the filter is checked only on its own, when createWeight rewrites it. A query of 600 term clauses plus a similarity query with a 600-term filter runs at the default maxClauseCount of 1,024, while the same 1,200 clauses with the filter as a sibling FILTER clause are rejected; ten similarity queries with 1,000-term filters run too. QueryVisitor.termCollector and RamUsageEstimator.sizeOf (on the 11.x line also the query cache's key estimate) miss the filter for the same reason. Search hits are correct. The gap is as old as the API: every release from 9.10.0 to 10.6.0 and main. A 3-line fix visits the filter through a FILTER sub-visitor.
// :145-152 createWeight: the filter is executed, after a rewrite (and so a clause check) of its own
final Weight filterWeight =
    filter == null
        ? null
        : searcher.createWeight(searcher.rewrite(filter), ScoreMode.COMPLETE_NO_SCORES, 1);

// :259-264 visit: the whole query reports one leaf; the filter is never visited
public void visit(QueryVisitor visitor) {
  if (visitor.acceptField(field)) {
    visitor.visitLeaf(this);
  }
}- The check.
IndexSearcher.searchrewrites the query first (IndexSearcher.java:750-754).rewrite(:871-880) rewrites until stable and then callsquery.visit(getNumClausesCheckVisitor())(:878). That visitor (:891-932) returns itself fromgetSubVisitorand counts one pervisitLeaf,consumeTermsorconsumeTermsMatchingcall. Each call first throwsTooManyNestedClausesif the count is already abovemaxClauseCount, then adds one (:907-929), so at the default 1,024 the 1,026th counted unit throws. It counts visitor callbacks, not terms as such; for the repro'sTermQuerydisjunctions that is one per term. - The filter stays in the tree. Neither
AbstractVectorSimilarityQuerynor its subclasses overriderewrite, so the rewritten query still holds the filter (protected final Query filter,:57). It is skipped only becausevisitdoes not descend. - The filter's own check.
searcher.rewrite(filter)increateWeightstarts a new counting visitor, so a filter over the limit on its own still throws, but its clauses are never added to the rest of the query. - Counted, executed probe. For the repro's query a replica of the check's visitor counts 601 (600 terms + 1 leaf); with the 600 filter terms as a sibling FILTER clause it counts 1,201; the filter alone counts 600. With the fix the repro's query counts 1,201 too. An independent fact check found the same counts on the rewritten tree and through
IndexSearcher.rewrite's real acceptance threshold. - Other visitors.
QueryVisitor.termCollector(QueryVisitor.java:86-98) collects only fromconsumeTermsand ignoresvisitLeaf(:53-58): 0 of the filter's 600 terms.RamUsageEstimator.sizeOfwalksvisitand charges a lone leaf the default 1,024 bytes: 1,024 instead of 701,824. On the unreleased 11.x line only (main andbranch_11x),LRUQueryCachesizes cached query keys this way, withsizeOf(query, 32)(LRUQueryCache.java:465-471, #15124): 32 bytes for the similarity query, 105,632 for its filter alone (executed); released 10.x charges such queries a fixed default. Caching is off by default. - For comparison.
ConstantScoreQuery.visitpasses its query a FILTER sub-visitor (ConstantScoreQuery.java:76-79), andBooleanQueryvisits FILTER clauses, so the same filter in either is counted and collected.
Exposure and likelihood206 words
- Who. Users of
FloatVectorSimilarityQuery,ByteVectorSimilarityQueryor the unreleased 11.x line'sFloat16VectorSimilarityQuerywith a filter. No Lucene query parser builds them; the application calls the constructor. Downstream (read on default branches, not run): Solr's{!vectorSimilarity}parser passes the request's pre-filter or filter queries as this filter, and the OpenSearch k-NN plugin usesFloatVectorSimilarityQueryfor radial search; Elasticsearch has its own similarity query. - Default vs opt-in. Opt-in: the
@lucene.experimentalsimilarity query with a filter. Default: codec,IndexSearcher,maxClauseCount1,024. - What it takes. The total must pass the limit only through filter clauses, each filter staying within the limit on its own (600 + 600 in the repro). One filter above the limit is still rejected. Large id lists usually go into a
TermInSetQuery, which counts as one clause, so real queries rarely get there (likelihood: rare). - Effect. A query of N filtered similarity queries can carry about N x
maxClauseCountclauses (executed: 10 and 50 queries with 1,000-term filters accepted). Visitor-based tools under-report the query: no filter terms, a 1,024-byte size estimate, and on the 11.x line a query-cache key charge that ignores the filter (32 bytes). No error, no wrong hits, no index effect; the work stays proportional to the query the application built.
One JUnit test, no index: an empty MultiReader and a plain IndexSearcher with the default limit of 1,024, because the check runs before any segment is searched. The query holds 600 term clauses plus a similarity query whose filter holds 600 more, and the test expects TooManyNestedClauses.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.index.MultiReader;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestVectorSimilarityQueryFilterClauseCount extends LuceneTestCase {

  private static Query disjunction(String prefix, int n) {
    BooleanQuery.Builder b = new BooleanQuery.Builder();
    for (int i = 0; i < n; i++) {
      b.add(new TermQuery(new Term("f", prefix + i)), Occur.SHOULD);
    }
    return b.build();
  }

  public void testFilterClausesCountTowardsMaxClauseCount() throws Exception {
    Query query =
        new BooleanQuery.Builder()
            .add(disjunction("a", 600), Occur.MUST)
            .add(
                new FloatVectorSimilarityQuery.Adaptive(
                    "v", new float[] {1, 0}, 0f, disjunction("b", 600)),
                Occur.MUST)
            .build();
    IndexSearcher searcher = new IndexSearcher(new MultiReader());
    // expected: TooManyNestedClauses (1,200 term clauses > default maxClauseCount 1024); actual: the filter's 600 are not counted, no exception
    expectThrows(IndexSearcher.TooManyNestedClauses.class, () -> searcher.search(query, 1));
  }
}
cp TestVectorSimilarityQueryFilterClauseCount.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/ && cd $LUCENE && ./gradlew :lucene:core:test --tests TestVectorSimilarityQueryFilterClauseCount -Ptests.seed=DEADBEEF
- Expected
TooManyNestedClauses: 1,200 term clauses are more than the defaultmaxClauseCountof 1,024, and the same clauses with a FILTER clause are rejected.- Observed
- No exception ("Expected exception TooManyNestedClauses but no exception was thrown"), with assertions on and off: the check counted 601.
More files, environment, full output303 words
Public API plus LuceneTestCase, in package org.apache.lucene.search only to sit next to Lucene's own tests. new IndexSearcher rather than newSearcher keeps it deterministic, and an empty MultiReader mirrors TestMaxClauseLimit. Each part (600) is under the limit and the sum (1,200) far above it, so the counter's boundary rule plays no part.
It compiles against 10.5.2 and later, where FloatVectorSimilarityQuery.Adaptive exists. For 9.10.0 to 10.5.1 use the old constructor, new FloatVectorSimilarityQuery("v", new float[] {1, 0}, 0f, 0f, filter); the result is the same.
Regression test: this same test; it passes with the recommended fix and fits as one more method of TestFloatVectorSimilarityQuery or TestMaxClauseLimit. Formatting: google-java-format wraps its one long comment line, nothing else.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails with assertions on and off; also fails on 10.6.0 and 10.5.2; the finder's old-constructor release variant fails on 10.5.1, 10.0.0, 9.12.3 and 9.10.0 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the code path is platform-independent) |
cp TestVectorSimilarityQueryFilterClauseCount.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE
./gradlew :lucene:core:test --tests TestVectorSimilarityQueryFilterClauseCount -Ptests.seed=DEADBEEF
# assertions off (production-like): add -Ptests.asserts=false
# gradle, stock main 645d4fe14a20, assertions on, seed DEADBEEF (stack frames and environment lines dropped)
TestVectorSimilarityQueryFilterClauseCount > testFilterClausesCountTowardsMaxClauseCount FAILED
    junit.framework.AssertionFailedError: Expected exception TooManyNestedClauses but no exception was thrown
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:2DC7ECFDF571A694]:0)
:lucene:core:test (FAILURE): 1 test, 1  failure

# the same with assertions off: 1 test, 1 failure; with the fix: 1 test, 0 failures (on and off)
# the repro runner: fails on main (on, off), on the 10.6.0 and 10.5.2 jars (off)

# supporting probe (not the repro), stock main vs the fix:
                                                         stock      with the fix
clause-check count, BQ(MUST a600, MUST simQ(filter=b600))   601        1201
clause-check count, BQ(MUST a600, FILTER b600, MUST simQ)   1201       1201
clause-check count, the filter b600 alone                   600        600
termCollector over simQ(filter=b600)                        0 terms    600 terms
RamUsageEstimator.sizeOf(simQ(filter=b600)) 1024 701824Query#visitshould visit "any child queries", and the limit counts clauses "cumulatively in all of its children"; the filter it runs acts as one.- LUCENE-8811 made the limit a visitor walk so splitting a query cannot evade it; LUCENE-8849 treated this gap as a bug.
- kNN queries consume their filter in rewrite; this one keeps it in the checked tree.
The full argument318 words
- The contract.
Query.java:88-93: "Recurse through the query tree, visiting any child queries."QueryVisitor.java:53-58:visitLeafis "Called by leaf queries that do not match on terms".IndexSearcher.java:1193-1199:TooManyNestedClausesis "Thrown when a client attempts to execute a Query that has more than getMaxClauseCount() total clauses cumulatively in all of its children"; the check's javadoc (:891-895) speaks of "the total number of clauses that a query and its children cumulatively have". - The design. CHANGES LUCENE-3041 (
lucene/CHANGES.txt:6469-6473): queries should "either pass the visitor down to any child queries, or call a visitX() or consumeX() method on it". LUCENE-8811 (:4681-4684): the clause checks "are now implemented using a QueryVisitor and apply to all queries"; MIGRATE.md:1533: "max clause count checks on all types of queries". On #9855 (LUCENE-8811) Adrien Grand wrote that it "removes ways to by-pass the maximum clause count by splitting boolean queries into multiple sub boolean queries". - Precedent. LUCENE-8849 "DocValuesRewriteMethod.visit wasn't visiting its embedded query" (
CHANGES.txt:5800; its fix also chose a FILTER sub-visitor, but never passes it on to the wrapped query,DocValuesRewriteMethod.java:73-77, which is the registry's LFV-038) and LUCENE-9050 (:6163-6164) were treated as bugs. On the open #14756, Luca Cavanna wrote "for the purpose of visiting, we should visit all variants". - No recorded intent. The leaf-only
visitwas copied fromAbstractKnnVectorQueryin #12679; no comment or review there mentionsvisit,QueryVisitorormaxClauseCount. No test covers it;TestMaxClauseLimit.testLargeDisjunctionMaxQueryasserts the nested walk for another composite. - How strong the case is. Persuasive, not conclusive: LUCENE-3041 lets a query "call a visitX() or consumeX() method" instead of descending, so a leaf callback is allowed as such, and
Query#visitdoes not define whether a filter held by a query is one of its children. What no contract allows for is an executed child that no visitor sees; maintainers may still consider vector queries opaque by design.
The devil's-advocate check177 words
The strongest case (the intended-behaviour verifier, weighed by the adjudication): every Lucene vector query is an opaque visitor leaf; ToParentBlockJoinQuery has a leaf visit and, when no child scores are needed, an inner rewrite of its child with its own budget (ToParentBlockJoinQuery.java:90-92, 98-108; with child scores no separate check runs, :109-121), and that branch is accepted the same way; the filter is still checked on its own; and maintainers called the limit approximate (Alan Woodward on LUCENE-8811: "it wouldn't be exact").
Why it fails: the kNN queries use up their filter inside rewrite (AbstractKnnVectorQuery.java:74-97), so no visit could expose it to the check; this query keeps the filter in the checked tree. Block-join children match other documents, which is why they stay out of term extraction; this filter matches the same documents, like a FILTER clause. "Approximate" was said about counting rules, not about skipping executed sub-queries, and nothing documents the exclusion. Maintainers could still choose to keep vector queries opaque and document it; that is why the adjudication's confidence is medium.
Recommended Visit the filter through a FILTER sub-visitor
In AbstractVectorSimilarityQuery.visit, also visit the filter through a FILTER sub-visitor, as ConstantScoreQuery does (3 lines). The repro then throws as expected; the 8 closest suites and all 2,340 core search-package tests pass. A behaviour change: oversized queries that run today will throw, so maintainers may want it on the 11.x line only, not in 10.x.
if (visitor.acceptField(field)) {
  visitor.visitLeaf(this);
}
if (filter != null) {
  filter.visit(visitor.getSubVisitor(BooleanClause.Occur.FILTER, this));
}
All options and trade-offs3 options · 609 words
Option A was built and run through gradle. B (rewrite the filter in place) needs the same visit change and more code; C (document the gap) leaves the contract broken. Workarounds that need no fix: count the filter's clauses yourself before searching, keep large id filters in one TermInSetQuery, or set a QueryTimeout. Not part of this fix: the kNN queries' visit, which cannot help their clause check because they consume the filter in rewrite.
After the leaf call, if (filter != null) filter.visit(visitor.getSubVisitor(BooleanClause.Occur.FILTER, this)); in the shared base class, so Float, Byte and Float16 all get it. FILTER because the filter restricts matching without scoring, like a FILTER clause; it is visited whatever acceptField(field) says about the vector field, since its own leaves check their own fields. LUCENE-8849 also chose a FILTER sub-visitor (its fix never passes it on, see LFV-038).
if (visitor.acceptField(field)) {
  visitor.visitLeaf(this);
}
if (filter != null) {
  filter.visit(visitor.getSubVisitor(BooleanClause.Occur.FILTER, this));
}
Trade-offs
- Behaviour change. A query whose filters take the cumulative count over the limit now throws
TooManyNestedClauses, as other composites do. The code change is limited tovisit, so matching is expected to stay the same and queries under the limit keep their hits; visitor consumers and query-cache accounting change (next point). - Visitors see the filter. Term collectors and term-extracting highlighters now get the filter's terms (600 instead of 0 in the probe), as they do for a FILTER clause;
RamUsageEstimator.sizeOfgives 701,824 bytes instead of 1,024, and on the 11.x line the query cache'ssizeOf(query, 32)gives 105,632 instead of 32 (executed; no cache run, so admission and eviction were not observed). - The similarity queries become stricter than the kNN queries, whose filter keeps a separate budget because
rewriteconsumes it. - The filter is still also rewritten and checked on its own in
createWeight(a cheap second walk, left unchanged). Not benchmarked.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(OpenJDK 25.0.3, seed DEADBEEF): stock, the minimal test fails with assertions on and off; with the fix it passes on and off. - The closest suites (8 classes: the Float, Byte, Float16 and Explicit similarity-query tests,
TestVectorSimilarityCollector,TestMaxClauseLimit,TestQueryVisitor), assertions on and off: 8 classes, 97 tests, 0 failures (3 skipped). - Every test class of
org.apache.lucene.searchin:lucene:core, assertions on: 215 classes, 2,340 tests, 0 failures (49 skipped). :lucene:coreecjLint and forbiddenApis (main and test) with the fix and the test: pass.- google-java-format passes on the fix and asks only to wrap the test's one long comment line; with that line wrapped it passes too.
- Earlier: the finder's 2 tests and the 34 tests of the Float and Byte similarity-query suites pass with it; the independent reproducer's own identical fix passes its 7 tests; on 9.10.0 the fix passes the old-API variant.
Override rewrite to return a new similarity query with the rewritten filter, and let createWeight use it without its own searcher.rewrite.
Trade-offs
Removes the second clause walk and makes the post-rewrite tree honest, but still needs the visit change, and touches equals/hashCode (query-cache keys) and every subclass. More change for no extra correctness. Not run.
Say in the class javadoc that the filter's clauses are checked only on their own and that visitors do not see the filter.
Trade-offs
A legitimate choice for consistency with the kNN queries, but it leaves the contradiction with Query#visit and the cumulative limit, and visitor tools still miss the filter. Not run.
Applications that rely on maxClauseCount alone to bound user-built filters inside vector similarity queries are not protected and should bound those filters themselves.
A hunt unit compared IndexSearcher's clause limit with a model of the clauses each query really executes, over 1,440 small queries built from 16 wrapper queries. The similarity query with a filter was under-counted in 35 of its 90 checks; a bytecode scan showed its filter is never visited, and a public-API JUnit confirmed it.
The method in full211 words
Method: semi-formal (the hunt's tier for bounded-exhaustive checks of the real jar against a reference model). The hunt unit's lens was queries that execute an embedded query but hide it from QueryVisitor.
- Differential check.
HiddenSubqueryTVbuilt every combination of 16 wrapper sites x primary leaves {1, 2, 4} x hidden leaves {1..10} x copies {1, 2, 3} (1,440 checks atmaxClauseCount8) and compared IndexSearcher's verdict with a model that counts the clauses each query executes, with assertions on and off. The site BQ(MUST P, MUST FloatVectorSimilarityQuery(filter = H)) was under-counted in 35 of its 90 checks. TheBooleanQuery,ConstantScoreQueryandDisjunctionMaxQuerycontrols had 0 mismatches in 270, and the model also caught the knownIndexOrDocValuesQueryover-count, so it is not vacuous. - Bytecode scan. A JDK ClassFile scan over 142 concrete
Queryclasses in 17 module jars flaggedAbstractVectorSimilarityQuery.filteras a field that is executed but never visited (an earlier unit's scan had the same row, triaged there for matching only). - Reduction. The finding was reduced to a public-API JUnit (float and byte), later minimized to the one-test repro above. Not claimed: the kNN queries and
RescoreTopNQueryshow the same count gap in the harness, but consume their sub-query inrewrite, so novisitchange could help there.
No prior report found: 54 tool queries and 38 manual GitHub searches on 2026-10-28 (issues, PRs, commits, mailing lists, the JIRA archive, downstream projects, the web), a scan of all 411 open PRs, and a GitHub re-check on 2026-10-31. Closest: LUCENE-8849, the same gap treated as a bug in another class.
Searches3 searches
- Nearest items, none a report: #12679 (the origin; its review never discusses
visit); #9855 (LUCENE-8811, the cumulative check and its intent); #14756 and open PR #16175 (the opposite over-count ofIndexOrDocValuesQuery); #9892 (LUCENE-8849) and #10092 (LUCENE-9050), the same kind of gap treated as bugs in other classes; opensearch-project/k-NN#3299, where a downstream query builder'svisitnow visits its filter, at another layer and without mentioning Lucene's queries. - Open PRs: 5 of the 411 open PRs touch
AbstractVectorSimilarityQuery.java(#16847, #16204, #15802, #13594, #13595); none changesvisit. Of the 56 PRs updated since 2026-10-28, the only one that changes a cited source file on main is the open #16952 (bulk-scoring upper bound inIndexSearcher.javaandLRUQueryCache.java, not the key sizing), with no clause-count, visit or query-size change. The others that list a cited file touch onlyCHANGES.txtorMIGRATE.md(#16806, #16816, #16857), another branch (#16911,branch_10x), or are a stale 2025 branch-merge PR (#14673). None changesvisit, the clause check or the fix site. - Same contract, other fix sites (registry): LFV-038 (
DocValuesRewriteMethod) and LFV-872 (IndriQuery). - Limits: keyword search only (the open-PR file scan finds fixes whatever their wording); private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive), downstream Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the web | 2026-10-28 | a scripted prior-report search, 54 queries (2,452 distinct hits, 0 high, 26 medium, read); 38 manual GitHub searches; the comment and review threads of 18 related issues and PRs; 4 Solr JIRA queries | no report of this gap or its symptoms |
| Open apache/lucene PRs | 2026-10-28 | changed-file scan of all 411 open PRs, diffs of those touching the fix-site file grepped for visit changes | 5 touch the file, none changes visit |
| GitHub (apache/lucene) | 2026-10-31 | "VectorSimilarityQuery visit"; "QueryVisitor filter", "maxClauseCount vector", "TooManyNestedClauses", "visit filter similarity", "similarity query filter clause" updated since 2026-10-28; the files of the 56 PRs updated since then; the commits on the fix-site file | nothing new; last commit on the file still #16104 (2026-05-28) |
Introduced with the class in 9.10.0 by #12679 (cd195980ecb, merged 2023-12-11), whose leaf-only visit was copied from the kNN queries. Every release since, 9.10.0 to 10.6.0, and main are affected; upstream has not changed visit.
Versions tested6 rows
Introduced by cd195980ecbcb45e19ce9465854fed0b6be79ea7 "Add support for similarity-based vector searches (#12679)" (Kaival Parikh; merged by Benjamin Trent on 2023-12-11; branch_9x backport 8089b8c9d33 plus 02127766776, a Java 11 adjustment of createWeight). It created AbstractVectorSimilarityQuery with both halves of the gap: the leaf-only visit and the separate rewrite of the filter. Not a regression, so no bisect. Float16VectorSimilarityQuery (#16735, unreleased, on the 11.x line only: main and branch_11x) inherits it. The visitor-based cumulative check (LUCENE-8811) was already in 9.0.0.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (gradle and runner); passes with the fix |
| 10.6.0, 10.5.2 | affected | minimal test fails (assertions off); finder's and verifiers' tests fail too |
| 10.5.1, 10.0.0, 9.12.3, 9.10.0 | affected | the old-constructor variant fails; on 9.10.0 the fix passes it |
| the other releases from 9.10.0 to 10.5.2 | read | unchanged visit and createWeight in every tag |
| 9.9.2 | no API | no similarity queries (the repro does not compile) |
upstream main 2f424fd428da (2026-10-30) | read | not fixed; last commit on the file is #16104 (2026-05-28) |
Confirmed by an independent reproducer, a devil's-advocate verifier, a works-as-designed review by a reviewer from another model family (OpenAI GPT-5.6) and an adjudication; re-run by a credibility audit, the minimization and this doc's gradle run. The only dissent was a procedural "not real" from a read-only review that named no flaw.
Checks and verdicts361 words
No cross-model review could run code (the 2026-10-31 cross-model fact check was read-only too); the executed checks are the finder's, the independent reproducer's, the separate re-runs for the cross-model reviews, the devil's advocate's, the adjudication's, the registration check's, the audit's, the minimization's, this doc's and the independent fact check's.
| Check | Verdict | What it found |
|---|---|---|
| Finder (differential check, then JUnit) | candidate | 2-test JUnit (float and byte) fails 2 of 2 on main (on, off), the 10.6.0 revision, 10.5.2 and 9.12.3; its in-test control throws; the one-line fix passes it. |
| Refute review (OpenAI GPT-5.6, read-only) | not real (procedural, low) | Could not run commands; named no flaw in the repro or root cause; rated the intended-behaviour case moderate. A separate re-run fails 2 of 2. |
| Independent reproducer | real | Own 7-test class: 4 of 7 fail on main, 10.5.2, 9.12.3 and 9.10.0 (10 similarity queries with 1,000-term filters accepted; termCollector misses the filter); 3 controls pass; its own fix passes 7 of 7. |
| Works-as-designed review (OpenAI GPT-5.6, read-only) | real (low) | Agrees on the root cause; inputs in contract; separate internal rewrite validation does not preserve a cumulative budget. Separate re-runs fail on main and pass with the fix. |
| Intended-behaviour devil's advocate | real (medium) | Built the opaque-vector-leaf and block-join case and rejected it; probes: 50 filtered queries accepted, sizeOf 1,024 vs 1,169,024 bytes. |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's class on main (on, off): 4 of 7 fail each. Impact minor: hits are correct. |
| Credibility audit and minimization | keep | The audit re-ran the finder's test (fails); the minimization cut it to one test on 645d4fe14a20 (fails on, off; passes with the fix). |
| Fact checks of this doc (2026-10-31) | corrections applied | An independent fact check re-ran the repro's gradle command on a copy of 645d4fe14a20 (fails on and off; passes with the fix) and its own probe (601 / 1,201 / 600 on the rewritten tree; one nested case accepted, rejected with the fix). A fact check by a reviewer from another model family (OpenAI GPT-5.6, read-only) and a diagram check agreed on the bug. Their wording and scope corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 509 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,407 words
- Registry title
- Float/Byte/Float16VectorSimilarityQuery.visit() never visits the filter, so the filter's clauses escape IndexSearcher's cumulative maxClauseCount check and QueryVisitor term collection
- Area
- search / vector similarity queries (AbstractVectorSimilarityQuery QueryVisitor traversal; consumers: IndexSearcher's cumulative clause limit, QueryVisitor.termCollector, RamUsageEstimator.sizeOf(Query))
- Priority
- Low, rank 737: The filter of the niche vector similarity queries is also hidden from the clause limit and term collection while hits stay correct, the same QueryVisitor-hiding class as LFV-917 on a narrower API, so it moves next to that row for consistency.
- Impact class
- minor
- Impact note
- Applications that pass a filter to the @lucene.experimental Float/Byte/Float16VectorSimilarityQuery, with the default searcher and default maxClauseCount (1024), get no TooManyNestedClauses for the filter's share of the query: the cumulative check never counts the filter, which is checked only on its own with a fresh budget, so a query holding N filtered similarity queries can carry about N x maxClauseCount clauses (measured: 10 x 1,000-term filters accepted), and QueryVisitor.termCollector and RamUsageEstimator.sizeOf (the LRUQueryCache key estimate) also miss the filter; search hits are correct, no scale beyond the clause limit is needed, every release since 9.10.0.
- Summary
- You build BooleanQuery(MUST a 600-term disjunction, MUST FloatVectorSimilarityQuery.Adaptive(field, target, 0f, filter = another 600-term disjunction)), 1,200 term clauses in all, and search it with the default maxClauseCount of 1024. You expect TooManyNestedClauses, which you do get when the same 600 clauses are a sibling FILTER clause, because the check counts 'total clauses cumulatively in all of its children' and Query#visit is documented to visit 'any child queries'. Instead the search runs: AbstractVectorSimilarityQuery.visit only calls visitor.visitLeaf(this), so the filter, which stays in the rewritten query and is executed in createWeight, is checked only on its own; ByteVectorSimilarityQuery and Float16VectorSimilarityQuery behave the same, and QueryVisitor.termCollector returns none of the filter's terms.
- Introduced
- cd195980ecbcb45e19ce9465854fed0b6be79ea7 (apache/lucene#12679 'Add support for similarity-based vector searches', by GitHub kaivalnp, merged by benwtrent), released in 9.x through the branch_9x backport 8089b8c9d3374dc4d451a4280daae85e0b139b84 (plus 0212776677674db06439279849dafbafd7cc7dbc, a Java 11 adjustment of createWeight that leaves visit untouched); it created AbstractVectorSimilarityQuery with the leaf-only visit() copied from AbstractKnnVectorQuery and the createWeight line that rewrites and checks the filter on its own [read: git blame -w -M -C and git log -L on visit() show only cd195980ecb; no PR comment or review mentions visit, QueryVisitor or maxClauseCount; exec: fails on 9.10.0, the first release with the class, while 9.9.2 has no such class]; not a regression, so no bisect (2023-12-12 (author date, +0530; merged 2023-12-11T19:18:36Z; branch_9x backport committed 2023-12-11))
- First affected version
- 9.10.0 [exec] (the first release with the vector similarity queries; 9.9.2 has none and the repro does not compile there [exec]); on the main line 10.0.0 [exec]; Float16VectorSimilarityQuery (#16735) is main only and unreleased
- Affected versions
- Every release that has the API: the 19 up to 10.5.2 (9.10.0, 9.11.0, 9.11.1, 9.12.0 to 9.12.3 and 10.0.0 to 10.5.2) and 10.6.0 (the branch_10_6 head 4ae946e5a9b, the RC1 revision), plus main a9779ef3c193 [exec: the finder's 2-test JUnit fails 2 of 2, with its in-test control passing, on 9.10.0 (-ea and -da), 9.12.3 (-ea and -da), 10.0.0, 10.5.1, 10.5.2 (-ea and -da), branch_10_6 (-da) and main (-ea and -da); the independent reproduction's 7-test JUnit fails 4 of 7, with its 3 controls passing, on 9.10.0 (-da), 9.12.3 (-da), 10.5.2 (-ea and -da) and main (-ea and -da); the one-line visit fix shadowed on 9.10.0 passes 2 of 2; read: the visit() body and the createWeight filter line are identical in all 19 release tags and on main, and no release overrides rewrite()]; the IndexSearcher visitor-based cumulative check (LUCENE-8811) already existed when the class was added; upstream main c5ab3e57b9ba, branch_10x and branch_10_6 still have the leaf-only visit (last commit on the file 6f30895add8, #16104, author date 2026-05-28, does not touch visit) [read 2026-10-28]; not fixed anywhere. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only: a scripted prior-report search with 54 queries over GitHub issues, PRs and commits, downstream Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and 9 web searches (2,452 distinct hits, 0 high, 26 medium); 38 manual GitHub searches without rate-limit failures; the comment and review threads of #12679, #16654, #16735, #15784, #13285, #12922, #656, #12004, #951, #14860, #12579, #15869, #16586, #11946, #16725, #9855, #12538 and opensearch-project/k-NN#3299; 4 Solr JIRA queries; a changed-file scan of all 411 open apache/lucene PRs (5 touch AbstractVectorSimilarityQuery.java: #16847, #16204, #15802, #13594, #13595, and none changes visit) and of the 67 PRs updated since 2026-10-26), plus the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's own searches. Refresh 2026-10-28: GitHub search 'VectorSimilarityQuery visit' returns only the known similarity-query PRs (#15869, #16654, #16671, #15784, #15836, #12679); '"similarity query" filter clause' nothing new; 'QueryVisitor filter' and 'maxClauseCount' updated since 2026-10-25: 0; 'visit filter vector' only HNSW visited-node items; the PRs updated since a recent cutoff (#16858, #16700, #16931, #16857, #16926, #16145) and the newest items up to #16931 do not touch the fix-site files; the last upstream commit on AbstractVectorSimilarityQuery.java is still 6f30895add8 (#16104, author date 2026-05-28). Related, not this bug: #12679 (origin; its review never discusses visitors); LUCENE-8811 (#9855, the visitor-based cumulative check: 'removes ways to by-pass the maximum clause count'); #14756 and open PR #16175 (the opposite over-count of IndexOrDocValuesQuery; maintainers: 'for the purpose of visiting, we should visit all variants'); LUCENE-8849 (#9892, DocValuesRewriteMethod.visit fixed with the same getSubVisitor(FILTER, ...) shape; registry LFV-038 is the related DocValuesRewriteMethod case) and LUCENE-9050 (#10092), the same omission fixed as bugs in other classes; opensearch-project/k-NN#3299 (a downstream query-builder analogue that does not mention Lucene's queries). Gaps: GitHub search is keyword-based (the open-PR file scan finds fixes regardless of wording); the search API rate-limited once during the refresh and the queries were retried after the reset.
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree and the repro runner, 2026-10-31; the minimization, 2026-10-29) anda9779ef3c193(the hunt and its verifiers, 2026-10-28; identical code for every cited source file; onlylucene/CHANGES.txtgained unrelated entries, and its line numbers here are those of645d4fe14a20); the release jars 9.10.0, 9.12.3, 10.0.0, 10.5.1, 10.5.2 and 10.6.0; 9.9.2 has no such classes. OpenJDK 25.0.3 on Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/search/AbstractVectorSimilarityQuery.java:145-152 (createWeight: searcher.createWeight(searcher.rewrite(filter), ScoreMode.COMPLETE_NO_SCORES, 1)), :259-264 (visit: if (visitor.acceptField(field)) visitor.visitLeaf(this)), :40 (@lucene.experimental); FloatVectorSimilarityQuery.java:34, ByteVectorSimilarityQuery.java:33, Float16VectorSimilarityQuery.java:34 (@lucene.experimental); Query.java:88-93 ('Recurse through the query tree, visiting any child queries'); IndexSearcher.java:871-880 (rewrite runs getNumClausesCheckVisitor), :892-932, :1193-1199 (TooManyNestedClauses 'total clauses cumulatively in all of its children'); AbstractKnnVectorQuery.java:93 (the kNN filter is rewritten inside rewrite)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/AbstractVectorSimilarityQuery.java:57, 69, 84, 145-152 (createWeight), 259-264 (visit) @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:80-84, 623, 750-754, 865-932 (rewrite and the clause-check visitor), 1193-1199 (TooManyNestedClauses)lucene/core/src/java/org/apache/lucene/search/Query.java:88-93; QueryVisitor.java:53-99lucene/core/src/java/org/apache/lucene/search/ConstantScoreQuery.java:76-79; LRUQueryCache.java:465-471; lucene/CHANGES.txt:206 (GITHUB#15124, 11.0.0)branch_11x: a Lucene clone refs/remotes/origin/branch_11x (603af870375, 2026-10-29) and GitHub read-only on 2026-10-31 (live head d0c0decc6606, 2026-10-30): Float16VectorSimilarityQuery.java present, AbstractVectorSimilarityQuery.java:260-264 the same leaf-only visit, LRUQueryCache.java:470 sizeOf(query, 32); releases/lucene/10.6.0 LRUQueryCache.java:428-433 (QUERY_DEFAULT_RAM_BYTES_USED for non-accountable queries)
- Who is affected
lucene/core/src/java/org/apache/lucene/search/FloatVectorSimilarityQuery.java:34; ByteVectorSimilarityQuery.java:33; Float16VectorSimilarityQuery.java:34 (@lucene.experimental); IndexSearcher.java:80-84
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/Query.java:88-93; QueryVisitor.java:53-58; IndexSearcher.java:891-895, 1193-1199; AbstractKnnVectorQuery.java:74-97, 478-483lucene/CHANGES.txt:4681-4684, 5800, 6163-6164, 6469-6473; lucene/MIGRATE.md:1531-1534lucene/core/src/test/org/apache/lucene/search/TestMaxClauseLimit.java:128-148lucene/core/src/java/org/apache/lucene/search/DocValuesRewriteMethod.java:73-77 (LUCENE-8849 fix 5286098ac5c: getSubVisitor result unused); lucene/join/src/java/org/apache/lucene/search/join/ToParentBlockJoinQuery.java:90-92, 98-121 (inner rewrite only when the child score mode is None, LUCENE-8701 4b0c36b17b6)
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/ConstantScoreQuery.java:76-79; AbstractKnnVectorQuery.java:74-97
- History
lucene/CHANGES.txt:2973 (GITHUB#12679, 9.10.0)
- TestVectorSimilarityQueryFilterClauseCount.java (one test):
repro/LFV-916/src/org/apache/lucene/search/TestVectorSimilarityQueryFilterClauseCount.java(47 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and a probe of the clause-check count on stock main and with the fix. The diagram's sizes come from RamUsageEstimator.sizeOf(query, 32), the query cache's call (32 bytes for the similarity query, 105,632 for its filter alone), and its term count from termCollector over the whole repro query (600 of 1,200); the text uses sizeOf(query) (1,024 vs 701,824) and the filter alone (0 of 600). Both pairs were executed. An independent diagram check found no errors.
assets/LFV-916/bug.png(509 KB)