Russian text may write ё as е: ещё as еще, всё ("everything") as все.
RussianAnalyzerturns text into terms in this order: lowercase each word, drop it if it is in the stop list (very common words such as "and", "still", "all"), then cut its ending with the Snowball Russian stemmer.- The stop filter removes a word only if it is spelled exactly as listed. Since 9.0 the stemmer first replaces every ё with е, so ёлка and елка both become
елк.
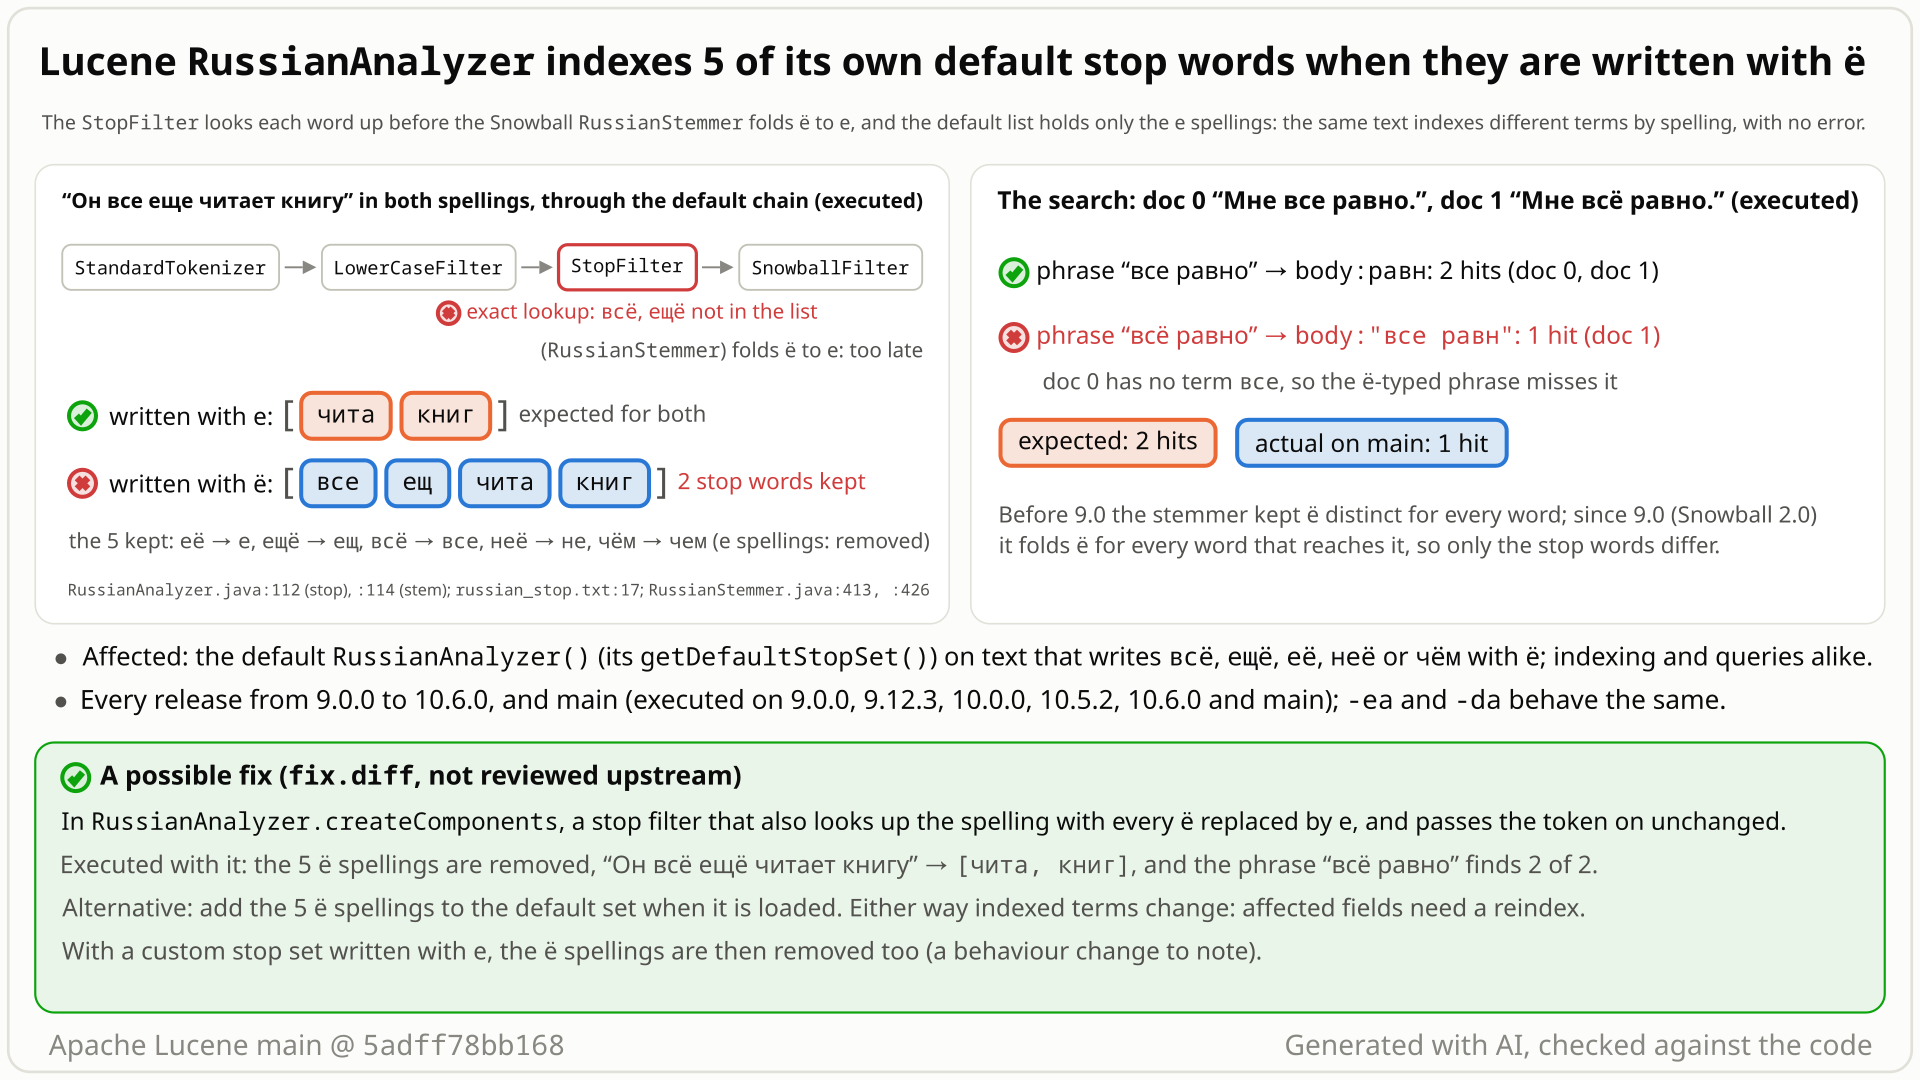
RussianAnalyzer: the stop filter removes все and еще but lets всё and ещё pass, because its lookup is exact, and the stemmer folds ё only afterwards, so the ё spelling indexes [все, ещ, чита, книг]. A two-document search shows the phrase "всё равно" finding 1 of 2 documents. Select the still to open it at full size. Generated with AI, checked against the code.- You index Russian text with the stock
new RussianAnalyzer(). Its default stop list says "letterё' is translated toе'" and holds все ("all") and еще ("still") only in their е spelling. - You expect "Он всё ещё читает книгу" ("He is still reading the book") to give [чита, книг], like "Он все еще читает книгу": since 9.0 the analyzer's stemmer folds ё to е, so every other word gets one term for both spellings.
- But the stop filter runs before the stemmer and looks the word up exactly. The list holds все, not всё, so всё passes; the stemmer then folds it and indexes
все. You get [все, ещ, чита, книг]. - Five default stop words behave this way: всё, ещё, её, неё and чём are indexed as все, ещ, е, не and чем. A phrase typed with ё, "всё равно", finds 0 hits on a document "Мне все равно."; the е-typed phrase finds it.
- No error, with assertions on or off.
Every user of the default RussianAnalyzer() whose documents or queries write всё, ещё, её, неё or чём with ё. Most Russian text prints ё as е, but dictionaries, teaching material and some authors write it, and ordinary text writes всё to tell it from все. Extra terms and phrase misses in one spelling direction; no exception or index damage.
Mechanism, terms and numbers501 words
RussianAnalyzer runs LowerCaseFilter, then StopFilter with the bundled Snowball list russian_stop.txt, then the Snowball RussianStemmer. The list's header says "letter ё' is translated to е'", so it holds only е spellings (все, еще, ее, нее, чем). Since 9.0 the stemmer replaces every ё with е before stemming, so every word that reaches it gets one term for both spellings. The StopFilter sits before that fold and does an exact lookup, so the five stop words whose standard spelling has ё (всё, ещё, её, неё, чём) are removed only when written with е; written with ё they are indexed as все, ещ, е, не and чем. The same sentence then indexes different terms depending on spelling, and a phrase typed with ё misses a document written with е. No error. It came with the Snowball 2.0 upgrade (LUCENE-9220, first released in 9.0.0) and is still on main; a small ё-aware stop lookup in RussianAnalyzer fixes it, and a fix changes indexed terms, so affected fields need reindexing.
RussianAnalyzer.createComponents(RussianAnalyzer.java:109-116):StandardTokenizer->LowerCaseFilter(:111) ->StopFilter(result, stopwords)(:112) -> optionalSetKeywordMarkerFilter(:113) ->SnowballFilter(..., new RussianStemmer())(:114). The javadoc lists the same order (:104-106);normalize()only lowercases (:118-121).- The default set is
russian_stop.txt, loaded withWordlistLoader.getSnowballWordSet(:45,:52-56). Header: "letterё' is translated toе'." (russian_stop.txt:17); the only ё in the file is in that line. Entries: все (:32), ее (:47), еще (:53), чем (:95), нее (:127). The file's own paradigm notes write её as ее (:187) and the neuter всё as все (:214-216). StopFilter("Removes stop words from a token stream",lucene/core/.../StopFilter.java:24) looks the token up exactly as it arrives, so всё is not found.RussianStemmer.stem()(RussianStemmer.java:399) starts with a loop that replaces every ё (eq_s("\u0451"),:413) with е (slice_from("\u0435"),:426). It runs after theStopFilter, so всё is indexed asвсе.
| е spelling (listed) | default analyzer | ё spelling | default analyzer | without stop words, both spellings |
|---|---|---|---|---|
| все | [] | всё | [все] | [все] |
| еще | [] | ещё | [ещ] | [ещ] |
| ее | [] | её | [е] | [е] |
| нее | [] | неё | [не] | [не] |
| чем | [] | чём | [чем] | [чем] |
Five ordinary words (ёлка, идёт, берёза, зелёный, ёж) get one term for both spellings. Of the 159 entries only these five have a real ё spelling: the exhaustive check found 72 ways to write an entry's е letters as ё that the stop-free chain maps to the entry's own term, all 72 kept by the default analyzer; the other 67 are mechanical variants, not spellings of the listed words (one, перёд, is a different word, the noun "front part"). In search (main a9779ef3c193, identical sources): the phrase "все равно" finds the document "Мне все равно.", the phrase "всё равно" becomes f:"все равн" and finds nothing.
Exposure and likelihood276 words
- Who is hit.
new RussianAnalyzer()orRussianAnalyzer(getDefaultStopSet()), no setting needed; assertions on and off behave the same. A custom or factory chain that puts an е-only Russian stop set before the Russian Snowball stemmer has the same gap (from the code, not run), and a fix inRussianAnalyzerdoes not cover it. - How often. ё is optional, and most Russian text prints it as е. Wikipedia ("Yo (Cyrillic)") says that by and large "it is used only in dictionaries and in pedagogical literature"; otherwise ё "occurs only when it is necessary to avoid ambiguity (such as to distinguish between все ('everybody') and всё ('everything') ...)", and marking it throughout "is the preference of some Russian authors and periodicals". Snowball calls it "rarely used". So ё text is the minority, but всё is exactly the case where even ordinary text writes the ё. Frequency was not measured. Their е forms are entries 14 (все), 29 (ее), 35 (еще), 77 (чем) and 109 (нее) of a list its header calls "ranked (commonest to rarest)".
- What goes wrong. The same sentence indexes different terms depending on spelling, and a phrase typed with ё ("всё равно") misses a document written with е ("все равно"), while the е-typed phrase finds it.
- What still works. Index and query share the chain, so a document and a query that both use ё still match, and the е spellings are removed as intended.
- Workaround today (from the code, not run): a custom analyzer that maps ё to е before the stop filter, for example with a
MappingCharFilter. - Reindexing. Any fix changes the indexed terms of these words, so affected fields need reindexing.
One JUnit test, one method, public API: the default RussianAnalyzer() on the same sentence in both spellings. The е sentence passes; the ё sentence fails on main, 10.6.0 and 9.12.3, with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ru;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestRussianAnalyzerYoStopWords extends BaseTokenStreamTestCase {

  /** The default stop list writes "всё" and "ещё" as "все" and "еще": "ё is translated to е". */
  public void testStopWordsWrittenWithYoAreRemoved() throws Exception {
    try (Analyzer a = new RussianAnalyzer()) {
      assertAnalyzesTo(a, "Он все еще читает книгу", new String[] {"чита", "книг"});
      assertAnalyzesTo(a, "Он всё ещё читает книгу", new String[] {"чита", "книг"});
    }
  }
}
cd $LUCENE
cp $REPRO/org/apache/lucene/analysis/ru/TestRussianAnalyzerYoStopWords.java lucene/analysis/common/src/test/org/apache/lucene/analysis/ru/
./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.ru.TestRussianAnalyzerYoStopWords -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
- Expected
- "Он всё ещё читает книгу" analyzes to [чита, книг], like "Он все еще читает книгу".
- Observed
- It analyzes to [все, ещ, чита, книг]:
term 0 expected:<[чита]> but was:<[все]>.
More files, environment, full output188 words
The test sits in org.apache.lucene.analysis.ru like the module's own tests but uses only public API. Deterministic, single thread, about 1 s. The first assertion is the control (the е spelling is removed); the second fails at line 28. The source holds Cyrillic literals, as TestRussianAnalyzer does. It compiles from 9.1.0 on (org.apache.lucene.tests); for 9.0.0 the test-framework package differs.
The failure message shows the first wrong term; the whole list is [все, ещ, чита, книг]. The same test is the suggested regression test; it passes with the recommended fix.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT), 10.6.0, 9.12.3: fail |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# gradle, main 5adff78bb168, seed DEADBEEF, -Ptests.asserts=true (the same with false)
TestRussianAnalyzerYoStopWords > testStopWordsWrittenWithYoAreRemoved FAILED
    org.junit.ComparisonFailure: term 0 expected:<[чита]> but was:<[все]>
        at org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
        ...
        at org.apache.lucene.analysis.ru.TestRussianAnalyzerYoStopWords.testStopWordsWrittenWithYoAreRemoved(TestRussianAnalyzerYoStopWords.java:28)

# the same failure through the JUnit runner: main (-ea, -da), 10.6.0 (-ea, -da), 9.12.3 (-ea, and -da in a separate re-check)
# the full token list, from an independent reproducer's test on a9779ef3c193: [все, ещ, чита, книг]
# with the recommended fix: passes (gradle, assertions on and off; JUnit runner -ea and -da)- The stop list says "letter
ё' is translated toе'" (russian_stop.txt:17), but the analyzer feeds it unfolded words. - Since 9.0 the same analyzer without stop words gives one term for both spellings of every word the stemmer sees.
- Arabic and Persian place the stop filter by how their lists are normalized; Lucene added missing Romanian spellings (#12172).
The full argument181 words
- The list is written in ё-folded form. "letter
ё' is translated toе'" (russian_stop.txt:17); its paradigm notes write её as ее and the neuter всё as все. Snowball's Russian page says of its algorithm: "The original algorithm here assumed it had already been mapped to е". - The chain declares the spellings equal.
RussianAnalyzer(CharArraySet.EMPTY_SET)maps both spellings to one term for 5 of 5 stop words and 5 of 5 ordinary words, becauseRussianStemmer.stem()folds ё first. - Arabic and Persian. ArabicAnalyzer: "the order here is important: the stopword list is not normalized!" (
ArabicAnalyzer.java:135); PersianAnalyzer: "the stopword list is normalized with the above!" (PersianAnalyzer.java:136-137). - Precedent. #12172 (2024) added the comma-below spellings to the Romanian stop list (
ro/stopwords.txt:4); #13233 addedRomanianNormalizationFilterafter itsStopFilterand innormalize()"to complete the job" and asked users to reindex. In 2009, LUCENE-1576 (a bug, Brazilian) and LUCENE-1963 (an enhancement, Arabic) moved lowercasing before theStopFilter. - Nothing says otherwise.
TestRussianAnalyzerhas no ё; no javadoc, CHANGES or MIGRATE entry, and no comment on LUCENE-9220's PR or issue, discusses ё.
The devil's-advocate check267 words
The strongest case for "intended" (built by the intended-behaviour verifier and by a reviewer from another model family, OpenAI GPT-5.6; both rated it moderate): the javadoc documents StopFilter before the stemmer, and StopFilter promises only exact matches; the header can be read as provenance, and Lucene regenerates the file verbatim from Snowball (gradle/regenerate/snowball/snowball.sh:55-70); in Snowball's design ё folding is the caller's job; and in the 2012 java-user thread "Two questions on RussianAnalyzer" a maintainer (rmuir) declined to add a ё/е option to RussianAnalyzer ("I dont think so, there are tons of choices here ... So we generally just provide XYZ_Analyzer as an example mostly ... Instead just make your own!") and suggested a TokenFilter in the user's own analyzer.
Why it fails: that reply is from Lucene 3.6, when the stemmer kept ё apart for every word. Since 9.0 the default chain folds ё for every word the stemmer sees, a side effect of the Snowball 2.0 upgrade (no comment on its PR or issue compares the fold with the stop list), so the gap left is the stop words. Points to state carefully: normalize() (multi-term queries) and stem-exclusion keywords still keep ё distinct, so the equivalence holds for words that reach the stemmer; все/всё and чем/чём are different words when ё is written, so the claim is about the spelling that omits ё, which the list's single entry is meant to cover; and since the header can be read as provenance, the change may fairly be seen as an improvement to the default analyzer (the evidence is the same). Verdict: a defect, Low priority.
Recommended A ё-aware stop lookup in RussianAnalyzer (recommended)
Recommended: in RussianAnalyzer, replace the StopFilter with a small package-private filter that also looks up the word with ё folded to е and passes the word on unchanged. Validated on 5adff78bb168: the repro and 18 of 18 Russian and Snowball tests pass. It changes indexed terms, so it needs a reindex note.
// RussianAnalyzer.createComponents: new StopFilter(...) becomes new YoAwareStopFilter(...)
@Override
protected boolean accept() {
  final char[] b = termAtt.buffer();
  final int len = termAtt.length();
  if (stopWords.contains(b, 0, len)) return false;
  int i = 0;
  while (i < len && b[i] != '\u0451') i++;      // no ё: nothing more to check
  if (i == len) return true;
  folded = ArrayUtil.grow(folded, len);
  for (int j = 0; j < len; j++) folded[j] = b[j] == '\u0451' ? '\u0435' : b[j];
  return stopWords.contains(folded, 0, len) == false;  // the token is not changed
}
All options and trade-offs3 options · 509 words
Every option changes default analysis output for the five words, so the CHANGES entry (and MIGRATE, as #13233 did for Romanian) should say that affected fields need reindexing.
Replace new StopFilter(result, stopwords) (RussianAnalyzer.java:112) with a nested package-private FilteringTokenFilter that removes a token when the token, or its spelling with every ё replaced by е, is in the stop set. The token itself passes on unchanged. One file, +41/-1.
// RussianAnalyzer.createComponents: new StopFilter(...) becomes new YoAwareStopFilter(...)
@Override
protected boolean accept() {
  final char[] b = termAtt.buffer();
  final int len = termAtt.length();
  if (stopWords.contains(b, 0, len)) return false;
  int i = 0;
  while (i < len && b[i] != '\u0451') i++;      // no ё: nothing more to check
  if (i == len) return true;
  folded = ArrayUtil.grow(folded, len);
  for (int j = 0; j < len; j++) folded[j] = b[j] == '\u0451' ? '\u0435' : b[j];
  return stopWords.contains(folded, 0, len) == false;  // the token is not changed
}
Trade-offs
Custom stop sets that list a ё spelling keep working (a sketch that folded the token itself broke a custom set {всё}; the cross-model reviews found that). A custom е-only set passed to RussianAnalyzer(CharArraySet) now also removes the ё spellings: a behaviour change, arguably the right one, to call out. The extra lookup is one-way: a custom set {все} now also removes всё, but a custom set {всё} still does not remove все (only ё is folded, never е). normalize() and stem exclusion are unchanged. TestAllAnalyzersHaveFactories skips member classes, so the nested filter needs no factory.
What the checks validated
Scratch worktree at 5adff78bb168: the one-method repro fails without the fix and passes with it; :lucene:analysis:common:test for org.apache.lucene.analysis.ru.* and org.apache.lucene.analysis.snowball.* passes 18 of 18 with -Ptests.asserts=true and false; checkGoogleJavaFormat, ECJ lint (ecjLintMain, ecjLintTest) and forbidden-apis pass; the separate EditorConfig lint did not run (its tool is not installed here). Earlier on a9779ef3c193: the finder's 6-test JUnit, a reviewer's custom-set test and an edge-case test (upper-case Ё, positions) pass.
After loading the list in DefaultSetHolder (RussianAnalyzer.java:47-63), add всё, ещё, её, неё, чём (the #12172 shape). Editing russian_stop.txt itself would not last: it is regenerated verbatim from Snowball (gradle/regenerate/snowball/snowball.sh:55-70); the alternative is a change upstream in Snowball.
Trade-offs
Smallest change; does not help custom е-only sets.
What the checks validated
Not run.
Add a ё-to-е filter after the StopFilter and in normalize(), as #13233 placed RomanianNormalizationFilter (RomanianAnalyzer.java:121-122, :130-131) next to a stop list holding both spellings.
Trade-offs
Also makes wildcard and prefix queries and stem exclusion spelling-blind; the largest behaviour change, and stem-exclusion sets that list ё spellings would need folding too.
What the checks validated
Not run (only a variant that folds the token itself before the StopFilter was tried: it passed the repro but broke a custom stop set {всё}).
Applications and search servers that build on RussianAnalyzer or getDefaultStopSet(), or that chain the same filters in the same order, index the same extra terms; mapping ё to е before the stop filter avoids it.
A bounded-exhaustive differential check on the stock jars: each default stop word, written with ё in every possible position, went through the default analyzer and through the same analyzer without stop words. The default kept all 72 variants that the stop-free chain treats as the stop word itself (5 real spellings); a Persian control kept 0 of 284.
The method in full132 words
Method: bounded-exhaustive differential checking (semi-formal tier). For every default stop entry of the Russian, German, Serbian and Romanian analyzers and a Persian control, every spelling variant generated from the substitutions a filter after the StopFilter performs (for Russian: every subset of е positions written as ё) was analyzed and compared with the same analyzer built with CharArraySet.EMPTY_SET as the equivalence oracle.
- Russian: 72 of 72 chain-equivalent variants kept (5 real spellings: её, ещё, всё, неё, чём; 67 mechanical variants that are not spellings of the listed words; the 5 are marked from a fixed list, not a dictionary). With ё folded before the
StopFilter: 0 of 72 (vacuity check). Persian control: 0 of 284. - Reduced to a public-API JUnit, then to the one-method test above.
- Found 2026-10-28 on main
a9779ef3c193.
New: our searches found nothing that describes this defect (re-checked 2026-11-03, and again 2026-11-04, the last time with the search cache bypassed). Related items concern other defects: a 2012 java-user request for general ё/е matching, made before the 9.0 stemmer fold and not about stop words, and the Romanian stop-list and normalizer fixes #12172 and #13233.
Searches4 searches
Our searches found no report of this defect (re-checked 2026-11-03 in two independent passes, and again on 2026-11-04 with the search cache bypassed). Related prior items, none of them this defect:
- java-user, 2012-04-19, "Two questions on RussianAnalyzer": a user asked for RussianAnalyzer to treat ё and е as one letter in general, and a maintainer (rmuir) declined ("I dont think so, there are tons of choices here ... Instead just make your own!"). It is about general ё/е matching in Lucene 3.6, when the stemmer kept ё apart for every word, so this stop-word inconsistency did not exist yet; it never mentions stop words and was never filed.
- #12172 and #13233 (Romanian, merged 2024-03-28): missing comma-below spellings in the Romanian stop list, then a Romanian normalization filter after the
StopFilterand innormalize(). Another language and file; precedent for the fix. - LUCENE-1576 (#2650), LUCENE-1963 (#3038) (2009): lowercasing moved before the
StopFilterin other analyzers (Brazilian, a bug; Arabic, an enhancement). - snowball #65, #68 and LUCENE-9220 (#10260): the origin of the stemmer's ё fold and how it reached Lucene; they cover the stemmer only.
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues, PRs and commits (incl. the migrated JIRA archive); downstream repositories; dev@, java-user@, issues@ and other Lucene, Solr and Lucene.NET lists; JIRA; the web | 2026-10-28 | a prior-report search tool, 2 runs (51 and 56 queries, 328 distinct hits); 42 manual GitHub searches incl. Cyrillic control queries; changed files of all 413 open PRs and 36 recently closed; commits by path on 4 branches; 17 list threads read; 12 web searches in English and Russian | only the related items above |
| the same sources, two independent passes | 2026-11-03 | re-check of every item found earlier | related items about different defects; nothing describes this defect |
| GitHub, lists, JIRA; commits by path; open PRs; the web | 2026-11-04 | the tool again (45 queries, 44 of them answered from its 7-day cache; 311 hits; the closest are 3 RussianAnalyzer threads of 2002-2004 that match only the class name); a refreshed GitHub pass (21 queries, nothing relevant); 6 searches for items updated since 2026-10-27; commits by path up to upstream main f72004515ec2; one web search | no report; no new commit or open PR on the Russian analyzer, its stop list or its stemmer |
| GitHub apache/lucene issues, PRs and commits (incl. the migrated JIRA archive); downstream repositories; dev@, java-user@, issues@, commits@; JIRA | 2026-11-04 (later) | the same 45 queries with the cache bypassed (0 cached); separately, a later re-check's GitHub searches with a Cyrillic control query and list searches since 2026-10-20 | 311 hits, the same 3 threads of 2002-2004; no report of this defect |
Since 9.0.0: 0203815ab2b (LUCENE-9220, 2020) brought in the Snowball 2.0 stemmer, which folds ё first, behind a stop filter that does not; the filter order and the list date from 3.1. Not fixed: main and 10.6.0 fail.
Versions tested6 rows
Introduced by 0203815ab2bf "LUCENE-9220: regenerate all stemmers/stopwords/test data from snowball 2.0 (#1262)" (apache/lucene-solr PR #1262 by rmuir, 2020-02-17; issue now #10260). It regenerated RussianStemmer from Snowball 2.0 (NEWS: "We now normalise 'ё' to 'е' before stemming"); it did not touch RussianAnalyzer, and the 159 stop entries stayed the same. git log -S'u0451' on RussianStemmer.java returns only this commit.
Before 9.0 (3.1.0 to 8.11.4) the chain order and the list were the same (LUCENE-2055, 3.1.0) and ё stop words were kept too, but the stemmer kept ё apart for every word, so nothing was inconsistent; only the list's stated precondition was unmet. Later Snowball upgrades (#13209, #13227 in 2024; #15505 in 2025) kept the fold. Upstream main f72004515ec2 (2026-11-03) has no later change to the chain or the lookup.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | the one-method JUnit fails through gradle (assertions on and off) and the JUnit runner (-ea, -da); passes with the fix |
| 10.6.0 | latest release | the one-method JUnit fails (-ea, -da) |
| 10.0.0 to 10.5.2 | affected | a version-independent probe fails on 10.0.0 and 10.5.2, the finder's JUnit on 10.5.2; the rest by reading (same chain, fold and entries) |
| 9.0.0 to 9.12.3 | first release 9.0.0 | the probe and the finder's JUnit (older test-framework package) fail on 9.0.0 (-ea, -da); the one-method JUnit fails on 9.12.3 |
| 3.1.0 to 8.11.4 | no inconsistency | ё stop words kept too, but the stemmer keeps ё apart for every word (probe on 3.1.0, 8.4.1, 8.11.4) |
| 3.0.3 | before the Snowball list | hard-coded stop list, no ё folding anywhere (probe) |
An independent reproducer, three executed review runs by a model from another family (OpenAI GPT-5.6; refute, intended and root-cause lenses), an intended-behaviour devil's advocate, an adjudication and an audit each re-ran it with their own tests or seeds; all say real and every control passes. This doc re-ran it on 5adff78bb168.
Checks and verdicts294 words
The reviews and verifiers ran on main a9779ef3c193 (the cross-model reviews on ea57360912ed, whose analysis sources are identical); this doc's runs are on 5adff78bb168.
| Check | Verdict | What it found |
|---|---|---|
| finder | found | The exhaustive check, then a 6-test public-API JUnit: 4 of 6 fail on main (-ea, -da), 10.5.2 and 9.12.3; both controls pass; 6 of 6 with the fix. |
| cross-model review, refute and intended lenses (OpenAI GPT-5.6, executed) | real (high), both | Own tests fail on main (also -da), 10.5.2 and 9.12.3; the intended case rated moderate; both found that a token-folding fix sketch broke a custom stop set {всё}. |
| independent reproducer | real | Own 5-test JUnit: 3 of 5 fail on main (-ea, -da), 10.5.2 and 9.12.3, controls pass ('Он всё ещё читает книгу' -> [все, ещ, чита, книг]); its probe shows the 9.0.0 / 8.11.3 boundary. |
| root-cause review (OpenAI GPT-5.6, executed) | real (high) | One cause: an instrumented trace shows the stop filter sees the unfolded token; its tests fail on main and pass with the fix. |
| intended-behaviour devil's advocate | real (medium) | Built the 'by design' case (documented order, exact-match StopFilter, the 2012 reply) and rejected it; found the 2012 thread. |
| adjudication | confirmed (medium), Low | Re-ran the independent reproducer's JUnit with -ea and -da and the finder's with -ea; medium because the contract is implied and upstream could answer 'build your own analyzer'. |
| audit | real | Re-ran the finder's JUnit on a clean checkout with -da and a new seed: 4 of 6 fail, controls pass. |
| this doc | reproduced | The one-method test fails on main 5adff78bb168 (gradle and the runner, assertions on and off), 10.6.0 and 9.12.3; passes with fix A, which also passes the Russian and Snowball test classes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 468 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,691 words
- Registry title
- RussianAnalyzer does not remove its default stop words when they are written with ё (её, ещё, всё, неё, чём): its StopFilter runs before the stemmer folds ё to е, although the bundled stop list says ё is translated to е
- Area
- analysis-common / Russian analyzer default stop words (RussianAnalyzer, snowball/russian_stop.txt; interaction with the Snowball RussianStemmer's ё-to-е fold)
- Priority
- Low, rank 441: The stock RussianAnalyzer keeps the ё spellings of five default stop words, a minor analysis-quality bug in the same class as the Telugu and Bengali stop-list rows, and it leads that group because Russian is far more widely used.
- Impact class
- minor
- Impact note
- Analysis quality only, with no error: every application that analyzes Russian text with the default RussianAnalyzer() (or its getDefaultStopSet()), on every release from 9.0.0 through 10.6.0 and on main, indexes and queries the five common function words её, ещё, всё, неё and чём of its own default stop list as ordinary terms (е, ещ, все, не, чем) whenever the text writes them with ё, while their е spellings are removed, so the same sentence indexes different terms depending on spelling and a phrase typed with ё ('всё равно') misses a document that writes it with е ('все равно') while the е-typed phrase finds it; no corruption, crash or scale, -ea and -da behave the same, and because a fix changes indexed terms, affected fields need reindexing after it.
- Summary
- You analyze Russian text with the stock RussianAnalyzer. Its default stop list, the bundled Snowball russian_stop.txt, says in its header that 'letter ё is translated to е', so it lists её, ещё, всё, неё and чём only as ее, еще, все, нее and чем, and since 9.0 the same analyzer without stop words maps the ё and е spellings of every word that reaches its stemmer to one term. But the StopFilter runs before the only step that folds ё to е (the Snowball RussianStemmer), so the е spellings are removed while the ё spellings pass the StopFilter and are indexed as е, ещ, все, не and чем: 'Он все еще читает книгу' gives [чита, книг] but 'Он всё ещё читает книгу' gives [все, ещ, чита, книг], with no error.
- Introduced
- 0203815ab2bf72a77fe8f58daa0e6e269e00e9a8 ('LUCENE-9220: regenerate all stemmers/stopwords/test data from snowball 2.0 (#1262)', apache/lucene-solr PR #1262 by rmuir; issue LUCENE-9220, now apache/lucene#10260) [read: git log -S'u0451' on RussianStemmer.java in the history clone returns only this commit; its parent has no ё handling; executed boundary: 8.11.4 keeps ё distinct for every word, 9.0.0 folds it]. It regenerated org.tartarus.snowball.ext.RussianStemmer from Snowball 2.0, whose stem() first replaces every U+0451 with U+0435; it did not touch RussianAnalyzer, and the 159 entries of russian_stop.txt are identical before and after. So the defect is an interaction: the chain order StopFilter before SnowballFilter and the analyzer's use of the Snowball list (added by LUCENE-2206), whose header states the ё-to-е precondition, both date from LUCENE-2055 (a6b7c5552ba, rmuir, 2010-02-05, first released in 3.1.0); from 3.1.0 to 8.11.4 that precondition was already unmet, but the stemmer kept ё distinct for every word too, so stop words were treated like all other words. Nothing in the PR or issue discusses Russian or ё. (2020-02-17 (authored and committed; PR merged 2020-02-17T17:38:02Z; master only, first released in 9.0.0))
- First affected version
- 9.0.0 [exec] (the first release containing 0203815ab2b: the finder's JUnit, legacy-import variant, fails 4 of 6 with both controls passing, and the version-independent probe keeps 5 of 5 ё spellings while the stop-free chain maps both spellings to one term for 5 of 5 stop words and 5 of 5 ordinary words, with -ea and -da). Releases 3.1.0 to 8.11.4 also keep the ё spellings [exec 3.0.3, 3.1.0, 8.4.1, 8.11.4], but there the stemmer keeps ё distinct for every word, so the analyzer-internal inconsistency does not exist; only the stop file's stated precondition is unmet. No 8.x release contains the commit.
- Affected versions
- Every 9.x and 10.x release, 9.0.0 through 10.5.2 (33 releases, git tag --contains 0203815ab2b), plus 10.6.0 (branch_10_6 4ae946e5a9b, the RC1 revision) and main a9779ef3c193; not fixed. [exec] the finder's JUnit or the follow-up probe fails on 9.0.0 (-ea and -da), 9.12.3, 10.0.0, 10.5.2, branch_10_6 4ae946e5a9b and main (-ea and -da); the independent reproduction's own JUnit fails on main (-ea and -da), 10.5.2 and 9.12.3, its main() form on 9.0.0 and main. [read] the other releases have the same chain order, the same ё fold and the same 159 entries; the later Snowball upgrades (#13209, #13227, 2024; #15505, 2025-12-18) kept the fold. Upstream main c5ab3e57b9ba (2026-10-28): last commit on analysis/ru 2026-01-15 (#15573, javadoc markup), on russian_stop.txt 2025-07-14 (#14933, build scripts), on RussianStemmer.java 2025-12-18 (#15505); none touches the chain or the stop lookup.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- related items only, no report of this defect, not fixed (searched 2026-10-28 plus a refresh the same day, read-only; re-checked 2026-11-03 in two independent passes): two scripted prior-report searches (51 and 56 queries over apache/lucene issues and PRs, commits, downstream repositories, the dev, java-user and issues lists, JIRA and the web; 328 distinct hits), 42 manual GitHub searches (apache/lucene, Elasticsearch, OpenSearch, Solr, Lucene.NET, Snowball and its website; Cyrillic control queries work), the changed files of all 413 open apache/lucene PRs plus 36 recently closed ones, commits by path (author dates) on main, branch_10x, branch_10_6 and branch_11x, JIRA (LUCENE, SOLR) and the Lucene, Solr and Lucene.NET lists (17 threads read). The closest related item: the java-user thread 'Two questions on RussianAnalyzer' (2012-04-19, Lucene 3.6) asked for RussianAnalyzer to treat ё and е as the same letter in general, and a maintainer (rmuir) declined ('this analyzer is just an example ... make your own'); it predates the 9.0 stemmer fold, never mentions stop words and was never filed as an issue, but the change it asked for (fold ё before the chain) is the same fix site. Related precedent, not this bug: #12172 and #13233 (Romanian stop-list spelling variants and RomanianNormalizationFilter, merged 2024-03-28), LUCENE-1576 (#2650) and LUCENE-1963 (#3038) (normalization placed after StopFilter, fixed as bugs in 2009), snowball #65 and #68 (origin of the stemmer's ё fold) and LUCENE-9220 (#10260, which brought it in; no ё discussion). Refresh (2026-10-28): GitHub search for 'ё', 'RussianAnalyzer' and 'russian stop' updated since 2026-10-26 in apache/lucene: 0 each; the 53 PRs updated since 2026-10-26 touch no Russian or Snowball file (only #16261, CharArraySet equals/hashCode, unrelated); the latest commits by path are unchanged.
- Lucene commit tested
- main
5adff78bb168(2026-11-04): the one-method JUnit through gradle in a scratch worktree, stock and with the recommended fix, with assertions on and off, plus the Russian and Snowball test classes with the fix; through the JUnit runner on main (-ea,-da, and with the fix), the released 10.6.0 (-ea,-da) and 9.12.3 jars; a version-independent probe on main. Earlier checks ran on maina9779ef3c193, whose Russian analyzer, stop list, stemmer andStopFilterare identical, and on 10.5.2, 10.0.0, 9.0.0, 8.11.4, 8.4.1, 3.1.0 and 3.0.3 for the version boundary. A separate re-check re-ran the test on 9.12.3 with assertions off.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/ru/RussianAnalyzer.java:37-38 (at a9779ef3c193) (class javadoc: stop words 'will not be indexed at all'), :45-63 (DEFAULT_STOPWORD_FILE russian_stop.txt loaded with WordlistLoader.getSnowballWordSet), :100-106 (createComponents javadoc: LowerCaseFilter, StopFilter, SetKeywordMarkerFilter, SnowballFilter), :109-116 (chain: StandardTokenizer, LowerCaseFilter :111, StopFilter :112, [SetKeywordMarkerFilter], SnowballFilter(RussianStemmer) :114), :119-121 (normalize: LowerCaseFilter only)lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/russian_stop.txt:13-17 (at a9779ef3c193) (header: ranked list; "letter `ё' is translated to `е'"; the file's only ё is in that header), :32 (все), :47 (ее), :53 (еще), :95 (чем), :127 (нее); 159 entrieslucene/analysis/common/src/java/org/tartarus/snowball/ext/RussianStemmer.java:399 (at a9779ef3c193) (stem()), :413 (eq_s("\u0451"): every ё is replaced by е before stemming)lucene/core/src/java/org/apache/lucene/analysis/StopFilter.java:24 (at a9779ef3c193) ('Removes stop words from a token stream.'); lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicAnalyzer.java:135 ('the order here is important: the stopword list is not normalized!'); lucene/analysis/common/src/java/org/apache/lucene/analysis/fa/PersianAnalyzer.java:136-137 ('the stopword list is normalized with the above!'); lucene/analysis/common/src/resources/org/apache/lucene/analysis/ro/stopwords.txt:4 (comma forms added by #12172)GitHub and lists, read-only (2026-10-28): apache/lucene #10260 (LUCENE-9220), apache/lucene-solr PR #1262, #12172, #13233, #2650 (LUCENE-1576), #3038 (LUCENE-1963), #3131 (LUCENE-2055), #3282 (LUCENE-2206), #16261, #16356, #16381; snowballstem/snowball #65 and #68; java-user thread 'Two questions on RussianAnalyzer' (2012-04-19, lists.apache.org/thread/k571m2m7jyhn36g1sgopco4cddwfzy9t)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/ru/RussianAnalyzer.java:104-121 (at 5adff78bb168) (javadoc order; chain :109-116, StopFilter :112, SnowballFilter :114; normalize :118-121), :45, :52-56 (default set)lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/russian_stop.txt:14-17 (at 5adff78bb168) (ranked list; ё is translated to е), :32, :47, :53, :95, :127 (entries), :187, :214-216 (paradigm notes)lucene/analysis/common/src/java/org/tartarus/snowball/ext/RussianStemmer.java:399-426 (at 5adff78bb168) (stem(): every ё replaced by е first)lucene/core/src/java/org/apache/lucene/analysis/StopFilter.java:24 (at 5adff78bb168)
- Who is affected
https://en.wikipedia.org/wiki/Yo_(Cyrillic) (usage of ё; read 2026-11-04); https://snowballstem.org/algorithms/russian/stemmer.html ("rarely used and often replaced by е in informal writing")lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/russian_stop.txt:14-15 (at 5adff78bb168) (ranked list), entry order computed from the file (все 14, ее 29, еще 35, чем 77, нее 109)
- Minimal repro
lucene/analysis/common/src/test/org/apache/lucene/analysis/ru/TestRussianAnalyzer.java:38-41 (at 5adff78bb168) (Cyrillic literals upstream)
- Why it looks unintended
lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/russian_stop.txt:17, (at 5adff78bb168) :187, :214-216https://snowballstem.org/algorithms/russian/stemmer.html ("The original algorithm here assumed it had already been mapped to е")lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicAnalyzer.java:135; (at 5adff78bb168) lucene/analysis/common/src/java/org/apache/lucene/analysis/fa/PersianAnalyzer.java:136-137lucene/analysis/common/src/resources/org/apache/lucene/analysis/ro/stopwords.txt:4; (at 5adff78bb168) lucene/analysis/common/src/java/org/apache/lucene/analysis/ro/RomanianAnalyzer.java:120-131https://github.com/apache/lucene/pull/12172; https://github.com/apache/lucene/pull/13233 (body: "to complete the job we need a normalizer", "users should reindex Romanian documents")https://github.com/apache/lucene/issues/2650 (LUCENE-1576, label type:bug); https://github.com/apache/lucene/issues/3038 (LUCENE-1963, label type:enhancement)Lucene main 5adff78bb168 gradle/regenerate/snowball/snowball.sh:55-70 (stop files regenerated verbatim)https://lists.apache.org/thread/k571m2m7jyhn36g1sgopco4cddwfzy9t (java-user, 2012-04-19); rmuir's reply to the ё/е question: https://lists.apache.org/api/email.lua?id=60ycrg1pml704phsqx30g73c6001vfz3
- Suggested fix
lucene/analysis.tests/src/test/org/apache/lucene/analysis/tests/TestAllAnalyzersHaveFactories.java:91-95 (at 5adff78bb168) (member and non-public classes skipped)Lucene main 5adff78bb168 gradle/regenerate/snowball/snowball.sh:55-70; lucene/analysis/common/src/java/org/apache/lucene/analysis/ro/RomanianAnalyzer.java:120-131https://github.com/apache/lucene/pull/12172; https://github.com/apache/lucene/pull/13233
- Prior reports
https://lists.apache.org/thread/k571m2m7jyhn36g1sgopco4cddwfzy9t; https://github.com/apache/lucene/pull/12172; https://github.com/apache/lucene/pull/13233; https://github.com/apache/lucene/issues/2650; https://github.com/apache/lucene/issues/3038; https://github.com/snowballstem/snowball/issues/65; https://github.com/snowballstem/snowball/pull/68; https://github.com/apache/lucene/issues/10260
- Diagrams
lucene/analysis/common/src/java/org/apache/lucene/analysis/ru/RussianAnalyzer.java:109-116; (at 5adff78bb168) lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/russian_stop.txt:17, (at 5adff78bb168) :32; lucene/analysis/common/src/java/org/tartarus/snowball/ext/RussianStemmer.java:399-426 (at 5adff78bb168)
- TestRussianAnalyzerYoStopWords.java (one test method):
repro/LFV-918/TestRussianAnalyzerYoStopWords.java(31 lines)
A summary still (the PNG) of the sentence through the analyzer's chain, the stop list and the stemmer code, and the two-document search, made from the code at 5adff78bb168 and an executed probe.
assets/LFV-918/bug.png(468 KB)