IndexSearcher.explain prints how a score was computed as a tree of numbers, each child an input of its parent. With IB and no normalization, two children are wrong.
IndexSearcher.explain(query, doc)returns anExplanation: a tree whose nodes each carry a value and say how it was computed from the nodes below them.IBSimilarity(information-based models) scores a term in a document asdistribution.score(tfn, lambda):tfnis the term frequency after length normalization,lambdaa corpus statistic.- The normalization is pluggable:
NormalizationH1,H2,H3,Z, orNoNormalization, which leaves tf as it is (tfn = tf). Each one also explains its own value, the tfn, in the tree.
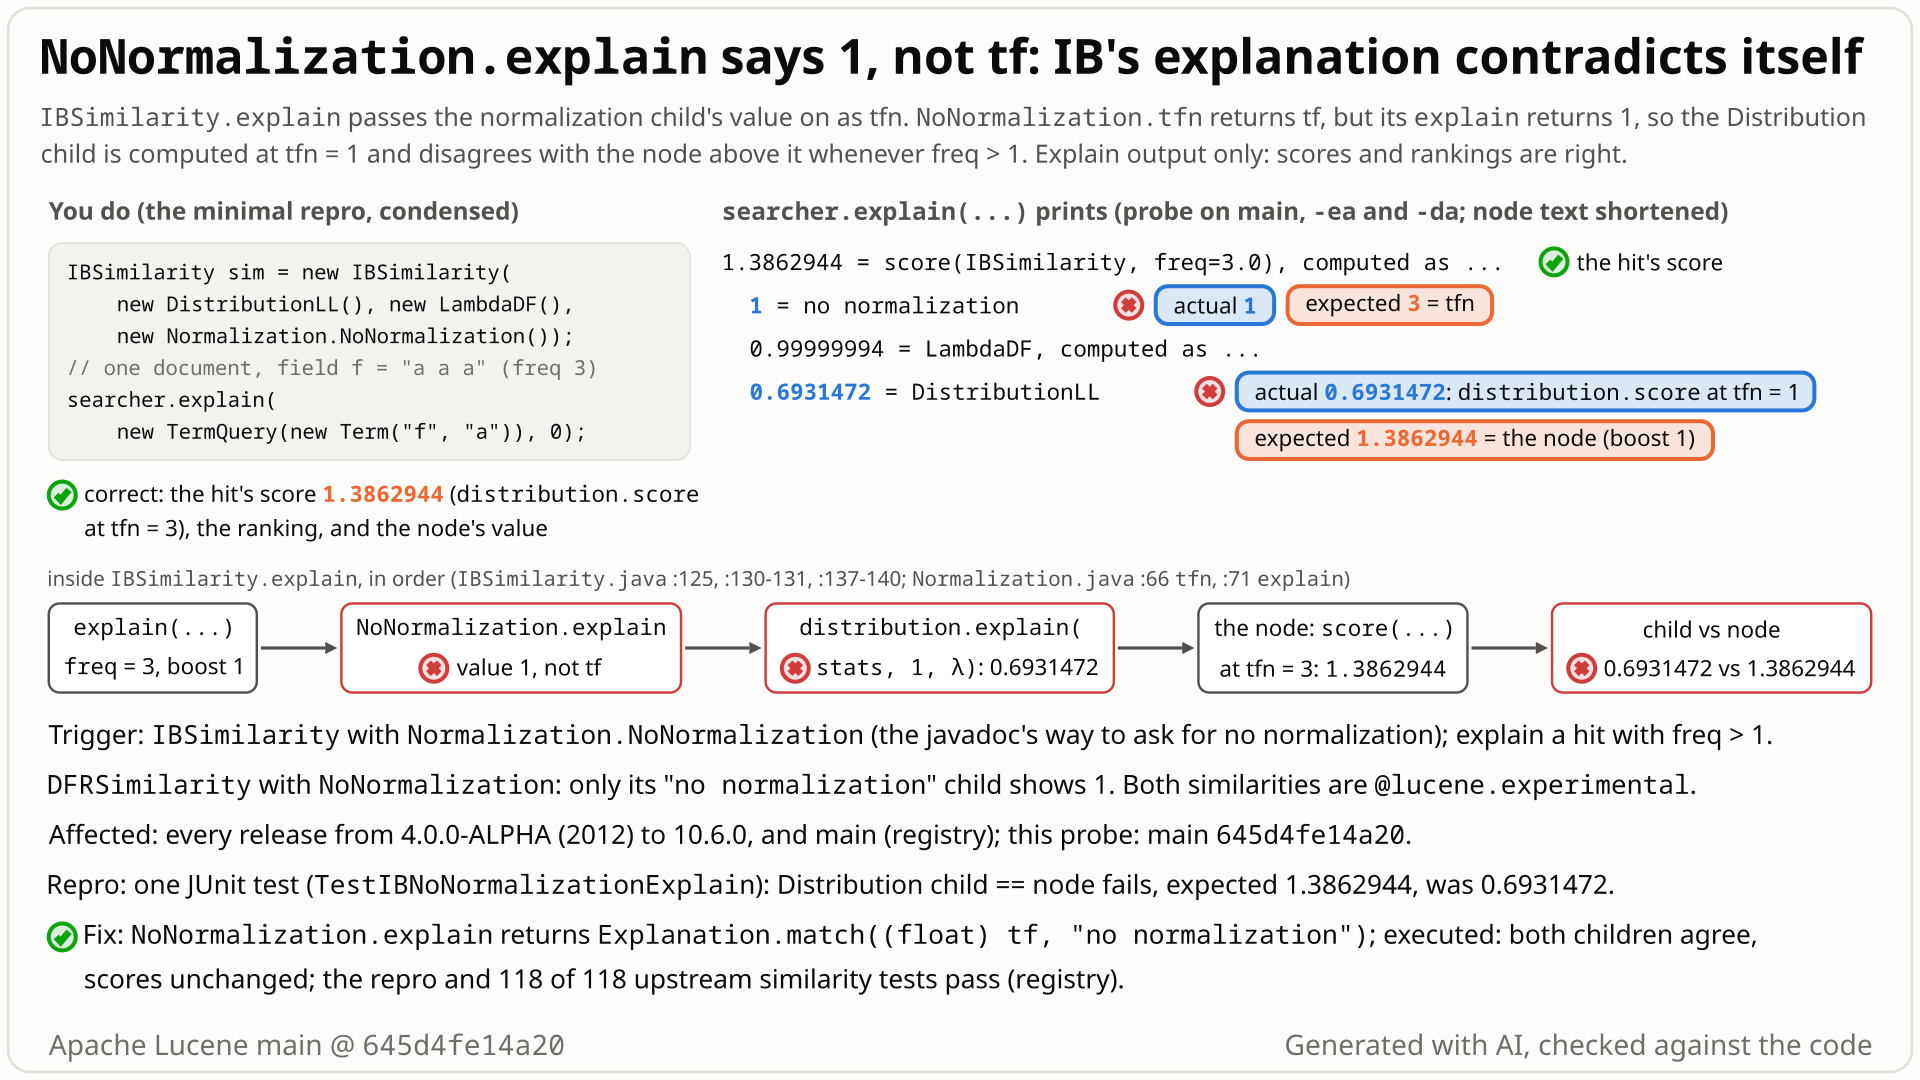
- Index one document whose field
fis "a a a" (the term occurs 3 times) and score it withIBSimilarity(DistributionLL, LambdaDF, NoNormalization), the documented way to ask IB for no normalization. - Call
IndexSearcher.explainforf:a. The IB node is 1.3862944 (ln 4), the real score, and says it is computed asdistribution.score(stats, normalization.tfn(...), lambda). - You expect its children to add up:
3 = no normalization, since no normalization means tfn = tf = 3, and1.3862944 = DistributionLL, as withNormalizationH1,H2,H3orZ. - Instead you get
1 = no normalizationand0.6931472 = DistributionLL(ln 2): the LL score at tfn = 1, a number the scorer never computed. - Why:
NoNormalization.explainreturns the value 1 while itstfnreturns tf, andIBSimilarity.explainhands that 1 to the distribution as tfn. UnderDFRSimilarityonly the1 = no normalizationchild is wrong.
Anyone who calls explain on a field scored by IBSimilarity with NoNormalization, an opt-in, experimental setup, gets a wrong Distribution child on every hit whose frequency is not 1 (a repeated term or a fractional sloppy-phrase frequency); with DFRSimilarity only the normalization child is off. Scores and rankings are correct. Present since 4.0 (2012); no prior report found.
Mechanism, terms and numbers549 words
Normalization.NoNormalization.tfn returns tf, but NoNormalization.explain returns Explanation.match(1, "no normalization"). IBSimilarity.explain passes that explanation's value to distribution.explain as tfn, so under IB with NoNormalization the Distribution child is distribution.score(stats, 1, lambda) while the node it explains is the real score at tfn = tf. On one document "a a a" with DistributionLL and LambdaDF the node is 1.3862944 (ln 4) and the child 0.6931472 (ln 2). All four IB distribution/lambda pairs show it; NormalizationH1/H2/H3/Z do not. Under DFRSimilarity, which computes tfn itself since 8.0.0, only the "no normalization" child shows 1, next to model children computed from "3.0 = tfn". Scores and rankings are correct. The code dates from LUCENE-2959 (2011): every release from 4.0.0-ALPHA to 10.6.0 has it, and all 14 releases run show the same defect, with identical numbers within each probe. A one-line fix, Explanation.match((float) tf, "no normalization"), passes the repro and the 118 similarity tests of lucene/core. Low priority: an opt-in, experimental similarity and explain output only.
Normalization.tfn"Returns the normalized term frequency" andexplain"Returns an explanation for the normalized term frequency" (Normalization.java:33-46). The genericexplainhas the value(float) tfn(stats, tf, len)(:47-56).NoNormalizationoverrides both:tfnreturnstf(:64-67),explainreturnsExplanation.match(1, "no normalization")(:69-72).IBSimilarity.scoreuses the real tfn:boost * distribution.score(stats, normalization.tfn(stats, freq, docLen), lambda.lambda(stats))(IBSimilarity.java:114-118).IBSimilarity.explainaddsnormExpl = normalization.explain(...)as a child and then callsdistribution.explain(stats, normExpl.getValue().floatValue(), lambdaExpl.getValue().floatValue())(:125-131): it takes the explanation's value as tfn.Distribution.explain"Returns the name of the model only, since both tfn and lambda are explained elsewhere" and returnsscore(stats, tfn, lambda)(Distribution.java:35-41). WithNoNormalizationthat isdistribution.score(stats, 1, lambda).- The node's own value is
score(stats, freq, docLen)(IBSimilarity.java:139-140), so the top value equals the search score. DFRSimilarity.explaincomputestfn = normalization.tfn(...)itself (DFRSimilarity.java:139-140) for its BasicModel and AfterEffect children (:143-144) but still addsnormExpl(:142), so only "1 = no normalization" is wrong there.
DistributionLL.score = -ln(lambda / (tfn + lambda)) (DistributionLL.java:33-35). One document, so LambdaDF = (1 + 1) / (1 + 1) = 1, moved down one ulp to 0.99999994 (LambdaDF.java:31-39). tfn 3 gives ln 4 = 1.3862944, the node and the search score; tfn 1 gives ln 2 = 0.6931472, the child. On the hunt's 5-document index (freq 3) the four pairs show node / child 1.7047480 / 0.9162907 (LL, DF), 1.2729657 / 0.6190392 (LL, TTF), 1.5447564 / 0.7996423 (SPL, DF) and 1.3294159 / 0.6553519 (SPL, TTF); with NormalizationH1 the child equals the node. Documents where the term occurs once look right, because there tfn = 1.
CheckHits.verifyExplanation takes a "computed as ... from:" node's own value as its combined value instead of recomputing it from the children (CheckHits.java:375, 437-438, 494-496). TestSimilarityBase runs NoNormalization but compares only the top explanation value with the score (:213-231); testLLForIB and testSPLForIB check the score only (:401-414, :468-476). TestDistributionLL and TestDistributionSPL do draw NoNormalization at random for IB (DistributionTestCase.java:97-99), but compare the score with the top explanation value and only rarely run CheckHits.verifyExplanation, which lets such a node through (BaseSimilarityTestCase.java:392-401).
Exposure and likelihood213 words
- Who. Callers of
IndexSearcher.explainon a field scored byIBSimilaritybuilt withNormalization.NoNormalization: every explained hit whose frequency, as passed to the similarity, is not exactly 1 is wrong, with no other data condition: a term that occurs more than once, or a fractional sloppy-phrase frequency (a sloppy phrase with freq 0.5 gives IB nodes of 0.40546513 over0.6931472 = DistributionLLchildren). UnderDFRSimilaritywithNoNormalizationonly the "no normalization" child shows 1. - Default or opt-in. Opt-in: IB and DFR are not the default similarity, and
NoNormalizationis one of five normalizations; both IB constructors name it as the way to ask for no normalization. Elasticsearch and OpenSearch map the IB/DFR settingnormalization: no, and Solrnone, toNoNormalization(read in their sources, not run). - Effect. A misleading explanation, not wrong results.
IndexSearcher.explainis "intended to be used in developing Similarity implementations", which is the audience that reads the children: here the Distribution child is about half the real score (0.6931472 against 1.3862944). - Scale. A one-document index is enough. Since 4.0.0-ALPHA (2012); no prior report found.
- Likelihood: plausible. Anyone using that configuration meets it on the first explained hit whose frequency is not 1, but IB without normalization is a niche choice and explanation children are rarely checked by hand.
One JUnit test on the public API: one document "a a a" scored by IBSimilarity(DistributionLL, LambdaDF, NoNormalization). It asserts that the Distribution child of the explanation equals the IB node at boost 1. Deterministic; the failure message prints the whole tree.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.similarities;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.Explanation;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIBNoNormalizationExplain extends LuceneTestCase {

  public void testDistributionChildMatchesScore() throws Exception {
    IBSimilarity sim =
        new IBSimilarity(new DistributionLL(), new LambdaDF(), new Normalization.NoNormalization());
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setSimilarity(sim))) {
      Document doc = new Document();
      doc.add(new TextField("f", "a a a", Field.Store.NO));
      w.addDocument(doc);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        searcher.setSimilarity(sim);
        Explanation ib = searcher.explain(new TermQuery(new Term("f", "a")), 0).getDetails()[0];
        double distribution = ib.getDetails()[2].getValue().doubleValue();
        // expected: distribution child = score (boost 1, tfn = freq = 3); actual: it uses tfn = 1
        assertEquals(ib.toString(), ib.getValue().doubleValue(), distribution, 1e-6);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.similarities.TestIBNoNormalizationExplain -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- The
DistributionLLchild equals the IB node, 1.3862944 (tfn = tf = 3), and the normalization child shows 3. - Observed
expected:<1.3862943649291992> but was:<0.6931471824645996>: the tree shows1 = no normalizationand0.6931472 = DistributionLL; with the fix the test passes.
More files, environment, full output393 words
One test class, one method, single thread. The test sets its own similarity on the writer and the searcher, so the test framework's random similarity does not apply, and ByteBuffersDirectory keeps the index in memory; the codec stays random. It sits in the similarities package but uses only public classes. Seeds DEADBEEF and 5EED1234 give the same values with assertions on and off.
It needs the org.apache.lucene.tests package (9.1.0 and later). Older releases were checked with a plain-Java probe of the same similarity configurations (a 5-document index, all four IB pairs, H1 controls; 4.0.0-ALPHA to 10.5.2, assertions off; 10.5.2 also with assertions on).
Lint: with the test and the fix in place, the core module's checkGoogleJavaFormat, forbiddenApisMain, forbiddenApisTest, ecjLintMain and ecjLintTest pass.
Regression test: this same test. It fails on stock main and passes with the fix. It checks the Distribution child only, so the alternative fix (IBSimilarity computing tfn itself) passes it too.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; 10.6.0, 10.5.2: fail; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (the only platform run) |
cp $REPRO/TestIBNoNormalizationExplain.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/similarities/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.similarities.TestIBNoNormalizationExplain -Ptests.seed=DEADBEEF -Ptests.asserts=true
# same failure with -Ptests.asserts=false
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true (the same with false)
TestIBNoNormalizationExplain > testDistributionChildMatchesScore FAILED
    java.lang.AssertionError: 1.3862944 = score(IBSimilarity, freq=3.0), computed as boost * distribution.score(stats, normalization.tfn(stats, freq, docLen), lambda.lambda(stats)) from:
      1 = no normalization
      0.99999994 = LambdaDF, computed as (n + 1) / (N + 1) from:
        1 = n, number of documents containing term
        1 = N, total number of documents with field
      0.6931472 = DistributionLL
     expected:<1.3862943649291992> but was:<0.6931471824645996>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:96C5D42B76EDBCE2]:0)
        at org.apache.lucene.search.similarities.TestIBNoNormalizationExplain.testDistributionChildMatchesScore(TestIBNoNormalizationExplain.java:49)
1 test completed, 1 failed

# the same explanation with the fix (plain-Java probe, fixed core jar)
  1.3862944 = score(IBSimilarity, freq=3.0), computed as boost * distribution.score(stats, normalization.tfn(stats, freq, docLen), lambda.lambda(stats)) from:
    3.0 = no normalization
    0.99999994 = LambdaDF, computed as (n + 1) / (N + 1) from: ...
    1.3862944 = DistributionLL

# DFR I(n)L with NoNormalization, stock main: only the normalization child is wrong
  0.31127813 = score(DFRSimilarity, freq=3.0), computed as boost * basicModel.score(stats, tfn) * afterEffect.score(stats, tfn) from:
    1 = no normalization
    1.2451125 = BasicModelIn, computed as tfn * log2((N + 1) / (n + 0.5)) from:
      3.0 = tfn, normalized term frequency
      ...
    0.25 = AfterEffectL, computed as 1 / (tfn + 1) from:
3.0 = tfn, normalized term frequencyNormalization.explainis documented to explain "the normalized term frequency": forNoNormalizationthat is tf, not 1.- IB uses that value as tfn, so the Distribution child shows a score never computed; with H1, H2, H3 or Z it equals the node.
- Nothing documents 1 as intended; tests check only the top value, and Lucene fixes explain-only errors as bugs.
The full argument262 words
- The contract.
Normalization.explain"Returns an explanation for the normalized term frequency" (Normalization.java:41); the generic implementation's value is that tfn (:49);NoNormalization.tfnreturnstf(:66). - IB relies on it.
Distribution.explain: tfn and lambda "are explained elsewhere" (Distribution.java:35-38).IBSimilarity.explainpasses the normalization explanation's value as tfn (IBSimilarity.java:129-131), and the node text says "computed as boost * distribution.score(stats, normalization.tfn(stats, freq, docLen), lambda.lambda(stats)) from:" (:145-147). With H1, H2, H3 or Z the Distribution child equals the node at boost 1, up to float rounding (the H1 control and the hunt's 16 IB configurations with H1/H2/H3/Z). - DFR's own tree contradicts itself: "1 = no normalization" sits next to
BasicModelIn, whose own child reads "3.0 = tfn, normalized term frequency". This is the weaker of the two symptoms: under DFR no computation consumes the 1, so it can be read as a display marker; under IB the Distribution child is a value the scorer never computes. - Explanations are a supported feature of these models. LUCENE-2959's CHANGES entry: the models "support all of lucene's features (boosts, slops, explanations, etc)" (
lucene/CHANGES.txt:16108-16112). - Precedent. Lucene files explain-only value errors under Bug Fixes: "GITHUB#13691: Fix incorrect exponent value in explain of SigmoidFunction" (9.12.0,
lucene/CHANGES.txt:2705); LUCENE-7065 (6.0.0,:9496). - History. The value 1 and the IB hand-off arrived together in
cfaf91c7398(2011); later commits on these lines are mechanical. No javadoc, test, CHANGES or MIGRATE entry or code comment says 1 is intended, nor does any upstream discussion found; the LUCENE-2959 and LUCENE-3220 threads discuss NoNormalization's name only.
The devil's-advocate check167 words
The strongest case for "not a bug" (the intended-behaviour check and the cross-model "intended" review): 1 is a neutral "nothing applied" marker, the convention of the old AfterEffect.NoAfterEffect, which explained itself as 1; Explanation.match documents its value as "the contribution to the score of the document"; the classes are @lucene.experimental; explain is a debugging aid; CheckHits deliberately treats "computed as" nodes as opaque; and nobody complained in 15 years.
Why it fails: normalization is not a multiplier. NoAfterEffect's 1 matched its own score, a factor of 1; NoNormalization's output is tf, and its documented explanation is of the normalized term frequency. Even read as a marker, IB consumes the 1 as tfn, so the Distribution child explains a score that was never computed, which is nobody's "contribution to the score". The experimental tag and the debugging purpose lower the impact (Low priority); they do not make the number right. Survival with tests that check only the top value is missing coverage, not intent.
Recommended NoNormalization.explain returns tf (validated)
Make NoNormalization.explain return tf as its value: Explanation.match((float) tf, "no normalization"), one line. It fixes the IB Distribution child and the normalization child under IB and DFR, and no score changes. The repro, the 118 similarity tests of lucene/core and the core lint checks pass with it.
    @Override
    public Explanation explain(BasicStats stats, double tf, double len) {
-      return Explanation.match(1, "no normalization");
+      return Explanation.match((float) tf, "no normalization");
    }
All options and trade-offs2 options · 355 words
Both options were run through gradle in a scratch worktree of 645d4fe14a20. The first fixes the root cause; the second only stops IB from reading tfn off an explanation. The two were not run together; the first alone is the minimal demonstrated fix.
Normalization.java +1/-1, the same change as the hunt's fix sketch:
    @Override
    public Explanation explain(BasicStats stats, double tf, double len) {
-      return Explanation.match(1, "no normalization");
+      return Explanation.match((float) tf, "no normalization");
    }
Trade-offs
- Fixes both symptoms: the IB Distribution child and the "no normalization" child under IB and DFR.
- No score change:
NoNormalization.tfnis untouched. - Code that parses explanation text and expects "1 = no normalization" would see "3.0 = no normalization"; the new value is the documented one.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle--offline, OpenJDK 25.0.3, seed DEADBEEF. Stock: the repro fails with assertions on and off. - With the fix:
:lucene:core:test --tests 'org.apache.lucene.search.similarities.*'runs 27 suites, 119 tests (the 118 upstream similarity tests,TestSimilarityBase27 among them, plus the repro), 0 failures, with assertions on and off.:lucene:queries:test --tests TestSpanSimilarity, the only regularly run test outside the similarities package that usesNoNormalization, passes; the@MonsterTest20NewsgroupsClassificationinlucene/classificationalso uses it, for scores only (no explain), and was not run. The core module'scheckGoogleJavaFormat,forbiddenApisMain,forbiddenApisTest,ecjLintMainandecjLintTestpass. - A plain-Java probe on the fixed jar shows "3.0 = no normalization" and "1.3862944 = DistributionLL" under IB and "3.0 = no normalization" under DFR, with unchanged scores.
IBSimilarity.java +2/-3: double tfn = normalization.tfn(stats, freq, docLen); and distribution.explain(stats, tfn, lambdaExpl.getValue().floatValue()).
Trade-offs
Fixes the Distribution child for any Normalization, including a user subclass whose explanation value differs from its tfn. Leaves "1 = no normalization" in the IB and DFR trees (run with the explain-tree probe), yet passes the regression test, which checks the Distribution child only. Good as a follow-up to the recommended fix.
What the checks validated
The similarities package with assertions on: 119 tests, 0 failures (the repro passes).
Elasticsearch and OpenSearch map the IB/DFR setting normalization: no, and Solr none, to NoNormalization (read in their sources, not run), so explanations of such fields there go through this code.
A semi-formal check recomputed every "computed as ... from:" node of 3,178 explanations (79 similarity configurations, 14,554 formula nodes) from its own children. The 104 IB nodes with NoNormalization disagreed while every other IB normalization agreed; the finder reduced it to a public-API test.
The method in full175 words
Method: semi-formal (a differential evaluation of explanation trees on the stock jars).
- Sweep. A public-API test program dumped every explained hit with its index statistics over 79 similarity configurations (DFR, IB, DFI, Axiomatic, LM, BM25, Classic and others) and many query types, with assertions on and off: 3,178 explained hits. An independent evaluator recomputed each "computed as <formula> from:" node from its own children and checked combiners and labelled statistics: 14,554 formula nodes.
- Finding. The 104 IB score nodes of the four IB configurations with
NoNormalizationdid not matchboost * distribution.score(...)on their own children; the 16 IB configurations with H1, H2, H3 or Z did. 10 of 10 injected wrong formulas were caught, so the check is not vacuous. - Then the finder reduced it to a JUnit test. An executing cross-model review, an independent reproducer, a second cross-model review, a devil's-advocate check, an adjudication, the registration check, an audit, the version-history runs, a prior-report search and a repro minimization followed. The same sweep found two sibling bugs with their own fix sites (LFV-920, LFV-922).
No prior report found in these searches (2026-10-28 and 2026-11-01): GitHub issues, PRs and commits, the JIRA archive, mailing lists, downstream trackers and the web, plus the files of every open PR. The closest items wrote or reworded this code (LUCENE-2959, LUCENE-8011, LUCENE-8015) without mentioning the value 1.
Searches2 searches
Verdict new. Related, not this bug: #4033 (LUCENE-2959) and #4293 (LUCENE-3220) wrote the code and discuss NoNormalization's name only; #9059 (LUCENE-8011) added IB's formula text (the CheckHits rule that takes a "computed as ... from:" node at its own value is older: LUCENE-7524, 2016, first in 6.4.0, with the single-child exemption from LUCENE-7996, 2017); #9045 (LUCENE-7997) checks only the top explanation value; #9063 (LUCENE-8015) fixed DFR's model children as a side effect without mentioning it; #16916 / #16909 (open) fix an IB class-javadoc link label; #16137 / #16139 are the IB DistributionSPL score path; #16921 / #16949 (open) reword BM25/TFIDF idfExplain javadoc. Lucene.NET carries the same NoNormalization.Explain returning 1 (a port, unreported).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive, apache/lucene-solr, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch, all of GitHub), JIRA (LUCENE, SOLR, LUCENENET), dev@/java-user@/issues@/commits@ lists, web and forums | 2026-10-28 | two scripted prior-report search runs (each 16 issue/PR, 3 commit, 2 downstream, 20 list and 4 JIRA-archive queries), 34 manual GitHub searches, 8 JIRA queries, 11 web and 5 forum searches; 16 upstream threads read in full; the changed files of all 413 open PRs and the 22 PRs closed since 2026-10-24 | no report |
| GitHub (apache/lucene, all of GitHub) | 2026-11-01 | "NoNormalization" issues and PRs, "IBSimilarity explain", all-GitHub "NoNormalization explain"; the changed files of all 62 PRs updated since 2026-10-28; last commits on the three fix-site files | no report; only #16949 touches the similarities package (BM25/TFIDF javadoc); not fixed upstream |
Introduced with the IB/DFR framework by LUCENE-2959 (cfaf91c7398, 2011), first released in 4.0.0-ALPHA. Every release run since, up to 10.6.0, and main show the same defect, with identical numbers within each probe. Not a regression; not fixed upstream.
Versions tested6 rows
Introduced by cfaf91c7398 "LUCENE-2959: add state of the art ranking to Lucene" (#4033), 2011-09-11, which merged the flexscoring branch; the code first appears there in 8f73f80d1d7 (LUCENE-3220, #4293, 2011-07-15). The value 1, the IB hand-off and the javadoc contract arrived together; later commits on these lines are mechanical (the Explanation.match API, float to double, Number values, reformatting). LUCENE-8011 (6771886cf33, 8.0.0) gave the IB node its formula text naming normalization.tfn. LUCENE-8015 (63b63c57348, 8.0.0) made DFRSimilarity.explain compute tfn itself, which fixed DFR's model children; until 7.7.3 they were computed at tfn = 1 too. IB was not touched. Upstream main 2f424fd428d (2026-10-30) has the same three files: the last commits are from 2020-12-23 (Normalization.java) and 2024-10-04 (IBSimilarity.java, DFRSimilarity.java).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails through gradle with assertions on and off; the fix passes |
main a9779ef3c193 | affected | the hunt's and verifiers' tests fail, -ea and -da; history probe 4 of 4 IB pairs |
| 10.6.0, 10.5.2 | affected | minimal test fails (-da); 10.5.2 also with the history probe (-ea, -da) |
| 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 | affected | history probe: 4 of 4 IB pairs, the same numbers; DFR model children use tfn 3 |
| 4.0.0-ALPHA, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3 | affected | history probe: 4 of 4 IB pairs, the same numbers; DFR model children also at tfn 1 |
| 3.6.2 | no API | no IB/DFR classes |
Reproduced by the finder, executing cross-model reviews (OpenAI GPT-5.6), an independent reproducer, a devil's-advocate check, the adjudication, the registration check, an audit, the repro minimization and this doc's gradle runs; every one says real.
Checks and verdicts292 words
Every reproduction ran on stock builds; every fix check with the patched class. The cross-model reviewers ran their own tests on a checkout whose similarity sources are byte-identical to the hunted commit.
| Check | Verdict | What it found |
|---|---|---|
| Finder (explanation-tree sweep) | candidate | 104 IB nodes with NoNormalization disagree with their children, the 16 other IB configurations agree; JUnit fails on main (-ea, -da); the version-history runs later ran it on 10.5.2, 10.0.0 and 9.12.3 (-da), where it fails too. |
| Cross-model refute review (OpenAI GPT-5.6, executing) | real (high) | Own JUnit fails on main with three seeds, -ea and -da; H1 control passes; with the fix all 118 similarity tests pass. |
| Independent reproducer | real | Own 3-test JUnit on 6 documents fails 2 of 3 on main, 10.5.2 and 9.12.3; documents with tf 1 are consistent; the fix passes 3 of 3. |
| Cross-model review (OpenAI GPT-5.6, intended lens, executing) | real (high) | Own JUnit (tf 4: node 2.0368819, child 0.9808292) fails on main and 10.5.2; rated the "by design" case weak. |
| Devil's advocate | real (high) | Built and rejected the "neutral marker" case; fails on main, 10.5.2 and 9.12.3. |
| Adjudication | confirmed (high), minor | Re-ran the independent reproduction's JUnit with a new seed: 2 of 3 fail, control passes; hand-checked the ln values. |
| Registration check and audit | confirmed | Re-runs on main with -ea and -da; the fix passes; numbers hand-checked. |
| Repro minimization | verified | The one-test repro fails on 645d4fe14a20 with -ea and -da, two seeds; the fix passes. |
| This doc (2026-11-01) | reproduced, fix validated | Gradle on 645d4fe14a20: stock fails, fix passes the repro, 118 similarity tests, TestSpanSimilarity and core lint; 10.6.0 and 10.5.2 jars fail. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 495 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,380 words
- Registry title
- Normalization.NoNormalization.explain reports 1 instead of tf, so IBSimilarity explains its Distribution at tfn = 1 and that child disagrees with the score it explains
- Area
- core / search similarities (Normalization.NoNormalization explanation; IBSimilarity and DFRSimilarity explain trees)
- Priority
- Low, rank 1040: Explain-only with correct scores; it needs IBSimilarity or DFRSimilarity with NoNormalization and a term frequency other than 1.
- Impact class
- minor
- Impact note
- Applications or developers that call IndexSearcher.explain on a field scored by the @lucene.experimental IBSimilarity (or DFRSimilarity) built with Normalization.NoNormalization, the documented way to ask for no normalization, get a wrong explanation for every hit whose term frequency is not exactly 1 (a term that occurs more than once, or a fractional sloppy-phrase frequency): under IB the Distribution child is distribution.score(stats, 1, lambda) (freq 3, LL with LambdaDF: 0.9162907 under a node of 1.7047480) and the 'no normalization' child shows 1 instead of tf; under DFR only the 'no normalization' child shows 1; scores and rankings are correct, ordinary scale, every release since 4.0.0-ALPHA.
- Summary
- You score a field with IBSimilarity(distribution, lambda, new Normalization.NoNormalization()) and call IndexSearcher.explain on a document where the term occurs 3 times. You expect the explanation to add up: the IB node says it is 'computed as boost * distribution.score(stats, normalization.tfn(stats, freq, docLen), lambda.lambda(stats))', NoNormalization.tfn returns tf, and Normalization.explain is documented to return 'an explanation for the normalized term frequency', so the normalization child should show 3 and the Distribution child should equal the node at boost 1. Instead NoNormalization.explain returns the value 1, IBSimilarity feeds that 1 into distribution.explain as tfn, and the Distribution child shows 0.9162907 under a node of 1.7047480 (all four IB distribution/lambda pairs), while the score itself is right.
- Introduced
- cfaf91c73981bcce5f240aba5ad1cc29d7b517e4 (LUCENE-2959 'add state of the art ranking to Lucene', apache/lucene#4033; svn trunk r1169470; git author and committer Robert Muir, CHANGES credits 'David Mark Nemeskey via Robert Muir'; no pull request, pre-GitHub). It merged the flexscoring branch, where the same code first appears in 8f73f80d1d7 (LUCENE-3220, apache/lucene#4293, 2011-07-15), and wrote both halves together with the javadoc contract they break: NoNormalization.explain returning new Explanation(1, "no normalization") while tfn returns tf, and IBSimilarity.explain passing normExpl.getValue() to distribution.explain [read: git log -S over the whole history ('"no normalization"' lists only 8f73f80d1d7, cfaf91c7398 and a branch_8x deletion; 'normExpl.getValue()' only those two plus 63b63c57348, LUCENE-8015, which removed it from DFRSimilarity only); blame and git log -L on main: every later touch (c6821e1a194 LUCENE-6446, 42717d5f4bb LUCENE-7997, 6771886cf33 LUCENE-8011, c1030eeb74e LUCENE-8012, 2d6ad2fee6d LUCENE-9570) is mechanical; the JIRA threads #4033 and #4293 discuss NoNormalization's naming, not its explain value]; executed: affected from 4.0.0-ALPHA on, not a regression (2011-09-11 (cfaf91c7398, trunk merge, svn r1169470); 2011-07-15 (8f73f80d1d7, flexscoring branch))
- First affected version
- 4.0.0-ALPHA [exec] (tagged 2012-06-29, the first release containing cfaf91c7398; run on a plain classpath with the checksum-verified Maven Central jar); first final release 4.0.0 [exec]; no unaffected release has the API: 3.6.2 has no IB/DFR classes [exec, reflection probe]
- Affected versions
- Every release from 4.0.0-ALPHA to 10.5.2 (123 release tags contain cfaf91c7398 and the defect lines are semantically unchanged since), 10.6.0 (the branch_10_6 head 4ae946e5a9b9, the RC1 revision) and main a9779ef3c193 [exec: the follow-up's history probe is AFFECTED in 4 of 4 IB distribution/lambda pairs, with its NormalizationH1 control consistent and identical numbers (LL with LambdaDF, freq 3: node 1.7047480, Distribution child 0.9162907, 'no normalization' child 1.0), on 4.0.0-ALPHA, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 (-da; 10.5.2 also -ea), the branch_10_6 head 4ae946e5a9b9 and main a9779ef3c193 (-ea and -da); the finder's JUnit fails on 9.12.3, 10.0.0, 10.5.2 and main (it does not compile on 9.0.0, which predates the tests package); the independent reproduction's JUnit fails 2 of 3 on main, 10.5.2 and 9.12.3; the intended-behaviour check's re-runs fail on main, 10.5.2 and 9.12.3]. In 4.0.0-ALPHA to 7.7.3, DFRSimilarity with NoNormalization also computed its BasicModel and AfterEffect children at tfn = 1 [exec]; since 8.0.0 (LUCENE-8015, 63b63c57348) only DFR's 'no normalization' child shows 1. Upstream main c5ab3e57b9b (author date 2026-10-28), branch_10_6 and branch_10x are unchanged: the last commits on Normalization.java are 2d6ad2fee6d (2020-12-23, reformat) and on IBSimilarity.java and DFRSimilarity.java dab731175c8 on main (2024-10-04, constructors) [read 2026-10-28]; not fixed anywhere. All runs on aarch64 Linux with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (verdict new, searched 2026-10-28, read-only: a scripted prior-report search in two runs (each 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list (dev@, java-user@, issues@, commits@) and 4 JIRA-archive queries; web leg in run 1), 2,624 and 2,795 distinct hits triaged; 34 manual GitHub searches (apache/lucene, apache/lucene-solr, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch and all of GitHub), 2 commit searches, 8 JIRA queries over LUCENE, SOLR and LUCENENET, 11 web and 5 forum searches; 16 upstream issue threads and apache/lucene-solr#280 read in full (among them LUCENE-2959 #4033, LUCENE-3220 #4293, LUCENE-8011 #9059, LUCENE-8015 #9063, LUCENE-7997 #9045); a changed-file scan of all 413 open apache/lucene PRs (none changes Normalization.java, IBSimilarity.explain or DFRSimilarity.explain; the only open PR on IBSimilarity.java, #16916 by GitHub Lyin-OTTF, changes one class-javadoc link) and of the 22 PRs closed since 2026-10-24 (none touches similarities); plus the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's own searches. Refresh 2026-10-28: 'NoNormalization' issues only #4293, PRs 0; 'IBSimilarity explain', '"no normalization" explain' and 'Normalization explain' 0; all-GitHub 'NoNormalization explain' 0; 'IBSimilarity' PRs only #16916 (javadoc link) and #16139 (merged 2026-09-10, DistributionSPL score path); issues matching 'explain' updated since 2026-10-27 only #16921 (BM25/TFIDF idfExplain javadoc wording, by GitHub hidingmyname); file lists of the 34 open and 7 closed PRs updated since 2026-10-27: only #16916 touches search/similarities; the last commits on the three fix-site files are unchanged; main head c5ab3e57b9b)
- Lucene commit tested
- main
645d4fe14a20(2026-11-01): the minimal test fails through gradle in a scratch worktree with assertions on and off; with the recommended fix it passes, the 118 similarity tests oflucene/coreandTestSpanSimilaritypass, and the core module's format, forbidden-apis and ECJ checks pass. The minimal test also fails on the 10.6.0 and 10.5.2 jars. Earlier, the hunt's tests ran on maina9779ef3c193(byte-identical similarity sources) and a history probe on 4.0.0-ALPHA to 10.5.2.
- Finding record
lucene/core/src/java/org/apache/lucene/search/similarities/Normalization.java:26 (@lucene.experimental), 41 (explain javadoc), 47-55 (generic explain value tfn), 64-66 (NoNormalization.tfn returns tf), 69-72 (NoNormalization.explain returns 1) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/search/similarities/IBSimilarity.java:66 (@lucene.experimental), 81 and 95 (constructor javadoc 'if you want no normalization, instead pass NoNormalization'), 115-117 (score), 121-132 (explain feeds normExpl value as tfn), 139-148 (node text) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/search/similarities/DFRSimilarity.java:134-145 (explain computes tfn with normalization.tfn) and Distribution.java:35-41 (explain javadoc 'both tfn and lambda are explained elsewhere') @ a9779ef3c193lucene/test-framework/src/java/org/apache/lucene/tests/search/CheckHits.java:437-500 (a 'computed as ... from:' node is taken as combined = value) @ a9779ef3c193GitHub REST/search (read-only), 2026-10-28: search/issues queries listed in upstream; repos/apache/lucene/pulls open and closed sorted by update and pulls/N/files for each updated since 2026-10-27; pulls/16916/files; repos/apache/lucene/commits?path= for the three fix-site files; commits/main = c5ab3e57b9b
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/Normalization.java:26, 33-56, 58-78a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/IBSimilarity.java:114-118, 120-132, 134-149a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/Distribution.java:32-41; DistributionLL.java:33-35; LambdaDF.java:31-39a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/DFRSimilarity.java:133-145a Lucene main checkout (645d4fe14a20) lucene/test-framework/src/java/org/apache/lucene/tests/search/CheckHits.java:375, 411-413, 437-438, 485-500a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/similarities/TestSimilarityBase.java:85-91, 213-231, 401-414, 468-476a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/similarities/DistributionTestCase.java:97-99; lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/BaseSimilarityTestCase.java:392-401
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/IBSimilarity.java:66, 81-82, 95-96; Normalization.java:26a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:934-941
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/Normalization.java:41, 47-56, 64-67, 69-72; Distribution.java:35-41; IBSimilarity.java:129-131, 139-148a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/Explanation.java:30a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:2689-2705 (9.12.0 Bug Fixes, GITHUB#13691), 9494-9498 (6.0.0 Bug Fixes, LUCENE-7065), 16108-16112 (LUCENE-2959)
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/Normalization.java:64-72; IBSimilarity.java:114-118, 125-131
- TestIBNoNormalizationExplain.java (one test class):
repro/LFV-921/src/org/apache/lucene/search/similarities/TestIBNoNormalizationExplain.java(53 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed runs.
assets/LFV-921/bug.png(495 KB)