Each snippet is javadoc text in a <pre><code class="language-xml"> block. Javadoc shows it as text and no build step parses it, so a slip survives. The convention is class="solr.<Name>" with the factory's simple class name, as the neighbouring LimitTokenPositionFilterFactory example writes it.
- An analysis factory builds a tokenizer, token filter or char filter from string arguments; Lucene registers every factory through Java's service loader (SPI).
- Schema-driven hosts such as Solr describe an analysis chain in XML: one
<tokenizer>,<filter>or<charFilter>element per factory,class="solr.StopFilterFactory"naming the factory. - Most factory javadocs open with such a
<fieldType>snippet. Lucene itself has no schema loader and never parses them.
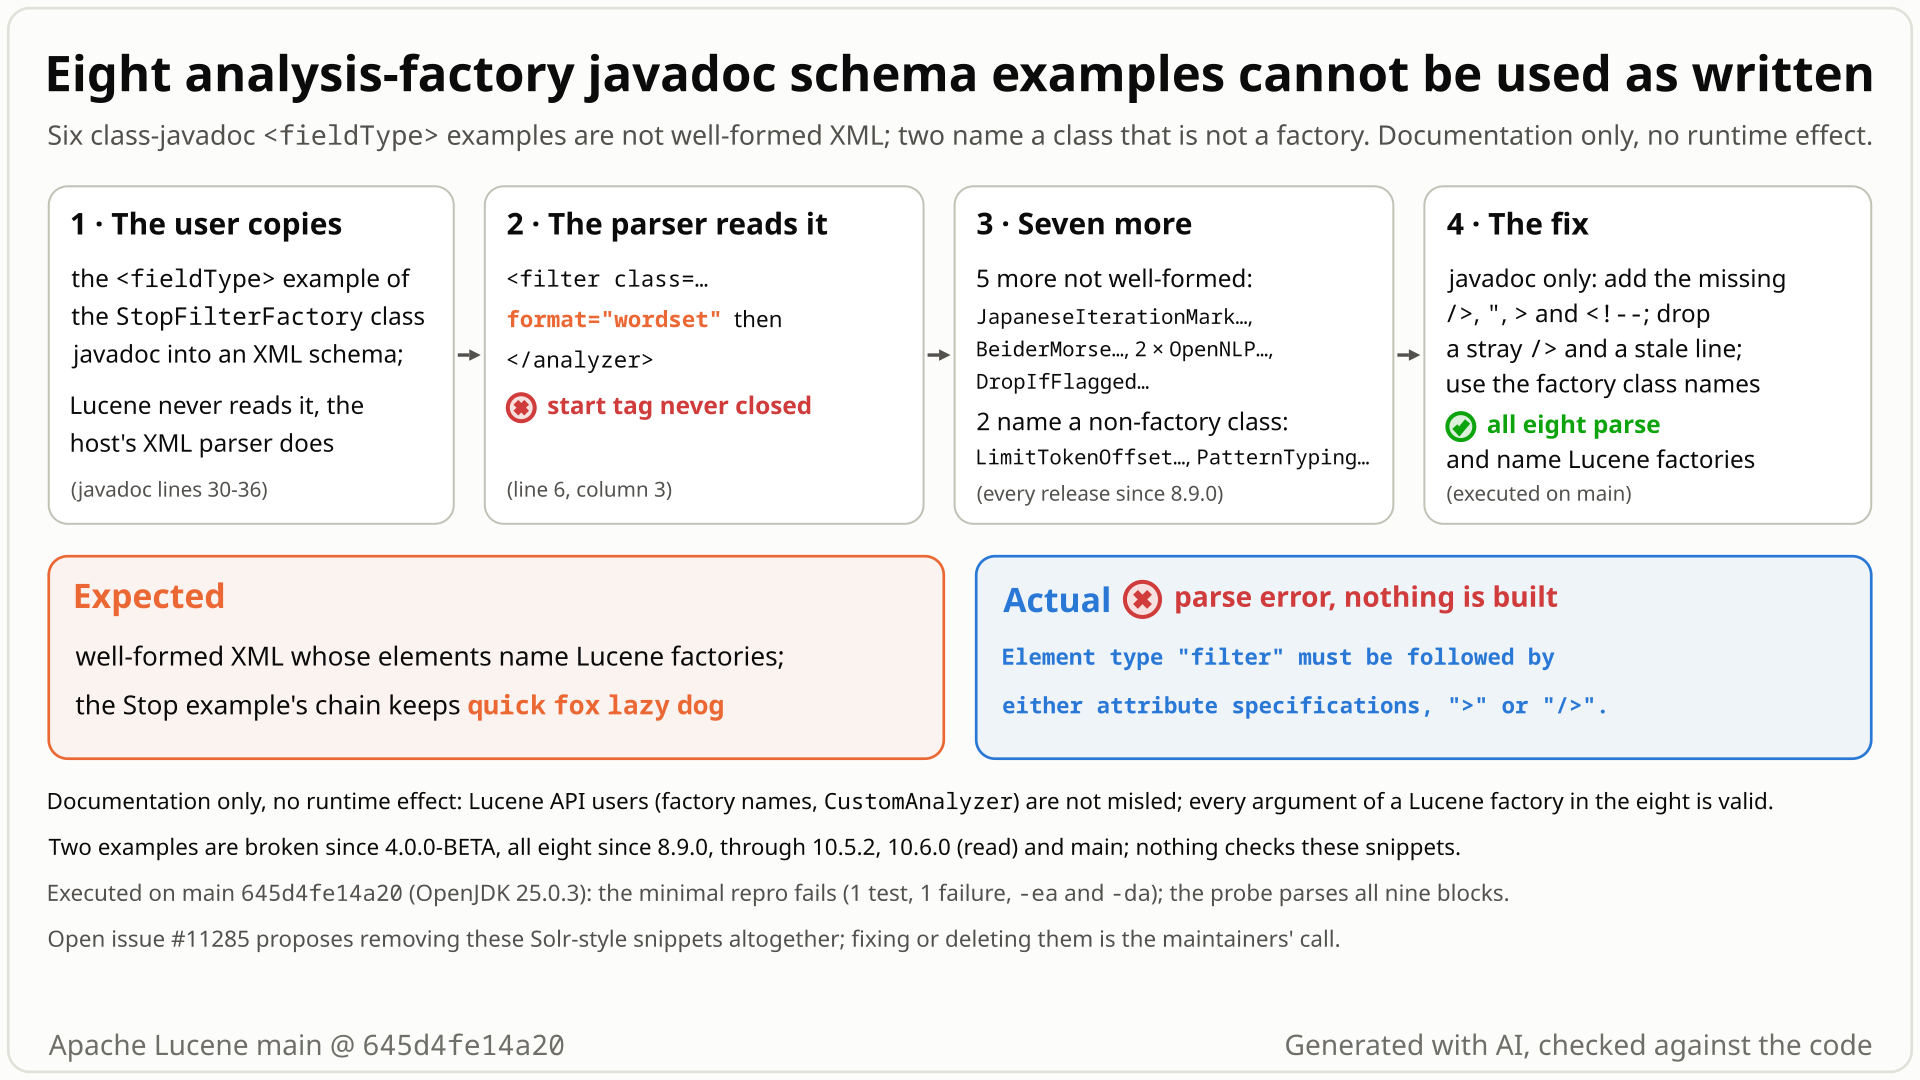
StopFilterFactory example as copied: the <filter tag never closes, so the parser stops at </analyzer>; seven more factory examples have similar slips, and a javadoc-only fix repairs all eight. Select the still to open it at full size. Generated with AI, checked against the code.- You want a stop filter in a Solr-style XML schema and copy the 7-line
<fieldType>example from theStopFilterFactoryjavadoc. - You expect well-formed XML whose elements each name a factory as
solr.<FactoryName>, as the other factory examples do (141 of the 149 blocks are well-formed; 328 of the 332 elements name a registered factory). - Instead the XML parser stops at line 6, column 3:
Element type "filter" must be followed by either attribute specifications, ">" or "/>". The<filtertag above never closes; its/>was lost in a 2013 cleanup. - Seven more examples have the same kind of slip: a missing quote, a missing
>, a stray/>,<--for<!--, orsolr.LimitTokenOffsetFilterandcom.example.PatternTypingFilter, which are filters, not factories. All eight are in every release since 8.9.0.
Readers who copy a snippet into a Solr-style XML schema get an XML parse error (six snippets) or a class that is not a factory (two) when the schema loads, every time. Lucene API users (CustomAnalyzer, SPI names) are not misled. StopFilterFactory is mainstream; the other seven are in optional modules or are rarely used filters.
Mechanism, terms and numbers556 words
Most Lucene analysis factories show, in their class javadoc, the XML you would put in a Solr-style schema to use them, for example <filter class="solr.StopFilterFactory" words="stopwords.txt"/>. In eight factories that snippet is broken. Six are not well-formed XML: StopFilterFactory (the <filter start tag is never closed), JapaneseIterationMarkCharFilterFactory (the class value has no closing quote after the class name, so the next quote ends it), BeiderMorseFilterFactory (no > before </filter>), OpenNLPTokenizerFactory and OpenNLPLemmatizerFilterFactory (the <fieldType start tag has no >, plus a stray /> line in the second) and DropIfFlaggedFilterFactory (<-- other filters --> is not an XML comment). Two parse but name a class that is not a factory: LimitTokenOffsetFilterFactory says solr.LimitTokenOffsetFilter, and PatternTypingFilterFactory's own element is com.example.PatternTypingFilter; its next line names solr.TokenAnalyzerFilter, a filter from a Solr patch that was never committed, and its first sentence describes that filter. Copying the StopFilterFactory snippet gives Element type "filter" must be followed by either attribute specifications, ">" or "/>" at line 6, column 3. No Lucene code parses these snippets, and every factory argument in them (each attribute other than class, the TokenAnalyzerFilter line aside) is one its factory reads, so only readers who copy them are hit. All eight are in every release since 8.9.0, the oldest two since 4.0.0-BETA. A javadoc-only fix (8 files, 11 insertions, 13 deletions) makes all eight parse and name registered factories.
| factory | lines | as written | what is wrong |
|---|---|---|---|
StopFilterFactory | 33-34 | <filter class="solr.StopFilterFactory" ignoreCase="true" / words="stopwords.txt" format="wordset" | start tag never closed: no /> |
JapaneseIterationMarkCharFilterFactory | 29 | <charFilter class="solr.JapaneseIterationMarkCharFilterFactory normalizeKanji="true" ... | no closing quote after the class name: the next " (meant to open normalizeKanji's value) ends the class value, and the parser stops at true" |
BeiderMorseFilterFactory | 35-38 | <filter class="solr.BeiderMorseFilterFactory" ... languageSet="auto", then </filter> | no > before </filter> |
OpenNLPTokenizerFactory | 34 | <fieldType name="text_opennlp" class="solr.TextField" positionIncrementGap="100" | start tag has no > |
OpenNLPLemmatizerFilterFactory | 33, 38 | the same <fieldType ... without >; a line holding only /> | missing >, stray /> |
DropIfFlaggedFilterFactory | 35 | <-- other filters --> | not an XML comment (<!-- -->); a placeholder line |
LimitTokenOffsetFilterFactory | 30 | <filter class="solr.LimitTokenOffsetFilter" .../> | names the filter, not the factory |
PatternTypingFilterFactory | 40, 41, 32 | com.example.PatternTypingFilter; solr.TokenAnalyzerFilter; first sentence "Provides a filter that will analyze tokens with the analyzer from an arbitrary field type" | own element names the filter in a placeholder package; TokenAnalyzerFilter exists nowhere in Lucene (a never-committed Solr patch); the sentence describes that filter |
The control, LimitTokenPositionFilterFactory lines 26-32, has the same shape and is correct.
Checked against Lucene's own SPI registrations (the META-INF/services/org.apache.lucene.analysis.*Factory files of lucene-core and the analysis modules: 9 char-filter, 19 tokenizer and 138 token-filter factories): LimitTokenOffsetFilter, PatternTypingFilter and TokenAnalyzerFilter are not among them.
No test or build task reads language-xml blocks, and javadoc rendering accepts the broken text. #15573 (2026-01-15) rewrote every one of these blocks from <pre class="prettyprint"> to <pre><code class="language-xml"> and kept all eight defects.
Any runtime effect: every factory argument in the eight snippets (each attribute other than class) is one its factory reads, the never-committed TokenAnalyzerFilter line aside. The exact error a particular schema host prints: no real schema loader was run. The two synonym-factory examples' [optional tokenizer factory parameters] placeholder is intentional and not reported.
Exposure and likelihood120 words
- Who. Readers who copy a snippet into an XML schema of a Solr-style host. No query, document or index file reaches the text.
- Default vs opt-in.
StopFilterFactoryis mainstream;LimitTokenOffset,PatternTypingandDropIfFlaggedare rarely used filters; the other four live in optional modules. - Scale. No size matters: the copied snippet fails every time. Every release from 4.0.0-BETA through 10.6.0 (132 releases) has at least two of the eight; all eight since 8.9.0.
- Effect. Loud, not silent: a strict XML parser rejects the six malformed snippets at once, and nothing in Lucene is indexed or searched differently (lenient parsers and real schema loaders were not tested).
- Priority. Low (rare, documentation only), but cheap to fix and easy to review.
One JUnit class with one test. It parses the StopFilterFactory example, copied verbatim from the javadoc with the HTML entities unescaped, with the JDK XML parser. Needs only core, codecs and test-framework (the test framework loads codecs); no random input. The other seven rows are shown by a source check (collapsed below).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.core;

import java.io.StringReader;
import javax.xml.parsers.DocumentBuilderFactory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.xml.sax.InputSource;
import org.xml.sax.SAXParseException;

public class TestStopFilterFactoryJavadocExample extends LuceneTestCase {

  // StopFilterFactory javadoc example, verbatim: expected well-formed XML; the filter tag never closes
  private static final String EXAMPLE =
      """
      <fieldType name="text_stop" class="solr.TextField" positionIncrementGap="100" autoGeneratePhraseQueries="true">
        <analyzer>
          <tokenizer class="solr.WhitespaceTokenizerFactory"/>
          <filter class="solr.StopFilterFactory" ignoreCase="true"
                  words="stopwords.txt" format="wordset"
        </analyzer>
      </fieldType>
      """;

  public void testExampleIsWellFormedXml() throws Exception {
    DocumentBuilderFactory dbf = DocumentBuilderFactory.newInstance();
    dbf.setFeature("http://apache.org/xml/features/disallow-doctype-decl", true);
    try {
      dbf.newDocumentBuilder().parse(new InputSource(new StringReader(EXAMPLE)));
    } catch (SAXParseException e) {
      throw new AssertionError("expected well-formed XML, but: " + e.getMessage(), e);
    }
  }
}
# $LUCENE: a built checkout (./gradlew jar); $REPRO: the directory holding org/apache/lucene/analysis/core/Test...java
# $DEPS: junit 4.13.2, randomizedtesting-runner 2.9.2, hamcrest 3.0
V=11.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar:$DEPS
javac -d out -cp "$CP" $REPRO/org/apache/lucene/analysis/core/TestStopFilterFactoryJavadocExample.java
java -ea -Dtests.seed=DEADBEEF -cp "out:$CP" org.junit.runner.JUnitCore org.apache.lucene.analysis.core.TestStopFilterFactoryJavadocExample
# assertions off, same result: java -da -Dtests.asserts=false ...
- Expected
- The
StopFilterFactoryjavadoc example parses as XML. - Observed
SAXParseExceptionat line 6, column 3:Element type "filter" must be followed by either attribute specifications, ">" or "/>", with assertions on and off.
More files, environment, full output391 words
The text block is the javadoc block StopFilterFactory.java:29-36 at 645d4fe14a20 with the * prefix removed and the entities unescaped; a script found the two identical there and at 10.5.2, and the same extraction on the unpatched tree regenerates the test's text exactly. Because the test embeds the snippet, on a release jar it re-tests the text; release dating rests on reading each release's sources.
Inside a Lucene checkout with gradle: put the file in lucene/analysis/common/src/test/org/apache/lucene/analysis/core/ and run ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.core.TestStopFilterFactoryJavadocExample. It fails there too (1 test, 1 failure, the same message), and its fixed twin passes.
All eight rows, read from source (Python stdlib XML parser plus a lookup of each solr.<Name> in the checkout's SPI service files; main 645d4fe14a20):
StopFilterFactory.java:29-36                      not well-formed XML (line 7, column 2)
JapaneseIterationMarkCharFilterFactory.java:26-32 not well-formed XML (line 4, column 83)
BeiderMorseFilterFactory.java:31-40               not well-formed XML (line 8, column 4)
OpenNLPTokenizerFactory.java:33-38                not well-formed XML (line 3, column 2)
OpenNLPLemmatizerFilterFactory.java:32-43         not well-formed XML (line 3, column 2)
DropIfFlaggedFilterFactory.java:32-38             not well-formed XML (line 4, column 7)
LimitTokenOffsetFilterFactory.java:26-32          <filter class="solr.LimitTokenOffsetFilter"> names no registered TokenFilterFactory
PatternTypingFilterFactory.java:36-45             com.example.PatternTypingFilter and solr.TokenAnalyzerFilter name no registered TokenFilterFactory
LimitTokenPositionFilterFactory.java:26-32        OK (control)
(This checker keeps the empty line after <pre><code>, so its line numbers are one higher than the JDK parser's.)
No separate regression test is suggested: this test copies the example, so it would not notice a later edit of the javadoc; the real guard is a build check over all language-xml blocks (Suggested fix, option C).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the 10.5.2 release jars give the same failure |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the test only parses a string; the platform cannot change the result) |
# the command above, main 645d4fe14a20, seed DEADBEEF, -ea (-da identical); banner and NOTE lines left out, ... = remaining runner frames
[Fatal Error] :6:3: Element type "filter" must be followed by either attribute specifications, ">" or "/>".
There was 1 failure:
1) testExampleIsWellFormedXml(org.apache.lucene.analysis.core.TestStopFilterFactoryJavadocExample)
java.lang.AssertionError: expected well-formed XML, but: Element type "filter" must be followed by either attribute specifications, ">" or "/>".
	at __randomizedtesting.SeedInfo.seed([DEADBEEF:3AF316B5A8EAB8DD]:0)
	at org.apache.lucene.analysis.core.TestStopFilterFactoryJavadocExample.testExampleIsWellFormedXml(TestStopFilterFactoryJavadocExample.java:45)
	...
Caused by: org.xml.sax.SAXParseException; lineNumber: 6; columnNumber: 3; Element type "filter" must be followed by either attribute specifications, ">" or "/>".
	...
FAILURES!!!
Tests run: 1,  Failures: 1

# standalone on main (-ea, -da) and on the 10.5.2 release jars (-ea, -da): the same failure- The blocks are offered as configuration ("Factory for {@link StopFilter}." then the XML) and maintained as XML: #15573 marked all of them
language-xmlin 2026. - The
StopFilterFactoryexample was correct in all 24 4.x releases; a 2013 cleanup removed its closing/>. - SOLR-6000 and LUCENE-8523 fixed the same wrong-class-name slip in
PatternCaptureGroupFilterFactoryandJapaneseNumberFilterFactory.
The full argument180 words
- Offered as configuration.
StopFilterFactory.java:27-29reads "Factory for {@link StopFilter}." and then the block, with no "schematic" marker;DropIfFlaggedFilterFactory.java:30says "In Solr this might be configured such as". No package doc, CHANGES or MIGRATE entry calls the snippets schematic. - Maintained as live XML. #15573 (Dawid Weiss, 2026-01-15) marked every block
language-xml. New factories still get one: #16371CaseFoldingFilterFactory(2026-07-31); #16722 extended theThaiTokenizerFactoryexample (2026-09-28). - The convention holds elsewhere. 141 of the 149 example blocks in all factory javadocs are well-formed (6 of the other 8 are this bug, 2 are the synonym factories' intentional placeholder), and 328 of their 332 elements name a registered factory (the 4 that do not are this bug).
- Broken by an unrelated edit. In 4.x the
StopFilterFactoryexample endedwords="stopwords.txt" enablePositionIncrements="true"/>; LUCENE-4963 (Adrien Grand, 2013-05-04, "Completely remove deprecated options in 5.0.") removed the attribute and the/>with it. - Precedent. LUCENE-8523 (Alan Woodward, 2018-10-14) changed
solr.JapaneseNumberFiltertosolr.JapaneseNumberFilterFactory, with the CHANGES entry "Correct typo in JapaneseNumberFilterFactory javadocs"; SOLR-6000 (2014-04-21) fixed the same inPatternCaptureGroupFilterFactory,solr.PatternCaptureGroupTokenFiltertosolr.PatternCaptureGroupFilterFactory, in two commits.
The devil's-advocate check146 words
Strongest case for "not a bug" (the intended-lens and refute reviewers, OpenAI GPT-5.6, and the devil's-advocate verifier): the snippets are Solr-specific illustrations, not input to any Lucene API (AbstractAnalysisFactory documents a constructor / inform / create() lifecycle, and Lucene parses no schema XML); DropIfFlaggedFilterFactory only says Solr "might" be configured so; com.example reads as a placeholder; and open issues #11285, #9013 and #9916 want these snippets removed altogether.
Why it fails: that argues for deleting the snippets, not for keeping broken ones. While they exist, upstream maintains them as XML and has fixed this exact class-name slip before (SOLR-6000, LUCENE-8523). A missing quote or > is not a placeholder. The case holds only for the TokenAnalyzerFilter line (deliberate, now stale) and, weakly, for the <-- other filters --> line. Every verifier and the adjudication called it real; the adjudication rated it a minor documentation defect.
Recommended Fix the eight snippets (validated)
Javadoc only, 8 files, 11 insertions, 13 deletions: add the missing quote, > and />, delete the stray />, write <!-- other filters -->, name solr.LimitTokenOffsetFilterFactory and solr.PatternTypingFilterFactory, drop the never-shipped TokenAnalyzerFilter line and reword PatternTypingFilterFactory's first sentence. Validated: all eight then parse and name registered factories; the eight factories' 33 tests pass and the javadoc builds.
All options and trade-offs3 options · 606 words
One fix was validated, with the javadoc diff applied to a scratch worktree of 645d4fe14a20; the other options were not run. A maintainer may prefer option B (open issue #11285); option A does not block it.
Javadoc only. Lines are at 645d4fe14a20; -/+ show the javadoc text as it is in the files.
StopFilterFactory.java:34
- *             words="stopwords.txt" format="wordset"
+ *             words="stopwords.txt" format="wordset"/>
JapaneseIterationMarkCharFilterFactory.java:29
- *     <charFilter class="solr.JapaneseIterationMarkCharFilterFactory normalizeKanji="true" normalizeKana="true"/>
+ *     <charFilter class="solr.JapaneseIterationMarkCharFilterFactory" normalizeKanji="true" normalizeKana="true"/>
BeiderMorseFilterFactory.java:37
- *        concat="true" languageSet="auto"
+ *        concat="true" languageSet="auto">
OpenNLPTokenizerFactory.java:34 (and OpenNLPLemmatizerFilterFactory.java:33, name="text_opennlp_lemma")
- * <fieldType name="text_opennlp" class="solr.TextField" positionIncrementGap="100"
+ * <fieldType name="text_opennlp" class="solr.TextField" positionIncrementGap="100">
OpenNLPLemmatizerFilterFactory.java:38
- *     />
DropIfFlaggedFilterFactory.java:35
- *       <-- other filters -->
+ *       <!-- other filters -->
LimitTokenOffsetFilterFactory.java:30
- *     <filter class="solr.LimitTokenOffsetFilter" maxStartOffset="100000" consumeAllTokens="false" />
+ *     <filter class="solr.LimitTokenOffsetFilterFactory" maxStartOffset="100000" consumeAllTokens="false" />
PatternTypingFilterFactory.java:32-34
- * Provides a filter that will analyze tokens with the analyzer from an arbitrary field type. By
- * itself this filter is not very useful. Normally it is combined with a filter that reacts to types
- * or flags.
+ * Factory for {@link PatternTypingFilter}, which sets the type and flags of tokens that match one
+ * of a set of regex patterns. By itself this filter is not very useful. Normally it is combined
+ * with a filter that reacts to types or flags.
PatternTypingFilterFactory.java:40-41
- *     <filter class="com.example.PatternTypingFilter" patternFile="patterns.txt"/>
- *     <filter class="solr.TokenAnalyzerFilter" asType="text_en" preserveType="true"/>
+ *     <filter class="solr.PatternTypingFilterFactory" patternFile="patterns.txt"/>
Trade-offs
None for users: documentation only. Dropping the TokenAnalyzerFilter line leaves a chain that exists in Lucene (PatternTypingFilter then TypeAsSynonymFilter, whose prefix and ignore arguments the example already uses); a placeholder comment there would also do. The new first sentence follows PatternTypingFilter's own javadoc (it sets a type and flags on matching tokens).
What the checks validated
- All nine checked blocks pass. The source check on the patched tree: every block well-formed and every
<charFilter>,<tokenizer>and<filter>names a registered factory, 0 of 9 broken (8 of 9 on the stock tree). A Lucene-side check (XML parse plus SPI lookup), not a run of a real schema loader. - The minimal test passes on the patched text. Its fixed twin, generated mechanically from the patched
StopFilterFactory.java, passes 1 of 1 with the plain command (assertions on and off) and standalone (on and off); the stock test fails the same runs. - The modules' tests and checks.
./gradlewwith the eight factories' own test classes in:lucene:analysis:common,:kuromoji,:phoneticand:opennlp(-Ptests.seed=DEADBEEF): 8 suites, 33 tests, 0 failures.checkGoogleJavaFormatandrenderJavadocpass on the four modules, and on the rendered pages all nine examples (the eight and the control) parse as XML. A javadoc edit cannot change behaviour; these runs show it builds and breaks nothing. - Independent corroboration. The 2026-11-01 refute reviewer (OpenAI GPT-5.6) wrote its own correction test with the same changes: 2 run, 0 failed on
645d4fe14a20.
Replace each Solr XML snippet by a list of parameters, as open issue #11285 (LUCENE-10249) proposes, or remove them, as #9013 (LUCENE-7964) and #9916 (LUCENE-8873) propose.
Trade-offs
A much larger change over about 146 factory files that the project has left open for years. Option A fixes today's text without blocking it.
A small test that extracts every <pre><code class="language-xml"> block from the factory sources, parses it and resolves each solr.<Name> through the SPI would stop this drift; this doc's source check is 84 lines of Python, the hunt's extractor 59.
Trade-offs
Build infrastructure for documentation, and it would encode Solr's naming convention in Lucene's build. Not part of the fix.
Downstream: hosts that read Solr-style XML schemas reject a copied snippet at load time (six fail XML parsing, two name a class that is not a factory); nothing reaches indexing or search.
A sweep extracted all 149 XML examples from factory javadocs (332 elements in 146 files), parsed each, resolved every class through Lucene's SPI and built it with the documented attributes. 141 blocks were well-formed and 328 elements named a registered factory; the failures, read against the source, gave these eight files (the rest: two intentional placeholders and separately tracked bugs).
The method in full112 words
- Sweep. A hunt unit on "analysis-factory javadoc examples and resource files build as documented" extracted every
<pre>schema example from the class javadoc of every*Factory.javain all non-sandbox modules, checked each block for XML well-formedness, resolved each element through the SPI under thesolr.<Name>convention, built it with exactly the documented attributes, gave it a minimal valid resource of the documented format and analyzed a sample (2026-10-28). - Controls. A known broken example (LFV-702, another factory) failed as expected, so the sweep is not vacuous;
LimitTokenPositionFilterFactory's example is the per-test control. - Tier. Semi-formal: an exhaustive check of every example against two exact rules (XML grammar, SPI registration), then a public-API JUnit.
No prior report: 270 queries over GitHub issues and PRs (with the JIRA archive), commits, the mailing lists, downstream repositories and the web (2026-10-28, refreshed 2026-11-01). Open issues #11285, #9013 and #9916 want these snippets removed but report no broken one; no open PR touches the files.
Searches3 searches
Related, not reports: #9534 (LUCENE-8488) wishes for checking javadoc examples in general; #9569 (LUCENE-8523) and SOLR-6000 are the precedents; #14257 (an issue) and #15573 (a PR) concern only the markup; #16949, another contributor's javadoc cleanup of 2026-10-29, touches none of the eight files. Neither tracking issue #16937 nor the dev@ thread on the bug list mentions it.
Limits: keyword search only; GitHub search does not index PR diffs or line-review comments; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| Scripted prior-report search, 2 query sets | 2026-11-01 | 90 + 69 queries (factory and class names, the wrong names, javadoc-example phrasings) over GitHub issues, PRs and commits, downstream repositories, dev@, java-user@, issues@, commits@, the JIRA archive and the web | no report of any of the eight |
| GitHub, JIRA, lists and web, manual | 2026-11-01 | 34 GitHub searches (every solr.<Name>Factory string, "javadoc example" phrasings), 18 JIRA, 30 list and 16 web queries, 13 direct reads (GitHub and JIRA REST, raw files, one list thread); the introducing issues and PRs read | only the cleanup issues and precedents above |
| Upstream state | 2026-11-01 | the eight files on main, branch_11x and branch_10_6; the changed files of all 409 open PRs and of the 30 PRs closed since 2026-10-27 | byte-identical on main f815e679bf6c; no PR changes them |
Eight separate slips written 2011 to 2021: seven were wrong from the start, and StopFilterFactory's broke in 2013 (LUCENE-4963). Two since 4.0.0-BETA, all eight since 8.9.0, through 10.6.0 and main; no release shows one fixed.
Versions tested7 rows
| example | written (author, date) | first release |
|---|---|---|
BeiderMorseFilterFactory | f3869ef3ce4 (Robert Muir, 2011-12-28, SOLR-2982, then a Solr class) | 4.0.0-BETA |
JapaneseIterationMarkCharFilterFactory | a15331043f9 (Christian Moen, 2012-07-10, LUCENE-4201) | 4.0.0-BETA |
StopFilterFactory | broken by fa76c301470 (Adrien Grand, 2013-05-04, LUCENE-4963); reached 5.x by the LUCENE-5944 backport | 5.0.0 |
LimitTokenOffsetFilterFactory | af6fe4d1741 (David Smiley, 2015-04-22, LUCENE-6423) | 5.2.0 |
| both OpenNLP factories | 3e2f9e62d77 (Steve Rowe, 2017-12-15, LUCENE-2899) | 7.3.0 |
DropIfFlaggedFilterFactory | ab5671d367e (Gus Heck, 2020-10-14, LUCENE-9574) | 8.9.0 |
PatternTypingFilterFactory | c087f6f8c0a (Gus Heck, 2021-01-23, LUCENE-9575) | 8.9.0 |
A probe read each example from the release's checksum-verified sources jar, parsed it and resolved its classes through that release's own SPI (15 releases and main executed; all 124 tags of the history clone from 4.0.0-alpha to 10.6.0 re-scanned). The LimitTokenCount/LimitTokenPosition controls pass in every run in which they exist (LimitTokenPosition from 4.3.0; 4.0.0-ALPHA has neither), and the StopFilterFactory row flips from OK to broken between 4.10.4 and 5.0.0.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; upstream main f815e679bf6c | affected | all eight (upstream read, not run: byte-identical) |
| 8.9.0 to 10.6.0 | affected | all eight (8.9.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2, 10.6.0 run) |
| 7.3.0 to 8.8.2 | six | six; DropIfFlagged and PatternTyping do not exist yet (7.3.0, 8.8.2 run) |
| 5.2.0 to 7.2.1 | four | Stop, LimitTokenOffset, JapaneseIterationMark, BeiderMorse (5.2.0, 7.2.1 run) |
| 5.0.0 to 5.1.0 | three | Stop, JapaneseIterationMark, BeiderMorse (both run) |
| 4.0.0-BETA to 4.10.4 | two | JapaneseIterationMark, BeiderMorse; the Stop example is well-formed (4.0.0-BETA, 4.10.4 run) |
| 4.0.0-ALPHA | no factories | not affected: no analysis factory SPI yet |
A finder, an independent reproducer, reviews from another model family (OpenAI GPT-5.6: two that could only read the code, one that executed its own test), a devil's-advocate check, an adjudication, an audit and a 2026-11-01 re-check. Every check that ran code reproduced it; the adjudication confirmed it, high confidence, as a minor documentation defect.
Checks and verdicts239 words
The first refute review (2026-10-28) could not run code; it voted not real (medium confidence), since it reproduced nothing and read the snippets as illustrations rather than input to a Lucene API; the 2026-11-01 refute review executed and found it real.
| Check | Verdict | What it found |
|---|---|---|
| Finder | reproduced (doc) | Example sweep, then a 10-test JUnit: 9 of 10 fail on main (-ea, -da), 10.5.2 and 9.12.3; the control passes. |
| Reproducer | real (doc) | Own 11-test JUnit: 9 fail on main, 10.5.2 and 9.12.3; controls pass; one-token fixes make each snippet parse and resolve. |
| Intended lens (OpenAI GPT-5.6) | real, medium | Reading only (the reviewer ran nothing): the "illustration" case holds only for the TokenAnalyzerFilter line. A separate second-parser check (Python minidom) confirmed the six malformed blocks. |
| Devil's advocate | real (doc) | #11285 does not excuse broken snippets; found the LUCENE-8523 precedent; corrected the Stop origin. |
| Adjudication and audit | confirmed (high), minor | Re-ran the independent reproduction's test (9 of 11 fail, controls pass) and read all eight defects in the source. |
| Refute lens, executed (OpenAI GPT-5.6) | real, high | Own source-driven test: 9 run, 8 fail on main (-ea and -da, two seeds) and on 645d4fe14a20; its correction test passes 2 of 2. |
| Re-check and brief | real, not fixed; fix validated | Minimal test fails on main and 10.5.2 (-ea, -da); source check 8 of 9 broken; the patched javadoc passes both. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 409 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,471 words
- Registry title
- Eight analysis-factory class javadoc schema examples cannot be used as written: six are not well-formed XML (StopFilterFactory, JapaneseIterationMarkCharFilterFactory, BeiderMorseFilterFactory, OpenNLPTokenizerFactory, OpenNLPLemmatizerFilterFactory, DropIfFlaggedFilterFactory) and two name a class that is not a factory (LimitTokenOffsetFilterFactory's solr.LimitTokenOffsetFilter, PatternTypingFilterFactory's com.example.PatternTypingFilter) (documentation defect)
- Area
- analysis-common, analysis-kuromoji, analysis-phonetic, analysis-opennlp / analysis factories (class javadoc <fieldType> schema examples)
- Priority
- Low, rank 1268: Eight broken schema snippets fail loudly and only when pasted into an XML schema, with no runtime effect.
- Impact class
- minor
- Impact note
- Documentation only, nothing changes at runtime: a reader who copies one of these eight class-javadoc snippets into a Solr-style XML schema gets an XML parse error (six snippets) or a class that does not resolve to any factory (LimitTokenOffset, PatternTyping) at once, when the schema loads; users of the Lucene API (the Map constructor, SPI names, CustomAnalyzer) are not misled, because every factory argument in the eight snippets (each attribute other than class, the never-committed TokenAnalyzerFilter line aside) is one its factory reads; all eight are in every release since 8.9.0 and two since 4.0.0-BETA, and no scale is needed.
- Summary
- You copy the <fieldType> example from the class javadoc of one of eight analysis factories (StopFilterFactory, for example) into a schema and expect well-formed XML whose elements name registered factories, as the other factory examples do (141 of the 149 example blocks are well-formed; 328 of the 332 elements name a registered factory). Instead six snippets are not well-formed XML (a class attribute with no closing quote after the class name, start tags with no '>' or '/>', a stray '/>' line, and '<-- other filters -->' instead of an XML comment), and two name a class that is not a factory: LimitTokenOffsetFilterFactory's example says solr.LimitTokenOffsetFilter (the filter, not its factory) and PatternTypingFilterFactory's own element says com.example.PatternTypingFilter. The PatternTyping example also lists solr.TokenAnalyzerFilter, a companion filter from a Solr patch that was never committed (a stale reference, not a typo), and its first javadoc sentence describes that companion filter rather than PatternTypingFilter.
- Introduced
- No single commit: eight independent hand-written examples, seven wrong from the commit that first wrote them and one (StopFilterFactory) broken by a later edit [read: git log -S / -L on each defect line in the full-history clone, and the bodies and comments of the introducing issues; release brackets executed with a history probe that reads each release's sources jar]. Per row: BeiderMorseFilterFactory f3869ef3ce4 (SOLR-2982, rmuir, then a Solr class; moved into Lucene by LUCENE-2510/LUCENE-4044); JapaneseIterationMarkCharFilterFactory a15331043f9 (LUCENE-4201 = #5273, Christian Moen); StopFilterFactory fa76c301470 (LUCENE-4963 = #6027, jpountz: removing the deprecated enablePositionIncrements attribute also dropped the '/>' that closed the tag; LUCENE-5211 499bd3688a3 later appended format="wordset" to the still-open tag); LimitTokenOffsetFilterFactory af6fe4d1741 (LUCENE-6423 = #7482, dsmiley); OpenNLPTokenizerFactory and OpenNLPLemmatizerFilterFactory 3e2f9e62d77 (LUCENE-2899 = #3973, sarowe); DropIfFlaggedFilterFactory ab5671d367e (LUCENE-9574 = #10614, PR apache/lucene-solr#1979, gus-asf); PatternTypingFilterFactory c087f6f8c0a (LUCENE-9575 = #10615, PR apache/lucene-solr#1995, gus-asf). (2011-12-28 (oldest row, BeiderMorse, as Solr code) to 2021-01-23 (newest row, PatternTyping); per row (author dates): BeiderMorse 2011-12-28, JapaneseIterationMark 2012-07-10, Stop 2013-05-04, LimitTokenOffset 2015-04-22, both OpenNLP 2017-12-15, DropIfFlagged 2020-10-14, PatternTyping 2021-01-23)
- First affected version
- 4.0.0-BETA [exec] (JapaneseIterationMarkCharFilterFactory and BeiderMorseFilterFactory; first GA 4.0.0; 4.0.0-ALPHA has no Lucene analysis factories at all). Per row: StopFilterFactory 5.0.0 (all 24 releases 4.0.0-BETA..4.10.4 are well-formed), LimitTokenOffsetFilterFactory 5.2.0, both OpenNLP factories 7.3.0, PatternTypingFilterFactory and DropIfFlaggedFilterFactory 8.9.0 (8.x backports apache/lucene-solr#2493 and #2483); all eight together from 8.9.0 [exec]
- Affected versions
- Every release from 4.0.0-BETA through 10.6.0 (132 releases) has at least two of the broken examples and every release from 8.9.0 on has all eight (8.9.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.6.0), and so do branch_10x head 1309534296e and main a9779ef3c193. [exec] with the follow-up history probe, which reads the example text from each release's SHA-1-checked sources jar and resolves class names against that release's jars: 4.0.0-BETA, 4.0.0, 4.10.4, 5.0.0, 5.1.0, 5.2.0, 7.2.1, 7.3.0, 8.8.2, 8.9.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and main (-ea and -da), and 10.6.0 (2026-11-01, -da); 4.0.0-ALPHA is not affected (no API). [read] all 140 release tags checked (131 in the history clone, 3.1 to 10.5.2, plus 8.8.2-8.11.4 from the lucene-solr repository) and both branch heads. The finder's JUnit fails 9 of 10 on main, 10.5.2 and 9.12.3, but it hard-codes the snippets, so on release jars it re-tests only the two class-name rows; the release dating rests on the history probe. Not fixed: upstream main 645d4fe14a20 (2026-10-28) has not touched the eight files since a9779ef3c193 [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-28): a scripted prior-report search in two query sets plus manual searches, 175 queries over apache/lucene issues and PRs (including the migrated JIRA archive), commits, apache/solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; bodies and comments of the introducing issues and PRs read (#5273, #6027, #7482, #3973, #6275, #10614, #10615, lucene-solr#1979 and #1995); the changed files of the open apache/lucene PRs updated since 2026-10-26 (71 checked; only #16911, which deletes the whole branch_10x tree, includes the files); all items by an active javadoc contributor (hidingmyname), none touching an analysis-factory example. No issue, PR, review comment or list post reports any of the eight broken examples. Related, not this bug: open cleanup issues #11285 (LUCENE-10249), #9013 (LUCENE-7964, with the 2017 dev@ thread) and #9916 (LUCENE-8873) propose removing or replacing all Solr XML snippets in factory javadocs and report no malformed or wrong snippet; precedents for the same kind of defect in other factories, fixed quickly: #9569 (LUCENE-8523, JapaneseNumberFilterFactory) and SOLR-6000 (PatternCaptureGroupFilterFactory); SOLR-14597 (never committed) is the origin of solr.TokenAnalyzerFilter. Refresh 2026-10-28: apache/lucene issues and PRs updated since a recent cutoff (5, unrelated), the 25 newest open PRs (#16929 and #16930 checked file by file; none touches the eight files), searches for each factory name, TokenAnalyzerFilter, 'fieldType javadoc' and 'javadoc example factory' updated since 2026-10-27 (no hits), and upstream commits touching the eight files since 2026-10-01 by author date (none; main head 645d4fe14a20). Gaps: keyword search only; GitHub search does not index PR diffs or line-review comments; private reports are not visible.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off (standalone and a plainjavac/javacommand), and on the 10.5.2 release jars; a source check of all eight blocks and theLimitTokenPositionFilterFactorycontrol (XML parse plus a lookup of every class name in the SPI service files) finds 8 of 9 broken. The fix was applied to a scratch worktree of645d4fe14a20: the source check finds 0 of 9 broken, the minimal test's fixed twin passes, and./gradlewruns of the eight factories' own test classes (8 suites, 33 tests, 0 failures),checkGoogleJavaFormatandrenderJavadocon the four modules pass, and every example on the rendered pages parses. Release dating (4.0.0-BETA to 10.6.0) comes from a probe that reads each release's sources jar. Upstream mainf815e679bf6c(2026-11-01) was read, not run: the eight files are byte-identical.
- Finding record
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LimitTokenOffsetFilterFactory.java:26-32 (example; :30 class="solr.LimitTokenOffsetFilter"); lucene/analysis/common/src/java/org/apache/lucene/analysis/pattern/PatternTypingFilterFactory.java:31-45 (first sentence :32; example :36-45; :40 com.example.PatternTypingFilter; :41 solr.TokenAnalyzerFilter); lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseIterationMarkCharFilterFactory.java:26-32 (:29 class attribute without closing quote); lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:29-36 (:33-34 filter start tag never closed); lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/BeiderMorseFilterFactory.java:31-40 (:35-38 no '>' before </filter>); lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPTokenizerFactory.java:33-38 (:34 fieldType start tag without '>'); lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPLemmatizerFilterFactory.java:32-43 (:33 fieldType start tag without '>', :38 stray '/>'); lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DropIfFlaggedFilterFactory.java:32-38 (:35 '<-- other filters -->'); all eight files identical in Lucene main ea57360912ed
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:26-36a Lucene main checkout (645d4fe14a20) lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseIterationMarkCharFilterFactory.java:26-32a Lucene main checkout (645d4fe14a20) lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/BeiderMorseFilterFactory.java:31-40a Lucene main checkout (645d4fe14a20) lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPTokenizerFactory.java:33-38a Lucene main checkout (645d4fe14a20) lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPLemmatizerFilterFactory.java:32-43a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DropIfFlaggedFilterFactory.java:30-38a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LimitTokenOffsetFilterFactory.java:26-32, :39a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/pattern/PatternTypingFilterFactory.java:31-45a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LimitTokenPositionFilterFactory.java:26-32 (control)a Lucene main checkout (645d4fe14a20): grep for TokenAnalyzerFilter over lucene/analysis and lucene/core/src (only PatternTypingFilterFactory.java:41)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:27-29a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DropIfFlaggedFilterFactory.java:30a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:45-52 (lifecycle)a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:7120 (LUCENE-8523 entry)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/pattern/PatternTypingFilter.java:31-41, :66-67 (sets type and flags); a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TypeAsSynonymFilterFactory.java:59-60 (prefix, ignore)
- TestStopFilterFactoryJavadocExample.java (one test, public API):
repro/LFV-931/src/org/apache/lucene/analysis/core/TestStopFilterFactoryJavadocExample.java(48 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-931/bug.png(409 KB)