WordStorage gives the table one slot per entry and puts each word in slot |String.hashCode() % size|, at most 20 words per slot. String.hashCode() is h = 31*h + c, so when the size is a multiple of 961 = 31 x 31, short words that end in the same two letters crowd into a few slots.
- A Hunspell dictionary is an
.affrules file plus one or more.dicword lists. At load time Lucene'sDictionaryreads all the lists into one in-memory hash table,WordStorage. - The table gets one slot per entry: the entry count times
hashFactor, default 1.0. Lucene adds hidden title-case entries for some words, and they count too. A word goes to slot|String.hashCode() % size|; words that share a slot form a chain. - A chain may hold at most 20 words; the 21st throws
Too many collisions. The limit was meant for rare bad luck, and the message asks users to report it.
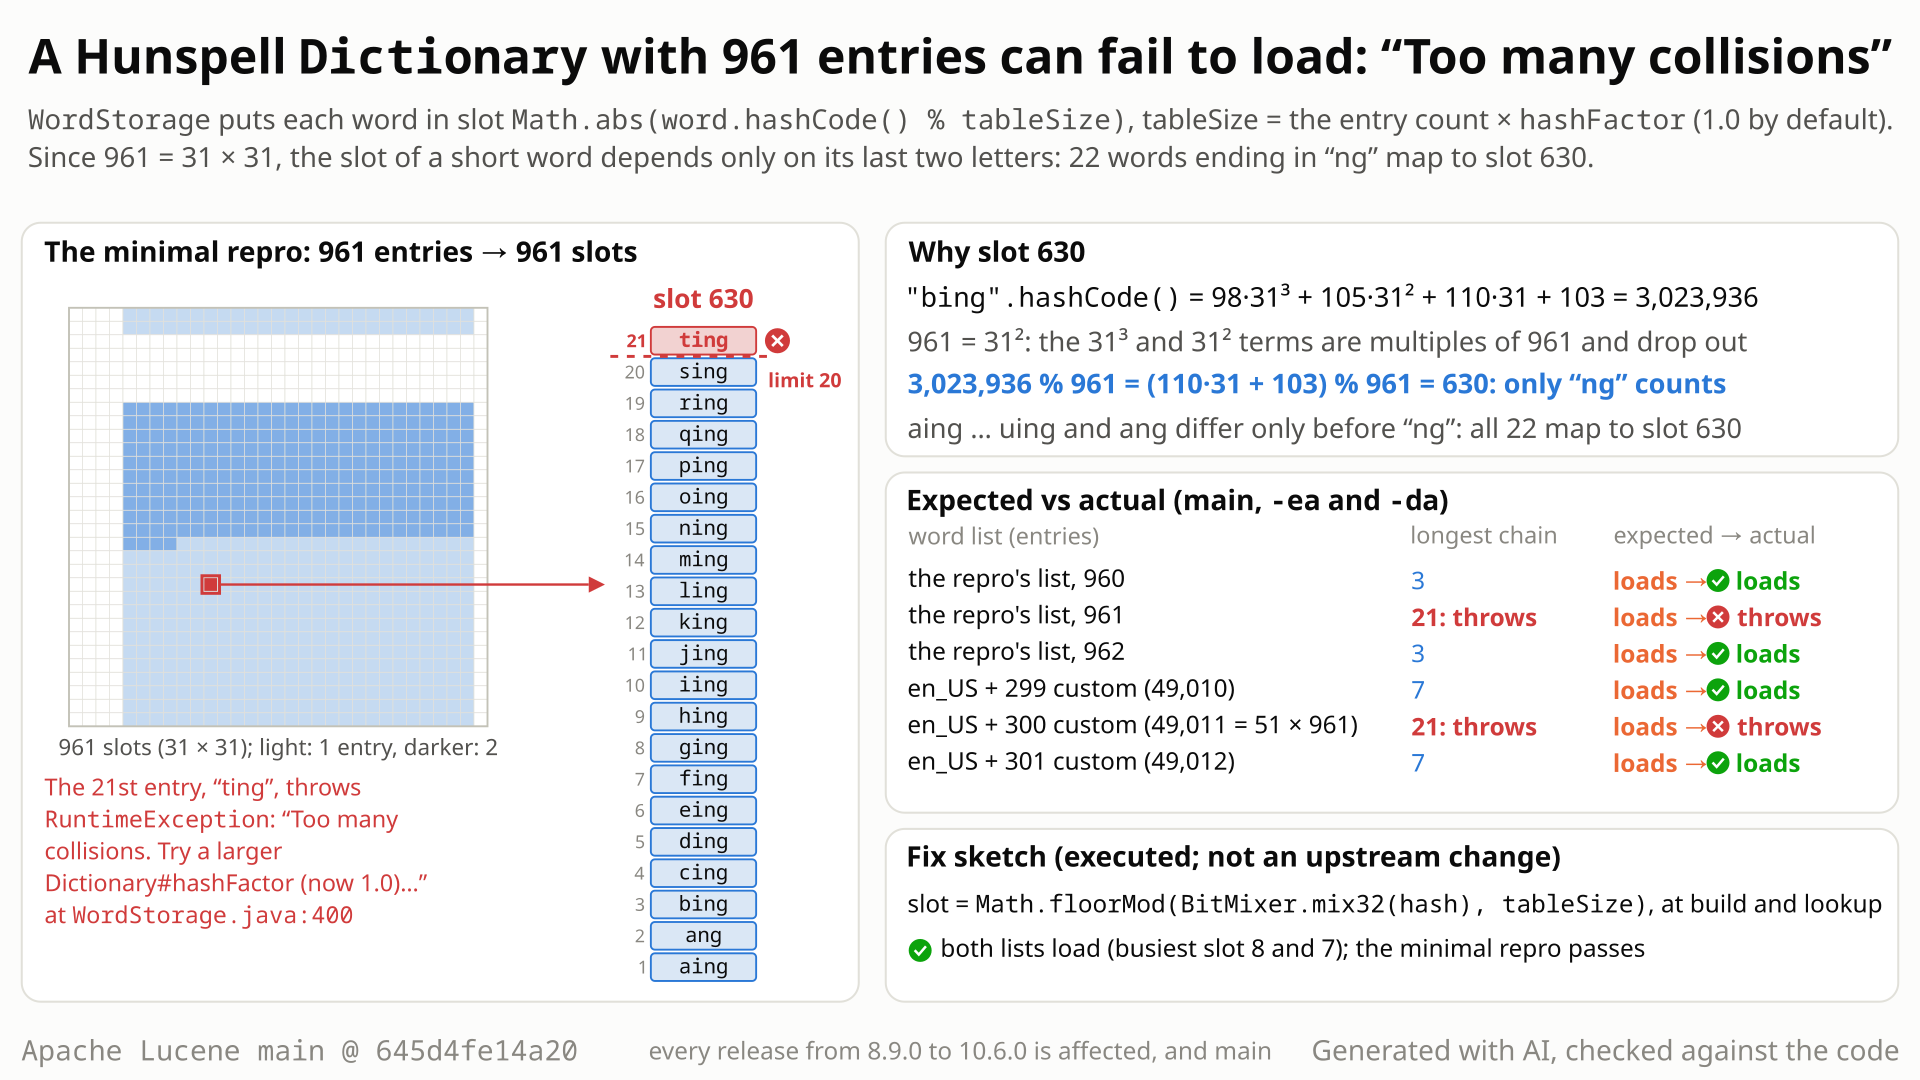
ang share slot 630, past the limit of 20. Select the still to open it at full size. Generated with AI, checked against the code.- Load the stock en_US Hunspell dictionary (48,711 entries in Lucene) plus a custom list of 300 words, for example with
HunspellStemFilterFactoryanddictionary="en_US.dic,custom.dic", the pattern its javadoc shows. That is 49,011 entries. - You expect it to load, as it does with 299 or 301 custom words.
- Instead it throws
RuntimeException: Too many collisions. Try a larger Dictionary#hashFactor (now 1.0). The word table has one slot per entry, 49,011 slots, and a slot may hold at most 20 words. - Why: a word goes to slot
hashCode() % 49,011, and 49,011 = 51 x 961 = 51 x 31 x 31.String.hashCode()ish = 31*h + c, so six-letter words ending in "er" can use only 51 of the slots, and one gets 22 (archer, buzzer, career, ...). - Minimal test: 961 plain words,
aaatobkdplusaingtouing. The 21 "-ing" words andangall land in slot 630 and loading fails; with 960 or 962 words the busiest slot holds 3.
Users of Lucene's opt-in Hunspell support (Dictionary, Hunspell, HunspellStemFilter, HunspellStemFilterFactory) with default settings, on every release since 8.9.0, whose word lists hit an unlucky total and hold many short words with a common ending, such as en_US plus 300, 1,261 or 10,871 custom words. Factory users cannot change hashFactor; adding or removing one word avoids it.
Mechanism, terms and numbers700 words
WordStorage, the hash table that holds a Hunspell Dictionary's words since 8.9.0, has one slot per entry (WordStorage.java:294: (int) (wordCount * hashFactor), default factor 1.0) and puts each word into slot Math.abs(String.hashCode() % tableSize) (build :390, lookup :109, on main 645d4fe14a20). A slot may hold at most 20 entries; the 21st throws RuntimeException: Too many collisions. Try a larger Dictionary#hashFactor (now 1.0). If this doesn't help, please report this to dev@lucene.apache.org (:399-404). String.hashCode() is the polynomial h = 31*h + c, so when the table size is a multiple of 961 = 31 x 31, every letter except the last two adds a multiple of 961: short words that share their last two letters crowd into a few slots.
A test dictionary of 961 plain words fails to load while 960 or 962 words load. In real use, the stock en_US dictionary (48,711 entries, hidden title-case entries included) plus a custom list of 300 words (49,011 = 51 x 961) fails: one slot gets 22 words, 21 of them six-letter "-er" words. Every release from 8.9.0 to 10.6.0 and main is affected; adding or removing one word avoids it.
- Entry count.
Dictionary.mergeDictionariesreads every.dicstream, skips its first line ("number of entries (approximately, sometimes)",Dictionary.java:1016) and passes each word line towriteNormalizedWordEntry(:1034), which adds one entry (:1060), plus a hidden title-case entry for mixed-case words and flagged upper-case words (:1062-1064,:1068-1079). The offline sorter counts every entry (SortingStrategy.java:74-78,:91-92), andreadSortedDictionariespasses that count andhashFactor()toWordStorage.Builder(Dictionary.java:1102-1104). - Table size.
hashTable = new int[(int) (wordCount * hashFactor)](WordStorage.java:294).hashFactor()is protected and returns 1.0; its javadoc: "If there are too many hash collisions, the factor can be increased, resulting in faster access, but more memory usage" (Dictionary.java:1160-1168). - Slot. Build:
int hash = Math.abs(currentEntry.hashCode() % hashTable.length)(WordStorage.java:390). Lookup:Math.abs(CharsRef.stringHashCode(word, offset, length) % hashTable.length)(:109), the same polynomialresult = 31 * result + chars[i](CharsRef.java:86-93). No bit mixing. - Limit.
if (++chainLengths[hash] > 20)throws theRuntimeException(WordStorage.java:399-404).HunspellStemFilterFactorycatches onlyParseException(:115), so it escapesinform()unwrapped.
- For a lowercase ASCII word of up to 5 letters the sum does not overflow, and every term except the last two is a multiple of 31^2 = 961, so
hash % 961 = (31*c[n-2] + c[n-1]) % 961: only the last two letters matter. - Every 6-letter lowercase word wraps exactly once (its sum lies in [2^31, 2^32)), so its residue also depends only on the last two letters (a different residue class than the shorter words).
- With a table of m x 961 slots,
slot % 961 = |hash % 961|(Math.absturns the negative remainder of a wrapped hash positive), so the words of one such group can use only m of the slots. With exactly 961 slots, one slot. - Minimal test: 961 slots;
aingtouingandangall have residue 630 (31 x 'n' + 'g' = 3,513 = 3 x 961 + 630), so slot 630 gets 22 entries. With 960 or 962 entries the busiest slot holds 3 (a slot count outside Lucene). - en_US + 300 words: 49,011 = 51 x 961 slots; the six-letter "-er" words share 51 slots and the busiest gets 22 (Kepler, Walter, Xavier, archer, buzzer, career, ... and one longer word). At 49,010 or 49,012 entries the busiest slot holds 7.
- Multiples of 31^3 are worse: en_US + 10,871 words gives 59,582 = 2 x 31^3 slots, and one slot gets 61 six-letter words ending in "ter" (Finder, Master, Potter, ...); at 1.5x, 2x and 3x that size (3, 4 and 6 x 31^3) the busiest slot still holds 47, 32 and 26.
- Modulo 31 for small lists: short words that share their last letter can use only m of m x 31 slots. 31 entries (21 two-letter words
batovaplus 10 others) throw; 30 and 32 load. For real-size dictionaries the multiples of 961 are what matter.
Exposure and likelihood346 words
- What goes wrong. The dictionary, and the stemmer, analyzer or spell checker built on it, cannot be created at all: a loud, deterministic failure at load, the same with assertions on and off. Nothing is silently wrong and no index is touched.
- What it takes. For real-size dictionaries the total entry count, hidden title-case entries and duplicate lines included, must be a multiple of 961 (about one list size in 961; for a small list a multiple of 31 can be enough, like the 124 = 4 x 31-entry test dictionary that found it). The content must also put more than 20 short words with a common ending into one slot group: in the finder's survey only en_US crosses the limit at multiples of 961 (3 of 3 sizes); nb_NO stays at 13 or below and sv_SE at 10.
- Executed real cases (three independent custom-word generators). Through the plain constructor, en_US plus 300, 1,261, 2,222, 3,183, 6,066, 9,910 or 10,871 custom words fails; 11 other list sizes load and spell-check. Through
HunspellStemFilterFactorywithdictionary="en_US.dic,custom.dic": 300, 1,261 and 10,871 fail; 299, 301, 1,260, 1,262 and 10,870 load. A model predicts 13 failing sizes among the 18 multiples of 961 from 51 x 961 to 68 x 961 (custom lists of 300 to about 16,600 words; model only beyond the 7 executed). - The advised remedy is not always available or enough.
hashFactor()is protected (aDictionarysubclass is needed) andHunspellStemFilterFactorycannot set it (HunspellStemFilterFactory.java:111). An integer factor keeps the size a multiple of 961; at en_US + 10,871 words the factors 1.5, 2.0 and 3.0 still throw, which is exactly when the message asks for a report. At en_US + 300 words, 1.5, 2.0, 3.0 and 4.0 load. - Workarounds. Add or remove one word. Direct-API users can subclass
Dictionaryand return a factor that makes the table size not divisible by 31, such as 1.1 (en_US + 10,871 words: 65,540 slots, loads); no fixed factor does that for every count. - How likely: rare. No public report was found in the five years since 8.9.0.
One JUnit test on the public Dictionary constructor: an .aff with only SET UTF-8 and a .dic of 961 plain words (940 three-letter words plus aing to uing), default hashFactor. Deterministic, single thread; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import static java.nio.charset.StandardCharsets.UTF_8;

import java.io.ByteArrayInputStream;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDictionary961Entries extends LuceneTestCase {

  public void testDictionaryWith961WordsLoads() throws Exception {
    StringBuilder dic = new StringBuilder("961\n");
    for (int i = 0; i < 940; i++) {
      dic.append((char) ('a' + i / 676))
          .append((char) ('a' + i / 26 % 26))
          .append((char) ('a' + i % 26))
          .append('\n');
    }
    for (char c = 'a'; c <= 'u'; c++) {
      dic.append(c).append("ing\n");
    }
    try {
      new Dictionary(
          new ByteBuffersDirectory(),
          "dict",
          new ByteArrayInputStream("SET UTF-8\n".getBytes(UTF_8)),
          new ByteArrayInputStream(dic.toString().getBytes(UTF_8)));
    } catch (RuntimeException e) {
      // expected: 940 three-letter words plus 21 "-ing" words load; actual: "Too many collisions"
      throw new AssertionError("expected the 961-word dictionary to load, but: " + e, e);
    }
  }
}
cp $REPRO/TestDictionary961Entries.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.hunspell.TestDictionary961Entries -Ptests.seed=DEADBEEF
- Expected
- The 961-word dictionary loads, as the same list with 960 or 962 words does.
- Observed
- The
Dictionaryconstructor throwsRuntimeException: Too many collisions. Try a larger Dictionary#hashFactor (now 1.0).
More files, environment, full output280 words
Copy the test into lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/ of a Lucene checkout and run it with gradle (command below). It uses only the public constructor; it sits in the hunspell package because the upstream hunspell tests do. With the mixed-hash fix it passes unchanged, so it doubles as the regression test.
Executed: gradle in a fresh scratch worktree of 645d4fe14a20 (fails with seed DEADBEEF, which picks assertions off, and with seed 933B0301 and -Ptests.asserts=true); the standalone runner on the stock main jars with -ea and -da, and on the release jars 8.0.0 to 10.6.0 (fails from 8.9.0 on, passes before).
Left out on purpose: the real en_US case, which needs an external dictionary file. Its executed numbers are under "Who is affected".
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on every release from 8.9.0 to 10.6.0 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestDictionary961Entries.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.hunspell.TestDictionary961Entries -Ptests.seed=DEADBEEF
# gradle, main 645d4fe14a20, -Ptests.seed=933B0301 -Ptests.asserts=true
TestDictionary961Entries > testDictionaryWith961WordsLoads FAILED
    java.lang.AssertionError: expected the 961-word dictionary to load, but: java.lang.RuntimeException: Too many collisions. Try a larger Dictionary#hashFactor (now 1.0). If this doesn't help, please report this to dev@lucene.apache.org
        at org.apache.lucene.analysis.hunspell.TestDictionary961Entries.testDictionaryWith961WordsLoads(TestDictionary961Entries.java:46)

        Caused by:
        java.lang.RuntimeException: Too many collisions. Try a larger Dictionary#hashFactor (now 1.0). If this doesn't help, please report this to dev@lucene.apache.org
            at org.apache.lucene.analysis.hunspell.WordStorage$Builder.flushGroup(WordStorage.java:400)
            at org.apache.lucene.analysis.hunspell.WordStorage$Builder.add(WordStorage.java:325)
            at org.apache.lucene.analysis.hunspell.Dictionary.readSortedDictionaries(Dictionary.java:1149)
            at org.apache.lucene.analysis.hunspell.Dictionary.<init>(Dictionary.java:270)
            at org.apache.lucene.analysis.hunspell.Dictionary.<init>(Dictionary.java:213)
            at org.apache.lucene.analysis.hunspell.Dictionary.<init>(Dictionary.java:192)
            at org.apache.lucene.analysis.hunspell.TestDictionary961Entries.testDictionaryWith961WordsLoads(TestDictionary961Entries.java:43)

# standalone runner, seed DEADBEEF
main 645d4fe14a20  -ea / -da   tests_run=1 failures=1   same message
10.6.0             -da         tests_run=1 failures=1   same message
10.5.2             -ea / -da   tests_run=1 failures=1   same message
8.9.0              -da         tests_run=1 failures=1   "Too many collisions, please report this to dev@lucene.apache.org"
8.8.2 -da tests_run=1 failures=0- The constructors document only
IOExceptionandParseException; thehashFactor()javadoc treats collisions as a speed/memory trade-off, not a load failure. - The message asks for a report; in the 2021 review the author planned to answer one with "raise this limit, or rehash automatically".
- 960 and 962 entries load, 961 fails: the table size causes it, not bad luck.
The full argument242 words
- Contract. The public constructors list only
@throws IOException Can be thrown while reading from the InputStreamsand@throws ParseException Can be thrown if the content of the files does not meet expected formats(Dictionary.java:186-187,:203-204,:223-224).Dictionaryis not marked@lucene.experimental. No javadoc, package doc,MIGRATE.mdentry or test documents a size or content limit; the analysis-common tests never mentionhashFactor, "Too many collisions" or the chain length. - History. In the LUCENE-9825 review (apache/lucene-solr#2459), Michael McCandless asked whether exceeding the cap was "statistically a small but non-trivial possibility". The author, Peter Gromov, answered: "Yes, it's a nontrivial possibility. I thought following the pattern
please report this to dev@lucene.apache.orgwould be enough (in which case we could either raise this limit, or rehash automatically, or suggest to alter the dictionary if it's wrong). Do you think we should be more proactive here?" (2021-03-08), and Michael McCandless replied "I think this exception and it's message is great -- no need to be more proactive" (2021-03-09). On #12464, which addedhashFactor, Dawid Weiss wrote: "Most people will use it out of the box and we can then count on their feedback if something is not right" (2023-07-27). Neither review discusses the table-size effect; CHANGES lists #12464 under 9.8.0 "Improvements". - Effect. 960 and 962 entries load, 961 does not; a stock dictionary plus 300 words fails, 299 or 301 load. The cause is structural, not an unlucky random collision.
The devil's-advocate check163 words
The strongest case for "works as designed" (the cross-model reviewer rated it moderate): the 20-entry cap is a deliberate safety limit that the reviewers endorsed ("+1 to keep this safety", "no need to be more proactive"), the message names the remedy (hashFactor), HunspellStemFilterFactory is @lucene.experimental, and a throws list need not be exhaustive.
Why it fails: the reviewers accepted the cap as a detector for presumed-random collisions plus a reporting channel, and the author's planned answer to a report on a dictionary that is not wrong was a code change ("raise this limit, or rehash automatically"). Here the input is a stock dictionary plus plain words and the cause is deterministic. The remedy cannot be reached from the factory and is not reliable (1.5, 2.0 and 3.0 fail at en_US + 10,871 words). Dictionary itself is not experimental, and "experimental" waives API compatibility, not loading valid data. The devil's advocate, the adjudication and two tie-breaks each rejected the works-as-designed case.
Recommended Mix the hash before the modulo (recommended)
Mix the hash before taking the slot: a private slot() helper returns Math.floorMod(BitMixer.mix32(hash), tableSize) at both the build and the lookup site (+12/-2 lines). The minimal test, the format check and all hunspell tests pass; en_US loads for every list size tried. No format change: the table is rebuilt at every load.
import org.apache.lucene.internal.hppc.BitMixer;

  private static int slot(int stringHash, int tableSize) {
    return Math.floorMod(BitMixer.mix32(stringHash), tableSize);
  }

  // lookupWord (:109)
  int hash = slot(CharsRef.stringHashCode(word, offset, length), hashTable.length);
  // Builder.flushGroup (:390)
  int hash = slot(currentEntry.hashCode(), hashTable.length);
All options and trade-offs3 options · 542 words
Three options. The mixed hash was validated with gradle in a scratch worktree at 645d4fe14a20; the other two were not executed. Whatever the choice, the build and lookup slot computations must stay identical.
In WordStorage, add a private static slot(int stringHash, int tableSize) that returns Math.floorMod(BitMixer.mix32(stringHash), tableSize) and use it in lookupWord (:109) and in Builder.flushGroup (:390). BitMixer is org.apache.lucene.internal.hppc.BitMixer from core. Same logic as the study's fix, re-formatted for google-java-format.
import org.apache.lucene.internal.hppc.BitMixer;

  private static int slot(int stringHash, int tableSize) {
    return Math.floorMod(BitMixer.mix32(stringHash), tableSize);
  }

  // lookupWord (:109)
  int hash = slot(CharsRef.stringHashCode(word, offset, length), hashTable.length);
  // Builder.flushGroup (:390)
  int hash = slot(currentEntry.hashCode(), hashTable.length);
Trade-offs
- A few integer operations per lookup (
mix32: two multiplies, three xor-shifts); no benchmark was run. - No format change:
WordStorageis in memory only and rebuilt at every load. org.apache.lucene.internal.hppcis exported by core "temporarily" to all modules (module-info.java:55-57);WordStoragealready importsIntArrayListfrom it. A committer may prefer a local mixer.- Word enumeration (
processAllWords,WordStorage.java:178) walks the table in slot order, so that order changes; suggestion ranking breaks ties by the word itself (GeneratingSuggester.java:103-106,:450-452). - The 20-entry cap stays. The mixed hash removes the radix-31 / table-size correlation shown here; it is still a fixed hash, so other inputs can still collide, but in the recorded survey the longest chain was at most 10 for every dictionary and size tried. That fits what the 2021 review intended the cap for.
What the checks validated
- Gradle, fresh scratch worktree at
645d4fe14a20+ the fix (its javadoc corrected after the cross-model fact check, code unchanged),-Ptests.seed=933B0402 -Ptests.asserts=true::lucene:analysis:common:checkGoogleJavaFormatpasses; the hunspell test package, the minimal test included, passes: 159 tests in 47 suites (146 run, 13 skipped), 0 failures, 0 errors. The skipped suites (TestAllDictionaries,TestPerformance,TestHunspellRepositoryTestCases) need external dictionaries. The unpatched checkout fails the minimal test in the same worktree. The previous wording of the diff gave the same counts (seeds 933B0302 and DEADBEEF, and in the fact checks). - Shadowed on the stock main jars: the minimal test passes with
-eaand-da; en_US plus k custom words loads and spell-checks for every k tried (0, 299, 300, 301, 1,261, 2,222, 3,183, 6,066, 9,910, 10,871). - Earlier runs of the study's equivalent fix: the finder's 7 tests, the independent reproducer's 11 and Lucene's 146 hunspell tests pass; the real-dictionary survey's longest chain is at most 10 for every size tried.
Bump (int) (wordCount * hashFactor) until it is not a multiple of 31 (or use a prime size).
Trade-offs
Smaller, but it keeps the unmixed polynomial hash, and a user-chosen factor would be adjusted silently. Modelled only: with sizes coprime to 31 the en_US worst chain is 8; not run in Lucene.
The two responses the author named in the 2021 review.
Trade-offs
Raising the limit only moves the threshold (61 entries in one slot at 2 x 31^3). Rehashing needs a second pass over the sorted entries, because the builder writes each entry into the table as it goes. Not executed.
An application that lets end users add words to a custom dictionary list can see that configuration refuse to load; the trigger is dictionary content, which Lucene treats as trusted configuration.
A side finding of a bounded-exhaustive check of Hunspell's SET encodings: one test dictionary with 124 = 4 x 31 entries failed to load for a reason unrelated to decoding. Removing any single word fixed it, so the trigger was the entry count; a slot count outside Lucene and a survey of real dictionaries confirmed the 31/961 mechanism.
The method in full141 words
Method: semi-formal (the hunt's tier for bounded-exhaustive checks), in a hunt unit that compared Lucene's Hunspell SET encodings with reference codec tables on the stock main jars.
- The decode leg loads a one-word-per-byte test dictionary for every non-control high byte of each loadable SET encoding and compares
Hunspell.spellwith the codec tables. - The all-high-byte ISO8859-3 dictionary (89 words plus 35 hidden title-case entries = 124 = 4 x 31 entries) failed to load for a reason unrelated to decoding.
- A ddmin-style minimiser showed that removing any single word makes it load, so the trigger is the entry count.
- The
String.hashCode()modulo 31 / 961 hypothesis was then confirmed by a slot count outside Lucene and a survey of real dictionaries (en_US, nb_NO, sv_SE and Lucene's test dictionaries), and reduced to a public-API JUnit test, later to the single test shown here.
No prior report found in three searches (2026-10-28 and twice on 2026-10-30) of GitHub issues, PRs, commits and the JIRA archive, the mailing lists, downstream projects, forums and the web. Closest: #12464, which added hashFactor and the current message, and the 2021 design review, which discussed random collisions, not table sizes.
Searches4 searches
Closest items, none of them this bug: #12464 (made the load factor customizable and wrote the current message; empty description, review about overriding and wording only); apache/lucene-solr#2459 / LUCENE-9825 (the design review: a too-long chain is "a nontrivial possibility", report it; no word on table sizes); #3, #10872 (LUCENE-9833, an unrelated AssertionError in lookupWord), #12239, #11909 (other WordStorage or hash-table changes); #16527, #16536, #16537, #16363, #12825 (recent changes that do not touch the slot or the limit); #16422 (the only open hunspell PR, affix parsing); #16919 (the only hunspell commit since 2026-10-01, AffixCondition.java). Not fixed upstream: WordStorage.java is byte-identical on main 2f424fd428da (2026-10-30), branch_11x and the tag releases/lucene/10.6.0. Gaps: keyword search; private channels are not visible.
| Where | When | How | Found |
|---|---|---|---|
| Search tool (apache/lucene issues, PRs and commits incl. the JIRA archive, downstream repositories, dev@, java-user@, issues@, commits@, JIRA, web) | 2026-10-28 and twice on 2026-10-30 | three passes (221, 216 and 278 query records): WordStorage, flushGroup, hashFactor, stringHashCode, the message versions, hash collisions, load factor, modulo, "multiple of 31", 961 | nothing about this bug; closest #12464 and the LUCENE-9825 review |
| Manual GitHub searches (apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch, Lucene.NET, all of GitHub; Discussions and code) | 2026-10-30 | issue, PR, Discussions and code queries for the messages, WordStorage, hashFactor and the mechanism | only #12464 contains the message; "961" and "multiple of 31" match only PR numbers |
| Open apache/lucene PRs | 2026-10-30 | changed files of all 408 open PRs | none touches WordStorage.java; only #16422 touches hunspell/Dictionary.java (affix parsing) |
| Mailing lists, forums, Stack Overflow, an IDE tracker | 2026-10-30 | the Solr, general@ and Lucene.NET lists (48 queries) plus forum and tracker searches, zero-hit ones checked with a "hunspell" control | no report |
Introduced in 8.9.0 by LUCENE-9825 (4842e0c9cab, 2021), which replaced the word FST with the WordStorage hash table; #12464 (9.8.0) added hashFactor and the current message. The minimal test fails on all 42 releases from 8.9.0 to 10.6.0 and on main, and passes on 8.0.0 to 8.8.2.
Versions tested6 rows
Introduced by 4842e0c9cab "LUCENE-9825: Hunspell: reverse the "words" trie for faster word lookup/suggestions" (Peter Gromov, 2021-03-05; reviewed as apache/lucene-solr#2459, merged to main through apache/lucene#2 on 2021-03-10). The 8.x line got it through the squashed backport c6b964a1157 (apache/lucene-solr#2499, 2021-05-28; CHANGES 8.9.0, LUCENE-9687). Second stage: 1af68bf2d7e (#12464, 2023-07-28; first released in 9.8.0) made the table size (int) (wordCount * hashFactor), added the protected hashFactor() (default 1.0) and the "Try a larger Dictionary#hashFactor" message, without changing the slot formula or the limit. git blame on main assigns WordStorage.java:109, :390, :399-400 and :404 to 4842e0c9cab, and :294 and :401-403 to 1af68bf2d7e. Old releases ran on JDK 25; release jars from Maven Central, SHA-1 checked.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle; standalone -ea and -da); en_US + 300 and + 1,261 words fail, also through HunspellStemFilterFactory |
| 9.8.0 to 10.6.0 | 24 releases | fail: "Too many collisions. Try a larger Dictionary#hashFactor (now 1.0). If this doesn't help, ..." |
| 8.9.0 to 9.7.0 | 18 releases | fail: "Too many collisions, please report this to dev@lucene.apache.org" |
| 8.0.0 to 8.8.2 | 19 releases | the dictionary loads (words stored in an FST, no hash table) |
4842e0c9cab^ vs 4842e0c9cab | commit pair | the hunspell package of the parent, shadowed onto the 9.0.0 jars, loads; that of the commit fails (also in a second pass under a new seed) |
mixed-hash fix (scratch worktree at 645d4fe14a20) | not affected | the minimal test and the hunspell test package pass (159 tests, 146 run, 0 failures) |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication, a credibility audit, a current-main re-verify, two tie-breaks and a fact check all found it real, most with their own en_US word generators; a reviewer from another model family agreed without running code. This doc re-ran the test with gradle and validated the fix.
Checks and verdicts672 words
The cross-model reviewer could not run code in its reading-only setup: its intended-lens review returned real (medium) and agreed on the root cause; its refute-lens records are procedural only (it could run nothing), which two tie-breaks resolved as real. The first fact check found two wording errors in an earlier draft (an overclaim about the cross-model reviewer, and 961 stated as strictly necessary). The second fact check found four slips in this page (a title that read as always, a missing absolute value, duplicated entries, an overclaim about prior reports) and the second cross-model fact check a wrong code comment in the fix and two overclaims. All are corrected here.
| Check | Verdict | What it found |
|---|---|---|
| finder (semi-formal) | candidate | Minimised a failing 124-entry test dictionary to the entry count; slot counts and a real-dictionary survey; its 7-test JUnit fails 3 of 7 on main (-ea, -da) and fails on 8.9.0, 8.11.4, 9.0.0, 9.8.0, 9.12.3, 10.5.2 and branch_10_6 (version variants). |
| independent reproducer | real | Own 11-test JUnit with four-letter "-ang"/"-eng" words: 5 of 11 fail on main (-ea, -da), 10.5.2 and 9.12.3, controls pass, the fix passes 11 of 11; its en_US scan fails for exactly k = 300 and 1,261 of k in [0, 1922). |
| cross-model review (OpenAI GPT-5.6, intended lens, reading only) | real (medium) | Could not run code; agreed on the root cause; rated the intended-behaviour argument moderate. |
| intended-behaviour devil's advocate | real | Built the works-as-designed case and rejected it; own en_US scan and factory run (300 and 1,261 fail, 299 and 301 load); factors 1.5, 2.0, 3.0 and 4.0 load at k = 300; slot count 22 at 49,011. |
| adjudication | confirmed (high), crash, Low | Re-ran the reproducer's JUnit (-ea, -da); own en_US check: k = 296 to 304 load except 300. |
| credibility audit | keep | Own word generator: k = 295 to 305 load except 300, k = 1,259 to 1,263 except 1,261. |
| current-main re-verify | real | Run twice on 2026-10-30: the minimal test on 645d4fe14a20 (-ea, -da) and 10.5.2 fails; 960/962 controls pass; 8.9.0 fails, 8.8.2 passes; the factory en_US case fails at 300 and 1,261; the fix passes. |
| tie-break 1 | real (high) | Own en_US generator and model: 7 failing list sizes on main, all 18 executed outcomes predicted; factors 1.5, 2.0 and 3.0 fail at k = 10,871, 1.1 loads. |
| tie-break 2 | real (high) | Minimal test fails on main (-ea, -da), 10.6.0, 10.5.2 and 8.9.0, passes on 8.8.2; controls and fix pass; own generator: en_US + 300, 1,261 and 10,871 words fail through the constructor and the factory, the neighbours load; own model predicts all 10 configurations. |
| fact check | real; wording corrected | Own gradle run of the repro (fails) and of the fix (159 tests, 0 failures); the minimal test on main, 10.6.0, 8.9.0 (fail) and 8.8.2 (pass); own en_US probe (every en_US number holds; en_US alone fails at exactly 49,011 slots) and a 31-entry probe. |
| fact check 2 | real; doc wording corrected | Own gradle run of the repro (fails, assertions off and on) and of the fix (159 tests, 0 failures); the minimal test on main and 10.6.0 (-ea, -da) and 8.9.0 (fail) and 8.8.2 (pass); own en_US probe: every en_US number holds. Four wording errors in this page, corrected. |
| cross-model fact check 2 (reading only) | real; wording corrected | Read the brief and the run records without running code: one wrong code comment in the fix's javadoc and two overclaims in the brief, corrected. |
| this doc | reproduced, fix validated | Fresh scratch worktree at 645d4fe14a20: the minimal test fails with gradle (assertions on); with the mixed-hash fix the format check and the hunspell test package (159 tests, 0 failures) pass. |
| fix re-run (corrected diff) | fix validated | Fresh scratch worktree at 645d4fe14a20: the minimal test fails unpatched; with the corrected diff the format check and the hunspell test package (159 tests, 0 failures) pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 440 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,432 words
- Registry title
- Hunspell Dictionary can fail to load with 'Too many collisions' when its entry count is a multiple of 961, because WordStorage takes the raw String.hashCode() modulo the table size (for example the en_US dictionary plus a 300-word custom list)
- Area
- analysis-common / hunspell WordStorage (dictionary word hash table)
- Priority
- Low, rank 614: A loud, deterministic 'Too many collisions' load failure in the opt-in Hunspell Dictionary that a real dictionary can hit when its entry count is a multiple of 961 (for example en_US plus a 300-word custom list), so it heads the loud opt-in load-crash rows right after LFV-894, the hyphenation-grammar load crash with the same profile.
- Impact class
- crash
- Impact note
- Load failure, not wrong results: applications that use Lucene's Hunspell support (opt-in: Dictionary, Hunspell, HunspellStemFilter or HunspellStemFilterFactory with an application-supplied dictionary) whose word lists add up, hidden title-case entries included, to a multiple of 961 entries with more than 20 short words sharing their last two letters cannot build the dictionary at all (RuntimeException at load, executed with the stock en_US dictionary plus a 300- or 1261-word custom list); no scale is needed, -ea and -da behave the same, the default hashFactor 1.0 is affected, every release from 8.9.0 to 10.6.0 has it, and adding or removing one word, or (direct-API users only, through a Dictionary subclass) a hashFactor that makes the table size not divisible by 31, such as 1.1, avoids it, while HunspellStemFilterFactory users cannot set the factor at all.
- Summary
- You load a Hunspell dictionary, for example the stock en_US dictionary plus a custom list of 300 words through HunspellStemFilterFactory's documented dictionary="en_US.dic,custom.dic" pattern, and expect it to load as it does with 299 or 301 custom words. Instead the Dictionary constructor throws RuntimeException 'Too many collisions. Try a larger Dictionary#hashFactor (now 1.0). If this doesn't help, please report this to dev@lucene.apache.org', so the analyzer cannot be built. WordStorage puts every word into slot Math.abs(String.hashCode() % tableSize) with tableSize = entry count x hashFactor (default 1.0); when that size is a multiple of 961 = 31*31, the slot of a short word depends almost only on its last two letters (31^2 divides every earlier term of the unmixed radix-31 hash), so short words with a common ending (six-letter '-er' words in en_US) pile into a few slots and one exceeds the hard limit of 20 entries.
- Introduced
- 4842e0c9cab35239b6d1da619b94a640e7227510 (LUCENE-9825 'Hunspell: reverse the "words" trie for faster word lookup/suggestions', apache/lucene-solr#2459 by donnerpeter, issue apache/lucene#10864; reached main through the merge f5012a4cdaf (apache/lucene#2, 2021-03-10) and branch_8x through the squashed hunspell backport c6b964a1157 (apache/lucene-solr#2499, listed in CHANGES under 8.9.0 as LUCENE-9687)); it brought the slot formula, table size = entry count and the 20-entry limit together [exec: the hunspell package of 4842e0c9cab^ shadowed onto the 9.0.0 jars passes, that of 4842e0c9cab fails] [read: git blame on main attributes WordStorage.java:109, :390 and :399-400 to it]. Second stage: 1af68bf2d7e (#12464, branch_9x 64afaf5784b) made the table size (int) (wordCount * hashFactor) with a protected Dictionary#hashFactor() (default 1.0) and added the 'Try a larger Dictionary#hashFactor' advice, without changing the slot formula or the limit [read: git blame :294, :401-403] (2021-03-05 (author date of 4842e0c9cab; merged to main 2021-03-10; branch_8x backport c6b964a1157 2021-05-28); hashFactor stage 1af68bf2d7e 2023-07-28)
- First affected version
- 8.9.0 [exec] (first release with WordStorage, through the branch_8x backport; 8.8.2 and earlier store the words in an FST and load all test lists [exec on 8.0.0, 8.4.0, 8.8.0, 8.8.1, 8.8.2]); 9.0.0 on the main line [exec]
- Affected versions
- every release from 8.9.0 to 10.6.0 (10.6.0 run as its release revision, branch_10_6 head 4ae946e5a9b9) and main a9779ef3c193. [exec] the follow-up's public-API probe fails on all 41 releases it ran from 8.9.0 to 10.5.2 (8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2) and on branch_10_6 head 4ae946e5a9b9 and main (-ea and -da), and passes on the 5 releases it ran before 8.9.0; from 8.9.0 to 9.7.0 the message has no hashFactor advice (no hashFactor API), from 9.8.0 on the advised factor 2.0 also fails for the synthetic list; the finder's JUnit fails on 8.9.0 and 8.11.4 (8.x variant), 9.0.0 (pre-9.8 variant), 9.8.0, 9.12.3, 10.5.2, branch_10_6 and main; the independent reproduction reproduces on 10.5.2 and 9.12.3, the cross-model review step on 10.5.2, and the intended-behaviour check on 10.5.2 and 9.12.3 (en_US plus 300 words). [read] upstream main 645d4fe14a20 (2026-10-28) is unchanged at the fix site
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-28, read-only, the prior-report record verdict new, 221 query records: two scripted prior-report searches over GitHub issues, PRs and commits, downstream repositories (Elasticsearch, OpenSearch, Solr, Lucene.NET), the dev@, java-user@, issues@ and commits@ lists plus users@solr, solr-user@, dev@solr and general@, JIRA and the web; manual GitHub issue, PR, code and Discussions searches for the three message variants, WordStorage, flushGroup, hashFactor and the mechanism; the touched files of 413 open apache/lucene PRs and 185 PRs updated since 2026-10-14; the Elastic and OpenSearch forums, Stack Overflow and the tracker of an IDE that embeds Lucene's hunspell, each zero-hit search checked against a positive control; upstream main checked at 645d4fe14a20). Closest items, not this bug: #12464 (2023, made the hash table load factor customizable and wrote the current message; empty description, no root-cause discussion), apache/lucene-solr#2459 / LUCENE-9825 (the 2021 design review, which accepted that exceeding the 20-entry cap is 'a nontrivial possibility' and asked for reports; the table-size effect was not discussed), #10872 / LUCENE-9833 (an unrelated AssertionError in WordStorage.lookupWord), #16527/#16536/#16537 (cancellation checks in WordStorage). Not fixed upstream: the slot formula is unchanged since 4842e0c9cab, and the only hunspell change after a9779ef3c193 is #16919 (c5ab3e57b9b, AffixCondition.java only). Recheck 2026-10-28 (GitHub REST and search: apache/lucene PRs and issues created since 2026-10-26, hunspell commits since 2026-10-01, 'Too many collisions', 'WordStorage', 'hashFactor'): nothing new.
- Lucene commit tested
- main
645d4fe14a20: the minimal test with gradle in a fresh scratch worktree (fails with assertions on and off) and with the standalone runner (-eaand-da: fails); with the mixed-hash fix the minimal test, the format check and the hunspell test package pass (159 tests, 0 failures). The minimal test on the release jars 8.0.0 to 10.6.0 (61 releases) and on the commit pair4842e0c9cab^/4842e0c9cab. The en_US cases ran on main and 10.5.2 with a system en_US dictionary (hunspell-en-US 2012-10-24). OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordStorage.java:109 (at a9779ef3c193) (lookup slot Math.abs(CharsRef.stringHashCode(...) % hashTable.length)), :294 (hashTable = new int[(int) (wordCount * hashFactor)]), :390 (build slot Math.abs(currentEntry.hashCode() % hashTable.length)), :399-404 (more than 20 entries in one slot throw RuntimeException 'Too many collisions. Try a larger Dictionary#hashFactor (now X). If this doesn't help, please report this to dev@lucene.apache.org')lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:1102-1104 (at a9779ef3c193) (WordStorage.Builder gets sorted.wordCount() and hashFactor()), :1161-1168 (hashFactor() javadoc: 'If there are too many hash collisions, the factor can be increased, resulting in faster access, but more memory usage'; protected, default 1.0)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/HunspellStemFilterFactory.java:35-52 (at a9779ef3c193) (javadoc example dictionary="en_GB.dic,my_custom.dic"), :111 (new Dictionary(tempDir, "hunspell", affix, dictionaries, ignoreCase): no hashFactor parameter)GitHub (read-only, 2026-10-28): apache/lucene PRs and issues since 2026-10-26, commits on the hunspell package since 2026-10-01 (only c5ab3e57b9b, #16919), search 'Too many collisions' (#9684, #9963, unrelated), is:pr WordStorage (#16537, #16536, #16527, #12825, #13), 'hashFactor' issues (none)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordStorage.java:109, :294, :390, :399-404a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:1016, :1034, :1060-1064, :1068-1079, :1102-1104, :1160-1168a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/SortingStrategy.java:74-78, :91-92; HunspellStemFilterFactory.java:115a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/CharsRef.java:86-93
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/HunspellStemFilterFactory.java:41, :111; Dictionary.java:1160-1168
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:186-187, :203-204, :223-224, :1160-1168; WordStorage.java:399-404; HunspellStemFilterFactory.java:51a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:3389
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/module-info.java:55-57; lucene/core/src/java/org/apache/lucene/internal/hppc/BitMixer.java:67-71; a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordStorage.java:23, :178, :317, :347; GeneratingSuggester.java:103-106, :450-452
- History
a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:3389, :5385
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordStorage.java:294, :390, :399-404
- TestDictionary961Entries.java (lucene/analysis/common, package org.apache.lucene.analysis.hunspell, 1 test):
repro/LFV-933/src/org/apache/lucene/analysis/hunspell/TestDictionary961Entries.java(49 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed runs listed under Sources.
assets/LFV-933/bug.png(440 KB)