A file-format javadoc that Lucene presents as the definition of the .si file gives a wrong type for its first field and leaves two fields out of the sequence.
- Every Lucene segment has one small
.sifile: which Lucene version wrote it, how many documents it holds, whether it is a compound file, its file list, diagnostics and attributes. - Lucene documents each index file in the javadoc of the class that writes it, as an ordered list of fields with their types. For
.siwith the default codec that class isLucene99SegmentInfoFormat. - A String is written as a variable-length byte count followed by the bytes; an Int32 is four bytes, little-endian since 9.0.
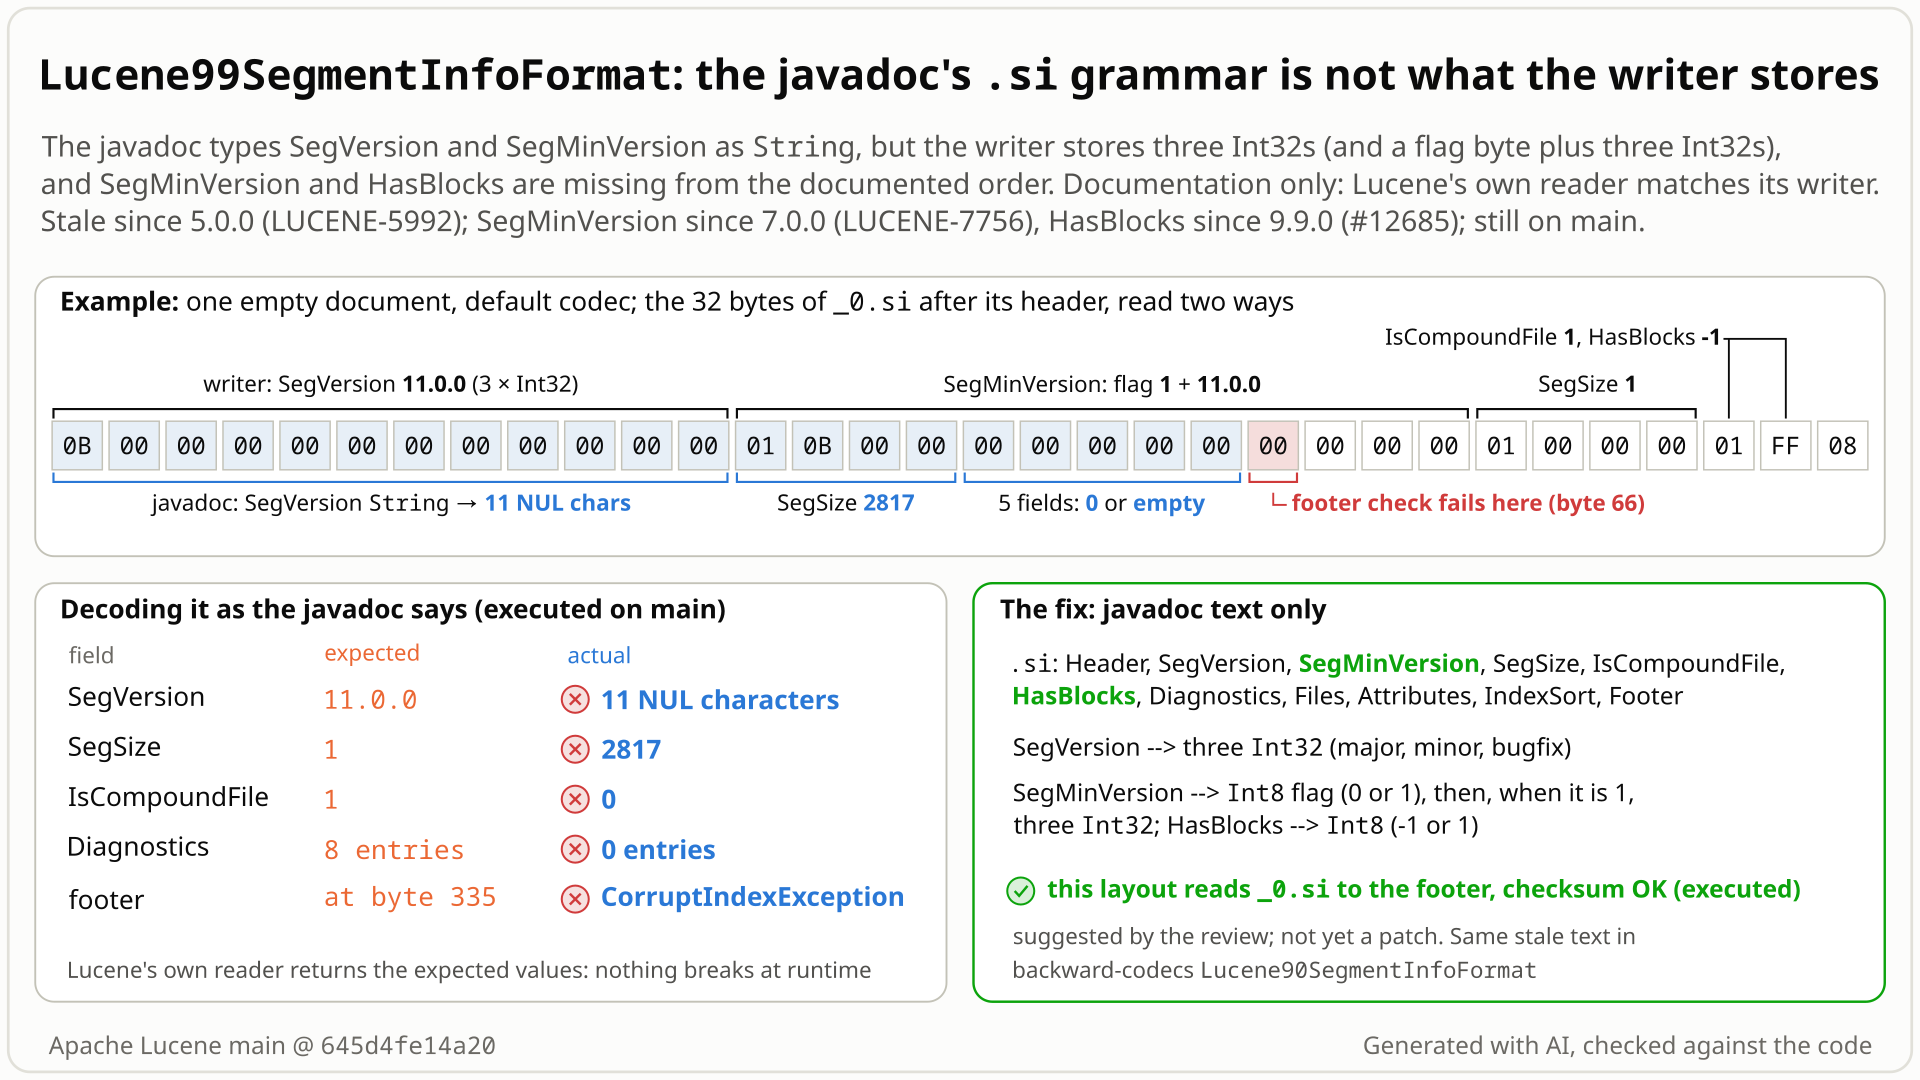
.si layout the javadoc gives next to the bytes Lucene writes for a one-document segment. Select the still to open it at full size. Generated with AI, checked against the code.- You write your own reader for a segment's
.sifile from theLucene99SegmentInfoFormatjavadoc, which the default codec's file-format docs link as the Segment Info format:Header, SegVersion, SegSize, IsCompoundFile, Diagnostics, ..., with SegVersion typed as a String. - You index one document with the default codec on main and parse its
.si. You expect SegVersion"11.0.0", SegSize 1 and IsCompoundFile 1, the valuesSegmentInforeports. - Instead you get SegVersion = 11 NUL characters, SegSize = 2,817 and IsCompoundFile = 0, and every later field is garbage. On 10.6.0 the version reads as 10 garbage characters.
- Why: the writer stores the version as three Int32s,
0B 00 00 0000 00 00 0000 00 00 00.readString()takes the first byte, 11, as a length and returns the next 11 zero bytes. Then come a min-version flag byte with three more Int32s and, after IsCompoundFile, a HasBlocks byte; neither is in the documented sequence. - Lucene itself is unaffected: its reader mirrors its writer. The text was right until LUCENE-5992 changed the encoding in 5.0.0.
Only people who read, port or re-implement the .si format from this javadoc: their parser fails on the first field of every .si the default codec writes, in the releases since 5.0.0. Applications that read and write indexes through Lucene are not affected: Lucene's reader matches the writer. The recorded searches found no public report.
Mechanism, terms and numbers564 words
The default codec writes each segment's .si file with Lucene99SegmentInfoFormat, and the file-format overview links that class as the Segment Info format and sends readers there for the details. Its javadoc gives the file as Header, SegVersion, SegSize, IsCompoundFile, Diagnostics, Files, Attributes, IndexSort, Footer and types SegVersion and SegMinVersion as DataOutput#writeString Strings. Since Lucene 5.0 the writer stores the version as three Int32s (major, minor, bugfix), then a flag byte and, when it is 1, the minimum version as three more Int32s, then SegSize, IsCompoundFile and a HasBlocks byte. A parser that follows the javadoc reads the first Int32 (major version 11, 0B 00 00 00) as a string length and gets 11 NUL characters instead of 11.0.0; a 1-document segment then reads as SegSize 2,817, and every later field is misaligned. Lucene's own reader matches its writer, so Lucene reads its own files correctly and no runtime effect is expected. The text was correct when written (2012) and went stale in three steps: LUCENE-5992 (5.0.0), LUCENE-7756 (7.0.0, SegMinVersion) and #12685 (9.9.0, HasBlocks). A javadoc-only fix was validated.
| # | javadoc sequence (Lucene99SegmentInfoFormat.java:48-49) | written by writeSegmentInfo (:196-246) |
|---|---|---|
| 1 | Header | Header (:188) |
| 2 | SegVersion: String (:57) | SegVersion: three Int32, major, minor, bugfix (:203-205) |
| 3 | (missing; typed String at :58) | SegMinVersion: Int8 flag, then three Int32 when it is 1 (:208-216) |
| 4 | SegSize: Int32 | SegSize: Int32 (:219) |
| 5 | IsCompoundFile: Int8 | IsCompoundFile: Int8, -1 or 1 (:221) |
| 6 | (missing; typed Int8 at :62) | HasBlocks: Int8, -1 or 1 (:222) |
| 7 | Diagnostics, Files, Attributes, IndexSort, Footer | the same (:223-245, :192) |
The reader, parseSegmentInfo (:121-179), mirrors the writer, so Lucene reads its own files correctly.
After the 45-byte header the file starts 0B 00 00 00 | 00 00 00 00 | 00 00 00 00 | 01 | 0B 00 00 00 | 00 00 00 00 | 00 00 00 00: version 11.0.0, flag 1, minimum version 11.0.0 (a flushed segment records the current version for both).
readString()at SegVersion reads the length byte0x0B= 11 and then 11 bytes: the rest of the major version and all of minor and bugfix, all zero. It returns 11 NUL characters and stops exactly at the flag byte.readInt()for SegSize then reads01 0B 00 00= 2817 (the segment has 1 document); the next byte, 0, is taken as IsCompoundFile (the segment is a compound file, 1); the following zero byte reads as an empty Diagnostics map (the real one has 8 entries). Every later field is garbage.- The number of garbage characters is the major version: 10 on 10.6.0, 9 on 9.9.0. Before 9.0 an Int32 was big-endian (
00 00 00 05), so the documented read returned an empty string.
No runtime, index, merge or search effect. The other .si elements (SegSize, IsCompoundFile, Diagnostics, Files, Attributes, IndexSort) are placed and typed consistently with the bytes, apart from the IndexSort --> writeVInt Int32 count wording (:63), which is cosmetic (it is a VInt). The compound-file value and the 8 diagnostics entries above are properties of this one-document configuration, not of the format.
Exposure and likelihood177 words
- Who is hit. Developers who decode
.sifiles themselves from the javadoc: ports of Lucene to other languages, index inspection or recovery tools, format tooling. The file-format overview calls itself "a high-level definition" (lucene104/package-info.java:54) and sends readers to the linked class pages for the details (:188); for.sithat page is this javadoc (:232). - Default vs opt-in. The default codec (
Lucene104Codec.java:73): every segment it writes has a.sifile and the mismatch is in its first field. No setting, input or scale is needed. Other codecs are outside this claim. - Who is not hit. Applications that read and write indexes through Lucene: the supported reader,
SegmentInfoFormat.read, matches the writer, andTestLucene99SegmentInfoFormat(17 tests) passes. - How long. From 5.0.0 to 10.6.0 and main, shown by representative runs per format class and the source history, not a run on every patch release;
Lucene99SegmentInfoFormatitself dates from 9.9.0, earlier releases carry predecessor classes with the same text. The recorded searches found no public report; it is rated minor and low priority.
One JUnit test (public Lucene APIs plus the test framework): index one empty document with the default codec, open the segment's .si, check its header, read the first documented field, SegVersion, with readString() as the javadoc types it, and compare it with SegmentInfo.getVersion(). Deterministic, about 2 seconds, the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene99;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SegmentInfo;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestLucene99SegmentInfoFormatJavadoc extends LuceneTestCase {

  public void testSegVersionIsTheDocumentedString() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc = new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        w.addDocument(new Document());
      }
      SegmentInfo si = SegmentInfos.readLatestCommit(dir).info(0).info;
      try (IndexInput in = dir.openInput(si.name + ".si", IOContext.READONCE)) {
        CodecUtil.checkIndexHeader(in, "Lucene90SegmentInfo", 0, 0, si.getId(), "");
        // javadoc: .si = Header, SegVersion (String), ...; the writer stores SegVersion as 3 Int32s
        String segVersion = in.readString();
        assertEquals(
            "SegVersion chars " + segVersion.chars().boxed().toList(),
            si.getVersion().toString(),
            segVersion);
      }
    }
  }
}
cp TestLucene99SegmentInfoFormatJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene99/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene99.TestLucene99SegmentInfoFormatJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- SegVersion reads as
"11.0.0", the valueSegmentInfo.getVersion()returns. - Observed
- SegVersion reads as 11 NUL characters (
SegVersion chars [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0] expected:<[11.0.0]>), with assertions on and off; 10 garbage characters on 10.6.0.
More files, environment, full output286 words
- The test pins the codec with
TestUtil.getDefaultCodec()(the test framework otherwise randomizes it) and uses aByteBuffersDirectory."Lucene90SegmentInfo"is the codec name the class writes into the header (Lucene99SegmentInfoFormat.java:94). The message prints the char codes because NUL characters are invisible. - It asserts only the first divergence. The missing SegMinVersion and HasBlocks are visible by reading the javadoc next to
writeSegmentInfo; the byte walk in the explanation above shows what the rest of a documented parse reads. - Results: fails 1 of 1 on main with assertions on and off, standalone and through gradle; on the published 10.6.0 jars (
SegVersion chars [0, 0, 0, 6, 0, 0, 0, 0, 0, 0] expected:<[10.6.0]>) and 9.9.0 jars ([0, 0, 0, 9, 0, 0, 0, 0, 0] expected:<[9.9.0]>). - As a regression test: the code is covered by
TestLucene99SegmentInfoFormat, and this test encodes the old text, so it would not guard the new one.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same test also fails on the published 10.6.0 and 9.9.0 jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestLucene99SegmentInfoFormatJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene99/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene99.TestLucene99SegmentInfoFormatJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
# excerpt: gradle on main 645d4fe14a20, -Ptests.seed=DEADBEEF; with -Ptests.asserts=false the lines are identical
TestLucene99SegmentInfoFormatJavadoc > testSegVersionIsTheDocumentedString FAILED
    org.junit.ComparisonFailure: SegVersion chars [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0] expected:<[11.0.0]> but was:<[<11 NUL characters>]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:83CC134AEA3AF546]:0)
        at app//org.junit.Assert.assertEquals(Assert.java:117)
        at app//org.apache.lucene.codecs.lucene99.TestLucene99SegmentInfoFormatJavadoc.testSegVersionIsTheDocumentedString(TestLucene99SegmentInfoFormatJavadoc.java:45)
:lucene:core:test (FAILURE): 1 test, 1  failure
# (excerpt: the suite-output lines and the repeated failure lines before the summary are left out;
# the 11 NUL characters are printed raw by JUnit and shown here as <11 NUL characters>)- It is written as an exact grammar: ordered fields, each type linked to its
DataOutputwriter. - It was right in 2012; LUCENE-5992 (5.0.0) changed the encoding and left the text, and two later changes added fields outside the sequence.
segments_Ndocuments the same version exactly ("three vInt: major, minor, bugfix").
The full argument215 words
- Contract text.
Lucene99SegmentInfoFormat.java:48-67lists the elements in order and links each type to itsDataOutputwriter method (SegVersion --> {@link DataOutput#writeString String}); nothing marks it as approximate.lucene104/package-info.java:188: "Details on each of these are provided in their linked pages." - History. LUCENE-4055 (
f330cf65adc, Robert Muir, 2012-05-22) wrote "SegVersion --> String" when the writer wrote the version withwriteString(output.writeString(si.getVersion())); 4.10.4 still writeswriteString(version.toString()), and the documented grammar parses there. LUCENE-5992 (#7054,a922e891914/776682ba9c3, Michael McCandless, 2014-10-06, "encode version using 3 ints, not String") changed the writer and reader, not the javadoc; its 22 comments never mention it (in review uschindler noticed that a different javadoc,Version#write, had become wrong). LUCENE-7756 (23b002a0fdf, 2017) and #12685 (6677109ee60, 2023) added SegMinVersion and HasBlocks to the type list and descriptions but not to the sequence; their reviews do not discuss it. - Consistency.
SegmentInfos.java:73-77documents the commit's Lucene version as "three {@link DataOutput#writeVInt vInt}: major, minor, bugfix", and the hunt found those fields match the bytes. - Precedent. LUCENE-713, LUCENE-7532 (#8583; fix commit
830a3fdfbf1, "add back lost codec file format documentation") and LUCENE-9353 (#90) fixed or restored file-format documentation. - No waiver. No test, CHANGES or MIGRATE entry, review comment or list thread accepts the stale text.
The devil's-advocate check184 words
Strongest case for "intended" (the refute reviewer and the cross-model review rated it moderate; the intended-behaviour check set it out as the strongest case and rejected it): the format classes are @lucene.experimental; the overview says it "attempts to provide a high-level definition of the Apache Lucene file formats", a policy from LUCENE-2946 (2012, "change file format documentation from bit-for-bit to highlevel"); the supported reader is SegmentInfoFormat.read; and the round trip is tested.
Why it fails: a wrong primitive type (String versus three Int32s) and two elements missing from an ordered list are not a high-level simplification. In the LUCENE-2946 thread (#4020, 2012-04-25) Robert Muir wrote "we can go into detail, but we can't do bit-for-bit with even StandardCodec" and "For the simple metadata files, and even stored fields and postings its fine (for now), but e.g. going bit-for-bit with packed integer compression of docvalues isnt very realistic" (their words), and .si is such a simple metadata file. @lucene.experimental allows the format to change, not its description to be wrong. Every verifier and the adjudication called it real, and the audit confirmed it.
Recommended A. Correct the sequence and the two types in Lucene99SegmentInfoFormat
Correct the javadoc: sequence Header, SegVersion, SegMinVersion, SegSize, IsCompoundFile, HasBlocks, Diagnostics, Files, Attributes, IndexSort, Footer; SegVersion as three Int32s (major, minor, bugfix); SegMinVersion as an Int8 flag followed, if it is 1, by three Int32s. Javadoc only, one file. Validated: a parser written from the new text reads a real .si to the footer.
All options and trade-offs4 options · 814 words
A is the fix; B to D are optional additions. Upstream retired branch_10x on 2026-10-29 (#16911), so the targets are main and branch_11x, plus branch_10_6 if wanted (its copy of the class carries the same lines).
A. Correct the sequence and the two types in Lucene99SegmentInfoFormat (validated by the checks) (recommended)
Javadoc only, Lucene99SegmentInfoFormat.java:48-79, 9 lines added, 6 removed: place SegMinVersion and HasBlocks in the sequence, type SegVersion as three Int32s and SegMinVersion as an Int8 flag plus three Int32s, say that the flag is 0 when the minimum version is unknown (as SegmentInfo.getMinVersion() documents), and give the HasBlocks values (-1 or 1, like IsCompoundFile).
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java
index 8512307156a..e2ee40d2b5f 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java
@@ -45,8 +45,8 @@ import org.apache.lucene.util.Version;
* <p>Files:
*
* <ul>
- * <li><code>.si</code>: Header, SegVersion, SegSize, IsCompoundFile, Diagnostics, Files,
- * Attributes, IndexSort, Footer
+ * <li><code>.si</code>: Header, SegVersion, SegMinVersion, SegSize, IsCompoundFile, HasBlocks,
+ * Diagnostics, Files, Attributes, IndexSort, Footer
* </ul>
*
* Data types:
@@ -54,8 +54,9 @@ import org.apache.lucene.util.Version;
* <ul>
* <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>SegSize --> {@link DataOutput#writeInt Int32}
- * <li>SegVersion --> {@link DataOutput#writeString String}
- * <li>SegMinVersion --> {@link DataOutput#writeString String}
+ * <li>SegVersion --> three {@link DataOutput#writeInt Int32}: major, minor, bugfix
+ * <li>SegMinVersion --> {@link DataOutput#writeByte Int8} flag, 0 or 1, followed, if it is 1,
+ * by three {@link DataOutput#writeInt Int32}: major, minor, bugfix
* <li>Files --> {@link DataOutput#writeSetOfStrings Set<String>}
* <li>Diagnostics,Attributes --> {@link DataOutput#writeMapOfStrings Map<String,String>}
* <li>IsCompoundFile --> {@link DataOutput#writeByte Int8}
@@ -71,12 +72,14 @@ import org.apache.lucene.util.Version;
*
* <ul>
* <li>SegVersion is the code version that created the segment.
- * <li>SegMinVersion is the minimum code version that contributed documents to the segment.
+ * <li>SegMinVersion is the minimum code version that contributed documents to the segment. Its
+ * flag is 0 if that version is unknown.
* <li>SegSize is the number of documents contained in the segment index.
* <li>IsCompoundFile records whether the segment is written as a compound file or not. If this is
* -1, the segment is not a compound file. If it is 1, the segment is a compound file.
* <li>HasBlocks records whether the segment contains documents written as a block and guarantees
- * consecutive document ids for all documents in the block
+ * consecutive document ids for all documents in the block. If this is -1, the segment has no
+ * such documents. If it is 1, it has.
* <li>The Diagnostics Map is privately written by {@link IndexWriter}, as a debugging aid, for
* each segment it creates. It includes metadata like the current Lucene version, OS, Java
* version, why the segment was created (merge, flush, addIndexes), etc.Trade-offs
- None for users: documentation only; no CHANGES entry strictly needed.
- The sequence and types are what the refute reviewer, the independent reproduction and the adjudication proposed; the wording is this doc's.
What the checks validated
- The new text matches the bytes of the recorded configuration. A fix-text check written only from the patched javadoc (Header; three Int32 for SegVersion; the flag and three Int32 for SegMinVersion; SegSize; the IsCompoundFile and HasBlocks bytes; Diagnostics, Files, Attributes; the sort count) compares every field with
SegmentInfoand ends exactly at the footer: passes 1 of 1 on main with assertions on and off and on the 10.6.0 jars. Scope: one flushed one-document segment, min version present (flag 1), no index sort; it does not exercise flag 0, sort fields or the reader's rejection of other flag values. It is a validation, not a proposed test. - Build checks on the patched tree (scratch worktree of
645d4fe14a20):./gradlew :lucene:core:test --tests "org.apache.lucene.codecs.lucene99.TestLucene99SegmentInfoFormat"plus the fix-text check,-Ptests.seed=DEADBEEF: 18 tests, 0 failures;:lucene:core:checkGoogleJavaFormatand:lucene:core:renderJavadocpass, and the rendered page shows the new sequence and types and noSegVersion --> String.
backward_codecs/lucene90/Lucene90SegmentInfoFormat.java:46-47 and :55-56 carry the same stale sequence and String types, and its test writer Lucene90RWSegmentInfoFormat.java:48, :57-58 copies them. That format has no HasBlocks: its reader (:118-142) reads the version, the min-version flag, the doc count, the compound byte, then the maps.
Trade-offs
Harmless, but some committers prefer not to touch frozen formats.
What the checks validated
Not run.
The same hunt found stale grammars in other default-codec file-format javadocs (.fnm, segments_N, .nvm, block-tree terms metadata, vector formats; separate findings and fix sites), which could be fixed in the same change, as could the cosmetic IndexSort --> writeVInt Int32 count wording.
Trade-offs
A bigger change to review; each part is still javadoc only.
#13342 ("Datacube format changes to support materialized views", open, last updated 2025-09-30) adds a Lucene910SegmentInfoFormat whose javadoc copies the stale parts verbatim: the same .si sequence and the same SegVersion and SegMinVersion String lines (it changes the class lead text and adds DataCubesConfig and DataCubeField entries). If it lands, its copy needs the same fix.
Trade-offs
Outside this fix site; it matters only if #13342 lands.
Downstream: only tools that parse .si files themselves from this javadoc are affected; applications that read and write indexes through Lucene are not.
Semi-formal: a differential check transcribed each default-codec file grammar once from its class javadoc and once from its writer, parsed the real bytes of 64 generated indexes with both and compared every value with Lucene's own reader. All 125 .si files diverged under the javadoc grammar; the writer grammar parsed every file to the footer.
The method in full122 words
- Each grammar is data in a small grammar language; one interpreter parses the bytes under the documented and the written grammar and compares every value with the real reader.
- 64 default-codec indexes (3 fixed, 1 dense-vector and 60 seeded random feature configurations), 1,114 file checks over 11 file types, including
.si. - Positive control: the writer grammars parse every file exactly to the footer. Vacuity check: 14 of 14 writer-grammar mutants with one element dropped are caught.
- JUnit tests on public Lucene APIs then bridged the finding to the stock jars (later reduced to the one-test repro), and per-release ports dated each of the three stale parts.
- This is a differential check of documentation against bytes, not model checking or a proof.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-28, rechecked 2026-11-01); SegVersion and SegMinVersion have no hits on all of GitHub. Not fixed upstream. Open PR #13342 copies the same text into a new class.
Searches4 searches
- Related, not this bug: #7054 / LUCENE-5992, #8807 / LUCENE-7756 and #12685 (the changes that made the text stale; none mentions it); #30 / LUCENE-9705 (copied the text into Lucene90); LUCENE-2946 (the 2012 doc policy); #16922 (a report on a different javadoc,
UpgradeIndexMergePolicy, that mentions the segment version); #13342 (copies the text). - Not fixed upstream: upstream main
f815e679bf6c(2026-11-01),branch_11xandbranch_10_6carry the stale lines; the file's last upstream commit is #14804 (2025-06-18, imports only).
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; the JIRA archive; downstream repositories; the web | 2026-10-28 | 51 scripted prior-report queries and 45 manual GitHub searches on the identifiers and phrases; all 413 open PRs and the 78 PRs closed since 2026-10-01 scanned by changed files | no report; SegVersion and SegMinVersion 0 issues or PRs on all of GitHub, 0 JIRA hits |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-28 | 20 scripted queries | no report; only notification mirrors of the related commits and PRs |
| apache/lucene (recheck) | 2026-10-28 | issues and PRs created since 2026-10-26, identifier searches, the newest open PRs' files, the file's upstream commits, the file at main 645d4fe14a20 | no report; the stale lines still on main |
| apache/lucene (recheck) | 2026-11-01 | the file on main, branch_11x and branch_10_6; the file's commit list; the 68 issues and PRs updated since 2026-10-28 and the changed files of the 54 PRs among them | no report, not fixed; only #16911 (decommissioning branch_10x) touches a SegmentInfoFormat file |
Stale since 5.0.0: LUCENE-5992 (2014-10-06) changed the version from a String to three Int32s and left the javadoc. LUCENE-7756 (7.0.0) added SegMinVersion as a String outside the sequence; #12685 (9.9.0) created this class from the stale text with HasBlocks outside the sequence. 4.10.4 is correct.
Versions tested6 rows
- Correct when written:
f330cf65adc(LUCENE-4055, Robert Muir, 2012-05-22). - SegVersion:
a922e891914(trunk) and the branch_5x backport776682ba9c3, "LUCENE-5992: encode version using 3 ints, not String", Michael McCandless, 2014-10-06; first release 5.0.0. The change is LUCENE-5992, not LUCENE-5998 (f82e41df81a), which only merged the reader and writer into the format class. - SegMinVersion:
23b002a0fdf, LUCENE-7756 (#8807), Adrien Grand, 2017-03-30; first release 7.0.0; wrong from the day it was written. - HasBlocks and the current class:
6677109ee60/ branch_9x26043819a5b, #12685, Simon Willnauer, 2023-10-23; first release 9.9.0. It createdLucene99SegmentInfoFormatby copying the stale Lucene90 javadoc. - The text moved through Lucene50 (5.0-6.1), Lucene62 (6.2-6.6), Lucene70 (7.0-8.5), Lucene86 (8.6-8.11), Lucene90 (9.0-9.8) and Lucene99 (9.9-main).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | SegVersion = 11 NUL characters, assertions on and off (standalone and gradle); the fix-text check passes with fix A |
10.6.0 (tag commit 4ae946e5a9b9) | affected | SegVersion = 10 garbage characters (the minimal test on the published jars) |
9.9.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 head | affected | the minimal test (9.9.0) and the hunt's and verifiers' tests fail; SegMinVersion and HasBlocks also unplaced |
| 7.0.0, 8.11.4, 9.8.0 | affected | the documented grammar fails at SegVersion (follow-up ports); fixing only SegVersion still fails at SegMinVersion on 7.0.0 and 8.11.4; on 9.8.0 fixing SegVersion and SegMinVersion together parses |
| 5.0.0, 6.6.6 | affected | SegVersion reads as an empty string (big-endian Int32); fixing only SegVersion parses (follow-up ports) |
| 4.10.4 | not affected | the version was a String; the documented grammar parses (follow-up port) |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6, one of them executed), an intended-behaviour devil's advocate and an adjudication (high confidence); an audit confirmed it as a low-priority documentation defect. This doc's runs validated the fix.
Checks and verdicts284 words
Every check re-ran a repro on main or a release, or read the same lines; none found a reading under which the javadoc is meant to differ from the bytes.
| Check | Verdict | What it found |
|---|---|---|
| finder (differential grammar check) | reproduced (doc) | 125 of 125 .si files diverge under the javadoc grammar; the writer grammar parses all; its JUnit fails 2 of 2 on main (assertions on and off), the branch_10_6 head, 10.5.2 and 9.12.3. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real, high confidence | Its own test fails with assertions on (three seeds) and off (one seed), on main ea57360912ed (the same file); its corrected-layout control reaches the footer; TestLucene99SegmentInfoFormat 17 tests, 0 failures; intended argument moderate. |
| independent reproducer | real | Own 3-test class: the literal and a generous reading fail, the writer-layout control passes, on main, 10.5.2 and 9.12.3; corrected the history to LUCENE-5992. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, high confidence | Intended argument moderate; a separate run re-ran the finder's test: 2 of 2 fail on main, 10.5.2 and 9.12.3. |
| intended-behaviour devil's advocate | real (documentation) | Rejected the LUCENE-2946 high-level policy and @lucene.experimental as excuses; re-ran on main and 10.5.2. |
| adjudication | confirmed, high; class minor | Re-ran the independent reproduction's test with a new seed, assertions on and off: 2 of 3 fail, the control passes. |
| audit | confirmed | Re-ran on main with assertions off; confirmed it as a minor documentation defect with no runtime impact. |
| this doc (2026-11-01) | real; fix A validated | Minimal test on main (on and off), 10.6.0, 9.9.0 and through gradle; byte probe; fix-text check; closest suite, format and javadoc checks on the patched tree. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 440 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,533 words
- Registry title
- The file-format javadoc of the default segment info format (Lucene99SegmentInfoFormat) gives a wrong .si grammar: SegVersion and SegMinVersion are typed as String, but the writer stores three Int32s (and a flag byte plus three Int32s), and SegMinVersion and HasBlocks are missing from the documented sequence (documentation defect; the writer and reader agree)
- Area
- codecs / segment info (Lucene99SegmentInfoFormat .si file-format javadoc vs its writer and reader)
- Priority
- Low, rank 1279: The default .si grammar is wrong for a file every segment has, a documentation-only defect.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so indexing, merging, CheckIndex and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement the .si format from this class javadoc (the default codec's package docs link it as the Segment Info format), and a parser that follows the text misreads the very first field of every .si file the default codec writes, then every later field (executed); the text has been wrong in every release since 5.0.0 (2015), and no scale or special setting is needed.
- Summary
- You decode a segment info (.si) file of the default codec by following the Lucene99SegmentInfoFormat javadoc, which gives the sequence Header, SegVersion, SegSize, IsCompoundFile, Diagnostics, Files, Attributes, IndexSort, Footer and types SegVersion (and SegMinVersion) as a String. The writer instead stores the version as three Int32s (major, minor, bugfix), then a flag byte and, when it is 1, the minimum version as three more Int32s, then SegSize, IsCompoundFile and a HasBlocks byte, so a parser built from the text reads the Int32 major version 11 as a string length and gets 11 NUL characters instead of '11.0.0', and every later field is misaligned. Lucene's own reader matches the writer, so nothing breaks at runtime; only the documentation is wrong, and it has been since 5.0.0.
- Introduced
- three stages [follow-up]: (1) a922e8919145243c5afc4d6e43448a8c2806eea7 (trunk, svn r1629769) / 776682ba9c36b9543980cd959ca0a62488a6318a (branch_5x, svn r1629775, the commit that first shipped, in 5.0.0), LUCENE-5992 'encode version using 3 ints, not String' (now apache/lucene#7054; a JIRA patch, no GitHub PR), by mikemccand: it changed the Lucene50 segment info writer and reader from writeString(version) to three writeInt calls and left the javadoc's String typing [read: git log and git show in the full-history clone; exec: the 4.10.4 documented grammar parses, the 5.0.0 one fails]; (2) 23b002a0fdf (LUCENE-7756, apache/lucene#8807, by jpountz; the history clone also holds an identical commit fd9689cb36a of the same date) added SegMinVersion, typed String and left out of the sequence, while the writer stored a flag byte plus three Int32s from the start [exec: the version-fixed grammar parses on 6.6.6 and fails on 7.0.0]; (3) 6677109ee60 / branch_9x 26043819a5b (PR apache/lucene#12685, by s1monw) created Lucene99SegmentInfoFormat by copying the stale Lucene90 javadoc and added HasBlocks to the type list and descriptions but not to the sequence [exec: the version-and-min-version-fixed grammar parses on 9.8.0 and fails on 9.9.0]. The String typing was correct when written (f330cf65adc, LUCENE-4055, 2012). The finder's first attribution to LUCENE-5998 (f82e41df81a) is corrected by the independent reproduction, the intended-behaviour check and the adjudication: that commit only merged the reader and writer into the format class (2014-10-06 (author date of a922e891914 and 776682ba9c3: SegVersion); 2017-03-30 (author date of 23b002a0fdf: SegMinVersion); 2023-10-23 (author date of 6677109ee60: HasBlocks and the Lucene99 class))
- First affected version
- 5.0.0 [exec] (SegVersion; the last unaffected release is 4.10.4 [exec], whose different class Lucene46SegmentInfoFormat documented the String version the writer then wrote); 7.0.0 [exec] for the SegMinVersion gap; 9.9.0 [exec] for the HasBlocks gap and the first release of Lucene99SegmentInfoFormat
- Affected versions
- every release from 5.0.0 through 10.6.0 (10.6.0 run as its release revision, the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream [exec: per-release public-API ports that transcribe each release's own javadoc grammar fail on 5.0.0, 6.6.6, 7.0.0, 8.11.4, 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.5.2 and main, and the writer-layout control parses exactly on 8.11.4, 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.5.2 and main; the finder's JUnit fails 2 of 2 on 9.9.0, 9.12.3, 10.0.0, 10.5.2, the branch_10_6 head and main (-ea and -da); the independent reproduction's JUnit fails 2 of 3, with its layout control passing, on main (-ea and -da), 10.5.2 (-ea and -da) and 9.12.3; read: the releases in between from each tag's javadoc and writer]. The stale text lives in Lucene50SegmentInfoFormat (5.0-6.1), Lucene62 (6.2-6.6), Lucene70 (7.0-8.5), Lucene86 (8.6-8.11), Lucene90 (9.0-9.8) and Lucene99 (9.9-main). Before 9.0 an Int32 is big-endian, so the documented readString returns an empty string; since 9.0 it is little-endian and returns as many NUL or garbage characters as the major version number. Caveats: the 8.9-8.11 sources are not in the history clone (javadoc read at 8.8.1, behaviour executed on 8.11.4); upstream main 645d4fe14a20 (2026-10-28) still carries the text [read]; all runs used JDK 25 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: 51 scripted prior-report queries over GitHub issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive, downstream repositories and the web; 45 manual GitHub searches on the identifiers and phrases (SegVersion and SegMinVersion: 0 issues or PRs on all of GitHub, 0 JIRA hits); all 413 open apache/lucene PRs and the 78 PRs closed since 2026-10-01 scanned by changed files; the file's commit history on main, branch_10x and branch_10_6). Nearest items, not the same bug: #7054 / LUCENE-5992 (made SegVersion stale; its 22 comments never mention the .si javadoc), #8807 / LUCENE-7756 (added SegMinVersion), #12685 (added HasBlocks; review comments say nothing about the javadoc), #30 / LUCENE-9705 (copied the text into Lucene90), LUCENE-2946 (2012 policy for high-level file-format docs; detail kept for simple metadata files), #16922 (open, 2026-10-27, a report about a different javadoc that mentions the segment version, in UpgradeIndexMergePolicy). Not prior art: open PR #13342 copies the same stale javadoc into a new Lucene910SegmentInfoFormat. Recheck (2026-10-28): none of the 29 apache/lucene issues and PRs created since 2026-10-26 (including a series of javadoc fixes, #16920-#16922, #16927, #16928, #16933-#16935) is about the .si or any file-format grammar; 'SegVersion' (apache/lucene) and 'SegMinVersion' (all of GitHub) 0 hits; 'SegmentInfoFormat' updated since 2026-10-26 0 hits; the open PRs opened after the follow-up's scan (#16929-#16932) and #16923 touch neither the class nor lucene104/package-info.java; by author date the file's latest commits on upstream main are 51b3a5baa73 (2025-06-18, imports only, #14804) and 6677109ee60 (2023-10-23, #12685); upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 48, 57, 58 and 62. Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone and through gradle; a byte probe (the documented and the written layout of one.si); the recommended fix in a scratch worktree (a fix-text check,TestLucene99SegmentInfoFormat,checkGoogleJavaFormat,renderJavadoc). The minimal repro and the fix-text check on the published 10.6.0 jars (tag commit4ae946e5a9b9), the minimal repro on 9.9.0. Earlier runs by the hunt and its verifiers on maina9779ef3c193andea57360912ed(the same file), thebranch_10_6head, 10.5.2 and 9.12.3, and the follow-up's per-release ports from 4.10.4 to 10.5.2. Upstream mainf815e679bf6c,branch_11xandbranch_10_6read on 2026-11-01: the stale lines are unchanged.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java:48-49 (documented sequence), :57-58 (SegVersion and SegMinVersion --> DataOutput#writeString String), :62 (HasBlocks --> Int8, not in the sequence), :70-84 (field descriptions), :87 (@lucene.experimental), :196-246 (writer: :203-205 three writeInt, :208-216 flag byte plus three writeInt, :219 maxDoc, :221 compound byte, :222 HasBlocks byte), :121-179 (reader mirrors the writer); identical at Lucene main ea57360912ed (compared 2026-10-28)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:54 ('a high-level definition'), :188 ('Details on each of these are provided in their linked pages'), :232 (links Lucene99SegmentInfoFormat as Segment Info)lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene90/Lucene90SegmentInfoFormat.java:46, :55-56 and lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene90/Lucene90RWSegmentInfoFormat.java (the same stale text in the frozen read-only copy and its test writer)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java (lines 42-88 class javadoc: 48-49 sequence, 57-58 String types, 61-62 Int8 types, 73-79 descriptions, 87 @lucene.experimental; 94 codec name; 121-179 reader; 188 header; 196-246 writer)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java (lines 168-171: flushed segments record Version.LATEST as version and min version)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 54, 188, 232)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java (line 73)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java (lines 48-67, 87)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 54, 188)lucene/core/src/java/org/apache/lucene/index/SegmentInfos.java (lines 63-77)a Lucene clone tag releases/lucene-solr/4.10.4 (Lucene46SegmentInfoWriter.java line 61: writeString(version.toString())) and releases/lucene-solr/5.0.0 (Lucene50SegmentInfoFormat.java: String in the javadoc, writeInt in the writer)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/SegmentInfo.java (lines 45, 48, 293-297)lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene90/Lucene90SegmentInfoFormat.java (lines 46-47, 55-56, 118-142) and lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene90/Lucene90RWSegmentInfoFormat.java (lines 48, 57-58)
- History
a Lucene clone tags releases/lucene-solr/4.10.4, releases/lucene-solr/5.0.0, releases/lucene/10.6.0
- TestLucene99SegmentInfoFormatJavadoc.java (JUnit, one test):
repro/LFV-934/src/org/apache/lucene/codecs/lucene99/TestLucene99SegmentInfoFormatJavadoc.java(52 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed byte probe (the first body bytes, the documented parse and the written layout of one .si).
assets/LFV-934/bug.png(440 KB)