SubmissionReport prints each hit's score with a NumberFormat that still has thousands grouping on. trec_eval parses that column with C atof(), which stops at the first comma.
- A TREC run file has one line per retrieved document: query id, the literal
Q0, document name, rank, score and run name. trec_eval reads it with the relevance judgments and computes precision, MAP, nDCG and other metrics. - trec_eval ignores the rank column. It sorts each query's documents by the score column, highest first, and breaks ties by document name.
- lucene/benchmark's quality package runs TREC topics against an index and writes such a file with
SubmissionReport;QueryDriveris its command line.
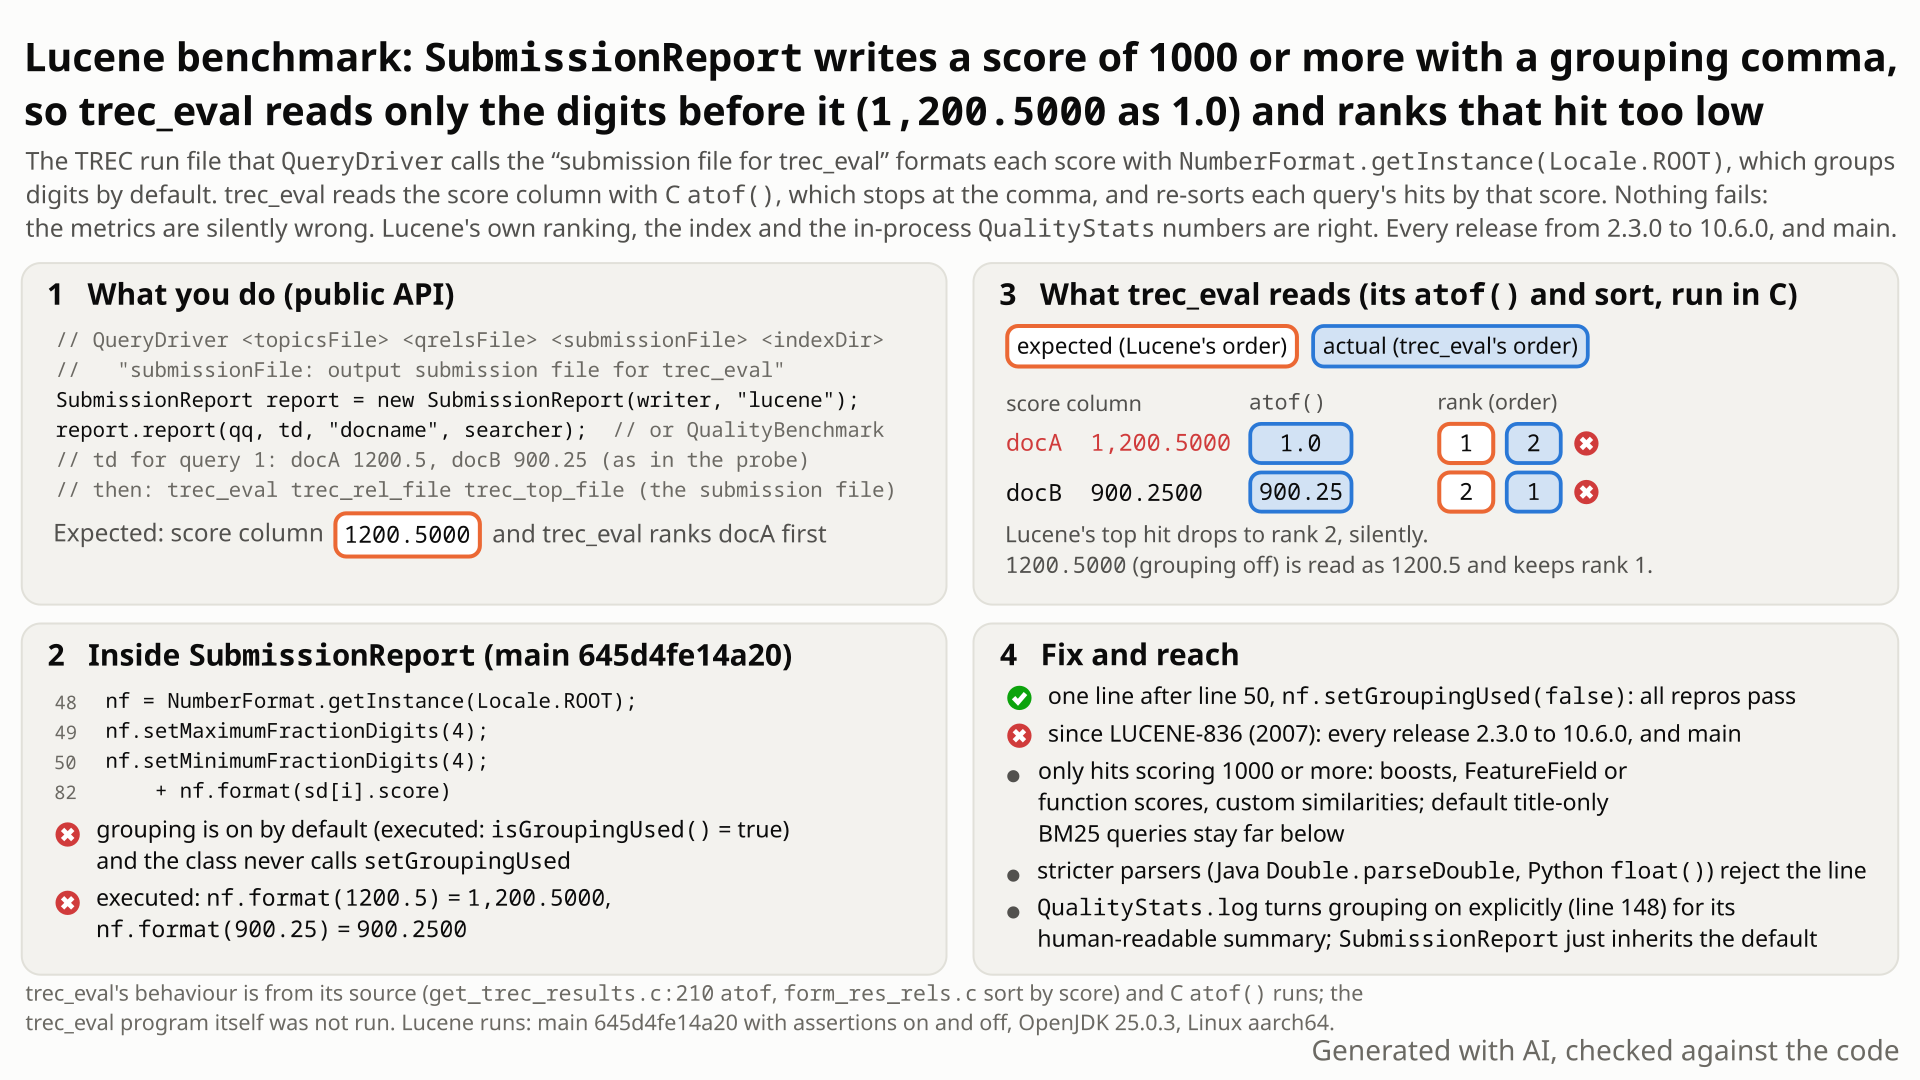
SubmissionReport, what trec_eval's atof() reads (1.0 and 900.25, so the two hits swap ranks), and the one-line fix and who is hit. Select the still to open it at full size. Generated with AI, checked against the code.- Evaluate search quality with lucene/benchmark:
QualityBenchmark(or theQueryDrivercommand line) writes one TREC line per hit,qid Q0 docno rank score tag, throughSubmissionReport, for trec_eval to score. - Lucene ranks docA first with score 1200.5 and docB second with 900.25. You expect the score column to read
1200.5000and900.2500. - Instead docA's line says
1,200.5000. The formatter isNumberFormat.getInstance(Locale.ROOT)with 4 decimals, and nobody turned its thousands grouping off, so every score of 1000 or more gets a comma. - trec_eval reads the column with C
atof(), which stops at the comma: docA scores 1.0. It ignores the rank column and re-sorts by score, so it evaluates [docB, docA], the reverse of Lucene's ranking. - No error anywhere: trec_eval reports precision, MAP and so on for the wrong order. Lucene's own results and its in-process metrics are right; only the file is wrong.
Users of the opt-in lucene/benchmark quality package who score its run file with trec_eval, when hits score 1000 or more: boosts, FeatureField (impact) queries, function scores or custom similarities. QueryDriver's default title-only BM25 queries stay far below 1000. Silent with trec_eval; every release since 2.3.0.
Mechanism, terms and numbers499 words
lucene/benchmark's search-quality package writes a TREC run file, one line per hit (qid Q0 docno rank score tag), through SubmissionReport. QueryDriver documents that file as the "output submission file for trec_eval". The score is formatted with NumberFormat.getInstance(Locale.ROOT) and 4 fixed decimals, and grouping is never turned off, so any score of 1000 or more is written with a thousands comma: 1200.5 as 1,200.5000. trec_eval reads the score with C atof(), which stops at the comma and returns 1.0, ignores the rank column and re-sorts each query's hits by the parsed score. A run Lucene ranked [1200.5, 900.25] is therefore evaluated as [900.25, 1.0], and every metric is computed on that order, with no error. It needs hit scores of 1000 or more (boosts, FeatureField or function scores, custom similarities); QueryDriver's default title-only BM25 queries stay far below, and through its own parser only a contrived query repeating one word 400 times got there. Lucene's ranking, the index and the in-process QualityStats numbers are not affected. Every release since 2.3.0 (2008) has it, through 10.6.0 and main; the fix is one line, nf.setGroupingUsed(false).
QueryDriverusage: "submissionFile: output submission file for trec_eval" (QueryDriver.java:48); it writes the file with the stockSubmissionReport(:59-63).SubmissionReportjavadoc: "Create a log ready for submission" (SubmissionReport.java:30).QualityBenchmarknames two configurations, "Against existing judgements" and "For submission (e.g. for a contest)" (QualityBenchmark.java:32-41).- trec_eval documents the line as
qid iter docno rank sim run_id, with "similarity sim (a double)"; "the rank field is ignored here; internally ranks will be assigned by sorting by the sim field with ties broken determinstically (using docno)" (get_trec_results.c:17-26, its spelling).
- The constructor builds
NumberFormat.getInstance(Locale.ROOT)and sets 4 minimum and maximum fraction digits (SubmissionReport.java:48-50). Nothing callssetGroupingUsed, so the formatter is the pattern#,##0.0000with grouping on and group size 3 (executed on JDK 25:999.5 -> 999.5000,1200.5 -> 1,200.5000,1234567.0 -> 1,234,567.0000). report()writes, per hit, the query id,Q0, the padded doc name, the 0-based rank,nf.format(sd[i].score)and the run name, separated by" \t "(:62-86, the score at:82).- trec_eval parses the field with
text_results_ptr->sim = atof(lines[i].sim);(get_trec_results.c:210) and sorts by it (form_res_rels.c:111-113,comp_sim_docnoat:266-275). No trec_eval source file callssetlocale, soatofruns in the "C" locale every C program starts in, and it reads the longest numeric prefix:1,200.5000is 1.0. Three independent C checks read grouped scores (1,200.5000,1,200.0000,1,000.5000) as 1.0.
Hits docA (1200.5) and docB (900.25) are written 1,200.5000 and 900.2500; trec_eval reads 1.0 and 900.25 and ranks docB first. In general a score of 1000 or more reads as its leading digit group (1 to 999): every score from 1000 to 1999.9999 becomes 1.0, and those hits are then ordered by document name, not by Lucene's ranking.
Exposure and likelihood274 words
- Who. People who evaluate relevance with the quality package and an external scorer: the
QueryDrivercommand line,QualityBenchmarkwith aSubmissionReport, or a directreport()call. Robert Muir described this workflow on PR #71 (2021): "generate submission.txt, then i run trec_eval etc from commandline myself". - When. Only for hits scoring 1000 or more. Measured reach with public API: a
BoostQueryof 10000 throughQualityBenchmarkscored 1139.5098 (written1,139.5098); FeatureField linear queries with 10 query terms of impact 120 each scored 1200, written1,200.0000, with no boosts, the custom-parser route the package docs suggest; QueryDriver's ownSimpleQQParserwith default BM25 got there only with a contrived query, the wordneedlerepeated 400 times over 1000 documents of which one contains it: each copy adds the one-term score 2.956, so 400 x 2.956 = 1182.4163 (200 copies: 591.2). Whether realistic long queries of distinct terms reach 1000 was not measured. Ordinary title queries score far less. For scale, upstreamTestQualityRun(title queries, BM25, the 578-line Reuters test file) writes 4,952 submission lines whose highest score is 4.9965. - Effect. With trec_eval: silent. Each affected hit is read as its leading digit group (1 to 999) and sinks below every hit whose parsed score is higher; scores from 1000 to 1999.9999 all tie at 1.0 and are ordered by document name; and the metrics are computed on that order. Strict parsers (Java
Double.parseDouble, Pythonfloat()) reject the line instead. - Not affected. Lucene's search results, the index, and the metrics
QualityBenchmarkcomputes itself with aJudge. - Releases. 2.3.0 (2008) through 10.6.0 and main. Likelihood: rare (a reasoned assessment, not a measured usage rate).
One JUnit test in lucene/benchmark, public API: one stored doc name, SubmissionReport.report of one hit with score 1200.5, then an exact check of the line's fifth column. Deterministic and single-threaded; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.benchmark.quality.utils;

import java.io.PrintWriter;
import java.io.StringWriter;
import java.util.Map;
import org.apache.lucene.benchmark.quality.QualityQuery;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.ScoreDoc;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.search.TotalHits;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSubmissionReportScoreFormat extends LuceneTestCase {

  public void testScoreColumnHasNoGroupingSeparator() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new StringField("docname", "d", Field.Store.YES));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        StringWriter out = new StringWriter();
        SubmissionReport report = new SubmissionReport(new PrintWriter(out), "run");
        TopDocs td =
            new TopDocs(
                new TotalHits(1, TotalHits.Relation.EQUAL_TO),
                new ScoreDoc[] {new ScoreDoc(0, 1200.5f)});
        report.report(new QualityQuery("1", Map.of()), td, "docname", new IndexSearcher(reader));
        report.flush();
        String score = out.toString().trim().split("\\s+")[4];
        // expected the score column 1200.5000 (trec_eval reads it with atof()); actual 1,200.5000
        assertEquals("1200.5000", score);
      }
    }
  }
}
mkdir -p $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/utils
cp $REPRO/TestSubmissionReportScoreFormat.java $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/utils/
cd $LUCENE && ./gradlew :lucene:benchmark:test --tests org.apache.lucene.benchmark.quality.utils.TestSubmissionReportScoreFormat -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
- Expected
- The score column reads
1200.5000, a number trec_eval can parse. - Observed
1,200.5000(expected:<1[]200.5000> but was:<1[,]200.5000>), assertions on and off; trec_eval'satof()reads it as 1.0.
More files, environment, full output187 words
The index holds one document only because report() reads the stored doc name. SubmissionReport uses Locale.ROOT, so the test framework's random default locale does not matter; the seed only satisfies the framework. The assertion pins the existing 4-decimal format without grouping, which both fix options produce, so the same test is the regression test.
The trec_eval consequence (atof("1,200.5000") = 1.0, then a re-sort by score) is not asserted: it comes from trec_eval's source and three independent C atof() checks. Nobody ran the trec_eval binary itself.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
mkdir -p $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/utils
cp $REPRO/TestSubmissionReportScoreFormat.java $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/utils/
cd $LUCENE && ./gradlew :lucene:benchmark:test --tests org.apache.lucene.benchmark.quality.utils.TestSubmissionReportScoreFormat -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
TestSubmissionReportScoreFormat > testScoreColumnHasNoGroupingSeparator FAILED
    org.junit.ComparisonFailure: expected:<1[]200.5000> but was:<1[,]200.5000>
:lucene:benchmark:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false, through the standalone runner on main (-ea, -da) and on the 10.6.0 and 10.5.2 release jars
# with setGroupingUsed(false): :lucene:benchmark:test (SUCCESS): 1 test, assertions on and offQueryDrivercalls the file the "output submission file for trec_eval"; trec_eval reads the score as "a double" withatof().- Grouping was never chosen: the 2007 commit turned it on explicitly only for
QualityStats.log, a summary for people. - No score range is documented, and legal queries (boosts, FeatureField impact queries) score 1000 or more.
The full argument194 words
- The documented purpose is trec_eval.
QueryDriver.java:48(added by LUCENE-2058, commit subject "specify trec_eval output file from commandline");SubmissionReport.java:30"Create a log ready for submission";QualityBenchmark.java:32-41"For submission (e.g. for a contest)". LUCENE-1116 (2008) made the line exactly the 6-column TREC run format. - The reader needs a plain number. trec_eval: "similarity sim (a double)" (
get_trec_results.c:21), parsed withatof(:210).1,200.5000is not a plain decimal number: strict parsers such as JavaDouble.parseDoublereject it, and Catofreads only its leading numeric prefix and returns 1.0. - Grouping was inherited, not chosen. LUCENE-836 (
98fa2d898d18, 2007) builtNumberFormat.getInstance()and set only the fraction digits; the same commit callednf.setGroupingUsed(true)inQualityStats.log(todayQualityStats.java:145-148), the human-readable summary. LUCENE-4199 (2012, "fix more default Locale uses") only changedgetInstance()togetInstance(Locale.ROOT). The issue threads #1911, #2193 and #3134 never discuss the score format. - No test pins it. The only test use,
TestQualityRun.java:84, creates aSubmissionReportonly whenVERBOSEand never parses the output. - Not claimed. The 4-decimal rounding can also tie scores that differ by less than 1e-4, which trec_eval then orders by document name; that is a weaker, separate point.
The devil's-advocate check175 words
The strongest case for "works as designed" (the intended-behaviour verifier and the cross-model reviews, each rating it moderate): the class calls its output a "log" and says "Extend this class and override report(...) to create different reports" (SubmissionReport.java:30-31); in LUCENE-836 (#1911) the author wrote that the "format of submission log can be modified, by extending a logger class"; lucene/benchmark is a developer tool with no compatibility promise; ordinary BM25 scores stay below 1000; and no test pins the format.
Why it fails: the shipped QueryDriver uses the stock class and documents its output as the trec_eval submission file, so the default is the format, not a sample to subclass. Nothing documents a score range. The only explicit format choice in the package (grouping on) is for the human-readable log. And the trigger is legal API that the package docs invite ("Create sophisticated Lucene queries by supplying a different Quality query parser"). The extension point is still a fair reason the defect stayed latent: a user who needed another format could override report(...).
Recommended Turn grouping off (validated, recommended)
Add nf.setGroupingUsed(false) to the SubmissionReport constructor (+1 line). Non-negative scores below 1000 are written exactly as today; larger ones lose only the commas. The repro passes with assertions on and off, and the whole lucene/benchmark module (91 tests) and its format and lint checks pass.
     nf = NumberFormat.getInstance(Locale.ROOT);
     nf.setMaximumFractionDigits(4);
     nf.setMinimumFractionDigits(4);
+    nf.setGroupingUsed(false); // the score column must be a plain number for trec_eval
   }
All options and trade-offs2 options · 382 words
Both options were built in a scratch worktree of 645d4fe14a20 and run with gradle. Option A changes nothing for non-negative scores below 1000, which is why it is recommended; a maintainer may still prefer the explicit format string of option B.
One line in the SubmissionReport constructor (1 file, +1).
     nf = NumberFormat.getInstance(Locale.ROOT);
     nf.setMaximumFractionDigits(4);
     nf.setMinimumFractionDigits(4);
+    nf.setGroupingUsed(false); // the score column must be a plain number for trec_eval
   }
Trade-offs
Smallest change. Every non-negative score below 1000 is written byte for byte as today (0 differences in 1,000,000 random float scores in [0, 1000)); larger scores lose only the commas. Existing run files without such scores stay identical. The comparison and the test cover finite non-negative scores; Lucene scorers may not produce negative ones (LUCENE-7996). A negative score in a hand-built TopDocs also only loses its commas, and infinity and NaN are written as today.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle: the repro fails on stock and passes with the fix, assertions on and off. - The whole
lucene/benchmarkmodule: 91 tests, 0 failures. - Upstream
TestQualityRunwith-Ptests.verbose=true, which writes a submission report: passes, and its 4,952 submission lines are identical to stock's. :lucene:benchmark:check -x test(format, ecjLint, forbiddenApis; main and test sources, the new test included) passes.
Drop the NumberFormat field, its import and the constructor lines, and write String.format(Locale.ROOT, "%.4f", sd[i].score) in report() (1 file, +1/-6).
-              + nf.format(sd[i].score)
+              + String.format(Locale.ROOT, "%.4f", sd[i].score)
Trade-offs
No formatter state, and the intent is explicit. But String.format rounds half-up where DecimalFormat rounds half-even, so exact ties change in the fourth decimal: 305 of 1,000,000 random float scores below 1000 come out different from today (584.28125 gives 584.2813 instead of 584.2812), and about 8.8% of float scores between 1000 and 1,001,000 differ from option A. Harmless for trec_eval, but a few run files change in the last digit. It also writes infinity as Infinity where today's formatter writes ∞ (NaN stays NaN).
What the checks validated
- Same worktree: the repro passes; the quality tests with
-Ptests.verbose=truepass with the same 4,952 submission lines as stock;:lucene:benchmark:check -x testpasses; the standalone runner passes with assertions on and off. - Not run: the whole module with this option.
Search results are not affected; only offline evaluation pipelines that feed this run file to trec_eval or another external scorer get wrong metrics.
Code reading in a hunt unit that compared lucene/benchmark's quality metrics with trec_eval's semantics. While checking the callers of QualityBenchmark, it read the run-file writer next to trec_eval's reader (atof), then confirmed the effect with a public-API JUnit on the stock jar.
The method in full79 words
- Hunt unit. Its main method checked the quality package's metrics against trec_eval's definitions; a side step of its second method read the callers (
QualityBenchmark,SubmissionReport) and compared the written run line with trec_eval's reader. Found 2026-10-28. - Witness. A public-API JUnit on the stock main jar (two tests: a direct report of [1200.5, 900.25] read back the way
atofdoes, andQualityBenchmarkwith aBoostQuery), not a model. - Method tier. Non-formal: code reading and executed tests.
No prior report found (2026-10-28: 196 queries over GitHub issues and PRs including the JIRA archive, the Lucene lists, downstream trackers and the web; the changed files of all 413 open PRs), refreshed 2026-10-30. Only #1911, which created the class, names SubmissionReport.
Searches4 searches
Nobody has reported a grouping separator in the run file's score column or trec_eval misreading it. Closest, not the same bug: LUCENE-2849 (#3923, open, stale since 2011), a decimal-comma crash in QualityStats.log under a non-English default locale (different file, symptom and fix; background only); LUCENE-4199, the Locale.ROOT sweep, which never mentions grouping. The Lucene.NET port formats the score with {0:F4} (no grouping), a port choice, not a report.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Solr, Elasticsearch, OpenSearch, Lucene.NET, trec_eval) | 2026-10-28 | two scripted prior-report searches and manual searches (196 queries in total: class and method names, grouping/thousands separator, comma in score, atof, run file, submission file, trec_eval, the related LUCENE ids); all 156 module:benchmark items | no report; only #1911 contains SubmissionReport; context: #3923, LUCENE-4199, #2193, #3134, #9048, #3263 |
| Open apache/lucene PRs | 2026-10-28 | changed-file lists of all 413 open PRs; the file's commit history | none touches SubmissionReport.java; its last commit is #16255 (2026-06-14, a field rename) |
| dev@, java-user@, issues@, commits@ lists, JIRA, Stack Overflow, the web | 2026-10-28 | list searches (14 quality-package and trec_eval threads read in full); all 49 JIRA benchmark-component bugs; Stack Overflow API; 9 web queries | how-to questions and usage only; nobody mentions commas or misparsed scores |
| GitHub refresh | 2026-10-30 | git ls-remote; issue and PR searches for SubmissionReport and four symptom phrasings; the file at main, 10.6.0 and branch_10_6; changed files of the 33 open PRs updated since 2026-10-28 | nothing new; the formatter is unchanged at main 716d6f216f52 and in 10.6.0; no open PR touches the quality package |
Introduced with the class by LUCENE-836 (98fa2d898d18, 2007-07-27), first released in 2.3.0. LUCENE-4199 (2012) switched to Locale.ROOT but kept grouping. Executed on 15 releases from 2.3.0 to 10.6.0 plus main: all affected; 2.2.0 has no quality package.
Versions tested6 rows
LUCENE-836 created SubmissionReport with NumberFormat.getInstance() and 4 fixed decimals; LUCENE-1116 (2008, also in 2.3.0) made the line the 6-column TREC run format; LUCENE-2058 (2009, first in 3.0.0) made QueryDriver write it as the trec_eval submission file; LUCENE-4199 (2012, first tag 4.0.0-beta) replaced the default locale with Locale.ROOT. Before 4.0 a decimal-comma default locale such as de_DE also cost every score its fraction (999,5000 read as 999.0, run with a current JDK); that part is gone, the grouping comma is not. No release tag from 2.3.0 to 10.5.2 calls setGroupingUsed in the class; 10.6.0 and upstream main 716d6f216f52 have the same formatter.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the one-method test fails, 1,200.5000, assertions on and off (gradle and standalone) |
| 10.6.0, 10.5.2 (release jars) | affected | the one-method test fails the same way |
main a9779ef3c193, ea57360912ed; 9.12.3 | affected | the finder's and verifiers' tests fail, assertions on and off; pass with the fix |
| 2.3.0, 2.9.4, 3.0.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 10.0.0 | version probe | 1200.5 written 1,200.5000 and read back by atof as 1.0; the below-1000 control reads correctly (en_US) |
| 2.2.0 | no such API | the benchmark jar has no quality package; the probe does not compile |
main + setGroupingUsed(false) | fix | 1200.5000, read back as 1200.5; the tests pass |
The finder, an executed cross-model review (OpenAI GPT-5.6), verifiers, an adjudication and a credibility audit agree that it is real; all but one read-only review ran code. This doc's one-method test fails on main, 10.6.0 and 10.5.2 and passes with either fix.
Checks and verdicts346 words
The cross-model reviews used an independent reviewer from another model family (OpenAI GPT-5.6) on main ea57360912ed, where the relevant classes are identical to 645d4fe14a20. Nobody ran the trec_eval binary; its reader behaviour comes from its source plus three independent C atof() checks.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Public-API JUnit (direct report with an atof-style read; QualityBenchmark with a BoostQuery): fails 2 of 2 on main (-ea, -da), ea57360912ed, 10.5.2 and 9.12.3; passes with the fix. |
| cross-model review, refute lens | real (high); intended argument moderate | Own checks on ea57360912ed: direct report, QualityBenchmark + BoostQuery, QueryDriver's SimpleQQParser + BM25 (the word needle repeated 400 times: 1,182.4163), a C atof check; all fail on stock and pass with the fix; upstream TestQualityRun passes with and without it. |
| Independent reproducer | real | Own JUnit (2 triggers and a below-1000 control): 2 of 3 fail on main (-ea, -da), 10.5.2 and 9.12.3, 3 of 3 pass with the fix; read trec_eval's source; own C atof check. |
| Cross-model review, intended lens | real (medium); intended argument moderate | Read-only, ran no Java; a separate run re-ran the finder's test with -da (fails) and with the fix (passes). |
| Devil's advocate | real (high), impact low | Built the works-as-designed case; own JUnit reaches 1200 with FeatureField queries and no boosts: fails on main (-ea, -da) and 10.5.2, passes with the fix. |
| adjudication | confirmed, high (Low) | Re-ran the independent reproduction's test (2 of 3 fail, -ea, -da), the finder's (2 of 2 fail) and the independent reproduction's fix check (3 of 3 pass). |
| credibility audit | keep | Re-ran the finder's test with -da (fails 2 of 2) and its own glibc atof check; kept the trec_eval-binary caveat. |
| this doc | reproduced; both fixes validated | The one-method test on 645d4fe14a20 (gradle and standalone, -ea, -da) and on the 10.6.0 and 10.5.2 jars; both fix options in a scratch worktree; the format comparison. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 598 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,217 words
- Registry title
- SubmissionReport writes scores of 1000 or more with a grouping comma ("1,200.5000") into the TREC run file that QueryDriver documents as the submission file for trec_eval, so trec_eval reads such a score as 1.0 and ranks those hits wrongly
- Area
- benchmark / quality (utils.SubmissionReport, the TREC run-file writer used by QualityBenchmark and QueryDriver)
- Priority
- Low, rank 583: It is the same opt-in benchmark silent-wrong-metric profile as LFV-940 but only for hits scoring 1000 or more, so it moves down from the MoreLikeThis rows to join its benchmark siblings, right after LFV-940.
- Impact class
- silent wrong results
- Impact note
- Only users of the lucene/benchmark quality package who write a TREC run file with SubmissionReport (directly, through QualityBenchmark, or with the QueryDriver command line) and score it with trec_eval or another external tool are hit, and only for hits scoring 1000 or more (boosts, FeatureField or function scores, custom similarities, or very long queries; QueryDriver's default title-only BM25 queries stay far below that): trec_eval silently reads such a score as 1.0 and re-ranks the run, so its metrics come out wrong, and stricter parsers reject the line instead. Lucene's own ranking, the index and the in-process QualityStats numbers are correct.
- Summary
- You evaluate search quality with lucene/benchmark's SubmissionReport, for example through QueryDriver, whose usage text calls the output the 'submission file for trec_eval', and expect the score column of each TREC run line (qid Q0 docno rank score tag) to be a plain number. SubmissionReport formats scores with NumberFormat.getInstance(Locale.ROOT) and never turns grouping off, so a hit scoring 1200.5 is written as '1,200.5000'. trec_eval reads that column with C atof(), which stops at the comma and returns 1.0, and then re-sorts the run by the parsed score, so a run [1200.5, 900.25] is evaluated as [900.25, 1.0], with the top hit moved down, and the reported metrics are silently wrong.
- Introduced
- 98fa2d898d1882f0bee2ccb7401e1135efd05520, LUCENE-836 'Add support for search quality benchmarking.' (author Doron Cohen; Subversion/JIRA-patch era, no PR; migrated as apache/lucene#1911): the constructor built NumberFormat.getInstance() with 4 fraction digits and never turned grouping off [read: git blame on main a9779ef3c193 and a scan of every release tag 2.3.0-10.5.2 in the history clone, none of which calls setGroupingUsed in SubmissionReport; exec: 2.2.0 has no quality API, 2.3.0 already writes '1,200.5000']. Related: LUCENE-1116 (9e65cd554f2e, 2008-01-03, also in 2.3.0) made the line the 6-column TREC run format; LUCENE-2058 (149a0c9b2588, 2009-11-13, first in 3.0.0) made QueryDriver write it as the 'output submission file for trec_eval'; LUCENE-4199 (3d964bea6364, 2012-07-08, first tag 4.0.0-beta) switched to Locale.ROOT and kept grouping. (2007-07-27 (LUCENE-836, author date of 98fa2d898d18))
- First affected version
- 2.3.0 [exec] (released 2008-01-24, the first release with the quality package; 2.2.0 has no quality API [exec: compile error])
- Affected versions
- Every release from 2.3.0 to 10.6.0 (10.6.0 [exec] on its release jars by the bug doc's test, -ea) and main a9779ef3c193 [exec: the finder's JUnit fails 2 of 2 on main (-ea and -da), ea57360912ed, 10.5.2 (-ea) and 9.12.3 (-ea and -da); the independent reproduction's JUnit fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; a version-bridging main() probe shows 1200.5 written as '1,200.5000' and read back by atof() as 1.0 on 2.3.0, 2.9.4, 3.0.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main, with a below-1000 control (999.5) read correctly under en_US] [read: all 141 release tags 2.3.0-10.5.2 in the history clone have the same formatter; 8.8.2-8.11.x are not tagged there, 8.11.4 was executed; upstream main 645d4fe14a20, branch_10x and branch_10_6 have the same formatter]. In 2.3.0-3.6.2 the formatter followed the JVM default locale, so under a decimal-comma locale such as de_DE every score also lost its fraction ('999,5000' read as 999.0) [exec on 2.3.0 and 3.6.2]; LUCENE-4199 removed that part with Locale.ROOT but left the grouping comma. All runs on aarch64 Linux with JDK 25, release jars checked against Maven Central SHA-1s.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only, 196 queries): two scripted prior-report searches (the finder's 48 queries plus 6 web, the follow-up's 81 plus 8 web) over apache/lucene issues and PRs including the migrated JIRA archive, commits, downstream trackers (apache/solr, apache/lucene-solr, elastic/elasticsearch, opensearch-project/OpenSearch, apache/lucenenet, usnistgov/trec_eval), dev@, java-user@, issues@ and commits@ and the web; all 156 items labelled module:benchmark; all 49 JIRA benchmark-component bugs; 14 quality-package and trec_eval list threads read in full; Stack Overflow; the changed-file lists of all 413 open PRs (none touches SubmissionReport.java). The only apache/lucene item whose text contains 'SubmissionReport' is LUCENE-836 (#1911), which created the class. Related, not this bug: LUCENE-2849 (#3923, still open, stale since 2011): a decimal-separator crash in QualityStats.log under a non-English default locale, a different file and defect that Locale.ROOT made obsolete; LUCENE-4199 (the Locale.ROOT sweep, no word on grouping); LUCENE-1116 (#2193) and LUCENE-2058 (#3134, contract evidence). The Lucene.NET port formats the score with '{0:F4}' (no grouping), a port choice, not a report. Not fixed upstream: SubmissionReport.java at upstream main 645d4fe14a20 (2026-10-28) is identical to a9779ef3c193; its last change was #16255 (2026-06-14, a typos rename). Recheck 2026-10-28: GitHub search 'SubmissionReport' still returns only #1911; none of the newest PRs (#16912-#16932, created 2026-10-26) or issues created since 2026-10-26 (#16918-#16935) concerns lucene/benchmark.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28): the one-method repro test through gradle in a scratch worktree and through the standalone runner, assertions on and off, stock and with both fix options (plus the benchmark module's tests and checks with the fixes); the 10.6.0 and 10.5.2 release jars (SHA-1 checked against Maven Central). Earlier hunt runs: maina9779ef3c193andea57360912ed, 9.12.3, and a version probe on 14 releases from 2.3.0 to 10.5.2.SubmissionReport.javais identical at the three main commits and unchanged on upstream main716d6f216f52(2026-10-29).
- Finding record
lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/utils/SubmissionReport.java:29-32 (javadoc 'Create a log ready for submission'), :45-51 (constructor: NumberFormat.getInstance(Locale.ROOT), 4 fraction digits, grouping left on), :70-83 (report: 'qid Q0 docno rank score tag' line, nf.format(sd[i].score))lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:40-48 (usage 'submissionFile: output submission file for trec_eval'), :60-63 (writes it with the stock SubmissionReport)lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/QualityStats.java:148 (nf.setGroupingUsed(true), set explicitly for the human-readable log; the only setGroupingUsed call in lucene/benchmark/src/java)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/utils/SubmissionReport.java:30, :45-51, :62-86 (:68, :82)a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:48, :59-63; lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/QualityBenchmark.java:32-41
- Who is affected
github.com/apache/lucene/pull/71 (LUCENE-9651), comment by rmuir of 2021-04-08 (read 2026-10-30)a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/package-info.java:78; utils/SimpleQQParser.java:72 (escapes the topic text)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:48; utils/SubmissionReport.java:30-31; QualityBenchmark.java:32-41; QualityStats.java:145-148; package-info.java:78; lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/TestQualityRun.java:84
- TestSubmissionReportScoreFormat.java (lucene/benchmark, one test):
repro/LFV-937/src/org/apache/lucene/benchmark/quality/utils/TestSubmissionReportScoreFormat.java(61 lines)
It was made in parallel with this doc; its values come from a probe on 645d4fe14a20 (assertions on and off) and a small reader that applies trec_eval's atof line and its sort to the written lines.
assets/LFV-937/bug.png(598 KB)