The .nvm grammar in the class javadoc is missing two fields that the writer has stored after DocsWithFieldLength since 8.0, so the documented Entry is 3 bytes short and the first value read wrong is NumDocsWithField.
- Norms are one small number per document and field that scoring uses (by default computed from the field's length). Each segment keeps them in two files:
.nvdholds the values, and.nvmholds one Entry per field saying which documents have a norm, how many, and where the values are. - When only some documents have a norm, the set of those documents is written with
IndexedDISI(already in 7.x). Since 8.0 (LUCENE-8585) that set also carries lookup tables (a jump table and a rank index) for fast access, and reading it back needs two more numbers: the jump-table entry count and the dense rank power. - Each codec format documents its files in its class javadoc as a typed grammar, and the default codec's overview sends readers there for the details.
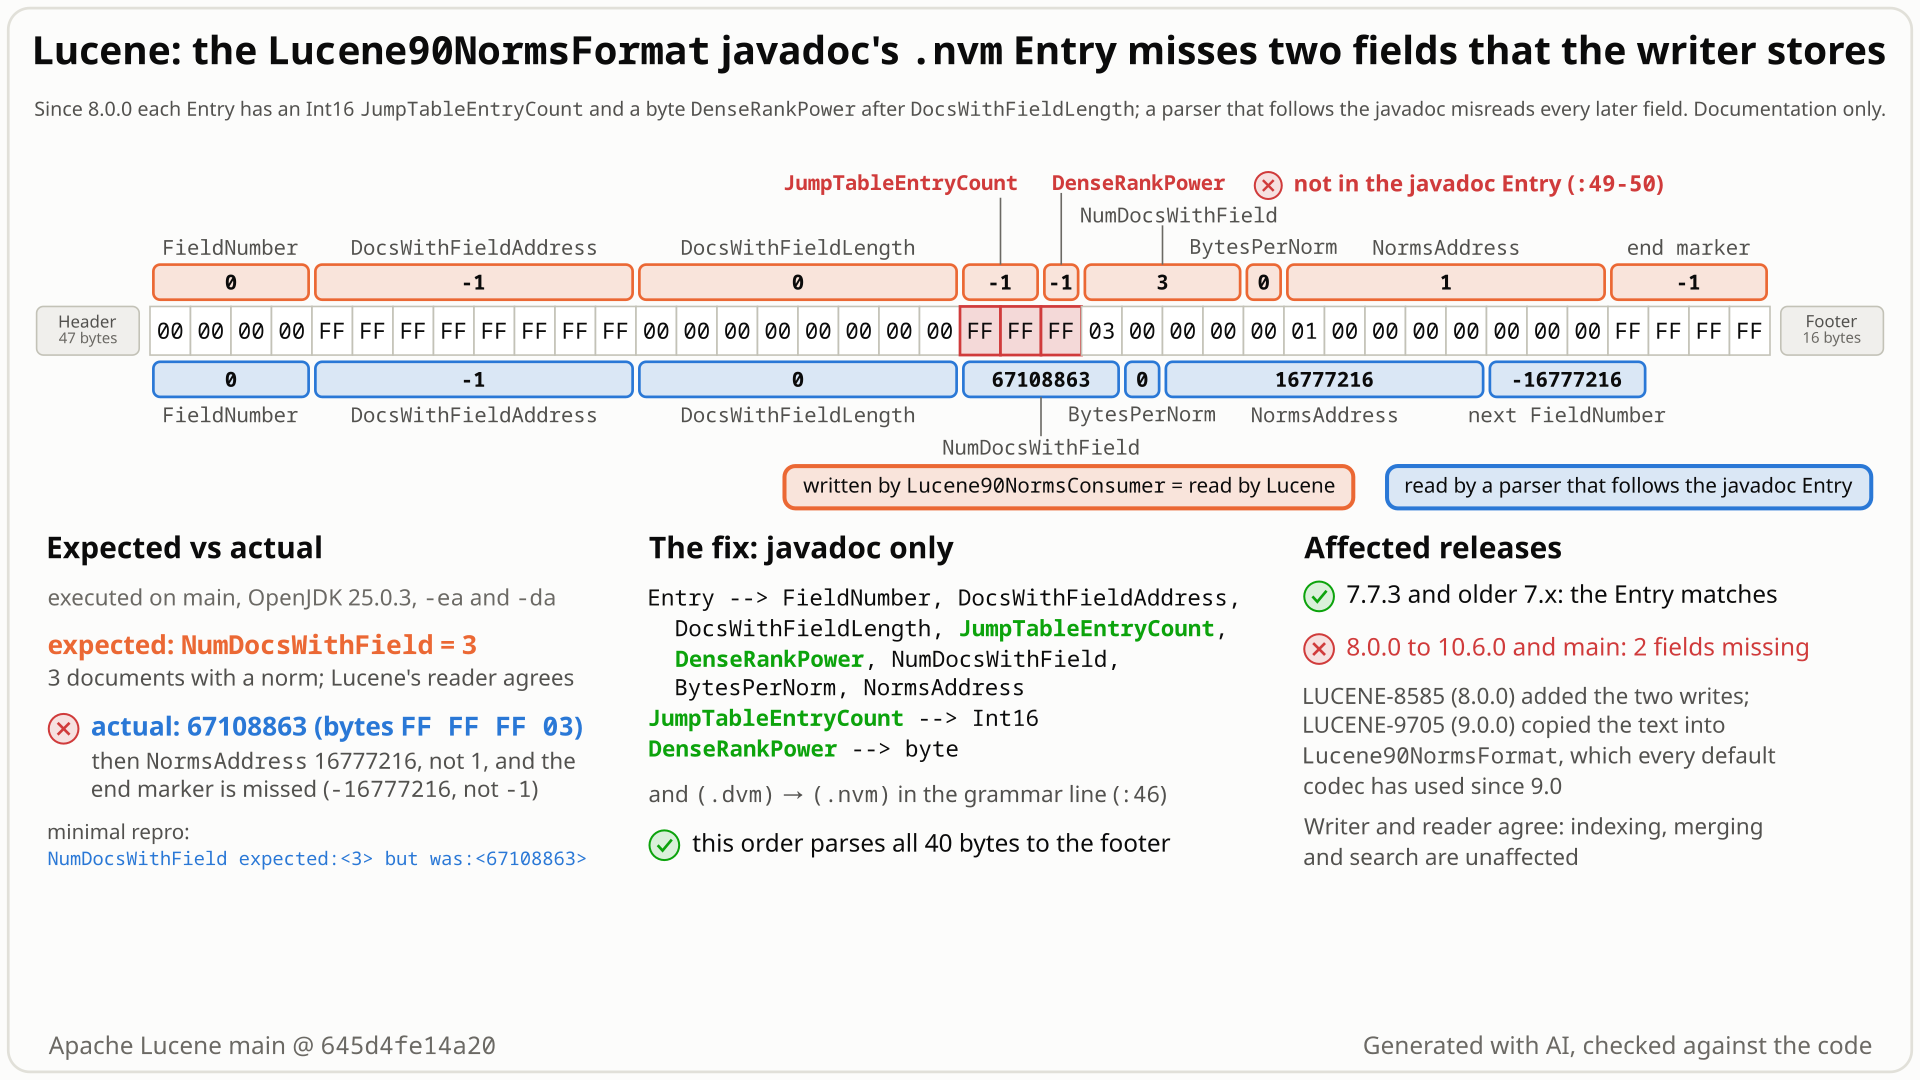
.nvm Entry as the javadoc documents it and as the writer writes it: two fields (3 bytes) are missing after DocsWithFieldLength, so the documented NumDocsWithField reads FF FF FF 03 = 67108863 instead of 3. Select the still to open it at full size. Generated with AI, checked against the code.- You write your own reader for the norms metadata file (
.nvm) from theLucene90NormsFormatjavadoc. It says each field's Entry is FieldNumber (Int32), DocsWithFieldAddress (Int64), DocsWithFieldLength (Int64), NumDocsWithField (Int32), BytesPerNorm (byte), NormsAddress (Int64). - You index 3 documents with one text field (default codec) and read the first Entry of
_0.nvm: FieldNumber 0, then the two Int64 values. You expect NumDocsWithField = 3, since every document has a norm. - You get 67108863. Right after DocsWithFieldLength the writer stores two values the javadoc does not list: the jump-table entry count (Int16, here -1 =
FF FF) and the dense rank power (byte, -1 =FF). Your Int32 readsFF FF FF 03= 0x03FFFFFF. - Every later value is 3 bytes off, in every Entry of every
.nvmfile. Lucene's own reader reads the two values and is unaffected: only the javadoc is wrong, since LUCENE-8585 added the fields in 8.0.0 (2019). The grammar line also calls the file.dvm.
People who read or re-implement .nvm from the javadoc: ports, index inspection or recovery tools, format write-ups. For them the first Entry of every .nvm file the default codec writes goes wrong (any index with a normed field, such as a TextField). Lucene's own indexing, merging and search are unaffected. Priority Low.
Mechanism, terms and numbers545 words
Lucene90NormsFormat is the norms format of every default codec since 9.0. Its class javadoc documents the norms metadata file (.nvm) as a typed grammar: each field's Entry is FieldNumber (Int32), DocsWithFieldAddress (Int64), DocsWithFieldLength (Int64), NumDocsWithField (Int32), BytesPerNorm (byte), NormsAddress (Int64). Since the jump tables of LUCENE-8585 (8.0.0, 2019) the writer also stores the jump-table entry count (Int16) and the dense rank power (byte) right after DocsWithFieldLength, in every Entry, and the reader reads them there. A parser written from the javadoc therefore reads NumDocsWithField from the wrong bytes (67108863 instead of 3 for a 3-document segment) and every later value 3 bytes off. The grammar line also labels the file .dvm, the doc-values extension, and the notes call BytesPerNorm "BytesPerValue". It is a documentation defect: Lucene's writer and reader agree, so nothing goes wrong at runtime; the fix is javadoc only.
* <p>Norms metadata (.dvm) --> Header,<Entry><sup>NumFields</sup>,Footer // :46
* <li>Entry --> FieldNumber, DocsWithFieldAddress, DocsWithFieldLength, // :49
* NumDocsWithField, BytesPerNorm, NormsAddress // :50
* <li>FieldNumber --> {@link DataOutput#writeInt Int32} // :51
* <li>DocsWithFieldAddress --> {@link DataOutput#writeLong Int64}
* <li>DocsWithFieldLength --> {@link DataOutput#writeLong Int64}
* <li>NumDocsWithField --> {@link DataOutput#writeInt Int32}
* <li>BytesPerNorm --> {@link DataOutput#writeByte byte}
* <li>NormsAddress --> {@link DataOutput#writeLong Int64} // :56The notes below it (:59-67) give the sentinels (FieldNumber -1 ends the metadata; DocsWithFieldAddress -2 when no document and -1 when every document has a norm) and call the bytes-per-norm element BytesPerValue (:61-62, and :76 in the .nvd grammar). The file extension is nvm (METADATA_EXTENSION, :103); .dvm is the doc-values metadata file.
:100meta.writeInt(field.number).- In each of the three branches (no document has a norm
:102-106, every document has one:107-111, some do:112-121; the first was only read, no run exercised it):writeLong(docsWithFieldOffset),writeLong(docsWithFieldLength),writeShort(jumpTableEntryCount),writeByte(denseRankPower). In the first two branches both are -1 (:105-106,:110-111); in the sparse branch they are the countIndexedDISI.writeBitSetreturns andIndexedDISI.DEFAULT_DENSE_RANK_POWER= 9 (:116-120). :123writeInt(numDocsWithValue),:126writeByte(numBytesPerValue),:128/:130the single value or the norms offset.close()writes the -1 end marker and the footer (:70-71).
The reader (Lucene90NormsProducer.readFields, :212-240) reads readLong, readLong, readShort (:223), readByte (:224), readInt (:225), readByte (:226), readLong (:238): the writer's order. Because all three branches write the two values, every Entry is 3 bytes longer than documented.
| javadoc says | the writer writes | value |
|---|---|---|
| FieldNumber, Int32 | FieldNumber, Int32 | 0 |
| DocsWithFieldAddress, Int64 | DocsWithFieldAddress, Int64 | -1 (all documents) |
| DocsWithFieldLength, Int64 | DocsWithFieldLength, Int64 | 0 |
| (missing) | JumpTableEntryCount, Int16 | -1 (FF FF) |
| (missing) | DenseRankPower, byte | -1 (FF) |
| NumDocsWithField, Int32 | NumDocsWithField, Int32 | 3 (03 00 00 00) |
| BytesPerNorm, byte | BytesPerNorm, byte | 0 (all 3 norms are equal) |
| NormsAddress, Int64 | NormsAddress, Int64 | 1 (with BytesPerNorm 0: the norm all 3 documents share) |
Reading the documented NumDocsWithField takes the bytes FF FF FF 03, a little-endian 0x03FFFFFF = 67,108,863. Before 9.0 Int32 was big-endian, so on 8.x the same bytes read -256 for a 4-document field (FF FF FF 00).
Exposure and likelihood169 words
- Who. Only people who decode
.nvmthemselves from this javadoc. Lucene's own code never consults it. - Default codec.
Codec.getDefault()isLucene104(Codec.java:59), which usesLucene90NormsFormat(Lucene104Codec.java:76); the codec overview links this class as the norms format (package-info.java:165,:283) and says "Details on each of these are provided in their linked pages" (:188). So the wrong grammar is the documented format of every index written since 9.0.0 that has a field with norms. - What they get. A wrong NumDocsWithField in the first Entry, then garbage for every later value. The misread count is usually absurd (67,108,863 for a 3-document segment), so it costs debugging time rather than silently corrupting anything.
- What nobody gets. Any runtime effect: writer and reader agree, and the upstream
TestLucene90NormsFormatround trip passes. - Scale and priority. Every release from 8.0.0 (March 2019) to 10.6.0 and main; nobody has reported it in more than seven and a half years, which fits the small audience. Impact minor, priority Low.
One JUnit class, one test, no randomness. It indexes 3 documents with one text field (default codec, no compound file) and reads the first Entry of _0.nvm exactly as the javadoc gives it. Put it in lucene/core's tests and run it with gradle.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene90;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestLucene90NormsMetaJavadoc extends LuceneTestCase {

  public void testDocumentedEntrySequence() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()).setUseCompoundFile(false);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (int i = 0; i < 3; i++) {
          Document doc = new Document();
          doc.add(new TextField("f", "a", Field.Store.NO));
          w.addDocument(doc);
        }
      }
      byte[] id = SegmentInfos.readLatestCommit(dir).info(0).info.getId();
      try (IndexInput in = dir.openInput("_0.nvm", IOContext.READONCE)) {
        CodecUtil.checkIndexHeader(in, "Lucene90NormsMetadata", 0, Integer.MAX_VALUE, id, "");
        assertEquals("FieldNumber", 0, in.readInt());
        in.readLong();
        in.readLong();
        // expected 3; actual 67108863, as an undocumented Int16 and byte precede NumDocsWithField
        assertEquals("NumDocsWithField", 3, in.readInt());
      }
    }
  }
}
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90NormsMetaJavadoc -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- NumDocsWithField = 3 (all 3 documents have a norm).
- Observed
- NumDocsWithField expected:<3> but was:<67108863> (0x03FFFFFF), with assertions on and off.
More files, environment, full output246 words
Public API only (IndexWriter, Directory.openInput, CodecUtil.checkIndexHeader, IndexInput reads, the default codec), single thread, in the lucene90 codec test package like the upstream norms tests. It needs 9.1.0 or later (the org.apache.lucene.tests test framework); the same file fails unchanged on the 10.6.0 release.
Regression test: optional. A javadoc fix writes the same bytes, so this test keeps failing after the fix (checked); it is evidence for the defect, not a regression test, and Lucene has no test that compares a format javadoc with the bytes. A regression form is this same test with the corrected Entry: insert assertEquals("JumpTableEntryCount", -1, in.readShort()); and assertEquals("DenseRankPower", -1, in.readByte()); before the NumDocsWithField line (validated, see Suggested fix).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same failure on the 10.6.0 release |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp $REPRO/TestLucene90NormsMetaJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90NormsMetaJavadoc -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
# main 645d4fe14a20, ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90NormsMetaJavadoc -Ptests.seed=DEADBEEF -Ptests.asserts=true
TestLucene90NormsMetaJavadoc > testDocumentedEntrySequence FAILED
    java.lang.AssertionError: NumDocsWithField expected:<3> but was:<67108863>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1011BD98D4109FDB]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.codecs.lucene90.TestLucene90NormsMetaJavadoc.testDocumentedEntrySequence(TestLucene90NormsMetaJavadoc.java:53)
1 test completed, 1 failed
BUILD FAILED

# main 645d4fe14a20, ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90NormsMetaJavadoc -Ptests.seed=DEADBEEF -Ptests.asserts=false
TestLucene90NormsMetaJavadoc > testDocumentedEntrySequence FAILED
    java.lang.AssertionError: NumDocsWithField expected:<3> but was:<67108863>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1011BD98D4109FDB]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.codecs.lucene90.TestLucene90NormsMetaJavadoc.testDocumentedEntrySequence(TestLucene90NormsMetaJavadoc.java:53)
1 test completed, 1 failed
BUILD FAILED

# 10.6.0 release (4ae946e5a9b9), the same file standalone, -ea, seed DEADBEEF
FAIL tests_run=1 failures=1: java.lang.AssertionError: NumDocsWithField expected:<3> but was:<67108863>- The javadoc is an exact grammar: fixed order, a typed
DataOutputlink per element, sentinel values; the codec overview sends readers to it for details. - The same Entry text matched the Lucene70 writer exactly; LUCENE-8585 (2019) added the two writes and kept the old text.
- Upstream has fixed such format-doc drift as bugs before (LUCENE-349, LUCENE-713, LUCENE-3072).
The full argument283 words
- An exact byte grammar. The class lists the elements in order, gives each a fixed type with a link to the
DataOutputmethod that writes it, and gives sentinel values (Lucene90NormsFormat.java:46-67). Nothing marks it as approximate;package-info.java:188sends readers to it for the details. - It used to be exact, and was kept in step with the writer. LUCENE-7475 (
9128bdbaf54, 2016) wrote the Lucene70 Entry with five elements; LUCENE-7485 (2fbbcac580f, 2016) added DocsWithFieldLength to the writer and, in the same commit, to the Entry, giving today's text. It matched that writer; the study's probe parses 7.5.0, 7.7.0 and 7.7.3 files exactly with it. - An oversight in a copy. LUCENE-8585 (
c13645bd4c6, 2019) added the two writes and createdLucene80NormsFormatfrom the Lucene70 javadoc, changing only the title, the codec names and the.nvdDocsWithFieldData link; it also added prose about jump tables to the lucene80 package doc. LUCENE-9705 (4d7b2aebfe0, 2021) copied the text verbatim intoLucene90NormsFormat. No comment on #9631 or on the PR review (apache/lucene-solr#525) mentions the norms grammar. - Upstream wants the current codec documented well. On that PR a reviewer (jpountz) wrote "Only the current codec needs to have a good description if its file formats". Upstream has fixed this kind of drift as bugs: LUCENE-349 (#1427, docs that "leave out several fields that are read from the file"), LUCENE-713 (#1788), LUCENE-3072 (#4145, "fileformats out of date"). The closest precedent is LUCENE-9353: it moved the terms metadata to a new
.tmdfile without touching the grammar (#1473, 2020), and about ten months later a separate commit under the same issue revised the terms-dictionary format documentation to match (5f5d1949e92, #90, 2021).
The devil's-advocate check153 words
The case for "intended" (rated moderate by reviewers): the codec format classes are @lucene.experimental (Lucene90NormsFormat.java:81); the overview says it "attempts to provide a high-level definition of the Apache Lucene file formats" (package-info.java:54, the LUCENE-2946 policy that moved the docs away from bit-for-bit detail); the supported way to read norms is the codec's own NormsProducer; and the round trip is tested. So nobody should parse .nvm by hand.
Why it fails: this class does not give a high-level description, it gives a typed, ordered grammar, and a precise grammar that is wrong is worse than none. In the LUCENE-2946 thread rmuir said detail is "fine (for now)" for "the simple metadata files", which .nvm is. @lucene.experimental is about API stability, not about whether the docs are true, and the Lucene70 version of this very text was exact. At most the argument makes the fix low priority, which it is.
Recommended Correct the .nvm grammar in the Lucene90NormsFormat javadoc (validated)
Javadoc only, one file (+8/-4): add JumpTableEntryCount (Int16) and DenseRankPower (byte) after DocsWithFieldLength, note that both are -1 when no or all documents have a norm, label the file .nvm, and say BytesPerNorm throughout. Validated with gradle: the corrected grammar parses the file to the footer, the norms format tests pass, and javadoc, format and lint checks pass.
All options and trade-offs4 options · 837 words
One fix was validated with gradle in a scratch worktree of 645d4fe14a20; the alternatives were not run.
One file, comments only, +8/-4: add JumpTableEntryCount (Int16) and DenseRankPower (byte) after DocsWithFieldLength in the Entry and the type list; one sentence that they describe the lookup tables of the docs-with-norm set (see IndexedDISI) and are both -1 when no document or every document has a norm; (.dvm) becomes (.nvm); BytesPerValue becomes BytesPerNorm in the notes and the .nvd grammar. The order is the writer's (Lucene90NormsConsumer.java:100-130) and the reader's (Lucene90NormsProducer.java:221-238).
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java
index b0d60c29f3c..e59757c8245 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java
@@ -43,14 +43,16 @@ import org.apache.lucene.store.DataOutput;
* <p>The Norms metadata or .nvm file.
* <p>For each norms field, this stores metadata, such as the offset into the Norms data
* (.nvd)
- * <p>Norms metadata (.dvm) --> Header,<Entry><sup>NumFields</sup>,Footer
+ * <p>Norms metadata (.nvm) --> Header,<Entry><sup>NumFields</sup>,Footer
* <ul>
* <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>Entry --> FieldNumber, DocsWithFieldAddress, DocsWithFieldLength,
- * NumDocsWithField, BytesPerNorm, NormsAddress
+ * JumpTableEntryCount, DenseRankPower, NumDocsWithField, BytesPerNorm, NormsAddress
* <li>FieldNumber --> {@link DataOutput#writeInt Int32}
* <li>DocsWithFieldAddress --> {@link DataOutput#writeLong Int64}
* <li>DocsWithFieldLength --> {@link DataOutput#writeLong Int64}
+ * <li>JumpTableEntryCount --> {@link DataOutput#writeShort Int16}
+ * <li>DenseRankPower --> {@link DataOutput#writeByte byte}
* <li>NumDocsWithField --> {@link DataOutput#writeInt Int32}
* <li>BytesPerNorm --> {@link DataOutput#writeByte byte}
* <li>NormsAddress --> {@link DataOutput#writeLong Int64}
@@ -58,13 +60,15 @@ import org.apache.lucene.store.DataOutput;
* </ul>
* <p>FieldNumber of -1 indicates the end of metadata.
* <p>NormsAddress is the pointer to the start of the data in the norms data (.nvd), or the
- * singleton value when BytesPerValue = 0. If BytesPerValue is different from 0 then there are
+ * singleton value when BytesPerNorm = 0. If BytesPerNorm is different from 0 then there are
* NumDocsWithField values to read at that offset.
* <p>DocsWithFieldAddress is the pointer to the start of the bit set containing documents
* that have a norm in the norms data (.nvd), or -2 if no documents have a norm value, or -1
* if all documents have a norm value.
* <p>DocsWithFieldLength is the number of bytes used to encode the set of documents that have
* a norm.
+ * <p>JumpTableEntryCount and DenseRankPower describe the lookup tables of that set (see
+ * {@link IndexedDISI}); both are -1 if no documents or all documents have a norm value.
* <li><a id="nvd"></a>
* <p>The Norms data or .nvd file.
* <p>For each Norms field, this stores the actual per-document data (the heavy-lifting)
@@ -73,7 +77,7 @@ import org.apache.lucene.store.DataOutput;
* <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>DocsWithFieldData --> {@link IndexedDISI#writeBitSet Bit set of MaxDoc bits}
* <li>NormsData --> {@link DataOutput#writeByte(byte) byte}<sup>NumDocsWithField *
- * BytesPerValue</sup>
+ * BytesPerNorm</sup>
* <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
* </ul>
* </ol>Trade-offs
None for users: no bytes or behaviour change. It does not name the value of DenseRankPower in the sparse case (IndexedDISI.DEFAULT_DENSE_RANK_POWER = 9 today). It leaves two older loose points as they are: the .nvd line uses Data without defining it, and the <Entry>^NumFields line does not show the -1 end marker of the :59 note. The corrected-grammar test checks the dense case only (both values -1); the sparse case was checked by the study's test and the independent reproducer.
What the checks validated
- Stock
645d4fe14a20: the repro fails with assertions on and off. The same test with the corrected Entry (two reads inserted, then read on to the -1 end marker and check the footer position) passes: the fix describes the bytes Lucene already writes. - With the fix: the repro still fails, as expected (no bytes change). The corrected-grammar test plus
TestLucene90NormsFormatandTestLucene90NormsFormatMergeInstance: 63 tests, 6 skipped, 0 failures (in each suitetestNCommonBigandtestSparseNCommonBigare skipped because the nightly test group is off, andtestMergeStabilityby its assumption on this seed's MockRandom postings format); the corrected-grammar test also passes with assertions off. :lucene:core:renderJavadoc,checkGoogleJavaFormatandecjLintMain: BUILD SUCCESSFUL. The rendered page says "Norms metadata (.nvm)" and never ".dvm" or "BytesPerValue"; its Entry lists all eight elements in the writer's order (from the run's log; the fact check re-rendered the page and saw the same).
lucene/backward-codecs/.../lucene80/Lucene80NormsFormat.java carries the same Entry on the 9.x and 10.x branches (10.6.0 tag: lines 46 and 49-50); main removed it (#15712). Its writer added the same two fields in 8.0.0, so the same text change applies there if the fix is backported.
Trade-offs
Touches a frozen read-only codec on a release branch; worth it only if the fix is backported anyway.
The smallest change that makes the grammar match the bytes; leaves the (.dvm) label and the BytesPerNorm / BytesPerValue mix, which are older (4.9.0 and 7.0.0) and harmless on their own.
Trade-offs
Leaves two known slips in the same ten lines; no reason to split them.
Dropping the two values would change the file format of every existing index, and the reader needs them to open the docs-with-norm set (IndexedDISI).
Trade-offs
A format break for a documentation slip; not a real option.
Products built on Lucene read norms through the codec and are unaffected; only tools that parse .nvm themselves from this javadoc misread it.
A semi-formal differential check. Each default-codec file grammar was written down twice, from the class javadoc and from the writer, and one interpreter parsed the bytes of 64 generated indexes with both. The writer grammar parsed every file to the footer; under the javadoc grammar all 112 .nvm files diverged at NumDocsWithField.
The method in full124 words
- Hunt. The grammars are data in a small grammar language; the interpreter compares every parsed value with Lucene's own reader. 64 index configurations (4 fixed and 60 seeded random), 1,114 file checks, assertions on and off.
- Controls. The writer grammar parses every file exactly to the footer (0 failures). Each of 14 single-element mutants of the writer grammar is detected, including dropping the
.nvmJumpTableEntryCount or DenseRankPower, so the check is not vacuous. - Result for
.nvm. 112 of 112 files diverge under the javadoc grammar, always first at Entry NumDocsWithField; the same unit found the sibling file-format javadoc defects of.fnm,.si,segments_N, the terms dictionary and the vector formats. - Minimized to the one-test repro of the Minimal repro section.
No public report found (GitHub issues, PRs and commits with the JIRA archive, the Lucene mailing lists, downstream repositories and the web; 2026-10-28, GitHub rechecked 2026-11-01). The nearest items are the changes that introduced and copied the text (#9631, #10744).
Searches3 searches
Closest hits, none this bug: #9631 / LUCENE-8585 and apache/lucene-solr#525 (made the Entry stale; no comment mentions it); #10744 / LUCENE-9705 and apache/lucene-solr#2392 (copied it); #4020 / LUCENE-2946 (the high-level docs policy); LUCENE-7532 (restored lost codec format docs). Recent javadoc-mismatch issues (#16821-#16828, #16920-#16922, #16927, #16928, #16933-#16935) include none about a file-format grammar. The hunt's LFV-169 concerns the same Int16 field at runtime, a different defect and fix site.
| Where | When | How | Found |
|---|---|---|---|
| Scripted searches | 2026-10-28 | three runs; the follow-up run and the extra run together made 16 GitHub issue/PR, 3 commit and 2 downstream-repository queries, 29 mailing-list queries over dev@, java-user@, issues@ and commits@, 8 JIRA and 6 web queries | 563 hits, none a report of this bug; the closest, LUCENE-9705, was read |
| GitHub, manual | 2026-10-28 | about 20 searches on the identifiers and phrases; the changed files of all 413 open apache/lucene PRs, the 49 updated since 2026-10-26 and the 120 closed since 2026-09-14 | DocsWithFieldLength and BytesPerNorm: 0 issues or PRs; jumpTableEntryCount and denseRankPower: only #9631; no open PR touches the file |
| GitHub, recheck | 2026-11-01 | 10 issue/PR searches (class names, field names, "norms metadata javadoc", "nvm javadoc" and others) and the file's upstream history (new items were not listed) | only #12427, #10744 and #9631, none a report; upstream main f815e679bf6c has the same file blob |
Wrong since 8.0.0: LUCENE-8585 (c13645bd4c6, 2019) added the two fields and kept the old text; LUCENE-9705 (4d7b2aebfe0, 2021) copied it into Lucene90NormsFormat (9.0.0). 7.7.3 is the last release where the grammar matches; every release from 8.0.0 to 10.6.0 and main are affected.
Versions tested7 rows
- Introduced by
c13645bd4c6"LUCENE-8585: Create jump-tables for DocValues at index-time" (Toke Eskildsen, 2019-01-18; the branch_8x cherry-pick5bb6a5b42c4shipped in 8.0.0; issue #9631). - Carried forward by
4d7b2aebfe0"LUCENE-9705: Create Lucene90DocValuesFormat and Lucene90NormsFormat (#2392)" (Julie Tibshirani, 2021-02-22), a verbatim copy; it created the file and is the only upstream commit on that path (git log --followalso lists the Lucene80 and Lucene70 predecessors). - Older cosmetic parts: the
(.dvm)label from LUCENE-5743 (2014:6384ae9fb70on trunk, the branch_4x backport1d9179ed685shipped in 4.9.0); the BytesPerNorm / BytesPerValue mix from9128bdbaf54(LUCENE-7475, 2016, 7.0.0). - Also stale: the frozen backward-codecs
Lucene80NormsFormaton the 9.x and 10.x lines; main removed it (#15712). - Not fixed upstream: upstream main
f815e679bf6c(2026-11-01) has the same file blobb0d60c29f3cas645d4fe14a20and 10.6.0. - Limits: 8.8.2-8.11.3 inferred between executed releases; 7.0.0-7.4.0 read only; all runs on Linux aarch64 with JDK 25.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | repro fails with gradle, assertions on and off (2026-11-01) |
10.6.0 (4ae946e5a9b9) | affected | repro fails (standalone, 2026-11-01) |
| 10.5.2, 10.0.0, 9.12.3 | affected | the finder's test fails; the probe's javadoc grammar fails, the writer layout parses to the footer |
| 9.1.0 | affected | the finder's test fails, and the minimal repro fails in the fact check (2026-11-01); the probe was not run here |
| 9.0.0 | affected | probe: NumDocsWithField 83886079 for 4 documents (first Lucene90NormsFormat) |
| 8.0.0, 8.8.1, 8.11.4 | affected | probe: NumDocsWithField -256 (big-endian FF FF FF 00); first affected 8.0.0 |
| 7.5.0, 7.7.0, 7.7.3 | not affected | probe: the javadoc grammar parses exactly; 7.7.3 last unaffected |
Every check agrees it is real and documentation-only: the finder's grammar check (with a positive control and mutants), an executing cross-model refute review (OpenAI GPT-5.6), an independent reproducer, an intended-lens review, a devil's advocate, the adjudication and the credibility audit. The brief re-ran the repro with gradle and validated the fix.
Checks and verdicts198 words
Each check ran separately. The intended-lens cross-model review could only read; a separate run re-ran the test for it.
| Check | Verdict | What it found |
|---|---|---|
| Finder (grammar check) | reproduced (doc) | 112 of 112 .nvm files diverge at NumDocsWithField; writer grammar 0 failures; 14 of 14 mutants killed. |
| Cross-model refute review (OpenAI GPT-5.6) | real, high (executed) | Own literal-Entry test fails on 4 seeds; writer-layout control passes; TestLucene90NormsFormat 28/0. |
| Independent reproducer | real | Dense, sparse and no-norms fields: 1 of 2 fails on main, 10.5.2, 9.12.3; control ends at the footer. |
| Intended lens (OpenAI GPT-5.6) | real, medium (reading only) | Works-as-designed argument moderate; a separate re-run of the finder's test fails. |
| Devil's advocate | real (doc) | Rejects the high-level-docs and experimental defences; re-run fails. |
| Adjudication | confirmed, high | Documentation defect, impact minor, not security-sensitive; re-ran the independent reproduction's and the finder's tests. |
| Credibility audit | confirmed | Re-ran both tests; minor, not an overclaim. |
| Brief gradle runs | fix validated | Repro fails on main (assertions on and off) and on 10.6.0; the corrected-grammar test passes on stock and fixed builds; with the fix 63 norms tests, 0 failures; javadoc, format and lint checks pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 417 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,409 words
- Registry title
- The file-format javadoc of the default norms format (Lucene90NormsFormat) gives a wrong .nvm grammar: each Entry omits the Int16 jump-table entry count and the byte dense rank power that the writer stores right after DocsWithFieldLength, so a parser that follows it misreads NumDocsWithField and every later field; the grammar line is also labelled '.dvm' (documentation defect; the writer and reader agree)
- Area
- codecs / norms (Lucene90NormsFormat .nvm file-format javadoc vs Lucene90NormsConsumer / Lucene90NormsProducer)
- Priority
- Low, rank 1282: The default norms .nvm grammar is wrong, a documentation-only defect, and norms exist for most text fields.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so indexing, merging, CheckIndex, scoring and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement the .nvm format from this class javadoc (the default codec's package docs link it as the Norms format), and a parser that follows the text misreads NumDocsWithField in the first entry of every .nvm file the default codec writes and then every later field (executed); the Entry has been wrong in every release since 8.0.0 (2019), and no scale or special setting is needed.
- Summary
- You decode the norms metadata (.nvm) file of the default codec by following the Lucene90NormsFormat javadoc, which says each Entry is FieldNumber (Int32), DocsWithFieldAddress (Int64), DocsWithFieldLength (Int64), NumDocsWithField (Int32), BytesPerNorm (byte), NormsAddress (Int64). Since the jump tables of Lucene 8.0 the writer stores two more fields right after DocsWithFieldLength, an Int16 jump-table entry count and a byte dense rank power, so a parser built from the text reads NumDocsWithField as 67108863 instead of 3 (the bytes FF FF and FF of the two missing fields plus the first byte of the real count) and every later field is shifted. Lucene's own reader matches the writer, so nothing breaks at runtime; only the documentation is wrong (it also labels the file '.dvm', the doc-values extension).
- Introduced
- c13645bd4c65f052e7f35df8e33d3dbfe6d7cd58 (master) / 5bb6a5b42c406dcc072554527f59b10ff41f2a8c (branch_8x cherry-pick, the commit that first shipped, in 8.0.0), LUCENE-8585 'Create jump-tables for DocValues at index-time' (now apache/lucene#9631; it landed as a direct commit, the GitHub PR apache/lucene-solr#525 was closed without merge), by tokee: it added meta.writeShort(jumpTableEntryCount) and meta.writeByte(denseRankPower) to the new Lucene80NormsConsumer in all three branches and created Lucene80NormsFormat with the Lucene70 Entry grammar unchanged (it did update the .nvd line and the lucene80 package-info prose about jump tables) [read: git show in the full-history clone; exec: the documented grammar parses on 7.7.3 and fails on 8.0.0]. Carried forward by 4d7b2aebfe01e2a8d0407c179238bb5e092b8d2a (LUCENE-9705, apache/lucene-solr#2392, by jtibshirani), which created Lucene90NormsFormat as a verbatim copy (first release 9.0.0); the file has not changed since. Two older cosmetic parts with their own origin: the '(.dvm)' label comes from 6384ae9fb70 (LUCENE-5743, by rmuir, 4.9.0) and the BytesPerNorm (Entry) / BytesPerValue (notes, .nvd grammar) naming mix from 9128bdbaf54 (LUCENE-7475, by jpountz, 7.0.0) (2019-01-18 (author date of c13645bd4c6 and of the branch_8x cherry-pick 5bb6a5b42c4, committed 2019-01-21); 2021-02-22 (4d7b2aebfe0, the copy into Lucene90NormsFormat); cosmetic parts 2014-06-10 (6384ae9fb70, '.dvm' label) and 2016-10-05 (9128bdbaf54, BytesPerNorm naming))
- First affected version
- 8.0.0 [exec] (the missing Entry fields; the last unaffected release is 7.7.3 [exec], whose Lucene70NormsFormat grammar matched its writer exactly); 9.0.0 [exec] is the first release of Lucene90NormsFormat; the '.dvm' label is older (4.9.0 [read])
- Affected versions
- every release from 8.0.0 through 10.6.0 (10.6.0 run as its release revision, the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream [exec: a public-API history probe that parses the .nvm with the javadoc grammar and with the writer layout fails the javadoc grammar on 8.0.0, 8.8.1, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) while the writer layout parses exactly to the footer, and passes it on 7.5.0, 7.7.0 and 7.7.3; the finder's JUnit fails 1 of 1 on 9.1.0, 9.12.3, 10.0.0, 10.5.2, the branch_10_6 head and main (-ea and -da); the independent reproduction's JUnit fails 1 of 2, with its writer-layout control passing, on main (-ea and -da), 10.5.2 and 9.12.3; read: the releases in between from the tags; 8.8.2-8.11.3 inferred between executed releases, the 8.11.4 sources jar has the same text]. The stale Entry lives in Lucene80NormsFormat (default in 8.0-8.11, and the frozen backward-codecs copy in every 9.x and 10.x release; removed from main by #15712) and Lucene90NormsFormat (9.0 to main, used by every default codec since). Before 9.0 an Int32 is big-endian, so for a 4-document field the documented NumDocsWithField reads -256 there and 83886079 since 9.0: the same FF FF FF bytes in the other byte order. Caveats: all runs used JDK 25 on Linux aarch64; upstream main 645d4fe14a20 (2026-10-28) still carries the text [read]; the zero-docs writer branch was read in code only
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: three scripted prior-report searches over GitHub issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive, downstream repositories and the web; about 20 manual GitHub searches on the identifiers and phrases (DocsWithFieldLength and BytesPerNorm: 0 issues or PRs; jumpTableEntryCount and denseRankPower: only #9631); all 413 open apache/lucene PRs scanned by changed files, the 49 PRs updated since 2026-10-26 re-fetched with full file lists, the 120 PRs closed since 2026-09-14 (none touches a norms file); the file's history on main, branch_10x, branch_10_6 and branch_11x). Nearest items, not the same bug: #9631 / LUCENE-8585 and apache/lucene-solr#525 (the change that made the Entry stale; 56 issue and 72 PR comments read, none mentions the norms javadoc), #10744 / LUCENE-9705 and apache/lucene-solr#2392 (copied the text into Lucene90), #4020 / LUCENE-2946 (2011 policy for high-level file-format docs; detail kept for simple metadata files), LUCENE-7532 (restored lost codec file-format docs, precedent). Context: a stream of javadoc-mismatch issues (#16821-#16828, #16920-#16922, #16927, #16928, #16933-#16935); none concerns a file-format grammar. Recheck (2026-10-28): none of the 29 apache/lucene issues and PRs created since 2026-10-26 is about the .nvm or any file-format grammar; 'Lucene90NormsFormat', 'NormsFormat javadoc', 'jumpTableEntryCount' and 'Norms metadata' return only old unrelated items (#12427, #10744, #4680, #4761, #4702, #9631, #5127); the files of the 24 PRs opened since 2026-10-26 touch no norms file except #16911 (decommissions branch_10x by deleting every file, including the backward-codecs Lucene80NormsFormat; not a fix); by author date the file's only commit on upstream main is 4d7b2aebfe0 (2021-02-22); upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 46 and 49-50. Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20: the repro with gradle in a scratch worktree, assertions on and off, then the javadoc fix with the norms format tests and the javadoc, format and lint checks (2026-11-01); the 10.6.0 release4ae946e5a9b9standalone (2026-11-01). The study ran on maina9779ef3c193(the norms format, writer, reader and codec overview files are identical to645d4fe14a20) and with a public-API probe on 7.5.0, 7.7.0, 7.7.3, 8.0.0, 8.8.1, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java:46 ('Norms metadata (.dvm)'), :49-50 (Entry), :51-56 (types), :61, :76 (BytesPerValue), :81 (@lucene.experimental); Lucene90NormsConsumer.java:100 (field number), :103-120 (three branches; writeShort jumpTableEntryCount :105/:110/:119, writeByte denseRankPower :106/:111/:120), :123 (numDocsWithValue), :126 (bytes per value), :128/:130 (min or norms offset), :70 (-1 end marker); Lucene90NormsProducer.java:223-226 (reader mirrors the writer); identical at Lucene main ea57360912ed (compared 2026-10-28)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:54 ('a high-level definition'), :165 and :283 (link Lucene90NormsFormat), :188 ('Details on each of these are provided in their linked pages'); lucene104/Lucene104Codec.java:76 (default codec uses Lucene90NormsFormat); lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene80/ on a9779ef has doc values only (no norms classes)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java:46, :49-56, :59-67, :76, :103lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsConsumer.java:70-71, :100-130lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsProducer.java:212-240lucene/core/src/java/org/apache/lucene/codecs/lucene90/IndexedDISI.java:109 (DEFAULT_DENSE_RANK_POWER = 9)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsConsumer.java:126-138 (BytesPerNorm 0 when min == max; NormsAddress is then the value)a Lucene clone tag releases/lucene-solr/7.7.3: lucene/core/src/java/org/apache/lucene/codecs/lucene70/Lucene70NormsConsumer.java:107 (IndexedDISI.writeBitSet in 7.x)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/Codec.java:59lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java:76lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:165, :188, :283
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsFormat.java:46-67, :81lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:54, :188
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsConsumer.java:100-130lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90NormsProducer.java:221-238a Lucene clone tag releases/lucene/10.6.0: lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene80/Lucene80NormsFormat.java:46, :49-50
- TestLucene90NormsMetaJavadoc.java (one test, lucene/core tests):
repro/LFV-938/src/org/apache/lucene/codecs/lucene90/TestLucene90NormsMetaJavadoc.java(57 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-938/bug.png(417 KB)