A javadoc that documents the byte layout of the default codec's terms files lists one element that is never written and leaves out one that is.
- The default codec stores each field's terms in a block tree:
.timholds the term blocks,.tipa trie index into them, and.tmdsmall per-field metadata (term counts, statistics, where each field's trie lives). - Each file starts with a header (codec magic, name, version, segment id and suffix) and ends with a checksum footer. The postings format also writes a small header of its own, the PostingsHeader, into one of these files.
- The
Lucene103BlockTreeTermsWriterclass javadoc gives each file's layout as a grammar, element by element, with VInt/VLong types.Lucene104PostingsFormatsends readers there for the details.
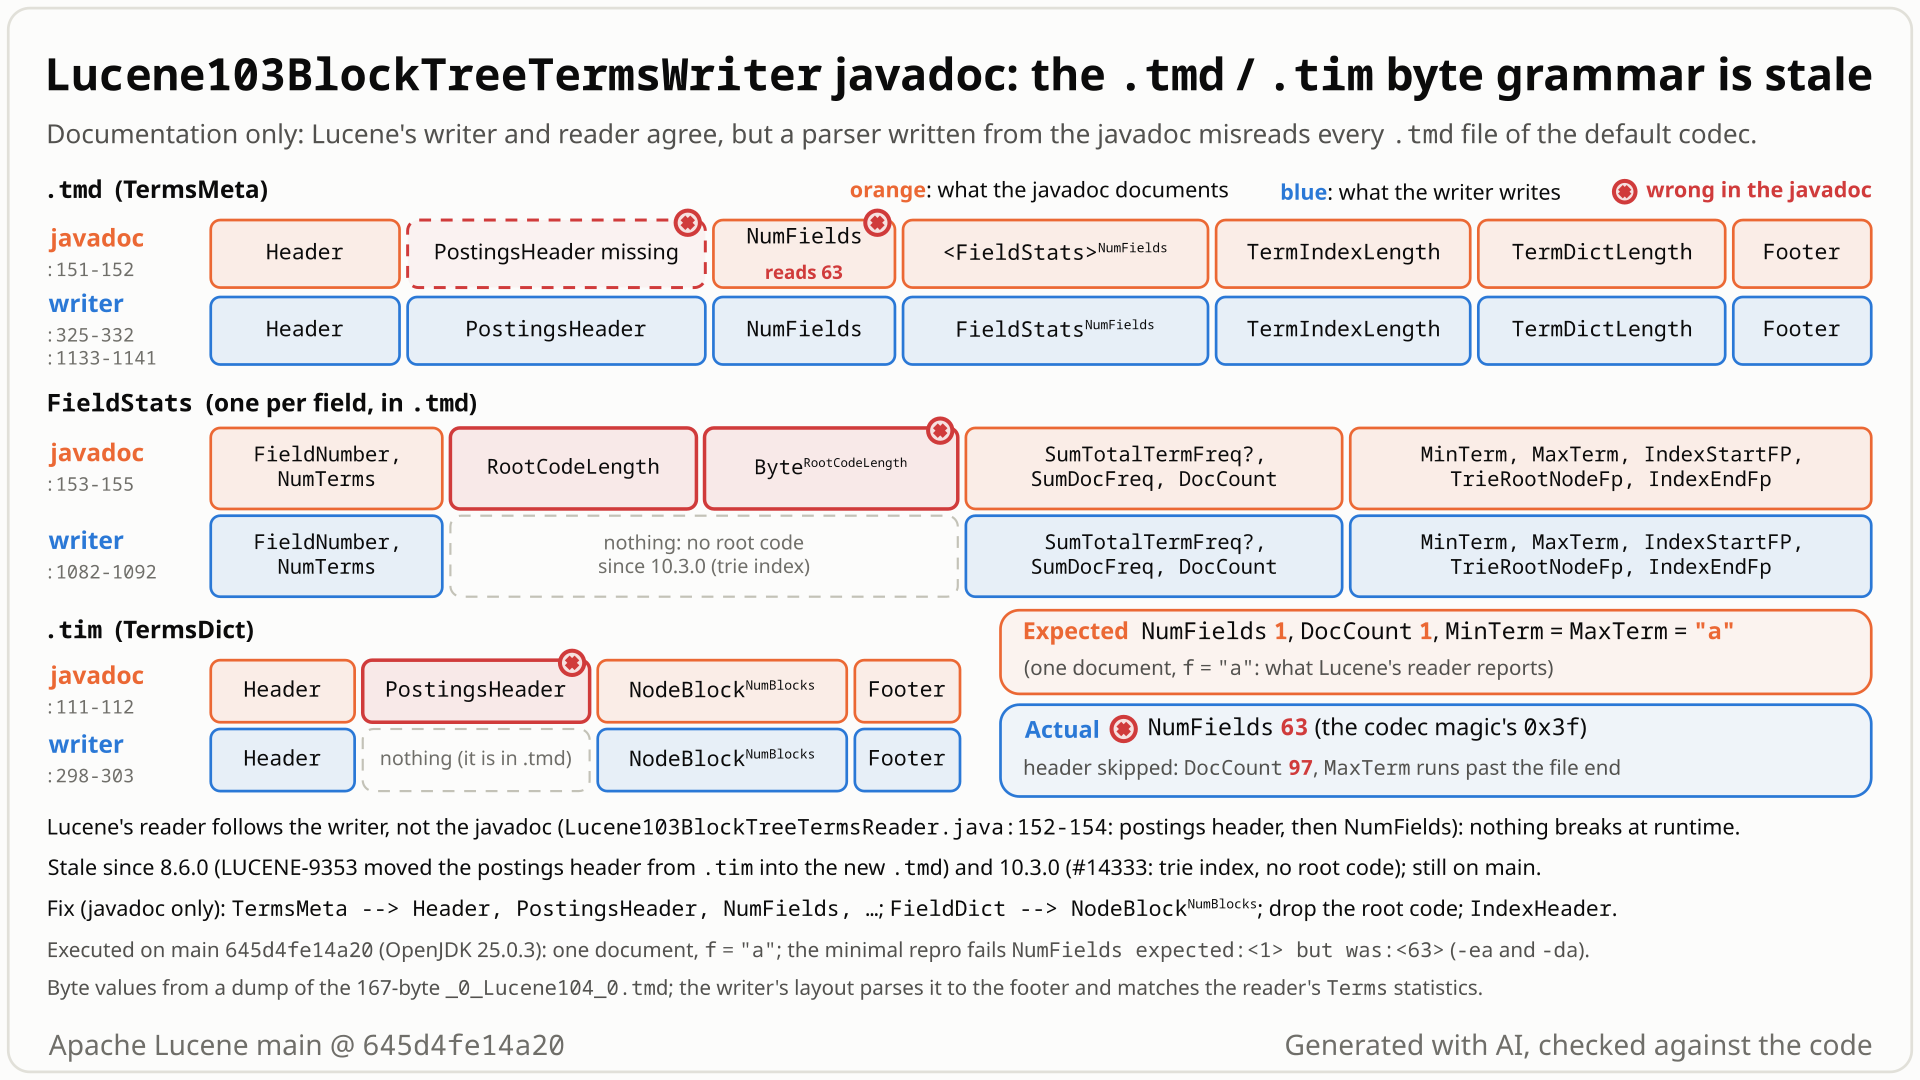
.tmd file as the javadoc describes it and as the writer writes it: the postings header between the header and NumFields, and FieldStats without a root code. Read with the javadoc, NumFields becomes 63. Select the still to open it at full size. Generated with AI, checked against the code.- You write a reader for the default codec's terms metadata file (
.tmd) from theLucene103BlockTreeTermsWriterjavadoc: Header, NumFields, then per field FieldNumber, NumTerms, RootCodeLength, the root code bytes, SumTotalTermFreq, ... - You index one document with one text field and expect NumFields = 1 right after the 55-byte header.
- You read 63. That is 0x3F, the first byte of the postings format's own header (codec magic 0x3FD76C17, name
Lucene104PostingsWriterTerms, block size 256), which the writer puts here, once. The javadoc instead puts this PostingsHeader at the start of every field in.tim, where nothing writes it. - Skip that header and the next stale element follows: with 3 documents ("a a a b", "b c", "c d e"), the documented RootCodeLength reads 9, which is really SumTotalTermFreq, and after 9 bytes of "root code" the documented SumTotalTermFreq reads 82, the first byte of the
.tipfile length. The trie terms index of 10.3.0 writes no root code. - Lucene's own reader follows the writer, so indexing, merging and search are fine. Only the documentation is wrong: since 8.6.0 for the header, since 10.3.0 for the root code.
People who read or re-implement the default codec's .tim/.tmd format from this javadoc: format inspectors, ports, recovery tools. Every .tmd file the default codec writes shows it at NumFields, on 8.6.0 to 10.6.0 and main. Lucene itself, and every application using its API, is unaffected; no public report was found.
Mechanism, terms and numbers718 words
The class javadoc of Lucene103BlockTreeTermsWriter describes the default codec's terms files as typed element lists (a grammar), and Lucene104PostingsFormat sends readers there for the format details. Two parts no longer match the writer. The .tmd grammar says Header, NumFields, <FieldStats>^NumFields, ..., but the writer puts the postings writer's header (an IndexHeader plus the packed block size, 256) between the header and NumFields; the javadoc instead documents that PostingsHeader at the start of every .tim field, where nothing writes it (stale since LUCENE-9353 moved it to the new .tmd file in 8.6.0). And each FieldStats still lists RootCodeLength, Byte^RootCodeLength, which the trie terms index of 10.3.0 no longer writes: #14333 replaced the FST elements after IndexStartFP (FSTHeader, FSTMetadata) with TrieRootNodeFp, IndexEndFp and kept the root code lines. A parser that follows the text reads NumFields as 63, the first byte of the codec magic, and, with that header skipped, takes SumTotalTermFreq for RootCodeLength. Lucene's reader follows the writer, so only the documentation is wrong. Minor: the headers are documented as CodecHeaders but are IndexHeaders. Separate and much older: the .tim term-block productions are simplified, not byte-exact; this page and the suggested fix do not cover them.
:111-112:TermsDict (.tim) --> Header, FieldDict^NumFields, Footer;FieldDict --> PostingsHeader, NodeBlock^NumBlocks.:151-155:TermsMeta (.tmd) --> Header, NumFields, <FieldStats>^NumFields, TermIndexLength, TermDictLength, Footer;FieldStats --> FieldNumber, NumTerms, RootCodeLength, Byte^RootCodeLength, SumTotalTermFreq?, SumDocFreq, DocCount, MinTerm, MaxTerm, IndexStartFP, TrieRootNodeFp, IndexEndFp.:159:NumFields,FieldNumber,RootCodeLength,DocCount --> VInt;:170: "RootCode points to the root block for the field.":121,:156,:187:Header --> CodecHeader(CodecUtil#writeHeader), and the.timnote at:131("Header is a CodecHeader storing the version information ..."): a minor wording point.
:298-330:CodecUtil.writeIndexHeaderfor.tim,.tipand.tmd(an IndexHeader is a CodecHeader plus the segment id and suffix: 55 bytes for.tmd).:332:postingsWriter.init(metaOut, state); // have consumer write its format/header. The default postings writer writes an IndexHeaderLucene104PostingsWriterTermsandwriteVInt(BLOCK_SIZE)(256) into the stream it is given, the.tmd(Lucene104PostingsWriter.java:223-227). Nothing goes into.tim, here or per field.:1082-1092: per field, FieldNumber, NumTerms, SumTotalTermFreq (unless DOCS-only), SumDocFreq, DocCount, MinTerm, MaxTerm, thenroot.index.save(...), which writes IndexStartFP, the root node fp and IndexEndFp (TrieBuilder.java:263-268). No root code.:1133-1141(close): NumFields, the buffered FieldStats, the.tipand.timlengths and the footer, so in the file the postings header sits between the.tmdheader and NumFields.
Lucene103BlockTreeTermsReader.java:145-152 checks the .tmd header and calls postingsReader.init(metaIn, state); :154 reads numFields; :160-179 read the FieldStats without a root code; FieldReader.java:80-82 read the three trie pointers. The format has one version (VERSION_START = VERSION_CURRENT = 0, :73-76), so no version writes a root code.
.tmd, right after its header:3f d7 6c 17 1c 'Lucene1...', the codec magic and the 28-character name of the postings writer's header; then the block size 256 and NumFields 1.- FieldStats for the 3 documents
"a a a b","b c","c d e":00 05 09 07 03 01 61 01 65 38 00 42 | 52 00 ..= FieldNumber 0, NumTerms 5, SumTotalTermFreq 9, SumDocFreq 7, DocCount 3, MinTerma, MaxTerme, IndexStartFP 56, TrieRootNodeFp 0, IndexEndFp 66, then TermIndexLength 82. Read with the javadoc, 9 becomes RootCodeLength and 82 SumTotalTermFreq. .tim, right after its header, continues with the first term block (0b 2c 61 62 63 64 65 ...); the codec magic occurs once in.tim, in its own header. (The block is not read as documented either: its first VInt0b= 11 is five entries plus the last-block flag,5 << 1 | 1(:735-742), not an EntryCount of 11; see Suggested fix.)
LUCENE-9353 (8.6.0) changed postingsWriter.init(termsOut, state) to init(metaOut, state), moving the header from .tim to the new .tmd, and left the javadoc as it was. #14333 (10.3.0) created Lucene103BlockTreeTermsWriter from Lucene90BlockTreeTermsWriter and swapped the FST elements of FieldStats (FSTHeader, FSTMetadata, after the IndexStartFP it kept) for TrieRootNodeFp, IndexEndFp, but kept RootCodeLength, Byte^RootCodeLength.
Exposure and likelihood271 words
- Who is hit. Anyone decoding
.tim/.tmdbytes from the documentation. Lucene sends them there:Lucene104PostingsFormat.java:97("See {@link Lucene103BlockTreeTermsWriter} for more details on the format") and:149for.tip. The file-format overview links its "Term dictionary" item (lucene104/package-info.java:154, "Details on each of these are provided in their linked pages",:188) and the.timand.tiprows of its extension table (:258-265) toLucene104PostingsFormat, which sends readers on here..tmdis not in that table at all, so this javadoc is the only place its layout is given. - Default vs opt-in. The default postings format: its block-tree writer calls
postingsWriter.init(metaOut, state)unconditionally in its constructor (:332) andLucene104PostingsWriter.initalways writes the header (:223-227), so every.tmdfile written this way has it before NumFields (read in the code; seen in all 125.tmdfiles of the hunt's sweep). No setting or scale is needed. Other postings formats plugged into the block tree write their own PostingsHeader there; not run. - How it shows. Not subtle (63 fields, garbage statistics), but the text gives no hint where the extra bytes come from:
Lucene104PostingsFormatdescribes the PostingsHeader under its.timheading, so a reader looks in the wrong file. - What it does not do. No wrong results, no runtime path, no index change: Lucene's code never reads the javadoc grammar. Lucene's
TestTrie(4 tests) andTestLucene104PostingsFormat(34 tests, 3 skipped) pass (this doc's gradle run, with the javadoc-only fix applied; the refute reviewer also ran one method of each). - How many. A small audience; the searches found no public report since 8.6.0 (2020).
One JUnit test, one document with one text field, public API only. It checks the .tmd header and reads the next VInt, which the javadoc calls NumFields. Deterministic, single thread, about 1.5 s; the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene103.blocktree;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestLucene103BlockTreeTermsMetaJavadoc extends LuceneTestCase {

  public void testDocumentedTermsMetaSequence() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()).setUseCompoundFile(false);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        Document doc = new Document();
        doc.add(new TextField("f", "a", Field.Store.NO));
        w.addDocument(doc);
      }
      byte[] id = SegmentInfos.readLatestCommit(dir).info(0).info.getId();
      try (IndexInput in = dir.openInput("_0_Lucene104_0.tmd", IOContext.READONCE)) {
        CodecUtil.checkIndexHeader(
            in, "BlockTreeTermsMeta", 0, Integer.MAX_VALUE, id, "Lucene104_0");
        // expected 1; actual 63, the first byte of the undocumented PostingsHeader written here
        assertEquals("NumFields", 1, in.readVInt());
      }
    }
  }
}
cp TestLucene103BlockTreeTermsMetaJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene103/blocktree/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene103.blocktree.TestLucene103BlockTreeTermsMetaJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- NumFields reads 1 (one indexed field), as the javadoc says it follows the header.
- Observed
NumFields expected:<1> but was:<63>, with assertions on and off: 63 is the first byte of the postings header the writer puts there.
More files, environment, full output274 words
- The test sits in the block-tree test package, like Lucene's own codec tests, and uses only public API (
IndexWriter,SegmentInfos,CodecUtil,IndexInput). It checks the header as an IndexHeader, which is what the writer writes; the javadoc's "CodecHeader" is the minor wording point. - Results: fails 1 of 1 on main
645d4fe14a20with assertions on and off, through gradle and standalone (1.43 s; also with a second seed. The test body uses no randomness; the test framework still randomizes its environment per seed, and the asserted byte, the first byte of the codec magic, is the same under both seeds). - It shows the first stale element only. The root-code element is reached only after skipping the misplaced header; the hunt's test (3 documents
"apple banana","banana cherry","cherry date apple") shows it on maina9779ef3c193(no codec change up to645d4fe14a20):SumTotalTermFreq (after RootCodeLength=7) expected:<7> but was:<101>, next toNumFields expected:<1> but was:<63>and.tim PostingsHeader magic expected:<1071082519> but was:<162267489>(1071082519 is the codec magic0x3FD76C17). - As a regression test: this test cannot guard the javadoc, because it transcribes a copy of the text and the bytes do not change with the fix. A regression form is this same test rewritten to the corrected grammar, which passes on main.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestLucene103BlockTreeTermsMetaJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene103/blocktree/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene103.blocktree.TestLucene103BlockTreeTermsMetaJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestLucene103BlockTreeTermsMetaJavadoc > testDocumentedTermsMetaSequence FAILED
    java.lang.AssertionError: NumFields expected:<1> but was:<63>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:2E92ECB75904EC9A]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
at org.apache.lucene.codecs.lucene103.blocktree.TestLucene103BlockTreeTermsMetaJavadoc.testDocumentedTermsMetaSequence(TestLucene103BlockTreeTermsMetaJavadoc.java:49)- The
.tmdgrammar is a short, typed element list, and it lists an element no version writes:Lucene103has one format version, without a root code. - Its own note calls the PostingsHeader "arbitrary per-file data": one per file, as written in
.tmd, not one per.timfield. - Committers fixed this grammar before: #90 (2021) rewrote it after
.tmdwas introduced.
The full argument182 words
- Contract text. Every
.tmdelement has a primitive type linked to aDataOutputmethod (Lucene103BlockTreeTermsWriter.java:157-161). "This document defines the index file formats used in this version of Lucene" (lucene104/package-info.java:50); "Details on each of these are provided in their linked pages" (:188). - Self-contradiction. "PostingsHeader and TermMetadata are plugged into by the specific postings implementation: these contain arbitrary per-file data (such as parameters or versioning information) and per-term data" (
:136-138). - No version writes a root code.
VERSION_START = VERSION_CURRENT = 0(Lucene103BlockTreeTermsReader.java:73-76); the FieldStats line lists the FST-era RootCode next to its trie replacementTrieRootNodeFp. - Precedent. #90 ("LUCENE-9353: revise format documentation of Lucene90BlockTreeTermsWriter", 2021) rewrote this grammar after LUCENE-9353; its review discussed which FieldStats element is the optional one, and it was approved as a fix ("Thank you @mocobeta for fixing this!"). #823 (2022) restructured the
.timline. #15619 / #15625 (2026-01) fixed a stale block-size sentence inLucene104PostingsFormat. - Nothing in the materials reviewed (the related PRs, JIRA issues and review threads, and CHANGES) says the grammar is meant to be approximate.
The devil's-advocate check291 words
Strongest case for "intended" (the refute reviewer, the GPT intended lens and this doc's cross-model fact check: moderate, not decisive; the intended-behaviour verifier: weak): the codec classes are @lucene.experimental (Lucene103BlockTreeTermsWriter.java:209); the overview "attempts to provide a high-level definition" (package-info.java:54), the policy of LUCENE-2946 (#4020, 2012, "change file format documentation from bit-for-bit to highlevel"); PostingsHeader/TermMetadata are italic plug-in placeholders, so their position could be schematic; and the page is not bit-exact elsewhere either: the .tim term-block productions leave out flag bits, a suffix-lengths section and the compression and run-length coding the writer uses (see Suggested fix; pointed out by the cross-model fact check of this doc).
Why it fails: "high-level" allows leaving detail out or simplifying an encoding (the .tip trie is deliberately {trie<byte[]>} with a TODO; the .tim blocks are simplified); it does not cover listing elements that no writer of this format writes, or leaving out a header that every .tmd file of the default codec carries. The LUCENE-2946 thread does not settle it: rmuir found exact docs fine "for the simple metadata files" and wanted a high-level explanation for the terms dictionary; that .tmd, added in 2020, is a small metadata file of the first kind is this page's reading. The placeholder reading does not explain the .tim position either: the current block-tree writer always passes the .tmd output to postingsWriter.init (:332), so a header written there lands once in .tmd, never in a per-field slot of .tim (the base class still names that argument termsOut and says implementations "typically" write a header, PostingsWriterBase.java:45-49). @lucene.experimental warns that the format may change between releases, not that the current page may be wrong. Every verifier and the adjudication rejected the "intended" reading.
Recommended A. Correct the stale .tmd, .tim and .tip lines in the Lucene103BlockTreeTermsWriter class javadoc (build-checked; validated for the .tmd layout only)
Correct the stale lines in the Lucene103BlockTreeTermsWriter javadoc: .tmd becomes Header, PostingsHeader, NumFields, ...; the .tim FieldDict loses its PostingsHeader and FieldStats its root code; headers become IndexHeaders. Javadoc only, one file; the simplified .tim term-block productions stay as they are. Checked: the corrected repro parses .tmd exactly to its footer; core's checks and javadoc build pass.
All options and trade-offs4 options · 1,231 words
Four ways to resolve it. A is the fix; B and C are optional add-ons for the two other places with the same stale text; D is the alternative, not recommended.
Backport: the same stale lines are on branch_11x and branch_10_6 (line 112 and two RootCodeLength lines each, read on GitHub 2026-11-01); branch_10x was decommissioned on 2026-10-29 (#16911). A dry run of the diff on those branches was not done.
A. Correct the stale .tmd, .tim and .tip lines in the Lucene103BlockTreeTermsWriter class javadoc (build-checked; validated for the .tmd layout only) (recommended)
In Lucene103BlockTreeTermsWriter.java: FieldDict --> NodeBlock^NumBlocks (:112); TermsMeta (.tmd) --> Header, PostingsHeader, NumFields, <FieldStats>^NumFields, TermIndexLength, TermDictLength, Footer (:151-152); FieldStats without RootCodeLength, Byte^RootCodeLength (:153-155), RootCodeLength out of the VInt list (:159) and the RootCode note removed (:170); Header --> {@link CodecUtil#writeIndexHeader IndexHeader} (:121, :131, :156, :187). 11 insertions, 13 deletions.
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java
index 4e85a69b881..3035f4dddac 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java
@@ -109,7 +109,7 @@ import org.apache.lucene.util.compress.LowercaseAsciiCompression;
*
* <ul>
* <li>TermsDict (.tim) --> Header, FieldDict<sup>NumFields</sup>, Footer
- * <li>FieldDict --> <i>PostingsHeader</i>, NodeBlock<sup>NumBlocks</sup>
+ * <li>FieldDict --> NodeBlock<sup>NumBlocks</sup>
* <li>NodeBlock --> (OuterNode | InnerNode)
* <li>OuterNode --> EntryCount, SuffixLength, Byte<sup>SuffixLength</sup>, StatsLength, <
* TermStats ><sup>EntryCount</sup>, MetaLength,
@@ -118,7 +118,7 @@ import org.apache.lucene.util.compress.LowercaseAsciiCompression;
* < TermStats ? ><sup>EntryCount</sup>, MetaLength, <<i>TermMetadata ?
* </i>><sup>EntryCount</sup>
* <li>TermStats --> DocFreq, TotalTermFreq
- * <li>Header --> {@link CodecUtil#writeHeader CodecHeader}
+ * <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>EntryCount,SuffixLength,StatsLength,DocFreq,MetaLength --> {@link DataOutput#writeVInt
* VInt}
* <li>TotalTermFreq --> {@link DataOutput#writeVLong VLong}
@@ -128,8 +128,8 @@ import org.apache.lucene.util.compress.LowercaseAsciiCompression;
* <p>Notes:
*
* <ul>
- * <li>Header is a {@link CodecUtil#writeHeader CodecHeader} storing the version information for
- * the BlockTree implementation.
+ * <li>Header is a {@link CodecUtil#writeIndexHeader IndexHeader} storing the version information
+ * for the BlockTree implementation.
* <li>DocFreq is the count of documents which contain the term.
* <li>TotalTermFreq is the total number of occurrences of the term. This is encoded as the
* difference between the total number of occurrences and the DocFreq.
@@ -148,15 +148,14 @@ import org.apache.lucene.util.compress.LowercaseAsciiCompression;
* statistics (such as sum of total term freq).
*
* <ul>
- * <li>TermsMeta (.tmd) --> Header, NumFields, <FieldStats><sup>NumFields</sup>,
- * TermIndexLength, TermDictLength, Footer
- * <li>FieldStats --> FieldNumber, NumTerms, RootCodeLength, Byte<sup>RootCodeLength</sup>,
- * SumTotalTermFreq?, SumDocFreq, DocCount, MinTerm, MaxTerm, IndexStartFP, TrieRootNodeFp,
- * IndexEndFp
- * <li>Header --> {@link CodecUtil#writeHeader CodecHeader}
+ * <li>TermsMeta (.tmd) --> Header, <i>PostingsHeader</i>, NumFields,
+ * <FieldStats><sup>NumFields</sup>, TermIndexLength, TermDictLength, Footer
+ * <li>FieldStats --> FieldNumber, NumTerms, SumTotalTermFreq?, SumDocFreq, DocCount, MinTerm,
+ * MaxTerm, IndexStartFP, TrieRootNodeFp, IndexEndFp
+ * <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>TermIndexLength, TermDictLength --> {@link DataOutput#writeLong Uint64}
* <li>MinTerm,MaxTerm --> {@link DataOutput#writeVInt VInt} length followed by the byte[]
- * <li>NumFields,FieldNumber,RootCodeLength,DocCount --> {@link DataOutput#writeVInt VInt}
+ * <li>NumFields,FieldNumber,DocCount --> {@link DataOutput#writeVInt VInt}
* <li>NumTerms,SumTotalTermFreq,SumDocFreq,IndexStartFP,TrieRootNodeFp,IndexEndFp --> {@link
* DataOutput#writeVLong VLong}
* <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
@@ -167,7 +166,6 @@ import org.apache.lucene.util.compress.LowercaseAsciiCompression;
* <ul>
* <li>FieldNumber is the fields number from {@link FieldInfos}. (.fnm)
* <li>NumTerms is the number of unique terms for the field.
- * <li>RootCode points to the root block for the field.
* <li>SumDocFreq is the total number of postings, the number of term-document pairs across the
* entire field.
* <li>DocCount is the number of documents that have at least one posting for this field.
@@ -184,7 +182,7 @@ import org.apache.lucene.util.compress.LowercaseAsciiCompression;
*
* <ul>
* <li>TermsIndex (.tip) --> Header, TrieIndex<sup>NumFields</sup>Footer
- * <li>Header --> {@link CodecUtil#writeHeader CodecHeader}
+ * <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <!-- TODO: better describe trie output here -->
* <li>TrieIndex --> {trie<byte[]>}
* <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
Trade-offs
- Keeps the class's typed style and fixes the two
.tmditems, the misplaced.timPostingsHeader and the header wording. The existing note (:136-138, "arbitrary per-file data") already explains the PostingsHeader and now matches where it sits; it stays in the.timnotes (moving that half to the.tmdnotes is optional, not run). PostingsHeaderstays an italic placeholder, because the block tree is postings-format agnostic; for the default codec it is "Header, PackedBlockSize" (Lucene104PostingsFormat.java:103), so the corrected.tmdline is exact for the default postings writer; other postings formats define their own.IndexHeaderis spelled asLucene104PostingsFormatalready spells it (:106).- Left as is, and older than this defect: the
.timterm-block productions (:113-124) are simplified, not byte-exact.EntryCountis written asnumEntries << 1 | isLastInFloor(:735-742), so the block0b 2c 61 62 63 64 65 ...holds 5 entries, not 11;SuffixLengthis a VLong token with the total suffix bytes, a leaf bit and a compression code (:920-925); the suffix bytes may be compressed (:883-930); the per-term suffix lengths are a section of their own (:934-946); singleton stats are run-length coded (:520-538). The flag bits were packed this way already in 4.10.4, the rest came with LUCENE-4702 (8.5.0). Describing that encoding exactly is a separate, larger javadoc change (not drafted, not run); fix A covers only the.tmditems, the misplaced header and the header wording. - Left out, could be added separately: that TrieRootNodeFp is relative to IndexStartFP (
FieldReader.java:80-87), and the missing comma inTrieIndex^NumFields Footer(:186).
What the checks validated
Validated on 2026-11-01 in a scratch worktree of 645d4fe14a20 with the diff applied:
- The minimal repro rewritten to the corrected grammar (one method, the same one document) reads
.tmdas Header, PostingsHeader (IndexHeaderLucene104PostingsWriterTerms, PackedBlockSize 256), NumFields 1, FieldStats (FieldNumber 0, NumTerms 1, SumTotalTermFreq 1, SumDocFreq 1, DocCount 1, MinTerm and MaxTerma, the three trie pointers), TermIndexLength =.tiplength, TermDictLength =.timlength, thenCodecUtil.checkFooter, which throws unless the parse ends exactly at the footer; it also checks that no codec magic follows the.timheader. It does not parse the.timterm blocks, which fix A leaves as they are. It passes with assertions on and off, through gradle and standalone. - The unchanged minimal repro still fails with the same message, as it must: the fix changes text, not bytes.
TestTrie(4 tests) andTestLucene104PostingsFormat(34 tests, 3 skipped) pass, seed DEADBEEF../gradlew :lucene:core:check -x testpasses (checkGoogleJavaFormat,ecjLint,forbiddenApis)../gradlew :lucene:core:renderJavadocpasses with 0 warnings; the rendered page shows the corrected lines and no RootCode.
Its "Term Dictionary" (.tim) section says the postings writer/reader "are actually responsible for encoding and decoding the PostingsHeader and TermMetadata sections described here" (Lucene104PostingsFormat.java:99-103), which places the header in .tim implicitly. One sentence saying that the PostingsHeader is written once to the terms metadata (.tmd) file, and TermMetadata per term in .tim, closes the loop.
Trade-offs
- Only implicit today, so it is optional; it helps a reader who starts from the postings format page.
What the checks validated
Not run.
C (optional). The same text in the backward-codecs test writer Lucene90BlockTreeTermsWriter (not run)
lucene/backward-codecs/src/test/.../lucene90/blocktree/Lucene90BlockTreeTermsWriter.java has the same FieldDict --> PostingsHeader text (:121, note :145) and the CodecHeader wording (:130, :140, :165, :196); its root code really is written.
Trade-offs
- A test-only writer for old-format indexes; fix it only for consistency between the copies. It is still on main (#16911 decommissioned
branch_10xonly).
What the checks validated
Not run.
Describe the files at a high level and drop the element lists.
Trade-offs
- Fits the "high-level" wording of LUCENE-2946, but loses the detail the class has always given and that #90 kept; A is the smaller, more reviewable change.
What the checks validated
Not run.
Downstream relevance is limited to tools that decode .tim/.tmd bytes by hand from this javadoc (inspectors, ports, recovery tools); Lucene's own reader and every application using its API are unaffected.
Semi-formal: a differential grammar check. Each default-codec file's grammar was transcribed from its javadoc and, separately, from its writer; one interpreter parsed the real bytes of 64 generated indexes under both and compared every value with Lucene's own reader. Under the javadoc grammar, all 125 .tim and 125 .tmd files diverged.
The method in full135 words
- The check made 1,114 file checks (all file types) per run over 64 indexes (4 fixed and 60 seeded random feature configurations), run once with assertions on and once off.
- Positive control: the writer's layout grammar parses every
.tmdfile exactly to its footer and, for every.tim, finds the postings header in.tmdrather than after the.timheader (0 failures; it does not parse the.timterm blocks). Vacuity check: 14 of 14 layout mutants with one element dropped are caught. - A JUnit test written from the result, then independent tests by verifiers, a reviewer from another model family (OpenAI GPT-5.6) and an adjudication reproduced it; 37 version-portable probe runs from 4.10.4 to main dated each element.
- This is a differential check of documentation against bytes, not model checking or a proof.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-28, rechecked 2026-11-01). Nearest: the changes that made the text stale (LUCENE-9353, #14333) or carried it forward (#90, #823), none of which mentions it. Not fixed upstream.
Searches3 searches
- Related, not this bug: #10393 / LUCENE-9353 and apache/lucene-solr#1473 (moved the header to
.tmd; no doc discussion); #14333 (kept RootCodeLength; its one layout review comment is about the.tiptrie); #90 and #823 (carried the.timPostingsHeader forward); #4020 / LUCENE-2946 (2012 high-level doc policy); #15619 / #15625 (a different stale sentence inLucene104PostingsFormat, fixed); an outside diagram repository of the FST-era format (no discrepancy reported). - Not fixed upstream: upstream main
f815e679bf6c(2026-11-01) has the sameLucene103BlockTreeTermsWriter.javaas645d4fe14a20;branch_11xandbranch_10_6carry the same lines. Tracking issue #16937 does not name it. - Open javadoc PRs: #16949, #16936 and #16904 touch no block-tree or
lucene104file.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; the JIRA archive; downstream repositories | 2026-10-28 | scripted prior-report searches (28 GitHub issue/PR, 5 commit, 4 downstream and 4 JIRA queries); 16 manual GitHub searches on the identifiers; the changed files of all 413 open PRs, with the patches of those touching the block-tree writer or postings format grepped; review comments of #14333, #90, #823 and lucene-solr#1473 | no report; RootCodeLength, TrieRootNodeFp, PostingsHeader, TermsMeta, FieldDict: 0 issues or PRs |
| Mailing lists and web | 2026-10-28 | 20 queries over dev@, java-user@, issues@ and commits@; 9 web searches | no report; only review mails of the related PRs, javadoc mirrors and old format pages |
| apache/lucene (recheck) | 2026-11-01 | upstream main HEAD and the file's commits; branch_11x and branch_10_6 contents; issues and PRs for the identifiers (all time) and for 7 phrasings created since 2026-10-27; the files of the open javadoc PRs; #16937 | no report: 0 hits; the file is unchanged on upstream main f815e679bf6c |
The postings header part dates from LUCENE-9353 (87a3bef50f8, 2020-06-16; first in 8.6.0), the root-code part from #14333 (878e23f7739, 2025-04-14; first in 10.3.0, backport #14563). 8.5.2 still matches on the header and 10.2.2 on the root code; from 8.6.0 (header) and 10.3.0 (root code) through 10.6.0 and main, the javadoc is wrong.
Versions tested5 rows
- Part A (PostingsHeader): LUCENE-9353 "Move terms metadata to its own file" (
87a3bef50f8on main,0dac659cd17on branch_8x, both 2020-06-16, apache/lucene-solr#1473) changedpostingsWriter.init(termsOut, state)toinit(metaOut, state). Carried forward by #90 (5f5d1949e92, 2021-04-20, 9.0.0: the.tmdgrammar without the header) and #823 (main2d278a0efe2/ branch_9x47bc1fff4d7, 2022-04-20, first released in 9.2.0 through the branch_9x commit: the per-fieldFieldDict --> PostingsHeaderwording). - Part B (RootCode): #14333 "A specialized Trie for Block Tree Index" (
878e23f7739, 2025-04-14; branch_10x backport65fd8648eb6, #14563, 2025-05-09) createdLucene103BlockTreeTermsWriter. In 9.0-10.2 the default codec usedLucene90BlockTreeTermsWriter, which really writes a root code. - Part C (wording): the headers became IndexHeaders with LUCENE-5969 (
4675aaf55d4, 2014-10-21; branch_5x0f304eafb93, 2014-10-24), first in 5.0.0; 4.10.4 matches. - Where the text lived: 8.6-8.11 in
BlockTreeTermsWriter(no.tmdgrammar at all), 9.0-10.2 inLucene90BlockTreeTermsWriter, 10.3.0 on inLucene103BlockTreeTermsWriter. - Since: the file's later upstream commits (#14633, #15826, #15970, #16237, the latest 2026-06-11) do not touch the javadoc.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal repro fails with assertions on and off (standalone and gradle); fix A validated |
10.6.0 (release commit 4ae946e5a9b), 10.5.2, 10.3.0 | affected | the hunt's test fails 3 of 3 (header placement and root code); same javadoc lines |
| 10.2.2 | partly | header placement fails (the hunt's placement tests fail, 2 of 3); the root code is really written (FST era), so that part matches |
| 9.12.3, 9.0.0, 8.11.4, 8.6.0 | partly | no PostingsHeader in .tim (it moved to .tmd); the root code is really written (checked on 8.6.0, 9.0.0 and 9.12.3) |
| 8.5.2 | not affected | the PostingsHeader really follows the .tim header (no .tmd file yet) |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication (high confidence); an audit confirmed it as a low-priority doc defect. This doc's gradle run checked the fix (the .tmd layout and the build).
Checks and verdicts376 words
Every check re-ran a repro on main or read the same lines; each executing check also had a control that reads the files the way the writer writes them (the .tmd to its footer) and passes, so the failures do not come from the parsers.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, refute lens (OpenAI GPT-5.6, executing) | real, high confidence | Its own public-API check fails with assertions on and off; its actual-layout control matches DirectoryReader; Lucene's TestTrie and TestLucene104PostingsFormat pass; intended argument moderate. |
| independent reproducer | real | Own 3-document test fails 4 of 5 on main (assertions on and off), 10.5.2 and 10.3.0; its writer-layout control parses .tmd exactly to the footer; the header tests also fail on 9.12.3. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading) | real, medium confidence | Root cause agrees, inputs in contract, intended argument moderate; the review itself only read code; the hunt's test was re-run for it on main a9779ef3c193: 3 of 3 fail with assertions on and with assertions off. |
| intended-behaviour devil's advocate | real, documentation only; intended argument weak | Built and rejected the LUCENE-2946, placeholder and experimental arguments; own 600-document, 3-field test fails 2 of 4 with both controls passing on main and 10.5.2. |
| adjudication | confirmed, high confidence, documentation | Re-ran the independent reproduction's test with assertions on (control passes) and the hunt's with assertions off (3 of 3). |
| credibility audit | confirmed, minor | A fourth re-run on main; writer, reader and javadoc read; "a real, low-stakes documentation fix". |
| this doc's validation (2026-11-01) | fix A build-checked | With fix A applied to a scratch worktree of 645d4fe14a20: the repro rewritten to the corrected grammar parses .tmd exactly to its footer (assertions on and off; the .tim term blocks are not parsed); the unchanged repro still fails, as it must; TestTrie and TestLucene104PostingsFormat pass; :lucene:core:check -x test and :lucene:core:renderJavadoc pass. |
| fact checks of this doc (2026-11-01) | bug real; corrections applied | An independent fact check and a cross-model fact check (OpenAI GPT-5.6) re-ran the repro and confirmed the bytes, the code lines, the history and the security call. They found one wrong count and several overstatements, corrected here, and the simplified .tim term-block productions, now a caveat under Suggested fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 489 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,573 words
- Registry title
- The file-format javadoc of the default terms dictionary (Lucene103BlockTreeTermsWriter) gives a wrong .tim/.tmd grammar: each .tmd FieldStats still lists RootCodeLength and root-code bytes, which the trie-based terms index no longer writes, and the PostingsHeader is documented at the start of every .tim field although it is written once in .tmd, before NumFields (documentation defect; the writer and reader agree)
- Area
- codecs / terms dictionary (Lucene103BlockTreeTermsWriter .tim/.tmd file-format javadoc vs its writer and reader)
- Priority
- Low, rank 1280: The default terms dictionary .tim/.tmd grammar has two stale elements going back to 8.6 and covers a central per-field file.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so indexing, merging, CheckIndex and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement the default terms dictionary format from this class javadoc (Lucene104PostingsFormat sends readers there for the format details), and a parser that follows the text misreads NumFields in every .tmd file the default codec writes and finds no PostingsHeader in .tim (executed); the PostingsHeader placement has been wrong since 8.6.0 (2020) and the root-code leftover since 10.3.0 (2025); no scale or special setting is needed.
- Summary
- You decode the terms metadata (.tmd) and terms dictionary (.tim) files of the default codec by following the Lucene103BlockTreeTermsWriter javadoc, which says .tmd is Header, NumFields, FieldStats... with a RootCodeLength and root-code bytes in each FieldStats, and that every .tim field starts with a PostingsHeader. The writer instead puts the postings writer's header (an IndexHeader plus the block size) once into .tmd, right after its own header and before NumFields, writes no PostingsHeader into .tim and, since the trie terms index of 10.3.0, writes no root code; a parser built from the text reads NumFields as 63 (the first byte of the codec magic) and, even with that header skipped, takes SumTotalTermFreq for RootCodeLength. Lucene's own reader matches the writer, so nothing breaks at runtime; only the documentation is wrong.
- Introduced
- two stages plus a wording point [follow-up]: (A, PostingsHeader placement) 87a3bef50f8c08404ee8bd66ca868caf5dd072cb (main) / 0dac659cd17 (branch_8x backport, the commit that first shipped, in 8.6.0), LUCENE-9353 'Move terms metadata to its own file' (apache/lucene-solr#1473, by jpountz): it changed postingsWriter.init(termsOut, state) to init(metaOut, state), which moved the postings header from .tim to the new .tmd, and left the javadoc as it was [read: git show in the full-history clone; exec: the documented .tim PostingsHeader is present on 8.5.2 and absent from 8.6.0]; carried forward by #90 (5f5d1949e92, 2021-04-20, 9.0.0: wrote the .tmd grammar without the postings header) and #823 (main 2d278a0efe2 / branch_9x 47bc1fff4d7, 2022-04-20, 9.2.0 through the branch_9x commit: the per-field 'FieldDict --> PostingsHeader' wording); (B, root code) 878e23f77390058b6787e0a0537de9087d1019b3 (main) / 65fd8648eb6 (branch_10x backport #14563, in 10.3.0), #14333 'A specialized Trie for Block Tree Index' (by gf2121): it created Lucene103BlockTreeTermsWriter from Lucene90BlockTreeTermsWriter, replaced the FST elements of FieldStats by TrieRootNodeFp and IndexEndFp, but kept RootCodeLength, Byte^RootCodeLength and the note 'RootCode points to the root block' [exec: the documented FieldStats parse on 8.6.0 to 10.2.2, where the root code really is written, and fail from 10.3.0]; (C, minor wording) 'Header --> CodecHeader' while IndexHeaders are written, since LUCENE-5969 (4675aaf55d4 main line 2014-10-21, 0f304eafb93 branch_5x 2014-10-24) [exec: 4.10.4 pass, 5.0.0 fail] (2020-06-16 (author date of 87a3bef50f8 and 0dac659cd17: PostingsHeader placement); 2025-04-14 (author date of 878e23f7739 on main: root code; backport 65fd8648eb6 authored 2025-05-09); 2014-10-21 / 2014-10-24 (CodecHeader wording, LUCENE-5969))
- First affected version
- 8.6.0 [exec] for the PostingsHeader placement (last unaffected release 8.5.2 [exec]); 10.3.0 [exec] for RootCodeLength/RootCode, the first release of Lucene103BlockTreeTermsWriter (last unaffected 10.2.2 [exec], FST era); 5.0.0 [exec] for the minor CodecHeader-vs-IndexHeader wording (4.10.4 [exec] unaffected)
- Affected versions
- PostingsHeader placement: 8.6.0 through 8.11.4, every 9.x and 10.x release through 10.6.0 (10.6.0 run as its release revision, the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; RootCode: 10.3.0 through 10.6.0 (the same branch_10_6 run) and main; not fixed upstream [exec: 37 version-portable follow-up probe runs, each checking one documented element, ended as expected on 4.10.4, 5.0.0, 8.5.2, 8.6.0, 8.11.4, 9.0.0, 9.12.3, 10.2.2, 10.3.0, 10.5.2, branch_10_6 4ae946e5a9b and main; the finder's JUnit fails 3 of 3 on main (-ea and -da), branch_10_6, 10.5.2 and 10.3.0, and 2 of 3 on 10.2.2 (placement tests only); the independent reproduction's JUnit fails 4 of 5, with its layout control passing, on main (-ea and -da), 10.5.2 and 10.3.0, and its 3 placement/header tests fail on 9.12.3; read: the releases in between from each tag's writer and javadoc]. Before 9.0 the stale text lived in the then-current block-tree writer class (BlockTreeTermsWriter, 8.6-8.11) and in Lucene90BlockTreeTermsWriter (9.x-10.2); the 8.6-8.11 javadoc did not document .tmd at all. Upstream main 645d4fe14a20 (2026-10-28) still carries the lines [read]; all runs used JDK 25 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: a scripted prior-report search with 28 GitHub issue/PR queries, 5 commit queries, 4 downstream-repository queries, 20 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA-archive queries and the web (546 distinct hits, none the same bug); 16 manual GitHub searches on the identifiers and phrases (RootCodeLength, TrieRootNodeFp, PostingsHeader, TermsMeta, FieldDict: 0 issues or PRs); all 413 open apache/lucene PRs scanned by changed files and the patches of every one touching the block-tree writer or the postings format grepped for grammar edits; review comments of #14333, #90, #823 and apache/lucene-solr#1473, JIRA comments of LUCENE-9353). Nearest items, not the same bug: #10393 / LUCENE-9353 (made the PostingsHeader placement stale; no documentation discussion), #90 (2021, revised this grammar after LUCENE-9353 and was approved as a fix, but left the PostingsHeader in .tim), #823 (2022, wrote the per-field FieldDict wording), #14333 (made RootCodeLength stale; its only doc-layout review request is about the .tip trie section), #4020 / LUCENE-2946 (2012 policy for high-level file-format docs), #15619 / #15625 (a different stale sentence in Lucene104PostingsFormat, fixed 2026-01), an outside diagram repository of the FST-era format (no discrepancy reported). Recheck (2026-10-28): 'RootCodeLength', 'TrieRootNodeFp' and 'PostingsHeader' in apache/lucene 0 hits; none of the 29 issues and PRs created since 2026-10-26 (including a series of javadoc fixes, #16920-#16922, #16927, #16928, #16933-#16935) is about a file-format grammar; of the open PRs updated since 2026-10-26 only #16911 (on branch_10x only; open when searched, merged 2026-10-29: removes the backward-codecs Lucene90 block-tree reader and its test writer copy there, no grammar edit in core) and #16480 (a version-history line in lucene104/package-info.java) touch related files; by author date the latest commits on Lucene103BlockTreeTermsWriter.java are 6b67118c4a0 (2026-06-11, #16237, a rename) and older, none editing the javadoc grammar; upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 112, 121, 131, 151, 153, 156, 159, 170 and 187. Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone and through gradle; fix A in a scratch worktree (the minimal repro rewritten to the corrected grammar, the closest suites,:lucene:core:check -x test,:lucene:core:renderJavadoc). The hunt's and the verifiers' tests on maina9779ef3c193(no codec change up to645d4fe14a20), the 10.6.0 release commit4ae946e5a9b, 10.5.2, 10.3.0 and 9.12.3; 37 follow-up probe runs from 4.10.4 to main.Lucene103BlockTreeTermsWriter.javais byte-identical on645d4fe14a20and upstream mainf815e679bf6c(2026-11-01) (read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java:111-112 (.tim TermsDict and FieldDict --> PostingsHeader, NodeBlock^NumBlocks), :121 and :131 (Header as CodecHeader), :136-138 (PostingsHeader is 'arbitrary per-file data'), :151-155 (.tmd TermsMeta and FieldStats with RootCodeLength, Byte^RootCodeLength), :156 and :187 (CodecHeader), :159 (RootCodeLength --> VInt), :170 ('RootCode points to the root block'), :298-330 (writeIndexHeader for .tim, .tip and .tmd), :332 (postingsWriter.init(metaOut, state)), :1082-1092 (FieldStats without a root code, then root.index.save), :1133-1141 (NumFields, field stats, .tip and .tim lengths, footer); identical at Lucene main ea57360912ed (compared 2026-10-28)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/TrieBuilder.java:262-267 (save: IndexStartFP, root node fp, IndexEndFp) and Lucene103BlockTreeTermsReader.java:73-76 (VERSION_START = VERSION_CURRENT = 0), :143-219 (reader follows the writer layout)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsWriter.java:222-227 (init: IndexHeader 'Lucene104PostingsWriterTerms' plus VInt BLOCK_SIZE into the stream it is given) and Lucene104PostingsFormat.java:93-104 (Term Dictionary section: 'See Lucene103BlockTreeTermsWriter for more details on the format'; PostingsHeader --> Header, PackedBlockSize)lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene90/blocktree/Lucene90BlockTreeTermsWriter.java:120-121, :145 (the same stale PostingsHeader text in the frozen test copy; its root code really is written)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java (lines 111-112, 113-124, 121, 131, 136-138, 151-161, 170, 187: javadoc; 298-332, 520-538, 735-742, 883-946, 1082-1092, 1133-1141: writer)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsWriter.java (lines 223-227, init) and Lucene104PostingsFormat.java (line 343, BLOCK_SIZE) and ForUtil.java (line 34)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/TrieBuilder.java (lines 263-268, save) and FieldReader.java (lines 80-87)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsReader.java (lines 73-76, 145-179)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java (lines 97, 99-103, 149) and package-info.java (lines 50, 154, 188, 258-265)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java (lines 113-124, 136-138, 157-161, 188-189, 209, 332, 520-538, 735-742, 920-946)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsReader.java (lines 73-76)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 54, 188)lucene/core/src/java/org/apache/lucene/codecs/PostingsWriterBase.java (lines 45-49)
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java (lines 99-106) and lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene90/blocktree/Lucene90BlockTreeTermsWriter.java (lines 121, 130, 140, 145, 165, 196)
- TestLucene103BlockTreeTermsMetaJavadoc.java (JUnit, one test):
repro/LFV-939/src/org/apache/lucene/codecs/lucene103/blocktree/TestLucene103BlockTreeTermsMetaJavadoc.java(53 lines)
Made from the code at 645d4fe14a20 and the executed byte dumps (the .tmd bytes after the header; the FieldStats bytes for three documents), in parallel with this doc.
assets/LFV-939/bug.png(489 KB)