TrecJudge turns a qrels file into the per-query set of relevant documents that QualityBenchmark scores every hit against. It keeps a line as relevant whenever its grade is not the exact text "0".
- A qrels file lists judged documents, one per line: query id, an unused column (0), document name, grade. Example:
1 0 good 1. - The grade is an integer: 0 is not relevant, 1 or more is relevant (2 = highly relevant). TREC Web track qrels (2010-2014) also use -2 for "spam or otherwise seems useless".
- trec_eval, the standard scorer, counts a document as relevant only when its grade is at least 1; a negative grade is never relevant (it reads it as "in pool, but unjudged").
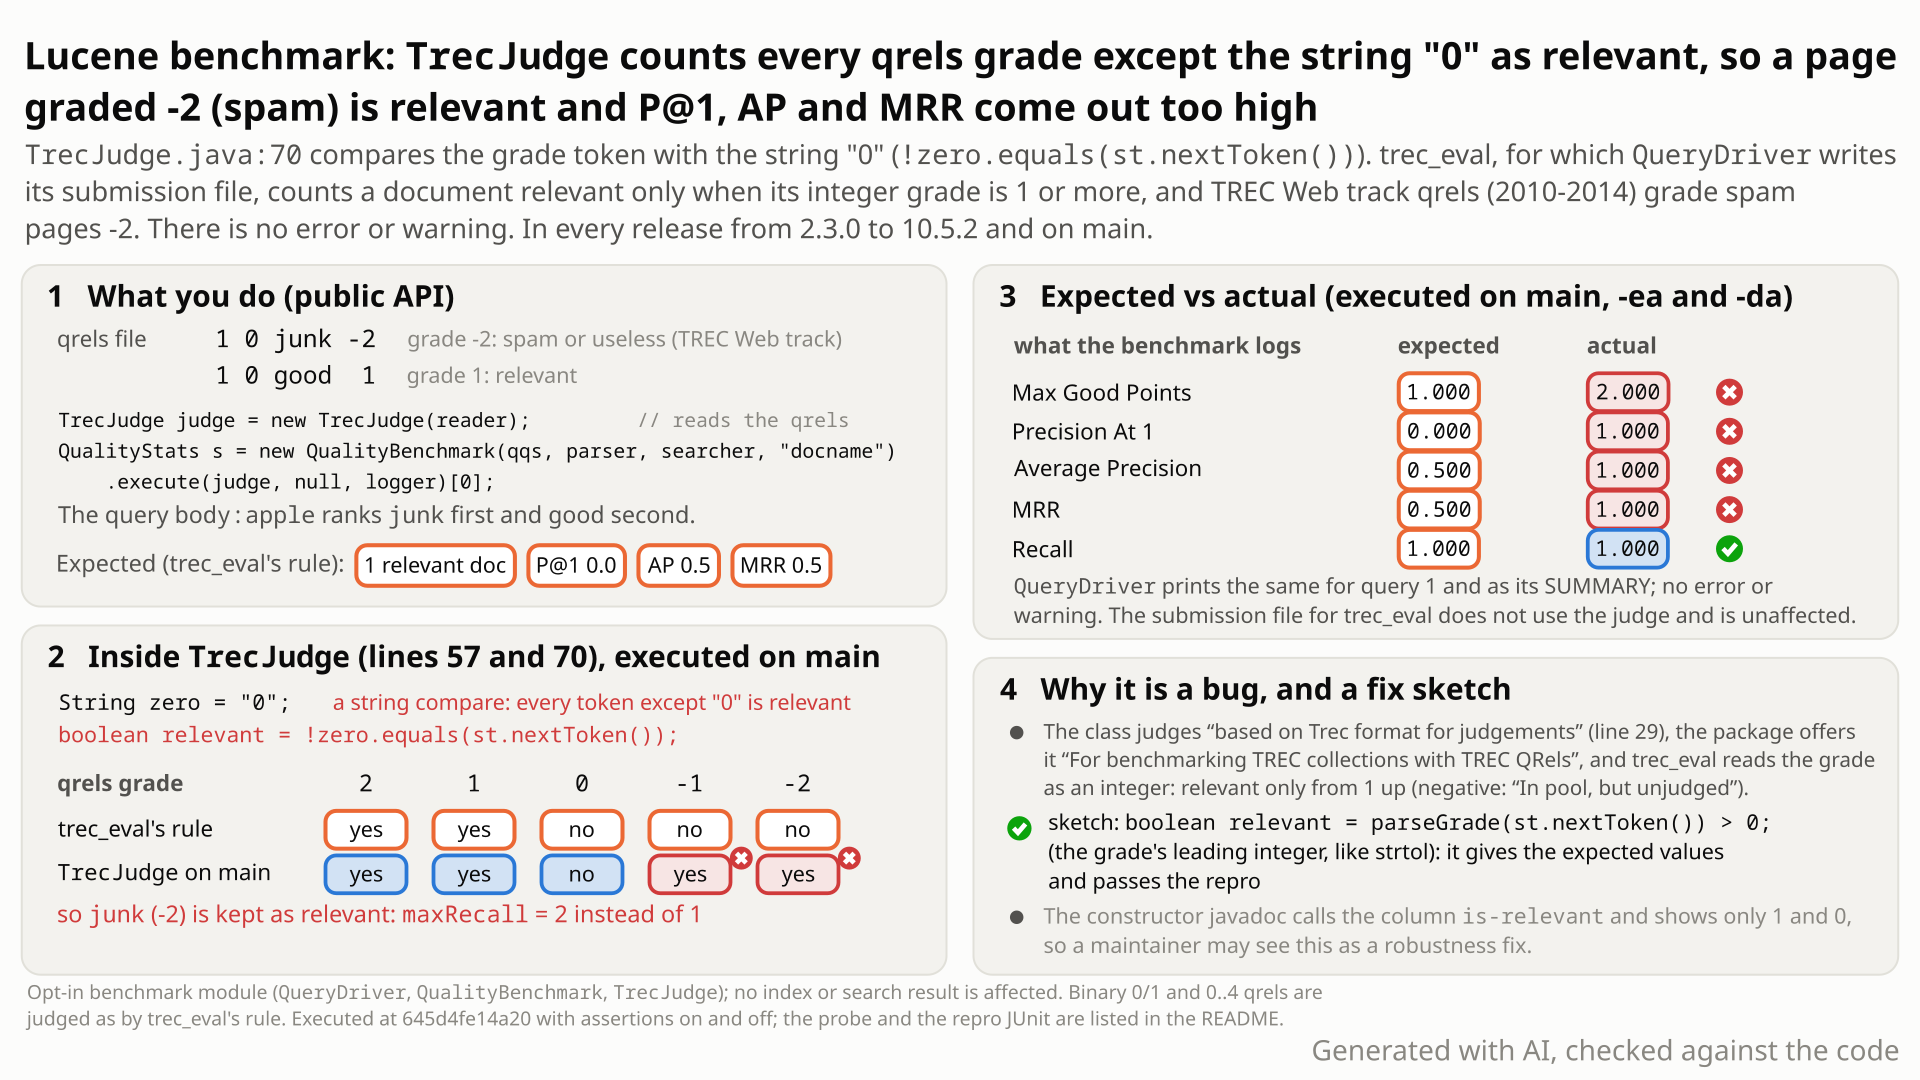
- You score a search run with Lucene's quality benchmark (
QueryDriver, orQualityBenchmarkwithTrecJudge). The qrels for query 1 say1 0 junk -2(spam) and1 0 good 1(relevant). - Your search ranks
junkfirst andgoodsecond. You expect what trec_eval's rule (grade 1 or more is relevant) gives: 1 relevant document, P@1 0, AP 0.5, MRR 0.5. - Instead Lucene reports 2 relevant documents, P@1 1.0, AP 1.0 and MRR 1.0, with no warning.
- Why:
TrecJudgenever reads the grade as a number. It marks a document relevant when the grade is not the string "0" (TrecJudge.java:70), so -2 and -1 count as relevant. Binary 0/1 qrels and grades 0 to 4 are judged correctly.
Users of the opt-in lucene/benchmark quality package (QueryDriver, QualityBenchmark or TrecJudge) whose qrels contain negative grades, such as TREC Web track 2010-2014 qrels. Every negative line counts, every run, with no warning. Binary qrels, the trec_eval submission file, indexes and search results are unaffected, so the priority is low.
Mechanism, terms and numbers544 words
TrecJudge (lucene/benchmark, org.apache.lucene.benchmark.quality.trec) reads TREC relevance judgements (qrels) for QualityBenchmark and QueryDriver. Each line is qnum 0 doc-name grade, and the grade is an integer: trec_eval counts a document as relevant only when its grade is at least 1, and TREC Web track qrels (2010-2014) use -2 for spam or useless pages. TrecJudge instead decides relevance with !"0".equals(grade), so every token except the exact text "0" is relevant, -2 and -1 included. The relevant-document count and the P@n, AP, MRR and recall that Lucene prints are then wrong, silently: a junk page graded -2 ranked above the only relevant page gives 2 relevant documents, P@1 1.0, AP 1.0 and MRR 1.0, where trec_eval's rule gives 1, 0, 0.5 and 0.5. Binary and non-negative graded qrels are unaffected, as are the trec_eval submission file, the index and search results. The test dates from LUCENE-836 (2007): every release from 2.3.0 to 10.6.0 is affected.
- Parsing. The constructor (
TrecJudge.java:54-86) splits each line into query id, an ignored column, document name and grade (:66-70):
   String zero = "0";                                    // :57
   ...
   boolean relevant = !zero.equals(st.nextToken());      // :70
A string comparison, not a number test: -2, -1, 00, 0.0, -0 and any word are "not the string 0", so they are relevant. The assert on :71 only checks for extra tokens, so assertions change nothing.
- Only relevant lines are kept (
:72-81), in a per-query set;isRelevant(:89-93) andmaxRecall(:153-161, the set size) read it. - The metrics.
QualityBenchmarkcreatesnew QualityStats(judge.maxRecall(qq), ...)(QualityBenchmark.java:126) and callsjudge.isRelevantfor every hit (:137-138). A relevant hit raises the good-hit count, sets MRR on the first one in the top 5 and adds its precision to the AP sum (QualityStats.java:85-97); AP is that sum divided bymaxGoodPoints(:122-124), recall is good hits divided bymaxGoodPoints(:100). - Worked steps. qrels
junk -2,good 1; hits: rank 1junk, rank 2good. Stock: both relevant,maxGoodPoints2; rank 1 precision 1/1 (MRR 1), rank 2 precision 2/2; AP = (1 + 1) / 2 = 1.0, P@1 = 1.0. trec_eval's rule: 1 relevant document; rank 1 is not relevant (P@1 0); rank 2 precision 1/2, reciprocal rank 1/2; AP = 0.5 / 1 = 0.5. - Where it shows. The per-query stats that
QualityBenchmarklogs ("Max Good Points", "Average Precision", "MRR", "Recall", "Precision At n";QualityBenchmark.java:140-143,QualityStats.java:156-166) and the SUMMARY thatQueryDriverprints (QueryDriver.java:101-102).
- qrels
d1:1, d2:-2, d3:0, d4:-1:maxRecall3 instead of 1. 00,-0and+0are judged relevant too (secondary: no real qrels file uses them); so are words such asx,noandfalse.- Controls: grades 1 and 2 relevant, 0 not relevant, as in trec_eval; the in-tree
TestQualityRun(binary qrels) passes.
- Not affected: binary 0/1 qrels and graded qrels with grades 0..4, the trec_eval submission file
QueryDriverwrites, the index and search results. - Related, not part of this bug: queries whose judgements are all 0 get
maxRecall0 and are left out ofQualityStats.average(by a commented design choice), where trec_eval averages them with AP 0.
Exposure and likelihood155 words
- Who is exposed. Anyone who evaluates relevance with the lucene/benchmark search-quality package on qrels that use negative grades: the TREC Web track 2010-2014 qrels (-2 for spam), or custom qrels that use -1 for "bad".
TrecJudgeis the adjudication the package documents for TREC qrels and the only oneQueryDriveruses. - Effect. Silent wrong evaluation numbers: the relevant-document count is too high, and P@n, AP, MRR and recall can all be wrong; in the example P@1 1.0 instead of 0 and AP 1.0 instead of 0.5. A system that ranks spam high can look better than one that does not.
validateDataonly checks that queries and judgements match. - Not affected. Binary 0/1 and non-negative graded qrels; the trec_eval submission file; indexes and search results.
- Workaround. Score the submission file with trec_eval, as experienced users do, or drop grades below 1 from the qrels first.
- Releases. Every release from 2.3.0 to 10.6.0 and main. Priority low.
One JUnit test method in lucene/benchmark, public API only: a TrecJudge built from the single qrels line 1 0 d -2, then isRelevant("d", query 1). No index, no randomness, one thread; the same result with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.benchmark.quality.trec;

import java.io.BufferedReader;
import java.io.StringReader;
import java.util.Map;
import org.apache.lucene.benchmark.quality.QualityQuery;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTrecJudgeNegativeGrade extends LuceneTestCase {

  public void testNegativeGradeIsNotRelevant() throws Exception {
    TrecJudge judge = new TrecJudge(new BufferedReader(new StringReader("1 0 d -2\n")));
    // expected grade -2 non-relevant (trec_eval: relevant only if grade >= 1); actual relevant
    assertFalse(
        "expected isRelevant=false for qrels grade -2, got true",
        judge.isRelevant("d", new QualityQuery("1", Map.of())));
  }
}
mkdir -p $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/trec
cp $REPRO/TestTrecJudgeNegativeGrade.java $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/trec/
cd $LUCENE && ./gradlew :lucene:benchmark:test --tests org.apache.lucene.benchmark.quality.trec.TestTrecJudgeNegativeGrade -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
- Expected
isRelevant("d", query 1)is false for the qrels line1 0 d -2: only grades of 1 or more are relevant.- Observed
isRelevantis true:AssertionError: expected isRelevant=false for qrels grade -2, got true, with assertions on and off.
More files, environment, full output320 words
The trec test directory does not exist on main (the module's quality tests sit one package up), hence the mkdir. The seed only satisfies the test framework. As a regression test, reword the comment so it states only the expectation, for example "TREC qrels grade -2 (junk) is not relevant: trec_eval counts a document only if grade >= 1". The end-to-end effect on P@n, AP and MRR follows from isRelevant and maxRecall. The numbers in the steps come from the hunt's end-to-end test (two documents, QualityBenchmark: relevant documents, P@1, AP) and, for MRR, from the diagram's probe (QualityBenchmark and QueryDriver on the same two documents), both run on the same commit. The expected numbers apply trec_eval's relevance rule, read from its source, by hand and through Lucene's own QualityStats; the trec_eval binary was not run.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; pure Java string handling) |
mkdir -p $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/trec
cp $REPRO/TestTrecJudgeNegativeGrade.java $LUCENE/lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/trec/
cd $LUCENE && ./gradlew :lucene:benchmark:test --tests org.apache.lucene.benchmark.quality.trec.TestTrecJudgeNegativeGrade -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
TestTrecJudgeNegativeGrade > testNegativeGradeIsNotRelevant FAILED
    java.lang.AssertionError: expected isRelevant=false for qrels grade -2, got true
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:3055D722D8068F5F]:0)
        ...
        at org.apache.lucene.benchmark.quality.trec.TestTrecJudgeNegativeGrade.testNegativeGradeIsNotRelevant(TestTrecJudgeNegativeGrade.java:30)
:lucene:benchmark:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false, on the standalone runner (-ea, -da) and on the 10.6.0 release jars (-ea, -da)
# with the recommended fix: :lucene:benchmark:test (SUCCESS): 1 test

# end to end: QueryDriver on the two-document example (junk -2 ranked 1st, good 1 ranked 2nd), same commit, -da;
# after each '#': the same query through QualityBenchmark with a judge that applies the grade >= 1 rule
SUMMARY
  Num Points:             2.000      # 2.000
  Num Good Points:        2.000      # 1.000
  Max Good Points:        2.000      # 1.000
  Average Precision:      1.000      # 0.500
  MRR:                    1.000      # 0.500
  Recall:                 1.000      # 1.000
Precision At 1: 1.000 # 0.000- The class judges "based on Trec format for judgements", and the package offers it "For benchmarking TREC collections with TREC QRels", with no 0/1-only precondition.
- The package's own example runs on graded TREC qrels (grades 0, 1, 2), and grade 2 already counts as relevant.
- trec_eval, which
QueryDriverwrites its submission file for, never counts a negative grade as relevant.
The full argument246 words
- Contract.
TrecJudge"Judge[s] if given document is relevant to given quality query, based on Trec format for judgements" (TrecJudge.java:28-30). The package: "For benchmarking TREC collections with TREC QRels, take a look at the trec package" (package-info.java:33-34); the trec package is "Utilities for Trec related quality benchmarking, feeding from Trec Topics and QRels inputs" (trec/package-info.java:18). - Graded example.
package-info.java:36-69runs "the TREC 2006 queries 701-850 on the .Gov2 collection" throughTrecJudge; those qrels (the TREC 2004-2006 Terabyte ad hoc qrels for topics 701-850) use only grades 0, 1 and 2: 108,435 / 22,566 / 4,351 lines over the three files. - Reference scorer.
QueryDriverwrites an "output submission file for trec_eval" (QueryDriver.java:48). trec_eval reads the grade as "an integer between -127 and 127" (get_qrels.c:42-43) through a checkedstrtolwrapper that rejects out-of-range or non-numeric grades (get_qrels.c:18-35,:217-221), counts relevant onlyrel >= relevance_level(form_res_rels.c:213,:228; default 1) and maps negative values to "In pool, but unjudged" (form_res_rels.c:178-180). - Real data. The TREC 2012 Web track eval-README: "-2: spam or otherwise seems useless for any information need, 0: not relevant, 1: relevant, 2: highly relevant, 3: key, 4: nav"; "Adhoc evaluation results are computed using trec_eval".
- History. The string test came in with the class (LUCENE-836, #1911, 2007); neither the commit nor the issue discusses graded or negative grades, and no test, comment or later commit says a negative grade means relevant.
The devil's-advocate check171 words
Strongest case (the intended-behaviour check and the cross-model reviews, rated moderate): the constructor javadoc names the 4th column is-relevant and shows only 1 and 0 (TrecJudge.java:41, :47-48, unchanged since 2007); the in-tree qrels fixture is binary; NIST's classic ad hoc qrels page calls the field "a binary code of 0 for not relevant and 1 for relevant"; and the package says "To run on different formats of queries and judgements provide your own Judge" (package-info.java:75-77). So negative grades might be outside the declared input.
Why it fails: the package offers TrecJudge for TREC qrels in general and demonstrates it on graded qrels; grades 2 to 4 already work, so the code is not binary-only in practice. Nothing treats a negative grade as relevant, and official qrels with -2 are scored with trec_eval. Even under the binary reading, the parser silently gives an out-of-format value the opposite meaning instead of rejecting it. Verdict: not intended, a defect. A committer may still call the change a robustness fix.
Recommended Parse the grade as an integer; relevant iff > 0
Read the grade as an integer and treat only grades above 0 as relevant: Integer.parseInt(st.nextToken()) > 0, plus a javadoc that names the column relevance-grade (+7/-4). The test and all 91 lucene/benchmark tests pass; 0/1 and 0..4 qrels behave as before.
All options and trade-offs3 options · 663 words
Option A was built and run in a scratch worktree of 645d4fe14a20. Option B, the hunt's sketch, was checked by shadowing the patched class over the main jars. A javadoc-only change was considered and not built.
Replace the string test with Integer.parseInt(grade) > 0 and document the column as an integer grade with trec_eval's default rule (grade 1 or more is relevant; 0 and negative grades are not).
    * <pre>
-   *     qnum  0   doc-name     is-relevant
+   *     qnum  0   doc-name     relevance-grade
    * </pre>
    *
-   * Two sample lines:
+   * The relevance grade is an integer. As in trec_eval, a document is relevant only if its grade is
+   * 1 or more; 0 and negative grades (such as -2 for spam pages in some TREC tracks) are not
+   * relevant.
+   *
+   * <p>Two sample lines:
 ...
-    String zero = "0";
 ...
-        boolean relevant = !zero.equals(st.nextToken());
+        boolean relevant = Integer.parseInt(st.nextToken()) > 0;
Trade-offs
- 0/1 and 0..4 qrels give exactly the same results as today (
TestQualityRunpasses). - Odd spellings of zero change meaning:
00,-0and+0become non-relevant (relevant today);+1is accepted as 1. - A grade token that is not a plain Java
intnow throwsNumberFormatExceptioninstead of silently counting as relevant:0.0, words such asx, values beyond theintrange, and any number with other characters attached. trec_eval also rejectsxand out-of-range values (it stops loading the qrels) but reads0.0as 0 with a warning. Wrap it in anIllegalArgumentExceptionnaming the line if a clearer message matters. - A query whose qrels lines are all negative (or all 0) keeps no relevant document:
maxRecall0, a "queries have no judgments" warning fromvalidateData, andQualityStats.averageleaves it out of the SUMMARY. All-0 queries are handled this way today; pre-filtering the qrels to grades >= 1 has the same effect. - No relevance-level option like trec_eval's
-lis added (out of scope).
What the checks validated
- Stock + test: fails with assertions on and off (gradle); + fix: passes, on and off.
- + fix: all
lucene/benchmarktests, 91 tests in 19 suites, 0 skipped, 0 failures (assertions on);TestQualityRunand the new test with assertions off. - + fix:
:lucene:benchmark:check -x testandrenderJavadocpass; the check tasks that ran were google-java-format, ecjLint and forbiddenApis (eclint is not configured in this checkout and errorProne was skipped). - With the patched class shadowed: the hunt's end-to-end test (P@1 0, AP 0.5), the independent reproduction's three tests (MRR 0.5;
00,-0,+0) and the minimal test through the standalone runner (-ea,-da) pass. Not run: the full Lucene test suite. - An independent fact check repeated the gradle runs in its own scratch worktree, with the same results.
A private parseGrade reads an optional sign and the leading digits (0.0 -> 0, -2 -> -2) and throws only when there is no digit; relevant iff > 0 (+17/-3).
Trade-offs
Closer to trec_eval's syntax for odd tokens (0.0 -> 0, without trec_eval's warning), but more code, and not an exact trec_eval parser. It throws on a grade beyond the long range, as trec_eval also rejects one: its str_to_long wrapper treats strtol's out-of-range result as an error and stops loading the qrels.
What the checks validated
Shadowed over the 645d4fe14a20 jars: the minimal test passes with -ea and -da, and so do a cross-model reviewer's test and the upstream TestQualityRun; in the hunt's harness the token mismatches drop from 10 to 0. Not run through gradle.
Document that the 4th column is a 0/1 flag and that any value other than 0 is relevant. Not built.
Trade-offs
Smallest change, but TREC Web track qrels stay silently wrong, and it contradicts the package's "TREC QRels" claim and its graded example.
Anyone who reports Lucene-computed P@n, AP or MRR from TrecJudge on qrels with negative grades has wrong numbers; indexes, search results and the trec_eval submission file are not affected.
A bounded-exhaustive differential check: a harness asked the real TrecJudge about every grade token in a small alphabet and every grade assignment of four documents over -2..2, and compared each answer with trec_eval's rule (relevant iff the integer grade is at least 1). Every mismatch involved a negative grade or an odd spelling of zero.
The method in full122 words
Method: bounded-exhaustive differential check (semi-formal), a hunt unit (benchmark quality metrics versus trec_eval). A planning probe first saw maxRecall 4 instead of 2 and grades -2 and -1 judged relevant. The finder's harness QualityRefCheck.java then ran, on the stock jar, 26 single-token checks over a 13-token grade alphabet (10 mismatches: -2, -1, 00, 0.0, -0) and all 625 four-document assignments of grades -2..2 (544 judged wrongly, exactly those with a negative grade; this count reflects the alphabet, not real-world frequency), against an independent reference of trec_eval's rule taken from its source. With the fix sketch shadowed, both counts were 0. The finder then wrote a public-API JUnit (a four-line qrels and an end-to-end QualityBenchmark run); this doc's test is its one-line form.
No prior report found: about 250 queries on 2026-10-28 and 170 on 2026-10-30 (GitHub issues, PRs and commits, the JIRA archive, every Lucene mailing list, Lucene.NET, the web), refreshed on 2026-10-30. A GitHub search for TrecJudge returns nothing.
Searches4 searches
Related, not reports of this bug: a 2010 java-user thread where a committer writes that "the results from the benchmark summary often differ with trec_eval" (general: it names no class, cause or input, and its collections have no negative grades); #1911 / LUCENE-836 (introduced the class, binary qrels, no discussion of grades); #3134 / LUCENE-2058 (added the trec_eval submission file); #9048 / LUCENE-8000 (committers score QueryDriver runs with trec_eval). The Lucene.NET port has the same test with no report. Tracking issue #16937 and the dev@ thread do not mention TrecJudge.
| Where | When | How | Found |
|---|---|---|---|
| GitHub (apache/lucene issues, PRs, commits; apache/lucene-solr, apache/lucenenet; all of GitHub) | 2026-10-28 and 2026-10-30 | scripted prior-report searches and manual searches: TrecJudge, QRelJudgement, isRelevant, maxRecall, qrels (grade, negative), graded relevance, spam -2, trec_eval, QueryDriver; issues read with comments; code and commit searches | no report; TrecJudge returns 0 issues or PRs |
| Open and recent apache/lucene PRs | 2026-10-28 and 2026-10-30 | changed-file lists of all 413 open PRs, then of the 52 PRs updated since 2026-10-28 | only #16911, the branch_10x decommission, which deletes every file |
| Mailing lists and JIRA archive | 2026-10-28 and 2026-10-30 | every lucene.apache.org list including openrelevance-dev@ and -user@ (168 matching mails read in full); JQL over LUCENE, SOLR, LUCENENET and ORP | no report; the 2010 java-user remark above is the closest |
| Refresh | 2026-10-30 | issue and PR searches for TrecJudge, "qrels grade", "qrels negative", "trec_eval relevance", "isRelevant maxRecall", "QueryDriver qrels"; the file's newest commit; PRs created since 2026-10-30 | no new item; the last commit on TrecJudge.java is still the 2021 reformat |
Present since TrecJudge was created by LUCENE-836 (98fa2d898d1, 2007, first released in 2.3.0); the string test is unchanged since. Executed and failing on 17 releases from 2.3.0 to 10.5.2, on 10.6.0 and on main; 2.2.0 has no quality package.
Versions tested6 rows
LUCENE-836 "Add support for search quality benchmarking" (Doron Cohen; 98fa2d898d1, svn r560372, 2007-07-27; review on JIRA LUCENE-836, migrated as #1911) created the quality package with String zero = "0" and !zero.equals(...); git blame -w -M -C -C and git log -S 'zero.equals' lead back to it. Later commits on the file (generics, which also removed a cast inside the parse loop, module moves, the license header, javadoc and @Override fixes, the diamond operator, a spelling fix and the LUCENE-9570 reformat 7f8b7ffbcad, 2021-01-03) left the grade test unchanged. Not a regression and not fixed upstream. The first release with it is 2.3.0 (tag commit of 2008-01-24 UTC).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the test fails, assertions on and off (gradle and standalone) |
10.6.0 (release jars, built at 4ae946e5a9b9) | affected | the test fails, assertions on and off |
| 10.5.2 | affected | the test fails, assertions on and off; the hunt's tests too |
| 2.3.0, 2.3.2, 2.4.1, 2.9.4, 3.0.3, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 | affected | a version-portable check gives the same wrong values (maxRecall 3 instead of 1; 2 relevant documents, P@1 1.0, AP 1.0); a fixed TrecJudge makes it pass on 2.3.0 and 8.11.4 |
| 2.2.0 | API absent | no quality package (the check does not compile) |
with the fix (main 645d4fe14a20) | not affected | the test and all lucene/benchmark tests pass |
The finder, two executed cross-model reviews (refute and intended lens, both real with high confidence), the independent reproduction, the intended-behaviour check (real, medium-high), an adjudication (confirmed, high) and a credibility audit rate it real; every check re-ran a repro on the stock jars.
Checks and verdicts422 words
The reviewer from another model family (OpenAI GPT-5.6) ran its own tests in the lenses; its refute-lens tests were re-run on 645d4fe14a20. Every verifier rated the intended-behaviour case (the is-relevant javadoc) moderate and rejected it.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Bounded-exhaustive harness: 10 of 26 token checks and 544 of 625 four-document assignments wrong, all with a negative grade or an odd zero; 0 with the fix. JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3. |
| cross-model review, refute lens | real, high | Own test (grades 3, -2, 0): the -2 document is relevant and maxRecall 2 instead of 1, with -ea, -da and 4 seeds; the binary control passes; the fix passes it and TestQualityRun. Re-run on 645d4fe14a20. |
| Independent reproducer | real | Own 3-test JUnit fails 3 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; the grade 1, 2 and 0 controls hold; read the trec_eval source. |
| Cross-model review, intended lens | real, high | Own test: -2 and -1 relevant, maxRecall 3 instead of 1 on main, 10.5.2 and 9.12.3; passes with the fix. Works-as-designed case moderate, rejected. |
| Devil's advocate | real, medium-high | Built the binary is-relevant case and rejected it; a token probe shows every token except the exact 0 relevant; re-ran the finder's JUnit. |
| adjudication | confirmed, high | Re-ran the independent reproduction's (3 of 3 fail) and the finder's (2 of 2 fail, -da) JUnits, and the independent reproduction's test with its fix (pass). |
| Follow-up, audit, packaging | keep | History on 17 releases and main; two prior-report searches; audit 4 re-ran the finder's JUnit (-da); the one-line test on 645d4fe14a20 and 10.5.2, and with the hunt's fix. |
| this doc's runs | reproduced, fix validated | The test on main 645d4fe14a20 (gradle, asserts on and off) and the 10.6.0 jars; the fix with all lucene/benchmark tests, check -x test and renderJavadoc; the hunt's and the independent reproduction's tests with the fix shadowed. |
| fact checks of the doc | substantively correct; corrections applied | A separate AI tool re-ran the gradle commands in its own scratch worktree, the standalone runner on main, 10.6.0 and 10.5.2, fix A shadowed and the diagram probe (identical values), and counted the official Terabyte qrels grades. An independent reviewer from another model family (OpenAI GPT-5.6) checked the text by reading. Their corrections (trec_eval's parser, the qrels counts, the fix trade-offs, the 2.3.0 date, citations) are in this version. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 566 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,427 words
- Registry title
- TrecJudge counts every qrels grade other than the literal string "0" as relevant, so negative TREC grades (such as -2 for spam pages in TREC Web track qrels) are judged relevant and inflate the relevant-document count, precision, AP and MRR
- Area
- benchmark / search-quality package (trec.TrecJudge, the qrels reader used by QualityBenchmark and QueryDriver)
- Priority
- Low, rank 582: It silently gives wrong precision, AP, MRR and recall in every release since 2.3.0 when qrels have negative grades, as TREC Web track qrels do, but only in the opt-in benchmark evaluation tool and with no effect on any index or search, so it is Low.
- Impact class
- silent wrong results
- Impact note
- Only users of the opt-in lucene/benchmark search-quality package (a developer evaluation tool: QueryDriver, QualityBenchmark or TrecJudge directly) whose qrels file contains negative grades, as TREC Web track 2010-2014 qrels do (-2 for spam or useless pages), get wrong Lucene-computed metrics with no error: every negatively graded document counts as relevant, which raises the relevant-document count (maxRecall, the recall denominator) and changes precision at n, AP, MRR and recall in the per-query and SUMMARY output that QueryDriver prints (in the repro 2 relevant documents instead of 1, P@1 1.0 instead of 0, AP 1.0 instead of 0.5); binary 0/1 qrels and non-negative graded qrels (0..4) give the same answer as trec_eval at its default relevance level, the trec_eval submission file that QueryDriver writes is unaffected, no index or search result is touched, and it is in every release since 2.3.0.
- Summary
- You evaluate search quality with QueryDriver or QualityBenchmark and a TREC qrels file read by TrecJudge, expecting a document to count as relevant only when its grade is 1 or more, as trec_eval counts it. TrecJudge instead treats every grade token except the exact string "0" as relevant, so documents graded -2 (spam or useless, in TREC Web track qrels) or -1 count as relevant: a junk page graded -2 that ranks above the only relevant page gives 2 relevant documents, P@1 1.0 and AP 1.0, where trec_eval gives 1, 0 and 0.5. There is no error or warning.
- Introduced
- 98fa2d898d1882f0bee2ccb7401e1135efd05520, LUCENE-836 'Add support for search quality benchmarking' (SVN r560372, Doron Cohen; review venue JIRA LUCENE-836, migrated as apache/lucene#1911; no PR), which created TrecJudge with String zero = "0"; ... boolean relevant = !zero.equals(st.nextToken()); (now TrecJudge.java:57 and :70) [read: git log --follow, git log -S 'zero.equals' over all refs and git blame -w -M -C -C in the full-history clone; bracketed by execution: 2.2.0 has no quality package, 2.3.0 fails]. Not a regression: the later commits on the file (LUCENE-1257 and LUCENE-2681 generics, LUCENE-2845 and LUCENE-3965 module moves, LUCENE-3949 license header, LUCENE-5512 diamond, a 2017 spelling fix, LUCENE-9570 reformat) left the parse loop unchanged (2007-07-27 (author date = commit date, 2007-07-27T20:24:52Z))
- First affected version
- 2.3.0 (2008-01-23) [exec]; 2.2.0 has no search-quality package [exec: compile error]
- Affected versions
- Every release from 2.3.0 to 10.6.0 (the 154 lucene-benchmark versions on Maven Central up to 10.5.2, and 10.6.0 [exec] on its release jars by the bug doc's test, -ea and -da), plus branch_10_6 and main a9779ef3c193 [read: git tag --contains 98fa2d898d1; TrecJudge.java is blob 43bf121521ff on main a9779ef3c193, branch_10_6 and upstream main 645d4fe14a20] [exec: a version-portable main() repro gives the same wrong values (maxRecall 3 instead of 1, relevant docs 2.0 instead of 1, P@1 1.0 instead of 0, AP 1.0 instead of 0.5) on 17 sampled releases (2.3.0, 2.3.2, 2.4.1, 2.9.4, 3.0.3, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2; -ea, 10.5.2 also -da) and on main a9779ef3c193 (-ea and -da); the finder's JUnit fails 2 of 2 on main a9779ef3c193 (-ea and -da), ea57360912ed, 10.0.0, 10.5.2 (-ea and -da) and 9.12.3; the independent reproduction's JUnit fails 3 of 3 on main (-ea and -da), 10.5.2 and 9.12.3]. Shadowing only TrecJudge.java with the fix sketch makes the portable repro pass on 2.3.0, 8.11.4 and 10.5.2. Not fixed on upstream main 645d4fe14a20 (2026-10-28): TrecJudge.java last changed by 7f8b7ffbcad (LUCENE-9570 reformat, author date 2021-01-03). All runs on Linux aarch64 with JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-28, read-only; the prior-report record, verdict new): 250 follow-up queries (two scripted prior-report searches of 73 queries each over GitHub issues, PRs and commits, downstream trackers, the Lucene and Solr mailing lists, the JIRA archive and the web; 47 manual GitHub issue searches, 4 code searches and 19 issues read with comments; 17 JQL searches over LUCENE, SOLR and LUCENENET; 21 list searches and 10 threads read; the changed-file lists of all 413 open apache/lucene PRs), plus the finder's 51-query run and the independent reproduction, the intended-behaviour check and judge legs. GitHub search 'TrecJudge' over all issues and PRs: 0 items. Closest items, none this bug: a 2010 java-user reply by a committer that the benchmark summary 'often differ[s] with trec_eval' (general, names no class, cause or input; the collections in that thread have no negative grades; a list post); LUCENE-836 (#1911), the introducing issue (binary qrels, no discussion of grades); LUCENE-1116 (#2193), LUCENE-2058 (#3134), LUCENE-1540 (#2614) and other quality-package issues, about other code. The Lucene.NET port (TrecJudge.cs) keeps the same test with no report. Open PRs: only the branch_10x decommission tombstone #16911 lists TrecJudge.java (it deletes every file). Not fixed upstream: TrecJudge.java on upstream main 645d4fe14a20 is blob 43bf121521ff, last changed by 7f8b7ffbcad (LUCENE-9570 reformat, author date 2021-01-03). Refresh (2026-10-28): 'repo:apache/lucene TrecJudge' still 0, 'qrels' 4 (#1911, #3532, #2041, #3345, none about grades), 'trec_eval' 5 (#3263, #9048, #71, #2614, #3134, none about TrecJudge), 'isRelevant maxRecall' 0, 'benchmark quality created:>=2026-10-26' 0; none of the 19 apache/lucene PRs created since 2026-10-26 touches lucene/benchmark/.../quality (first 100 files each; the only larger one is the 7,630-file #16911 tombstone). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28): the one-method repro through gradle in a scratch worktree and through the standalone runner, assertions on and off, stock and with the recommended fix; the 10.6.0 and 10.5.2 release jars (assertions on and off). The hunt, the verifiers and the study's history runs used maina9779ef3c193, whereTrecJudge.javais the same blob; the history runs covered 17 releases from 2.3.0 to 10.5.2. Upstream main on 2026-10-30 (716d6f216f52), branch_10_6 and the 10.6.0 tag have the sameTrecJudge.java.
- Finding record
lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/TrecJudge.java:28-53 (class javadoc 'based on Trec format for judgements'; constructor format 'qnum 0 doc-name is-relevant' with sample grades 1 and 0), 57 (String zero = "0"), 70 (boolean relevant = !zero.equals(st.nextToken())), 72 (only relevant docs kept), 89-93 (isRelevant), 153-161 (maxRecall); QualityBenchmark.java:126 (judge.maxRecall), 137 (judge.isRelevant), 142 (per-query stats log); trec/QueryDriver.java:45-48 (usage 'submission file for trec_eval'), 82 (new TrecJudge(qrelsFile)), 100-101 (SUMMARY log); package-info.java:33-34 ('For benchmarking TREC collections with TREC QRels') [read at the registration check]
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/TrecJudge.java:54-93, :113-115, :153-161a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/QualityBenchmark.java:126, :137-143a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/QualityStats.java:85-100, :122-124, :156-166, :196-235a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:82, :98, :101-102
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/package-info.java:33-34, :54a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:82a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/TrecJudge.java:119-151 (validateData)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/TrecJudge.java:28-30, :41, :47-48, :57, :70a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/package-info.java:33-34, :36-69, :75-77a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/package-info.java:18a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:48a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/test/org/apache/lucene/benchmark/quality/trecQRels.txt (grades 0 and 1 only)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/TrecJudge.java:72-81, :119-151, :153-161; a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/QualityStats.java:201-217; a Lucene main checkout (645d4fe14a20) lucene/benchmark/src/java/org/apache/lucene/benchmark/quality/trec/QueryDriver.java:85 (a query with no kept document: no judgement, maxRecall 0, validateData warning, left out of the average)
- TestTrecJudgeNegativeGrade.java (lucene/benchmark, one test):
repro/LFV-940/src/org/apache/lucene/benchmark/quality/trec/TestTrecJudgeNegativeGrade.java(34 lines)
It is made in parallel with this doc; every on-screen value comes from the code at 645d4fe14a20 or an executed run.
assets/LFV-940/bug.png(566 KB)