The javadoc that documents the default .fnm format lists a field record's bytes in an order the writer has not used since 5.0.0.
- Every Lucene segment has one
.fnmfile. For each field it records the name and number and what is indexed for it: postings options, doc values, points, vectors. - Each codec format class documents its file as a grammar in its class javadoc: an ordered list of named elements, each with a type (Byte, VInt, String, ...). The default codec's file-format overview links these pages "for details".
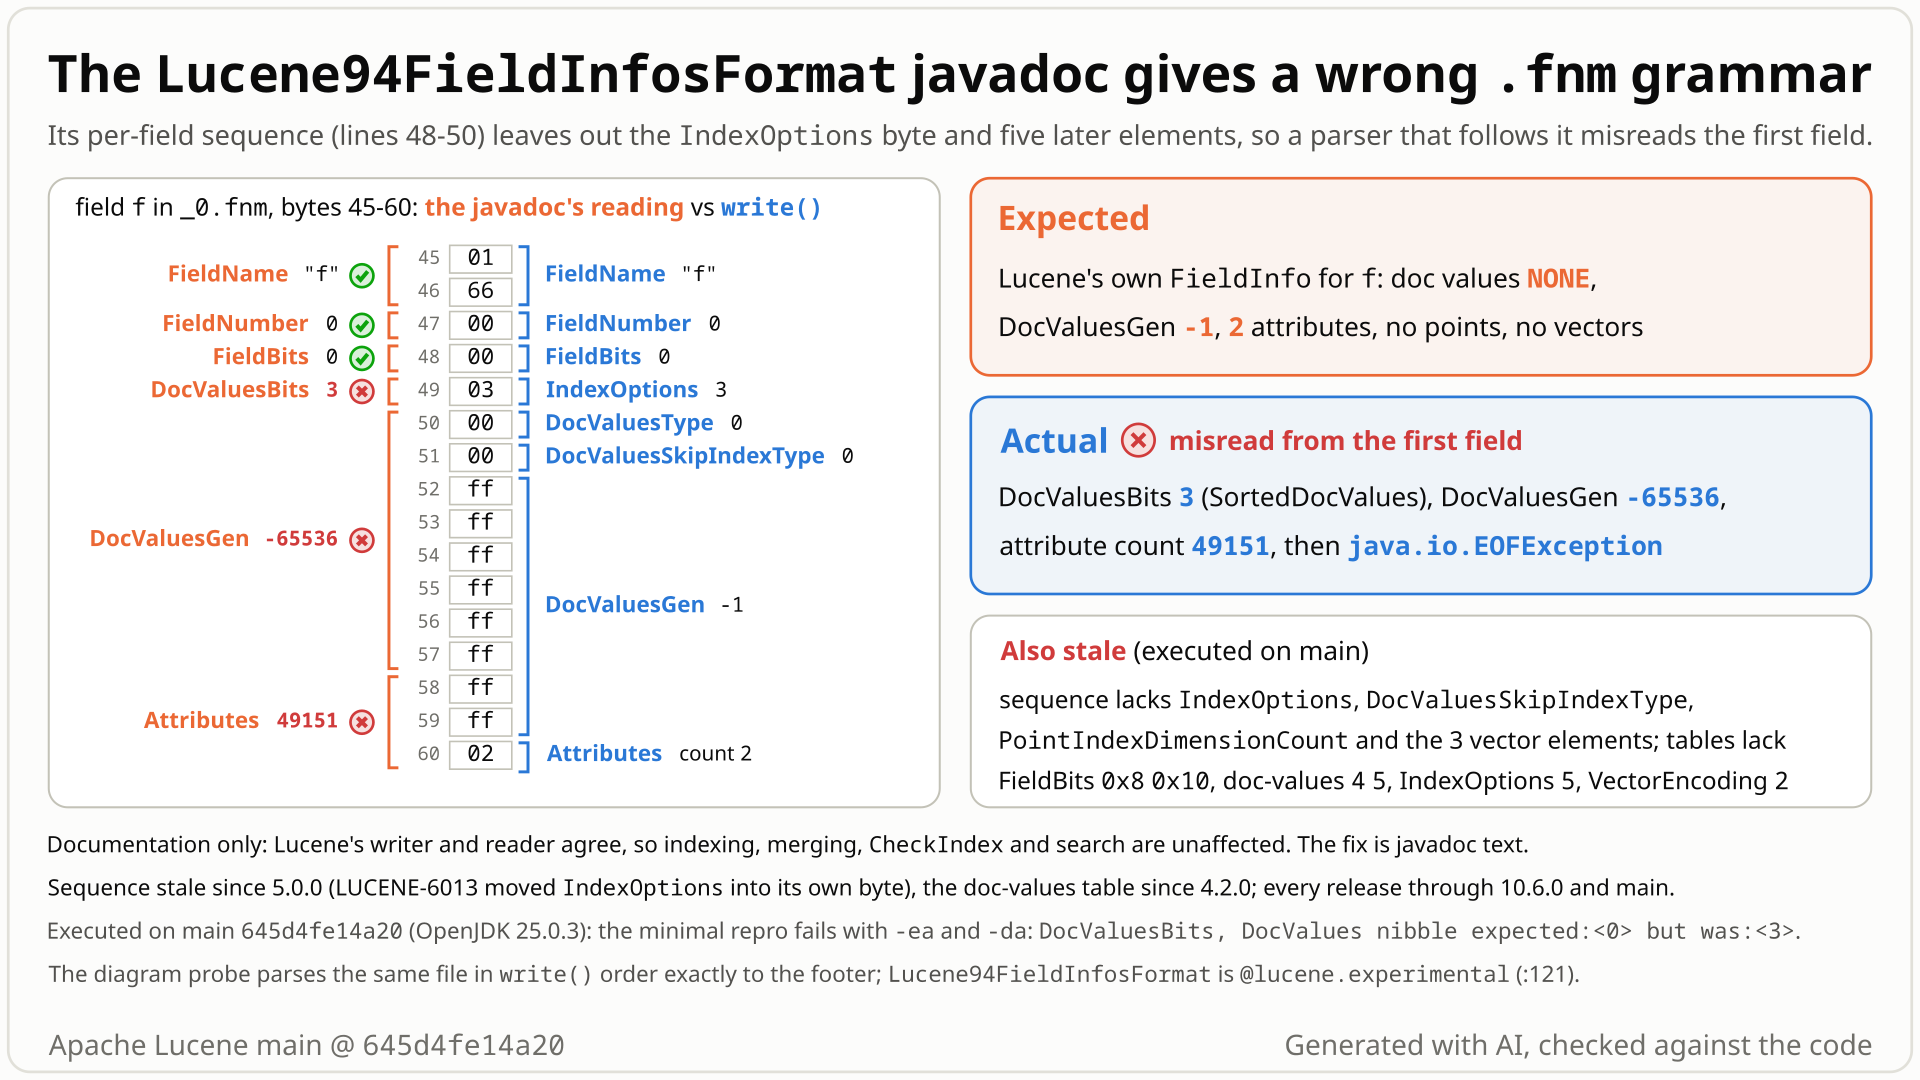
.fnm: the javadoc's reading (left) against the order write() uses (right). The javadoc reads the IndexOptions byte 3 as DocValuesBits, and every later value is off. Select the still to open it at full size. Generated with AI, checked against the code.- You index one document with one text field,
f= "a", with the default codec, and decode its.fnmfile in the order theLucene94FieldInfosFormatjavadoc gives: FieldName, FieldNumber, FieldBits, DocValuesBits, DocValuesGen, ... - You expect FieldName "f", FieldNumber 0 and FieldBits 0, then DocValuesBits 0, because the field has no doc values.
- The first three match, but the next byte is 3, which the javadoc's table reads as "SortedDocValues". From there every value is off: DocValuesGen reads -65536 instead of -1, the attribute count 49151 instead of 2, and the parse runs off the end of the file.
- Why: since 5.0.0 the writer puts an IndexOptions byte right after FieldBits (3 = DOCS_AND_FREQS_AND_POSITIONS). The javadoc lists its type but never placed it in the sequence. Later releases added a skip-index byte, PointIndexDimensionCount and three vector elements, also never placed.
- The tables are stale too: doc-values codes 4 and 5, FieldBits 0x8 and 0x10, IndexOptions 5 and VectorEncoding 2 are written but not listed. Lucene's reader matches its writer, so only the text is wrong.
People who read or re-implement the .fnm format from Lucene's documentation: ports to other languages, index inspectors, recovery tools. For them it fails on the first field of every default-codec .fnm that has at least one field. Lucene users who only call its APIs are not affected; nothing wrong happens at runtime.
Mechanism, terms and numbers674 words
The class javadoc of Lucene94FieldInfosFormat, the field infos format of the default codec (Lucene104Codec.java:72), gives the .fnm file as Header, FieldsCount, <FieldName, FieldNumber, FieldBits, DocValuesBits, DocValuesGen, Attributes, DimensionCount, DimensionNumBytes>^FieldsCount, Footer (Lucene94FieldInfosFormat.java:48-50 on main 645d4fe14a20). The writer (:431-456) writes, per field, FieldName, FieldNumber, FieldBits, IndexOptions, a doc-values type byte, a doc-values skip-index byte, DocValuesGen, Attributes, PointDimensionCount, PointIndexDimensionCount and PointNumBytes only when the dimension count is non-zero, then VectorDimension, VectorEncoding and VectorSimilarityFunction; the reader (:147-213) reads the same order.
IndexOptions is typed as a Byte (:58) but never placed; the skip-index byte and PointIndexDimensionCount appear nowhere; the vector elements are described (:104-118) but not placed. The tables miss written values: DocValuesBits is described as a norms nibble plus a doc-values nibble with codes 0..3 (:88-97), but the byte holds one code, and SORTED_SET is 4 and SORTED_NUMERIC 5; FieldBits lists 0x1, 0x2 and 0x4 but 0x8 (soft-deletes field) and 0x10 (parent field) are set; IndexOptions 5 (since 10.5.0) and VectorEncoding 2 (FLOAT16, main only) are missing.
A parser that follows the javadoc reads a text field's IndexOptions byte (3) as "SortedDocValues" and is misaligned from the first field on. The sequence has been wrong since 5.0.0: LUCENE-6013 moved IndexOptions into its own byte and updated the type list, not the sequence. Later changes edited parts of the javadoc (6.0.0 added the point elements to the sequence, 9.0.0 and 9.4.0 described the vector elements) but none placed IndexOptions or brought the sequence and the tables up to date. Documentation only; the fix is javadoc text.
FieldInfos (.fnm) --> Header,FieldsCount, <FieldName,FieldNumber,
FieldBits,DocValuesBits,DocValuesGen,Attributes,DimensionCount,DimensionNumBytes>
FieldsCount,Footer| # | element | type | in the javadoc sequence? |
|---|---|---|---|
| 1 | FieldName | String | yes |
| 2 | FieldNumber | VInt | yes (typed VInt, linked to writeInt) |
| 3 | FieldBits (0x1, 0x2, 0x4, 0x8 soft-deletes, 0x10 parent) | Byte | yes; 0x8 and 0x10 not in the table |
| 4 | IndexOptions (0..5) | Byte | no (typed at :58, never placed); 5 not in the table |
| 5 | doc-values type (one code 0..5) | Byte | as "DocValuesBits": two nibbles, codes 0..3 |
| 6 | DocValuesSkipIndexType (0..1) | Byte | no (since 10.0.0) |
| 7 | DocValuesGen | Int64 | yes |
| 8 | Attributes | Map<String,String> | yes |
| 9 | PointDimensionCount | VInt | as "DimensionCount" |
| 10 | PointIndexDimensionCount, only if #9 != 0 | VInt | no (since 7.6.0) |
| 11 | PointNumBytes, only if #9 != 0 | VInt | as "DimensionNumBytes", unconditional |
| 12 | VectorDimension | VInt | no (described at :104) |
| 13 | VectorEncoding (0..2) | Byte | no (described at :105-109 with 0..1) |
| 14 | VectorSimilarityFunction (0..3) | Byte | no (described at :110-118) |
For one TextField f = "a", the field record is 01 66 | 00 | 00 | 03 | 00 | 00 | ff ff ff ff ff ff ff ff | 02 ...(2 attributes)... | 00 | 00 | 01 | 00 (dumped by the fix's validation check, which parses it with the corrected grammar exactly to the footer):
- Lucene reads: FieldName "f", FieldNumber 0, FieldBits 0, IndexOptions 3 (DOCS_AND_FREQS_AND_POSITIONS), doc values 0, skip index 0, DocValuesGen -1, 2 attributes (the per-field postings format and suffix), PointDimensionCount 0, VectorDimension 0, VectorEncoding 1 (FLOAT32), similarity 0 (EUCLIDEAN).
- The javadoc's order takes
03as DocValuesBits (low nibble 3 = SortedDocValues), the next 8 bytes,00 00 ff ff ff ff ff ff, as DocValuesGen (-65536, not -1), andff ff 02as the attribute count (49151, not 2); reading 49151 map entries then throwsjava.io.EOFExceptionat the end of the 153-byte file (the diagram's probe, assertions on and off). An independent verifier's literal-sequence test also measured -65536 for point and vector fields.
The first line says "Lucene 9.0 Field Infos format." (:44); the field descriptions call the point elements PointDimensionCount and PointNumBytes (:102) while the sequence says DimensionCount and DimensionNumBytes; and the write() comment "pack the DV type and hasNorms in one byte" (:444) has been wrong since LUCENE-6006 (5.0.0).
Exposure and likelihood201 words
- Who is hit. Anyone who decodes
.fnmfrom the class javadoc instead of fromread(): ports of Lucene to other languages, index inspectors, recovery or forensic tools, and developers learning the format. - Default vs opt-in. The default codec:
Lucene104Codecinstalls this format (Lucene104Codec.java:72), and the file-format overview links this class for the.fnmfile (lucene104/package-info.java:147,:243). Every field record carries the IndexOptions byte, so the mismatch shows on the first field of every default-codec.fnmwith at least one field, whatever the field (a segment with no fields has no field record to misread). - Scale. A parser built from the sequence misreads the first field and every later one; one built from the tables rejects or misreads valid codes (any SORTED_SET or SORTED_NUMERIC field, any index with a soft-deletes or parent field). The hunt's grammar check found the documented grammar diverging on 125 of 125
.fnmfiles from 64 generated default-codec indexes, while the writer's layout parsed all of them to the footer. - What it does not do. No wrong results, no index change, no runtime path: Lucene's writer and reader agree, and
TestLucene94FieldInfosFormatpasses. No earlier report was found. Impact class minor, priority low.
One JUnit test indexes one document with one TextField using the default codec and non-compound files, then reads the .fnm in the documented order. FieldsCount, FieldName, FieldNumber and FieldBits match; the next byte, documented as DocValuesBits, is 3. Deterministic, single thread, about 1.4 s; the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene94;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestLucene94FieldInfosFormatJavadoc extends LuceneTestCase {

  public void testDocumentedFieldSequence() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()).setUseCompoundFile(false);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        Document doc = new Document();
        doc.add(new TextField("f", "a", Field.Store.NO));
        w.addDocument(doc);
      }
      byte[] id = SegmentInfos.readLatestCommit(dir).info(0).info.getId();
      try (IndexInput in = dir.openInput("_0.fnm", IOContext.READONCE)) {
        CodecUtil.checkIndexHeader(in, "Lucene94FieldInfos", 0, Integer.MAX_VALUE, id, "");
        assertEquals("FieldsCount", 1, in.readVInt());
        assertEquals("FieldName", "f", in.readString());
        assertEquals("FieldNumber", 0, in.readVInt());
        assertEquals("FieldBits", 0, in.readByte());
        // expected 0 (no doc values); actual 3: the IndexOptions byte the documented sequence omits
        assertEquals("DocValuesBits, DocValues nibble", 0, in.readByte() & 0x0F);
      }
    }
  }
}
cp TestLucene94FieldInfosFormatJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene94/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene94.TestLucene94FieldInfosFormatJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- After FieldsCount 1, FieldName "f", FieldNumber 0 and FieldBits 0, DocValuesBits reads 0: the field has no doc values.
- Observed
- It reads 3 (
expected:<0> but was:<3>), the IndexOptions byte the documented sequence leaves out; the same with assertions off.
More files, environment, full output239 words
- The test reads the header with
CodecUtil.checkIndexHeaderand then the documented elements one by one. The failing byte is written atLucene94FieldInfosFormat.java:442(indexOptionsByte), right before the real doc-values byte at:445. - Results: fails 1 of 1 on main with assertions on and off (seed DEADBEEF; seed 5EED1234 gives the same message; the test has no random input), standalone and through gradle. The hunt's larger tests, which also check the value tables, fail on main, the 10.6.0 release commit and 10.5.2. On 9.12.3 only its sequence test is evidence (it fails): its value-table test assumes the 10.0 skip-index byte and ends in an
EOFExceptionthere. - Even simpler for a reader: put the sequence line (
:48-50) next towrite()(:431-456). - As a regression test: this test would not guard the javadoc. It transcribes today's documented order, and a doc fix leaves the bytes unchanged, so a regression form would read the corrected order (as the fix's validation check does).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the hunt's tests also fail on the 10.6.0 release commit and 10.5.2, and its sequence test on 9.12.3 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestLucene94FieldInfosFormatJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene94/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene94.TestLucene94FieldInfosFormatJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestLucene94FieldInfosFormatJavadoc > testDocumentedFieldSequence FAILED
    java.lang.AssertionError: DocValuesBits, DocValues nibble expected:<0> but was:<3>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:AF4ECEFFEFFD713C]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
at org.apache.lucene.codecs.lucene94.TestLucene94FieldInfosFormatJavadoc.testDocumentedFieldSequence(TestLucene94FieldInfosFormatJavadoc.java:52)- Written as an exact grammar, every element typed and linked to its writer method; the format overview points readers to it.
- IndexOptions is typed as a Byte but never placed; the 2014 change that split it out updated only the type list.
- The tables are wrong, not abbreviated: a norms nibble gone since 5.0.0, only 4 of 6 doc-values codes.
The full argument206 words
- Contract text.
Lucene94FieldInfosFormat.java:48-62: production notation with every element typed and linked to aDataOutputmethod.lucene104/package-info.java:50: "This document defines the index file formats used in this version of Lucene";:188: "Details on each of these are provided in their linked pages." - History. In LUCENE-6013 (#7075, 2014) the author wrote "I'll update the javadocs for the format changes" and then "New patch, fixing docs"; the type list and the tables were updated, the sequence line was not, and none of the saved issue comments discusses the sequence, so this reads as an omission, not a decision. Later changes that added bytes or values changed the writer and reader together; some edited the javadoc (LUCENE-6861 put the point elements into the sequence, LUCENE-9322 and LUCENE-10577 described the vector elements), but none placed IndexOptions or the newer bytes, and none of their saved PR discussions mentions the stale sequence.
- Tests. No test compares a format javadoc with the bytes.
TestLucene94FieldInfosFormattests codec behaviour (theBaseFieldInfoFormatTestCaseround trips, andtestVectorSimilarityFuncschecksSIMILARITY_FUNCTIONSdirectly) but never compares the javadoc grammar with the written bytes. - Precedent. Upstream has fixed file-format documentation errors of this kind before: LUCENE-713 (#1788), LUCENE-3072 (#4145), LUCENE-7532 (#8583, "Add back lost codec file format documentation").
The devil's-advocate check150 words
Strongest case for "intended" (the refute reviewer, the intended-lens cross-model reviewer and the devil's-advocate verifier; rated moderate): the format classes are @lucene.experimental (:121); LUCENE-2946 (#4020, 2012) moved the file-format docs from "bit-for-bit" to "high-level", and package-info.java:54 still says "This document attempts to provide a high-level definition"; the supported way to read .fnm is FieldInfosFormat.read; and the runtime round trip is tested.
Why it fails: in the same LUCENE-2946 thread rmuir wrote (2012-04-25) "we can go into detail, but we can't do bit-for-bit with even StandardCodec... For the simple metadata files, and even stored fields and postings its fine (for now)", and .fnm is such a simple metadata file. The page is presented in exact-looking production notation; its tables are wrong rather than abbreviated; and @lucene.experimental allows the format to change, not the current format to be described wrongly. Every verifier and the adjudication rejected the "intended" reading.
Recommended A. Rewrite the grammar, type list and tables to match write()
Rewrite the class javadoc to match write(): place IndexOptions, the skip-index byte, the conditional point elements and the three vector elements; note how the older format versions differ; make the doc-values byte one code 0..5; add the missing codes. Javadoc only. Validated: it parses a 12-field segment to the footer; the suite and static checks pass.
All options and trade-offs3 options · 1,408 words
Three ways to resolve it; A was validated. Targets: main and branch_11x, plus branch_10_6 if wanted (branch_10x was decommissioned, #16911). The file is byte-identical on all of them and on the 10.6.0 tag, so the diff applies unchanged; for branch_10_6 drop the FLOAT16 line, since 10.6.0's VectorEncoding has no FLOAT16; the format-version paragraph applies there unchanged (10.6.0 also writes version 2 and reads 0 and 1).
Optional extras for the same change: the write() comment "pack the DV type and hasNorms in one byte" (:444, a code comment, not in the diff), and, on main, the frozen backward-codecs Lucene90FieldInfosFormat, which carries the same stale text (branch_10_6 also has Lucene60FieldInfosFormat).
A. Rewrite the grammar, type list and tables to match write() (validated by the checks) (recommended)
The new sequence is <FieldName,FieldNumber,FieldBits,IndexOptions,DocValuesType,DocValuesSkipIndexType,DocValuesGen,Attributes,PointDimensionCount,PointIndexDimensionCount?,PointNumBytes?,VectorDimension,VectorEncoding,VectorSimilarityFunction>^FieldsCount. The type list names every byte element and links the VInt ones to writeVInt; the tables gain FieldBits 0x8 and 0x10 (linked to IndexWriterConfig#setSoftDeletesField and #setParentField), IndexOptions 5, a single-code doc-values table 0..5, a skip-index table (0 NONE, 1 RANGE) and VectorEncoding 2; IndexOptions 1 is named DOCS, the current enum constant, not DOCS_ONLY; a new paragraph says this is format version 2 (written since 10.0) and that read() also accepts version 1 (9.10-9.12, no DocValuesSkipIndexType byte) and version 0 (9.4-9.9, also never FieldBits 0x10); the first line becomes "Lucene 9.4 Field Infos format.". One file, +32/-14 lines.
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java
index acd4bf55152..b0c37f52dd7 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java
@@ -41,13 +41,18 @@ import org.apache.lucene.store.IndexInput;
import org.apache.lucene.store.IndexOutput;
/**
- * Lucene 9.0 Field Infos format.
+ * Lucene 9.4 Field Infos format.
*
* <p>Field names are stored in the field info file, with suffix <code>.fnm</code>.
*
* <p>FieldInfos (.fnm) --> Header,FieldsCount, <FieldName,FieldNumber,
- * FieldBits,DocValuesBits,DocValuesGen,Attributes,DimensionCount,DimensionNumBytes>
- * <sup>FieldsCount</sup>,Footer
+ * FieldBits,IndexOptions,DocValuesType,DocValuesSkipIndexType,DocValuesGen,Attributes,
+ * PointDimensionCount,PointIndexDimensionCount?,PointNumBytes?,
+ * VectorDimension,VectorEncoding,VectorSimilarityFunction> <sup>FieldsCount</sup>,Footer
+ *
+ * <p>This is format version 2, written since Lucene 10.0. The reader also accepts version 1 (Lucene
+ * 9.10 to 9.12), which has no DocValuesSkipIndexType byte, and version 0 (Lucene 9.4 to 9.9), which
+ * in addition never sets FieldBits 0x10.
*
* <p>Data types:
*
@@ -55,8 +60,10 @@ import org.apache.lucene.store.IndexOutput;
* <li>Header --> {@link CodecUtil#checkIndexHeader IndexHeader}
* <li>FieldsCount --> {@link DataOutput#writeVInt VInt}
* <li>FieldName --> {@link DataOutput#writeString String}
- * <li>FieldBits, IndexOptions, DocValuesBits --> {@link DataOutput#writeByte Byte}
- * <li>FieldNumber, DimensionCount, DimensionNumBytes --> {@link DataOutput#writeInt VInt}
+ * <li>FieldBits, IndexOptions, DocValuesType, DocValuesSkipIndexType, VectorEncoding,
+ * VectorSimilarityFunction --> {@link DataOutput#writeByte Byte}
+ * <li>FieldNumber, PointDimensionCount, PointIndexDimensionCount, PointNumBytes, VectorDimension
+ * --> {@link DataOutput#writeVInt VInt}
* <li>Attributes --> {@link DataOutput#writeMapOfStrings Map<String,String>}
* <li>DocValuesGen --> {@link DataOutput#writeLong(long) Int64}
* <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
@@ -76,36 +83,47 @@ import org.apache.lucene.store.IndexOutput;
* <li>If the second lowest order-bit is set (0x2), norms are omitted for the indexed field.
* <li>If the third lowest-order bit is set (0x4), payloads are stored for the indexed
* field.
+ * <li>If the fourth lowest-order bit is set (0x8), the field is the soft-deletes field (see
+ * {@link org.apache.lucene.index.IndexWriterConfig#setSoftDeletesField}).
+ * <li>If the fifth lowest-order bit is set (0x10), the field is the parent field (see
+ * {@link org.apache.lucene.index.IndexWriterConfig#setParentField}).
* </ul>
* <li>IndexOptions: a byte containing index options.
* <ul>
* <li>0: not indexed
- * <li>1: indexed as DOCS_ONLY
+ * <li>1: indexed as DOCS
* <li>2: indexed as DOCS_AND_FREQS
* <li>3: indexed as DOCS_AND_FREQS_AND_POSITIONS
* <li>4: indexed as DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS
+ * <li>5: indexed as DOCS_AND_CUSTOM_FREQS
* </ul>
- * <li>DocValuesBits: a byte containing per-document value types. The type recorded as two
- * four-bit integers, with the high-order bits representing <code>norms</code> options, and
- * the low-order bits representing {@code DocValues} options. Each four-bit integer can be
- * decoded as such:
+ * <li>DocValuesType: a byte containing the field's doc values type:
* <ul>
* <li>0: no DocValues for this field.
* <li>1: NumericDocValues. ({@link DocValuesType#NUMERIC})
- * <li>2: BinaryDocValues. ({@code DocValuesType#BINARY})
- * <li>3: SortedDocValues. ({@code DocValuesType#SORTED})
+ * <li>2: BinaryDocValues. ({@link DocValuesType#BINARY})
+ * <li>3: SortedDocValues. ({@link DocValuesType#SORTED})
+ * <li>4: SortedSetDocValues. ({@link DocValuesType#SORTED_SET})
+ * <li>5: SortedNumericDocValues. ({@link DocValuesType#SORTED_NUMERIC})
+ * </ul>
+ * <li>DocValuesSkipIndexType: a byte containing the type of the doc values skip index:
+ * <ul>
+ * <li>0: no skip index. ({@link DocValuesSkipIndexType#NONE})
+ * <li>1: a skip index over value ranges. ({@link DocValuesSkipIndexType#RANGE})
* </ul>
* <li>DocValuesGen is the generation count of the field's DocValues. If this is -1, there are no
* DocValues updates to that field. Anything above zero means there are updates stored by
* {@link DocValuesFormat}.
* <li>Attributes: a key-value map of codec-private attributes.
- * <li>PointDimensionCount, PointNumBytes: these are non-zero only if the field is indexed as
- * points, e.g. using {@link org.apache.lucene.document.LongPoint}
+ * <li>PointDimensionCount: it is non-zero only if the field is indexed as points, e.g. using
+ * {@link org.apache.lucene.document.LongPoint}. PointIndexDimensionCount and PointNumBytes
+ * follow only if it is non-zero.
* <li>VectorDimension: it is non-zero if the field is indexed as vectors.
* <li>VectorEncoding: a byte containing the encoding of vector values:
* <ul>
* <li>0: BYTE. Samples are stored as signed bytes
* <li>1: FLOAT32. Samples are stored in IEEE 32-bit floating point format.
+ * <li>2: FLOAT16. Samples are stored in IEEE 16-bit floating point format.
* </ul>
* <li>VectorSimilarityFunction: a byte containing distance function used for similarity
* calculation.Trade-offs
- The
?marks for the two conditional point elements follow the notation the default postings format javadoc already uses (Lucene104PostingsFormat.java:104); the description says they follow only when PointDimensionCount is non-zero. - Renaming DocValuesBits to DocValuesType is the one cosmetic choice; keeping the old name gives a smaller diff, but the text must still say the byte is a single code.
DOCVALUES_SKIPPER= 0x20 (:479, a leftover of #13449 that #13784 replaced before any release) is never written, so the text leaves it out.- The grammar is the current writer layout (format version 2,
FORMAT_CURRENTat:467-471, written at:424).read()also accepts versions 0 and 1 (:138-145): it reads the skip-index byte only from version 2 (:189-194) and rejects the 0x10 bit below version 1 (:165-176);FORMAT_CURRENTis 0 at the 9.4.0-9.9.2 tags and 1 at 9.10.0-9.12.3. The fix states this in one paragraph; the validation parses current-format files only. - If the open WIP PR #13525 (multi-vector) lands, it adds one more element to the same grammar.
What the checks validated
Validated on 2026-11-01 in scratch worktrees of 645d4fe14a20 with the diff applied (removed afterwards), seed DEADBEEF, first for the first version of the diff and again for the final one shown here (format-version paragraph and the DOCS name added after the fact checks):
- Fixed-text check (a validation helper, not the repro): a parser written from the new text, with the corrected value tables transcribed from it, reads the repro's one-field
.fnmand a 12-field segment (11 fields plus the parent fieldsetParentFieldadds) with every element and every new value (FieldBits 0x1, 0x2, 0x8, 0x10; IndexOptions 1, 3 and 5; doc-values 1, 4 and 5; skip index 1; aLongPointwith PointIndexDimensionCount 1 and PointNumBytes 8; FLOAT32 and FLOAT16 vectors) exactly to the footer, every value equal to Lucene's reader: 2 of 2 pass with assertions on and off. It covers the current writer layout (format version 2) only; the sentence on versions 0 and 1 rests on readingread()andFORMAT_CURRENTat the release tags. ./gradlew :lucene:core:test --tests TestLucene94FieldInfosFormat --tests TestLucene94FieldInfosFormatFixedJavadoc: 14 tests (the suite's 12, the check's 2), BUILD SUCCESSFUL with assertions on and off, for both versions of the diff.:lucene:core:check -x test(ecjLint, forbiddenApis, google-java-format, licenses) and:lucene:core:renderJavadoc: BUILD SUCCESSFUL for both versions; the rendered page of the final one shows the new sequence, the format-version paragraph and1: indexed as DOCS. google-java-format rewrapped two list items of the first draft and the new paragraph of the final one; the diff shown is the formatted one.- The minimal repro still fails on the patched tree (
expected:<0> but was:<3>, first version), as it must: a javadoc fix leaves the bytes unchanged. - The full Lucene test suite was not run (javadoc-only change).
Insert IndexOptions and the skip-index byte and add PointIndexDimensionCount and the vector elements to the sequence; leave the tables.
Trade-offs
- Fixes the alignment, which breaks a parser first.
- Leaves the norms-nibble description and the missing codes, so a parser built from the tables still rejects valid files (any SORTED_SET field, any soft-deletes index).
What the checks validated
Not run.
Keep only the prose and say that the .fnm layout is defined by write() and read().
Trade-offs
- Nothing left to drift; fits LUCENE-2946's "high-level" direction.
- Removes the only written description of the default
.fnmformat, which the file-format overview promises (package-info.java:188).
What the checks validated
Not run.
Downstream relevance only for tools that parse .fnm themselves from this javadoc; Lucene, and products that read indexes through Lucene, are unaffected.
Non-formal at first: a probe parsed a default-codec .fnm with the javadoc's grammar and compared it with Lucene's reader. A semi-formal differential check then parsed 125 .fnm files from 64 generated indexes with the documented grammar and with the writer's: all 125 diverge, while the writer's grammar parses every file to the footer.
The method in full154 words
- First probe (2026-10-28): parsed one default-codec
.fnmby the class javadoc and compared every value with Lucene's reader: out of sync at the first field, doc-values codes 4 and 5, FieldBits 0x8 (main, assertions on and off). - Hunt unit: every file grammar written as data; the documented grammar transcribed only from the javadoc, the layout grammar from the writer; one interpreter over the real bytes of 64 generated default-codec indexes (1114 file checks). For
.fnm, 125 of 125 files diverge; the layout grammar parses all of them exactly to the footer (positive control), and 14 of 14 single-element layout mutants across the check's 7 formats are caught (vacuity check), both.fnmones (drop DocValuesSkipIndex, drop VectorSimilarityFunction) included. An alignment of the two grammars gave the element-level diff: the skip-index byte, PointIndexDimensionCount, the vector elements, FieldBits 0x10, IndexOptions 5 and VectorEncoding 2. - This is a differential grammar check, not model checking or a proof.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-28, rechecked 2026-11-01). Nearest: LUCENE-6013 (#7075), the change that left the sequence stale. Not fixed upstream.
Searches3 searches
- Related, not this bug: #7075 / LUCENE-6013 (made the sequence stale; no one noted it); #13449, #13784, #12829, #15584, #16383 (added bytes or values; none mentions the class javadoc); #11818 (a different, fixed defect in the same class: the codec header name in code); #4020 / LUCENE-2946 (the 2012 doc policy); #1788, #4145, #8583 (older file-format doc fixes in other files); #16939 (closed: a broken link to the file-formats page in the 10.6.0 docs, not this text).
- Open work on the class: #16863 changes
read()and imports in this class, not the javadoc; open WIP #13525 adds one javadoc bullet for a new multi-vector byte and leaves the stale grammar. A series of javadoc-vs-code fixes (issues #16821-#16828, #16920-#16922, #16927, #16928, #16933-#16936 and PR #16949) has no file-format grammar item. - Not fixed upstream: upstream main
f815e679bf6c(2026-11-01),branch_10_6andbranch_11xhold the same file; its latest commit is still #15584 (2026-04-24), which did not touch the javadoc.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; the JIRA archive; downstream repositories | 2026-10-28 | 61 scripted prior-report queries (over GitHub issues, PRs and commits, downstream repositories, JIRA, the lists and the web); 45 manual apache/lucene searches (class names, DocValuesBits, FieldBits, docValuesByte, indexOptionsByte, SOFT_DELETES_FIELD, PARENT_FIELD_FIELD, DocValuesSkipIndexType, DOCS_AND_CUSTOM_FREQS, FLOAT16, "file format" with javadoc/wrong/outdated/stale, LUCENE-6013); 24 downstream and GitHub-wide searches; 12 JIRA queries (4 of them scripted); the changed files of all 413 open PRs; a pickaxe over the javadoc lines in the full history | no report; in apache/lucene issues, PRs and commits, DocValuesBits, IndexOptions byte fnm and docValuesByte SORTED_SET have 0 hits (the few downstream and JIRA results for such terms were judged unrelated); two open PRs touch the file, neither fixes the text |
| Mailing lists and web | 2026-10-28 | 38 queries over dev@, java-user@, issues@ and commits@ (20 of them scripted, counted in the 61 above); 16 web searches (8 of them scripted) | no thread about the .fnm javadoc; only mirrors of old 4.x format pages |
| apache/lucene (recheck) | 2026-11-01 | upstream main HEAD and the file's commits; the file blob on main, branch_10_6 and branch_11x; 7 searches over items updated since 2026-10-28 (Lucene94FieldInfosFormat, FieldInfosFormat javadoc, fnm javadoc, DocValuesBits, fnm format, field infos format javadoc, file format javadoc) with a control search; the changed files of every open PR | no report (0 hits; the control search returns 20 unrelated items); only #16863, #13525 and #16480 touch a FieldInfosFormat file or the codec overview, none fixing this |
Sequence wrong since 5.0.0 (LUCENE-6013, 2014); doc-values table incomplete since 4.2.0; later format changes (points, soft deletes, vectors, parent field, skip index, new codes) edited the javadoc at most in part and never placed IndexOptions. 4.10.4 parses as documented; every release from 5.0.0 on, and main, does not.
Versions tested4 rows
- Primary part: LUCENE-6013 (#7075, SVN era), mikemccand,
8f9f8a3252c(trunk) /9ac215e4f99(branch_5x), author date 2014-10-21, released in 5.0.0: IndexOptions moved out of FieldBits into its own byte, added to the type list and tables, not to the sequence. - Layers (each changed writer and reader together; where it edited the javadoc, as noted, it did not bring the sequence and tables up to date; a single hash is a main commit, and a release on another branch got the change through a backport): SORTED_SET = 4
b44aa618348(LUCENE-4765, 4.2.0); SORTED_NUMERIC = 5398af4596bd(LUCENE-5748, 4.9.0); norms nibble dropped78e445ce579(LUCENE-6006, 5.0.0); conditional DimensionNumBytesd3869edb96d(LUCENE-6861, 6.0.0; it added DimensionCount and DimensionNumBytes to the sequence, both unconditional); FieldBits 0x8e7a0a12926c(LUCENE-8335, 7.4.0); PointIndexDimensionCount1118299c338(LUCENE-8496, 7.6.0); vector elementsc02f07f2d5d(LUCENE-9322, 9.0.0; described, not placed); theLucene94FieldInfosFormatclass, copied from the stale Lucene90 text with a VectorEncoding byte described but not placed,a693fe819b0(#1054, 9.4.0); FieldBits 0x10df6bd25ce44(#12829, 9.10.0); skip-index byteb59a357e586(#13784, 10.0.0); IndexOptions 55158a52a082(#15584, 10.5.0); VectorEncoding 2bfe5c847d3c(#16383, main only). - From 5.0.0 to 9.3.0 the stale sequence sat in the then-default
Lucene50,Lucene60andLucene90FieldInfosFormat; 9.4.0 is the first release of the current class. On main only the frozen backward-codecsLucene90FieldInfosFormatremains (Lucene60FieldInfosFormatwas removed byaf85bbcf1c0, #15712, and is still onbranch_10_6;Lucene50FieldInfosFormatby4b3e8d7ce8f, LUCENE-9627). - Caveats: 8.9.0-8.11.3 are not tagged in the history clone (javadoc read at 8.8.x, behaviour run on 8.11.4); the later layers' PR numbers and dates come from git log reads, not a bisect.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (and a9779ef3c193) | affected | the minimal repro fails with assertions on and off; the hunt's tests fail on the sequence, codes 4 and 5, FieldBits 0x8 and 0x10, IndexOptions 5 and VectorEncoding 2 |
10.6.0 (release commit 4ae946e5a9b), 10.5.2 | affected | the finder's tests fail 2 of 2; IndexOptions 5 is written on 10.5.2 |
| 10.0.0, 9.12.3, 9.4.0, 9.0.0, 8.11.4, 7.6.0, 6.0.0, 5.0.0 | affected | the documented sequence fails on the first field (history probes) |
| 4.10.4, 4.2.0 | partly | the documented sequence parses to the footer; only the doc-values table misses code 4 (and 5 from 4.9.0) |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication (high confidence); an audit confirmed it as a low-priority doc defect. This doc's gradle run validated the fix.
Checks and verdicts441 words
Every check either re-ran a test on main or read the same javadoc and writer lines; none found a reading under which the documented sequence is meant to differ from the bytes.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, refute lens (OpenAI GPT-5.6, executing) | real, high confidence | Its own StringField test reads the IndexOptions byte (1 = DOCS) where DocValuesBits is documented, on four seeds with assertions on and off; its empty-document control passes; intended argument moderate. |
| independent reproducer | real | Own tests fail 4 of 5 on main (on and off), 3 of 4 on 10.5.2 and 9.12.3; even a generous reading with IndexOptions inserted diverges on every field (DocValuesGen -256 on main, from the skip-index byte); its writer-layout control parses to the footer. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, high confidence | It could not run any code, so it read only; a separate run re-ran the finder's test with assertions off: 2 of 2 fail. Intended argument moderate. |
| intended-behaviour devil's advocate | real (documentation defect) | Built and rejected the LUCENE-2946 / @lucene.experimental case; showed IndexOptions 5 is written on 10.5.2 too and FLOAT16 writes 2 on main. |
| adjudication | confirmed, high confidence, documentation defect, minor | Re-ran the independent reproduction's tests with assertions on and off (5 run, 4 failed, control passes) and read the javadoc, writer and reader lines. |
| credibility audit | confirmed, minor | Re-ran the finder's test on a new seed: 2 of 2 fail. Its "committer view" is the AI auditor's own simulated judgement, not a statement by any Lucene committer: a javadoc-only PR would likely merge without much discussion. |
| fact checks of this doc (2026-11-01; Claude, and OpenAI GPT-5.6 as an independent reviewer from another model family) | bug holds; text errors fixed | Both re-ran the repro (fails 1 of 1, assertions on and off) and re-read the code lines, history and sources; the bug, impact and classification hold. They found text errors (field count of the validation segment, which backward-codecs copies exist on main, a seed claim, the mutant scope, the 9.12.3 evidence, the format versions the grammar covers, the DOCS_ONLY name, the zero-field case, the later javadoc edits, the test description and the scope of a 0-hit search). All are fixed here; the fix diff was revised and re-validated. |
| this doc's validation (2026-11-01) | fix A validated | In scratch worktrees with fix A (first and final version): the fixed-text check parses the repro's file and a 12-field segment to the footer (on and off); TestLucene94FieldInfosFormat (12 tests), :lucene:core:check -x test and renderJavadoc pass; the repro fails through gradle on stock, on and off. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 427 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,828 words
- Registry title
- The file-format javadoc of the default field infos format (Lucene94FieldInfosFormat) gives a wrong .fnm grammar: the per-field sequence leaves out IndexOptions, the doc-values skip-index byte, PointIndexDimensionCount and the three vector elements, and the value tables miss written values (doc-values codes 4 and 5, FieldBits 0x8 and 0x10, IndexOptions 5 since 10.5.0, VectorEncoding 2 on main) (documentation defect; the writer and reader agree)
- Area
- codecs / field infos (Lucene94FieldInfosFormat .fnm file-format javadoc vs its writer and reader)
- Priority
- Low, rank 1278: The default .fnm grammar has been wrong since 5.0 and misleads a re-implementer on the first field of every index.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so indexing, merging, CheckIndex and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement the .fnm format from this class javadoc (Lucene104Codec installs this format and the default codec's package docs link it for the details), and a parser that follows the documented sequence misreads the first field of every .fnm the default codec writes, then every later field (executed); the sequence has been wrong in every release since 5.0.0 (2015), the doc-values value table since 4.2.0, and no scale or special setting is needed.
- Summary
- You decode a field infos (.fnm) file of the default codec by following the Lucene94FieldInfosFormat javadoc, which gives each field as FieldName, FieldNumber, FieldBits, DocValuesBits, DocValuesGen, Attributes, DimensionCount, DimensionNumBytes, documents DocValuesBits as a norms nibble plus a doc-values nibble with codes 0..3, and lists only FieldBits 0x1, 0x2 and 0x4. The writer instead puts an IndexOptions byte right after FieldBits, writes a single doc-values code (SORTED_SET = 4, SORTED_NUMERIC = 5) followed by a skip-index byte, writes PointIndexDimensionCount and PointNumBytes only when the dimension count is non-zero, appends VectorDimension, VectorEncoding and VectorSimilarityFunction, and sets FieldBits 0x8 (soft-deletes field) and 0x10 (parent field), so a parser built from the text reads the IndexOptions byte of a text field (3) as 'SORTED doc values' and loses alignment on the first field. Lucene's own reader matches the writer, so nothing breaks at runtime; only the documentation is wrong, and its sequence has been since 5.0.0.
- Introduced
- layered [follow-up]. Primary part (the per-field sequence): 8f9f8a3252c73428e67bc5d390e58d1370e060ba (trunk) / 9ac215e4f99a8813b23ad700a05b154b37f728ff (branch_5x, the commit that shipped in 5.0.0), LUCENE-6013 'remove IndexableFieldType.indexed and FieldInfo.indexed' (now apache/lucene#7075; SVN era, no GitHub PR), by mikemccand: it moved IndexOptions out of FieldBits into its own byte written after FieldBits and added it to the type list and the tables but not to the sequence [read: git show in the full-history clone; exec: the documented sequence parses on 4.10.4 and fails on 5.0.0, where the same sequence with IndexOptions inserted parses]. Every other layer changed the writer and reader together and left the javadoc as it was: DocValuesBits table 0..3 without SORTED_SET = 4 since b44aa618348 (LUCENE-4765, 4.2.0) and SORTED_NUMERIC = 5 since 398af4596bd (LUCENE-5748, 4.9.0); norms nibble dropped by 78e445ce579 (LUCENE-6006, 5.0.0); DimensionNumBytes written only for point fields since d3869edb96d (LUCENE-6861, 6.0.0); FieldBits 0x8 e7a0a12926c (LUCENE-8335, 7.4.0); PointIndexDimensionCount 1118299c338 (LUCENE-8496, 7.6.0); vector elements c02f07f2d5d (LUCENE-9322, 9.0.0); the Lucene94 class itself a693fe819b0 (apache/lucene#1054, LUCENE-10577, 9.4.0), which copied the stale Lucene90 text and added a VectorEncoding byte, described but not placed; FieldBits 0x10 df6bd25ce44 (#12829, 9.10.0); skip-index byte b59a357e586 (#13784, 10.0.0); IndexOptions 5 5158a52a082 / branch_10x 3a55cc9ac5e (#15584, 10.5.0); VectorEncoding 2 bfe5c847d3c (#16383, main only) [read: git log in the full-history clone, subjects and author dates checked at the registration check; exec: a before/after release pair, or a compile error where the API did not exist yet, for each layer] (2014-10-21 (author date of 8f9f8a3252c and 9ac215e4f99: the per-field sequence); 2013-02-20 (author date of b44aa618348: the first value missing from the DocValuesBits table); later layers 2014-06-12 to 2026-07-27 (see introduced_commit))
- First affected version
- 5.0.0 [exec] for the per-field sequence (the last unaffected release is 4.10.4 [exec], whose documented Lucene46FieldInfosFormat sequence parses the file exactly to the footer); 4.2.0 [exec] for the incomplete DocValuesBits table; 9.4.0 [exec] is the first release of Lucene94FieldInfosFormat (5.0.0-9.3.0 carry the same text in the then-default Lucene50, Lucene60 and Lucene90FieldInfosFormat)
- Affected versions
- every release from 5.0.0 through 10.6.0 for the sequence (4.2.0-4.10.4 for the DocValuesBits table only; 10.6.0 run as its release revision, the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream [exec: per-release public-API history probes fail the documented sequence on 5.0.0, 5.5.5, 6.0.0, 7.5.0, 7.6.0, 8.11.4, 9.0.0, 9.3.0, 9.4.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) and pass on 4.2.0 and 4.10.4, with the writer-layout control parsing in every run; value-table probes fail from each value's first release (codes 4 and 5 on 4.2.0 and 4.9.0, FieldBits 0x8 on 7.4.0, PointIndexDimensionCount on 7.6.0, FieldBits 0x10 on 9.10.0, IndexOptions 5 on 10.5.0, VectorEncoding 2 on main) and do not compile on the release before, where the API did not exist; the finder's JUnit fails 2 of 2 on 10.0.0, 10.5.2, the branch_10_6 head and main (-ea and -da), and its sequence test fails on 9.4.0 and 9.12.3 (on 9.x its value-table test's own layout assumes the 10.0 skip-index byte, so that EOF is not evidence); the independent reproduction's JUnit fails 4 of 5 on main (-ea and -da) and 3 of 4 on 10.5.2 and 9.12.3, with its writer-layout control passing; read: the javadoc sequence line and the 0..3 table in the release sources of every tagged release 4.2.0-10.5.2]. Per part: IndexOptions missing from the sequence and the stale norms nibble 5.0.0 on; doc-values code 4 4.2.0 on, code 5 4.9.0 on; conditional DimensionNumBytes 6.0.0 on; FieldBits 0x8 7.4.0 on; PointIndexDimensionCount 7.6.0 on; vector elements 9.0.0 on (VectorEncoding 9.4.0 on); FieldBits 0x10 9.10.0 on; skip-index byte 10.0.0 on; IndexOptions 5 10.5.0 on (also branch_10x and branch_10_6); VectorEncoding 2 main only. Caveats: 8.9.0-8.11.3 are not tagged in the history clone (javadoc read at 8.8.x, behaviour executed on 8.11.4); upstream main 645d4fe14a20 (2026-10-28) holds a byte-identical file; all runs used JDK 25 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-28: 61 scripted prior-report queries over GitHub issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and downstream repositories, plus 45 manual apache/lucene GitHub searches, 24 downstream and global GitHub searches, 8 JIRA, 18 list and 8 web queries; 'DocValuesBits', 'IndexOptions byte fnm' and 'docValuesByte SORTED_SET' have 0 hits; all 413 open apache/lucene PRs enumerated by changed files and the 22 PRs closed since 2026-10-25 checked; pickaxe over the javadoc lines in the full-history clone). Nearest items, not the same bug: #7075 / LUCENE-6013 (the change that left the sequence stale; its author wrote 'I'll update the javadocs for the format changes' and nobody discussed the sequence), #13449, #13784, #12829, #15584 and #16383 (the changes that added bytes or values; none mentions the class javadoc), #11818 (a different defect in the same class, the codec header name in code, fixed 2022), #4020 / LUCENE-2946 (2012 policy for high-level file-format docs), #1788 / LUCENE-713, #4145 / LUCENE-3072 and #8583 / LUCENE-7532 (precedents: file-format doc errors fixed upstream). Open work, not prior art: #16863 changes read() in this class without touching the javadoc; open draft #13525 adds a javadoc line for a new multi-vector byte and leaves the stale sequence and tables; an ongoing series of javadoc-vs-code issues (16 issues, #16821-#16828, #16920-#16922, #16927, #16928, #16933-#16935) contains no file-format grammar item. Recheck (2026-10-28): none of the 30 apache/lucene issues and PRs created since 2026-10-26 is about the .fnm javadoc; 'Lucene94FieldInfosFormat' returns only #16863, #16211, #16506, #13449, #11818 and #11755, and 'FieldInfosFormat javadoc', 'fnm javadoc', 'DocValuesBits', 'fnm grammar' and 'field infos format documentation' return nothing; none of the open PRs created since 2026-10-27 changes a FieldInfosFormat file or lucene104/package-info.java; by author date the file's latest upstream commits are 5158a52a082 (2026-04-24, #15584), b59a357e586 (2024-09-17, #13784) and 3da48d0403e (2024-09-11, #13759); upstream main head 645d4fe14a20 (2026-10-28) still has the stale text. Not fixed upstream
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone (seeds DEADBEEF and 5EED1234) and through gradle in a scratch worktree (on and off); fix A in that worktree: the fixed-text check (on and off),TestLucene94FieldInfosFormat,:lucene:core:check -x testand:lucene:core:renderJavadoc. The hunt's and the verifiers' tests on maina9779ef3c193, 10.5.2, 9.12.3 and the 10.6.0 release commit4ae946e5a9b; history probes on releases from 4.2.0 to 10.5.2 and main.Lucene94FieldInfosFormat.javais byte-identical (blobacd4bf55152) on645d4fe14a20,a9779ef3c193, upstream mainf815e679bf6c(2026-11-01),branch_10_6,branch_11xand the 10.6.0 tag (read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java:44 ('Lucene 9.0 Field Infos format.'), :48-50 (documented sequence), :58 (FieldBits, IndexOptions, DocValuesBits --> Byte; IndexOptions never placed), :59 (FieldNumber, DimensionCount, DimensionNumBytes labelled VInt, linked to writeInt), :72-79 (FieldBits 0x1, 0x2, 0x4 only), :80-87 (IndexOptions 0..4), :88-97 (DocValuesBits as two four-bit integers, norms high, codes 0..3), :102-118 (point and vector elements described, not placed; VectorEncoding 0..1), :121 (@lucene.experimental), :147-213 (reader mirrors the writer), :258-276 (docValuesByte: SORTED_SET 4, SORTED_NUMERIC 5), :370-388 (indexOptionsByte: DOCS_AND_CUSTOM_FREQS 5), :427-457 (writer, incl. the comment 'pack the DV type and hasNorms in one byte'), :477-478 (SOFT_DELETES_FIELD 0x8, PARENT_FIELD_FIELD 0x10); identical at Lucene main ea57360912ed (compared 2026-10-28)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java:72 (the default codec installs new Lucene94FieldInfosFormat()) and lucene104/package-info.java:50 ('defines the index file formats used in this version'), :54 ('a high-level definition'), :147 and :243 (links Lucene94FieldInfosFormat), :188 ('Details on each of these are provided in their linked pages')lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene90/Lucene90FieldInfosFormat.java:48, :57 (the same stale text in the frozen read-only copy; the Lucene50 and Lucene60 copies no longer exist on main)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java (lines 44, 48-50, 55-62, 72-118 javadoc; 147-213 read(); 258-276 docValuesByte; 370-388 indexOptionsByte; 427-457 write(); 474-479 flag constants)lucene/core/src/java/org/apache/lucene/index/VectorEncoding.java (lines 29, 32, 38: BYTE, FLOAT32, FLOAT16) and index/IndexOptions.java (line 56)lucene/core/src/java/org/apache/lucene/store/DataInput.java (lines 102-108, 146-148: little-endian readInt/readLong)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java (line 72) and codecs/lucene104/package-info.java (lines 50, 147, 188, 243)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene94/Lucene94FieldInfosFormat.java (lines 48-62, 121) and lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 54, 188)lucene/core/src/test/org/apache/lucene/codecs/lucene94/TestLucene94FieldInfosFormat.java (lines 25-39: testVectorSimilarityFuncs)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexOptions.java (line 36: DOCS)a Lucene clone tags releases/lucene/9.4.0, 9.9.2, 9.10.0, 9.12.3, 10.0.0 (Lucene94FieldInfosFormat FORMAT_CURRENT 0, 0, 1, 1, 2)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java (line 104, the ? notation)a Lucene clone tag releases/lucene/10.6.0 (VectorEncoding.java: no FLOAT16; Lucene94FieldInfosFormat.java blob acd4bf55152)
- TestLucene94FieldInfosFormatJavadoc.java (JUnit, one test):
repro/LFV-942/src/org/apache/lucene/codecs/lucene94/TestLucene94FieldInfosFormatJavadoc.java(56 lines)
Made from the code at 645d4fe14a20 and an executed probe on the minimal repro's index (the same bytes parsed in the javadoc's order and in write()'s order, assertions on and off), in parallel with this doc.
assets/LFV-942/bug.png(427 KB)