The documented layout misses four fields the writer writes, gives NameCounter the wrong type, and links little-endian writers for fields written big-endian.
- Every commit writes a small file
segments_N(N is the commit generation) that lists the index's segments: name, id, codec, deletes and update generations. Lucene reads it back withSegmentInfos.readCommit. - The
SegmentInfosclass javadoc documents that file as an ordered list of fields, each with a type and a link to the method that writes it (for example Int32 viaDataOutput#writeInt). The default codec's file-formats overview links this page as the Segments File. - Since 9.0,
DataOutput#writeIntand#writeLongwrite little-endian.segments_Nstays big-endian on purpose, written withCodecUtil.writeBEInt/writeBELong.
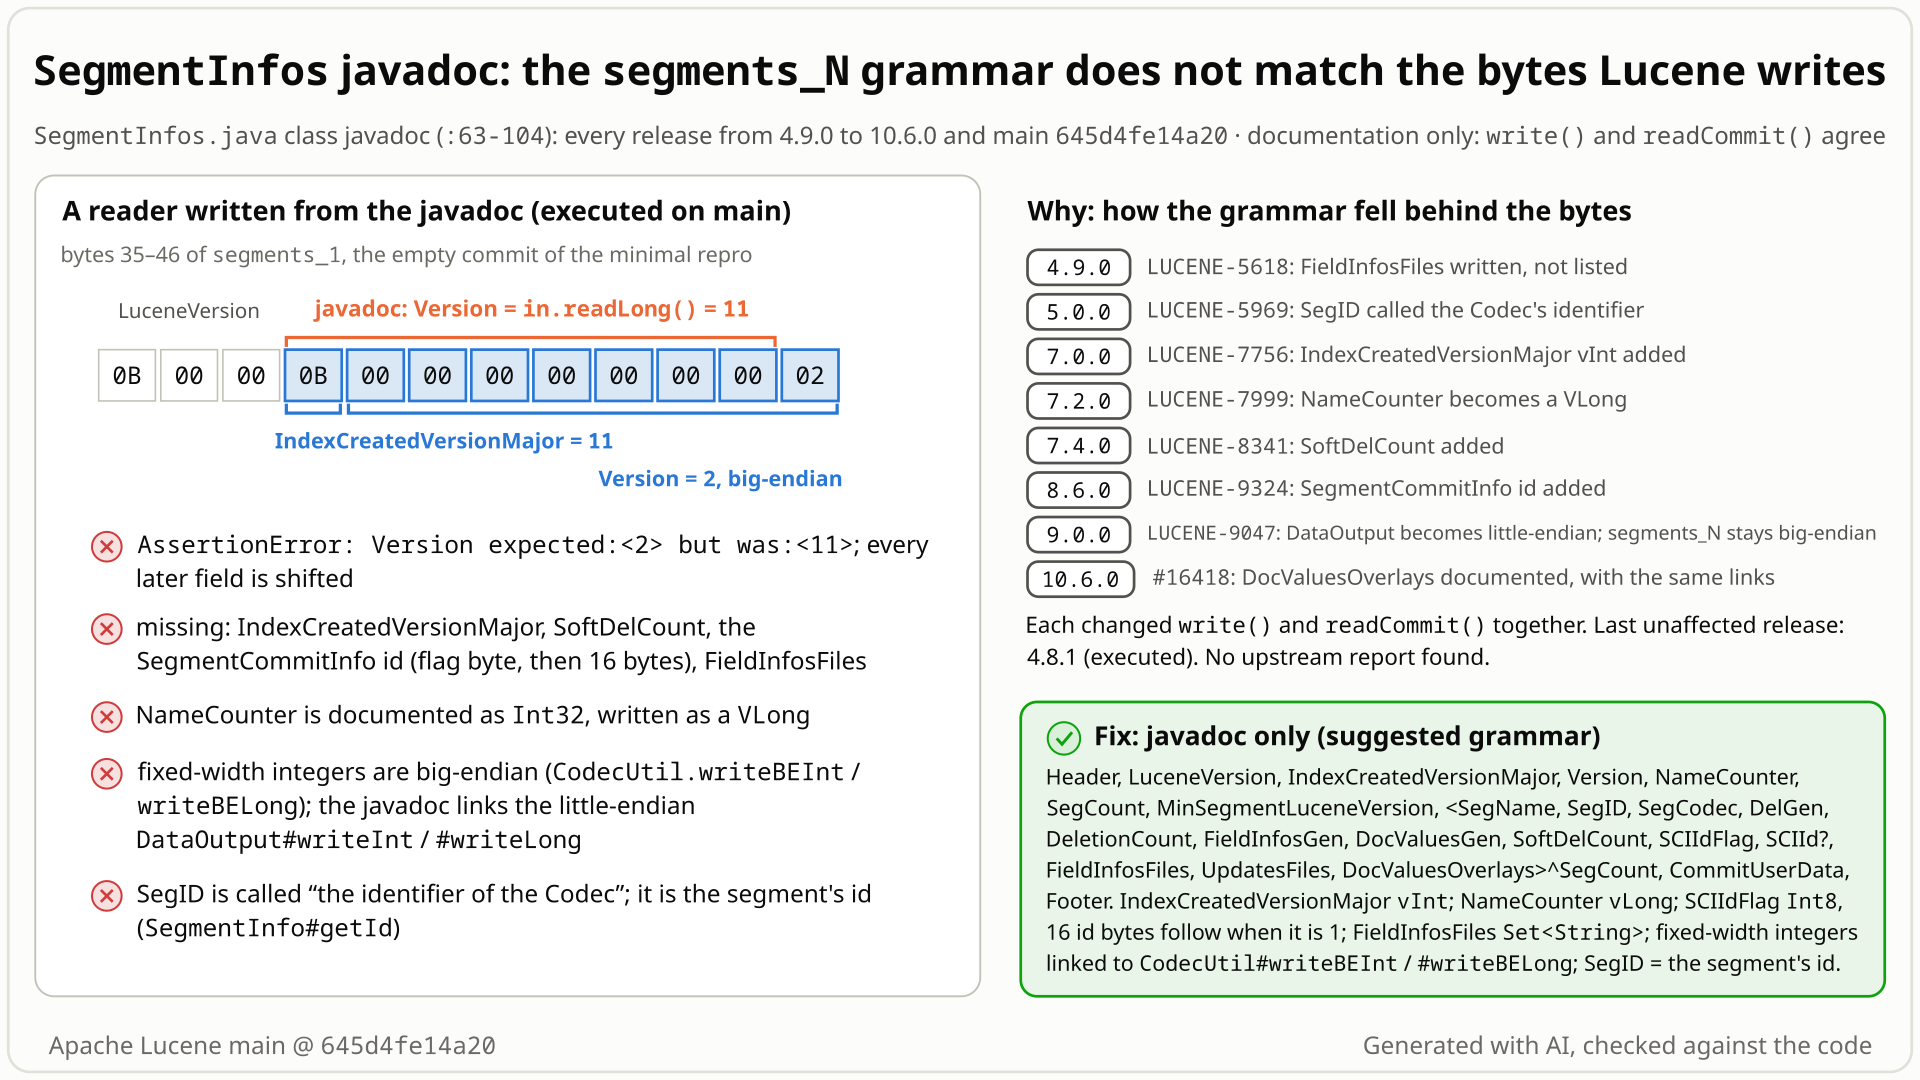
segments_N, read the way the javadoc says and the way Lucene writes them: the undocumented IndexCreatedVersionMajor byte sits where Version should start. Select the still to open it at full size. Generated with AI, checked against the code.- Open and close an
IndexWriteron an empty directory (main). Lucene writessegments_1: 69 bytes, a 35-byte header, 18 bytes of commit data and a 16-byte footer. - Read it the way the
SegmentInfosjavadoc says: after the header comes LuceneVersion (three vInts: 11, 0, 0), then Version, an Int64 written byDataOutput#writeLong. - You expect Version = 2, what
SegmentInfos.getVersion()returns for this commit. - You get 11. The next bytes are
0Band00 00 00 00 00 00 00 02: an undocumented vInt, IndexCreatedVersionMajor = 11, then Version = 2 written big-endian, whilewriteLongis little-endian. From there every field is read at the wrong offset. - The rest is stale too: NameCounter is a vLong, not an Int32, and each segment entry has three undocumented fields (SoftDelCount, a segment-commit id, FieldInfosFiles). Lucene's own reader matches the writer, so only hand-written readers break.
No Lucene user who goes through the API: writer and reader agree, so commits, search and CheckIndex work. It misleads anyone who writes their own segments_N reader, inspector, port or recovery tool from this javadoc, which the file-formats overview links as the Segments File. They go wrong right after LuceneVersion in every commit written since 7.0.
Mechanism, terms and numbers584 words
Every Lucene commit writes a small file, segments_N, that lists the index's segments, and the SegmentInfos class javadoc documents it field by field; the default codec's file-formats overview links that page as the Segments File. The documented layout no longer matches the bytes: the writer adds IndexCreatedVersionMajor (a vInt right after LuceneVersion, since 7.0.0), and per segment SoftDelCount (7.4.0), a segment-commit id (a flag byte plus 16 bytes, 8.6.0) and FieldInfosFiles (4.9.0), none of them listed; NameCounter is written as a vLong (7.2.0), not the documented Int32; and the fixed-width integers are written big-endian while the text links DataOutput#writeInt / #writeLong, which write little-endian since 9.0.0. SegID is also called the codec's identifier; it is the segment's id. Lucene's writer and reader agree, so nothing goes wrong at runtime; a reader that follows the text misreads the field right after LuceneVersion of every commit written since 7.0 (Version = 11 instead of 2 for an empty commit on main) and is out of sync from there on. The fix is a javadoc edit.
The javadoc's sequence (SegmentInfos.java:63-66): Header, LuceneVersion, Version, NameCounter, SegCount, MinSegmentLuceneVersion, <SegName, SegID, SegCodec, DelGen, DeletionCount, FieldInfosGen, DocValuesGen, UpdatesFiles, DocValuesOverlays>^SegCount, CommitUserData, Footer.
What write() writes (SegmentInfos.java:633-751; readCommit mirrors each step):
| element | javadoc says | writer does | since |
|---|---|---|---|
| IndexCreatedVersionMajor | not listed | out.writeVInt(indexCreatedVersionMajor) right after the three LuceneVersion vInts (:640-642, :646) | 7.0.0 (LUCENE-7756) |
| NameCounter | Int32 via DataOutput#writeInt (:78) | out.writeVLong(counter) (:649) | 7.2.0 (LUCENE-7999) |
| SoftDelCount | not listed | CodecUtil.writeBEInt(out, softDelCount) after DocValuesGen (:714) | 7.4.0 (LUCENE-8341) |
| segment-commit id | not listed | one byte, 1 or 0, then, if 1, the 16-byte SegmentCommitInfo#getId() (:717-725) | 8.6.0 (LUCENE-9324) |
| FieldInfosFiles | not listed | out.writeSetOfStrings(siPerCommit.getFieldInfosFiles()) before UpdatesFiles (:727) | 4.9.0 (LUCENE-5618) |
| byte order of Version, SegCount, DelGen, DeletionCount, FieldInfosGen, DocValuesGen, UpdatesFiles and DocValuesOverlays integers | linked to DataOutput#writeInt / #writeLong (:78-80, :84-89), "LE byte order" (DataOutput.java:68, :218) | CodecUtil.writeBEInt / writeBELong (:648, :650, :690, :701-703, :729-731, :738-745), "big endian order" (CodecUtil.java:689, :697) | 9.0.0 (LUCENE-9047) |
| SegID description | "the identifier of the Codec that encoded this segment" (:104) | the segment's own id, si.getId() (:679, :687) | 5.0.0 |
| Int64 row | names Generation and Checksum (:79) | no such element in the sequence | leftovers |
Header, LuceneVersion, MinSegmentLuceneVersion, SegName, SegCodec, CommitUserData and Footer match.
new IndexWriter(dir, new IndexWriterConfig()).close() on main writes segments_1, 69 bytes. Between the 35-byte header and the 16-byte footer (which starts C0 28 93 E8) are 18 bytes:
0B 00 00                  LuceneVersion 11.0.0 (three vInts)
0B                        IndexCreatedVersionMajor 11 (vInt, undocumented)
00 00 00 00 00 00 00 02   Version 2 (big-endian Int64)
00                        NameCounter 0 (vLong)
00 00 00 00               SegCount 0 (big-endian Int32)
00                        CommitUserData, empty map
Read as documented, Version takes 0B 00 00 00 00 00 00 00 = 11 (little-endian), NameCounter 02 00 00 00 = 2, and SegCount 00 00 00 C0 = -1073741824, already one byte into the footer.
Fixing only the commit-level items is not enough. On an independent verifier's index (3 segments, NameCounter 160, a hard delete, a soft delete, a doc-values update, user data), applying IndexCreatedVersionMajor, big-endian integers and the vLong counter one by one, the read still fails in the first segment entry at UpdatesFiles until SoftDelCount, the segment-commit id and FieldInfosFiles are added; only the full writer layout parses exactly to the footer.
Exposure and likelihood175 words
- Who. People who read, inspect or re-implement
segments_Nfrom the javadoc: ports to other languages, index inspectors, recovery or forensic tools, format tooling. The default codec's overview sends them there: "This document defines the index file formats used in this version of Lucene" (lucene104/package-info.java:50), "Details on each of these are provided in their linked pages" (:188), and the file table linksSegmentInfosas the Segments File (:221-222). - Default vs opt-in. No setting is involved. Every commit written since 7.0 has the IndexCreatedVersionMajor byte where the text puts Version; every commit since 4.9.0 has FieldInfosFiles in each segment entry.
- What they lose. A reader built from the text is out of sync from the field after LuceneVersion on; they have to read
write()to find the real layout. - Scale. Small audience; the searches found no report since 2014. The prior-art search found two StackOverflow questions about decoding
segments_Nfor recovery, so people do try; neither cites the javadoc. - Not affected. Lucene's behaviour, results and indexes. Nothing to fix in code.
One JUnit class, one test, public API only: commit an empty index, read segments_N back, skip the header and the three LuceneVersion vInts, read the next 8 bytes with readLong as the javadoc's link says, and compare with SegmentInfos#getVersion(). The header's random id and the randomized test codec do not touch the bytes it checks.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSegmentsNJavadocVersionField extends LuceneTestCase {

  public void testFieldAfterLuceneVersionIsVersion() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      new IndexWriter(dir, new IndexWriterConfig()).close();
      SegmentInfos sis = SegmentInfos.readLatestCommit(dir);
      try (IndexInput in = dir.openInput(sis.getSegmentsFileName(), IOContext.READONCE)) {
        CodecUtil.checkIndexHeader(
            in,
            "segments",
            0,
            Integer.MAX_VALUE,
            sis.getId(),
            Long.toString(sis.getGeneration(), Character.MAX_RADIX));
        in.readVInt();
        in.readVInt();
        in.readVInt();
        // javadoc: LuceneVersion (3 vInts) then Version (Int64); written: IndexCreatedVersionMajor
        assertEquals("Version", sis.getVersion(), in.readLong());
      }
    }
  }
}
# copy the file into $LUCENE/lucene/core/src/test/org/apache/lucene/index/, then:
./gradlew :lucene:core:test --tests org.apache.lucene.index.TestSegmentsNJavadocVersionField -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false

# or plain javac/java against the built jars; $DEPS = junit 4.13.2, randomizedtesting-runner 2.9.2, hamcrest 3.0
CP=$LUCENE/lucene/core/build/libs/lucene-core-11.0.0-SNAPSHOT.jar:$LUCENE/lucene/codecs/build/libs/lucene-codecs-11.0.0-SNAPSHOT.jar:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-11.0.0-SNAPSHOT.jar:$DEPS
javac -d out -cp "$CP" $REPRO/org/apache/lucene/index/TestSegmentsNJavadocVersionField.java
java -ea -cp "out:$CP" -Dtests.seed=DEADBEEF org.junit.runner.JUnitCore org.apache.lucene.index.TestSegmentsNJavadocVersionField
- Expected
- Version = 2: the Int64 after LuceneVersion equals
SegmentInfos#getVersion(). - Observed
Version expected:<2> but was:<11>: the 11 is the undocumented IndexCreatedVersionMajor byte (10 on 10.x, 9 on 9.12.3).
More files, environment, full output251 words
The test lives in package org.apache.lucene.index like Lucene's own index tests but uses only public API (IndexWriter, SegmentInfos.readLatestCommit, Directory.openInput, CodecUtil.checkIndexHeader, IndexInput). No documents, single thread. The random inputs do not touch the bytes it checks: the header's id is random (StringHelper.randomId(), SegmentInfos.java:638) but the test skips the header, and segments_N is written by SegmentInfos itself, so the randomized test codec cannot change the outcome. It shows the first divergence a reader following the text hits; the other stale items are read off the javadoc and write() (see the table above).
Regression test (optional): this same test reading the corrected layout: IndexCreatedVersionMajor as a vInt, then Version with CodecUtil.readBELong. It passes on today's code, so it guards the bytes, not the text.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the published 10.6.0 and 10.5.2 jars fail with 10, 9.12.3 with 9 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the result does not depend on the platform) |
# main 645d4fe14a20, seed DEADBEEF, -ea (the -da run prints the same)
JUnit Vintage:TestSegmentsNJavadocVersionField:testFieldAfterLuceneVersionIsVersion
  => java.lang.AssertionError: Version expected:<2> but was:<11>
     __randomizedtesting.SeedInfo.seed([DEADBEEF:2DAB27313494B3D6]:0)
     org.junit.Assert.fail(Assert.java:89)
     org.junit.Assert.failNotEquals(Assert.java:835)
     org.junit.Assert.assertEquals(Assert.java:647)
     org.apache.lucene.index.TestSegmentsNJavadocVersionField.testFieldAfterLuceneVersionIsVersion(TestSegmentsNJavadocVersionField.java:44)

# published release jars, -ea, seed DEADBEEF
10.6.0: Version expected:<2> but was:<10>
10.5.2: Version expected:<2> but was:<10>
9.12.3: Version expected:<2> but was:<9>

# the same test reading the corrected layout (IndexCreatedVersionMajor vInt, then CodecUtil.readBELong)
main 645d4fe14a20, -ea and -da: 1 test, 0 failures

# gradle, scratch worktree of 645d4fe14a20, stock source
TestSegmentsNJavadocVersionField > testFieldAfterLuceneVersionIsVersion FAILED
java.lang.AssertionError: Version expected:<2> but was:<11>- The page is an exact, typed, ordered grammar, and the file-formats overview says the details are "provided in their linked pages".
- Extended as the format grew, though not every time (#16418 added DocValuesOverlays in 2026); the gaps come from changes that updated
write()but not the text. - A stale segments-file doc was fixed as a defect before (LUCENE-350, 2005).
The full argument202 words
- The contract is the page. An ordered element sequence, a type and a writer link for each element, and field descriptions (
SegmentInfos.java:61-117); nothing marks it approximate. The overview: "This document defines the index file formats used in this version of Lucene" (package-info.java:50), "Details on each of these are provided in their linked pages" (:188). - Updated as the format evolved, though not every time. LUCENE-5618 (2014) added DocValuesGen and the map form of UpdatesFiles; LUCENE-5954 (2015) added LuceneVersion and MinSegmentLuceneVersion; #16418 (Jim Ferenczi, 2026-08-13) added DocValuesOverlays to the sequence, data types and descriptions. LUCENE-7756, LUCENE-7999, LUCENE-8341 and LUCENE-9324 changed the bytes without touching the text; none of their issues or reviews mentions it.
- The oldest gap was made while editing the grammar. LUCENE-5618's commit (2014-05-21) rewrote the sequence in the same diff that added
writeStringSet(getFieldInfosFiles()), and did not list it. - Precedent. LUCENE-350 (2005, "counter field in segments file is not documented in fileformats.xml"), LUCENE-3072 ("3.1 fileformats out of date") and LUCENE-7532 (a missing 6.2 file-format description) were fixed as defects. LUCENE-7532 came from a java-user@ thread ("an overview of the index format on Javadoc", 2016-10-29) in which Michael McCandless wrote "Yes please! This is a bug."
The devil's-advocate check199 words
The strongest case for "not a bug", built by the refute reviewer, the intended-lens reviewer and the devil's-advocate verifier (the cross-model reviewers rated it moderate; the devil's-advocate verifier found it fails for the core claim and conceded only the byte-order item): SegmentInfos is @lucene.experimental (SegmentInfos.java:119); the overview "attempts to provide a high-level definition" (package-info.java:54, the LUCENE-2946 policy of 2012); the supported reader is SegmentInfos.readCommit; and big-endian was chosen on purpose (on PR #107 rmuir wrote "I think its fine that segments_N and codec headers just stay bigendian"), so the writeInt / writeLong links may be width labels.
Why it fails: experimental allows the format to change, not a wrong description of the current one; LUCENE-2946 itself kept detailed docs for "the simple metadata files" ("its fine (for now)", rmuir), and this grammar stayed element-level and was extended in 2026; the page exists for people who need the layout. The byte-order point is the only one that survives, so it is the secondary item: CodecUtil's own header/footer javadoc uses the same links for big-endian fields (CodecUtil.java:60, :64, :399-403). The missing fields and the NameCounter type are wrong under any reading.
Recommended Rewrite the grammar to match write() (validated)
Javadoc only: list IndexCreatedVersionMajor (vInt) after LuceneVersion, and SoftDelCount, a SegCommitID (flag byte plus 16-byte id) and FieldInfosFiles in each segment entry; type NameCounter as vLong; link the fixed-width integers to CodecUtil#writeBEInt / #writeBELong; call SegID the segment's id; drop Generation and Checksum. No code changes.
* <li><code>segments_N</code>: Header, LuceneVersion, IndexCreatedVersionMajor, Version,
* NameCounter, SegCount, MinSegmentLuceneVersion, <SegName, SegID, SegCodec, DelGen,
* DeletionCount, FieldInfosGen, DocValuesGen, SoftDelCount, SegCommitID, FieldInfosFiles,
* UpdatesFiles, DocValuesOverlays><sup>SegCount</sup>, CommitUserData, Footer
...
* <li>IndexCreatedVersionMajor --> {@link DataOutput#writeVInt vInt}
* <li>NameCounter --> {@link DataOutput#writeVLong vLong}
* <li>SegCount, DeletionCount, SoftDelCount --> {@link CodecUtil#writeBEInt Int32}
* (big-endian)
* <li>Version, DelGen, FieldInfosGen, DocValuesGen --> {@link CodecUtil#writeBELong Int64}
* (big-endian)
* <li>SegCommitID --> one {@link DataOutput#writeByte byte}, 1 if an id follows and 0 if not,
* then the id as {@link DataOutput#writeByte Int8<sup>ID_LENGTH</sup>} if the byte is 1
* <li>FieldInfosFiles --> {@link DataOutput#writeSetOfStrings(Set) Set<String>}All options and trade-offs4 options · 623 words
Option A was validated in a scratch worktree of 645d4fe14a20; the others were not run.
In the SegmentInfos class javadoc: add IndexCreatedVersionMajor to the sequence and SoftDelCount, SegCommitID and FieldInfosFiles to the segment entry; type NameCounter as vLong; link SegCount, DeletionCount, SoftDelCount, Version, DelGen, FieldInfosGen, DocValuesGen and the UpdatesFiles / DocValuesOverlays integers to CodecUtil#writeBEInt / #writeBELong with "(big-endian)"; spell out the UpdatesFiles count; describe SegID as the segment's id and add descriptions for the new fields; drop Generation and Checksum. 1 file, +25/-12, javadoc only (google-java-format applied). The excerpt below shows the changed grammar and type lines.
* <li><code>segments_N</code>: Header, LuceneVersion, IndexCreatedVersionMajor, Version,
* NameCounter, SegCount, MinSegmentLuceneVersion, <SegName, SegID, SegCodec, DelGen,
* DeletionCount, FieldInfosGen, DocValuesGen, SoftDelCount, SegCommitID, FieldInfosFiles,
* UpdatesFiles, DocValuesOverlays><sup>SegCount</sup>, CommitUserData, Footer
...
* <li>IndexCreatedVersionMajor --> {@link DataOutput#writeVInt vInt}
* <li>NameCounter --> {@link DataOutput#writeVLong vLong}
* <li>SegCount, DeletionCount, SoftDelCount --> {@link CodecUtil#writeBEInt Int32}
* (big-endian)
* <li>Version, DelGen, FieldInfosGen, DocValuesGen --> {@link CodecUtil#writeBELong Int64}
* (big-endian)
* <li>SegCommitID --> one {@link DataOutput#writeByte byte}, 1 if an id follows and 0 if not,
* then the id as {@link DataOutput#writeByte Int8<sup>ID_LENGTH</sup>} if the byte is 1
* <li>FieldInfosFiles --> {@link DataOutput#writeSetOfStrings(Set) Set<String>}Trade-offs
The smallest change that makes the page an accurate spec again, in the existing style and with the element names readers know; SegCommitID, UpdatesCount and FieldNumber are new names, any will do. Linking CodecUtil#writeBEInt / #writeBELong (documented as "big endian order") states the byte order without a new convention. It does not prevent future drift. Optional extras the validated diff leaves out: the untouched MinSegmentLuceneVersion line still says "this is only written only if" (an older typo, SegmentInfos.java:76), and the SegID and SegCommitID rows could link DataOutput#writeBytes, which the writer calls, instead of #writeByte.
What the checks validated
Yes, in a scratch worktree of 645d4fe14a20 (removed after the runs). With the fix, checkGoogleJavaFormat (after one formatter re-wrap), renderJavadoc (javadoc with -Xdoclint:all,-missing, which fails on an unresolved link) and ecjLintMain of core pass; every new link target is a public declaration. TestSegmentInfos (8 tests) and the minimal test rewritten to read the corrected layout pass with gradle, assertions on and off (run with the hand-written diff, which differs from the formatted one only in the wrapping of three javadoc lines). An independent verifier's parser that reads exactly the corrected layout parses a 3-segment commit (hard and soft deletes, a doc-values update, user data) to the footer with every value equal to Lucene's reader: 4 of 4 pass, -ea and -da. The stock minimal test fails under gradle; it keeps failing after the fix by design, since the fix changes no bytes.
Add the four missing elements, type NameCounter as vLong, fix the SegID sentence and the Int64 row, and add one sentence such as "All fixed-width integers in this file are written big-endian (see CodecUtil#writeBEInt)" instead of relinking each row.
Trade-offs
Smaller diff; the per-row links still point at little-endian writers.
What the checks validated
Not run (text only).
CodecUtil's header and footer javadoc links DataOutput#writeInt / #writeLong for its big-endian Magic, Version, AlgorithmID and Checksum fields (CodecUtil.java:60, :64, :399-403).
Trade-offs
Closes the same convention gap at its source; widens the change beyond segments_N.
What the checks validated
Not run.
Drop the field list and point readers at the source.
Trade-offs
No duplicated layout left to drift (the pointer itself can still go stale), but the file-formats overview would then link a page with no format on it, against its own promise ("defines the index file formats"). Not recommended.
What the checks validated
Not run.
Relevant only to tools outside Lucene that parse segments_N themselves (ports, index inspectors, recovery tools); Lucene's own writer and reader agree.
A differential grammar check: each default-codec file's layout was transcribed once from its javadoc and once from its writer, and one interpreter parsed the real bytes of 64 generated indexes under both, comparing every value with Lucene's own reader. All 64 segments_N files diverged under the javadoc; the writer's layout parsed all exactly.
The method in full147 words
- Method (semi-formal). Every file grammar is data in a small grammar language: the documented grammar transcribed only from the class javadoc, the layout grammar from the writer. A generic interpreter parsed the real bytes of 64 generated default-codec index configurations (fixed and seeded random; 1,114 file checks) under both and compared every parsed value with Lucene's reader. Positive control: the layout grammar parses every file exactly to the footer. Vacuity check: 14 of 14 single-element layout mutants are killed.
- Result for this file. 64 of 64
segments_Nfiles diverge under the documented grammar, also under a big-endian reading of it (2026-10-28). - Lead. The hunt started from a probe of the
.fnmformat only;segments_Ncame from the grammar check. - Then. A reviewer from another model family (OpenAI GPT-5.6) wrote and ran its own test; independent verifiers, an intended-lens reviewer and an adjudication re-ran or rebuilt the evidence.
No prior report found (GitHub issues and PRs, commits, the JIRA archive, the lists, downstream repositories and the web; 2026-10-28, re-checked 2026-11-01). Nearest: #16766 fixed only the readCommit method javadoc, and #16418 added DocValuesOverlays to this grammar without touching the rest.
Searches4 searches
Closest items, none this bug:
- #16766 (merged 2026-10-05, "Fix outdated SegmentInfos#readCommit javadocs"): the
readCommit/readLatestCommitmethod javadoc only; the class grammar is untouched. - #16418 (merged 2026-08-13): added DocValuesOverlays to the grammar; its description and reviews say nothing about the rest.
- #10089 / LUCENE-9047, PR #107 and #11185 / LUCENE-10148: the little-endian
DataOutputchange and its javadoc follow-up; they keepsegments_Nbig-endian on purpose and never mention this javadoc. - #4020 / LUCENE-2946 (2012): the "high-level" policy for the format docs.
- #1428 / LUCENE-350, #4145 / LUCENE-3072, #8583 / LUCENE-7532: older format-doc defects, fixed.
- #16571 (open, "Let a merge write more than one segment") touches
SegmentInfos.javaonly at merge bookkeeping (lines 1125-1173), and #16949 (open, javadoc fixes) does not touch it.
| Where | When | How | Found |
|---|---|---|---|
| Scripted prior-report searches (4 runs + the finder's) | 2026-10-28 | 84 GitHub issue/PR, 15 commit, 10 downstream, 100 mailing-list (dev@, java-user@, issues@, commits@) and 20 JIRA-archive queries on the element names, segments_N, the endianness helpers and file-format docs | no report |
| GitHub, manual | 2026-10-28 | 26 logged searches (each element name, "identifier of the Codec", segments_N with javadoc / IndexCreatedVersionMajor / grammar across GitHub, Lucene.NET, downstream repos); changed files of all 413 open PRs | no report; open PRs touching the file change no grammar line |
| Web | 2026-10-28 | 17 queries | javadoc mirrors, old file-format pages, two recovery questions; no report |
| GitHub, recheck | 2026-11-01 | file blob on upstream main f815e679bf6c; 2 searches; all 64 issues and PRs (11 issues, 53 PRs) updated since 2026-10-28, and the changed files of the 53 PRs | blob unchanged; nothing about the grammar |
Stale since 4.9.0 (LUCENE-5618, 2014, left FieldInfosFiles out); later format changes added gaps: 7.0.0 IndexCreatedVersionMajor, 7.2.0 NameCounter as vLong, 7.4.0 SoftDelCount, 8.6.0 the segment-commit id, 9.0.0 little-endian writeInt / writeLong. Every release 4.9.0 to 10.6.0 and main; each boundary executed.
Versions tested10 rows
- Introduced by
6ba5d793838(branch_4x, first shipped in 4.9.0) /c863a7251d5(trunk), LUCENE-5618 / LUCENE-5636 (Shai Erera, 2014-05-21): added the FieldInfosFiles set after DocValuesGen and edited the grammar in the same diff without listing it. - Then
0f304eafb93(LUCENE-5969, 5.0.0) wrote the SegID sentence;23b002a0fdf(LUCENE-7756, 7.0.0) IndexCreatedVersionMajor;ea36f5040c3/4c5ce2d646b(LUCENE-7999, 7.2.0) the vLong counter;fe83838ec37/21f03a49532(LUCENE-8341, 7.4.0) SoftDelCount;113043b1ed2/2d63a9d1208(LUCENE-9324, 8.6.0) the segment-commit id;b84e0c272b6(LUCENE-9047, 9.0.0) madeDataOutputlittle-endian whilesegments_Nstayed big-endian.75eddfaff22(#16418, 10.6.0) added DocValuesOverlays with the same little-endian links. - Method. A portable probe parses each release's commit with that release's own javadoc grammar and tries all 128 subsets of 7 corrections; at each executed byte-layout boundary (4.9.0, 7.0.0, 7.2.0, 7.4.0, 8.6.0, 9.0.0) the minimal correction set grows by exactly one. The 5.0.0 SegID sentence is text only, and the 10.6.0 overlays need no correction beyond the byte order.
- Before 4.9.0. 4.6.0-4.8.1 had a different, since-fixed mismatch (UpdatesFiles documented as a set, written as a map), not part of this claim.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; upstream main f815e679bf6c | affected | minimal test fails, Version 11 (-ea and -da); upstream read, same file blob |
| 10.6.0, 10.5.2 | affected | minimal test fails, Version 10 (published jars) |
| 9.12.3 | affected | minimal test fails, Version 9 (published jar) |
| 9.0.0 | + byte order | linked writeInt/writeLong measured little-endian; all six corrections needed |
| 8.6.0, 8.11.4 | + commit id | boundary 8.5.2 / 8.6.0 |
| 7.4.0, 8.5.2 | + SoftDelCount | boundary 7.3.1 / 7.4.0 |
| 7.2.0, 7.3.1 | + vLong counter | boundary 7.1.0 / 7.2.0 |
| 7.0.0, 7.1.0 | + IndexCreatedVersionMajor | boundary 6.6.6 / 7.0.0 |
| 4.9.0 to 6.6.6 | FieldInfosFiles | 4.9.0, 4.10.4, 5.0.0, 5.1.0, 5.5.5, 6.6.6 executed: one correction needed |
| 4.6.0, 4.8.1 | not affected | an update-free commit parses exactly as documented |
A refute reviewer from another model family (OpenAI GPT-5.6, executing), independent verifiers, an intended-lens reviewer and an adjudication all call it a real documentation defect; the adjudication re-ran the correction ladder and the writer-layout control. This brief re-ran the repro, the control and the fix checks.
Checks and verdicts343 words
Each check ran separately; the refute reviewer and the independent reproducer wrote and executed their own tests.
| Check | Verdict | What it found |
|---|---|---|
| Finder | reproduced (documentation) | Grammar check: 64 of 64 segments_N files diverge, writer layout 0 failures, 14 of 14 mutants killed; JUnit fails on main (-ea/-da), the branch_10_6 head, 10.5.2, 9.12.3. |
| Refute lens (OpenAI GPT-5.6) | real, high confidence | Own empty-commit test fails at IndexCreatedVersionMajor (3 seeds -ea, 1 -da); its control passes; ran on an earlier main, ea57360912ed, with an identical class javadoc and writer. |
| Independent reproducer | real | Own 3-segment test: correction ladder fails 6 of 6, each step at the next claimed defect (main, 10.5.2, 9.12.3); the fully corrected layout parses to the footer, 4 of 4. |
| Intended lens (OpenAI GPT-5.6, reading only) | real, high | Rated the experimental / high-level case moderate and rejected it; a separate re-run failed 3 of 3. |
| Devil's advocate | real (documentation) | Rejected LUCENE-2946, @lucene.experimental and the big-endian choice as reasons for the core claim, conceding only that the byte-order item may be "accepted as is"; moved the first affected release from 7.0 to 4.9.0; found the Generation/Checksum leftovers. |
| Adjudication | confirmed, high; minor | Re-ran the independent reproduction's ladder (-ea, -da: 6 of 6 fail) and control (4 of 4 pass); checked each sub-claim against write(). |
| History follow-up | first release 4.9.0 | 22 probe runs on 21 targets, 4.6.0 to main; every boundary pinned. |
| This brief | real; fix validated | Minimal repro on main (-ea/-da) and the published 10.6.0, 10.5.2, 9.12.3 jars; corrected-reading twin passes; byte dump; writer-layout control re-run (4 of 4); gradle checks and tests with the fix. |
| Fact checks | real; wording fixed | An independent fact check re-ran the repro (standalone, plain javac/java, gradle), the release jars, the twin, the byte dump and the independent reproducer's runs, and re-read every cited line and commit; a cross-model fact check (OpenAI GPT-5.6, reading only) re-read the evidence. Both found the bug and the fix sound; their wording and count corrections are applied here. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 524 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,627 words
- Registry title
- The SegmentInfos class javadoc gives a wrong segments_N (commit point) grammar: IndexCreatedVersionMajor, SoftDelCount, the SegmentCommitInfo id and FieldInfosFiles are missing, NameCounter is documented as an Int32 but written as a VLong, the fixed-width integers are written big-endian although the javadoc links the little-endian DataOutput#writeInt/#writeLong, and SegID is called the codec's identifier (documentation defect; the writer and reader agree)
- Area
- index / SegmentInfos (segments_N file-format javadoc vs its writer and reader)
- Priority
- Low, rank 1277: It is a documentation-only file-format defect where writer and reader agree; segments_N is the central commit file, and a parser built from the text misreads the field right after LuceneVersion.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so commits, reopen, CheckIndex and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement segments_N from this class javadoc (the default codec's package docs link it as the Segments File format), and a parser that follows the text misreads the field right after LuceneVersion in every commit written since 7.0, and loses sync from then on (executed); no scale or special setting is needed.
- Summary
- You decode a segments_N commit file by following the SegmentInfos class javadoc, which gives the order Header, LuceneVersion, Version, NameCounter, SegCount, MinSegmentLuceneVersion, then per segment SegName, SegID, SegCodec, DelGen, DeletionCount, FieldInfosGen, DocValuesGen, UpdatesFiles, DocValuesOverlays, and types NameCounter as an Int32 and the fixed-width fields with links to DataOutput#writeInt/#writeLong (little-endian since 9.0). The writer instead puts an IndexCreatedVersionMajor VInt right after LuceneVersion, writes NameCounter as a VLong, writes Version, SegCount, DelGen, DeletionCount and the other fixed-width fields big-endian, and adds SoftDelCount, a flag byte plus the 16-byte SegmentCommitInfo id and the FieldInfosFiles set to every segment entry, so a parser built from the text reads the VInt 11 where Version should be and every later field is misaligned. Lucene's own reader matches the writer, so nothing breaks at runtime; only the documentation is wrong, and it has not matched the bytes since 4.9.0 (2014).
- Introduced
- a stack of omissions, oldest first [follow-up; each boundary executed with a portable probe, last-before release passes, first-after fails]: (1) FieldInfosFiles: 6ba5d793838 (branch_4x, the commit that first shipped, in 4.9.0) / c863a7251d5 (trunk), LUCENE-5618 and LUCENE-5636 (now apache/lucene#6680, #6698; Subversion era, no pull request), by shaie: it edited the segments_N grammar in the same diff and added writeStringSet(getFieldInfosFiles()) after DocValuesGen without listing it [exec: 4.8.1 needs no current correction, 4.9.0 needs FieldInfosFiles]; (2) the SegID sentence 'the identifier of the Codec': 0f304eafb93 (branch_5x, LUCENE-5969, by rmuir, 5.0.0) [read; executed only as SegID == SegmentInfo#getId]; (3) IndexCreatedVersionMajor VInt: 23b002a0fdf (LUCENE-7756, #8807, by jpountz, 7.0.0) [exec: 6.6.6 / 7.0.0]; (4) NameCounter as VLong: 4c5ce2d646b (branch_7x) / ea36f5040c3 (master), LUCENE-7999 (#9047), by mikemccand, 7.2.0 [exec: 7.1.0 / 7.2.0]; (5) SoftDelCount: 21f03a49532 (branch_7x) / fe83838ec37 (master), LUCENE-8341 (#9388), by s1monw, 7.4.0 [exec: 7.3.1 / 7.4.0]; (6) SegmentCommitInfo id (flag byte plus 16 bytes): 2d63a9d1208 (branch_8x) / 113043b1ed2 (master), LUCENE-9324 (#10364, PR apache/lucene-solr#1434), by s1monw, 8.6.0 [exec: 8.5.2 / 8.6.0]; (7) endianness links: b84e0c272b6 (LUCENE-9047, #10089, PR #107, by iverase, 9.0.0) made DataOutput#writeInt/#writeLong little-endian while segments_N deliberately stayed big-endian through CodecUtil.writeBE*, and the javadoc links were not revisited [exec: 8.11.4 / 9.0.0]. 75eddfaff22 (#16418, by jimczi, 2026-08; backported as 3a6cd003aaf, #16554, released in 10.6.0) added DocValuesOverlays to the grammar with the same little-endian links and left the rest as it was. Leftovers: 'Generation' and 'Checksum' in the Int64 data-type row match no element (819eda82e33 LUCENE-2446, 4.8.0; b7047694256 LUCENE-5925, 5.0.0) [read] (2014-05-21 (author date of 6ba5d793838 and c863a7251d5: FieldInfosFiles, the oldest part still present); later parts 2014-10-24 (SegID wording), 2017-03-30 (IndexCreatedVersionMajor), 2017-10-24 (NameCounter VLong), 2018-05-26 (SoftDelCount), 2020-04-18 (SegmentCommitInfo id), 2021-05-03 (endianness links), 2026-08-13 (DocValuesOverlays added with the same links))
- First affected version
- 4.9.0 [exec] (FieldInfosFiles; for the defect as claimed 4.8.1 is the last unaffected release [exec]: an update-free commit parses exactly as documented, and its separate, since-fixed UpdatesFiles mismatch of 4.6.0-4.8.1 is not part of this claim); later parts: 5.0.0 (SegID wording) [read], 7.0.0 (IndexCreatedVersionMajor, the first stale field a parser of a 7.0+ commit hits) [exec], 7.2.0 (NameCounter VLong) [exec], 7.4.0 (SoftDelCount) [exec], 8.6.0 (SegmentCommitInfo id) [exec], 9.0.0 (endianness links) [exec]
- Affected versions
- every release from 4.9.0 through 10.6.0 (10.6.0 run as its release revision, the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream [exec: the follow-up's portable history probe (each release's own javadoc grammar, all 128 subsets of the seven corrections, exact = every value equals SegmentInfos as read by Lucene and the footer at the end) on 4.6.0, 4.8.1, 4.9.0, 4.10.4, 5.0.0, 5.1.0, 5.5.5, 6.6.6, 7.0.0, 7.1.0, 7.2.0, 7.3.1, 7.4.0, 8.5.2, 8.6.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da): the minimal correction set grows by exactly one part at each boundary; the finder's JUnit fails 3 of 3 on main (-ea and -da), the branch_10_6 head, and, as its release variant without DocValuesOverlays, on 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 6 of 6 with its writer-layout control passing on main (-ea and -da), 10.5.2 and 9.12.3; read: the releases in between from a scan of every release tag for changes to the class javadoc or the write calls]. Caveats: 8.8.2-8.11.4 are not tagged in the history clone (8.11.4 executed from checksum-verified release jars); upstream main 645d4fe14a20 (2026-10-28) still carries the text [read]; all runs used JDK 25 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: four scripted prior-report searches (68 GitHub issue/PR, 12 commit, 8 downstream, 80 mailing-list and 16 JIRA-archive queries plus web queries) on the element names, segments_N, the endianness helpers and file-format documentation, the finder's 51-query run, and about 30 manual GitHub searches; all 413 open apache/lucene PRs scanned by changed files and the diffs of those touching SegmentInfos.java grepped for grammar edits; the introducing issues LUCENE-5618, LUCENE-7756, LUCENE-7999, LUCENE-8341, LUCENE-9324 and LUCENE-9047/PR #107 read for any remark about the grammar). Nearest items, not the same bug: #16766 (merged 2026-10-05, 'Fix outdated SegmentInfos#readCommit javadocs': the readCommit/readLatestCommit METHOD javadoc only, the LFV-119 area), #16418 (added DocValuesOverlays to the class grammar; its description and reviews say nothing about the rest), #11185 / LUCENE-10148 and #10089 / LUCENE-9047 (why DataOutput is little-endian while segments_N stayed big-endian; neither mentions the SegmentInfos javadoc), LUCENE-2946 (2012 policy for high-level file-format docs). Recheck (2026-10-28): none of the 29 apache/lucene issues and PRs created since 2026-10-26 (including a series of javadoc fixes, #16920-#16922, #16927, #16928, #16933-#16935) is about segments_N or any file-format grammar; 'FieldInfosFiles' 0 hits, 'NameCounter' 1 unrelated 2011 issue (#4681), 'segments_N format updated since 2026-10-26' 0 hits; of the open PRs updated since 2026-10-26 only #16571 touches SegmentInfos.java (merge bookkeeping, no grammar line) and #16480 touches lucene104/package-info.java (no grammar line); by author date the file's latest upstream commits are 330ee57b167 (#16788, 2026-10-21), f30bd1b9b4f (#16476) and ed2d3ee8d49 (#16766, both 2026-10-05), none in the class javadoc; upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 63, 78, 79 and 104. Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, and its twin that reads the corrected layout passes; a byte dump of an empty commit; the writer-layout control of an independent verifier (3 segments, deletes, a soft delete, a doc-values update, user data) parses exactly to the footer with every value equal to Lucene's reader; the javadoc fix was checked with gradle in a scratch worktree of645d4fe14a20. Releases: the minimal test fails on the published 10.6.0, 10.5.2 and 9.12.3 jars (SHA-1 checked); the version-history runs parsed each release's commit with that release's own javadoc on 21 targets from 4.6.0 to main (4.6.0 and 4.8.1 clean). Upstream mainf815e679bf6c(2026-11-01) was read, not run:SegmentInfos.javahas the same blob.
- Finding record
lucene/core/src/java/org/apache/lucene/index/SegmentInfos.java:63-66 (documented sequence), :78 (NameCounter, SegCount, DeletionCount --> DataOutput#writeInt Int32), :79-80 (Generation, Version, DelGen, Checksum, FieldInfosGen, DocValuesGen --> DataOutput#writeLong Int64), :84-89 (UpdatesFiles and DocValuesOverlays typed with writeInt/writeLong), :104 ('SegID is the identifier of the Codec that encoded this segment'), :119 (@lucene.experimental); writer write(): :640-642 LuceneVersion vInts, :646 writeVInt(indexCreatedVersionMajor), :648 writeBELong(version), :649 writeVLong(counter), :650 writeBEInt(size()), :665-667 MinSegmentLuceneVersion, :678-688 SegName, SegID (si.getId()), SegCodec, :690 / :701-703 BE DelGen, DelCount, FieldInfosGen, DocValuesGen, :714 writeBEInt(softDelCount), :717-725 SegmentCommitInfo id flag byte plus 16 bytes, :727 writeSetOfStrings(getFieldInfosFiles()), :728-733 BE UpdatesFiles, :737-747 BE DocValuesOverlays, :749-750 user data and footer; reader :433 readBEInt(softDelCount) mirrors the writer; class javadoc identical at Lucene main ea57360912ed (compared 2026-10-28)lucene/core/src/java/org/apache/lucene/store/DataOutput.java:65 and :217 ('Writes an int/a long as four/eight bytes (LE byte order)') and lucene/core/src/java/org/apache/lucene/codecs/CodecUtil.java:690, :698 (writeBEInt, writeBELong)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:50 ('defines the index file formats used in this version of Lucene'), :54 ('a high-level definition'), :188 ('Details on each of these are provided in their linked pages'), :221-222 (links SegmentInfos as the Segments File, segments_N)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/SegmentInfos.java:63-66, :78-90, :104 (javadoc); :633-751 (write); :347-348, :386-389, :425-433, :443-463 (readCommit) at 645d4fe14a20lucene/core/src/java/org/apache/lucene/store/DataOutput.java:68, :218 (LE byte order); lucene/core/src/java/org/apache/lucene/codecs/CodecUtil.java:689-701 (writeBEInt / writeBELong, big endian order)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:50, :54, :188, :221-222
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/SegmentInfos.java:61-119; lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:50, :54, :188; lucene/core/src/java/org/apache/lucene/codecs/CodecUtil.java:60, :64, :399-403
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/CodecUtil.java:60, :64, :399-403, :689-701
- TestSegmentsNJavadocVersionField.java (one test, public API):
repro/LFV-943/src/org/apache/lucene/index/TestSegmentsNJavadocVersionField.java(48 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-943/bug.png(524 KB)