A Kuromoji or Nori user dictionary file saved with a UTF-8 byte order mark: the mark stays glued to line 1.
- Kuromoji (Japanese) and Nori (Korean) split text into words with a built-in dictionary. A user dictionary file adds your own words: one entry per line;
#starts a comment. - A Nori entry is the word, then optionally its parts:
세종시 세종 시indexes세종시as세종+시. A Kuromoji entry isword,segmentation,readings,part-of-speech. - A byte order mark (BOM) is the 3 bytes
EF BB BFthat some editors write at the start of a UTF-8 file. Decoded, it is the invisible character U+FEFF.
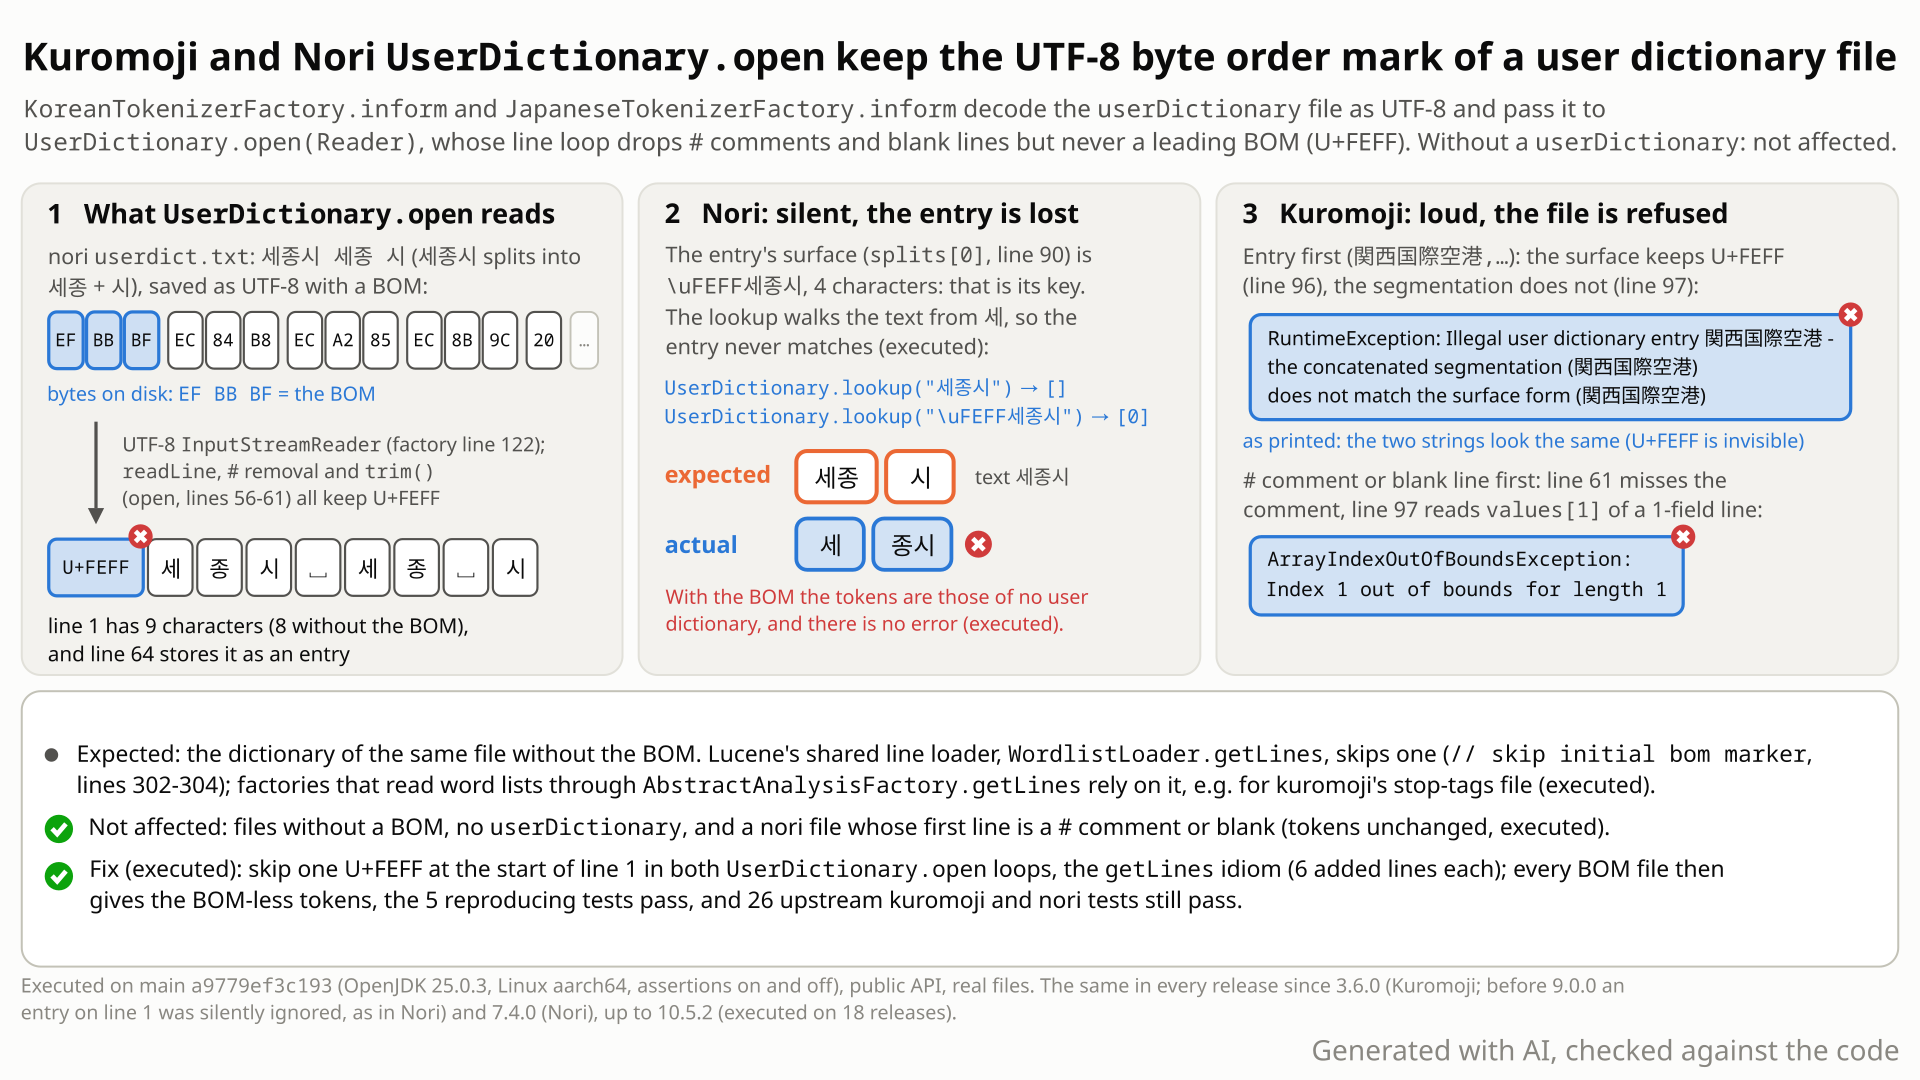
- You give
KoreanTokenizerFactorya user dictionary with one line,세종시 세종 시: index "Sejong City" as "Sejong" + "city". Your editor saved the file as UTF-8 with a byte order mark (BOM): 3 invisible bytes,EF BB BF, at the start. - You expect the same result as without the BOM:
세종시gives[세종, 시]. Lucene's loader for stop words and the other analysis resource files skips a leading BOM. - You get
[세, 종시], the result with no user dictionary at all, and no error. The factory decodes the BOM to the character U+FEFF and the loader keeps it, so the entry is stored as U+FEFF +세종시, which ordinary text does not contain. - Kuromoji refuses such a file at setup. The 5-line dictionary of its own factory test, whose line 1 is a
#comment, throwsArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1, because the BOM hides the#. An entry on line 1 throwsIllegal user dictionary entry, quoting two strings that print the same.
Only applications with a Kuromoji or Nori user dictionary (the userDictionary factory argument, or UserDictionary.open on their own reader) whose file starts with a BOM, as editors such as Windows Notepad often write. Nori silently ignores the first entry when line 1 is an entry; Kuromoji fails at setup. Rare: no report found since 2012.
Mechanism, terms and numbers711 words
JapaneseTokenizerFactory and KoreanTokenizerFactory take a userDictionary file. Each factory decodes the file itself with a strict decoder (UTF-8 by default) and passes the reader to UserDictionary.open, whose loop removes # comments and skips blank lines but never removes a leading byte order mark; Java's UTF-8 decoder keeps it as U+FEFF. In Nori the first entry is stored under the key U+FEFF + 세종시, which ordinary text does not contain, so 세종시 is segmented [세, 종시] (the result without any user dictionary) instead of [세종, 시], with no error. Kuromoji fails at analyzer setup: the dictionary of its own testUserDict (line 1 is a comment) throws ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1, and an entry on line 1 throws Illegal user dictionary entry, whose two quoted strings print the same. Lucene's shared line loader for the other analysis resource files skips the mark (WordlistLoader.getLines, "skip initial bom marker", SOLR-1865), so the stop-tags file of the same module and the new Thai user dictionary accept a BOM. Present since Kuromoji 3.6.0 (2012) and Nori 7.4.0 (2018). Skipping a U+FEFF at the start of line 1 in both loops fixes it; both modules' full test suites pass with that change.
- User dictionary: the
userDictionaryargument ofJapaneseTokenizerFactoryandKoreanTokenizerFactory(a resource path, decoded withuserDictionaryEncoding, default UTF-8), or aReaderpassed toUserDictionary.open. - Byte order mark (BOM): the 3 bytes
EF BB BFat the start of a file saved as "UTF-8 with BOM". Java's UTF-8 decoder returns them as the character U+FEFF (JDK-4508058, Won't Fix).
- Both factories'
informopen the file, build a strict decoder (default UTF-8), wrap it in anInputStreamReaderand callUserDictionary.open(reader)(KoreanTokenizerFactory.java:110-124,JapaneseTokenizerFactory.java:142-156). None of the 173 charsets of JDK 25 strips a UTF-8 BOM, souserDictionaryEncodingis no workaround (a UTF-16 file with a BOM works: that decoder consumes its BOM). - Nori (
ko/dict/UserDictionary.java:56-65):line.replaceAll("#.*$", ""), skip ifline.trim().length() == 0, else keep the line.trim()removes only characters up to U+0020, so U+FEFF stays. An entry on line 1 is stored under U+FEFF +세종시(:89-90,:125-131). The lookup starts at every position of the text, so the key could only match where the text itself has U+FEFF before세종시; ordinary text does not, so for세종시the system dictionary decides:[세, 종시]. A comment or blank line 1 leaves a junk entryU+FEFFwith no visible effect in the inputs tested. - Kuromoji (
ja/dict/UserDictionary.java:59-69): the comment pattern^#.*$(:37) does not match U+FEFF +# ..., and the line is not empty, so it is parsed as a one-field entry and the constructor'svalues[1](:97) throwsArrayIndexOutOfBoundsException, against the loop's own comment "Skip empty lines or comment lines" (:63). An entry on line 1 keeps U+FEFF in its surface (:96) but not in its segmentation, so the LUCENE-8933 check (:114-123) throwsIllegal user dictionary entry. - The other resource files skip it:
WordlistLoader.getLinesdrops a U+FEFF at the start of the first line (WordlistLoader.java:302-304, "skip initial bom marker").AbstractAnalysisFactory.getWordSetandgetLinesuse it, and with them the stop-tags file ofJapanesePartOfSpeechStopFilterFactoryand the newThaiTokenizerFactoryuser dictionary. The two CJK user dictionaries read lines themselves.
| file | without BOM | with BOM |
|---|---|---|
Nori 세종시 세종 시, text 세종시 | [세종, 시] | [세, 종시] (= no user dictionary), no error |
| Nori, comment or blank line 1, then entries | entries apply | the same (no visible effect in the inputs tested) |
Kuromoji, the 5-line dictionary of upstream testUserDict (line 1 # Custom segmentation for long entries), text 関西国際空港に行った | [関西, 国際, 空港, に, 行っ, た] | ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1 at setup |
Kuromoji, entry 関西国際空港,関西 国際 空港,... on line 1 | [関西, 国際, 空港] | RuntimeException: Illegal user dictionary entry <U+FEFF>関西国際空港 - the concatenated segmentation (関西国際空港) does not match the surface form (<U+FEFF>関西国際空港) |
Kuromoji stop-tags file (control, read through getLines) | [空港, 行っ, た] | the same |
Before 9.0.0 Kuromoji did not throw for an entry on line 1; like Nori, it silently ignored it (3.6.0: 朝青龍 gave [朝, 青龍] instead of [朝青龍]).
Exposure and likelihood260 words
- Who is exposed. Applications that opt in to a Kuromoji or Nori user dictionary: the
userDictionaryargument ofJapaneseTokenizerFactory/KoreanTokenizerFactory(directly, through thejapanese/koreanSPI names, or through a search-server schema, as both factory javadocs show), or code that passes aReaderover such a file toUserDictionary.open. The default configuration, without a user dictionary, is not affected. - What it takes. The dictionary file saved as UTF-8 with a BOM. User dictionaries are hand-edited word lists, and editors such as Windows Notepad often write a BOM (the SOLR-1865 change note says so).
- Nori: silent. When line 1 is an entry, that entry is ignored: documents and queries with that word are segmented as if it were not in the dictionary, with no error. The other entries work. A comment or blank line 1 hides the problem (no visible effect in the inputs tested).
- Kuromoji 9.0.0 and later: loud. An ordinary BOM-prefixed file fails at analyzer setup, with
ArrayIndexOutOfBoundsException(comment or blank line 1, the shape of Lucene's own test dictionary and of the Solr sample) orIllegal user dictionary entry(entry on line 1); neither names the byte order mark. Kuromoji 3.6.0 to 8.11.4 silently ignored an entry on line 1, like Nori. - Scale. Deterministic, at setup, independent of index size: one entry (Nori) or the whole dictionary (Kuromoji).
- How likely. Rare (registry: rare, priority low): opt-in, needs the BOM, Nori loses only an entry on line 1, Kuromoji fails loudly so users re-save the file, and no report was found since Kuromoji shipped in 2012.
The test shows that a Nori user dictionary that starts with a UTF-8 byte order mark (UserDictionary.open("\uFEFF세종시 세종 시\n")) silently loses its first entry.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ko;

import java.io.StringReader;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.ko.dict.UserDictionary;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestNoriUserDictionaryUtf8Bom extends BaseTokenStreamTestCase {

  public void testLeadingBomKeepsFirstEntry() throws Exception {
    UserDictionary dict = UserDictionary.open(new StringReader("\uFEFF세종시 세종 시\n"));
    Tokenizer tokenizer =
        new KoreanTokenizer(
            newAttributeFactory(), dict, KoreanTokenizer.DecompoundMode.DISCARD, false);
    tokenizer.setReader(new StringReader("세종시"));
    // expected: the user entry segments 세종시 as [세종, 시], as without the BOM; actual: [세, 종시]
    assertTokenStreamContents(tokenizer, new String[] {"세종", "시"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-950/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/nori/build/libs/lucene-analysis-nori-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ko.TestNoriUserDictionaryUtf8Bom
# the module(s) analysis-nori also need their third-party runtime jars
- Expected vs actual
- Expected
KoreanTokenizerto segment 세종시 as [세종, 시], as without the mark; actual: [세, 종시] (term 0 expected:<세[종]> but was:<세[]>), with -ea and -da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<세[종]> but was:<세[]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.ko.TestNoriUserDictionaryUtf8Bom.testLeadingBomKeepsFirstEntry(TestNoriUserDictionaryUtf8Bom.java:33)- Lucene's loader for other analysis resource files skips a leading BOM (
WordlistLoader.getLines), as do the hunspell dictionary and the new Thai user dictionary. - On the factory path Lucene decodes the bytes itself, and no JDK charset strips a UTF-8 BOM.
- Kuromoji's loop says "Skip empty lines or comment lines", yet a BOM makes it crash on one.
The full argument263 words
- The factory owns the decoding. It turns the file's bytes into characters itself (
JapaneseTokenizerFactory.java:142-156,KoreanTokenizerFactory.java:110-124); no factory argument helps:userDictionaryEncodingcannot remove a UTF-8 BOM, because no JDK 25 charset does. The only workarounds are re-saving the file without the BOM or wrapping theResourceLoaderto drop the three bytes, which a workaround probe on main confirmed; a workaround does not make the behaviour intended. - Lucene skips the mark elsewhere.
WordlistLoader.getLines(SOLR-1865, 2010: it "ignores Byte Order Markers (BOMs) at the beginning of input files, these are often created by editors such as Windows Notepad"), the hunspell dictionary (LUCENE-5505, listed under 4.8.0 "Bug fixes") and the newest tokenizer user dictionary (Thai, GITHUB#16722, 10.6.0, read throughgetWordSet). Of the three tokenizer user dictionaries, one skips a BOM and two do not. - The loader's own intent. Kuromoji's loop says "Skip empty lines or comment lines"; with a BOM it instead crashes on a comment line.
- Nothing documents or tests the current behaviour. No javadoc, CHANGES or MIGRATE entry says a user dictionary must be BOM-free,
UserDictionary.openhas no javadoc, no Kuromoji or Nori test uses a BOM, and neither loader ever had BOM handling. - Valid input, silent effect. A BOM-prefixed file is valid UTF-8 and Nori accepts it without a word; a silently ignored entry is the kind of leniency a committer objected to in LUCENE-8584 ("Now they can add something to the end of their dictionary and it gets ignored?").
- Classification is open. No document promises BOM handling, so upstream may call the fix an improvement (SOLR-1865 was typed Improvement).
The devil's-advocate check264 words
Rated moderate by the cross-model reviews (an independent reviewer from another model family, OpenAI GPT-5.6, reading-only) and by the intended-behaviour checker. (a) UserDictionary.open(Reader) takes characters and promises no BOM handling; Java keeps U+FEFF on purpose; a committer wrote on LUCENE-7785 "if you have a byte order mark in your character input (reader) then your conversion from bytes is screwed up somewhere before". (b) LUCENE-8933 deliberately made Kuromoji require surface = segmentation, and LUCENE-8584 declined to make the loader lenient ("Its not stuff a library should be doing"). (c) KoreanTokenizerFactory is @lucene.experimental. (d) In 2010 a committer answered "No." to "should we consider that a bug?" about a BOM in a stop list, and SOLR-1865 was typed Improvement.
Why it fails: (a) on the factory path the "conversion from bytes" is Lucene's own code, so that remark argues for fixing the factory, not for keeping the behaviour (it was also about a char filter, not file loading); (b) LUCENE-8933 validates entries, it does not intend a comment line to crash, and the LUCENE-8584 objection was to silently ignored entries, which is what Nori does now; (c) experimental does not make a silent loss intended, and the Kuromoji factory is not experimental; (d) the same 2010 reply went on: "Yes, we can ignore them for the first line of the file to be more user-friendly. I'll open an issue" (SOLR-1865 followed), and in 2014 the same slip in hunspell went under "Bug fixes". What survives is the bug-or-improvement classification, not the defect, and maintainers could still reasonably prefer the factory-only fix, which keeps open(Reader) strict.
Recommended Skip a BOM at the start of line 1 in both UserDictionary.open loops (recommended, validated)
In both UserDictionary.open loops, drop a U+FEFF at the start of line 1 before the comment check, the idiom WordlistLoader.getLines already uses (+6 lines each). The 6 new tests pass, and so do all 90 Nori and 198 Kuromoji tests and both modules' static checks.
    // text + optional segmentations
    boolean firstLine = true;
    while ((line = br.readLine()) != null) {
      // skip initial bom marker
      if (firstLine && line.length() > 0 && line.charAt(0) == '\uFEFF') {
        line = line.substring(1);
      }
      firstLine = false;
      // Remove comments
      line = line.replaceAll("#.*$", "");
All options and trade-offs4 options · 631 words
Two fixes were applied in a scratch worktree of a9779ef3c193 and run with gradle; the worktree was removed afterwards. The other options were not run.
Before the comment and blank-line checks, remove a U+FEFF at position 0 of the first line; a first comment line is then skipped as intended. The same 6 lines in ja/dict/UserDictionary.java and ko/dict/UserDictionary.java (the Nori loop is shown); the idiom of WordlistLoader.getLines:302-304, with braces (getLines drops U+FEFF until it has kept a line, this drops it from the first line read: the same for a file that starts with a BOM). It reaches every caller of the public open(Reader), including downstream code that reads the file itself.
    // text + optional segmentations
    boolean firstLine = true;
    while ((line = br.readLine()) != null) {
      // skip initial bom marker
      if (firstLine && line.length() > 0 && line.charAt(0) == '\uFEFF') {
        line = line.substring(1);
      }
      firstLine = false;
      // Remove comments
      line = line.replaceAll("#.*$", "");
Trade-offs
Only a U+FEFF at the very start of the input is removed; a later one is untouched. A dictionary whose first surface deliberately began with U+FEFF would change meaning. It changes a public Reader API, which the "a Reader holds characters" view may resist. No CHANGES entry is drafted; open PR #16272 touches both files, so the patch may conflict with it; open PR #14969 edits the Nori constructor, not the loop.
What the checks validated
- The 6 new tests and the closest upstream suites (
TestKoreanTokenizerFactory8, Noridict.TestUserDictionary2,TestJapaneseTokenizerFactory9, Kuromojidict.TestUserDictionary7) pass with assertions on and off: 32 tests, 0 failures (stock: 4 of the 6 new tests fail). - All of
:lucene:analysis:nori:test(14 classes, 90 tests, 4 skipped) and:lucene:analysis:kuromoji:test(31 classes, 198 tests, 7 skipped), assertions on: 0 failures. :lucene:analysis:nori:check :lucene:analysis:kuromoji:check -x testpasses with the new tests in place (google-java-format, ecjLint, forbiddenApis on main and test sources).- Earlier, with the hunt's version of the same change: the finder's repro 5/5, the reproducer's 13/13, the version-independent probe on main clean, the bounded-exhaustive check 0 mismatches, 26 upstream dictionary and factory tests pass.
Wrap the decoding reader in a PushbackReader, read one character and push it back unless it is U+FEFF, in JapaneseTokenizerFactory.inform and KoreanTokenizerFactory.inform.
        PushbackReader reader = new PushbackReader(new InputStreamReader(stream, decoder));
        // skip initial bom marker
        int first = reader.read();
        if (first != -1 && first != '\uFEFF') {
          reader.unread(first);
        }
        userDictionary = UserDictionary.open(reader);
Trade-offs
Puts the BOM handling where the bytes are decoded and leaves UserDictionary.open(Reader) strict, which answers the "a Reader holds characters" objection; it does not help code that calls open(Reader) on its own reader. Open PR #16272 changes the same KoreanTokenizerFactory.inform line, so this may conflict with it too. A UTF-16 file is unaffected (its decoder already consumed the BOM).
What the checks validated
Assertions on: the 3 Kuromoji tests and the Nori factory and control tests pass; as designed, the Nori testUserDictionaryOpenWithBom still fails (13 tests, 1 failed), because open(Reader) is unchanged. The full modules and the static checks were not run with it.
Throw an IllegalArgumentException naming the byte order mark.
Trade-offs
Nothing is lost silently and the message is precise, but it refuses valid UTF-8 that Lucene's other resource readers accept.
Use one small helper here and in the snowball word-set loader, the ICUTokenizerFactory rule files and the synonym parsers, which keep a BOM the same way.
Trade-offs
Fixes the whole class at once but touches several modules; worth raising if upstream wants one issue.
Two downstream search servers read the user dictionary with their own UTF-8 reader and hand the text to UserDictionary.open (read, not executed), so only a fix inside open reaches them.
A bounded-exhaustive metamorphic check loaded every user dictionary of 1 to 3 lines with and without a leading BOM and compared the analysis: 304 of 336 Kuromoji and 126 of 310 Nori checks differed, while three controls that read through WordlistLoader.getLines gave 0. The lead came from the same slip found earlier in a word-list loader.
The method in full190 words
Method (semi-formal): a bounded-exhaustive metamorphic check on the stock main jars.
- The law: loading a file F and loading BOM + F give the same analysis of every probe text (terms, position increments, position lengths), or the same exception class.
- The harness enumerated every user dictionary of 1 to 3 lines over a 4-line Kuromoji alphabet (two entries, a comment, a blank line) in search and normal mode, and a 5-line Nori alphabet (a compound entry, a noun entry,
c++, a comment, a blank line), with LF and CRLF line ends. Kuromoji: 304 of 336 checks mismatch, all loud (exceptions); Nori: 126 of 310, all silent (different segmentation). Three controls that read throughWordlistLoader.getLines(stop words, stemmer overrides, char mappings) give 0, and with the fix sketch every family gives 0, so the check both detects the defect and accepts the fix. - The lead came from an earlier hunt unit that found the same BOM slip in the snowball word-set loader and probed the other readers that bypass
getLines(first executed 2026-10-27). The finder then reduced it to a public-API JUnit. No model checker, solver or proof was involved.
No prior report found in GitHub issues and PRs (including the changed files of all 414 open PRs), the JIRA archive, the Lucene and Solr lists, Stack Exchange or the web in English, Japanese and Korean (searched 2026-10-28). SOLR-1865 and LUCENE-5505 fixed the same slip in other readers.
Searches5 searches
No report of this defect was found. The nearest items fixed the same slip at other fix sites or changed other parts of user dictionary loading. Gaps: keyword search only (GitHub does not index U+FEFF itself); private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repos, Lucene and Solr lists, JIRA archive | 2026-10-28 | a scripted prior-report search, three query sets plus the finder's run, every hit grepped for BOM, FEFF and "byte order mark" | about 4,200 distinct items (about 11,000 hits over the four runs), none about this bug |
| GitHub (apache/lucene, lucene-solr, solr, two downstream search servers, the original kuromoji project, all of GitHub) | 2026-10-28 | 68 manual searches, including everything created or updated since 2026-10-25; refreshed | no report |
| Open apache/lucene PRs | 2026-10-28 | changed files of all 414 open PRs (4 very large PRs list only their first 100 files) | #16272 (Nori FST heap use) is the only one that touches both UserDictionary files (and KoreanTokenizerFactory); it leaves the line loops as they are. #14969 (Nori token metadata) edits the Nori UserDictionary constructor only |
| LUCENE and SOLR JIRA; Lucene and Solr lists; Stack Exchange; web | 2026-10-28 | 14 JQL queries with 17 issues read in full, about 70 list queries, 8 Stack Exchange queries, 27 web queries in English, Japanese and Korean | none reports this bug |
| Related, not this bug | 2026-10-28 | read | SOLR-1865 (getLines BOM skip, Improvement), #6568 / LUCENE-5505 (hunspell BOM, Bug), #3584 / LUCENE-2510, #9642 / LUCENE-8596 and #7527 / LUCENE-6468 (other user dictionary parsing fixes), #9976 / LUCENE-8933 (the surface check), #9630 / LUCENE-8584 (Won't Fix, leniency), #8836 / LUCENE-7785 |
Present since each loader's first release: Kuromoji 3.6.0 (LUCENE-3305, 2012) and Nori 7.4.0 (LUCENE-8231, 2018, its loop copied from Kuromoji); never fixed. Executed on 18 Kuromoji and 10 Nori releases up to 10.5.2 and main. Until 8.11.4 Kuromoji also lost a first-line entry silently; from 9.0.0 it throws.
Versions tested6 rows
Introduced by LUCENE-3305, the Kuromoji code donation (Subversion era, no PR): trunk cd372bdc838 (2012-01-12, committed by Robert Muir) and the branch_3x backport 8c9485fb664, released in 3.6.0; and LUCENE-8231 (#9278), the Nori module: e851b89cbeb and branch_7x 8651fbaa8bc (2018-04-13, Jim Ferenczi), released in 7.4.0, whose loop lines git blame traces to the Kuromoji commit. Neither loader ever had BOM handling, so it is an omission, not a regression.
The symptom changed twice, the cause never: LUCENE-8933 (73ba88a50de, 9.0.0) made Kuromoji require surface = segmentation, so a BOM before an entry now throws (the 8.x backport only rejects longer segmentations, so 8.3.0 to 8.11.4 stay silent); LUCENE-8596 (9.0.0) anchored the comment pattern, which keeps the comment-line exception for a different reason. Upstream main 645d4fe14a20 (2026-10-28) has the same four files; on branch_10_6 both loaders and both inform methods are identical (the factories differ only in javadoc markup).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new tests: 2 of 3 fail per module (gradle, -ea and -da); the finder's 4 of 5, the reproducer's 6 of 13 |
| 9.0.0, 9.12.3, 10.0.0, 10.5.2 | Kuromoji throws | Kuromoji: Illegal user dictionary entry or ArrayIndexOutOfBoundsException; Nori: first entry silently lost |
| 7.4.0, 7.7.3, 8.0.0, 8.2.0, 8.3.0, 8.11.4 | affected | Nori and Kuromoji: first-line entry silently lost; Kuromoji comment line 1: ArrayIndexOutOfBoundsException |
| 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.1.0, 5.2.0, 6.6.6, 7.3.1 | affected | Kuromoji only (Nori from 7.4.0): first-line entry silently lost (朝青龍 gives [朝, 青龍]), comment line 1 throws |
| 3.5.0 | no Kuromoji | the API does not exist |
| main with the fix | fix | every probed BOM file loads like its BOM-less copy |
A finder, an independent reproducer, an intended-behaviour devil's advocate, cross-model reviews (OpenAI GPT-5.6, reading-only) and an adjudication: confirmed, high confidence. One review said not real only because it could not run code; it agreed with the root cause.
Checks and verdicts219 words
Every check that executed code reproduced the behaviour; the reading-only refute review found no artifact.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 4 of 5 on main (-ea, -da), 10.5.2, 9.12.3 and 9.1.0; 5 of 5 with its fix; bounded-exhaustive check. |
| intended review (OpenAI GPT-5.6) | real (medium) | Reading-only; root cause agrees, inputs in contract; intended-behaviour case moderate, not persuasive. |
| independent reproducer | real | Own tests with real BOM files fail 6 of 13 on main, 10.5.2 and 9.12.3; 13 of 13 with the fix; found that a BOM before a Nori comment line has no visible effect. |
| refute review (OpenAI GPT-5.6) | not real (low) | Procedural only: reading-only, it could not execute code; it agreed with the root cause and found no artifact; separate re-runs fail 4 of 5. |
| devil's advocate | real (medium-high) | Real files through FilesystemResourceLoader fail 2 of 7; UTF-16, no-BOM and Thai controls pass; no JDK charset strips a UTF-8 BOM; intended argument moderate. |
| adjudication | confirmed (high) | Re-ran the reproducer's and the finder's tests with new seeds, assertions on and off. |
| registry re-run, audit and this doc | keep | Re-runs fail on main and pass with the fix; this doc's gradle validation of the new tests and of both fixes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 558 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,530 words
- Registry title
- Kuromoji and Nori UserDictionary.open keep a leading UTF-8 byte order mark, so Nori silently drops the first user-dictionary entry and Kuromoji refuses to load the file
- Area
- analysis-kuromoji + analysis-nori / user dictionary loading (UserDictionary.open, reached through the JapaneseTokenizerFactory / KoreanTokenizerFactory userDictionary argument)
- Priority
- Low, rank 500: It is the same kept-BOM slip in the kuromoji and nori user dictionaries, where nori silently drops the first entry and kuromoji fails loudly, and those are used less than the synonym factories.
- Impact class
- silent wrong results
- Impact note
- Applications that load a Kuromoji or Nori user dictionary (the opt-in userDictionary factory argument, or UserDictionary.open on their own Reader) from a file saved as UTF-8 with a byte order mark: Nori silently ignores the first entry whenever line 1 is an entry (every release since 7.4.0), Kuromoji silently ignored it in 3.6.0-8.11.4 and since 9.0.0 refuses such a file with a RuntimeException whose two quoted strings print the same, and in every Kuromoji release a BOM before a comment or blank first line gives ArrayIndexOutOfBoundsException at analyzer setup; no scale is needed.
- Summary
- You give KoreanTokenizerFactory or JapaneseTokenizerFactory a user dictionary file that an editor saved as UTF-8 with a byte order mark (bytes EF BB BF), and expect the same dictionary as from the file without the mark, because Lucene's shared resource-line loader skips a leading BOM for the other file-based analysis factories (WordlistLoader.getLines, 'skip initial bom marker', SOLR-1865). Instead both factories decode the file themselves and pass it to UserDictionary.open, which keeps the invisible U+FEFF on line 1: in Nori the first entry becomes '\uFEFF세종시', which no text contains, so 세종시 is segmented [세, 종시] instead of the user's [세종, 시] with no error. Kuromoji (9.0.0 and later) rejects the file with 'Illegal user dictionary entry \uFEFF関西国際空港 - the concatenated segmentation (関西国際空港) does not match the surface form (\uFEFF関西国際空港)', and when line 1 is a '#' comment or blank it throws ArrayIndexOutOfBoundsException 'Index 1 out of bounds for length 1', because the BOM hides the comment from its 'skip empty lines or comment lines' check.
- Introduced
- kuromoji: cd372bdc83836148a7ae2e2958407ff0a37b7fc2 (LUCENE-3305 'add Kuromoji Japanese morphological analyzer', apache/lucene#4378, trunk svn r1230748, author Robert Muir; the loop was first imported on the lucene3305 contribution branch in bee8224c049, unreleased) with the branch_3x backport 8c9485fb66427e54ff0dac9708fdcbe72ba62e94 (r1231536), the one released in 3.6.0. nori: e851b89cbeb1f55edc0f2c1276e2ae812eca2643 (LUCENE-8231, apache/lucene#9278, master, author Jim Ferenczi) with branch_7x 8651fbaa8bc65fdfec397ad4e7ebe2b5acf78d7b, released in 7.4.0; its open() loop was copied from kuromoji (git blame -w -M -C -C traces the loop lines to cd372bdc838). Neither loader has ever had BOM handling (git log -i -G 'feff|bom|byte.order' over both modules and the 3.x kuromoji sources: no commit), so this is an omission from the first commit, not a regression. [read: git history in the full-history clone; the boundaries are executed: 3.5.0 has no kuromoji and 7.3.1 has no nori] (2012-01-12 (kuromoji, trunk; branch_3x 2012-01-14; contribution-branch import 2012-01-03); 2018-04-13 (nori))
- First affected version
- 3.6.0 [exec] for kuromoji (tagged 2012-04-11; UserDictionary loader; the Lucene JapaneseTokenizerFactory from 4.0.0 [exec], in 3.6 the factory was Solr-only); 7.4.0 [exec] for nori (tagged 2018-06-18; UserDictionary.open and KoreanTokenizerFactory). Neither API exists earlier: 3.5.0 has no kuromoji and 7.3.1 has no nori [exec: probe reports the API absent; Maven Central has no such jar].
- Affected versions
- Every release from 3.6.0 (kuromoji) and 7.4.0 (nori) to 10.5.2, 10.6.0 (by reading: branch_10_6 head 4ae946e5a9b9, below), and main a9779ef3c193 [exec: history probe BUG with clean controls on 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.1.0, 5.2.0, 6.6.6, 7.3.1, 7.4.0, 7.7.3, 8.0.0, 8.2.0, 8.3.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (nori from 7.4.0 on); the finder's JUnit fails on 9.1.0, 9.12.3, 10.5.2 and main; other releases inferred from code, read]. Symptom by era [exec]: kuromoji BOM + entry on line 1 = that entry silently never matches in 3.6.0-8.11.4 (the 8.x backport of the LUCENE-8933 check only rejects longer segmentations), RuntimeException 'Illegal user dictionary entry' from 9.0.0 (strict LUCENE-8933 check, 73ba88a50de); kuromoji BOM + '#' comment or blank line 1 = ArrayIndexOutOfBoundsException in every release; nori BOM + entry on line 1 = that entry silently lost in every release. Not fixed upstream: no commit touches the four files after a9779ef3c193 (last commits dbf0d1426f13, author date 2026-05-14, and 378ca8d1bbf3, 2026-01-15, both unrelated); upstream main head 645d4fe14a20 (2026-10-28) and the branch_10_6 head 4ae946e5a9b9 have identical UserDictionary sources [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-28, read-only; the prior-report record, verdict new): three scripted prior-report searches and the finder's (about 7,400 distinct hits over GitHub issues, PRs and commits, downstream repositories, the Lucene and Solr lists and the JIRA archive, all grepped for BOM, FEFF and byte order mark); 68 manual GitHub searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch, the predecessor atilika/kuromoji and codelibs (including items created or updated since 2026-10-25); 14 JQL queries on LUCENE and SOLR with 17 issues read in full; 72 queries over the Lucene and Solr list archives; 8 Stack Overflow queries; 27 web queries in English, Japanese and Korean; the changed-file lists of all 414 open apache/lucene PRs (only #16272, nori FST heap use, touches these files, and it leaves the line loop unchanged). No issue, PR, JIRA entry, list post, downstream issue or web page describes a BOM at the start of a kuromoji or nori user dictionary. Related only: SOLR-1865 (2010, BOM skip in the resource-line loader, typed Improvement; the precedent), #6568 / LUCENE-5505 (hunspell ignores BOMs, a Bug fix), #3584 / LUCENE-2510 (2010 remark that the Solr loader 'ignores BOM markers'), #9642 / LUCENE-8596 and #7527 / LUCENE-6468 (other user-dictionary parsing fixes), #9976 / LUCENE-8933 (introduced the surface check whose message the kuromoji case hits), #9630 / LUCENE-8584 (won't fix: the library should not be lenient about duplicate entries), the 2022 java-user thread 'Issue with Japanese User Dictionary' (same message, different cause) and #8836 / LUCENE-7785 (a committer's view that a BOM in a Reader means the byte decoding went wrong earlier). Not fixed: the four files are unchanged on upstream main (head 645d4fe14a20, 2026-10-28) and branch_10_6. Refresh 2026-10-28 (GitHub search and REST API): apache/lucene issues and PRs updated since 2026-10-26 that mention UserDictionary, kuromoji, nori, BOM or 'byte order mark': 0; 'BOM UserDictionary' and '"user dictionary" BOM': 0; of the 20 PRs created since 2026-10-26 (changed-file lists fetched), only #16911 lists the four files, because it decommissions branch_10x by deleting every file on that branch, and none changes them on main; the last commits on the four files are dbf0d1426f13 (author date 2026-05-14) and 378ca8d1bbf3 (2026-01-15). Gaps: keyword search only (GitHub does not index U+FEFF itself), GitHub's search rate limit was exhausted and those queries waited for the reset, the web search tool throttled some queries, and private reports are not searchable.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: two new test classes with the closest upstream suites, assertions on and off (stock: 4 of 32 tests fail; with the recommended fix: 0), that fix with all of:lucene:analysis:nori:test(90 tests) and:lucene:analysis:kuromoji:test(198 tests) and both modules'check -x test, and the factory-only fix with the selection; the worktree was removed afterwards. The hunt's repros on main (-ea,-da), 9.1.0, 9.12.3 and 10.5.2, and its version-independent probe on 19 releases from 3.5.0 to 10.5.2 and main; OpenJDK 25.0.3, Linux aarch64.
- Finding record
a Lucene main checkout lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/UserDictionary.java:49-65 (open: readLine, strip '#.*$', skip lines whose trim() is empty, no BOM check); lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:52-69 (open: same loop with LINE_COMMENT '^#.*$' and the comment 'Skip empty lines or comment lines'), :95-124 (constructor: values[1] at :97, surface-vs-segmentation RuntimeException at :114-123); lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:44-45, :142-156 and lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizerFactory.java:44-64 (userDictionary, userDictionaryEncoding, @lucene.experimental), :110-124 (inform: strict UTF-8 InputStreamReader over the resource, passed to UserDictionary.open); lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304 ('// skip initial bom marker' in getLines); re-read in the registration check; identical at ea57360912ed (git diff empty)
- The finding in 30 seconds
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizerFactory.java:110-124 (inform: strict decoder, InputStreamReader :122, UserDictionary.open :123) (main a9779ef3c193)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:142-156 (inform: reader :154, UserDictionary.open :155)lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/UserDictionary.java:49-72, :89-90, :114, :125-131, :161-184 (open loop; token = splits[0]; FST add; lookup from every start offset)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:37, :52-76, :96-97, :114-123 (LINE_COMMENT; open loop; surface and values[1]; LUCENE-8933 check)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:297-314 ('skip initial bom marker' at :302-304)lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:283-302; lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiTokenizerFactory.java:68; lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapanesePartOfSpeechStopFilterFactory.java:74
- Who is affected
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:39-52 and lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizerFactory.java:39-66 (javadoc schema examples; @lucene.experimental at :64)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/userdict.txt (line 1 is a comment) [read]
- Why it looks unintended
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:142-156; lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizerFactory.java:64, :110-124lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:63 ('Skip empty lines or comment lines')lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304lucene/CHANGES.txt:12543-12555 (4.8.0 Bug fixes, LUCENE-5505); :446, :476-478 (10.6.0, GITHUB#16722)lucene/MIGRATE.md:1291-1294 (LUCENE-8933)
- Suggested fix
lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304
- TestNoriUserDictionaryUtf8Bom.java (JUnit test):
repro/LFV-950/src/org/apache/lucene/analysis/ko/TestNoriUserDictionaryUtf8Bom.java(35 lines)
assets/LFV-950/bug.png(558 KB)