DocAndScoreQuery turns a list of (document, score) pairs into a query. Since #16686, anyone writing their own kNN query can build one from a TopDocs they assembled themselves.
- An index is made of segments. Inside a segment, documents have ids 0 to
maxDoc - 1; the global doc id is the segment'sdocBaseplus that id. createDocAndScoreQuerysortstopKby global doc id, then finds where each segment's entries start with a binary search for the segment'sdocBase.- Each segment then walks its own slice and subtracts its
docBaseto get its own ids. Deletions, doc values and the other clauses of a query are checked per segment, with that id.
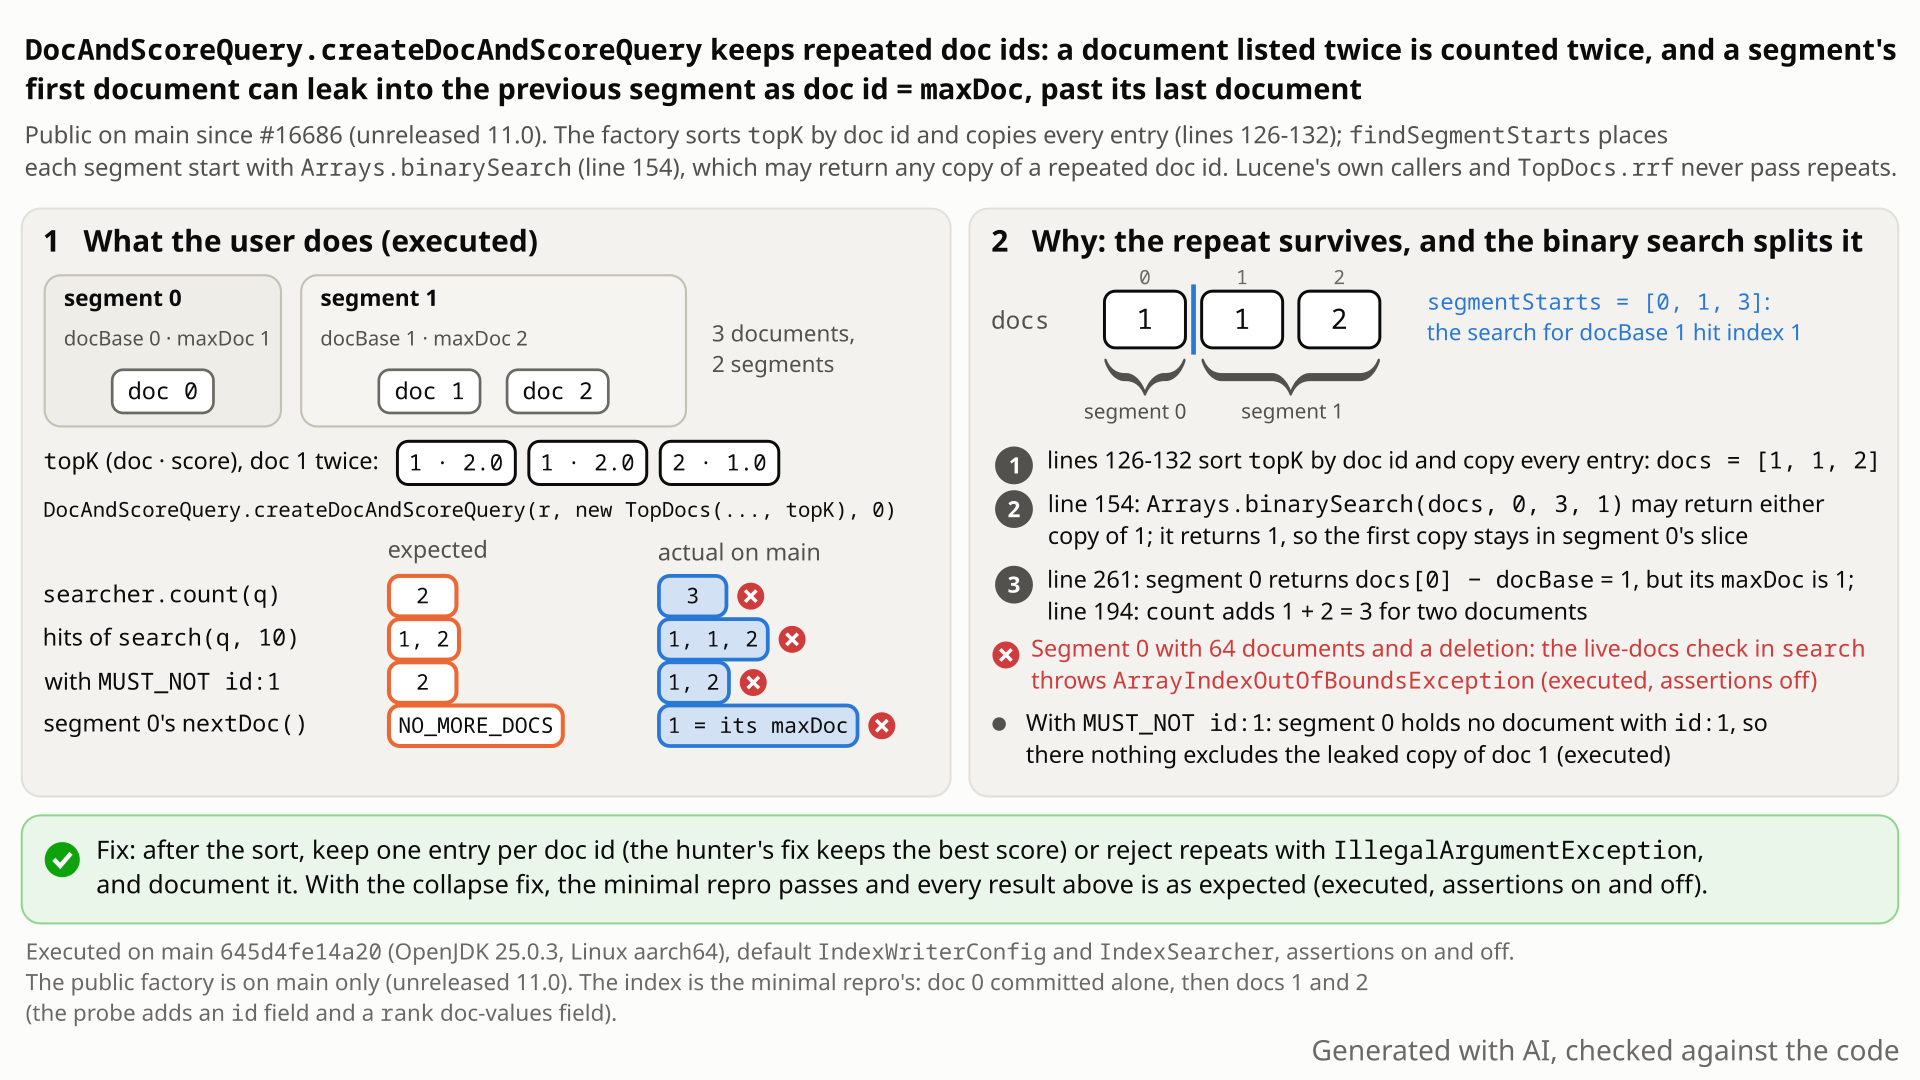
topK that lists doc 1 twice: the binary search splits the two copies, so segment 0 returns doc id 1, one past its only document, the count is 3 and a MUST_NOT clause on doc 1 does not remove it. Select the still to open it at full size. Generated with AI, checked against the code.- You index three documents in two segments: segment 0 holds doc 0, segment 1 holds docs 1 and 2.
- You pass a
TopDocsthat lists doc 1 twice,(1, 2.0), (1, 2.0), (2, 1.0), toDocAndScoreQuery.createDocAndScoreQuery, for example after concatenating two kNN result lists that both found doc 1. - You expect what the javadoc promises, a query that "matches exactly the documents in topK": docs 1 and 2, once each, a count of 2, nothing in segment 0.
- You get a count of 3 and hits
[1, 1, 2]. The factory keeps both copies, and the binary search that splits the list by segment lands on the second copy, so segment 0, whose only doc id is 0, also returns doc id 1. - That leaked copy is checked against segment 0, where doc 1 does not exist: with a
MUST_NOTclause on doc 1 the hits are[1, 2]instead of[2]. In the same shape with 64 documents and a deletion in segment 0, the search throwsArrayIndexOutOfBoundsException(assertions off).
Code on main (unreleased 11.0) that builds its own TopDocs for the new public factory and lets a document appear twice, such as a custom kNN query that concatenates the results of two vector fields. Default configuration, a few documents. Lucene's own callers and TopDocs.rrf never pass repeats, and no release exposes the public factory.
Mechanism, terms and numbers955 words
#16686 made DocAndScoreQuery and its createDocAndScoreQuery(IndexReader, TopDocs, ...) factory public on main, for authors of their own kNN queries. The javadoc promises a query that "matches exactly the documents in topK" and lists its preconditions, but not that a document may appear only once, and the factory does not check it. It sorts the entries by doc id and copies every one, so a repeated document is counted, iterated and returned once per copy (two kNN fields that find the same 4 documents give a count of 8). Segment boundaries are found with Arrays.binarySearch, which may land on any copy of a repeated value: when the repeated document is the first document of a segment, the earlier copy stays in the previous segment and comes out there as doc id maxDoc, one past its last document. That copy is checked against the wrong segment's live docs, doc values and other clauses. With deletions there, the live-docs check reads past its end: with assertions off it throws ArrayIndexOutOfBoundsException when that segment's maxDoc is a multiple of 64 and its live docs are dense (64 documents, one deleted), drops the copy for other sizes, and lets it through with sparse live docs (128 documents, one deleted: the document is returned twice). A doc-values sort throws or uses another document's value, and when that segment has no deletions the document is returned even if it is deleted or excluded by a MUST_NOT clause. Lucene's own callers and TopDocs.rrf never pass repeats, and no release exposes the public factory (9.9.0 to 10.6.0 reach the same code through a kNN query subclass that overrides protected hooks, judged contrived). Rejecting repeats with IllegalArgumentException (or collapsing them) fixes it; both were validated.
- The factory copies every entry.
createDocAndScoreQuery(:121-143) reads the max score fromscoreDocs[0](:125), sortstopK.scoreDocsby doc id in place (:126) and copies all entries intodocs[]andscores[](:127-132). Nothing removes or rejects a repeated doc id; the only input check isassert len > 0(:124). - Segment slices come from a binary search.
findSegmentStarts(:145-161) places each segment's first entry withArrays.binarySearch(docs, resultIndex, docs.length, upper), whereupperis the segment'sdocBase(:153-154). The JDK documents that "If the range contains multiple elements with the specified value, there is no guarantee which one will be found." Fordocs = [1, 1, 2]anddocBase1 the search probes the middle index first and returns index 1, sosegmentStarts = [0, 1, 3]. - Each segment counts and iterates its slice entry by entry.
Weight#countissegmentStarts[ord + 1] - segmentStarts[ord](:192-195);nextDocsteps one entry at a time (:217-224) and returnsdocs[upTo] - context.docBase(:254-262). Segment 0 gets slice[0, 1)= doc 1 and returns1 - 0 = 1, itsmaxDoc; segment 1 gets docs 1 and 2 and returns 0 and 1. In general the leaked copy comes out asdocBase(next) - docBase(prev) = maxDoc(prev). - Why the leaked copy escapes deletions and
MUST_NOT. The collector adds segment 0'sdocBase, so the hit has the right global id, but everything per segment is checked in segment 0: its live docs (an out-of-range bit; with assertions off: with 64 documents and a deletion,ArrayIndexOutOfBoundsException; with 3, 63 or 65 documents a clear padding bit, so the copy is dropped; with sparse live docs, 128 documents and one deletion, it passes and the document is returned twice; with no deletions, no check at all), its doc values (read past the end) and aMUST_NOTclause's iterator on segment 0, which never reaches doc idmaxDoc, so the exclusion does not apply. AFILTERclause never matches it there either, so a conjunction drops it. - Repeats away from a boundary stay in range but are counted and returned once per copy.
- Minimal layout (segment 0 = doc 0; segment 1 = docs 1, 2),
topKdocs[1, 1, 2]: segment 0 iterates[1]withmaxDoc1;Weight#count1 + 2;IndexSearcher#count3; hits[1, 1, 2]; withMUST_NOT id:1hits[1, 2]instead of[2]. - Two kNN fields that both find the same 4 documents, lists concatenated:
IndexSearcher#count8,totalHits8, every hit twice, iterator1 1 2 2 3 3 4 4. - Segment 0 with 64 documents and a deletion, docs
[64, 64, 65]:ArrayIndexOutOfBoundsException: Index 1 out of bounds for length 1from the live docs (assertions off),AssertionError: index=64, numBits=64(on). Other sizes, doc 0 deleted, docs[b, b, b+1]withb= segment 0'smaxDoc, assertions off: 3, 63 and 65 documents give hits[b, b+1](the copy reads a clear, unused bit and is dropped); 128 documents (sparse live docs) give[128, 128, 129], the document twice; with assertions on all five sizes throw anAssertionError. - Segment 0 with 64 documents and no deletion, sorted by a numeric doc-values field:
EOFExceptionwith the test framework's wrapped directory (newDirectory()),IndexOutOfBoundsExceptionwith a plainByteBuffersDirectory; with a 3-document segment 0 the document is sorted with a value that is not its own (1000 instead of 1003). - Segment 0 without deletions: the document is returned even when it is deleted, and despite a
MUST_NOTclause that matches it; aFILTERclause still excludes it.
Making the binary search return the first copy alone makes the minimal test pass but keeps the doubled hits (expected:<[64, 65]> but was:<[64, 64, 65, 65]>).
Exposure and likelihood244 words
- Who is exposed. Authors of their own kNN queries on main or
branch_11xwho build theTopDocsby hand, for example by concatenating the results of two vector fields or two query vectors without de-duplicating. #16686 opened the API for exactly such "own KNN query classes". - Configuration and scale. Default configuration and a few documents: the minimal test uses a plain
IndexWriterConfig,ByteBuffersDirectoryandIndexSearcher(some consequence probes setNoMergePolicyonly to keep their segment layout). The boundary shape also needs the repeated document to be the first document of a segment other than the first. - Symptoms. Doubled counts,
totalHitsand hits, with no error. At a segment boundary, depending on the previous segment: an exception far from the cause (ArrayIndexOutOfBoundsException,EOFException,IndexOutOfBoundsException), a wrong sort value, a document returned twice, or a deleted orMUST_NOT-excluded document returned. - Not exposed. Lucene's own callers (
AbstractKnnVectorQuery.java:156,RescoreTopNQuery.java:90) pass lists without repeats.TopDocs.rrf(TopDocs.java:372) merges repeated documents: the same two-field inputs combined with it pass, including the boundary layout with a deletion and a doc-values sort. No release has the public factory (package-private in 10.x, private in 9.x); 9.9.0 to 10.6.0 reach the same code through a kNN query subclass that overrides protected hooks (see History). - Likelihood: rare. It needs a hand-built list that keeps a document twice. Downstream multi-kNN code (elastic/elasticsearch#92118) shows such lists do contain repeats, and de-duplicates them before building its own query.
One JUnit class, one method, public API: three empty documents in two segments, topK docs [1, 1, 2], and an assertion that segment 0, which holds only doc 0, matches nothing. It draws no random values itself (the framework still randomizes codec and similarity; every seed tried fails the same way), with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDocAndScoreQueryRepeatedDoc extends LuceneTestCase {

  public void testRepeatedFirstDocOfSegment() throws IOException {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        w.addDocument(new Document());
        w.commit();
        w.addDocument(new Document());
        w.addDocument(new Document());
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        ScoreDoc[] topK = {new ScoreDoc(1, 2f), new ScoreDoc(1, 2f), new ScoreDoc(2, 1f)};
        Query q =
            DocAndScoreQuery.createDocAndScoreQuery(
                r, new TopDocs(new TotalHits(3, TotalHits.Relation.EQUAL_TO), topK), 0);
        Weight weight = new IndexSearcher(r).createWeight(q, ScoreMode.COMPLETE, 1f);
        Scorer seg0 = weight.scorer(r.leaves().get(0));
        // expected: segment 0 (doc 0 only) matches nothing; actual: it returns doc 1 == its maxDoc
        int first = seg0 == null ? DocIdSetIterator.NO_MORE_DOCS : seg0.iterator().nextDoc();
        assertEquals("first doc of segment 0", DocIdSetIterator.NO_MORE_DOCS, first);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestDocAndScoreQueryRepeatedDoc -Ptests.seed=DEADBEEF
- Expected
- Segment 0 matches nothing: its first
nextDoc()isNO_MORE_DOCS(2147483647). - Observed
expected:<2147483647> but was:<1>: segment 0, whose only document has doc id 0, returns doc id 1.
More files, environment, full output338 words
The class sits in org.apache.lucene.search next to the kNN tests and uses nothing package-private; a probe outside the package shows the same leak. It uses a plain IndexWriterConfig, ByteBuffersDirectory and a plain IndexSearcher, with a commit after the first document so that segment 0 holds doc 0 and segment 1 holds docs 1 and 2. It needs the public 3-argument factory, so it compiles only on main and branch_11x (10.6.0 has no createDocAndScoreQuery(IndexReader, TopDocs, int) and its factories are package-private: "incompatible types: int cannot be converted to NoMatchExplainer").
Regression test: this same test. With the collapse fix it passes as written. With the recommended reject fix the factory call throws, so the test's last five statements become a TopDocs local and one expectThrows(IllegalArgumentException.class, () -> DocAndScoreQuery.createDocAndScoreQuery(r, topDocs, 0)); that form passes with the fix and fails on stock ("Expected exception IllegalArgumentException but no exception was thrown").
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with either fix: no out-of-range doc id; 10.6.0: does not compile (no createDocAndScoreQuery(IndexReader, TopDocs, int); the factories are package-private) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; plain Java logic) |
cp $REPRO/TestDocAndScoreQueryRepeatedDoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestDocAndScoreQueryRepeatedDoc -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false (the recorded runs added --offline --no-daemon)
# gradle, scratch worktree of 645d4fe14a20, seed DEADBEEF, assertions on
   >     java.lang.AssertionError: first doc of segment 0 expected:<2147483647> but was:<1>
   >         at __randomizedtesting.SeedInfo.seed([DEADBEEF:E90A93E502F3C914]:0)
   >         at org.junit.Assert.fail(Assert.java:89)
   >         at org.junit.Assert.failNotEquals(Assert.java:835)
   >         at org.junit.Assert.assertEquals(Assert.java:647)
   >         at org.apache.lucene.search.TestDocAndScoreQueryRepeatedDoc.testRepeatedFirstDocOfSegment(TestDocAndScoreQueryRepeatedDoc.java:47)
:lucene:core:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false: same message, 1 of 1 failed

# public-API probe outside the package, same layout with an id field per document (assertions on and off identical)
topK docs=[1, 2]    | leaf0 Weight#count=0 iterated=[]  | leaf1 Weight#count=2 iterated=[0 1] | IndexSearcher#count=2 totalHits=2 hits=[1, 2] | with MUST_NOT id:1 hits=[2]
topK docs=[1, 1, 2] | leaf0 Weight#count=1 iterated=[1] | leaf1 Weight#count=2 iterated=[0 1] | IndexSearcher#count=3 totalHits=3 hits=[1, 1, 2] | with MUST_NOT id:1 hits=[1, 2]- The javadoc promises a query that "matches exactly the documents in topK" and lists its preconditions (same reader, descending scores, non-empty), but not uniqueness.
- A segment returning a doc id equal to its
maxDocbreaks theDocIdSetIteratorcontract under any reading. - #16686 opened the class, untagged, for authors of their own kNN queries, who build such lists.
The full argument266 words
- The contract describes a set of documents. "Create a query that matches exactly the documents in {@code topK}" and "@param topK the documents to match" (
DocAndScoreQuery.java:104,:114).IndexSearcher#count: "Count how many documents match the given query" (IndexSearcher.java:491);Weight#count: "Counts the number of live documents that match" (Weight.java:182). A count of 3 for 2 documents contradicts all three. - Every other precondition is listed. Global doc ids of that reader, that reader only (else
IllegalStateException), descending score order, non-empty (DocAndScoreQuery.java:103-120). The class has no@lucene.internalor@lucene.experimentaltag, and it already fails fast on the other documented misuse (another reader throws increateWeight,:170-171). - The iterator contract. A leaf doc id equal to
maxDoclies outside the segment's doc-id space under any reading. Repeats away from a boundary are a weaker point:DocIdSetIteratorsays "a set of non-decreasing doc ids" (DocIdSetIterator.java:23), which read literally allows equal neighbours, but also "set" and, fornextDoc, "Advances to the next document in the set" (:127); the test framework asserts strictly increasing, in-range ids (AssertingScorer.java:171"backwards nextDoc",AssertingLeafCollector.java:128-130"Out of order", "Out of range"). - Lucene's other public set-like inputs de-duplicate or reject.
TermInSetQuery.java:153andPointInSetQuery.java:118skip repeats ("// deduplicate");RoaringDocIdSet.Builderthrows "Doc ids must be added in-order" (RoaringDocIdSet.java:118). - An exposure, not a design. The copy-every-entry factory and the binary search date from LUCENE-9614 (2021), when only Lucene's duplicate-free callers could reach them. #16686 changed only visibility and javadoc; its discussion covers
NoMatchExplainervisibility and the backport, nothing about input requirements.
The devil's-advocate check217 words
The intended-behaviour verifier and the adjudication built the strongest case for "callers must de-duplicate": topK is a TopDocs, which "Represents hits returned by IndexSearcher#search" (TopDocs.java:26), and the javadoc expects it "as produced by a nearest-neighbors search" (DocAndScoreQuery.java:109-110); a search never returns a document twice. The package-private constructor has documented docs "in ascending order" since 2021 (:52); #12152 built count on "a monotonically increasing start for each scored document"; a maintainer wrote "Lucene hits would never duplicate docid" in the #15950 review; TopDocs.rrf is the idiomatic fusion; and a downstream project de-duplicates before building its own analogous query (elastic/elasticsearch#92118).
Why it fails: the public javadoc spells out its preconditions and leaves uniqueness out (the ascending-order and monotonic notes concern the package-private constructor and internal callers); the API was opened for authors who build such lists themselves; and the failure mode is no error at the call, then an out-of-range doc id that crashes far away or lets a deleted or excluded document through. So even if maintainers rule uniqueness a precondition, a documented check is warranted. The cross-model reviews rated the intended-behaviour case "moderate"; the reproducer, the devil's advocate, the adjudication and an audit kept the bug. Verdict: not intended; at least a missing precondition check in a new public API.
Recommended Reject repeated doc ids with IllegalArgumentException (recommended, validated)
Reject repeated doc ids in the factory with IllegalArgumentException and state it in the javadoc (+5/-1). Validated: the repro now fails fast at the call, its expectThrows form passes, and 297 core kNN and rescore tests, the join kNN tests and the format, ECJ and forbidden-apis checks pass. Collapsing repeats is validated too.
for (int i = 0; i < len; i++) {
  docs[i] = topK.scoreDocs[i].doc;
  scores[i] = topK.scoreDocs[i].score;
  if (i > 0 && docs[i] == docs[i - 1]) {
    throw new IllegalArgumentException("topK lists doc " + docs[i] + " more than once");
  }
}
All options and trade-offs4 options · 581 words
Two fixes were validated through gradle in a scratch worktree of 645d4fe14a20; both act in the factory, before the segment split, so every segment's slice holds distinct, increasing doc ids. A third change was run for comparison only: it is not sufficient.
In createDocAndScoreQuery, after the sort, throw when a doc id equals the previous one, and add the precondition to the javadoc: "Each document may appear at most once in {@code topK}; {@link IllegalArgumentException} is thrown otherwise."
for (int i = 0; i < len; i++) {
  docs[i] = topK.scoreDocs[i].doc;
  scores[i] = topK.scoreDocs[i].score;
  if (i > 0 && docs[i] == docs[i - 1]) {
    throw new IllegalArgumentException("topK lists doc " + docs[i] + " more than once");
  }
}
Trade-offs
- Least opinionated. No score policy to choose; callers that combine lists keep control of fusion (for example
TopDocs.rrf). It matches the class's existing fail-fast check of the reader. The devil's-advocate verifier and the adjudication call it the least opinionated choice, and an audit expects a committer to accept it with little debate. - Cost. One comparison per entry; Lucene's own callers never trigger it. The throw comes after the documented in-place sort of
topK. It also changes behaviour for released kNN query subclasses whose overridden hooks return a repeat: they getIllegalArgumentExceptioninstead of wrong results, so a CHANGES line is worth considering. - Test. The minimal test's final statements become an
expectThrows(see Minimal repro).
What the checks validated
- Repro: now stops at the factory with
IllegalArgumentException: topK lists doc 1 more than once; theexpectThrowsform passes with the fix and fails on stock. :lucene:coresearch.*Knn*,TestPatience*,TestRescoreTopNQuery*,TestFilterReadersForwardVectorPrefetch: 297 tests, 2 skipped, 0 failures;:lucene:joinkNN tests: 39, 0 failures.checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain: pass.
After the sort, merge equal doc ids, keep the maximum of their scores and trim the arrays with ArrayUtil.copyOfSubArray; one javadoc sentence: "A document listed more than once matches once, with the highest of its scores." (+17/-3)
Trade-offs
Fulfils "matches exactly the documents in topK" literally and keeps the minimal test unchanged, but silently picks a fusion policy (max): a caller who wanted sum or first gets max without noticing, so the policy must be documented. The hunt's original version used Arrays#copyOf, which Lucene's forbidden-apis check rejects ("Prefer using ArrayUtil"); this version does not.
What the checks validated
- The minimal test passes as written, assertions on and off; 14 core classes, 298 tests (the repro and the same suites), 2 skipped, 0 failures; the assertions-off subset (91) and the join kNN tests (39) pass.
- All five lint tasks pass; the hunt's 4-test class (assertions on and off) and the independent reproducer's 5-test class pass with it.
findSegmentStarts steps back to the first index of a run of equal doc ids.
Trade-offs
Run for comparison only: the minimal test passes, but repeats are still counted and returned twice (the hunt's tests fail 3 of 4, expected:<[64, 65]> but was:<[64, 64, 65, 65]>). Useful as hardening on top of a factory fix, not instead.
Add "each document at most once" to the javadoc without a check.
Trade-offs
Keeps the out-of-range doc id, and its deletion and MUST_NOT effects, for anyone who misses the sentence.
An application that concatenates result lists without de-duplicating and relies on a MUST_NOT clause or a deletion to hide a document can get that document back when it is the first document of a segment.
A probe written while reading the new public factory's contract came first: two concatenated kNN result lists gave a count of 8 for 4 documents. The hunt unit then modelled the segment-boundary binary search in Z3 with the JDK's exact algorithm, found the witness [b, b, c] at docBase = b, and reduced it to a public-API JUnit.
The method in full183 words
Method: non-formal first signal (a probe; the Z3 model came after it).
- While reading the contract of the factory made public by #16686, the hunt ran a probe on main (2026-10-28): two kNN result lists concatenated,
IndexSearcher#count8 for 4 distinct documents, iterator1 1 2 2 3 3 4 4. - The hunt unit wrote a Z3 model of
findSegmentStartswith Java's exactArrays.binarySearch0over unbounded 32-bit doc ids: 24 satisfiable cases with repeats, witnessdocs = [b, b, c],docBase = b, and none for a lower-bound search. It checked the model against the real jar on 64,659 sorted arrays. - A bounded-exhaustive model-based test of the factory javadoc against the stock jar (every
topKmultiset of size 1 to 4 on 5 segment layouts and 3 score variants, 12 observables, 3,135 cases, about 307,000 checks): all 2,295 repeated-doc cases fail, none of the 840 duplicate-free cases. - It reduced this to a public-API JUnit; an independent reproducer, a devil's-advocate verifier, cross-model reviews and an adjudication then checked it. A later step shrank the repro to one test on three documents.
No prior report found (2026-10-28: GitHub issues, PRs and commits, downstream projects, four mailing lists, the JIRA archive and the web; GitHub rechecked 2026-10-31). Closest: a downstream project de-duplicates multi-kNN results before building its own analogous query (elastic/elasticsearch#92118).
Searches2 searches
Verdict new: no issue, PR, review comment, commit, list thread, JIRA entry or downstream report describes repeated doc ids in DocAndScoreQuery or its factory. Related, not reports: #16686 (the introducing change); #12152 (count built on monotonic segment starts); the #15950 review remark "Lucene hits would never duplicate docid"; elastic/elasticsearch#92118 (a downstream design remark that handling duplicates in that project's query "would then require some change within KnnScoreDocQuery to handle duplicate docs"); the OpenSearch k-NN plugin's own copy of the factory (same pattern, no report); #13470 (TopDocs.rrf, which de-duplicates); open draft PR #16847 (long doc ids), which rewrites the same lines without changing repeat handling, so a fix may need a rebase.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, Elasticsearch, OpenSearch and its k-NN plugin, Solr), dev@, java-user@, issues@, commits@, JIRA, web | 2026-10-28 | three runs of a scripted prior-report search (45 queries each) plus the finder's and a verifier's runs; 31 manual GitHub searches; code search; the comment and review threads of 31 Lucene and 4 downstream issues and PRs; the changed files of the 200 most recent open apache/lucene PRs; four mailing-list threads | no report; related #16686, #12152, #15950, elastic/elasticsearch#92118, #13470, #16847 |
| GitHub (recheck) | 2026-10-31 | DocAndScoreQuery, createDocAndScoreQuery, "DocAndScoreQuery duplicate", findSegmentStarts, "knn duplicate doc ids", "same document twice knn" in apache/lucene issues and PRs updated since 2026-10-28; the file's commit history on main; the complete changed-file lists of all 410 open apache/lucene PRs (fact check) | nothing related; the file's last commit is still the introducing one; of the 410 open PRs only draft PR #16847 touches DocAndScoreQuery.java |
Introduced on main by #16686 (2026-09-29), which made the class and factory public; the code that keeps repeats dates from LUCENE-9614 (9.0.0) but had no public entry point. No release has the public factory; 9.9.0 to 10.6.0 reach the same code through a kNN subclass that overrides the experimental mergeLeafResults hook (judged contrived).
Versions tested6 rows
Introduced by #16686, "Make DocAndScoreQuery public" (c857eeebe7e, mccullocht, 2026-09-29, main only, milestone 11.0.0; CHANGES lists it under 11.0.0 API Changes). It made the class and both factory overloads public and added the "matches exactly the documents in topK" javadoc, without changing the factory body. With the parent's DocAndScoreQuery.java shadowed into the main jars, a public-API probe does not compile and the in-package test still fails, because the logic is identical.
Latent mechanism: LUCENE-9614 (624560a3d70, msokolov, 2021-08-13, first released in 9.0.0); later refactors (#12004, #12146, #12152, #13528, #14009, #14226, #16271) kept the behaviour. In 9.9.0 to 10.6.0 (the newest release) the same code is reachable through a subclass that overrides the protected @lucene.experimental AbstractKnnVectorQuery#mergeLeafResults hook (inherited by KnnFloatVectorQuery; its javadoc says it "is useful for reading and / or modifying the final results") to return a repeated entry: fails 2 of 2 on 9.9.0, 9.12.3, 10.5.2 and 10.6.0; 9.8.0 has no hook. Other protected per-leaf hooks (searchLeaf, approximateSearch, exactSearch) could feed repeats the same way, through TopDocs.merge, which does not de-duplicate (read, not executed). Judged contrived.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (and a9779ef3c193) | affected | minimal test fails with assertions on and off; count 3 for 2 documents; the hunt's and the reproducer's tests fail |
main head 2f424fd428da, branch_11x | affected | same file (blob 4ba4c473359e), not executed |
c857eeebe7e^ (before #16686, file shadowed) | bisect | no public factory: a public-API probe does not compile; the in-package logic is identical |
10.6.0, 10.5.2, 9.12.3, branch_10_6 | not affected | no public factory (package-private in 10.x; in 9.x a private method of a nested class); the public-API tests do not compile |
9.9.0 to 10.6.0 via mergeLeafResults override | contrived | an override that returns a repeated entry reaches the same code and fails 2 of 2 (9.9.0, 9.12.3, 10.5.2, 10.6.0) |
with either fix (645d4fe14a20) | not affected | no out-of-range doc id; 297 or 298 core kNN and rescore tests and 39 join kNN tests pass |
An independent reproducer, a devil's-advocate verifier and cross-model reviews agree on the root cause (one review was negative only because it could not run code); the adjudication confirmed with medium confidence, and the bug still reproduces on 645d4fe14a20.
Checks and verdicts376 words
Every executing check ran on stock builds of main (a9779ef3c193 or 645d4fe14a20, the same file) or on releases. The cross-model reviews could only read the code; separate runs re-ran the repro.
| Check | Verdict | What it found |
|---|---|---|
| Finder (Z3 model, model-based test, JUnit) | candidate | JUnit fails 4 of 4 with assertions on and off; the duplicate-free control passes; all 2,295 repeated-doc cases of the exhaustive test fail and none of the 840 duplicate-free ones; the collapse fix passes plus 87 kNN and rescore tests. |
| Cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (low), procedural only | Could not run code; agreed with the root cause and that the inputs are in contract, rated the intended case moderate and said static review "strongly favors a genuine defect". A separate re-run failed 4 of 4. |
| Independent reproducer | real | Own public-API JUnit fails 4 of 5 with assertions on and off, also with the default codec forced, 40 of 50 over 10 random iterations; the control passes; no public factory in 10.5.2 or 9.12.3. |
| Cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium | Intended case moderate and rejected; separate re-runs fail 4 of 4 and the controls pass. |
| Devil's advocate | real, low severity | Built the "callers must de-duplicate" case and found it loses to the javadoc as written; its TopDocs.rrf control passes 2 of 2. |
| Adjudication | confirmed, medium | Re-ran the reproducer's JUnit (assertions off, 4 of 5 fail) and the finder's (on, 4 of 4). |
| Audit and re-verify | keep; still reproduces | Audit re-ran the public probe, the finder's test and the control; on 645d4fe14a20 the finder 4/4, the reproducer 4/5 and the public probe 2/2 fail, the control passes. |
| This brief (2026-10-31) | reproduced, fixes validated | Gradle on 645d4fe14a20 with assertions on and off; both fixes validated; the lower-bound-only change shown insufficient; 10.6.0 compile check; upstream recheck. |
| Fact checks (2026-10-31) | bug holds; wording corrected | An independent fact check re-ran the repro, both fixes, a deletion-size probe, the hook route on 10.6.0 (2 of 2 fail) and a scan of all open PRs; a cross-model fact check (OpenAI GPT-5.6, reading only) read the code and logs. Their corrections are applied in this doc. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 540 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,461 words
- Registry title
- DocAndScoreQuery.createDocAndScoreQuery (public on main since #16686) keeps repeated doc ids: a document listed twice is counted and returned twice, and a repeated first document of a segment is iterated by the previous segment as doc id == maxDoc (a deleted or MUST_NOT-excluded document comes back, or a search with deletions or a doc-values sort throws)
- Area
- search / kNN query execution (DocAndScoreQuery public factory, new in 11.0 via #16686; Weight#count and DocIdSetIterator contracts)
- Priority
- Low, rank 870: Repeated doc ids in the new public DocAndScoreQuery factory cause doubled or deleted hits or exceptions, but only for custom kNN authors on unreleased 11.0.
- Impact class
- silent wrong results
- Impact note
- Only code on main (unreleased 11.0) that builds its own TopDocs for the new public factory and lets a document appear twice, for example a custom kNN query that concatenates the result lists of two fields or two query vectors, is hit: counts, totalHits and hits are inflated with no error, and when the repeated document is the first document of a segment it can also be returned although deleted or excluded by a MUST_NOT clause, or the search throws (ArrayIndexOutOfBoundsException with deletions, EOFException or IndexOutOfBoundsException in a doc-values sort); default IndexWriterConfig, codec, directory and searcher otherwise, ordinary scale (a few documents); Lucene's own callers (kNN rewrite, RescoreTopNQuery) and TopDocs.rrf never pass repeats.
- Summary
- You build a query with the public DocAndScoreQuery.createDocAndScoreQuery from a TopDocs that lists some document twice, for example the concatenated, score-sorted results of two KnnFloatVectorQuery searches that both found it, and you expect what the javadoc promises, a query that 'matches exactly the documents in topK', so each document is counted and returned once. Instead every entry is kept: for 4 documents found through both fields IndexSearcher#count and totalHits are 8, each hit comes back twice and the leaf iterator returns 1 1 2 2 3 3 4 4. When the repeated document is the first document of a segment (docs [64, 64, 65] with segment 1 starting at 64), Arrays.binarySearch in findSegmentStarts can land on the later copy, so segment 0's iterator returns doc 64, which equals its maxDoc: a plain search then throws ArrayIndexOutOfBoundsException from the live docs when segment 0 has deletions, a doc-values sort throws or sorts the document by another document's value, and when segment 0 has no deletions the document is returned even if it is deleted or excluded by a MUST_NOT clause.
- Introduced
- c857eeebe7ea60d7952c77784d84dea7ed8755de (apache/lucene#16686 'Make DocAndScoreQuery public', mccullocht; main only, milestone 11.0.0): it made the class and both factory overloads public and added the 'matches exactly the documents in topK' javadoc, with no uniqueness precondition or check and no change to the factory body [exec: a public-API probe outside the package fails on main and does not compile with the parent's DocAndScoreQuery.java (c857eeebe7e^ = 2a38fffef52) shadowed into the main jars, while the in-package test still fails 4 of 4 there]. The mechanism itself (copy every entry after the doc-id sort; Arrays.binarySearch at each docBase in findSegmentStarts) dates from 624560a3d70 (LUCENE-9614, msokolov, 2021-08-13, first released in 9.0.0) [read: git blame of DocAndScoreQuery.java:126-161 on main] and was harmless while only Lucene's duplicate-free internal callers could reach it. (2026-09-29 (author date of c857eeebe7e, 20:07:30Z; merged 20:07:31Z); latent mechanism 2021-08-13 (624560a3d70))
- First affected version
- unreleased (main / 11.0.0-SNAPSHOT only: CHANGES lists GITHUB#16686 under 11.0.0 API Changes and branch_11x f85446cb1af carries the identical file [read]; branch_10_6, branch_10x and every release up to 10.6.0 keep the class and factory package-private [exec: compile errors on 10.6.0, 10.5.2 and 9.12.3; read: branch_10x])
- Affected versions
- main from c857eeebe7e (2026-09-29) to at least the upstream head 645d4fe14a20 (2026-10-28; no later commit touches DocAndScoreQuery.java) [exec on 645d4fe14a20 2026-10-29: finder 4/4, the independent reproduction 4/5, public probe 2/2, -ea and -da; exec on a9779ef3c193: the finder's JUnit fails 4 of 4 with -ea and -da (seed DEADBEEF); the independent reproduction's own JUnit fails 4 of 5 with -ea and -da, its control passes, and 40 of 50 over 10 random iterations (every non-control test); separate runs and the intended-behaviour check re-ran the finder's JUnit (4 of 4, -ea and -da); the adjudication re-ran the independent reproduction's (-da, seed 5EED385) and the finder's (-ea, seed 5EED386); the registration check re-ran the finder's (-da, seed 5EED3851, 4 of 4)]; branch_11x f85446cb1af [read: identical DocAndScoreQuery.java blob, re-checked 2026-10-29]. Not affected through the public API: 9.0.0 to 10.6.0 (branch_10_6 4ae946e5a9b) and branch_10x (package-private class) [exec: 9.12.3, 10.5.2 and 10.6.0 compile errors; read: branch_10x]. In 9.9.0 to 10.6.0 the same factory code is reachable only through a subclass that overrides the protected @lucene.experimental KnnFloatVectorQuery#mergeLeafResults to add a repeated entry [exec: 9.9.0, 9.12.3, 10.5.2 and 10.6.0 fail 2 of 2; 9.8.0 has no such hook]; that route is judged contrived. All runs on Linux aarch64 with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only): three scripted prior-report searches (each 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list (dev@, java-user@, issues@, commits@) and 4 JIRA-archive queries; 50, 1,539 and 1,033 distinct hits, 0 high), the finder's run (45 queries, 86 hits, 0 high) and the intended-behaviour check's intended-behaviour run (42 queries, 154 hits, 0 high or medium), 31 manual GitHub GraphQL searches (apache/lucene, Elasticsearch, OpenSearch and its k-NN plugin, Solr), code search, the comment and review threads of 31 issues and PRs (Lucene and downstream), the changed-file lists of the open apache/lucene PRs and of all PRs created since 2026-10-25, four mailing-list threads and web searches. Nearest items, not reports of this bug: #16686 (the introducing change; its discussion covers NoMatchExplainer visibility and the backport only), #12152 (count() built on 'monotonically increasing' segment starts), the #15950 review exchange in which a maintainer notes that 'Lucene hits would never duplicate docid', elastic/elasticsearch#92118 (a downstream project de-duplicates multi-kNN results before building its own analogous query; review remark that handling them in the query 'would then require some change within KnnScoreDocQuery to handle duplicate docs'), the downstream OpenSearch k-NN copy of the factory (same pattern, no report), #13470 (TopDocs.rrf, which de-duplicates), and open PR #16847 (long doc ids), which rewrites the same lines without changing duplicate handling. Not fixed: no commit after c857eeebe7e touches DocAndScoreQuery.java. Refresh 2026-10-28 (GitHub search and REST API, read-only): no issue or PR mentioning DocAndScoreQuery updated since 2026-10-26, 'createDocAndScoreQuery' finds only #14009, open items mentioning DocAndScoreQuery are #16267 and #12819 (unrelated), none of the 20 PRs created since 2026-10-26 touches DocAndScoreQuery.java (file lists checked), and the last commit on the file is still c857eeebe7e on upstream main head 645d4fe14a20.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails through gradle in a scratch worktree with assertions on and off, and a public-API probe outside the package shows the leak, the count of 3 and theMUST_NOTescape. Both fixes were validated there (the repro, the 13 core test classes picked by the kNN, patience and rescore test filters, the join kNN tests, and the format, ECJ and forbidden-apis checks). The hunt, the verifiers and the adjudication ran maina9779ef3c193;DocAndScoreQuery.javais the same blob there, on645d4fe14a20, on upstream main2f424fd428da(2026-10-30) and onbranch_11x. 10.6.0 has no public factory and nocreateDocAndScoreQuery(IndexReader, TopDocs, int): the test does not compile there.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/DocAndScoreQuery.java:103-120 (public factory javadoc), :121-142 (factory body: assert len > 0, sort by doc id, copy every entry), :145-161 (findSegmentStarts, Arrays.binarySearch at :154), :192-195 (Weight#count); lucene/CHANGES.txt:138 (GITHUB#16686 under 11.0.0) [read by the registration check]
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/DocAndScoreQuery.java:121-143, :145-161, :192-195, :217-224, :254-262 (main 645d4fe14a20)java.util.Arrays#binarySearch(int[], int, int, int) javadoc (OpenJDK 25)
- Who is affected
lucene/core/src/java/org/apache/lucene/search/AbstractKnnVectorQuery.java:156; search/RescoreTopNQuery.java:90; search/TopDocs.java:372 (main 645d4fe14a20)https://github.com/apache/lucene/pull/16686 (commit message: 'useful if you are writing your own KNN query classes')https://github.com/elastic/elasticsearch/pull/92118
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/DocAndScoreQuery.java:52, :103-120, :170-171; search/IndexSearcher.java:491; search/Weight.java:182; search/DocIdSetIterator.java:23, :127; search/TopDocs.java:26 (main 645d4fe14a20)lucene/test-framework/src/java/org/apache/lucene/tests/search/AssertingScorer.java:171; AssertingLeafCollector.java:128-130lucene/core/src/java/org/apache/lucene/search/TermInSetQuery.java:153; search/PointInSetQuery.java:118; util/RoaringDocIdSet.java:118
- Prior reports
https://github.com/apache/lucene/pull/16686, https://github.com/apache/lucene/pull/15950, https://github.com/elastic/elasticsearch/pull/92118, https://github.com/apache/lucene/pull/16847
- History
lucene/CHANGES.txt:138 (main 645d4fe14a20)
- TestDocAndScoreQueryRepeatedDoc.java (one test class):
repro/LFV-955/src/org/apache/lucene/search/TestDocAndScoreQueryRepeatedDoc.java(51 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and executed probes on the same three-document layout.
assets/LFV-955/bug.png(540 KB)