The synonym factories read the synonyms file themselves. The word-list factories (stop words and the like) read their files through a shared line loader that drops a leading byte order mark; the synonym path keeps it on line 1.
- A byte order mark (BOM) is the three bytes
EF BB BFthat some editors write at the start of a UTF-8 file. Java decodes them into one invisible character, U+FEFF (ZERO WIDTH NO-BREAK SPACE). It is not whitespace, sotrim()keeps it. - A synonyms file in the default Solr format has one rule per line:
couch, sofamakes two words equivalent,tv => televisionmaps one to the other, and lines starting with#are comments.
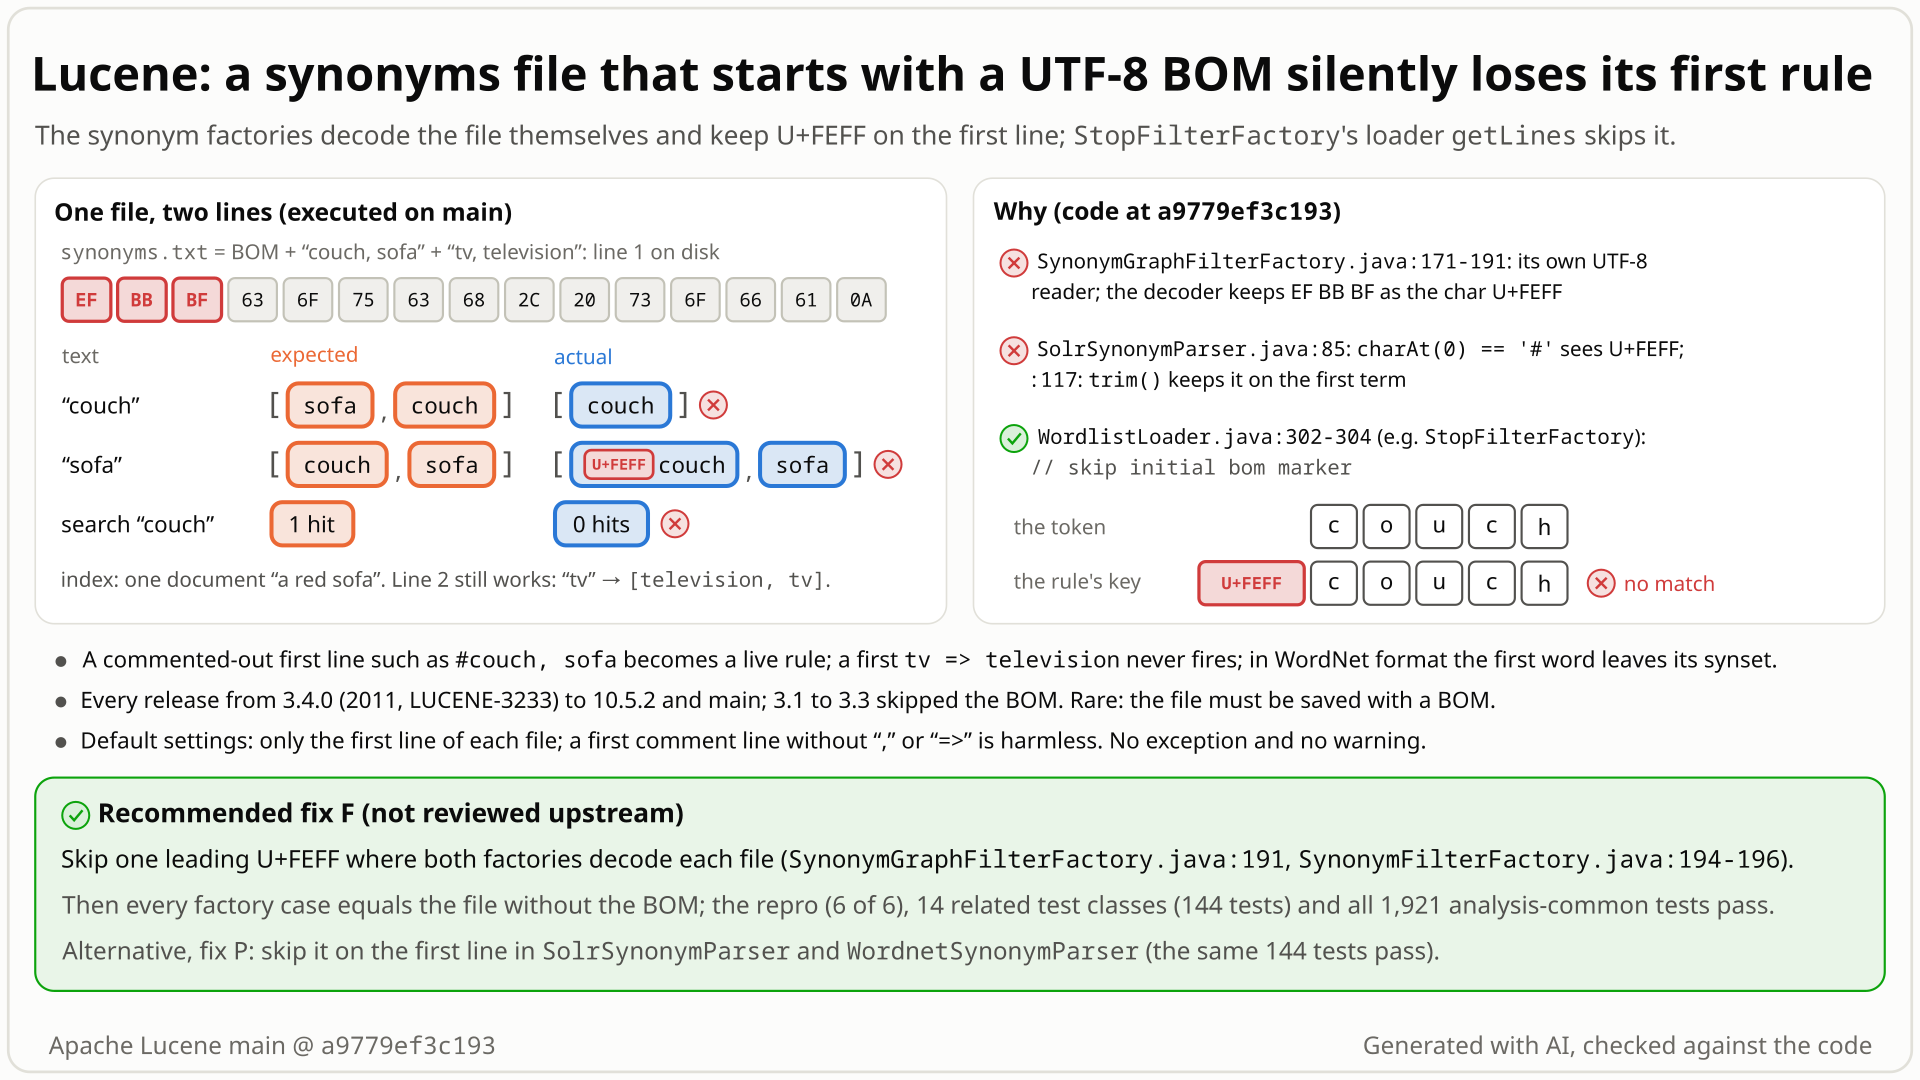
EF BB BF then couch, sofa and tv, television: the decoder keeps the mark as U+FEFF on line 1, so the rule's key is \uFEFFcouch, the token couch matches nothing, and a search for couch over a red sofa finds 0 hits. Select the still to open it at full size. Generated with AI, checked against the code.- You save
synonyms.txtwith two rules,couch, sofaandtv, television, in an editor that writes UTF-8 with a byte order mark: 30 bytes instead of 27, startingEF BB BF, which Java decodes to the invisible character U+FEFF. - You load it with
SynonymGraphFilterFactoryand its defaults, and expect what the same file without the mark gives:couchexpands to[sofa, couch], and a search forcouchfinds the one documenta red sofa. - You get
[couch]: the first rule is stored as\uFEFFcouch, sofa, so the tokencouchnever matches it, and the search finds 0 of 1 documents. Line 2 still works (tvgives[television, tv]). No error, and printed tokens look right because U+FEFF is invisible. - A commented-out first line is hit too:
#couch, sofanow starts with U+FEFF, not#, so it becomes a live rule andsofaexpands to\uFEFF#couch. The Apache license header that opens Lucene's own test synonyms files has a comma, so with a mark it becomes a rule as well. - Why: the synonym factories decode the file with their own reader. The word-list factories (stop words, keep words, stemmer overrides, char-filter mappings, type files) read through
WordlistLoader.getLines, which drops a leading mark ("skip initial bom marker"), and so did the synonym factory until its 3.4.0 rewrite.
Anyone who loads a synonyms file saved as UTF-8 with a byte order mark through SynonymGraphFilterFactory or the deprecated SynonymFilterFactory; the default settings are affected. One rule per file goes wrong, silently. The synonym filter is opt-in (no stock analyzer uses it); indexes keep wrong expansions until reindexed.
Mechanism, terms and numbers796 words
SynonymGraphFilterFactory and the deprecated SynonymFilterFactory decode the synonyms file with their own strict UTF-8 reader and pass it to SolrSynonymParser (the default format) or WordnetSynonymParser. Some editors save UTF-8 with a byte order mark, the bytes EF BB BF, which Java decodes to the invisible character U+FEFF. Nothing on the synonym path drops it: the Solr parser treats a line as a comment only if its first character is #, and trim() and the default whitespace rule tokenizer keep U+FEFF, so it stays glued to the first term of the first line. With couch, sofa on line 1, couch gets no synonym and sofa gains the invisible synonym \uFEFFcouch; a commented-out first line #couch, sofa becomes a live rule; in WordNet format the first word leaves its synset. With the default settings only the first line of each file is affected, and no error is raised. The word-list factories (stop words, keep words, stemmer overrides, char-filter mappings, type files) read through WordlistLoader.getLines, which skips a leading mark (SOLR-1865, 2010), and the synonym factory did too in 3.1 to 3.3; the 3.4.0 rewrite (LUCENE-3233) gave it its own reader without the skip. Every release from 3.4.0 to 10.5.2, 10.6.0 (branch_10_6) and main is affected (10 releases executed, the rest inferred from the unchanged code). Skipping one leading U+FEFF where the factories decode each file fixes it.
- Synonyms file: the
synonymsparameter ofSynonymGraphFilterFactoryand the deprecatedSynonymFilterFactory(one file or a comma-separated list), parsed bySolrSynonymParser(format=solr, the default) orWordnetSynonymParser(format=wordnet). - Byte order mark (BOM): the bytes
EF BB BFat the start of a UTF-8 file. Java's UTF-8 decoder keeps them as the character U+FEFF;Character.isWhitespace(0xFEFF)is false and"\uFEFF".trim()has length 1.
SynonymGraphFilterFactory.loadSynonyms(SynonymGraphFilterFactory.java:168-194) builds a strict UTF-8 decoder and, for each file, callsparser.parse(new InputStreamReader(loader.openResource(file), decoder))(:191). The deprecatedSynonymFilterFactory.loadSynonyms(SynonymFilterFactory.java:171-199) does the same (:194-196). The decoded first line of the example is\uFEFFcouch, sofa, 12 characters.SolrSynonymParser.addInternalskips a line only if it is empty or itscharAt(0)is#(SolrSynonymParser.java:85; javadoc:33: "Blank lines and lines starting with '#' are comments"). It splits the line on=>and,, and each piece goes throughunescape(...).trim()and the rule analyzer (:96-118), by default aWhitespaceTokenizer(SynonymGraphFilterFactory.java:146), which does not split on U+FEFF. So the first term is\uFEFFcouch, and a#first line is parsed as a rule; it only has a visible effect when it contains,or=>.WordnetSynonymParser.parsereads the synset id from fixed columns,line.substring(2, 11)(WordnetSynonymParser.java:53-54): with the mark, line 1 gives(10000000instead of100000001, so the first word starts a synset of its own.- The factories that read word lists and line files through
AbstractAnalysisFactory.getLines/getWordSetgo throughWordlistLoader.getLines, which drops a leading U+FEFF before the#test:// skip initial bom marker(WordlistLoader.java:302-304). Stop words, keep words and common-grams words in the defaultwordsetformat, stemmer overrides, char-filter mappings and type lists get the skip. Not every resource loader does: thesnowballwords format (AbstractWordsFileFilterFactory.java:89-90->AbstractAnalysisFactory.getSnowballWordSet, its own reader), ICU tokenizer rule files and the Japanese and Korean user dictionaries keep the mark too (separate reports).
| first line of the file | text | without the mark | with the mark |
|---|---|---|---|
couch, sofa | couch | [sofa, couch] | [couch]; the map key is \uFEFFcouch |
couch, sofa | sofa | [couch, sofa] | [\uFEFFcouch, sofa] |
couch, sofa; search couch over a red sofa | Synonym(f:couch f:sofa), 1 hit | f:couch, 0 hits | |
tv => television | tv | [television] | [tv]: the mapping never fires |
#couch, sofa (commented out) | sofa | [sofa] | [\uFEFF#couch, sofa]: the comment is a rule |
the Apache license header, # The ASF licenses ... Apache License, Version 2.0 | Version 2.0 | [Version, 2.0] | the 12 header tokens from \uFEFF# to License added as a synonym |
# my synonyms (no , or =>) | couch | [sofa, couch] (the diagram check's probe) | [sofa, couch]: harmless |
WordNet: couch and sofa in synset 100000001 | couch | [sofa, couch] | [couch] |
deprecated SynonymFilterFactory, couch, sofa | couch | [couch, sofa] | [couch] |
Line 2 and later lines are unaffected; with a comma-separated list, each file that starts with a mark loses its own first line. With the non-default tokenizerFactory=org.apache.lucene.analysis.standard.StandardTokenizerFactory, which drops a leading U+FEFF, the first rule survives, but a commented-out first rule still becomes active, and a mark followed by a blank first line fails to load (term: \uFEFF was completely eliminated by analyzer) while the same file without the mark loads.
Exposure and likelihood334 words
- Who is exposed. Applications that configure
SynonymGraphFilterFactoryor the deprecatedSynonymFilterFactorywith a synonyms file: directly, throughCustomAnalyzer, or through a search server's schema (the factory javadoc example is a schema snippet). The factories' defaults are affected:format=solr, the whitespace rule tokenizer,expand=true. The component is opt-in: no stock Lucene analyzer uses it;SynonymGraphFilterFactoryand both parsers are@lucene.experimental, andSynonymFilterFactoryis deprecated. - What it takes. A synonyms file saved as UTF-8 with a byte order mark, which the 2010 CHANGES entry for the shared loader's skip describes as "often created by editors such as Windows Notepad", whose first line is a rule, or a
#line with,or=>. A re-saved copy of a file that starts with the Apache license header qualifies: that header line has a comma. - What happens. The first rule silently stops matching its first term (missed expansions: the
couchquery finds 0 of 1 documents), and its other terms gain an invisible synonym that matches nothing; a first explicit mapping never fires; a commented-out first rule becomes active and adds expansions the user disabled; in WordNet format the first word loses its synonyms. With the default settings, no error or warning (with the non-defaultStandardTokenizerFactoryas the rule tokenizer, a mark before a blank first line makes loading fail). - Scale. Deterministic and independent of index size: one line per file. If the filter runs at index time, terms indexed with the wrong rules stay until reindexing.
- Versions. Every release from 3.4.0 to 10.5.2, 10.6.0 (branch_10_6) and main (10 releases executed, the rest inferred from the code).
- How likely. Rare: a file saved with a mark is needed, only its first line goes wrong, and no public report was found in 15 years. The WordNet half is the weaker one (WordNet prolog files are machine-generated), so the Solr-format symptoms lead.
- Workarounds. Save the file without a mark, or start it with a blank line or a comment line without
,or=>.
The test shows that SynonymGraphFilterFactory with a synonyms file that starts with a UTF-8 byte order mark ("\uFEFFfoo, bar\n") silently drops the first rule.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.synonym;

import java.io.StringReader;
import java.util.HashMap;
import java.util.Map;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;
import org.apache.lucene.tests.util.StringMockResourceLoader;

public class TestSynonymGraphFilterFactoryUtf8Bom extends BaseTokenStreamTestCase {

  public void testBomBeforeFirstRule() throws Exception {
    SynonymGraphFilterFactory factory =
        new SynonymGraphFilterFactory(new HashMap<>(Map.of("synonyms", "synonyms.txt")));
    factory.inform(new StringMockResourceLoader("\uFEFFfoo, bar\n"));
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("foo"));
    // expected: foo expands to [bar, foo], as without the BOM; actual: [foo]
    assertTokenStreamContents(factory.create(tokenizer), new String[] {"bar", "foo"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-956/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.synonym.TestSynonymGraphFilterFactoryUtf8Bom
- Expected vs actual
- Expected "foo" to expand to [bar, foo], as without the mark; actual: [foo] (
term 0 expected:<[bar]> but was:<[foo]>), with -ea and -da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<[bar]> but was:<[foo]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.synonym.TestSynonymGraphFilterFactoryUtf8Bom.testBomBeforeFirstRule(TestSynonymGraphFilterFactoryUtf8Bom.java:36)- The format says "lines starting with '#' are comments", yet a commented-out first rule becomes live.
- Lucene's shared line loader has dropped a leading mark on purpose since 2010; the synonym factory did too until its 3.4.0 rewrite removed it without a word.
- The equivalent hunspell change was filed under Bug fixes; nothing says synonyms files must be BOM-free.
The full argument269 words
- The file's own comment rule. "Blank lines and lines starting with '#' are comments" (
SolrSynonymParser.java:33). A user who writes#couch, sofaon line 1 sees a line that starts with#; with a mark, Lucene makes it a rule. - Lucene's shared line loader drops the mark on purpose. SOLR-1865 (2010) added the skip with the CHANGES entry "SolrResourceLoader.getLines ignores Byte Order Markers (BOMs) at the beginning of input files, these are often created by editors such as Windows Notepad"; LUCENE-4257 moved it into
WordlistLoader.getLines(WordlistLoader.java:302-304). Every factory that reads its file throughgetLinesorgetWordSetgets it: the same resource loader and the same bytes give a different result for synonyms. - The synonym factory had it and lost it silently. In 3.1 to 3.3,
SynonymFilterFactoryread its rules withSolrResourceLoader.getLines, skip included. LUCENE-3233 (3.4.0) replaced that with a plainInputStreamReader. Its issue (41 comments), its CHANGES entries ("Improved memory usage, build time, and performance of SynonymFilterFactory"; "Added SynonymFilter ... with parsers for wordnet and solr formats") and the upgrade notes say nothing about BOM or encoding handling. Executed: 3.3.0 clean, 3.4.0 affected, 3.4.0 withluceneMatchVersion3.3 (the old loader) clean. - Hunspell's equivalent was a bug fix. "LUCENE-5505: HunspellStemFilter ignores BOM markers in dictionaries" is listed under "Bug fixes" (
lucene/CHANGES.txt:12543,:12554);Dictionary.java:351-352: "ignore any BOM marker on first line". - Valid input, no documented exclusion. A file with a mark is valid UTF-8, and the factories' strict decoder accepts it. No javadoc, test, CHANGES or MIGRATE entry says synonyms files must be BOM-free, and no synonym test uses a mark.
The devil's-advocate check274 words
The checkers built the strongest case for "intended": (a) SynonymMap.Parser.parse takes a Reader, i.e. characters, and the Solr grammar exempts only lines whose first character is #; U+FEFF is a real character (ZERO WIDTH NO-BREAK SPACE). (b) SynonymGraphFilterFactory and the parsers are @lucene.experimental. (c) Committers have said Reader-level parsers do not deal with encodings: "If you use Lucene directly, the stopword file parser does not care about encodings at all, it simply takes a java.io.Reader" (uschindler, SOLR-1860, 2010), and "if you have a byte order mark in your character input (reader) then your conversion from bytes is screwed up somewhere before" (dweiss, LUCENE-7785, 2017, about a char-filter mapping: an analogy). (d) In the 2010 user-list thread behind the skip, rmuir answered "No." to whether a file with a mark is a bug, then proposed skipping it "to be more user-friendly"; SOLR-1865 is typed Improvement. (e) Nobody reported it in 15 years.
Why we think it fails: (a) to (c) describe the Reader-level parser; users configure the factory with a file name, and the factory itself turns the bytes into characters, so by the reasoning of (c) the factory is where the mark should go (the recommended fix). (d) was about whether to handle marks at all; the project then did, in the very loader the synonym factory used until 3.4.0, and the rewrite dropped it without a word. (e) shows rarity, not intent. The cross-model reviews rated the works-as-designed case moderate (the intended-lens review: "not ultimately persuasive"; the refute-lens review: "not conclusive"), and the devil's advocate rated it weak to moderate. The literal reading (a) stays arguable: expect "improvement, not bug".
Recommended F. Skip the mark where the factories decode each file (SynonymGraphFilterFactory and SynonymFilterFactory)
Skip one leading U+FEFF where both factories decode each synonyms file (loadSynonyms), as the shared line loader does: read the first character through a PushbackReader and push it back unless it is U+FEFF. Validated: the repro, an on-disk test, all upstream synonym suites and the whole analysis-common module pass, and so does the module's format and lint check.
     for (String file : files) {
       decoder.reset();
-      parser.parse(new InputStreamReader(loader.openResource(file), decoder));
+      try (PushbackReader reader =
+          new PushbackReader(new InputStreamReader(loader.openResource(file), decoder), 1)) {
+        // skip initial bom marker, as WordlistLoader.getLines does for other resource files
+        int first = reader.read();
+        if (first != -1 && first != '\uFEFF') {
+          reader.unread(first);
+        }
+        parser.parse(reader);
+      }
     }
All options and trade-offs3 options · 846 words
Options F and P were each applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; the worktree was removed afterwards. Option C was not run. Pick one of F and P: together they would strip two leading U+FEFF characters.
F. Skip the mark where the factories decode each file (SynonymGraphFilterFactory and SynonymFilterFactory) (validated by the checks) (recommended)
In both loadSynonyms methods (SynonymGraphFilterFactory.java:191, SynonymFilterFactory.java:194-196), wrap the decoding reader in a PushbackReader of size 1, read one character and push it back unless it is U+FEFF, then parse as before, inside a try-with-resources. +19/-4 lines over the two files (one import each; the deprecated factory drops its unused java.io.Reader import).
What it changes. Only the factory path: one U+FEFF at the very start of each synonyms file is dropped before the parser sees it, the case getLines covers for the word-list factories. It covers every parser the factory loads, including a custom SynonymMap.Parser named in format. Files without a mark are read unchanged. SynonymGraphFilterFactory now also closes each reader itself, as the deprecated factory already did; the parser's own close() makes the second close a no-op. A decoding error in the first character is now raised by the factory's read() rather than inside parse: the same MalformedInputException, an IOException, either way (read, not run).
     for (String file : files) {
       decoder.reset();
-      parser.parse(new InputStreamReader(loader.openResource(file), decoder));
+      try (PushbackReader reader =
+          new PushbackReader(new InputStreamReader(loader.openResource(file), decoder), 1)) {
+        // skip initial bom marker, as WordlistLoader.getLines does for other resource files
+        int first = reader.read();
+        if (first != -1 && first != '\uFEFF') {
+          reader.unread(first);
+        }
+        parser.parse(reader);
+      }
     }
Trade-offs
- A direct caller of
SolrSynonymParser.parse(Reader)orWordnetSynonymParser.parse(Reader)that builds its own Reader from a marked file still gets the glued term. That matches the committers' view that Reader-level parsers are encoding-agnostic, but such callers exist downstream (engines that read synonyms files with their own UTF-8 reader; checked by reading only) and would need their own skip. - Like
getLines, it cannot tell a mark from a file whose first character is meant as a ZERO WIDTH NO-BREAK SPACE (not a realistic synonym). - Open PR #13054 (synonym map off-heap) rewraps
loadSynonyms, so the two may conflict. - Indexes built with the wrong rules keep their terms until reindexed. No CHANGES entry is drafted.
What the checks validated
- Gradle in a scratch worktree of main
a9779ef3c193, seed DEADBEEF, assertions on and off: the 6-test repro passes (stock: 5 of 6 fail), the independent on-disk test passes 6 of 6 (stock: 3 of 6 fail), and all upstream synonym suites plusTestConditionalTokenFilterpass: 14 classes, 144 tests, 0 failures, each way. - All of
:lucene:analysis:common:testwith assertions on: 341 classes, 1,921 tests (the two BOM test classes included), 18 skipped, 0 failures. :lucene:analysis:common:check -x testpasses with the repro added (google-java-format, ecjLint, forbiddenApis).
P. Skip the mark on the first line in the two parsers (SolrSynonymParser and WordnetSynonymParser) (validated by the checks)
In SolrSynonymParser.addInternal (before the comment test, SolrSynonymParser.java:85) and WordnetSynonymParser.parse (before substring(2, 11), WordnetSynonymParser.java:54), drop a leading U+FEFF from the first line of each parse() call, the idiom of WordlistLoader.getLines. +6 lines per parser. This is the hunt's fix; the finder, a checker and the registration check ran it in the repro harness.
+    boolean first = true;
     while ((line = in.readLine()) != null) {
+      if (first) {
+        first = false;
+        // skip initial bom marker, as WordlistLoader.getLines does
+        if (line.length() > 0 && line.charAt(0) == '\uFEFF') line = line.substring(1);
+      }
       if (line.length() == 0 || line.charAt(0) == '#') {
Trade-offs
Also covers downstream callers that build their own Reader and call the parsers directly. But it changes @lucene.experimental Reader-level parsers that committers have called encoding-agnostic, a Reader whose text really starts with U+FEFF loses it, and a custom SynonymMap.Parser named in format is not covered.
What the checks validated
- The same gradle runs, assertions on and off: the repro, the on-disk test and the upstream synonym suites pass (14 classes, 144 tests, 0 failures, each way);
:lucene:analysis:common:check -x testpasses with the repro added. The whole module was not re-run for this option. - Earlier, shadowed into the repro harness by the finder and the checkers: the repro 6 of 6, 94 upstream synonym tests, an independent on-disk test 6 of 6, a root-cause variant 8 of 8; the bounded-exhaustive check drops to 0 mismatches.
A shared helper (for example in AbstractAnalysisFactory, next to getLines) that opens a resource as strict UTF-8 and drops one leading U+FEFF, used wherever a factory decodes a resource itself.
Trade-offs
Would also fix the same pattern in other loaders (snowball-format words files and ICU tokenizer rule files are separate confirmed reports, and the Japanese and Korean user dictionaries a sibling one), so it suits a single "BOM in resource files" issue; it touches several modules and needs its own tests. Not drafted.
Search servers that load synonyms files through these factories inherit it whenever an operator saves the file in an editor that writes a byte order mark; engines that pass their own UTF-8 reader to the parsers see the same (by reading their code, not run).
A bounded-exhaustive metamorphic check of the real factories: every synonyms file of 1 to 3 lines over a small alphabet must analyze the same with and without a leading byte order mark. Solr format: 456 of 620 checks differed per factory; WordNet: 112 of 336; three loaders that use the shared line loader: 0.
The method in full221 words
- First signal. On 2026-10-27 a probe in the hunt's unit on factory resource-file formats (the unit that found the snowball words-file case) printed
<BOM>foo,bar : foo -> [foo]for the synonym factory and recorded it as a lead for another unit; a planning probe re-ran it (8 checks, 6 failing). - Method (semi-formal): bounded-exhaustive metamorphic check on the stock main jars, in the hunt's unit on synonym and user-dictionary loaders. Law: loading F and loading BOM+F give the same analysis of every probe text (terms, position increments, position lengths) or the same exception class. Inputs: every file of 1 to 3 lines over a 5-line Solr alphabet (equivalence, explicit mapping, comment with a comma, blank, multi-word) and a 4-line WordNet alphabet, with LF and CRLF line ends and
expandtrue and false, through both synonym factories, plus three controls that read through the shared line loader (stop filter, stemmer override, mapping char filter). - Signal. Solr format: 456 of 620 checks mismatch for each factory (372 with a term glued to U+FEFF, 84 where a first mapping never fires); WordNet: 112 of 336 for each factory; the three controls: 0. With the parser fix shadowed, every family: 0.
- The finder then traced it to the factories' own reader, checked the 3.4.0 history and wrote the public-API JUnit; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-28: GitHub issues, PRs and commits, JIRA, the Lucene and Solr lists, downstream trackers, the web and the changed files of all 414 open PRs). Closest: SOLR-1865 (2010), which made the shared line loader skip the mark.
Searches6 searches
A 2018 issue in a downstream plugin repository ends with the reporter saying that saving synonyms.txt as "UTF-8 without BOM" solved their problem, but the error they reported (an analyze-request error) does not depend on file content, and no symptom of this bug and no Lucene code is named; it was judged not a report and is listed for transparency. Tracking issue #16937 and the dev@ thread do not mention it.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (three new runs, plus the finder's and a checker's) | 2026-10-28 | a loader, a symptom and a WordNet/regression angle: 937, 737 and 156 distinct hits over GitHub issues, PRs and commits, downstream repositories, the Lucene and Solr lists and the JIRA archive; earlier runs 191 and 52 hits; every hit scanned for BOM, byte order mark and FEFF | no report |
| GitHub (manual) | 2026-10-28 | about 50 searches over apache/lucene (including items created since 2026-10-20 and 2026-10-26), apache/solr, apache/lucene-solr, downstream search-engine repositories and all of GitHub; the changed-file lists of all 414 open apache/lucene PRs; a refresh | no report; only open PR #13054 (synonym map off-heap) touches loadSynonyms, with no BOM handling |
| JIRA (LUCENE, SOLR) | 2026-10-28 | 10 queries; SOLR-1865, SOLR-1860 and SOLR-12731 read in full | only SOLR-1865 (the shared loader, stop-word lists) and SOLR-1860 (stop-word lists) |
| Mailing lists | 2026-10-28 | 35 queries over 7 Lucene and Solr lists; threads read | only the 2010 solr-user thread behind SOLR-1865 |
| Web and Stack Overflow | 2026-10-28 | 26 web queries; 7 "synonyms not working" questions read | no report; one downstream plugin issue (2018) with BOM folklore, not this bug |
| Closest items (read) | 2026-10-28 | full threads | SOLR-1865 (precedent), #4306 / LUCENE-3233 (the 3.4.0 rewrite; 41 comments, no BOM discussion), #6568 / LUCENE-5505 (hunspell ignores BOMs, a bug fix), SOLR-1860, #13054 (open PR) |
A regression in 3.4.0: LUCENE-3233 (015ecfa0a02, 2011-07-11) gave the synonym factory its own reader and bypassed the BOM-skipping line loader it used in 3.1 to 3.3. Executed: 3.3.0 clean, every tested release from 3.4.0 to 10.6.0 and main affected. Never fixed.
Versions tested8 rows
Introduced by LUCENE-3233 "HuperDuperSynonymsFilter" (#4306), by rmuir: trunk 015ecfa0a02 and the branch_3x backport a52015db05f, both 2011-07-11 ("LUCENE-3233: improve ram/perf of SynonymFilter, add wordnet parsing, nuke contrib/wordnet"), no PR. It added FSTSynonymFilterFactory, which passes new InputStreamReader(loader.openResource(file), decoder) straight to the new SolrSynonymParser and WordnetSynonymParser, and made SynonymFilterFactory use it for luceneMatchVersion 3.4 and later. Before, SynonymFilterFactory.loadRules read the rules with SolrResourceLoader.getLines, which had skipped a leading U+FEFF since SOLR-1865 (2010-05-08).
Reach over time. 3.4.0 to 3.6.2: Solr's factory with luceneMatchVersion 3.4 or later (the value the 3.4.0 example config ships); a lower value kept the old loader until 5.0.0 removed it. The factories moved into Lucene's own jars in 4.0.0-beta (LUCENE-4044); SynonymGraphFilterFactory (same loader) exists since 6.4.0. The WordNet format came with the introducing commit, so it was never unaffected.
Never fixed. No commit on any branch adds BOM handling to the synonym code. The reader line was edited (LUCENE-5219 turned parser.add into parser.parse, LUCENE-5945 restructured the file-list loop), but through those and LUCENE-4095 and LUCENE-6664 the factories kept passing an unmodified InputStreamReader to the parser. Upstream main 645d4fe14a20 (2026-10-28) has no later change to the synonym package or WordlistLoader.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the JUnit fails 5 of 6 (assertions on and off); the on-disk tests 3 of 6 and 6 of 8 (assertions on and off) |
branch_10_6 4ae946e5a9b9 | affected | the JUnit fails 5 of 6 (assertions on) |
| 10.5.2, 10.0.0, 9.12.3, 9.1.0 | affected | the JUnit fails 5 of 6 (assertions on); the on-disk tests on 10.5.2 and 9.12.3 too |
| 8.11.4, 6.4.0, 5.0.0, 4.0.0 | affected | main() checks through the public factories: every BOM file differs from its twin (both factories from 6.4.0) |
| 3.6.2, 3.4.0 | affected | main() check through the released Solr factory and resource loader: 3 of 3 differ (first rule, mapping, commented-out rule) |
3.4.0 and 4.0.0 with luceneMatchVersion 3.3 | control | the old getLines-based loader: no difference |
| 3.3.0 | not affected | the last release whose synonym factory read through getLines: no difference |
fix F on main a9779ef3c193 | not affected | the repro, the on-disk test, all upstream synonym suites (144 tests) and all 1,921 analysis-common tests pass; fix P gives the same on the suites |
An independent reproducer, reviews by a reviewer from another model family, a devil's advocate with real files on disk, an adjudication and a credibility audit all re-ran or re-read it; every executed check reproduced it. This doc re-ran it through gradle and validated two fixes.
Checks and verdicts365 words
The cross-model reviews were reading-only (they read ea57360912ed, whose synonym package and WordlistLoader equal a9779ef3c193, and could not run code); every claim they read was executed by the other checks. Everything else ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model review, intended lens | real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: root cause agrees, inputs in contract; the intended-behaviour case is moderate and "not ultimately persuasive". A separate re-run failed 5 of 6. |
| Independent reproducer | real | Own test with real files on disk through CustomAnalyzer.builder(Path): 6 of 8 fail on main (assertions on and off), 10.5.2 and 9.12.3; both controls pass; 8 of 8 pass with a root-cause shadow. |
| Cross-model review, refute lens | not real (low), procedural | The same OpenAI GPT-5.6 reviewer, reading only: "not real" because it could not run its own test; it agreed with the root cause and the inputs, and rated the intended-behaviour case moderate, "not conclusive". A separate main() with other words (red, crimson, scarlet => vermilion) found 6 of 6 cases different, assertions on and off. |
| Intended-behaviour devil's advocate | real (high) | Intended argument weak to moderate. Its on-disk test fails 3 of 6 on main, 10.5.2 and 9.12.3 and passes with the fix; it found the license-header case. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test (6 of 8 fail, assertions on) and the finder's (5 of 6, assertions off) with new seeds. |
| Credibility audit | downgrade (impact only) | An independent on-disk main() check: 6 of 8 cases differ, both controls agree; the bug stands, impact re-scored for an opt-in, experimental component. |
| Fix validation (this doc) | fixes F and P pass | Gradle in a scratch worktree of a9779ef3c193, seed DEADBEEF: stock, the repro fails 5 of 6 and the on-disk test 3 of 6 with assertions on and off; with fix F and, separately, fix P both pass, as do the upstream synonym suites (144 tests with the two BOM classes); with fix F all 1,921 analysis-common tests pass; the module check passes with the repro added, which needed two javadoc paragraphs rewrapped. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 434 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,727 words
- Registry title
- SynonymGraphFilterFactory and SynonymFilterFactory keep a UTF-8 byte order mark at the start of a synonyms file, so the file's first rule silently stops working and a commented-out first line that contains a comma becomes a live rule
- Area
- analysis-common / synonym file loading (SynonymGraphFilterFactory and the deprecated SynonymFilterFactory loadSynonyms -> SolrSynonymParser, WordnetSynonymParser)
- Priority
- Low, rank 499: This is the same kept-BOM class as LFV-718 and LFV-719, but the synonym factories are the most widely used of the affected file loaders and the first rule silently stops working, so it leads the BOM rows right after LFV-857.
- Impact class
- silent wrong results
- Impact note
- Every user of SynonymGraphFilterFactory or the deprecated SynonymFilterFactory whose synonyms file was saved as UTF-8 with a byte order mark, in every release since 3.4.0 and with the factory's default settings (solr format, whitespace rule tokenizer): only the first line of each such file is affected, but there the first rule silently stops matching because its first term carries an invisible U+FEFF, a first line that starts with '#' and contains ',' or '=>' (such as the Apache license header of the example synonyms files) becomes a rule, and in WordNet format the first word leaves its synset; no error is raised, the index is not damaged and no scale is needed.
- Summary
- You configure SynonymGraphFilterFactory (or SynonymFilterFactory) with a synonyms file that an editor saved as UTF-8 with a byte order mark (bytes EF BB BF) and expect the same rules as from the file without the mark, because Lucene's shared resource-line loader skips a leading BOM for the word-list factories that read through it (WordlistLoader.getLines, 'skip initial bom marker', SOLR-1865) and the synonym factory itself skipped it until 3.4.0. Instead the factory decodes the file with its own UTF-8 reader and SolrSynonymParser keeps U+FEFF glued to the first line: with the first rule 'foo, bar' the text 'foo' is no longer expanded (and 'bar' gains the invisible synonym '\uFEFFfoo'), a first rule 'baz => qux' never fires, and a first line '#couch, sofa' is no longer a comment, so 'sofa' expands to '\uFEFF#couch'. In WordNet format the fixed-column synset id (substring(2, 11)) is shifted by one character, so the first word ends up in a synset of its own; nothing reports an error.
- Introduced
- 015ecfa0a0255f053682bb2436b2b8dec5cb8283 (LUCENE-3233 'HuperDuperSynonymsFilter', apache/lucene#4306; trunk svn r1145158, author rmuir, message 'LUCENE-3233: improve ram/perf of SynonymFilter, add wordnet parsing, nuke contrib/wordnet'; no pull request, Subversion era) with the branch_3x backport a52015db05f790613906a9858531ff16e3d78b8a (r1145178), the one released in 3.4.0. The commit added FSTSynonymFilterFactory, which passes new InputStreamReader(loader.openResource(file), decoder) straight to the new SolrSynonymParser and WordnetSynonymParser, and made SynonymFilterFactory use it for luceneMatchVersion >= 3.4; before, SynonymFilterFactory.loadRules read the rules with SolrResourceLoader.getLines, which had skipped a leading U+FEFF before the '#' comment test since SOLR-1865 (f3c25f02d587, 3.x backport 7aaf7ed9a20, 2010-05-08). So this is a regression; no issue comment (body and 41 comments read), CHANGES entry or upgrade note mentions BOM or encoding handling, so the drop looks unintended (not provable). Never fixed: git log --all -G 'FEFF|[Bb][Oo][Mm]' over the synonym paths finds no commit on any branch, and the reader line was carried unchanged through LUCENE-4095 (bc3a3dc5d47), LUCENE-5219 (9d16038391b), LUCENE-5945 (3eb66fb19ca) and LUCENE-6664 (c0467bb9291, which added SynonymGraphFilterFactory). [read: git history in the full-history clone; the boundary is executed: 3.3.0 clean, 3.4.0 BUG, 3.4.0 and 4.0.0 with luceneMatchVersion 3.3 (old getLines-based SlowSynonymFilterFactory) clean] (2011-07-11 (trunk and branch_3x; author and commit dates identical, Subversion import))
- First affected version
- 3.4.0 [exec] (Solr SynonymFilterFactory with luceneMatchVersion >= 3.4, the value the 3.4.0 example solrconfig.xml ships; the parsers ship in Lucene contrib analyzers from 3.4.0 and the Lucene-module factory exists from 4.0.0-beta, LUCENE-4044). Last unaffected release: 3.3.0 [exec]. luceneMatchVersion < 3.4 kept the BOM-safe SlowSynonymFilterFactory through 4.10.4 [exec controls on 3.4.0 and 4.0.0 pass]; 5.0.0 removed it. format=wordnet was added by the introducing commit, so for that format no unaffected release exists.
- Affected versions
- Every release from 3.4.0 to 10.6.0 (branch_10_6 head 4ae946e5a9b9) and main a9779ef3c193 [exec: main() differential checks through the public factory (BOM file vs the same file without it) on 3.4.0, 3.6.2, 4.0.0, 5.0.0, 6.4.0 and 8.11.4 (both factories from 6.4.0); the finder's JUnit fails 5 of 6 on 9.1.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 and main (-ea; main also -da); the independent reproduction's and the intended-behaviour check's own tests fail on main (-ea and -da), 10.5.2 and 9.12.3 (-ea); releases in between read]. SynonymGraphFilterFactory is affected since it was added in 6.4.0 [exec]. Not affected: 3.1-3.3, which read synonyms through getLines [3.3.0 exec]. Upstream main 645d4fe14a20 (2026-10-28) has no synonym-package or WordlistLoader commit after a9779ef3c193.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-28, read-only; the prior-report record, verdict new): three scripted prior-report searches (937, 737 and 156 distinct hits over GitHub issues, PRs and commits, downstream repositories, the Lucene and Solr lists and the JIRA archive; every stored hit scanned for BOM, byte order mark and FEFF) plus the finder's (191 hits) and the intended-behaviour check's (42 queries, 52 hits); manual GitHub searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch and all of GitHub, including items created or updated in the last 48 h; 10 JQL queries on LUCENE and SOLR (SOLR-1865, SOLR-1860 and SOLR-12731 read in full); 35 queries over the Lucene and Solr list archives; Stack Exchange; 26 web queries; the changed-file lists of all 414 open apache/lucene PRs (only #13054, synonym map off-heap, open since 2024, touches loadSynonyms, and it adds no BOM handling). No issue, PR, JIRA entry, list post or downstream report describes a BOM at the start of a synonyms file breaking its first rule. Related only: SOLR-1865 (2010, BOM skip in getLines, typed Improvement, about stopword lists; the precedent), #4306 / LUCENE-3233 (the 3.4.0 rewrite that bypassed getLines; 41 comments, no BOM discussion), #6568 / LUCENE-5505 (hunspell ignores BOMs, filed as a bug fix), SOLR-1860 (stopwords), #10073 / LUCENE-9030 and #9148 / LUCENE-8100 (other WordNet-parser issues), and a 2018 downstream plugin issue (sing1ee/elasticsearch-jieba-plugin#17) whose reporter later wrote that their problem was solved by saving synonyms.txt as 'UTF-8 without BOM', although the error they reported ('request body or source parameter is required' from _analyze) does not depend on file content and no symptom of this defect is described. Not fixed: the four synonym files are unchanged on upstream main (head 645d4fe14a20, 2026-10-28) and branch_10_6 since 2026-04-02 (author dates). Refresh 2026-10-28 (GitHub search and REST API): apache/lucene items mentioning synonym created since 2026-10-26 or updated since 2026-10-27: 0; BOM updated since 2026-10-26: 0; 'byte order mark' updated since 2026-10-20: 0; 'FEFF synonym': 0; SolrSynonymParser: the same 5 old, unrelated items; of the 20 PRs created since 2026-10-26, none lists a synonym file or WordlistLoader.java in its changed files (first page; #16911 deletes all of branch_10x); the only synonym-package commit on main since 2026-10-01 is 2eb462541b1c (#16834, author 2026-10-13, unrelated, already in a9779ef3c193); elastic/elasticsearch 'synonyms BOM', opensearch-project/OpenSearch 'synonym BOM', apache/solr 'synonyms BOM' and all-of-GitHub 'synonyms.txt "byte order mark"': 0.apache.org stores only the start of each mail, the web and Stack Exchange searches were throttled at times, and private reports are not searchable.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree (removed afterwards), seed DEADBEEF, assertions on and off: stock, the 6-test JUnit fails 5 of 6 and an independent on-disk test 3 of 6; with fix F (factories) and, separately, fix P (parsers), both pass together with all upstream synonym suites (144 tests); with fix F all of:lucene:analysis:common:testpasses and so does:lucene:analysis:common:check -x testwith the repro added. Through the repro harness: the JUnit on main (assertions on and off), branch_10_64ae946e5a9b9, 10.5.2, 10.0.0, 9.12.3 and 9.1.0; two independent on-disk tests on main, 10.5.2 and 9.12.3;main()checks through the released factories on 3.3.0, 3.4.0 (and withluceneMatchVersion3.3), 3.6.2, 4.0.0 (and with 3.3), 5.0.0, 6.4.0 and 8.11.4; a bounded-exhaustive metamorphic check on main; the diagram's probe on main, stock and with each fix. The cross-model reviews readea57360912ed, whose synonym package andWordlistLoaderequala9779ef3c193. OpenJDK 25.0.3, Linux aarch64.
- Finding record
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:167-194 (loadSynonyms: strict UTF-8 decoder, new InputStreamReader(loader.openResource(file), decoder) passed straight to parser.parse); SynonymFilterFactory.java:171-197 (same loader, try-with-resources); SolrSynonymParser.java:33 ('Blank lines and lines starting with '#' are comments'), :82-87 (addInternal: readLine, comment test on charAt(0)); WordnetSynonymParser.java:53-54 (synset id = line.substring(2, 11)); lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304 ('// skip initial bom marker' in getLines); lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/synonyms.txt line 1 (license header with a comma); re-read in the registration check; identical at ea57360912ed (git diff empty)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:146 (default WhitespaceTokenizer), :168-194 (loadSynonyms; decoder :171-175; files :188; InputStreamReader + parse :191) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymFilterFactory.java:171-199 (loadSynonyms; try-with-resources :194-196) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:33 (comment rule), :82-139 (addInternal; charAt(0) test :85; split/unescape/trim/analyze :90-118) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/WordnetSynonymParser.java:53-54 (substring(2, 11)) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:297-314 (getLines), :302-304 (skip initial bom marker) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:279-302 (getWordSet, getLines) @ a9779ef3c193; getLines callers in analysis-common: StemmerOverrideFilterFactory.java:74, MappingCharFilterFactory.java:73, TypeTokenFilterFactory.java:74, WordDelimiterFilterFactory.java:140, WordDelimiterGraphFilterFactory.java:143, PatternTypingFilterFactory.java:94; snowball format: lucene/analysis/common/src/java/org/apache/lucene/analysis/en/AbstractWordsFileFilterFactory.java:87-90, AbstractAnalysisFactory.java:308-328 (own InputStreamReader :322, no BOM skip; registry LFV-718)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:43-52 (schema example), :72 (@lucene.experimental), :93-96 (defaults: ignoreCase false, format, expand true) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:57, WordnetSynonymParser.java:33 (@lucene.experimental) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymFilterFactory.java:73-78 (@deprecated, @Deprecated) @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/synonyms.txt, synonyms2.txt line 1 (license header with a comma) @ a9779ef3c193
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:33, :85 @ a9779ef3c193; lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304 @ a9779ef3c193lucene/CHANGES.txt:12543 (Bug fixes), :12554 (LUCENE-5505) @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:351-352
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:188-192, SynonymFilterFactory.java:191-197, SolrSynonymParser.java:67-87, WordnetSynonymParser.java:45-54 @ a9779ef3c193
- History
a Lucene clone: git log a9779ef3c193..645d4fe14a20 over the synonym package and WordlistLoader.java: no commit (6 commits in range; checked 2026-10-28)
- TestSynonymGraphFilterFactoryUtf8Bom.java (JUnit test):
repro/LFV-956/src/org/apache/lucene/analysis/synonym/TestSynonymGraphFilterFactoryUtf8Bom.java(38 lines)
Every number on screen comes from a probe executed for the diagram on main a9779ef3c193 (stock, with fix F and with fix P), and every code line from the code at that commit.
assets/LFV-956/bug.png(434 KB)