The class javadoc that documents the default live-docs file names a field the writer does not write, and leaves out one it does.
- When a segment has deleted documents, Lucene writes a small live-docs file,
.liv: one bit per document, set = live. Each new round of deletes writes a new file whose name carries a higher deletes generation:_0_1.liv,_0_2.liv, ... - Like the other index files of the default codec, it starts with an IndexHeader (magic, codec name, version, the 16-byte segment id and a short suffix string) and ends with a 16-byte codec footer (magic, algorithm id, CRC32 checksum).
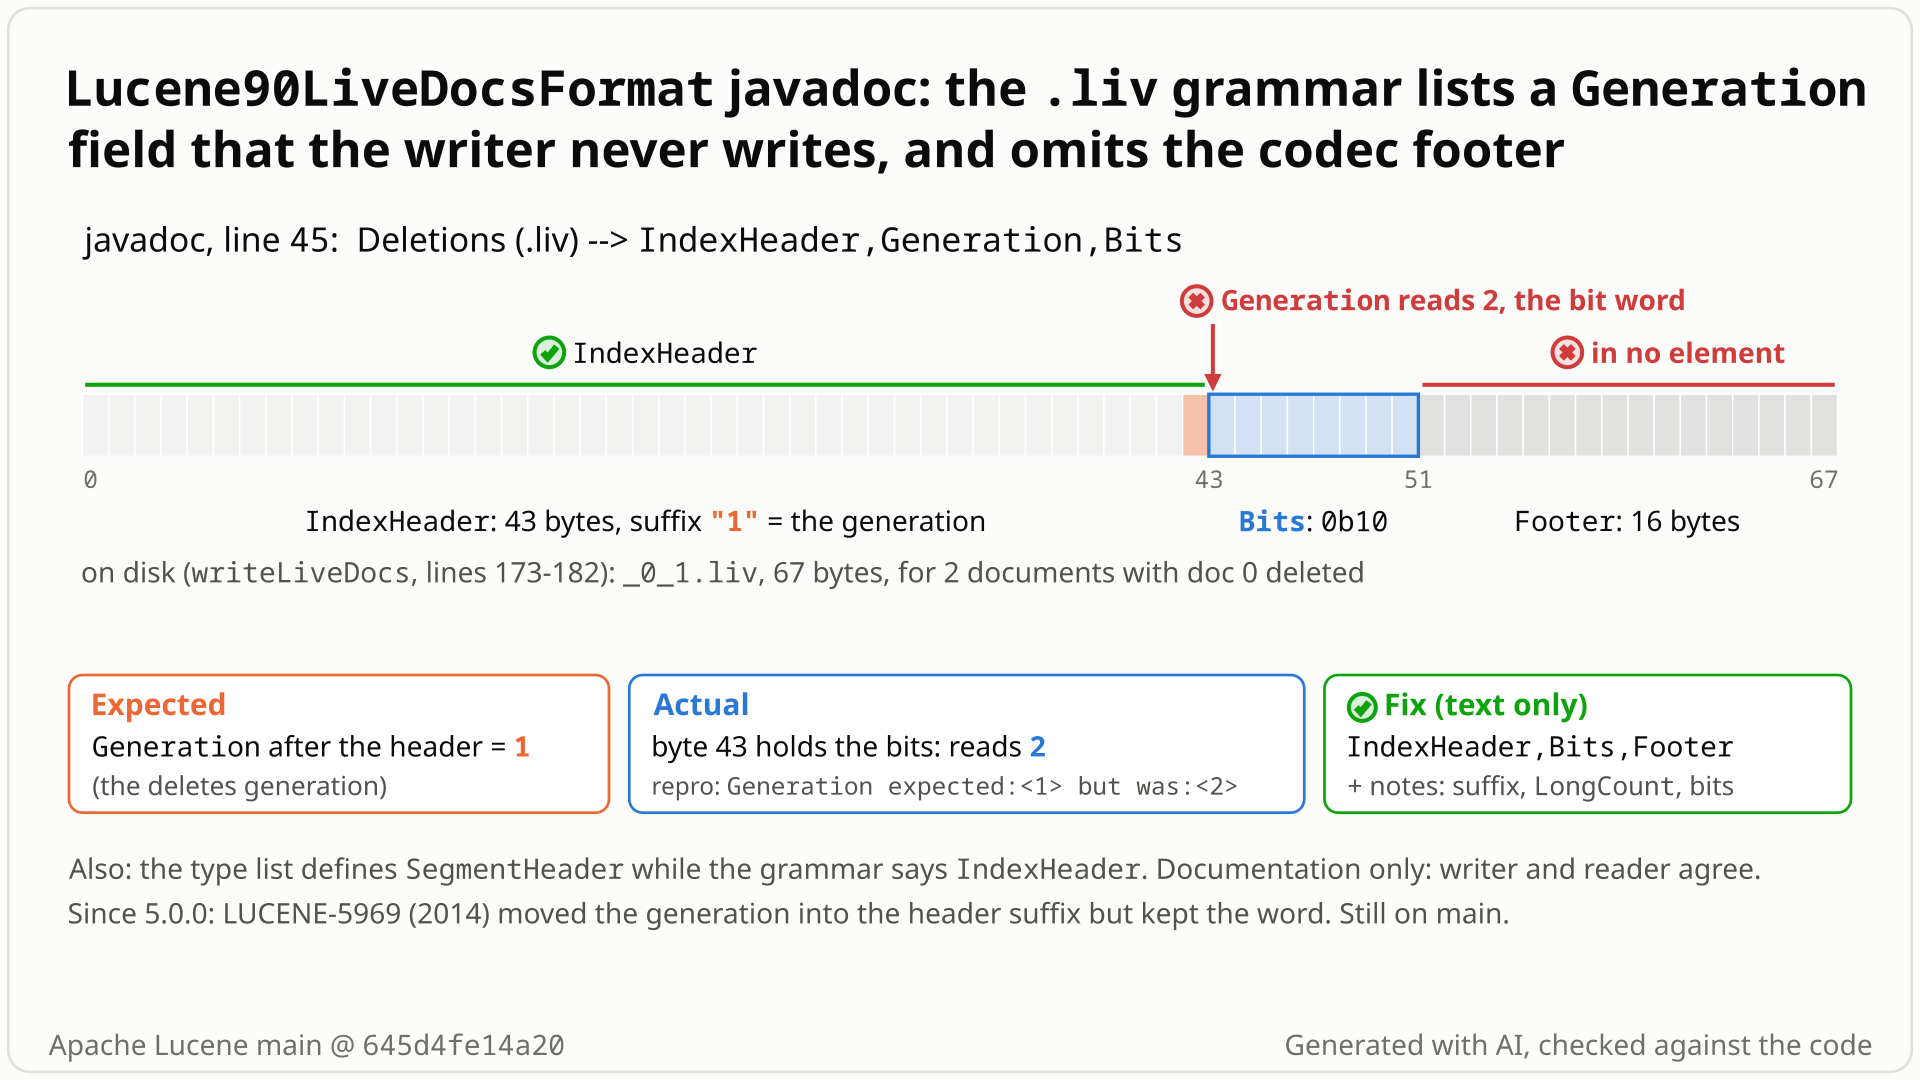
.liv grammar next to the bytes Lucene writes for the repro's two-document segment. Select the still to open it at full size. Generated with AI, checked against the code.- You index 2 documents with the default codec and delete doc 0. Lucene writes the live-docs file
_0_1.liv, 67 bytes; the segment's deletes generation is 1. - You decode it as the
Lucene90LiveDocsFormatjavadoc says:IndexHeader, Generation, Bits. After the 43-byte header you expect the Generation: 1. - You get 2. The 8 bytes there,
02 00 00 00 00 00 00 00, are the Bits word (binary 10: doc 1 live, doc 0 deleted). The generation is the header's last byte, its suffix "1" (base 36). - After the Bits, 16 bytes remain that the grammar never mentions: the codec footer with its checksum. Lucene's own reader expects exactly this layout, so only a decoder written from the javadoc goes wrong, on every
.livfile the default codec has written since 5.0.0.
People who read, inspect or re-implement the .liv format from this javadoc: format inspectors, ports, recovery tools. The default codec's file-format overview links this page for the details. Every .liv file since 5.0.0 is affected, with no setting involved. Lucene's writer and reader agree, so deletes, merges, CheckIndex and search are unaffected.
Mechanism, terms and numbers613 words
When a segment has deleted documents, the default codec writes a .liv file with one bit per document. The class javadoc of Lucene90LiveDocsFormat gives its layout as Deletions (.liv) --> IndexHeader,Generation,Bits (Lucene90LiveDocsFormat.java:45 on main 645d4fe14a20), defines SegmentHeader --> IndexHeader (:48), a name the grammar does not use, and leaves LongCount undefined (:49). The writer (:173-182) stores the deletes generation as the IndexHeader's suffix, in base 36, then the bit words, then a 16-byte codec footer; nothing is written between the header and the bits. A decoder that follows the text and reads Generation as a field of its own (the javadoc gives it no type; before LUCENE-5969 it was an Int64) reads the first bit word where it expects the generation (2 instead of 1 in the repro) and finds 16 trailing bytes the grammar does not mention. LUCENE-5969 (2014, before 5.0.0) moved the generation from an Int64 field into the header suffix and kept the word in the grammar; the footer has never been listed. Lucene's reader (:86-98) matches the writer, so only the javadoc is wrong, in every release from 5.0.0 to 10.6.0 and on main.
Deletions (.liv) --> IndexHeader,Generation,Bits

  SegmentHeader --> IndexHeader      (CodecUtil#writeIndexHeader)
  Bits --> <Int64>^LongCount
Generation has no type line, SegmentHeader does not occur in the grammar, LongCount and the bit meaning are not defined, and there is no Footer.
gen = info.getNextDelGen()(:168); the file name carries it (:169).CodecUtil.writeIndexHeader(output, CODEC_NAME, VERSION_CURRENT, info.info.getId(), Long.toString(gen, Character.MAX_RADIX))(:173-178): the generation is the header suffix, in base 36.writeBits(output, bits)(:180): the bits as Int64 words in batches of up to 1024 bits,bits2words(numBitsToCopy)words per batch (:201-213), the bits pastmaxDoccleared (:205-207).CodecUtil.writeFooter(output)(:182):CodecFooter --> Magic,AlgorithmID,Checksum, 16 bytes (CodecUtil.java:396).- The reader mirrors it:
checkIndexHeaderwith the same suffix (:86-92),readLongsofbits2words(maxDoc)words (:131-139),checkFooter(:98); a set bit is a live document (:144-145).
IndexHeader (43 bytes) 3f d7 6c 17 10 4c 75 63 65 6e 65 39 30 4c 69 76 65 44 6f 63 73 00 00 00 00
                       68 a3 41 43 0b 4a 55 52 c2 51 b4 61 f2 1a 24 0e 01 31   <- suffix: length 1, "1"
Bits    (8 bytes)      02 00 00 00 00 00 00 00                                  <- Int64 = 2 = binary 10
Footer  (16 bytes)     c0 28 93 e8 00 00 00 00 00 00 00 00 45 f2 e2 c9
The segment id bytes and the checksum differ per run; the layout does not. Whatever integer type a reader assumes for the untyped Generation (Int64, Int32, VLong, VInt), the bytes 02 00 00 ... read as 2. In the hunt's larger index (200 documents, two deletions, 91 bytes) the same reading gives -9 instead of the generation 1, and with Generation skipped the grammar ends at byte 75 of 91, 16 bytes (the footer) short.
15b8b1e66d9 (2014-09-26) added a real output.writeLong(gen) after the header, documented as Generation --> Int64, and the reader compared it with the expected generation ("file mismatch, expected generation=..."). c4bf601b68f (LUCENE-5969, 2014-10-22) moved the generation into the header suffix and removed the write, the reader check and the type line, but kept Generation in the grammar and the label SegmentHeader. The footer was never in the grammar, from the class's first version on.
Exposure and likelihood155 words
- Who is hit. Anyone who decodes a
.livfile without Lucene, or checks one by hand, following the class javadoc: format inspectors, ports to other languages, recovery or forensic tools. The default codec's overview (lucene104/package-info.java) links this class as Live documents (:177,:303), says it "defines the index file formats used in this version of Lucene" (:50) and "Details on each of these are provided in their linked pages" (:188). - Default vs opt-in. The default codec, every
.livfile it writes, on every release since 5.0.0. No setting changes the layout. - Scale. No runtime effect. The symptom is confined to a decoder written from the text: a wrong generation right after the header and 16 unexplained trailing bytes. A careful reader who cross-checks
CodecUtiland the overview's footer note can work it out, which keeps the impact minor. - Rating. Impact class minor, likelihood plausible, priority low.
One JUnit test, public API: index 2 documents with the default codec, delete doc 0, open the 67-byte _0_1.liv, check its IndexHeader with the generation "1" as suffix, then read the next element of the documented grammar. Deterministic, single thread, about 1.5 s; the same with assertions off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene90;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.IndexFileNames;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.index.SegmentCommitInfo;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestLucene90LiveDocsFormatJavadoc extends LuceneTestCase {

  public void testGenerationFollowsIndexHeader() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig()
              .setCodec(TestUtil.getDefaultCodec())
              .setMergePolicy(NoMergePolicy.INSTANCE);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (String id : new String[] {"0", "1"}) {
          Document doc = new Document();
          doc.add(new StringField("id", id, Field.Store.NO));
          w.addDocument(doc);
        }
        w.deleteDocuments(new Term("id", "0"));
      }
      SegmentCommitInfo sci = SegmentInfos.readLatestCommit(dir).info(0);
      long gen = sci.getDelGen();
      String file = IndexFileNames.fileNameFromGeneration(sci.info.name, "liv", gen);
      try (IndexInput in = dir.openInput(file, IOContext.READONCE)) {
        String suffix = Long.toString(gen, Character.MAX_RADIX);
        CodecUtil.checkIndexHeader(in, "Lucene90LiveDocs", 0, 0, sci.info.getId(), suffix);
        // javadoc: IndexHeader,Generation,Bits; actual: gen is the header suffix, next is Bits 0b10
        assertEquals("Generation", gen, in.readLong());
      }
    }
  }
}
cp TestLucene90LiveDocsFormatJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90LiveDocsFormatJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- After the IndexHeader comes the Generation the javadoc lists: 1, the segment's deletes generation.
- Observed
Generation expected:<1> but was:<2>: the 8 bytes after the header are the Bits word 0b10; the same with assertions off and on 10.6.0 and 9.12.3.
More files, environment, full output287 words
- The test sits in the codec package, like Lucene's own codec tests, and passes the codec name as the literal
"Lucene90LiveDocs"(the value of the class's privateCODEC_NAME,:58).checkIndexHeaderpassing with the suffix"1"shows the generation is already in the header; the next read takes Generation as a field of its own, as the grammar lists it. With this input the next bytes are02 00 00 ..., so any integer type for Generation reads 2; the test uses Int64, the type the element had before LUCENE-5969 (the javadoc itself gives none). It does not check the footer; the hunt's grammar check and the independent reproduction's test do. - Results: fails 1 of 1 on main with assertions on and off, standalone (1.52 s) and through gradle, and on the published 10.6.0 and 9.12.3 jars; 5 random-seed iterations fail 5 of 5 with the same message. The hunt's and the verifiers' larger tests also fail on 10.5.2 and the
branch_10_6head. - As a regression test: this test cannot guard the javadoc, because it transcribes the grammar. A form that pins down the corrected layout is this same test with its last line replaced by "next is the Bits word 0b10, then exactly the 16 footer bytes remain" (the fix check below).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same test also fails on the published 10.6.0 and 9.12.3 jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestLucene90LiveDocsFormatJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90LiveDocsFormatJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestLucene90LiveDocsFormatJavadoc > testGenerationFollowsIndexHeader FAILED
    java.lang.AssertionError: Generation expected:<1> but was:<2>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:5BDBCBCA94AFA0A]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.codecs.lucene90.TestLucene90LiveDocsFormatJavadoc.testGenerationFollowsIndexHeader(TestLucene90LiveDocsFormatJavadoc.java:60)

1 test completed, 1 failed- Generation was a real Int64 field until LUCENE-5969 moved it into the header suffix (2014); the write and its type line went, the word stayed.
- The type list still defines
SegmentHeader, a name the grammar no longer uses. - The overview sends readers here for format details; sibling grammars (
.cfs,.nvm,.fnm) list their Footer.
The full argument200 words
- History.
15b8b1e66d9wrote the generation as an Int64 after the header and documentedGeneration --> Int64;c4bf601b68f(LUCENE-5969) removed both the write and the type line. History suggests the word left in the grammar is what remains of the deleted field; it does not prove an oversight, because the same author revised the line later (5dcd24bf04c) and kept the word. Either way, the comma-separated grammar now lists an element that has no bytes of its own. - A half-renamed type list. It defines
SegmentHeader, which the grammar no longer uses; no reading makes that definition intended. - The contract.
lucene104/package-info.java:50and:188(quoted under "Who is affected"). - Convention. Most core grammars list
Footerexplicitly:.cfs(Lucene90CompoundFormat.java:49,:57),.nvm/.nvd(Lucene90NormsFormat.java:57,:77),.fnm(Lucene94FieldInfosFormat.java:48-50,:62),.si(Lucene99SegmentInfoFormat.java:67); not all do: the.cfeentry-table production (Lucene90CompoundFormat.java:50-51) does not. A.fnmfile written for doc-values updates has a generation suffix in its header (ReadersAndUpdates.java:846,:854), and the.fnmgrammar folds it intoHeaderwith no Generation element. - Precedent. File-format doc errors were filed and fixed as ordinary issues, e.g. LUCENE-7532 (#8583) and LUCENE-713 (#1788).
The devil's-advocate check215 words
Strongest case for "intended" (the refute reviewer, the intended-lens reviewer and the devil's-advocate verifier; rated moderate): CodecUtil.writeIndexHeader's javadoc gives "generation" as an example suffix (CodecUtil.java:90-92), so IndexHeader,Generation could be read as one element; the overview says every index file ends with a checksum footer (package-info.java:381-383) and calls itself "a high-level definition" (:54), the policy of LUCENE-2946 (#4020); and LiveDocsFormat is @lucene.experimental. Under that reading (Generation zero-width, footer implicit) the bytes parse exactly: 143 of 143 files in the hunt's grammar check.
Why it fails: the grammar is a comma-separated sequence of elements, and Generation was a separate Int64 element until its type line was deleted; a suffixed header elsewhere (.fnm) is documented as plain Header; "high-level" allows leaving detail out, not listing an element that is not written or defining a name the grammar does not use, and on LUCENE-2946 rmuir wrote that bit-for-bit detail is fine "For the simple metadata files, and even stored fields and postings its fine (for now)"; @lucene.experimental is about API stability. The generous reading lowers the severity; it does not make the text right. Every verifier and the adjudication still concluded that the text is wrong as written; the reviewers rated the case for an intended reading moderate.
Recommended A. Correct the grammar and say what the parts hold
Javadoc only: make the grammar IndexHeader,Bits,Footer, relabel the SegmentHeader type line as IndexHeader, add Footer --> CodecFooter, and note that the header suffix is the deletes generation in base 36, LongCount = ceil(maxDoc/64) and a set bit means live. Validated: the corrected-grammar test, the live-docs suite, core's static checks and the javadoc render pass.
All options and trade-offs3 options · 655 words
Two ways to correct the text; A was validated. Backport: the file is byte-identical on branch_10_6, so the same diff applies there if wanted; main and branch_11x are the usual targets.
Grammar IndexHeader,Bits,Footer, the type lines IndexHeader and Footer, and a short Notes list: the header suffix is the deletes generation in base 36 (as in the file name), LongCount = ceil(maxDoc / 64), bit (docID % 64) of word (docID / 64) is set for a live document, and the bits from maxDoc on are clear. Javadoc only.
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90LiveDocsFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90LiveDocsFormat.java
@@ -42,11 +42,21 @@
*
* <p>Although per-segment, this file is maintained exterior to compound segment files.
*
- * <p>Deletions (.liv) --> IndexHeader,Generation,Bits
+ * <p>Deletions (.liv) --> IndexHeader,Bits,Footer
*
* <ul>
- * <li>SegmentHeader --> {@link CodecUtil#writeIndexHeader IndexHeader}
+ * <li>IndexHeader --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>Bits --> <{@link DataOutput#writeLong Int64}> <sup>LongCount</sup>
+ * <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
+ * </ul>
+ *
+ * <p>Notes:
+ *
+ * <ul>
+ * <li>The suffix of the IndexHeader is the deletes generation in base 36, the same generation as
+ * in the file name.
+ * <li>LongCount is ceil(maxDoc / 64). Bit (docID % 64) of Int64 number (docID / 64) is set if the
+ * document is live and clear if it is deleted. The bits from maxDoc on are clear.
* </ul>
*/
public final class Lucene90LiveDocsFormat extends LiveDocsFormat {Trade-offs
- Every added fact was checked on real files: in all 143
.livfiles of 91 generated indexes the suffix is the base-36 generation, a set bit is a live document (least significant bit first) and the bits pastmaxDocare clear; the writer clears them explicitly (:205-207). The fixed text parses 59 of 59 files in a second sweep. - 10 more javadoc lines to keep in sync (12 inserted, 2 replaced), on a simple and stable format (
VERSION_CURRENTis stillVERSION_START).
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle, seed DEADBEEF (2026-11-01): on stock main the minimal test fails with assertions on and off. - With fix A applied (2 lines changed, 10 added; 12 insertions, 2 deletions): the same test with its last line following the corrected grammar (next the Bits word 0b10, then exactly the 16 footer bytes remain) passes 1 of 1 with assertions on and off;
TestLucene90LiveDocsFormatpasses (4 tests, 0 failures,testOverflowskipped as a monster test);:lucene:core:check -x test(google-java-format, ecj lint, forbidden APIs) passes;:lucene:core:renderJavadocpasses and rendersDeletions (.liv) --> IndexHeader,Bits,Footerwith the type lines and notes. A javadoc edit cannot change the bytes, so the corrected-grammar test checks that the new text describes them, not a code change. - Earlier: the refute reviewer applied the same text to a scratch copy (live-docs tests and javadoc lint passed), and the hunt's grammar check parses 59 of 59
.livfiles with it.
Grammar IndexHeader,Bits,Footer, the label SegmentHeader changed to IndexHeader, and a Footer --> CodecFooter type line; no notes.
- * <p>Deletions (.liv) --> IndexHeader,Generation,Bits
+ * <p>Deletions (.liv) --> IndexHeader,Bits,Footer
*
* <ul>
- * <li>SegmentHeader --> {@link CodecUtil#writeIndexHeader IndexHeader}
+ * <li>IndexHeader --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>Bits --> <{@link DataOutput#writeLong Int64}> <sup>LongCount</sup>
+ * <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
* </ul>Trade-offs
Removes the wrong element and the wrong label and lists the footer, but a reader still has to find out from the code that the header suffix holds the generation, what LongCount is and which bit value means live.
What the checks validated
Not built (the diff applies cleanly to 645d4fe14a20, git apply --check).
For example "Generation: the deletes generation, stored as the IndexHeader suffix".
Trade-offs
Keeps a grammar element that has no bytes of its own, unlike the .fnm convention (Header only), and still needs the label and Footer fixes.
What the checks validated
Not run.
It matters only to third-party tools that decode .liv files themselves from this javadoc, which would misread the generation and the trailing footer bytes.
Semi-formal: a grammar check extracted the .liv production and its type list from the javadoc and interpreted it over the bytes of 143 .liv files from 91 generated default-codec indexes, with Lucene's own reader as the oracle for every bit. Every reading of the text as written failed on all 143 files; the writer's real layout parsed all 143.
The method in full150 words
- The check extracts the production and type definitions mechanically from the javadoc source, checks them for well-formedness (it reports the undefined element Generation, the undefined count LongCount and the unused definition SegmentHeader) and interprets them over the real bytes, under every typing of the untyped Generation: absent, Int64, Int32, VLong, VInt.
- Inputs: 91 indexes (11 fixed and 80 seeded random configurations: sizes, flushes, compound files, deletion rates for both live-docs read paths, 1-3 deletion commits, many field types), 143
.livfiles, the same results with assertions on and off.LiveDocsFormat.readLiveDocsis the oracle for every bit. - Positive control: the writer-layout grammar parses all 143 files exactly. Vacuity: 3 of 3
.livlayout mutants (footer dropped, Int64 generation inserted, LongCount + 1) are killed. Fix check: the corrected text parses 59 of 59 files. - This is a differential grammar check of documentation against real output, not model checking or a proof.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-28, rechecked 2026-11-01). Nearest: LUCENE-5969 (#7031), which made the text stale, and LUCENE-9705 (lucene-solr#2274), which copied it. Not fixed upstream.
Searches3 searches
- Related, not this bug: #7031 (LUCENE-5969; its 105 comments never mention the
.livgrammar); apache/lucene-solr#2274 / #10744 (LUCENE-9705, copied the text); #15413 (last change to the file, reader code only); #15712 (deleted the backward-codecs copy, which had the same text); #4020 (LUCENE-2946, the high-level doc policy); open #16768 and #16623 (LiveDocs utility classes, not this file). - Not fixed upstream: the file is byte-identical on upstream main
f815e679bf6c(2026-11-01),branch_10_6andbranch_11x. Tracking issue #16937 does not name it. - Open javadoc PRs: #16949 "Fix stale names and examples in javadocs" (27 files) touches no codec file-format page; #16939 (the 10.6.0 docs link to the file-formats page) is a different problem.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene and apache/lucene-solr issues, PRs and commits; the JIRA archive; downstream repositories | 2026-10-28 | three scripted prior-report searches (45 non-web queries each; their web part was covered by the 14 web searches below); 48 manual GitHub searches incl. lucene-solr and four downstream projects; the changed files of all 414 open PRs and of the PRs closed since 2025-11-20; class-name, file-list and history searches, because GitHub search tokenizes IndexHeader,Generation,Bits poorly | no report; only the commits that made or copied the text |
| Mailing lists and web | 2026-10-28 | dev@, java-user@, issues@ and commits@ (scripted searches); 14 web searches | no report; only javadoc mirrors, old file-format PDFs and the commits@ diff mails |
| apache/lucene (recheck) | 2026-11-01 | the file's blob on upstream main, branch_10_6 and branch_11x; its commits; issues and PRs updated since 2026-10-28 for Lucene90LiveDocsFormat, LiveDocsFormat javadoc, liv file format, IndexHeader Generation, file format javadoc grammar and SegmentHeader; the changed files of the 39 open PRs updated since then; #16949 and #16939 | no report; the file is unchanged upstream |
Stale since LUCENE-5969 (c4bf601b68f, 2014-10-22), before 5.0.0: the generation moved into the header suffix and the grammar kept the word; the footer was never listed. Affects every release with this .liv format, 5.0.0 to 10.6.0, and main; in 4.x the default codec writes .del files instead.
Versions tested7 rows
- Created:
afee9af13f2(2014-09-26):Lucene50LiveDocsFormat, grammarSegmentHeader,Bits, while the writer already appended a footer. - Generation added:
15b8b1e66d9(2014-09-26):writeLong(gen)after the header, documentedGeneration --> Int64. - Introduced:
c4bf601b68f(LUCENE-5969 "Add Lucene50Codec", #7031; lucene5969 branch, svn r1633514, Robert Muir, 2014-10-22T04:21Z): the generation moved into the header suffix; the write and the type line removed, the word and theSegmentHeaderlabel kept. Later the same day,5dcd24bf04c("fix precommit, improve file format docs", same author) changed the first element toIndexHeaderand keptGeneration. It reached branch_5x as0f304eafb93and trunk asff50c35fc22(2014-10-24). svn era: no GitHub PR. - Copied:
f0a2f1fe039(LUCENE-9705, apache/lucene-solr#2274, 2021-02-04) createdLucene90LiveDocsFormatwith the same text; it is the live-docs format from 9.0.0 on. - No release ever had the correct grammar: the Int64 element was added and removed during 5.0 development. All 98 release tags 5.0.0-8.8.1 and 9.0.0-10.5.2 in the release-tag clone, and the 10.6.0 tag, carry the same lines; the clone has no 8.8.2 or 8.9.0-8.11.4 tags (8.11.4's bytes were executed, its javadoc was not read).
- First affected release: 5.0.0, the first with this binary
.livformat (Lucene50LiveDocsFormat); in 4.10.4 the default codec writes.delfiles throughLucene40LiveDocsFormat(Lucene410Codec.java:57). The SimpleText codec has written its own plain-text.livfiles since 4.0.0; that is a different format with no grammar in its javadoc.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails with assertions on and off (standalone and gradle) |
10.6.0 (published jars, 4ae946e5a9b) | affected | the minimal test fails |
| 9.12.3 | affected | the minimal test fails; also the finder's and the independent reproduction's tests |
10.5.2, branch_10_6 head | affected | the finder's and the independent reproduction's tests fail |
| 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 10.0.0 | affected | the history probe (same source unchanged) fails |
c4bf601b68f, 0f304eafb93 vs their parents | A/B | each parent writes the Int64 Generation, each introducing commit does not |
| 4.10.4 | not affected | the default codec writes .del files (Lucene40LiveDocsFormat); no Lucene50/90LiveDocsFormat class |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication (high confidence); a credibility audit confirmed it as a minor documentation defect. This doc re-ran the repro and validated the fix.
Checks and verdicts282 words
Every check either re-ran a repro on main or read the same lines; all concluded that the grammar is wrong as written, while the reviewers rated the case for an intended reading moderate.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, refute lens (OpenAI GPT-5.6, executing) | real, high confidence | Its own test failed in three runs (two seeds with assertions on, one with them off); its writer-layout control passed; the fix applied to a scratch copy passed the live-docs tests and javadoc lint. Intended argument moderate. |
| independent reproducer | real | Its own test (130 documents, deletes in two commits, generation 2) fails 2 of 3 on main, 10.5.2 and 9.12.3 with assertions on and off ("reads -34"; "grammar ends at byte 67 of 83, 16 bytes not described"); its layout control passes. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium confidence | It could not run code, so it only read; a separate run re-ran the finder's test on main with assertions on and off, failing as stated. |
| intended-behaviour devil's advocate | real (documentation defect) | Built and rejected the "high-level docs", "Generation = header suffix" and "footer note" readings; re-ran on main and 10.5.2. |
| adjudication | confirmed, high confidence, documentation | Re-ran the finder's test and the independent reproduction's on new seeds. |
| credibility audit | confirmed, minor | Re-ran the finder's test on a new seed; "a real but trivial documentation defect". |
| this doc's validation (2026-11-01) | fix A validated | In a scratch worktree of 645d4fe14a20: the minimal test fails on stock main with assertions on and off; with fix A the corrected-grammar test and TestLucene90LiveDocsFormat pass, and core's static checks and javadoc render pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 299 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,444 words
- Registry title
- The file-format javadoc of the default live-docs format (Lucene90LiveDocsFormat) gives the .liv grammar as 'IndexHeader,Generation,Bits', but no separate Generation has been written since LUCENE-5969 (the deletes generation is the IndexHeader suffix), the codec footer the writer appends is missing, and the type list defines SegmentHeader instead of IndexHeader (documentation defect; the writer and reader agree)
- Area
- codecs / live docs (Lucene90LiveDocsFormat .liv file-format javadoc vs its writer and reader)
- Priority
- Low, rank 1283: The .liv grammar has a phantom Generation field and no footer, a documentation-only defect that makes a doc-following parser misread the first bit word of every segment with deletions.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so deleting, merging, CheckIndex and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement the .liv format from this class javadoc (the default codec's package docs link it as the Live Documents format), and a decoder that follows the text cannot account for the bytes of any .liv file the default codec writes (executed); the text has been wrong in every release since 5.0.0 (2015), and no scale or special setting is needed beyond a segment with deletions.
- Summary
- You decode a live-docs (.liv) file of the default codec by following the Lucene90LiveDocsFormat javadoc, which gives the layout 'IndexHeader, Generation, Bits'. The writer instead stores the deletes generation inside the IndexHeader (as its suffix, in base 36), then the bit words, then a 16-byte codec footer, so there is no Generation field after the header: a decoder that reads one there gets the first word of the bit set, and one that skips it finds 16 bytes the grammar does not mention. The type list also defines 'SegmentHeader' while the grammar says 'IndexHeader'; Lucene's own reader matches the writer, so nothing breaks at runtime, only the documentation is wrong.
- Introduced
- c4bf601b68f04a7f8ea1cbddea0b77a9858c48b2 (lucene5969 feature branch, svn r1633514, LUCENE-5969 'Add Lucene50Codec', now apache/lucene#7031; svn era, no GitHub PR; by rmuir): it moved the generation into the IndexHeader suffix (writeIndexHeader(..., Long.toString(gen, Character.MAX_RADIX))), removed output.writeLong(gen) and the 'Generation --> Int64' type line, but kept 'Generation' in the grammar; it reached the 5.0.0 release line as 0f304eafb93 (branch_5x, svn r1633993) and trunk as ff50c35fc22 [exec: commit-level A/B on both lines, each parent writes the Int64 Generation element, each introducing commit does not]. Secondary parts [read]: the missing Footer dates from the first Lucene50LiveDocsFormat, afee9af13f2 (2014-09-26), whose grammar 'SegmentHeader,Bits' already omitted the footer the writer appended; the SegmentHeader/IndexHeader label mismatch comes from c4bf601b68f plus 5dcd24bf04c ('LUCENE-5969: fix precommit, improve file format docs', the same day, which renamed the grammar's first element to IndexHeader and kept Generation). The text was copied unchanged into Lucene90LiveDocsFormat by f0a2f1fe039 (LUCENE-9705, apache/lucene-solr#2274, 2021) (2014-10-22 (author date of c4bf601b68f, lucene5969 branch); 2014-10-24 (0f304eafb93 on branch_5x, ff50c35fc22 on trunk); the footer omission is older, 2014-09-26 (afee9af13f2); all before the 5.0.0 release)
- First affected version
- 5.0.0 [exec] (the first release with this binary .liv format; in 4.10.4 and older the default codec writes .del through Lucene40LiveDocsFormat, and neither Lucene50LiveDocsFormat nor Lucene90LiveDocsFormat exists [exec on 4.10.4]; SimpleText's plain-text .liv files, written since 4.0.0, are a different format); no release ever shipped the correct state, because the Int64 Generation element was added (15b8b1e66d9, 2014-09-26) and removed (c4bf601b68f / 0f304eafb93, 2014-10-22/24) during 5.0 development
- Affected versions
- every release with the .liv format, 5.0.0 through 10.6.0 (the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream [exec: a single main() probe compiled unchanged fails on 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main, with its writer-layout control passing everywhere; the finder's JUnit fails 1 of 2 on main (-ea and -da), the branch_10_6 head, 10.5.2 and 9.12.3 (9.x API variant); the independent reproduction's JUnit fails 2 of 3, its layout control passing, on main, 10.5.2 and 9.12.3, each with -ea and -da; read: all 98 release tags from 5.0.0 to 10.5.2 in the release-tag clone carry the identical grammar line, the SegmentHeader type line and a writeFooter call]. The text lives in Lucene50LiveDocsFormat (5.0.0-8.x) and Lucene90LiveDocsFormat (9.0.0-main). Caveats: the release-tag clone has no 8.8.2 or 8.9.0-8.11.4 tags (8.11.4 bytes executed, its javadoc not read); upstream main 645d4fe14a20 (2026-10-28) still carries the lines [read]; all runs used JDK 25 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: three scripted prior-report searches of 45 queries each over GitHub issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and downstream repositories (all non-web queries completed; 10 web queries did not finish and were covered by the 14 web searches), 48 manual GitHub searches incl. the archived lucene-solr repo and four downstream projects, 14 web searches (javadoc mirrors and old file-format PDFs only), all 414 open apache/lucene PRs scanned by changed files and the PRs closed since 2025-11-20; GitHub search tokenizes 'IndexHeader,Generation,Bits' poorly, so class-name, file-list and history searches back it up). Nearest items, not the same bug: #7031 / LUCENE-5969 (made the Generation element stale; its 105 GitHub comments (106 on JIRA) never mention the .liv grammar), apache/lucene-solr#2274 / #10744 LUCENE-9705 (copied the text into Lucene90LiveDocsFormat), #15413 (last change to the file, reader code only), #15712 (deleted the backward-codecs copy that had the same text), #4020 / LUCENE-2946 (2012 policy for high-level file-format docs; detail kept for simple metadata files), open #16768 and #16623 (LiveDocs utility classes, do not touch this file). Tracking issue #16937 does not name it. Recheck (2026-10-28): six searches (Lucene90LiveDocsFormat, LiveDocsFormat javadoc, liv file format, IndexHeader Generation Bits, SegmentHeader javadoc, file format javadoc footer) find no report; none of the 31 apache/lucene issues and PRs created since 2026-10-26 (including a series of javadoc fixes, #16920-#16922, #16927, #16928, #16933-#16936) concerns it; of the open PRs updated since 2026-10-27 only #16480 touches a related file (lucene104/package-info.java, a History bullet); by author date the file's latest upstream commits are 011703499168af (#15413, 2025-11-25) and 2550eb2a72a6 (#14998, 2025-09-05), neither touching the grammar; upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 45 and 48. Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone and through gradle, and a byte probe of the same index; the recommended fix in a scratch worktree (the same test following the corrected grammar, the closest live-docs suite,:lucene:core:check -x testand:lucene:core:renderJavadoc). The minimal repro on the published 10.6.0 and 9.12.3 jars. The hunt's and the verifiers' tests on maina9779ef3c193(the same file), thebranch_10_6head4ae946e5a9b, 10.5.2 and 9.12.3; the history probe on 4.10.4, twelve releases from 5.0.0 to 10.5.2 (5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2) and the 2014 commits.Lucene90LiveDocsFormat.javais byte-identical on645d4fe14a20, upstream mainf815e679bf6c(2026-11-01),branch_10_6andbranch_11x(read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90LiveDocsFormat.java:45 ('Deletions (.liv) --> IndexHeader,Generation,Bits'), :48 ('SegmentHeader --> IndexHeader'), :49 ('Bits --> <Int64>^LongCount'), :173-178 (writeIndexHeader with suffix Long.toString(gen, Character.MAX_RADIX)), :180 (writeBits), :182 (writeFooter), :86-98 (reader: checkIndexHeader with the same suffix, checkFooter); identical at Lucene main ea57360912ed (compared 2026-10-28)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:50 ('defines the index file formats used in this version of Lucene'), :54 ('a high-level definition'), :188 ('Details on each of these are provided in their linked pages'), :303 (links Lucene90LiveDocsFormat as Live Documents), :381 (checksum footers added to each index file in 4.8)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90LiveDocsFormat.java (lines 45-50 the javadoc; 74-102 readLiveDocs; 131-139 readLongs; 144-145 bit meaning; 164-194 writeLiveDocs; 196-216 writeBits)lucene/core/src/java/org/apache/lucene/codecs/CodecUtil.java (lines 90-92 suffix such as generation, 97 IndexHeader grammar, 396 CodecFooter grammar)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 177, 188, 303)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java (49, 57), lucene90/Lucene90NormsFormat.java (57, 77), lucene94/Lucene94FieldInfosFormat.java (48-50, 62), lucene99/Lucene99SegmentInfoFormat.java (67), LiveDocsFormat.java (29), CodecUtil.java (90-92), lucene104/package-info.java (50, 54, 188, 381-383)lucene/core/src/java/org/apache/lucene/index/ReadersAndUpdates.java (line 846)
- History
a Lucene clone release tags 4.0.0 and 4.10.4 (git show: SimpleTextLiveDocsFormat.java LIVEDOCS_EXTENSION "liv" at 4.0.0 line 48 and 4.10.4 line 50; 4.10.4 Lucene410Codec.java line 57 Lucene40LiveDocsFormat, Lucene40LiveDocsFormat.java line 69 DELETES_EXTENSION "del")
- TestLucene90LiveDocsFormatJavadoc.java (JUnit, one test):
repro/LFV-970/src/org/apache/lucene/codecs/lucene90/TestLucene90LiveDocsFormatJavadoc.java(64 lines)
Made from the code at 645d4fe14a20 and an executed probe of the repro's index, in parallel with this doc.
assets/LFV-970/bug.png(299 KB)