The class javadoc that documents the default compound file's table of contents leaves out a part the writer writes, and misdescribes another.
- To save file handles, Lucene by default packs a newly flushed segment's files (and a merged segment's, if it is small enough) into one compound file:
_0.cfsholds the bytes of_0.fnm,_0.fdtand the others one after another (each start aligned to 64 bytes), and_0.cfeis its table of contents, one entry per file (name, start offset, length). - Like every index file,
.cfestarts with an IndexHeader (magic, codec name, version, the 16-byte segment id and a suffix) and ends with a 16-byte codec footer (magic, algorithm id, CRC32 checksum).
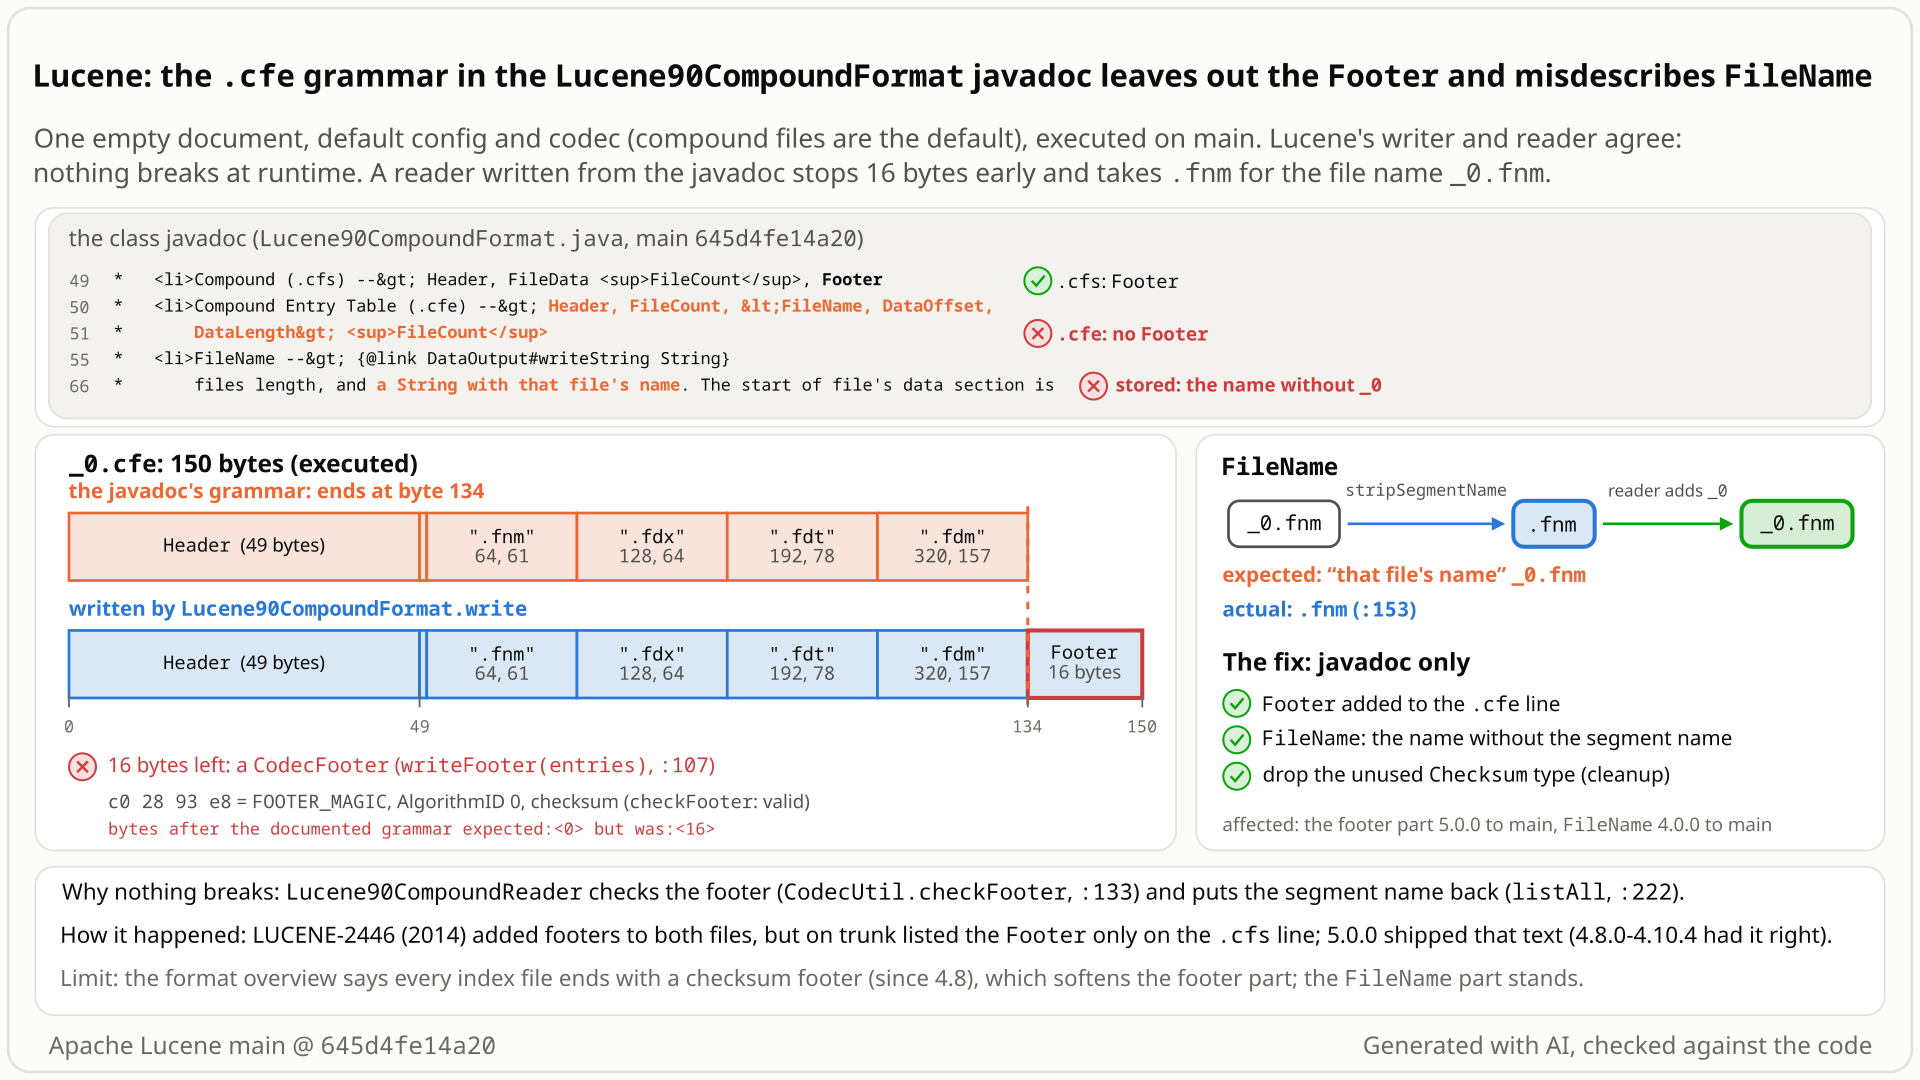
.cfe grammar next to the 150 bytes Lucene writes for the repro's one-document segment. Select the still to open it at full size. Generated with AI, checked against the code.- You index one empty document with the default codec and compound files on (the default for new segments). Lucene packs the segment's 4 files into
_0.cfsand writes their 150-byte table of contents,_0.cfe. - You decode
_0.cfeas theLucene90CompoundFormatjavadoc says: Header (49 bytes), FileCount (4), then 4 entries of FileName, DataOffset, DataLength (21 bytes each). You expect the file to end at byte 134, and the names to be_0.fnm,_0.fdx,_0.fdt,_0.fdm. - You get 16 more bytes after the last entry: the codec footer (
c0 28 93 e8, algorithm id, CRC32 checksum). The.cfsline right above lists its Footer; the.cfeline does not. - And the names read
.fnm,.fdx,.fdt,.fdm: the writer strips the segment name_0, and Lucene's reader adds it back. Lucene reads its own files fine; only a tool written from the javadoc goes wrong, on every.cfefile since 5.0.0.
People who read, inspect or re-implement the .cfe format from this javadoc: format inspectors, ports, recovery or extraction tools. The default codec's overview links this page for the details. Every .cfe file since 5.0.0 is affected, with no setting involved. Lucene's writer and reader agree, so indexing, merging, CheckIndex and search are unaffected.
Mechanism, terms and numbers788 words
A compound segment is two files: .cfs holds the bytes of all the segment's files and .cfe is its table of contents. The class javadoc of Lucene90CompoundFormat, linked from the default codec's file-format overview as "Compound File", gives Compound (.cfs) --> Header, FileData^FileCount, Footer (Lucene90CompoundFormat.java:49 on main 645d4fe14a20) and Compound Entry Table (.cfe) --> Header, FileCount, <FileName, DataOffset, DataLength>^FileCount (:50-51), with no Footer on the .cfe line, and says each entry holds "a String with that file's name" (:65-66). The writer appends a 16-byte codec footer to .cfe (:107) and stores each name with the segment name stripped (:153), for example .fnm for _0.fnm. A decoder that follows the text stops 16 bytes before the end of every .cfe file, and a lookup by the names it read, taken as file names, fails (the segment name is missing). Lucene's reader checks the footer (Lucene90CompoundReader.java:133) and adds the segment name back (:222), so only the javadoc is wrong: the footer part in every release from 5.0.0 to 10.6.0 and on main, the FileName part from 4.0.0 on. The unused Checksum on the type line (:54) belongs to the linked CodecFooter grammar; removing it is cleanup.
Compound (.cfs) --> Header, FileData^FileCount, Footer
Compound Entry Table (.cfe) --> Header, FileCount, <FileName, DataOffset, DataLength>^FileCount

  Header --> IndexHeader                     (CodecUtil#writeIndexHeader)
  FileCount --> VInt
  DataOffset,DataLength,Checksum --> UInt64
  FileName --> String
  FileData --> raw file data
  Footer --> CodecFooter                     (CodecUtil#writeFooter)

Notes: ... Each directory entry contains a long pointer to the start of this file's data section,
the files length, and a String with that file's name. ...
The .cfe production has no Footer, although Footer is defined (:57) and used on the .cfs line (:49). Checksum (:54) is used by neither production: it is the last element of the linked CodecFooter grammar (CodecUtil.java:396).
CodecUtil.writeIndexHeader(entries, ENTRY_CODEC, ...)(:102),entries.writeVInt(numFiles)(:117).- Per file, in ascending size order:
entries.writeString(IndexFileNames.stripSegmentName(file)),writeLong(startOffset),writeLong(length)(:153-155).stripSegmentNamereturns "the filename with the segment name removed" (IndexFileNames.java:133-144); it cuts at the second_or else the first.(:119-127), so_0.fnmis stored as.fnm, while a per-field file keeps the_of its suffix (the history probe saw_Lucene50_0.docstored on 5.0.0-7.7.3). - Then
CodecUtil.writeFooter(entries)(:107), right afterCodecUtil.writeFooter(data)for the.cfs(:106). - The reader mirrors it:
readMappingreads the string as anid(Lucene90CompoundReader.java:144),CodecUtil.checkFooterverifies the footer (:133), lookups strip the segment name from the requested name (:171,:235), andlistAlladds it back (:222).
bytes 0-48     IndexHeader (49 bytes: magic, "Lucene90CompoundEntries", version, segment id, empty suffix)
byte  49       FileCount = 4 (VInt)
bytes 50-70    FileName ".fnm"  DataOffset 64   DataLength 61    (21 bytes: 1 + 4 + 8 + 8)
bytes 71-91    FileName ".fdx"  DataOffset 128  DataLength 64
bytes 92-112   FileName ".fdt"  DataOffset 192  DataLength 78
bytes 113-133  FileName ".fdm"  DataOffset 320  DataLength 157
               <- the documented grammar ends here, at byte 134 of 150
bytes 134-149  Footer: c0 28 93 e8 | 00 00 00 00 | 8-byte CRC32 checksum   (not in the .cfe grammar)
The segment id and the checksum differ per run; this one-document index's layout does not. CodecUtil.checkFooter accepts the 16 left-over bytes. The compound directory lists the sub-files as _0.fnm, _0.fdx, _0.fdt, _0.fdm. In the hunt's sweep the same holds for all 87 .cfe files of 91 generated indexes (16 bytes left over in each) and all 1720 entries (stripped names).
- Footer. LUCENE-2446 added
writeFooterto both compound files in one change. On trunk (c189d0fb74d, 2014-04-01) the javadoc got, Footeron the.cfsline only, plusChecksumon the type line; the branch_4x backport (819eda82e33, 2014-04-02) put, Footeron the.cfeline instead, so 4.8.0-4.10.4 documented the.cfefooter. The LUCENE-5944 bulk backport (55594bad9b0, 2014-09-18) replaced the branch_5x text with the trunk text, so from 5.0.0 the.cfeline has no Footer. LUCENE-5969 and LUCENE-9705 copied the text intoLucene50CompoundFormatandLucene90CompoundFormat. - FileName. Up to 3.0.x the writer stored the full name and "with that file's name" was right. LUCENE-2455 (
d6dd2e234e1, 2010, 3.1) started storing the stripped name, so that entries stay valid when a segment is renamed, and the sentence was not updated;25a59d8902e(2012-06-11) moved it into the public format docs (4.0.0).
Exposure and likelihood223 words
- Who is hit. Anyone who decodes a
.cfefile without Lucene, or checks one by hand, following the class javadoc. The default codec's overview (lucene104/package-info.java) says it "defines the index file formats used in this version of Lucene" (:50), links this class as "Compound File" (:237) and says "Details on each of these are provided in their linked pages" (:188). Two outside.cfeparsers exist (a 2021 draft format description and a 2018 script); both worked around the text without reporting it. - Default vs opt-in. The default codec; compound files are the default for new segments (
IndexWriterConfig.java:96-99,DEFAULT_USE_COMPOUND_FILE_SYSTEM = true) and for small segments (package-info.java:195). Every.cfefileLucene90CompoundFormatwrites shows both parts; no setting changes its layout (a segment that is not compound has no.cfeat all). - Scale. No runtime effect. The symptom is confined to code written from the text: a decoder stops 16 bytes early and looks for
.fnmwhere the compound directory has_0.fnm; a tool that wrote.cfefiles by the text would produce files Lucene's reader rejects atcheckFooter(read, not executed). A careful reader who cross-checks the overview's footer note and the reader code can work it out, which keeps the impact minor. - Rating. Impact class minor, likelihood plausible, priority low.
One JUnit class, public API: index one empty document with the default codec and compound files on, then read _0.cfe with only the documented grammar. One method per wrong statement: the bytes left after the last entry, and the stored names. Deterministic, single thread, about 2.6 s; the same with assertions off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene90;

import java.util.Arrays;
import java.util.TreeSet;
import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.codecs.CompoundDirectory;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SegmentInfo;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestLucene90CompoundEntriesJavadoc extends LuceneTestCase {

  private static SegmentInfo writeCompoundSegment(Directory dir) throws Exception {
    IndexWriterConfig iwc =
        new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()).setUseCompoundFile(true);
    try (IndexWriter w = new IndexWriter(dir, iwc)) {
      w.addDocument(new Document());
    }
    return SegmentInfos.readLatestCommit(dir).info(0).info;
  }

  public void testEntryTableEndsAfterLastEntry() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      SegmentInfo si = writeCompoundSegment(dir);
      try (IndexInput in = dir.openInput(si.name + ".cfe", IOContext.READONCE)) {
        in.seek(CodecUtil.indexHeaderLength("Lucene90CompoundEntries", ""));
        for (int i = in.readVInt(); i > 0; i--) {
          in.readString();
          in.readLong();
          in.readLong();
        }
        // javadoc: .cfe ends after the last <FileName, DataOffset, DataLength>; written: a Footer
        assertEquals("bytes after the documented grammar", 0, in.length() - in.getFilePointer());
      }
    }
  }

  public void testFileNameIsTheFileName() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      SegmentInfo si = writeCompoundSegment(dir);
      TreeSet<String> fileNames = new TreeSet<>();
      try (IndexInput in = dir.openInput(si.name + ".cfe", IOContext.READONCE)) {
        in.seek(CodecUtil.indexHeaderLength("Lucene90CompoundEntries", ""));
        for (int i = in.readVInt(); i > 0; i--) {
          fileNames.add(in.readString());
          in.readLong();
          in.readLong();
        }
      }
      try (CompoundDirectory cfs = si.getCodec().compoundFormat().getCompoundReader(dir, si)) {
        // javadoc: FileName is "that file's name"; written: the name without the segment name
        assertEquals("FileName values", new TreeSet<>(Arrays.asList(cfs.listAll())), fileNames);
      }
    }
  }
}
cp TestLucene90CompoundEntriesJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90CompoundEntriesJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- The documented grammar ends at the end of
_0.cfe, and the FileName values are the compound file's names_0.fdm,_0.fdt,_0.fdx,_0.fnm. - Observed
bytes after the documented grammar expected:<0> but was:<16>andFileName values expected:<[_0.fdm, _0.fdt, _0.fdx, _0.fnm]> but was:<[.fdm, .fdt, .fdx, .fnm]>; the same with assertions off and on 10.6.0.
More files, environment, full output289 words
- The test sits in the codec package, like Lucene's own codec tests;
Lucene90CompoundEntriesis the class'sENTRY_CODEC(:79). Both methods skip the IndexHeader, read FileCount and the entries exactly as the grammar says, then compare with the real file: the first checks that nothing is left, the second compares the names with the compound directory'slistAll(). - Two methods, because the javadoc makes two independent wrong statements; both read the same one-document segment.
- Results: fails 2 of 2 on main with assertions on and off, standalone (2.59 s) and through gradle, and on the published 10.6.0 jars; 5 random-seed iterations fail 10 of 10 with the same messages. The hunt's and the verifiers' larger tests also fail on 10.5.2, 9.12.3 and the
branch_10_6head. On 9.x the test needs the 3-argumentgetCompoundReader(dir, si, IOContext.DEFAULT). - As a regression test: this test cannot guard the javadoc, because it transcribes the grammar. A form that pins down the corrected layout is this same test with its two assertions following the corrected grammar (
CodecUtil.checkFooterafter the last entry; names compared withstripSegmentNameoflistAll()), the fix check below.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same test also fails on the published 10.6.0 jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestLucene90CompoundEntriesJavadoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90CompoundEntriesJavadoc -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestLucene90CompoundEntriesJavadoc > testFileNameIsTheFileName FAILED
    java.lang.AssertionError: FileName values expected:<[_0.fdm, _0.fdt, _0.fdx, _0.fnm]> but was:<[.fdm, .fdt, .fdx, .fnm]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:F6E6066DC01DD8C4]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.apache.lucene.codecs.lucene90.TestLucene90CompoundEntriesJavadoc.testFileNameIsTheFileName(TestLucene90CompoundEntriesJavadoc.java:76)

TestLucene90CompoundEntriesJavadoc > testEntryTableEndsAfterLastEntry FAILED
    java.lang.AssertionError: bytes after the documented grammar expected:<0> but was:<16>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:DDD941FE5F8B8BCF]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.codecs.lucene90.TestLucene90CompoundEntriesJavadoc.testEntryTableEndsAfterLastEntry(TestLucene90CompoundEntriesJavadoc.java:57)

2 tests completed, 2 failed- The
.cfsline right above lists its Footer; so does every explicit whole-file production in the core codecs but.liv. - 4.8.0-4.10.4 listed the
.cfeFooter; a 2014 bulk backport replaced that line with trunk text that lacked it. - "That file's name" was true until 3.1 (LUCENE-2455), when the writer started stripping the segment name; the sentence was not updated.
The full argument177 words
- The line above.
.cfs --> Header, FileData^FileCount, Footer(:49), with its ownFootertype line (:57); both files get a footer in the same method (:106-107). - Convention. Every other explicit whole-file production (
(.ext) --> ...) in the core codecs names its Footer, for example the norms metadata and data files (Lucene90NormsFormat.java:46,:71),.tvd/.tvx(Lucene90TermVectorsFormat.java:82,:157),.fnm,.si, the terms dictionary, postings andsegments_N; the only other production without it is.liv(LFV-970). Formats documented in prose or as file lists (doc values, points, stored fields, vectors) have no such production to compare. - History. 4.8.0-4.10.4 listed the Footer on the
.cfeline; it was lost when LUCENE-5944 replaced the 4.x text with the trunk text, which had it on the.cfsline instead. No issue or review discusses it. - FileName. The sentence describes the pre-3.1 writer, which stored the full name; LUCENE-2455 changed the writer and not the sentence.
- The contract.
lucene104/package-info.java:50and:188(quoted under "Who is affected").
The devil's-advocate check304 words
Strongest case for "intended" (made by the refute reviewer, the intended-lens reviewer and the devil's-advocate verifier; the cross-model reviewers rated it moderate): the overview's History says "checksum footers were added to the end of each index file" since 4.8 (package-info.java:381-383), dev-docs/file-formats.md:80-84 says to add headers and footers to all files and TestAllFilesHaveChecksumFooter checks every file, .cfe included, so a per-file grammar need not repeat the footer; the overview calls itself "a high-level definition" (:54); the reader calls the stored string an id (Lucene90CompoundReader.java:144); and CompoundFormat is @lucene.experimental (CompoundFormat.java:28). The .cfs production is not byte-complete either: the 64-byte alignment padding between sub-files is only in the Notes prose. Under the generous footer reading the documented grammar parses all 87 .cfe files of the hunt's sweep.
Why it fails: under that reading the .cfs Footer on the line above would be redundant too, and the explicit whole-file productions in the core codecs do not leave the footer out; the explicit .cfs line invites a literal reading of the .cfe line. "High-level" allows leaving detail to prose, as the .cfs alignment is, not a production that ends 16 bytes early with no prose mentioning those bytes. The id reading conflicts with the plain words "that file's name", which date from when the full name was stored, and the FileName part does not depend on the footer convention at all. @lucene.experimental is about API stability. Committers edited this block twice (LUCENE-10019, #15341) and only touched the alignment note, so that is not an acceptance decision. The generous reading lowers the severity of the footer part; it does not make the text right. The final verdicts of all verifiers and the adjudication kept the defect (the cross-model review with medium confidence), with the intended argument rated moderate by the cross-model reviewers.
Recommended A. Add the Footer, say what FileName holds, drop the unused Checksum
Javadoc only: add , Footer to the .cfe production, describe FileName as the file name without the segment name (for example .fnm for _0.fnm), and drop the unused Checksum from the type line (cleanup). Validated: the test rewritten to the corrected grammar passes, TestLucene90CompoundFormat passes and :lucene:core:check -x test is clean.
All options and trade-offs3 options · 880 words
Two ways to correct the text; A was validated. Backport: the javadoc lines are the same on branch_10_6 (2 lines higher), so the same text change applies there if wanted; main and branch_11x are the usual targets.
A. Add the Footer, say what FileName holds, drop the unused Checksum (validated by the checks) (recommended)
, Footer at the end of the .cfe production; the type line DataOffset,DataLength --> UInt64; FileName --> String, the file name without the segment name (for example .fnm for _0.fnm); and the same words in the Notes sentence. Javadoc only, one file, 7 lines in and 5 out; the Notes sentence is reflowed the way google-java-format wants it.
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java
@@ -48,11 +48,12 @@
* <ul>
* <li>Compound (.cfs) --> Header, FileData <sup>FileCount</sup>, Footer
* <li>Compound Entry Table (.cfe) --> Header, FileCount, <FileName, DataOffset,
- * DataLength> <sup>FileCount</sup>
+ * DataLength> <sup>FileCount</sup>, Footer
* <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>FileCount --> {@link DataOutput#writeVInt VInt}
- * <li>DataOffset,DataLength,Checksum --> {@link DataOutput#writeLong UInt64}
- * <li>FileName --> {@link DataOutput#writeString String}
+ * <li>DataOffset,DataLength --> {@link DataOutput#writeLong UInt64}
+ * <li>FileName --> {@link DataOutput#writeString String}, the file name without the segment
+ * name (for example <code>.fnm</code> for <code>_0.fnm</code>)
* <li>FileData --> raw file data
* <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
* </ul>
@@ -63,8 +64,9 @@
* <li>FileCount indicates how many files are contained in this compound file. The entry table
* that follows has that many entries.
* <li>Each directory entry contains a long pointer to the start of this file's data section, the
- * files length, and a String with that file's name. The start of file's data section is
- * aligned to 64 bytes to not introduce additional unaligned accesses with mmap.
+ * files length, and a String with that file's name without the segment name. The start of
+ * file's data section is aligned to 64 bytes to not introduce additional unaligned accesses
+ * with mmap.
* </ul>
*/
public final class Lucene90CompoundFormat extends CompoundFormat {Trade-offs
- The corrected text was checked against real files: the writer's layout parses all 87
.cfefiles of the hunt's 91 generated indexes, all 1720 entries hold the stripped name, and the corrected text, extracted from the patched javadoc, parses all 38.cfefiles of a second 41-configuration sweep. - Dropping
Checksumis cleanup: the linked CodecFooter grammar defines it. Optional extra: the Notes list the entry parts as pointer, length, name, while the grammar order is FileName, DataOffset, DataLength; the sentence could follow the grammar order (not in the diff).
What the checks validated
Gradle in a scratch worktree of 645d4fe14a20 (seed DEADBEEF, 2026-11-01), two runs. Stock: the minimal repro fails 2 of 2 with assertions on and off. Run 2, the diff shown (fix A): the same test following the corrected grammar (CodecUtil.checkFooter after the last entry; names compared with stripSegmentName of listAll()) passes 2 of 2 with assertions on; TestLucene90CompoundFormat passes (36 tests, 0 failures, 1 nightly-only test skipped); :lucene:core:check -x test (google-java-format, ecj lint, forbidden APIs) succeeds. Run 1, on the hunt's text, which has the same grammar lines and differs only in the line breaks of the Notes sentence: the same test also passes with assertions off, TestLucene90CompoundFormat passes and :lucene:core:renderJavadoc renders the corrected grammar, but google-java-format failed on those line breaks, hence the reflowed diff. Option B passes google-java-format (run 2). The verbatim repro keeps failing with the fix, by design: it transcribes the old grammar, and the fix changes no code.
, Footer on the .cfe line and the FileName wording (type line and note), keeping Checksum on the type line.
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java
@@ -48,11 +48,12 @@
* <ul>
* <li>Compound (.cfs) --> Header, FileData <sup>FileCount</sup>, Footer
* <li>Compound Entry Table (.cfe) --> Header, FileCount, <FileName, DataOffset,
- * DataLength> <sup>FileCount</sup>
+ * DataLength> <sup>FileCount</sup>, Footer
* <li>Header --> {@link CodecUtil#writeIndexHeader IndexHeader}
* <li>FileCount --> {@link DataOutput#writeVInt VInt}
* <li>DataOffset,DataLength,Checksum --> {@link DataOutput#writeLong UInt64}
- * <li>FileName --> {@link DataOutput#writeString String}
+ * <li>FileName --> {@link DataOutput#writeString String}, the file name without the segment
+ * name (for example <code>.fnm</code> for <code>_0.fnm</code>)
* <li>FileData --> raw file data
* <li>Footer --> {@link CodecUtil#writeFooter CodecFooter}
* </ul>
@@ -63,8 +64,9 @@
* <li>FileCount indicates how many files are contained in this compound file. The entry table
* that follows has that many entries.
* <li>Each directory entry contains a long pointer to the start of this file's data section, the
- * files length, and a String with that file's name. The start of file's data section is
- * aligned to 64 bytes to not introduce additional unaligned accesses with mmap.
+ * files length, and a String with that file's name without the segment name. The start of
+ * file's data section is aligned to 64 bytes to not introduce additional unaligned accesses
+ * with mmap.
* </ul>
*/
public final class Lucene90CompoundFormat extends CompoundFormat {Trade-offs
Fixes both wrong statements and leaves the redundant Checksum entry for a reader to puzzle over.
What the checks validated
Not built or tested (the diff applies cleanly on 645d4fe14a20 and passes checkGoogleJavaFormat, run 2).
Leave the .cfe line as is, because the overview says every index file ends with a footer.
Trade-offs
Keeps the .cfe line inconsistent with the .cfs line beside it and does nothing for the FileName wording.
What the checks validated
Not run.
Not security-sensitive; it matters only to third-party tools that read or write .cfe files themselves from this javadoc, which would stop 16 bytes early or look up the wrong names.
Semi-formal: a grammar check extracted the .cfe production and its type list from the javadoc and interpreted it over the bytes of 87 real .cfe files from 91 generated default-codec indexes, with each segment's compound directory as the oracle. All 87 ended 16 bytes early and all 1720 entries held the stripped name; the writer's real layout parsed all 87.
The method in full169 words
- The check extracts the
.cfeand.cfsproductions and the shared type list mechanically from the javadoc source, checks them for well-formedness (it reports the unused definitionChecksum) and interprets them over the real bytes of each compound segment. The oracle is the segment'sCompoundDirectory: entry count, every FileName resolving to an inner file, DataLength equal to the inner file length, 64-byte aligned DataOffset. - Inputs: 91 indexes (11 fixed and 80 seeded random configurations), 87 compound segments, the same results with assertions on and off.
- Positive control: the writer-layout grammar (the proposed fix text) parses all 87
.cfefiles. Vacuity: 3 of 3 layout mutants (footer dropped, DataLength dropped, DataOffset/DataLength swapped) are killed. The.cfsproduction parses all 87.cfsfiles. Fix check: the corrected text parses 38 of 38 files in a second sweep. - The unit's starting lead was a probe that saw 16 bytes after the documented grammar. This is a differential grammar check of documentation against real output, not model checking or a proof.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-28, rechecked 2026-11-01). Nearest: LUCENE-2446 (#3520), which made the line wrong, and LUCENE-2455 (#3529), which introduced the stripped names. Not fixed upstream.
Searches3 searches
- Related, not this bug: #3520 (LUCENE-2446; no comment on the compound javadoc); #7006 (LUCENE-5944, the bulk backport); #7031 (LUCENE-5969) and #10744 / apache/lucene-solr#2268 (LUCENE-9705), which copied the text forward; #3529 (LUCENE-2455, the stripped names and why); #203 (LUCENE-10019) and #15341, which edited the alignment note of the same bullet and never mention the grammar.
- Outside parsers, not reports: kaitai-io/kaitai_struct_formats#407 (a 2021 draft
.cfedescription that cites the Lucene50 javadoc but ends with a codec footer) and a 2018 gist that guards on end of file and handles leading-dot names. Neither says the javadoc is wrong or was reported to Lucene. - Not fixed upstream: the file is byte-identical on upstream main
f815e679bf6c(2026-11-01) andbranch_11x;branch_10_6has the same javadoc lines. No open PR changes a compound file; the open javadoc PR #16949 touches nolucene90file. Tracking issue #16937 does not name it.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene and apache/lucene-solr issues, PRs and commits; the JIRA archive; downstream repositories | 2026-10-28 | three scripted prior-report searches (footer, FileName, file-format docs: 72 issue/PR, 9 commit and 6 downstream queries); 43 more searches over apache/lucene, the main downstream repositories and the global index; the changed files of all 413 open PRs; the file's history on main, branch_10x and branch_10_6 | no report; only the commits that made or copied the text |
| Mailing lists, JIRA and web | 2026-10-28 | dev@, java-user@, issues@ and commits@ (60 scripted queries) and 12 scripted JIRA-archive queries; 6 more JIRA and 13 web searches | no report; two outside parsers that worked around the text |
| apache/lucene (recheck) | 2026-11-01 | the file's blob on upstream main, branch_11x and branch_10_6; its commits; issues and PRs updated since 2026-10-28 for 10 terms (Lucene90CompoundFormat, CompoundFormat javadoc, cfe footer, compound entry table, stripSegmentName, ...); the changed files of the 39 open PRs updated since then; #16949; #16937 and its comments | no report; the file is unchanged upstream |
Footer part since 5.0.0: LUCENE-2446 (2014) put the Footer on the .cfs line, not the .cfe line, on trunk, and a bulk backport carried that text into 5.0. FileName part since 4.0.0. Affects 5.0.0 to 10.6.0 and main; 4.8.0-4.10.4 listed the .cfe Footer.
Versions tested7 rows
- Origin (footer):
c189d0fb74d(LUCENE-2446 "add checksums to index files", #3520, Robert Muir, 2014-04-01, trunk; JIRA patch era, no PR):writeFooterfor both compound files,, Footeron the.cfsline only,Checksumon the type line. The branch_4x backport819eda82e33(2014-04-02) put, Footeron the.cfeline instead. - Released:
55594bad9b0(LUCENE-5944, #7006, 2014-09-18), the branch_5x bulk backport of trunk, replaced the correct 4.x line: first affected release 5.0.0. Copied by LUCENE-5969 (af3e1d1c4b15/33bdf278cba,Lucene50CompoundFormat) and LUCENE-9705 (eafeb664340, apache/lucene-solr#2268,Lucene90CompoundFormat, 9.0.0). - FileName: stale since LUCENE-2455 (
06b82e04ee9/d6dd2e234e1, May 2010, 3.1); in the public format docs since25a59d8902e/49b3257d451(2012-06-11), first release 4.0.0. - Later edits of the block (LUCENE-10019, #15341) changed only the alignment note.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails, both parts, with assertions on and off (standalone and gradle) |
10.6.0 (published jars, 4ae946e5a9b) | affected | the minimal test fails, both parts |
main a9779ef3c193, branch_10_6 head, 10.5.2, 9.12.3 | affected | the finder's and the independent reproduction's tests fail, both parts |
| 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 | affected | the history probe fails, both parts (each release's own documented grammar) |
| 4.8.0, 4.10.4 | partly | footer part clean (the .cfe line lists the Footer); FileName part fails |
| 4.0.0, 4.7.2 | partly | footer part clean (no footer written or documented); FileName part fails |
| main with the corrected text | fix | the history probe's fixed-javadoc control passes |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication (high confidence); a credibility audit confirmed it as a minor documentation defect. This doc re-ran the repro and validated the fix.
Checks and verdicts334 words
Every check either re-ran a repro on main or read the same lines; none found a reading under which the grammar is right as written.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, refute lens (OpenAI GPT-5.6, executing) | real, high confidence | Its own 4-test check failed the documented production and the FileName meaning, with 2 controls passing (one seed with assertions on, one off). Intended argument moderate; its correction (dropping Checksum is cleanup) was accepted. |
| independent reproducer | real | Its own test (3 documents) fails 2 of 3 on main (assertions on and off), 10.5.2 and 9.12.3 ("ends at byte 565 of 581 expected:<0> but was:<16>"; "FileName '.nvd' is not the name of a sub-file"); its control shows the 16 trailing bytes are exactly one valid codec footer. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium confidence | It could not run code, so it only read; a separate run re-ran the finder's test on main, failing as stated. |
| intended-behaviour devil's advocate | real (documentation defect) | Built and rejected the global-footer, "high-level", id and @lucene.experimental readings; corrected the history (footer part 5.0.0, not 4.8); re-ran on main and 10.5.2. |
| adjudication | confirmed, high confidence, documentation | Re-ran the independent reproduction's test and the finder's on new seeds and checked the 4.10.4 and 5.0.0 sources. |
| credibility audit | confirmed, minor | Re-ran the finder's test on a new seed; "Correct but trivial": a javadoc fix that would merge without fuss. |
| this doc's validation (2026-11-01) | fix A validated | Stock main: the minimal repro fails 2 of 2 with assertions on and off (gradle). With fix A (run 2): the test following the corrected grammar passes with assertions on, TestLucene90CompoundFormat passes (36 tests, 1 nightly-only skipped) and check -x test is clean. Run 1, on the hunt's text (the same grammar lines, other Notes line breaks): the same test also passes with assertions off and the javadoc renders; google-java-format failed on those line breaks, so the final diff is reflowed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 437 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,508 words
- Registry title
- The file-format javadoc of the default compound format (Lucene90CompoundFormat) gives an incomplete .cfe entry-table grammar: it leaves out the codec footer the writer appends (the .cfs line beside it lists one), and it says each entry holds the file's name although the writer stores the name with the segment name stripped (documentation defect; the writer and reader agree)
- Area
- codecs / compound files (Lucene90CompoundFormat .cfe file-format javadoc vs the Lucene90CompoundFormat writer / Lucene90CompoundReader)
- Priority
- Low, rank 1285: The .cfe grammar leaves out the footer, which the package-level footer rule partly covers, and misstates the stored names; it is documentation only.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so indexing, merging, CheckIndex and search are unaffected in every configuration; the people misled are those who read, inspect or re-implement the .cfe format from this class javadoc (the default codec's file-format overview links it as the Compound File format), and a parser that follows the text stops 16 bytes before the end of every .cfe file and takes stored names such as '.nvd' for full file names (executed); compound files are written by default (IndexWriterConfig.DEFAULT_USE_COMPOUND_FILE_SYSTEM = true), the footer has been missing from the grammar in every release since 5.0.0 and the FileName wording has been wrong since 4.0.0, and no scale or special setting is needed.
- Summary
- You decode the compound entry table (.cfe) of a default-codec segment by following the Lucene90CompoundFormat javadoc, which says the file is Header, FileCount and then FileCount entries of FileName, DataOffset, DataLength, each holding 'a String with that file's name'. The writer also appends a 16-byte codec footer (the .cfs line just above lists its Footer, the .cfe line does not) and stores each name with the segment name stripped, for example '.nvd' for _0.nvd, so a parser built from the text ends 16 bytes early (byte 134 of 150 in the minimal repro, byte 502 of 518 in the hunt's 20-document test) and cannot find the sub-files by the names it read. Lucene's own reader checks the footer and puts the segment name back, so nothing breaks at runtime; only the documentation is wrong (the type line also lists an unused 'Checksum', which belongs to the linked CodecFooter grammar, so dropping it is cleanup).
- Introduced
- Missing .cfe Footer (the main part): c189d0fb74dd1632c18d7c87d490516ff08b3fae (trunk, LUCENE-2446 'add checksums to index files', migrated as apache/lucene#3520; JIRA patch era, no PR) added CodecUtil.writeFooter to the .cfe writer and ', Footer' to the .cfs line only (plus 'Checksum' to the type line); the branch_4x backport 819eda82e33 put the Footer on the .cfe line instead, so 4.8.0-4.10.4 documented it. It reached the release line with 55594bad9b07af90de4ab2a2fb0bac8e8c2b0b3c (branch_5x, LUCENE-5944 bulk backport of trunk, apache/lucene#7006), which replaced the 4.x text with the trunk text; carried forward by LUCENE-5969 (apache/lucene#7031, 5893b1da299, Lucene50CompoundFormat) and LUCENE-9705 (apache/lucene-solr#2268, eafeb664340, Lucene90CompoundFormat). FileName wording: the writer stores stripSegmentName(file) since LUCENE-2455 (d6dd2e234e1 trunk / 06b82e04ee9 branch_3x, 2010), after which the older 'that file's name' sentence was stale; 25a59d8902e / 49b3257d451 ('merge/cleanup outdated javadocs', 2012-06-11) moved it into the public CompoundFileDirectory javadoc that the format overview links [read: git show in the full-history clone; exec: history probe boundary 4.10.4 not affected / 5.0.0 affected for the footer part] (2014-04-01 (author date of c189d0fb74d on trunk); 2014-09-18 (author date of 55594bad9b0, the release-line commit); FileName part: 2010-05-26/27 (LUCENE-2455) and 2012-06-11 (moved into the public format docs))
- First affected version
- 5.0.0 [exec] for the missing .cfe Footer (the last unaffected release is 4.10.4 [exec]: 4.8.0-4.10.4 list the Footer on the .cfe line; 4.0.0-4.7.2 wrote no footer, so their footer-less line was right); FileName wording 4.0.0 [exec] in the public format docs (3.1 in an internal class javadoc [read]); 9.0.0 [exec] is the first release of Lucene90CompoundFormat
- Affected versions
- every release from 5.0.0 through 10.6.0 (the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; FileName part also 4.0.0-4.10.4; not fixed upstream (main 645d4fe14a20 on 2026-10-28 has the same text) [exec: a version-independent history probe that parses a real .cfe with each release's own documented production fails the footer part on 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) and passes it on 4.0.0, 4.7.2, 4.8.0 and 4.10.4, and fails the FileName part on all 13 releases and main; the same probe with the fixed javadoc text passes on main; the finder's JUnit fails 2 of 3 on main (-ea and -da), the branch_10_6 head, 10.5.2 and 9.12.3 (9.x API variant), with its writer-layout control passing; the independent reproduction's JUnit fails 2 of 3 on main (-ea and -da), 10.5.2 and 9.12.3; read: the releases in between from the tags; branch_10x and branch_10_6 text read on GitHub]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: three scripted prior-report searches (footer, FileName, file-format docs: 72 GitHub issue/PR queries, 9 commit queries, 6 downstream-repo queries, 60 mailing-list queries over dev@, java-user@, issues@ and commits@, 12 JIRA-archive queries), 43 more issue/PR searches over apache/lucene, the main downstream repositories and the global index, 6 JIRA and 13 web searches; all 413 open apache/lucene PRs checked by changed files, and the PRs updated since 2026-10-26; the file's history on main, branch_10x and branch_10_6 by author date). Nearest items, not the same bug: #3520 / LUCENE-2446 (the change that made the .cfe line wrong; no comment on the compound javadoc), #7031 / LUCENE-5969 and #10744 / LUCENE-9705 with apache/lucene-solr#2268 (copied the text forward), #3529 / LUCENE-2455 (introduced the stripped names), #203 / LUCENE-10019 and #15341 (edited the alignment note of the same bullet, merged 2026-01-08, never mention the grammar); outside .cfe parsers (a 2021 draft format description, kaitai-io/kaitai_struct_formats#407, and a 2018 gist) worked around the text without reporting it. Recheck (2026-10-28): 'Lucene90CompoundFormat', 'CompoundFormat javadoc', 'cfe footer', 'Compound Entry Table', 'compound file javadoc', 'stripSegmentName' and 'cfe javadoc' return only old unrelated items; none of the issues and PRs created since 2026-10-26 is about it; of the 50 open PRs updated since then only #16911 (deletes the whole branch_10x tree, including the backward-codecs Lucene50CompoundFormat; not a fix) and #16480 (a package-info History bullet) touch a matching file; upstream main 645d4fe14a20 still has the text, last changed by 25e381bb7a1a (#15341, author date 2026-01-08). Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone and through gradle, and a byte probe of the same index; the recommended fix in a scratch worktree (the same test following the corrected grammar, the closest compound-format suite and:lucene:core:check -x test; assertions off and:lucene:core:renderJavadocon the hunt's text, which differs only in the line breaks of the Notes sentence). The minimal repro on the published 10.6.0 jars. The hunt's and the verifiers' tests on maina9779ef3c193(the same file),4ae946e5a9b(the 10.6.0 tag commit, then thebranch_10_6head), 10.5.2 and 9.12.3; the history probe on 13 releases from 4.0.0 to 10.5.2.Lucene90CompoundFormat.javais byte-identical on645d4fe14a20, upstream mainf815e679bf6c(2026-11-01) andbranch_11x; thebranch_10_6head91eaab4fb298and 10.6.0 have the same javadoc, 2 lines higher (read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java:49 ('.cfs --> Header, FileData^FileCount, Footer'), :50-51 ('.cfe --> Header, FileCount, <FileName, DataOffset, DataLength>^FileCount', no Footer), :54 ('DataOffset,DataLength,Checksum --> UInt64'), :55 (FileName --> String), :57 (Footer --> CodecFooter), :65-67 ('a String with that file's name'), :107 (CodecUtil.writeFooter(entries)), :117 (writeVInt FileCount), :153-155 (writeString(IndexFileNames.stripSegmentName(file)), writeLong offset, writeLong length); Lucene90CompoundReader.java:133 (CodecUtil.checkFooter of the entries), :144 (readString id), :171 and :235 (lookups by stripSegmentName); read 2026-10-28lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:54 ('a high-level definition'), :188 ('Details on each of these are provided in their linked pages'), :237 (links Lucene90CompoundFormat as 'Compound File'), :381-383 (since 4.8 checksum footers at the end of each index file); CodecUtil.java:397-404 (CodecFooter --> Magic,AlgorithmID,Checksum); index/IndexWriterConfig.java:99 (DEFAULT_USE_COMPOUND_FILE_SYSTEM = true); dev-docs/file-formats.md:80-82 (headers and footers on all files); lucene/core/src/test/org/apache/lucene/index/TestAllFilesHaveChecksumFooter.java
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java (lines 49-67 the javadoc; 95-109 write; 113-157 writeCompoundFile; 102 header, 106-107 footers, 117 FileCount, 153-155 entry)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundReader.java (lines 133 checkFooter, 139-147 readMapping, 171 and 235 lookups by stripSegmentName, 222 listAll adds the segment name)lucene/core/src/java/org/apache/lucene/index/IndexFileNames.java (lines 133-144 stripSegmentName)lucene/core/src/java/org/apache/lucene/codecs/CodecUtil.java (line 396 CodecFooter grammar)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 188, 195, 237)lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java (lines 96-99)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundReader.java (line 133)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90CompoundFormat.java (lines 49, 57, 106-107), lucene90/Lucene90NormsFormat.java (46, 71), lucene90/Lucene90TermVectorsFormat.java (82, 157), CompoundFormat.java (28), lucene104/package-info.java (50, 54, 188, 381-383), lucene90/Lucene90CompoundReader.java (144)dev-docs/file-formats.md (lines 80-84) and lucene/core/src/test/org/apache/lucene/index/TestAllFilesHaveChecksumFooter.java
- TestLucene90CompoundEntriesJavadoc.java (JUnit, one class, one method per wrong statement):
repro/LFV-971/src/org/apache/lucene/codecs/lucene90/TestLucene90CompoundEntriesJavadoc.java(80 lines)
Made from the code at 645d4fe14a20 and an executed probe of the repro's index, in parallel with this doc.
assets/LFV-971/bug.png(437 KB)