The table that maps file extensions to formats in the File Formats overview has not kept up with the default codec since 8.5.0.
- A Lucene segment is a set of files that share a name and differ by extension; each format of the codec writes its own files, for example
.timfor the terms dictionary. Small segments are packed into one compound.cfsfile; by default, merged segments above 64 MB stay separate files. - The default codec's package documentation, the File Formats overview, has a "Summary of File Extensions" table: one row per kind of file, its extensions, a short description and a link to the format page with the details.
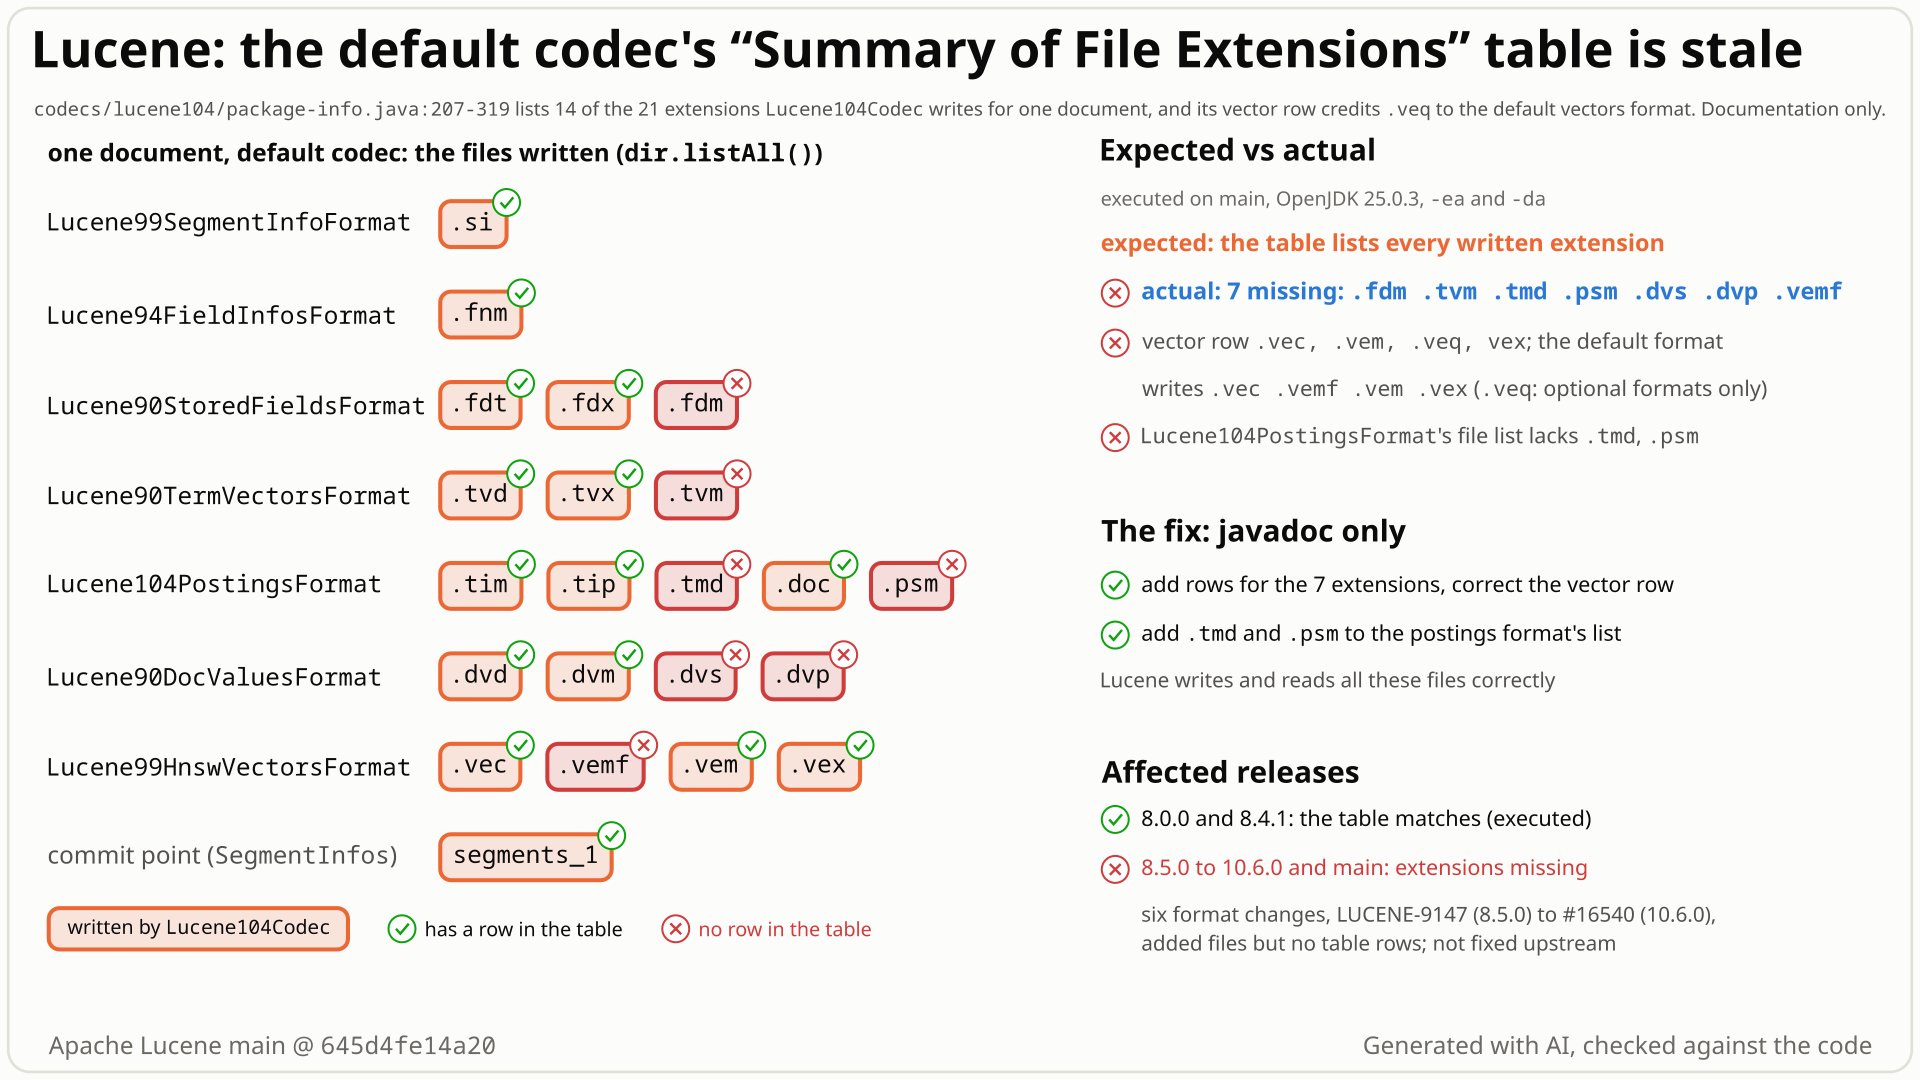
.veq and an undotted vex where the default format writes .vemf and .vex. Select the still to open it at full size. Generated with AI, checked against the code.- You index one document with a stored field with term vectors, a numeric doc-values field and a 2-dimensional vector, with the default codec and no compound file. The directory gets 21 segment files with 21 different extensions.
- You look each extension up in the File Formats overview's "Summary of File Extensions" table, which "summarizes the names and extensions of the files". It lists 25 extensions, including the metadata files
.nvm,.dvm,.kdmand.vem, so you expect all 21 there. - 7 are missing:
.fdm,.tvm,.tmdand.psm(stored-fields, term-vectors, terms and postings metadata),.dvsand.dvp(doc-values skip index and presence data) and.vemf(vector metadata). - The vector row says
.vec, .vem, .veq, vex; the default vector format wrote.vec,.vem,.vemfand.vex..veqcomes only from the optional quantized formats, andvexlacks its dot. The postings format's own file list also omits.tmdand.psm. - Why: since 8.5.0 (2020), six format changes each added a file and documented it at most on its own format page, never in this table.
People and tools that learn a segment's files from the overview: someone sizing an index by file type, a backup or copy tool that picks files by extension, a format port. Default codec, ordinary documents; the files show for non-compound segments (by default, merged segments above 64 MB). Lucene and its searches are unaffected.
Mechanism, terms and numbers582 words
The default codec's package documentation (codecs/lucene104/package-info.java, the File Formats overview) says it "defines the index file formats used in this version of Lucene" (:50), and its "Summary of File Extensions" table "summarizes the names and extensions of the files in Lucene" (:211, table :213-319). The table lists the metadata files of norms, doc values, points and vectors (.nvm, .dvm, .kdm, .vem) but not seven extensions the default codec writes for ordinary documents: .fdm, .tvm, .tmd, .psm, .dvs, .dvp and .vemf.
Its vector row (:312-318) links the default Lucene99HnswVectorsFormat and reads .vec, .vem, .veq, vex: that format writes .vec, .vemf, .vem and .vex, .veq comes only from the optional scalar-quantized formats, and vex has no dot. The default postings format's "Files and detailed format" list (Lucene104PostingsFormat.java:81-89) names .tim, .tip, .doc, .pos and .pay but not the .tmd and .psm files the same format writes.
Lucene writes, reads, merges and checks all these files correctly; nothing reads the table at runtime. The table matched the codec through 8.4.1. None of the six format changes since 8.5.0 (2020) that added the missing files put them in the table: five touched no package-info.java, and #13585 copied the whole table into its new lucene912 package without a .psm row. The vector row's current text was written by #12582 (9.9.0), when the HNSW format could still write .veq; from 9.0.0 through 9.8.0 the row read .vec, .vem and lacked .vex. Documentation only; the fix is javadoc text.
A stored StringField with term vectors, a NumericDocValuesField and a 2-dimensional KnnFloatVectorField give 22 files: segments_1 and 21 segment files.
| written | in the table? | written by (constant, file:line) | on its own format page |
|---|---|---|---|
.si, .fnm, .fdt, .fdx, .tvd, .tvx, .tim, .tip, .doc, .dvd, .dvm, .vec, .vem | yes | ||
.vex | as vex, without the dot | Lucene99HnswVectorsFormat.java:90 | |
.fdm | no | Lucene90CompressingStoredFieldsWriter.java:67, created :131-132 | Lucene90StoredFieldsFormat.java:92 |
.tvm | no | Lucene90CompressingTermVectorsWriter.java:69, created :259-260 | Lucene90TermVectorsFormat.java:54 |
.tmd | no (nor in the postings list) | Lucene103BlockTreeTermsReader.java:84, created Lucene103BlockTreeTermsWriter.java:321-324 | Lucene103BlockTreeTermsWriter.java:91, :147 |
.psm | no (nor in the postings list) | Lucene104PostingsFormat.java:325, created Lucene104PostingsWriter.java:153 | only the constant's one-line javadoc |
.dvs, .dvp | no | Lucene90DocValuesFormat.java:195, :197; both created for every segment with doc values (Lucene90DocValuesConsumer.java:110, :120) | Lucene90DocValuesFormat.java:135-136 |
.vemf | no | Lucene99FlatVectorsFormat.java:81; the HNSW format always uses this flat format (Lucene99HnswVectorsFormat.java:155-156) | Lucene99FlatVectorsFormat.java:48 |
With compound files the directory holds only _0.cfe, _0.cfs, _0.si and segments_1, all listed.
It links Lucene99HnswVectorsFormat, the default (Lucene104Codec.java:123), with the cell .vec, .vem, .veq, vex and the text ".vem the vector metadata, .veq the quantized vector data, and .vex the hnsw graph data". In lucene/core, .veq (with .vemq) is defined only by the optional Lucene104ScalarQuantizedVectorsFormat (:107-108); the read-only backward-codecs Lucene99ScalarQuantizedVectorsFormat (:53-54) defines the same two for old indexes. The default format writes .vec and .vemf through its flat format and .vem and .vex itself (:89-90).
"Files and detailed format:" .tim, .tip, .doc, .pos, .pay. The format also writes .psm and, through its terms dictionary (:410-413), .tmd; .tim and .tip, also terms-dictionary files, are listed.
Exposure and likelihood274 words
- Who is hit. Anyone who looks an index file up in the File Formats overview, or builds on it: sizing an index by file type, a backup, copy or inspection tool that selects files by extension, a port of the format. Lucene users who only call its APIs are unaffected, and Lucene's own file lists (
SegmentInfo.files(), the commit's file names) are correct. - Default vs opt-in. The default codec and ordinary documents:
.fdm,.tmdand.psmare written for nearly every segment (stored fields and postings),.dvsand.dvpfor every segment with doc values,.vemffor every segment with vectors,.tvmwith term vectors. - When the files are visible. Flushed segments are compound by default (
IndexWriterConfig.java:99,DocumentsWriterPerThread.java:643), but a merge writes any segment above 64 MB as separate files (CompoundFormat.java:42,:163-179; the defaultTieredMergePolicymeasures bytes,MergePolicy.java:598-600). So any default index with a merged segment above 64 MB shows them in its directory. - Scale. None needed: one document shows 7 of 21 extensions unlisted.
- What it does not do. No wrong results, no index change, no runtime path. Every missing file except
.psmis documented on its own format page, though not every such page is reachable from the table:.tmd's page (Lucene103BlockTreeTermsWriter) is one link away from the table's postings link, and.vemf's page (Lucene99FlatVectorsFormat) cannot be reached from the vector row's link, whose page links only the abstractFlatVectorsFormat(Lucene99HnswVectorsFormat.java:41). The searches found no report of it although it dates from 8.5.0 (2020), which suggests the audience is small. Impact class minor, priority low.
One JUnit test indexes one document (a stored field with term vectors, a numeric doc-values field, a 2-dimensional vector) with the default codec into a non-compound directory and looks every written extension up in a verbatim copy of the table's 25 extensions. Deterministic, single thread, about 1.7 s; the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene104;

import java.util.Set;
import java.util.TreeSet;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.IndexFileNames;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestLucene104ExtensionTable extends LuceneTestCase {

  private static final Set<String> SUMMARY_OF_FILE_EXTENSIONS_TABLE =
      Set.of(
          "si", "cfs", "cfe", "fnm", "fdx", "fdt", "tim", "tip", "doc", "pos", "pay", "nvd", "nvm",
          "dvd", "dvm", "tvx", "tvd", "liv", "kdd", "kdi", "kdm", "vec", "vem", "veq", "vex");

  public void testTableListsEveryExtensionTheDefaultCodecWrites() throws Exception {
    FieldType storedWithTermVectors = new FieldType(StringField.TYPE_STORED);
    storedWithTermVectors.setStoreTermVectors(true);
    Document doc = new Document();
    doc.add(new Field("id", "1", storedWithTermVectors));
    doc.add(new NumericDocValuesField("dv", 1));
    doc.add(new KnnFloatVectorField("vector", new float[] {1, 2}));
    Set<String> missing = new TreeSet<>();
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setCodec(new Lucene104Codec()).setUseCompoundFile(false);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        w.addDocument(doc);
      }
      for (String file : dir.listAll()) {
        String extension = IndexFileNames.getExtension(file);
        if (file.startsWith(IndexFileNames.SEGMENTS) == false
            && SUMMARY_OF_FILE_EXTENSIONS_TABLE.contains(extension) == false) {
          missing.add(extension);
        }
      }
    }
    // expected: the table lists every written extension; actual: 7 extensions are missing
    assertEquals("written extensions missing from the extensions table", Set.of(), missing);
  }
}
cp TestLucene104ExtensionTable.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene104/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene104.TestLucene104ExtensionTable -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- Every extension the document writes is in the table: the set of missing extensions is empty.
- Observed
expected:<[]> but was:<[dvp, dvs, fdm, psm, tmd, tvm, vemf]>, with assertions on and off.
More files, environment, full output444 words
- The test embeds the table, so it checks today's text, not a parse of it. That its 25 extensions equal the table's was checked mechanically at
645d4fe14a20, 10.5.2, 10.6.0 and later main (a control set compares different, so the check is not vacuous). - It asserts the missing extensions only. The vector row and the postings list rest on the source lines (see the explanation above) and on the version-aware check, which parses the table and the list from source, indexes 300 documents non-compound and compound, and fails four ways on main (shown in the full output).
- Even simpler for a reader: put the table (
package-info.java:213-319) next to a directory listing of a non-compound segment. - Results: fails 1 of 1 on main with assertions on and off (seed DEADBEEF; the test data has no random values, though
LuceneTestCasestill randomizes things such as locale and time zone), standalone and through gradle; on the 10.4.0, 10.5.2 and 10.6.0 release jars it reports 5, 6 and 7 missing extensions. - As a regression test: the same test with the seven extensions added to its set passes on the fixed tree and fails the next time the default codec writes an extension the set lacks. It keeps
veq, which fix A moves out of the vector row's extension cell, so its set has 32 extensions and the fixed table 31 (droppingveqwould make them equal; not run). Like the repro it checks only that every written extension is in its set, not the vector row, the dots or the postings list.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on the 10.4.0, 10.5.2 and 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestLucene104ExtensionTable.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene104/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene104.TestLucene104ExtensionTable -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestLucene104ExtensionTable > testTableListsEveryExtensionTheDefaultCodecWrites FAILED
    java.lang.AssertionError: written extensions missing from the extensions table expected:<[]> but was:<[dvp, dvs, fdm, psm, tmd, tvm, vemf]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:33A5926AE3A763FA]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.apache.lucene.codecs.lucene104.TestLucene104ExtensionTable.testTableListsEveryExtensionTheDefaultCodecWrites(TestLucene104ExtensionTable.java:64)

# release jars: 10.4.0 [fdm, psm, tmd, tvm, vemf]; 10.5.2 [dvs, fdm, psm, tmd, tvm, vemf]; 10.6.0 [dvp, dvs, fdm, psm, tmd, tvm, vemf]

# version-aware check (parses the table and the postings list from source), main:
FAIL A: written but absent from the table (excluding points files): [dvp, dvs, fdm, psm, tmd, tvm, vemf]
FAIL B: vector row lists [.vec, .vem, .veq, vex] but the default vectors format wrote [vec, vem, vemf, vex]
FAIL C: table extension cells without a leading dot: [vex]
FAIL D: written by Lucene104PostingsFormat but absent from its 'Files and detailed format' list [doc, pay, pos, tim, tip]: [psm, tmd]
failures=4- The page "defines the index file formats used in this version"; its table lists norms, doc-values, points and vector metadata files, not these.
- The vector row is wrong, not short: it credits
.veqto a format that never writes it, omits.vemfand writesvexundotted. - Upstream fixed the same staleness in this table before (#13801, points row).
The full argument246 words
- Contract text.
package-info.java:50: "This document defines the index file formats used in this version of Lucene";:211: "The following table summarizes the names and extensions of the files in Lucene". The table was added (LUCENE-1841, #2916, 2009) so readers can look files up by extension. - No rule explains the omissions. The table lists the metadata files of norms, doc values, points and vectors (
.nvm,.dvm,.kdm,.vem), but not those of stored fields, term vectors, terms, postings and flat vectors. - History shows omissions, not decisions. None of the six changes that added the missing files put them in the table: five touched no
package-info.java, and #13585, which copied the whole table into its newlucene912package, gave.psmno row and documented it only in the constant's javadoc. The PR discussions the follow-up read do not mention the table. A history search (git log -Gover everypackage-info.java) found no version of the table that ever had a cell with any of the seven extensions.vexwas dotted in 10.2.x and came back undotted from an older copy in 10.3.0. - Precedent. #13801 (romseygeek, merged 2024-09-18, "Correct Point file extensions in Codec javadocs") replaced the stale points cell
.dii, .dimwith.kdd, .kdi, .kdm. Other file-format doc fixes: LUCENE-7532 (#8583), #15625. - Tests. No test or build check was found that compares the overview with the files written (searched
lucene/*/src/test,build-toolsandgradleat645d4fe14a20).
The devil's-advocate check179 words
Strongest case for "intended" (the refute reviewer, the intended-lens cross-model reviewer and the devil's-advocate verifier; all rated it moderate): the page "attempts to provide a high-level definition" (:54), the table only "summarizes", the details are "provided in their linked pages" (:188), and those pages document the missing files (all but .psm); .veq is a real extension of this version (the optional scalar-quantized formats); and the codec is @lucene.experimental (Lucene104Codec.java:53).
Why it fails: a summary may be short, but not wrong: the vector row states something false about the format it links, vex is a typo, and listing some formats' metadata files but not others is inconsistency, not brevity. @lucene.experimental allows the format to change, not the current one to be described wrongly. The linked pages do not close the gap either: .vemf's page cannot be reached from the vector row's link, .tmd's is one link further on, and .psm has no page. Upstream treated exactly this as a defect in #13801. Every verifier and the adjudication rejected the "intended" reading.
Recommended A. Update the table and the postings list to the files the default codec writes
Add rows for .fdm, .tvm, .tmd and .psm; add .dvs, .dvp to the doc-values row; make the vector row .vec, .vemf, .vem, .vex, noting that optional quantized formats add .veq and .vemq; list .tmd and .psm in the postings format's files. Javadoc only. Validated: a check that parses the fixed text finds no gap; tests and static checks pass.
All options and trade-offs3 options · 977 words
Three ways to resolve it; A was validated. Targets: main and branch_11x, plus branch_10_6 if wanted (branch_10x was decommissioned, #16911). In 10.6.0 package-info.java is the same file and the postings list the same text, so the diff should apply there too (not tried).
Optional extras: the frozen backward-codecs lucene99 and lucene103 package docs carry the same vector row; fixing them is optional, as they describe old codecs.
A. Update the table and the postings list to the files the default codec writes (validated by the checks) (recommended)
Four new rows (.fdm Field Metadata, .tmd Term Metadata, .psm Postings Metadata, .tvm Term Vector Metadata), each linked to its format like its neighbours; the doc-values row becomes .dvd, .dvm, .dvs, .dvp; the vector row becomes .vec, .vemf, .vem, .vex, describes .vemf as the raw vector metadata and .vem as the HNSW graph metadata, and says the optional scalar-quantized formats add .veq and .vemq. In Lucene104PostingsFormat, the "Files and detailed format" list gains .tmd (with a link to Lucene103BlockTreeTermsWriter) and .psm (maximum impact sizes and the end pointers of the .doc, .pos and .pay files, as Lucene104PostingsWriter.java:711-720 writes). Two files, +28/-4 lines.
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java
index f2fb84f3a7e..df59b54aa43 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java
@@ -83,9 +83,12 @@ import org.apache.lucene.util.packed.PackedInts;
  * <ul>
  *   <li><code>.tim</code>: <a href="#Termdictionary">Term Dictionary</a>
  *   <li><code>.tip</code>: <a href="#Termindex">Term Index</a>
+ *   <li><code>.tmd</code>: Term Metadata, see {@link Lucene103BlockTreeTermsWriter}
  *   <li><code>.doc</code>: <a href="#Frequencies">Frequencies and Skip Data</a>
  *   <li><code>.pos</code>: <a href="#Positions">Positions</a>
  *   <li><code>.pay</code>: <a href="#Payloads">Payloads and Offsets</a>
+ *   <li><code>.psm</code>: Postings metadata (maximum impact sizes and the end pointers of the
+ *       .doc, .pos and .pay files)
  * </ul>
  *
  * <a id="Termdictionary"></a>
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java
index ebcf8c1e5e4..1a90a706783 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java
@@ -255,6 +255,11 @@
  * <td>The stored fields for documents</td>
  * </tr>
  * <tr>
+ * <td>{@link org.apache.lucene.codecs.lucene90.Lucene90StoredFieldsFormat Field Metadata}</td>
+ * <td>.fdm</td>
+ * <td>Metadata about the stored fields and their index</td>
+ * </tr>
+ * <tr>
  * <td>{@link org.apache.lucene.codecs.lucene104.Lucene104PostingsFormat Term Dictionary}</td>
  * <td>.tim</td>
  * <td>The term dictionary, stores term info</td>
@@ -265,6 +270,11 @@
  * <td>The index into the Term Dictionary</td>
  * </tr>
  * <tr>
+ * <td>{@link org.apache.lucene.codecs.lucene104.Lucene104PostingsFormat Term Metadata}</td>
+ * <td>.tmd</td>
+ * <td>Per-field term statistics and the location of the Term Index</td>
+ * </tr>
+ * <tr>
  * <td>{@link org.apache.lucene.codecs.lucene104.Lucene104PostingsFormat Frequencies}</td>
  * <td>.doc</td>
  * <td>Contains the list of docs which contain each term along with frequency</td>
@@ -280,13 +290,18 @@
  * <td>Stores additional per-position metadata information such as character offsets and user payloads</td>
  * </tr>
  * <tr>
+ * <td>{@link org.apache.lucene.codecs.lucene104.Lucene104PostingsFormat Postings Metadata}</td>
+ * <td>.psm</td>
+ * <td>Small metadata about how postings are encoded</td>
+ * </tr>
+ * <tr>
  * <td>{@link org.apache.lucene.codecs.lucene90.Lucene90NormsFormat Norms}</td>
  * <td>.nvd, .nvm</td>
  * <td>Encodes length and boost factors for docs and fields</td>
  * </tr>
  * <tr>
  * <td>{@link org.apache.lucene.codecs.lucene90.Lucene90DocValuesFormat Per-Document Values}</td>
- * <td>.dvd, .dvm</td>
+ * <td>.dvd, .dvm, .dvs, .dvp</td>
  * <td>Encodes additional scoring factors or other per-document information.</td>
  * </tr>
  * <tr>
@@ -295,6 +310,11 @@
  * <td>Stores offset into the document data file</td>
  * </tr>
  * <tr>
+ * <td>{@link org.apache.lucene.codecs.lucene90.Lucene90TermVectorsFormat Term Vector Metadata}</td>
+ * <td>.tvm</td>
+ * <td>Metadata about the term vectors and their index</td>
+ * </tr>
+ * <tr>
  * <td>{@link org.apache.lucene.codecs.lucene90.Lucene90TermVectorsFormat Term Vector Data}</td>
  * <td>.tvd</td>
  * <td>Contains term vector data.</td>
@@ -311,10 +331,11 @@
  * </tr>
  * <tr>
  * <td>{@link org.apache.lucene.codecs.lucene99.Lucene99HnswVectorsFormat Vector values}</td>
- * <td>.vec, .vem, .veq, vex</td>
+ * <td>.vec, .vemf, .vem, .vex</td>
  * <td>Holds indexed vectors; <code>.vec</code> files contain the raw vector data,
- * <code>.vem</code> the vector metadata, <code>.veq</code> the quantized vector data, and <code>.vex</code> the
- * hnsw graph data.</td>
+ * <code>.vemf</code> the raw vector metadata, <code>.vem</code> the hnsw graph metadata, and
+ * <code>.vex</code> the hnsw graph data. The optional scalar-quantized formats add
+ * <code>.veq</code> (quantized vector data) and <code>.vemq</code> (its metadata).</td>
  * </tr>
  * </table>
  *
Trade-offs
- Covers every gap; the descriptions are short and match the writers. The
.psmdescription is the only one that is new text (no format page describes the file today). - The table still has to be kept up to date by hand. A test like the repro, with its set updated, would catch the next gap (optional).
- For a
branch_10_6backport the same diff should apply (not tried);.dvpexists there (10.6.0).
What the checks validated
Validated in a scratch worktree of 645d4fe14a20 with the diff applied (removed afterwards), seed DEADBEEF, 2026-11-01:
- The fixed text matches the files. The version-aware check, which parses the table and the postings list straight from the patched source and indexes 300 documents with the default codec (non-compound and compound), reports 0 failures with assertions on and off; on the stock text it reports 4 (missing extensions, vector row, undotted
vex, postings list). - Suite:
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene104.TestLucene104PostingsFormat --tests org.apache.lucene.codecs.lucene104.TestLucene104ExtensionTableFixed: 35 tests (34 of the suite, 2 of them skipped by the framework, and the repro with the seven extensions added to its set), BUILD SUCCESSFUL with assertions on and off. - Static checks and docs:
:lucene:core:checkGoogleJavaFormatpasses with the diff unchanged;:lucene:core:check -x test(ecjLint, forbiddenApis, google-java-format, the regenerate checksums) and:lucene:core:renderJavadocpass; the rendered page shows the four new rows and the corrected doc-values and vector rows, and the rendered postings list shows.tmdand.psm. - The unchanged repro still fails on the patched tree, as it must: it embeds the old table. Through gradle on stock
645d4fe14a20it fails with assertions on and off. - The full Lucene test suite was not run (javadoc-only change).
Correct the vector row (.vec, .vemf, .vem, .vex and the .veq note) and the postings list; leave the missing metadata rows.
Trade-offs
Smallest diff, but the table stays incomplete and inconsistent (some formats' metadata files listed, others not), which is the larger part of the defect. Not run.
Fix the vector row and the postings list, and change :211 to say the table lists the main files of each format and that each linked page lists its metadata files.
Trade-offs
Nothing left to drift for future metadata files, but readers looking up an unknown file by extension still have to search the format pages, which is what the table is for. Not run.
Downstream relevance only for tools that select or copy index files by the table's extensions instead of Lucene's own file lists; Lucene, and products that read indexes through Lucene, are unaffected.
Semi-formal: a differential check extracted the table's extension cells and the postings "Files" list from the javadoc source and compared them both ways with the files of 91 generated default-codec indexes. Seven written extensions were never listed and the listed .veq was never written by the default format; on the fixed text a 41-configuration sweep finds nothing.
The method in full206 words
- Hunt unit, 2026-10-28: the table's extension cells and
Lucene104PostingsFormat's "Files and detailed format" list were extracted mechanically from the javadoc source. The extensions written were collected from the real files (top level and inside compound files) of 91 generated indexes: 11 fixed configurations (two of them with a scalar-quantized vectors format) and 80 seeded random feature mixes (stored fields, term vectors, postings with positions, offsets and payloads, norms, all five doc-values types dense and sparse with and without a skip index, points, float, byte and float16 vectors, deletions, soft deletes, doc-values updates, compound files, a file-system directory). The two sets were compared both ways, with assertions on and off. - Result: written but not in the table
[.dvp, .dvs, .fdm, .psm, .tmd, .tvm, .vemf]; in the table but never written by the default format[.veq]; postings list misses[.psm, .tmd]. On the fixed text the same extraction, run as a separate 41-configuration sweep (the 11 fixed and 30 seeded random), finds nothing missing, extra or undotted (positive control; a sweep, not a proof). - Starting lead: a follow-up of an earlier unit that collected the set of extensions the default codec writes. This is a differential check, not model checking or a proof.
No prior report in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-28, again 2026-11-01). Nearest: #13801, which fixed only the points row of the same table. Not fixed upstream.
Searches2 searches
- Related, not this bug: #13801 (fixed only the points row; precedent); #16939 / #16941 (a wrong link to the File Formats page from the docs build, fixed 2026-10-29; not the table's content); #16491 (stale block-size comments in the lucene104 reader and writer); #15625 (a different sentence of the postings javadoc); #10744 (a 2021 comment that package javadocs are copied "pretty inconsistently", naming no row); #2916 (where the table came from); the PRs that added each file (none discusses the table).
- Open PRs: #16480 touches
lucene104/package-info.javaonly to add a History bullet; #16949 (a javadoc-fix series) has no codec file-format item. - Not fixed upstream: upstream main
f815e679bf6c(2026-11-01) has the same blobs of both files; the latest commits are #15160 (2025-09-10) onpackage-info.javaand #15625 (2026-01-28 UTC; 2026-01-29 in the author's time zone) onLucene104PostingsFormat.java.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; the JIRA archive; downstream repositories; mailing lists; web | 2026-10-28 | scripted prior-report searches (three runs plus the finder's: GitHub, commit, downstream, mailing-list and JIRA-archive queries), 19 more searches on apache/lucene, 18 on downstream repositories, 9 web searches; the changed files of all 414 open apache/lucene PRs | no report; nearest #13801 (points row only) and #10744 (a general remark) |
| apache/lucene and the lists (recheck) | 2026-11-01 | scripted prior-report searches (4 runs: 64 GitHub issue/PR, 12 commit, 8 downstream, 80 mailing-list and 16 JIRA-archive queries); 37 manual GitHub searches ("Summary of File Extensions", "Files and detailed format", each extension, Lucene104PostingsFormat, "file formats" stale/outdated, date-bounded); every issue and PR updated since 2026-10-27 (118) and the changed files of the 51 open PRs updated since then; 5 web searches | no report; only #16480 touches the package-info file (a History bullet) |
Grew one gap per format change since 8.5.0 (2020): .fdm/.tvm 8.5.0, .tmd 8.6.0, the vector row's current wrong form 9.9.0 (it had lacked .vex since 9.0.0), .psm 9.12.0, .dvs 10.5.0, .dvp 10.6.0. 8.4.1 matches its table; every release from 8.5.0 to 10.6.0, and main, does not.
Versions tested6 rows
- Oldest part: LUCENE-9147 "Move the stored fields index off-heap" (apache/lucene-solr#1179, migrated issue #10187), jpountz,
136dcbdbbce(main) /597141df6b6(branch_8x), 2020-02-05, first in 8.5.0: it started writing.fdmand.tvm, documented.fdmon the stored-fields page and touched no package-info. The 8.4.1 and 8.5.0 tables are the same apart from one unrelated link. - Later layers (none put its file in the table: #12582 wrote the vector row's current text, #13585 copied the table into its new
lucene912package without a.psmrow, the other four touched no package-info):.tmd87a3bef50f8/0dac659cd17(LUCENE-9353, lucene-solr#1473, jpountz, 8.6.0); the vector row.vec, .vem, .veq, vexf2bf5339e53(#12582, benwtrent, written when the HNSW format could still write.veq) anda47ba3369f4(#12729, benwtrent:.veqmoved to separate formats,.vemfadded, row untouched), both 9.9.0;.psmb4a8810b7ae(#13585, jpountz, 9.12.0);.dvs37b6d65a7d6(#15976, romseygeek, 10.5.0);.dvp1160d3c8a25(#16540, sgup432, 10.6.0). - The undotted
vex: 9.9.0-10.1.0 and 10.3.0 on; 10.2.x had.vex(#14078 had moved the overview tolucene102/package-info.javawhile the default codec stayedLucene101; that row also listed.veb, .vemb), and 10.3.0 brought the old text back (#14333 / #14563). - Out of scope: the stale points row of 8.6.0-9.12.x, fixed for 10.0.0 by #13801.
- An earlier, superseded vector-row gap: from 9.0.0 (LUCENE-9004,
b36b4af22bb, the first vector format, which writes.vex) through 9.8.0 the row read.vec, .vemand lacked.vex; #12582 replaced it in 9.9.0. The executed 9.8.0 run reports[fdm, tmd, tvm, vex]missing and the row[.vec, .vem]against the written[vec, vem, vex]. - Caveats: 53 releases affected. This follow-up executed 12 of them (plus the clean 8.4.1, and main); with the study's 2026-10-28 run, 22 distinct affected releases have been executed. The rest are inferred, not run: from the executed releases on either side, each with its own default codec and table, from the study's extraction of the table's extensions at every 8.0.0-10.5.2 tag, and from the table's history (8.8.2-8.11.3 are not tagged in the history clone). JDK 25 on Linux aarch64 only.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal repro fails with assertions on and off; the version-aware check fails all four parts (missing, vector row, dot, postings list) |
| 10.6.0, 10.5.2, 10.5.0, 10.4.0 | affected | the minimal repro reports 7 (10.6.0), 6 (10.5.2) and 5 (10.4.0) missing extensions; 10.5.0 ran the version-aware check only; .dvp from 10.6.0, .dvs from 10.5.0 |
| 9.12.0, 9.11.1, 9.9.0 | affected | missing .fdm, .tmd, .tvm, .vemf (and .psm from 9.12.0); vector row wrong; vex undotted |
| 9.8.0 | affected | missing .fdm, .tmd, .tvm and .vex: the vector row .vec, .vem lacks .vex, written since 9.0.0; postings list misses .tmd |
| 8.11.4, 8.6.0, 8.5.2, 8.5.0 | affected | missing .fdm, .tvm (from 8.5.0) and .tmd (from 8.6.0) |
| 8.4.1, 8.0.0 | not affected | the table lists every file the default codec writes (8.4.1 with assertions on and off) |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication (high confidence); an audit confirmed it as a low-priority doc defect; re-checked on 645d4fe14a20. This doc's gradle run validated the fix.
Checks and verdicts435 words
Every check either re-ran a test or read the same table and writer lines; none found a reading under which the table is meant to leave these files out or credit .veq to the default format.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | reproduced | Differential check over 91 generated indexes (a separate 41-configuration sweep checked the fixed text); its 3-test JUnit fails 3 of 3 on main (on and off), the 10.6.0 release commit and 10.5.2. |
| cross-model review, refute lens (OpenAI GPT-5.6, executing; study) | real, high confidence | Own audit on three seeds reproduced the missing sets and the vector-row mismatch; a compound control passes; with the fix text its check passes; intended argument moderate. |
| independent reproducer | real | Own check that parses the table and the list from source: 4 of 4 fail on main (on and off), 10.5.2 and 9.12.3; 0 failures with the fix text. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium confidence | It could not run any code, so it read only; a separate run re-ran the finder's test: 3 of 3 fail on and off. Noted that the .dvp CHANGES entry cites issue #16298 (the PR is #16540). |
| intended-behaviour devil's advocate | real (documentation defect) | Built and rejected the "high-level summary" case; found no version of the table with a .fdm, .tmd, .psm or .vemf cell; moderate on the .veq wording. |
| adjudication | confirmed, high confidence, documentation defect, minor | Re-ran the independent reproduction's check with a fresh seed on main, on and off (4 failures each), and read the source. |
| credibility audit | confirmed, minor | Re-ran the finder's test on new seeds: 3 of 3 fail. Its committer-perspective note (the auditor's own view, not a Lucene committer's): "I'd merge this as a small doc PR, the same way as #13801. It's a real but cosmetic documentation defect." |
| re-check on 645d4fe14a20 and a second refute review (2026-11-01) | real, high confidence | The minimal repro fails on main and 10.5.2, on and off; the control with the seven extensions added passes. The second cross-model review's own test parses the real table with a file-system directory and finds the same seven plus the undotted vex; its compound control passes. |
| this doc's validation (2026-11-01) | fix A validated | In a scratch worktree with fix A: the version-aware check on the fixed text reports 0 failures (on and off; 4 on the stock text); TestLucene104PostingsFormat with the updated repro (35 tests), checkGoogleJavaFormat, :lucene:core:check -x test and renderJavadoc pass; the repro fails through gradle on stock, on and off. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 404 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,531 words
- Registry title
- The default codec's 'Summary of File Extensions' table (codecs/lucene104 package documentation) is stale: it omits .fdm, .tvm, .tmd, .psm, .dvs, .dvp and .vemf, which the default codec writes, credits .veq to the default HNSW vectors format (which does not write it) and gives 'vex' without its dot; Lucene104PostingsFormat's 'Files and detailed format' list also omits .tmd and .psm (documentation defect; the code is correct)
- Area
- codecs / default codec file-format overview (codecs/lucene104 package-info 'Summary of File Extensions' table and the Lucene104PostingsFormat 'Files and detailed format' list vs the files the default codec writes)
- Priority
- Low, rank 1281: The stale extension table in the default codec overview leaves out common files, but the per-format javadocs list nearly all of them and it is a missing-name list, not a wrong byte grammar.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writers and readers are unaffected in every configuration; the people misled are readers of the published File Formats overview and of the Lucene104PostingsFormat file list (people who inspect, size or copy index directories by extension, or write format tools from the overview), who find .fdm, .tmd and .psm (written for almost every default-codec index) and .tvm, .dvs, .dvp and .vemf unlisted and a .veq that the default vectors format never writes; the linked per-format javadocs already document every missing file except .psm; the drift began in 8.5.0 (2020) and needs no scale or special setting.
- Summary
- You index ordinary documents with the default codec and look up the files in the index directory in the 'Summary of File Extensions' table of the codec's package documentation, which says it 'summarizes the names and extensions of the files' of this format version. Seven extensions the default codec writes are missing (.fdm, .tvm, .tmd, .psm, .dvs, .dvp, .vemf); the vector row lists '.vec, .vem, .veq, vex', but the default Lucene99HnswVectorsFormat it links writes .vec, .vemf, .vem and .vex (.veq comes only from the optional scalar-quantized formats) and 'vex' lacks its dot; and Lucene104PostingsFormat's own 'Files and detailed format' list leaves out .tmd and .psm. Lucene itself reads and writes all these files correctly; each format change since 8.5.0 that added a file updated at most its own class javadoc, never this overview.
- Introduced
- accumulated staleness, one layer per format change [follow-up, boundaries executed]. Earliest still-present layer: 136dcbdbbce (main) / 597141df6b6 (branch_8x, first in 8.5.0), LUCENE-9147 'Move the stored fields index off-heap' (apache/lucene-solr#1179, migrated issue apache/lucene#10187), by jpountz: it started writing .fdm and .tvm and documented .fdm in the stored-fields format javadoc but not in the codec table [exec: 8.4.1 pass, 8.5.0 fail]. Later layers: 87a3bef50f8 / 0dac659cd17 (LUCENE-9353, apache/lucene-solr#1473, jpountz: .tmd, 8.6.0); f2bf5339e53 / 6623c42553b (#12582, benwtrent: wrote the '.vec, .vem, .veq, vex' row while the HNSW format itself still wrote .veq) and a47ba3369f4 / 448e6112954 (#12729, benwtrent: moved .veq to separate formats and added .vemf without touching the row), both first in 9.9.0; b4a8810b7ae / 59b7c28eb47 (#13585, jpountz: .psm, 9.12.0); 37b6d65a7d6 / 71a214ce53c (#15976, romseygeek: .dvs, 10.5.0); 1160d3c8a25 / 977dfa876d2 (#16540, sgup432: .dvp, 10.6.0). The undotted 'vex' was dotted in 10.2.x (#14078) and came back in 10.3.0, when #14333 / #14563 created lucene103/package-info.java from the older text. Correction of an earlier attribution: LUCENE-9456 (8.7.0) only moved more metadata into the existing .fdm and .tvm files (8.6.3 and 8.7.0 write the same set) (2020-02-05 (author date of 136dcbdbbce and 597141df6b6: .fdm and .tvm); later layers 2020-06-16 (.tmd), 2023-10-24 and 2023-11-10 (the vector row), 2024-07-31 (.psm), 2026-04-22 (.dvs), 2026-09-11 (.dvp))
- First affected version
- 8.5.0 [exec] (.fdm and .tvm missing; the last unaffected release is 8.4.1 [exec], and 8.0.0 also passes); the wrong vector row (.veq credited to the default format, .vemf missing, undotted 'vex') from 9.9.0 [exec]
- Affected versions
- every release from 8.5.0 through 10.6.0 (the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream. By part [follow-up]: .fdm/.tvm 8.5.0-10.6.0; .tmd (table and postings list) 8.6.0-10.6.0; .veq misattributed and .vemf missing 9.9.0-10.6.0 (the 10.2.x row also lists .veb/.vemb); undotted 'vex' 9.9.0-10.1.0 and 10.3.0-10.6.0 (dotted in 10.2.0-10.2.2; 10.6.0 by reading); .psm (table and postings list) 9.12.0-10.6.0; .dvs 10.5.0-10.6.0; .dvp 10.6.0, branch_10x and main [exec: the follow-up's version-aware check, which parses each release's own table and postings list and indexes with that release's default codec, passes on 8.0.0 and 8.4.1 and fails on 8.5.0, 8.5.2, 8.6.0, 8.6.3, 8.7.0, 8.8.1, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 9.11.1, 9.12.0, 9.12.3, 10.0.0, 10.1.0, 10.2.0, 10.2.2, 10.3.0, 10.4.0, 10.5.0, 10.5.2 and main (-ea and -da), and passes on main with the fix text applied; the finder's JUnit fails 3 of 3 on main (-ea and -da), the branch_10_6 head, 10.4.0, 10.5.0 and 10.5.2 (2 of 3 on 10.0.0, where its postings check is vacuous because 10.0 writes Lucene912 postings); the independent reproduction's check fails on main, 10.5.2 and 9.12.3]. 8.8.2-8.11.3 are inferred (not tagged in the history clone; same codec, and the 8.8.1 and 8.11.4 tables are identical). Out of scope: the 8.6-9.12 stale points row, fixed for 10.0.0 by #13801. Caveats: all runs used JDK 25.0.3 on Linux aarch64; upstream main 645d4fe14a20 (2026-10-28) has not changed either file
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: three scripted prior-report searches (48 GitHub, 9 commit, 6 downstream, 60 mailing-list and 12 JIRA-archive queries over dev@, java-user@, issues@, commits@) plus the finder's run (51 queries), 14 more issue and PR queries on apache/lucene, 18 on downstream repositories, 5 more searches and 9 web searches; all 414 open apache/lucene PRs enumerated by changed files). Nearest items, not the same bug: #13801 (romseygeek, merged 2024-09-18, 'Correct Point file extensions in Codec javadocs': fixed only the points row of the same table, '.dii, .dim' to '.kdd, .kdi, .kdm', and names no other row; an earlier fix of the same kind); #10744 / LUCENE-9705 (a 2021 comment by msokolov that package javadocs were copied 'pretty inconsistently over time'; names no table or extension); the changes that made the text stale (apache/lucene-solr#1179, #1473 and #1752, #12582, #12729, #13585, #15976, #16540; none of their threads discusses the table); #90 (revised only the blocktree writer javadoc for .tmd); #15625 (the last Lucene104PostingsFormat javadoc fix, a different sentence). Not a fix: open PR #16480 touches lucene104/package-info.java only to add a History bullet; open PR #16911 deletes branch_10x. Recheck (2026-10-28): six issue and PR searches, including items created or updated in the last 48 hours, found no report; none of the 20 PRs created since 2026-10-26 touches either file; by author date the latest upstream commits are 00f2b01e798 (2025-09-10, #15160) for package-info.java and 19bf11ddad8 (2026-01-28, #15625) for Lucene104PostingsFormat.java, so upstream main 645d4fe14a20 still has the stale table and list. Not fixed upstream. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone (seed DEADBEEF) and through gradle in a scratch worktree (on and off); the fix in that worktree: the version-aware text check (on and off),TestLucene104PostingsFormatwith the repro's updated form,:lucene:core:checkGoogleJavaFormat,:lucene:core:check -x testand:lucene:core:renderJavadoc. The minimal repro on the 10.4.0, 10.5.2 and 10.6.0 release jars; the version-aware check on 8.4.1 (pass), 8.5.0, 8.5.2, 8.6.0, 8.11.4, 9.8.0, 9.9.0, 9.11.1, 9.12.0, 10.4.0, 10.5.0, 10.5.2, 10.6.0 and main. Both fix-site files have the same blobs on645d4fe14a20and on upstream mainf815e679bf6c(2026-11-01) (read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:50 ('defines the index file formats used in this version of Lucene'), :54 ('a high-level definition'), :188 ('Details on each of these are provided in their linked pages'), :211 ('summarizes the names and extensions of the files in Lucene'), :289 ('.dvd, .dvm'), :312-318 (vector row '.vec, .vem, .veq, vex' linked to Lucene99HnswVectorsFormat); Lucene104PostingsFormat.java:81-89 ('Files and detailed format': .tim, .tip, .doc, .pos, .pay), :324-325 (META_EXTENSION = "psm") [read at the follow-up step, clean checkout]
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 54, 188, 194-197, 207-319: the table; 289 doc-values row; 312-318 vector row)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java (lines 81-89 'Files and detailed format'; 324-325 META_EXTENSION psm; 410-413 fieldsConsumer)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java (67, 131-132), lucene90/compressing/Lucene90CompressingTermVectorsWriter.java (69, 259-260), lucene103/blocktree/Lucene103BlockTreeTermsReader.java (84), lucene103/blocktree/Lucene103BlockTreeTermsWriter.java (91, 147, 321-324), lucene104/Lucene104PostingsWriter.java (153)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java (135-136, 195, 197), lucene90/Lucene90DocValuesConsumer.java (110, 120), lucene99/Lucene99FlatVectorsFormat.java (48, 81), lucene99/Lucene99FlatVectorsWriter.java (111-120), lucene99/Lucene99HnswVectorsFormat.java (89-90, 155-156), lucene104/Lucene104ScalarQuantizedVectorsFormat.java (107-108), lucene104/Lucene104Codec.java (71, 120-123), lucene90/Lucene90StoredFieldsFormat.java (92), lucene90/Lucene90TermVectorsFormat.java (54)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java (99), index/DocumentsWriterPerThread.java (643), index/LiveIndexWriterConfig.java (143), index/MergePolicy.java (598-600), codecs/CompoundFormat.java (42, 54, 163-179)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 54, 188, 211, 289, 312-318)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java (line 53 @lucene.experimental)
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsWriter.java (153, 711-720: what .psm holds)lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene99/package-info.java and lucene103/package-info.java (line 314: the same vector row)
- TestLucene104ExtensionTable.java (JUnit, one test):
repro/LFV-972/src/org/apache/lucene/codecs/lucene104/TestLucene104ExtensionTable.java(66 lines)
assets/LFV-972/bug.png(404 KB)