The default codec's file-format javadoc for doc values gives the wrong block size for terms dictionaries and leaves out their LZ4 compression.
- A SORTED or SORTED_SET doc-values field stores, per document, an ordinal (ord) into the sorted list of the field's distinct terms. That list, the terms dictionary, lives in the segment's
.dvdfile. - To save space, a term is stored as the length of the prefix it shares with the previous term plus the rest, its suffix. Every so many terms, one term is stored in full, so that a lookup can start decoding there instead of at the beginning.
- You read the
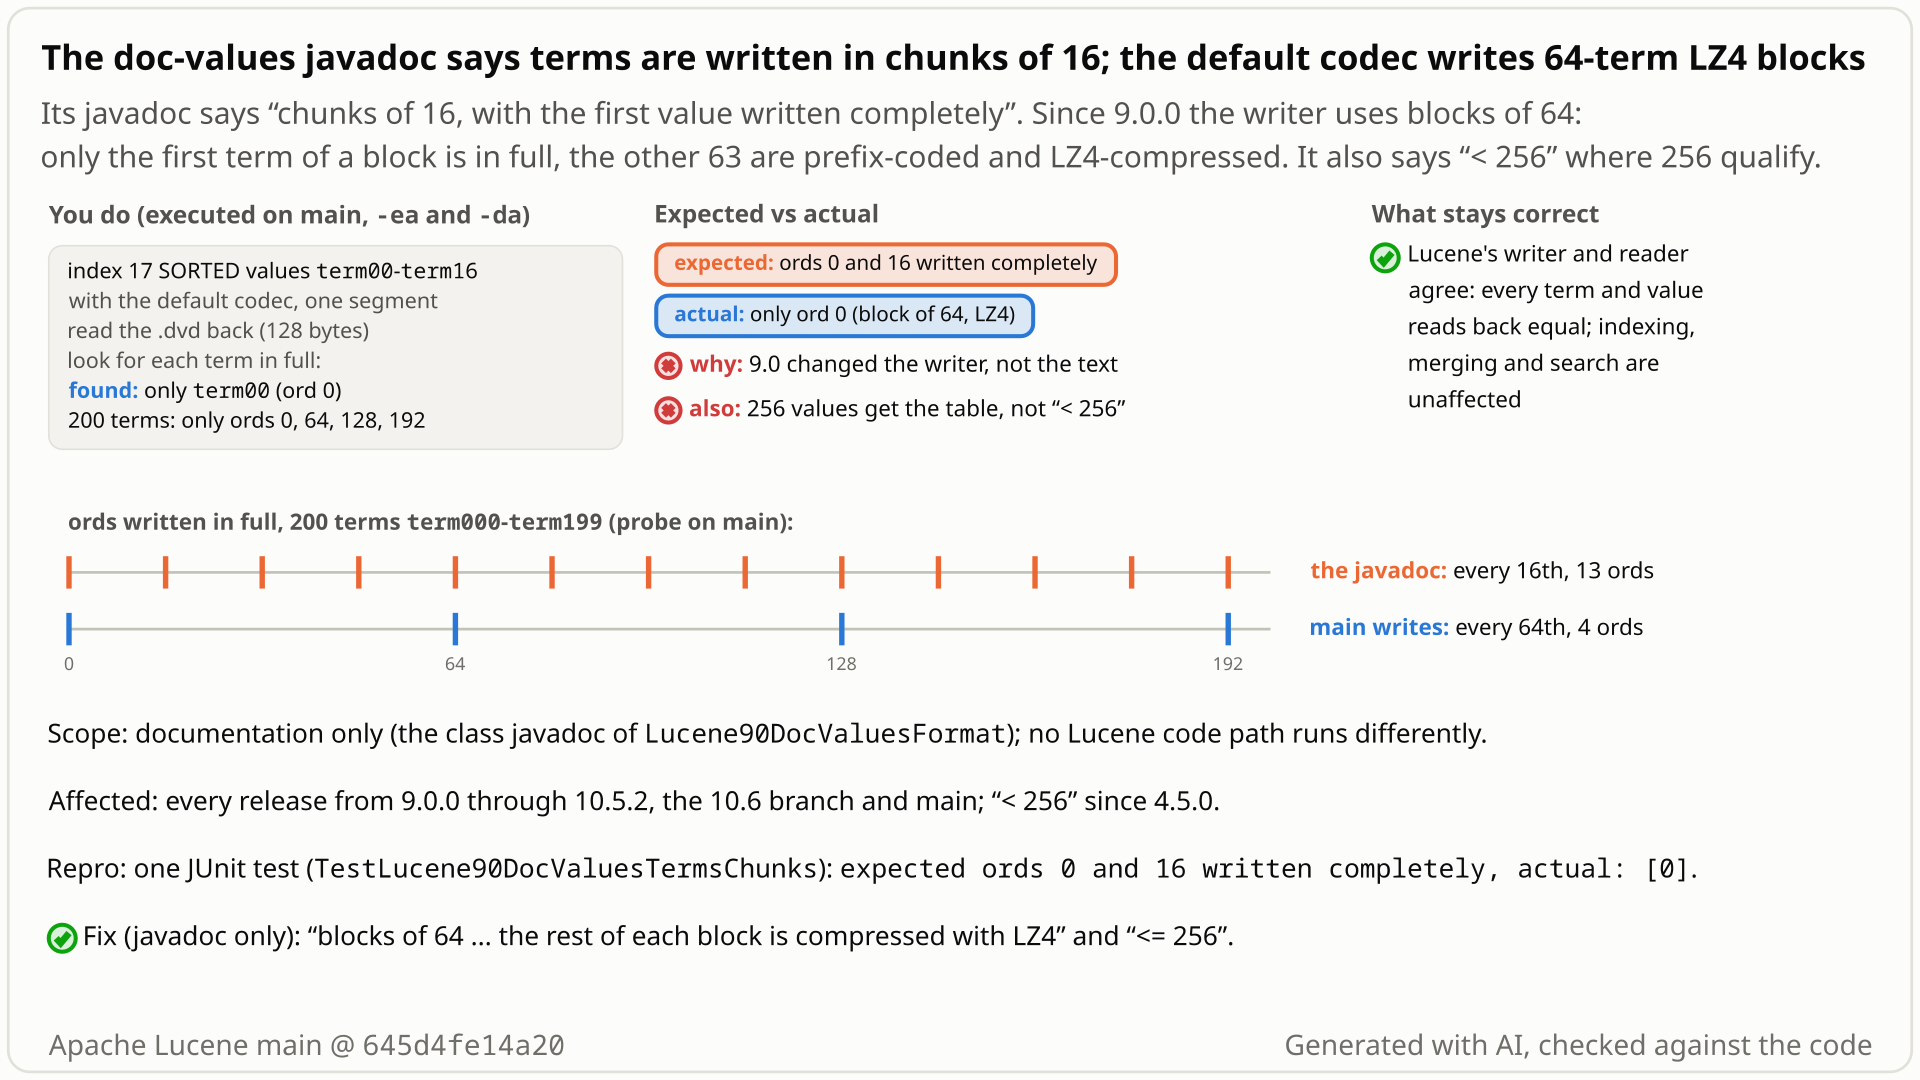
Lucene90DocValuesFormatjavadoc, the doc-values format of the default codec, to learn how a SORTED field's distinct terms are stored in the.dvdfile: "written in chunks of 16, with the first value written completely and other values sharing prefixes". - You index 17 documents with the SORTED values
term00toterm16and look in.dvdfor each term stored in full (a length byte, then its bytes). You expect ords 0 and 16, the first term of each chunk of 16. - Instead only ord 0 is there. The writer uses blocks of 64: the first term in full, the other 63 as suffixes after a shared prefix (just "6" for
term16, which sharesterm1withterm15), and that part LZ4-compressed. With 1,000 terms the javadoc predicts 63 full terms; the file has 16 (ords 0, 64, 128, ...). - A smaller slip in the same javadoc: a lookup table is said to be used for fewer than 256 unique values, but exactly 256 get it too. 4,096 documents with 256 distinct values give a 4,169-byte
.dvd; with 257 values it is 24,651 bytes. - Nothing breaks: Lucene's reader matches its writer. The text has been stale since LUCENE-9843 removed the 16-term mode in 9.0.0 (2021), and the fix is a javadoc edit.
Developers who learn the .dvd format from this javadoc to inspect, debug, port or re-implement it. On every release since 9.0.0, with no setting involved, the text omits the LZ4 step for any SORTED or SORTED_SET field with 2 or more terms and gets the block size wrong from 17 terms on. Lucene users see no runtime effect.
Mechanism, terms and numbers602 words
The class javadoc of Lucene90DocValuesFormat, the doc-values format of the default codec, says that terms dictionaries ("Prefix-compressed Binary", used by SORTED and SORTED_SET fields) are "written in chunks of 16, with the first value written completely and other values sharing prefixes" (Lucene90DocValuesFormat.java:101-104 on main 645d4fe14a20). Since 9.0.0 the writer uses blocks of 64 terms: it writes the first term of each block in full, prefix-codes the other 63, and compresses them with LZ4 (Lucene90DocValuesConsumer.addTermsDict, :758-851; TERMS_DICT_BLOCK_LZ4_SHIFT = 6, Lucene90DocValuesFormat.java:217); since 9.2.0 (LUCENE-10536) the first term is the LZ4 dictionary. LUCENE-9843 (a7a02519f0a, 2021) removed the 16-term mode and deleted its constant from this same file, but left the sentence. So only terms 0, 64, 128, ... appear in full in a .dvd file: 17 terms give 1 complete term where the text predicts 2, and 1,000 terms give 16 where it predicts 63. A second, smaller slip: table compression is said to apply for "(< 256)" unique values (:77), but the writer keeps the table up to and including 256 (Lucene90DocValuesConsumer.java:434, size() > 256). Lucene's reader matches its writer, so only the documentation is wrong.
Lucene90DocValuesFormat.java:101-104(BINARY section; the SORTED bullet at:110says terms are "written as Prefix-compressed Binary"): "Prefix-compressed Binary: values are written in chunks of 16, with the first value written completely and other values sharing prefixes. chunk addresses are written as Monotonic-compressed numerics. A reverse lookup index is written from a portion of every 1024th term." No word about LZ4.:77: "Table-compressed: when the number of unique values is very small (< 256), and when there are unused "gaps" in the range of values used ... a lookup table is written instead."
Lucene90DocValuesFormat.java:217-219:TERMS_DICT_BLOCK_LZ4_SHIFT = 6(64 terms) is the only block size.Lucene90DocValuesConsumer.addTermsDict(:758-842, called for SORTED at:755and SORTED_SET at:1061): when(ord & blockMask) == 0(:785, every 64th term) it records the block address and writes the term in full,data.writeVInt(term.length)and its bytes (:797-798); every other term goes into a buffer as one token byte (shared-prefix and suffix lengths, with extra vints for long ones) plus its suffix (:803-816). Each block's buffer is written as its length andLZ4.compressWithDictionary(termsDictBuffer, 0, dictLength, ...)with the block's first term as the dictionary (:844-851; the dictionary dates from LUCENE-10536 in 9.2.0, while 9.0.0 and 9.1.0 callLZ4.compresswithout one). A last block that holds only its first term gets no LZ4 data (:823).- The reader mirrors it: block mask from
TERMS_DICT_BLOCK_LZ4_SHIFT(Lucene90DocValuesProducer.java:1770,:1792) andLZ4.decompress(:1950). - Table: the writer drops the unique-value table only when
uniqueValues.size() > 256(Lucene90DocValuesConsumer.java:434) and uses it only for 2 or more unique values whose ordinals need fewer bits than the value range (:485-488); the reader rejects onlytableSize > 256(Lucene90DocValuesProducer.java:392-393).
- 17 SORTED terms
term00..term16, default codec, one segment: only ord 0 appears in full in.dvd(the javadoc predicts ords 0 and 16). - The hunt's check: 100, 300 and 1,000 distinct terms give 2, 5 and 16 complete terms (ords 0, 64, 128, ...); chunks of 16 would give 7, 19 and 63.
- 4,096 NUMERIC values with a gap (0 to 254 and 2^40, i.e. 256 distinct):
.dvdis 4,169 bytes, 8-bit ordinals per document, a table (the table itself goes to.dvm,Lucene90DocValuesConsumer.java:492-494); with 257 distinct values 24,651 bytes, 48 bits per document.
Exposure and likelihood224 words
- Who is hit. People who study the default codec's file formats: to inspect or recover an index, to write a reader in another language, or to start a custom codec from
Lucene90DocValuesFormat. The default codec's overview sends them here:lucene104/package-info.java:172and:288link the class as the per-document values format, and:188says "Details on each of these are provided in their linked pages". - Default vs opt-in. Default:
Lucene104Codecusesnew Lucene90DocValuesFormat()(Lucene104Codec.java:122), and Lucene90 has only the 64-term LZ4 layout; no setting gives 16-term chunks. A dictionary with one term has no LZ4 data, and the text is right for it. - What a reader gets wrong. The text puts the block boundaries in the wrong place and does not say that the rest of each block is LZ4-compressed, so it is not enough to read this part of the format. A mental model built from it gets the block size wrong by a factor of 4 and misses the decompression step.
- Scale. None needed: 2 or more distinct terms give an LZ4 block the text does not mention; 17 or more show the wrong block size (ord 16 is not stored in full).
- What it does not do. No wrong result, exception or corruption: Lucene reads what it writes. Impact minor, priority Low; no public report found since 9.0.0 (2021).
One JUnit test, public API only: index 17 SORTED values with the default codec, read the .dvd file back and list which terms appear in full as a length byte plus their bytes. All terms share the prefix term, so only a term written completely can match. Deterministic, single thread; the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene90;

import java.nio.charset.StandardCharsets;
import java.util.ArrayList;
import java.util.Arrays;
import java.util.List;
import java.util.Locale;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.BytesRef;

public class TestLucene90DocValuesTermsChunks extends LuceneTestCase {

  public void testTermsWrittenInChunksOf16() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()).setUseCompoundFile(false);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (int i = 0; i < 17; i++) {
          Document doc = new Document();
          doc.add(new SortedDocValuesField("f", new BytesRef(term(i))));
          w.addDocument(doc);
        }
      }
      String dvd = Arrays.stream(dir.listAll()).filter(f -> f.endsWith(".dvd")).findFirst().get();
      byte[] bytes = new byte[(int) dir.fileLength(dvd)];
      try (IndexInput in = dir.openInput(dvd, IOContext.READONCE)) {
        in.readBytes(bytes, 0, bytes.length);
      }
      String data = new String(bytes, StandardCharsets.ISO_8859_1);
      List<Integer> inFull = new ArrayList<>();
      for (int ord = 0; ord < 17; ord++) {
        if (data.contains((char) term(ord).length() + term(ord))) {
          inFull.add(ord);
        }
      }
      // javadoc: "written in chunks of 16, with the first value written completely" -> ord 16 in full
      assertTrue("expected ords 0 and 16 written completely, actual: " + inFull, inFull.contains(16));
    }
  }

  private static String term(int i) {
    return String.format(Locale.ROOT, "term%02d", i);
  }
}
cp TestLucene90DocValuesTermsChunks.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90DocValuesTermsChunks -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false instead (same failure)
- Expected
- Ords 0 and 16 are in
.dvdin full, the first term of each chunk of 16, as the javadoc says. - Observed
- Only ord 0 is in full:
expected ords 0 and 16 written completely, actual: [0], with assertions on and off.
More files, environment, full output269 words
- The scan works: ord 0, the first term of the block, is found. Prefix-coded entries hold only a token byte and the suffix ("6" for
term16), inside an LZ4-compressed buffer, so a term after the first cannot match. For this input nothing else in.dvdholds a whole term: the reverse terms index writes no term bytes for 17 terms (Lucene90DocValuesConsumer.java:883-893: an entry only at ord 0, with sort key length 0). - The test sits in the
lucene90test package only for locality; it uses no package-private API.new IndexWriterConfig()withsetUseCompoundFile(false)and one flush give one segment with one.dvdfile. - Regression test: none suggested. The fix is javadoc-only; this test asserts the old text, so it keeps failing after the fix by design. The layout itself is already pinned by
TestLucene90DocValuesFormat. - The "(< 256)" slip needs no test:
Lucene90DocValuesFormat.java:77next toLucene90DocValuesConsumer.java:434(size() > 256) shows it; the executed sizes are 4,169 bytes for 256 values and 24,651 for 257.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the hunt's larger tests fail the same way on 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux, aarch64 (the result does not depend on the platform) |
cp TestLucene90DocValuesTermsChunks.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestLucene90DocValuesTermsChunks -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false instead (same failure)
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true
TestLucene90DocValuesTermsChunks > testTermsWrittenInChunksOf16 FAILED
    java.lang.AssertionError: expected ords 0 and 16 written completely, actual: [0]
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:7757A8A4DE400BCB]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.codecs.lucene90.TestLucene90DocValuesTermsChunks.testTermsWrittenInChunksOf16(TestLucene90DocValuesTermsChunks.java:62)
1 test completed, 1 failed
# assertions off (-Ptests.asserts=false): the same failure, same line- "Chunks of 16" was true until 8.x. LUCENE-9843 (9.0.0) removed the 16-term mode and deleted its constant from this same file, but left the sentence.
- Lucene's own CHANGES (9.2.0) describes the real layout: the first term of each block uncompressed, the other 63 compressed.
- Tests are built on 64-term blocks and say "<= 256"; the reader accepts a 256-entry table.
The full argument205 words
- History. The sentence was written for
Lucene45DocValuesFormat(c2f37e0de2d, 2013-08-19, "javadocs/cleanups"), when it was true (16-term address interval), and copied into every later format, intoLucene90DocValuesFormatby LUCENE-9705 (4d7b2aebfe0, 2021-02-22). LUCENE-9663 (8.9.0) added 64-term LZ4 blocks for the non-default BEST_COMPRESSION mode; LUCENE-9843 (a7a02519f0a, 2021-05-06, 9.0.0) removed the modes, and its diff of this file deletesTERMS_DICT_BLOCK_SHIFT = 4but not the sentence. Its issue (#10882, 18 comments) never mentions the javadoc. - The real layout is documented elsewhere.
CHANGES.txt:4257-4259(9.2.0, LUCENE-10536): "Doc values terms dictionaries now use the first (uncompressed) term of each block as a dictionary when compressing suffixes of the other 63 terms of the block." - Tests.
TestLucene90DocValuesFormatbuilds its terms-dictionary cases fromTERMS_DICT_BLOCK_LZ4_SIZE(:1116,:1204);LegacyBaseDocValuesFormatTestCase.java:1359and:1518: "for numbers of values <= 256, all storage layouts are tested". - The text is meant to be exact. It gives numbers (16, 256, 1024; "blocks of 16384 values" at
:89is right), and the codec overview sends readers to it for the details (lucene104/package-info.java:188). Upstream merged javadoc corrections of this kind (#13801 "Correct Point file extensions in Codec javadocs", #12984 "Improve Javadoc for Lucene90StoredFieldsFormat"), and in 2015 replaced outdated doc-values format javadocs (#7921, LUCENE-6863).
The devil's-advocate check192 words
Strongest case for "intended" (built by the cross-model refute and intended reviews, the intended-behaviour verifier and the adjudication): the layout is deliberate (LUCENE-9843, LUCENE-10536); the class is @lucene.experimental (Lucene90DocValuesFormat.java:140); the codec overview calls itself "a high-level definition" (lucene104/package-info.java:54); the bullets are informal prose, not a byte grammar; and "(< 256)" reads like "fits in a byte", a sufficient condition rather than the exact threshold (the bullet also leaves out the bits-saved test).
Why it fails: it defends the code, not the text. "Chunks of 16" is a specific number about the current default format, and Lucene90 has no 16-term path at all. The LZ4 step is not a detail a high-level description may skip, since the bytes after a block's first term cannot be read without decompressing them. @lucene.experimental warns of API changes, not of wrong docs. The constant was deleted from the same file without the sentence, and no discussion decided to keep it. Every verifier and the adjudication rejected the argument for the text; the "(< 256)" half is the weaker one (medium confidence), so it is presented as an imprecision fixed in the same edit.
Recommended A. Describe the 64-term LZ4 blocks and the inclusive 256 bound
Rewrite two javadoc bullets: terms are "written in blocks of 64, with the first value written completely and other values sharing prefixes; the rest of each block is compressed with LZ4, using the first value as a dictionary", and the lookup table is used for up to 256 unique values ("<= 256"). Javadoc only; no code changes.
All options and trade-offs3 options · 900 words
Three ways to resolve it, all javadoc-only; A was validated. Targets: main and branch_11x, and branch_10_6 if wanted (the two sentences are identical there).
A. Describe the 64-term LZ4 blocks and the inclusive 256 bound (validated by the checks) (recommended)
The hunt's text ("blocks of 64 ... the rest of each block is compressed with LZ4, using the first value as a dictionary. Block addresses ..." and "(<= 256)"), re-wrapped by the build's formatter (./gradlew tidy): as written, the hunt's <= 256 line is 101 columns and fails checkGoogleJavaFormat.
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java
index 777e76d9792..1c62864fea9 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java
@@ -74,10 +74,10 @@ import org.apache.lucene.util.packed.DirectWriter;
* <ul>
* <li>Delta-compressed: per-document integers written as deltas from the minimum value,
* compressed with bitpacking. For more information, see {@link DirectWriter}.
- * <li>Table-compressed: when the number of unique values is very small (< 256), and when there
- * are unused "gaps" in the range of values used (such as {@link SmallFloat}), a lookup table
- * is written instead. Each per-document entry is instead the ordinal to this table, and those
- * ordinals are compressed with bitpacking ({@link DirectWriter}).
+ * <li>Table-compressed: when the number of unique values is very small (<= 256), and when
+ * there are unused "gaps" in the range of values used (such as {@link SmallFloat}), a lookup
+ * table is written instead. Each per-document entry is instead the ordinal to this table, and
+ * those ordinals are compressed with bitpacking ({@link DirectWriter}).
* <li>GCD-compressed: when all numbers share a common divisor, such as dates, the greatest common
* denominator (GCD) is computed, and quotients are stored using Delta-compressed Numerics.
* <li>Monotonic-compressed: when all numbers are monotonically increasing offsets, they are
@@ -98,8 +98,9 @@ import org.apache.lucene.util.packed.DirectWriter;
* length}).
* <li>Variable-width Binary: one large concatenated byte[] is written, along with end addresses
* for each document. The addresses are written as Monotonic-compressed numerics.
- * <li>Prefix-compressed Binary: values are written in chunks of 16, with the first value written
- * completely and other values sharing prefixes. chunk addresses are written as
+ * <li>Prefix-compressed Binary: values are written in blocks of 64, with the first value written
+ * completely and other values sharing prefixes; the rest of each block is compressed with
+ * LZ4, using the first value as a dictionary. Block addresses are written as
* Monotonic-compressed numerics. A reverse lookup index is written from a portion of every
* 1024th term.
* </ul>
Trade-offs
- It states the numbers again (64 and 256), so a future layout change must update the text, as it should have in 9.0; both match the code (
TERMS_DICT_BLOCK_LZ4_SIZE,size() > 256). - "using the first value as a dictionary" is the LUCENE-10536 wording from CHANGES; "Block addresses" replaces the lower-case "chunk addresses".
- The table bullet stays as informal as today: besides at most 256 unique values, the writer needs 2 or more of them and ordinals that take fewer bits than the value range (
Lucene90DocValuesConsumer.java:485-488), which "unused gaps" only paraphrases. For the exact condition, a wording such as "a lookup table of up to 256 unique values is written instead when their ordinals need fewer bits than the values themselves" would state it (not validated). - Like the current text, A stays a high-level description (no token or vint grammar), not a spec to build a parser from.
What the checks validated
- Scratch worktree at
645d4fe14a20, 2026-11-01, JDK 25.0.3. Before the fix the minimal test fails there through gradle with assertions on and off (1 of 1,actual: [0]). - With the fix, a fix-check test passes 2 of 2 with assertions on and off. It asserts that for 65 terms
term00..term64exactly ords 0 and 64 are in.dvdin full, and that for 4,096 documents.dvdis under 8,192 bytes with 256 distinct values (a table, 8-bit ordinals) and over 8,192 bytes with 257; it printed 4,169 and 24,651 bytes. It does not check the LZ4 bytes, the token format or the dictionary. TestLucene90DocValuesFormat, the closest suite: 177 tests, 0 failures (23 nightly tests skipped).:lucene:core:check -x testpasses on the re-wrapped diff (on the hunt's unwrapped text it failed atcheckGoogleJavaFormat, where gradle stopped);:lucene:core:renderJavadocpasses and renders "very small (<= 256)" and "written in blocks of 64, ... compressed with LZ4, using the first value as a dictionary".- The fix-check test, the suite and the render ran on the same words before the re-wrap, which changes only line breaks inside a comment; the static checks ran on the final diff.
- The minimal test keeps failing after the fix, by design: it asserts the old text.
Replace the number and "chunk addresses", and leave out the LZ4 sentence and the 256 bound.
Trade-offs
Smallest diff, but it keeps the larger omission: the text would still not say that the rest of each block is LZ4-compressed. Not recommended.
What the checks validated
Not run (a subset of A).
Also fix "(< 256)" in backward-codecs Lucene80DocValuesFormat (:78), which repeats it; its "chunks of 16" (:102) is right for its default BEST_SPEED mode (TERMS_DICT_BLOCK_SHIFT = 4, :207), while its BEST_COMPRESSION mode wrote 64-term LZ4 blocks from 8.9.0.
Trade-offs
Frozen formats are rarely edited, and a precise text there must describe both modes.
What the checks validated
Not run.
No downstream runtime relevance: Lucene's reader and writer agree, so only an outside .dvd reader written from this javadoc would be affected.
Semi-formal: a check pulled the numeric claims out of the codec file-format javadocs ("written in chunks of N", "< N") and tested them against the bytes of .dvd files the default codec wrote. Independent reproducers, cross-model reviews and an adjudication confirmed it; runs on releases from 4.4.0 to main dated it.
The method in full174 words
- The hunt's check (part of a differential file-format check) extracted "written in chunks of 16" and "very small (< 256)" from the javadoc text and checked them on real files: for SORTED fields with 100, 300 and 1,000 distinct terms, which ords appear in clear; for NUMERIC fields of 4,096 documents with 254 to 258 distinct values, the
.dvdsize. The corrected text matched both checks. - An independent reproducer wrote its own test (200 terms
dvterm-000000todvterm-000199, all sharing the 10-byte prefixdvterm-000, plus controls: complete ords are exactly the multiples of 64; 255 values compact, 257 not); on 8.11.4 the same test sees 16-term chunks, so the method detects them where they exist. - A reviewer from another model family (OpenAI GPT-5.6) ran its own test on 9 seeds (5 with assertions on, 4 off) and a corrected-contract variant (4 of 4 pass); a second review, an intended-behaviour devil's advocate and an adjudication agreed it is real.
- This is a byte-level check of documentation claims, not model checking or a proof.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream trackers or the web (searched 2026-10-28, rechecked 2026-11-01). Nearest: LUCENE-9843, which made the text stale, and LUCENE-10536, whose CHANGES entry describes the real layout. Not fixed upstream.
Searches3 searches
- Related, not this bug: #10882 (LUCENE-9843, made the sentence stale; no javadoc remark in 18 comments); #11572 / PR #838 (LUCENE-10536, the 1 + 63 layout in CHANGES only); #10702 (LUCENE-9663, added the LZ4 blocks); #7921 (LUCENE-6863, 2015, outdated doc-values format javadocs replaced by the high-level text that is now stale); #6000 and #10996 (background on the 256 threshold); #16540 (2026-09-11, the file's last change) left both sentences. Tracking issue #16937 does not name it.
- Not fixed upstream: upstream main
f815e679bf6c(2026-11-01),branch_11xandbranch_10_6have both sentences at lines 77 and 101. - Open javadoc PR: #16949 ("Fix stale names and examples in javadocs") touches no codec file-format javadoc.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; the JIRA archive; downstream trackers | 2026-10-28 | three scripted prior-report searches (48 issue/PR queries, commits, downstream repositories, 12 JIRA-archive queries and the JIRA REST search); 35 manual GitHub searches; the changed files of all 414 open PRs and of 1,074 PRs closed since 2025-11-20; the file's history on main, branch_11x, branch_10x and branch_10_6 | no report; the nearest items made or described the layout change |
| Mailing lists and web | 2026-10-28 | 60 queries over dev@, java-user@, issues@ and commits@; 11 web searches | no report |
| apache/lucene (recheck) | 2026-11-01 | upstream main, branch_11x and branch_10_6 at lines 77 and 101; the file's commits; 8 searches ("Lucene90DocValuesFormat javadoc", "chunks of 16", "Prefix-compressed", "Table-compressed", "blocks of 64", ...); the 34 issues and PRs created since 2026-10-28; the files of #16949 and of open PRs updated since 2026-10-28 | no report; only #16896 (the producer) touches a Lucene90DocValues file |
Stale since LUCENE-9843 (a7a02519f0a, 2021-05-06), first released in 9.0.0: it removed the 16-term mode and its constant but not the sentence. 8.8.2 and the earlier default codecs are correct; 8.9.0-8.11.4 are wrong only in the non-default BEST_COMPRESSION mode. The "(< 256)" wording has been off by one since 4.5.0.
Versions tested7 rows
- 2013:
2c6bf041900("bump 4.5 codec", 2013-08-16) adds "(< 256)" while the writer already keeps the table up to 256;c2f37e0de2d("javadocs/cleanups", 2013-08-19) adds "chunks of 16", then true. Both reach 4.5.0 and are copied into every later doc-values format, intoLucene90DocValuesFormatby LUCENE-9705 (4d7b2aebfe0, 2021-02-22). - 2021: LUCENE-9663 (
5856c0f176c, 8.9.0) adds 64-term LZ4 blocks in the non-default BEST_COMPRESSION mode; LUCENE-9843 (a7a02519f0a, 2021-05-06, 9.0.0) makes them the only layout. - 2022: LUCENE-10536 (#838;
8f89db80480on main, backport1677be091ec, first released in 9.2.0) makes the first term of each block the LZ4 dictionary (9.0.0 and 9.1.0 compress without one) and describes "the other 63 terms of the block" in CHANGES; the class javadoc is not touched. - Before 9.0: the default doc-values formats of 4.5.0 to 8.x (Lucene45, 49, 410, 50, 54, 70, 80) each have a 16-term interval constant and the same sentence (read at 4.5.0, 4.9.0, 4.10.0, 5.0.0, 5.4.0, 6.0.0, 7.0.0 and 8.0.0); 8.8.2 writes 16-term chunks in both of its modes (executed).
- Releases: all 34 tags from 9.0.0 to 10.6.0 carry both sentences,
TERMS_DICT_BLOCK_LZ4_SHIFT = 6as the only block shift andsize() > 256in the writer.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails with assertions on and off (gradle and standalone): only ord 0 in full |
10.6.0 (4ae946e5a9b, tested as the branch_10_6 head), 10.5.2, 10.0.0, 9.12.3, 9.1.0 | affected | the hunt's test fails 2 of 2: ords in full [0, 64] for 100 terms; 256 values table-compressed |
| 9.0.0 | affected | the same failures; the first release after LUCENE-9843 |
| 8.9.0, 8.11.4 | non-default mode only | default BEST_SPEED writes 16-term chunks (ords 0, 16, 32, ...); BEST_COMPRESSION writes ords 0, 64, 128, 192 in full |
| 8.8.2 | "< 256" only | both modes write 16-term chunks (correct); only the "(< 256)" check fails |
| 4.5.0 | "< 256" only | 256 values table-compressed (4,126 vs 21,023 bytes at 257); the first javadoc with the number |
| 4.4.0 | not affected | the same behaviour, but the javadoc gives no number |
Confirmed by an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication (high confidence); a credibility audit confirmed it as a minor documentation defect. This doc's gradle run validated the fix.
Checks and verdicts291 words
Every check re-ran a test on main or read the same lines; none found a reading under which the text describes the current format.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own test fails 2 of 4 on main (-ea, -da), 10.5.2, 9.12.3 and 9.0.0, its controls passing; on 8.11.4 the chunks-of-16 test passes, so the method sees 16-term chunks where they exist. |
| cross-model review, refute lens (OpenAI GPT-5.6, executing) | real, high confidence | Own test fails on 9 seeds (5 with assertions on, 4 off); controls pass; a corrected-contract variant passes 4 of 4; the intended argument is strong for the code, not the javadoc. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading) | real, high confidence | Read only; a separate run re-ran the finder's test on main (2 of 2 fail). |
| intended-behaviour devil's advocate | real: high for "chunks of 16", medium for "< 256" | Weighed @lucene.experimental, the informal-prose reading, "fits in a byte" and the LUCENE-10536 CHANGES entry; none makes the text intended. |
| adjudication | confirmed, high confidence, documentation | Re-ran the independent reproduction's test with assertions on and off: 2 of 4 fail, controls pass. |
| credibility audit | confirmed, minor | Re-ran the finder's test on a new seed; re-read the writer, constants and javadoc; impact minor not inflated. |
| this doc's validation (2026-11-01) | fix A validated | Fix A in a scratch worktree at 645d4fe14a20: a fix-check test passes 2 of 2 with assertions on and off (asserts ords 0 and 64 in full for 65 terms, and a .dvd under 8,192 bytes for 256 values and over it for 257; it printed 4,169 and 24,651); TestLucene90DocValuesFormat 177 tests, 0 failures; check -x test and renderJavadoc pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 381 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,708 words
- Registry title
- The file-format javadoc of the default doc-values format (Lucene90DocValuesFormat) says terms dictionaries are 'written in chunks of 16, with the first value written completely', but since 9.0 they are written in blocks of 64 terms whose other 63 terms are prefix-coded and then LZ4-compressed; it also says table compression is used for fewer than 256 unique values, while exactly 256 are table-compressed (documentation defect; the writer and reader agree)
- Area
- codecs / doc values (Lucene90DocValuesFormat class javadoc prose vs Lucene90DocValuesConsumer)
- Priority
- Low, rank 1284: The doc-values javadoc describes 16-term chunks without LZ4 while the writer uses 64-term LZ4 blocks, which misleads .dvd re-implementers for every SORTED and SORTED_SET field.
- Impact class
- minor
- Impact note
- Documentation only: Lucene's writer and reader agree, so indexing, merging, CheckIndex, sorting, faceting and search on doc values are unaffected in every configuration; the people misled are those who read, inspect or re-implement the .dvd format from this class javadoc (the default codec's package docs link it as the Per-Document Values format), who are told that every 16th term is stored in full and nothing about LZ4, while every SORTED and SORTED_SET terms dictionary the default codec writes stores only every 64th term in full and LZ4-compresses the rest (executed for SORTED, SORTED_SET read from the shared writer code); the 'chunks of 16' sentence has been stale since 9.0.0 (2021), the '< 256' wording is a one-value imprecision from 4.5.0 (2013), and no scale or special setting is needed.
- Summary
- You read the Lucene90DocValuesFormat javadoc to learn how the default codec stores the terms of SORTED and SORTED_SET doc values, and it says they are written in chunks of 16 terms, each starting with one term written in full while the others share prefixes. Since Lucene 9.0 the writer instead uses blocks of 64 terms: only the first term of each block is stored in full, and the other 63 are prefix-coded and then compressed with LZ4, a step the javadoc never mentions, so in the .dvd file only terms 0, 64, 128, ... appear in clear, not 0, 16, 32, .... The same javadoc says a lookup table is used for numeric fields with fewer than 256 unique values, but a field with exactly 256 is also table-compressed; Lucene's own reader matches the writer, so nothing breaks at runtime, only the documentation is wrong.
- Introduced
- a7a02519f0a5652110a186f4909347ac3349092d (LUCENE-9843 'Remove compression option on default codec's docvalues', now apache/lucene#10882; landed from a JIRA patch, no GitHub PR; committed by rmuir, CHANGES credits the patch to jdconrad; main only, never on branch_8x): it removed the doc-values compression modes so that terms dictionaries always use 64-term LZ4 blocks, and its diff of Lucene90DocValuesFormat.java deleted TERMS_DICT_BLOCK_SHIFT = 4 (the 16-term constant) but left the 'chunks of 16' sentence untouched [read: git show in the full-history clone; exec: the finder's chunks-of-16 test passes on 8.8.2, 8.9.0 and 8.11.4 and fails from 9.0.0 on]. Older parts [read + exec]: the sentence itself comes from c2f37e0de2d (2013-08-19, 'javadocs/cleanups', Lucene45DocValuesFormat, by rmuir), when it was true (ADDRESS_INTERVAL = 16), and was copied into Lucene90DocValuesFormat by 4d7b2aebfe0 (LUCENE-9705, apache/lucene-solr#2392, 2021-02-22); the '(< 256)' wording comes from 2c6bf041900 (2013-08-16, 'bump 4.5 codec', by rmuir) and was off by one from the start (the writer has always dropped the table only when size() > 256). A narrower earlier form: LUCENE-9663 (5856c0f176c on main, b61b19c746a on branch_8x, apache/lucene-solr#2302) made the sentence wrong for the non-default BEST_COMPRESSION mode of Lucene80DocValuesFormat in 8.9.0-8.11.4 (2021-05-06 (author and commit date of a7a02519f0a, the main part); 2013-08-16 (2c6bf041900, the '< 256' wording); 2021-02-09 author / 2021-02-15 commit (5856c0f176c, LUCENE-9663, the non-default-mode form, on branch_8x as b61b19c746a on 2021-03-17))
- First affected version
- 9.0.0 [exec] for the main claim in the default codec (the last unaffected release is 8.11.4 [exec], whose default BEST_SPEED mode really writes 16-term chunks); 8.9.0 [exec] for the narrower form in the non-default BEST_COMPRESSION mode; 4.5.0 [exec] for the '< 256' wording (4.4.0 [exec] behaves the same but its javadoc gives no number)
- Affected versions
- every release from 9.0.0 through 10.5.2 (33 releases), 10.6.0 (the branch_10_6 head 4ae946e5a9b) and main a9779ef3c193; not fixed upstream [exec: the finder's JUnit fails 2 of 2 on 9.0.0 (pre-9.1 test-package variant), 9.1.0, 9.12.3, 10.0.0, 10.5.2, the branch_10_6 head and main (-ea and -da); the independent reproduction's JUnit fails 2 of 4, its two controls passing, on main (-ea and -da), 10.5.2, 9.12.3 and 9.0.0; read: all 33 9.x and 10.x release tags carry the same two sentences, TERMS_DICT_BLOCK_LZ4_SHIFT = 6 as the only block shift and 'size() > 256' in the writer]. For 'chunks of 16' before 9.0: 8.9.0-8.11.4 are affected only in the non-default BEST_COMPRESSION mode [exec 8.9.0 and 8.11.4: that mode writes ords 0, 64, 128, 192 in clear, BEST_SPEED writes 0, 16, 32, ...], and 8.8.2 and older are not affected [exec 8.8.2: both modes write 16-term chunks]. The '< 256' wording is inexact in every release from 4.5.0 [exec 4.5.0, 8.8.2, 8.9.0, 8.11.4, 9.0.0 and later]; the frozen backward-codecs Lucene80DocValuesFormat repeats both sentences (not part of this finding). Caveats: all runs used JDK 25 on Linux aarch64; the releases between the executed ones were read from the tags; upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 77 and 101 [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-28: three scripted prior-report searches over GitHub issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the JIRA REST search, and downstream repositories; 35 manual GitHub searches incl. downstream trackers and the last 48 hours; 11 web searches; all 414 open apache/lucene PRs, the 50 open PRs updated since 2026-10-26 and 1074 PRs closed since 2025-11-20 checked by changed files for this file; the file's history on main, branch_11x, branch_10x and branch_10_6; GitHub phrase search treats numbers loosely, so file-list and history checks back it up). Nearest items, not the same bug: #10882 / LUCENE-9843 (made the sentence stale; 18 comments, none about the javadoc), #11572 / PR #838 / LUCENE-10536 (its CHANGES entry gives the correct 1 + 63 layout; no comment about the javadoc), #10702 / LUCENE-9663 (added the LZ4 blocks), #7921 / LUCENE-6863 (2015 precedent: outdated doc-values format javadocs replaced by the high-level text that is now stale), #6000 / LUCENE-4936 and #10996 (background on the 256 threshold), open #16358, #15737 and #562 (touch only skip-index and version constants of the file), #16540 (last change to the file, 2026-09-11, left both sentences). Tracking issue #16937 does not name it. Recheck (2026-10-28): six searches ('Lucene90DocValuesFormat javadoc', '"chunks of 16"', 'DocValuesFormat "Prefix-compressed"', 'terms dictionary LZ4 javadoc', '"Table-compressed" doc values', 'doc values javadoc 256 unique values') find no report; none of the 31 apache/lucene issues and PRs created since 2026-10-26 (including a series of javadoc fixes, #16920-#16922, #16927, #16928, #16933-#16936) concerns it; of the open PRs updated since 2026-10-27 only #16896 (Lucene90DocValuesProducer.java) and #16480 (lucene104/package-info.java, a History bullet) touch related files, neither this javadoc; by author date the file's latest upstream commits are 1160d3c8a256 (#16540, 2026-09-11) and 696f4e7d81d6 (#15993, 2026-05-20); upstream main 645d4fe14a20 (2026-10-28) still has the stale lines 77 and 101. Not fixed upstream.
- Lucene commit tested
- main
645d4fe14a20: the minimal repro through gradle with assertions on and off, and standalone (-eaand-da); the recommended fix in a scratch worktree (a fix-check test of the corrected text's block size and table bound,TestLucene90DocValuesFormat,:lucene:core:check -x testand:lucene:core:renderJavadoc). The hunt's tests on 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2, 10.6.0 (4ae946e5a9b, tested as the branch_10_6 head) and maina9779ef3c193, and on 4.4.0, 4.5.0, 8.8.2, 8.9.0 and 8.11.4 for the history. All 34 release tags from 9.0.0 to 10.6.0 read for the two sentences and the constants, and the default doc-values formats of 4.5.0, 4.9.0, 4.10.0, 5.0.0, 5.4.0, 6.0.0, 7.0.0 and 8.0.0 for the 16-term constant; upstream mainf815e679bf6c,branch_11xandbranch_10_6read on 2026-11-01 (both sentences unchanged).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java:77 ('Table-compressed: when the number of unique values is very small (< 256)'), :101-104 ('Prefix-compressed Binary: values are written in chunks of 16, with the first value written completely and other values sharing prefixes'), :140 (@lucene.experimental), :217-219 (TERMS_DICT_BLOCK_LZ4_SHIFT = 6, SIZE, MASK); identical at Lucene main ea57360912edlucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:434 (unique-value table dropped only when size() > 256), :755 and :1061 (SORTED and SORTED_SET both call addTermsDict), :758-849 (addTermsDict: block mask and shift from TERMS_DICT_BLOCK_LZ4_*, the first term of each block written with writeVInt(length) in clear, the others prefix-coded into a buffer, LZ4.compressWithDictionary at :849)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:54 ('a high-level definition'), :172 and :288 (link Lucene90DocValuesFormat as Per-document values), :188 ('Details on each of these are provided in their linked pages')lucene/test-framework/src/java/org/apache/lucene/tests/index/LegacyBaseDocValuesFormatTestCase.java:1358-1359 and :1517-1518 ('for numbers of values <= 256, all storage layouts are tested')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java (lines 77, 101-104, 110, 217-219)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java (lines 434, 485-488, 492-494, 755, 758-842, 823, 844-851, 883-893, 1061)a Lucene clone release tags 9.0.0, 9.1.0 and 9.2.0: Lucene90DocValuesConsumer.java (LZ4.compress at :626 in 9.0.0 and 9.1.0; dictLength and LZ4.compressWithDictionary from 9.2.0)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java (lines 392-393, 1770, 1792, 1950)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 54, 172, 188, 288)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java (line 122)
- Why it looks unintended
lucene/CHANGES.txt (lines 4176, 4257-4259, 4630, 4751)lucene/core/src/test/org/apache/lucene/codecs/lucene90/TestLucene90DocValuesFormat.java (lines 1116, 1204)lucene/test-framework/src/java/org/apache/lucene/tests/index/LegacyBaseDocValuesFormatTestCase.java (lines 1359, 1518)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java (lines 89, 140) and lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 54, 188)
- Suggested fix
lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene80/Lucene80DocValuesFormat.java (lines 78, 102, 207) and Lucene80DocValuesConsumer.java (line 220)
- History
a Lucene clone: tag --contains 1677be091ec (first 9.2.0); git grep of the doc-values constants and the sentence at 4.5.0, 4.9.0, 4.10.0, 5.0.0, 5.4.0, 6.0.0, 7.0.0, 8.0.0
- TestLucene90DocValuesTermsChunks.java (JUnit, one test):
repro/LFV-974/src/org/apache/lucene/codecs/lucene90/TestLucene90DocValuesTermsChunks.java(69 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed repro (17 terms: only ord 0 in full).
assets/LFV-974/bug.png(381 KB)