Float.toStringwrites plain decimals only from 0.001 up to just below 10,000,000 (0.5,2.5). Outside that range it uses scientific notation:0.0009fprints9.0E-4.- The query syntax after
^accepts only digits with an optional.digits(2,0.5,0.0009). It has no exponent, so9.0E-4is not a number to it.
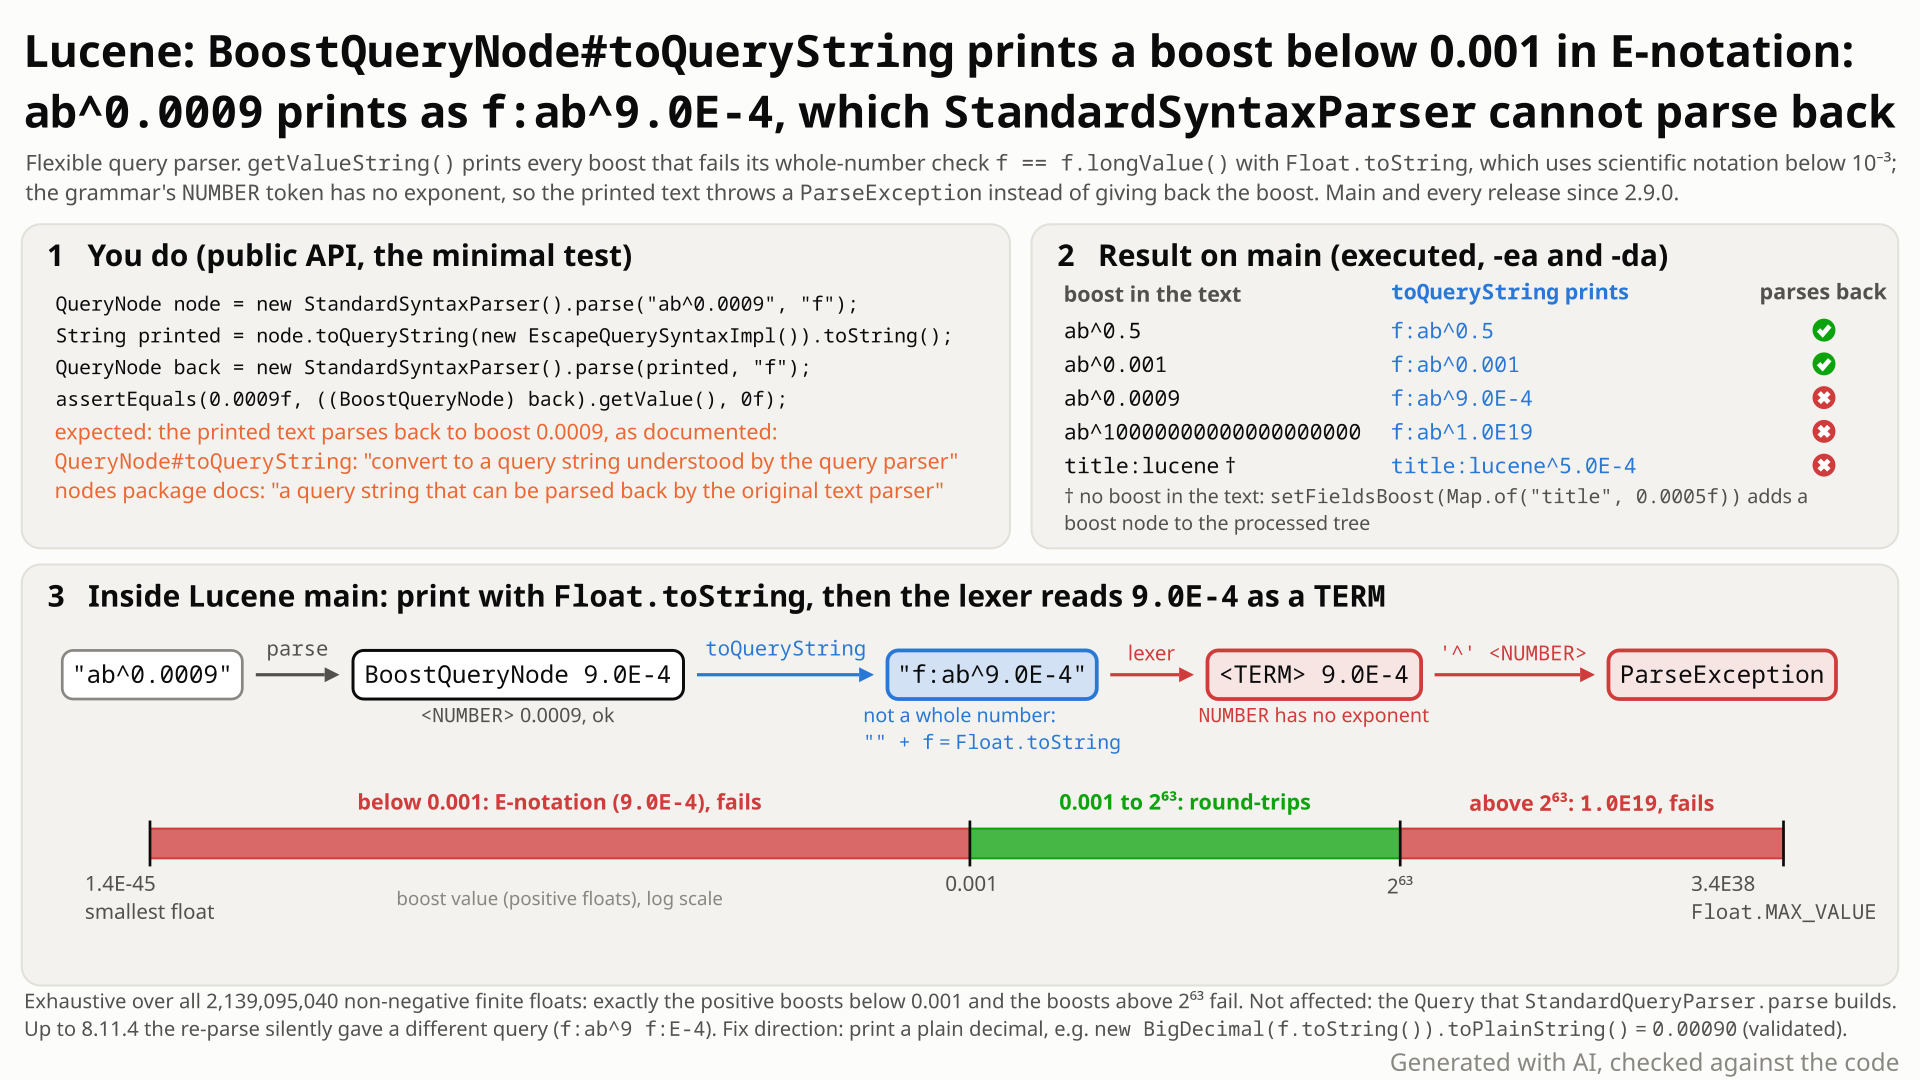
ab^0.0009 becomes a boost node holding 0.0009; toQueryString prints it as ab^9.0E-4, and the same parser rejects that text when it reads it back. Select the still to open it at full size. Generated with AI, checked against the code.- Parse
ab^0.0009with the flexibleStandardSyntaxParser, the syntax parser behindStandardQueryParser. The tree is aBoostQueryNodewith boost 0.0009. - Print the tree with
toQueryString(new EscapeQuerySyntaxImpl()). You expect text the parser reads back: the method is documented to produce "a query string understood by the query parser". - Instead you get
f:ab^9.0E-4. The node prints the boost with Java'sFloat.toString, which switches to scientific notation below 0.001. Boosts above 2^63 are hit too:1e19prints1.0E19. - Parsing
f:ab^9.0E-4again throwsParseException: after^the grammar accepts only digits with an optional.digits. Before 9.0 the same text silently became a different query,f:ab^9 f:E-4. - Search is unaffected:
StandardQueryParser.parsebuilds the right boost. The fuzzy node has the same pattern in a different method, and there it is silent today:ab~0.0001printsab~1.0E-4, which re-parses asab~2plus an extra term.
Applications that print a flexible-parser syntax tree, a hand-built boost node or a tree with a configured field boost via toQueryString, then parse or forward the text, when a boost is below 0.001 (usually a computed one) or above 2^63. Default configuration. Searches built by StandardQueryParser.parse are unaffected.
Mechanism, terms and numbers696 words
The flexible query parser reads a boost ^N into a BoostQueryNode holding a float. To print it, toQueryString() and toString() write a whole-number boost as a long and every other boost with Float.toString, which uses scientific notation below 0.001. So ab^0.0009 prints f:ab^9.0E-4. The grammar's number token has no exponent, so the same parser rejects that text with ParseException; before 9.0.0 it silently read it as a different query (f:ab^9 f:E-4). Above 2^63 the whole-number check overflows and 1e19 prints 1.0E19, with the same result. An exhaustive check ran the real printer on all 2,139,095,040 non-negative finite floats and classified its output with a model of the grammar's number token (validated against the real parser in 761,082 checks): exactly the boosts in (0, 0.001) and above 2^63 print text that does not parse back; every other boost round-trips. That breaks the documented promise that a node tree prints "a query string that can be parsed back by the original text parser". Original parsing and search are unaffected: the Query built from the original text is correct, and the impact appears only when printed node text is reused as query syntax. FuzzyQueryNode has the same pattern in a different method (ab~0.0001 prints ab~1.0E-4), and there the re-parse silently builds a different query. The fix prints a plain decimal (BigDecimal.toPlainString) in both nodes.
- Parse side. The grammar's
Boostrule reads'^' <NUMBER>and buildsnew BoostQueryNode(node, Float.parseFloat(...))(StandardSyntaxParser.jj:695-702,:115-116). The node stores afloat(BoostQueryNode.java:33). - Print side (
BoostQueryNode.java:80-84):
private CharSequence getValueString() {
  Float f = Float.valueOf(this.value);
  if (f == f.longValue()) return "" + f.longValue();   // whole numbers up to 2^63
  else return "" + f;                                  // Float.toString: 9.0E-4, 1.0E19
}
toQueryString returns the child's text + "^" + getValueString() (:91-95), and toString prints <boost value='...'> with the same helper (:86-89).
- The grammar.
NUMBERis(<_NUM_CHAR>)+ ( "." (<_NUM_CHAR>)+ )?with no exponent (StandardSyntaxParser.jj:160), whileTERM(:161) accepts digits,.,Eand-. By longest match9.0E-4lexes as one term, soBoost ::= '^' <NUMBER>(:688-703) fails.
Float.toString is plain only for magnitudes in [10^-3, 10^7). Every non-integral float is below 2^23, and integral floats up to 2^63 take the long branch, so [0.001, 2^63] always prints plainly. Below 0.001 the else branch prints 9.0E-4. Above 2^63 longValue() saturates at Long.MAX_VALUE, the equality fails and 1e19 prints 1.0E19. An exhaustive run printed all 2,139,095,040 non-negative finite floats with the real BoostQueryNode and classified each output with a model of the NUMBER token (the model agreed with the real parser in all 761,082 real-parser checks on a sample around the notation switches and at random). It found 981,668,462 failures in (0, 0.001) and 545,259,519 above 2^63, and none elsewhere. A grid through 15 host constructs (term, phrase, group, ranges, wildcard, regexp, ...) gave 5,700 ParseExceptions in 19,620 checks and no silent difference.
FuzzyQueryNode.toQueryString appends "~" + this.similarity (FuzzyQueryNode.java:50-57). The grammar's number after ~ is optional (StandardSyntaxParser.jj:712-729), so f:ab~1.0E-4 re-parses without error as ~ with the default 2 edits plus a separate term 1.0E-4. ab~0.0001 builds f:ab~1; its printed text builds f:ab~2 f:1.0e-4, which matched 1 document instead of 0 on a one-document index. That witness is narrow: the edit count changes only for 1-2 character terms (FuzzyQuery.floatToEdits already gives 2, the cap, for 3 or more, so abcd~0.0001 builds f:abcd~2). The extra clause is there for every term: under the default OR operator it widens the query (f:abcd~2 f:1.0E-4), under AND it narrows it (+f:abcd~2 +f:1.0E-4), and what it matches depends on the analyzer.
BoostQueryNodeBuilder copies getValue() into the BoostQuery (BoostQueryNodeBuilder.java:48), so StandardQueryParser.parse("ab^0.0009", "f") searches with boost 0.0009. Apart from the node printers themselves (composite nodes print their children; IntervalQueryNode.toString() returns its own toQueryString), Lucene puts toQueryString output only into exception messages (for example QueryTreeBuilder.java:161); it never parses it again.
Exposure and likelihood178 words
- Who. Code that turns node trees back into text to log, display, cache, forward or rewrite a query and then parses it again. The usual source is the syntax tree from
StandardQueryParser.getSyntaxParser().parse(text, field), plus hand-builtBoostQueryNodetrees and processed trees with a configured field boost (setFieldsBoost(Map.of("title", 0.0005f))printstitle:lucene^5.0E-4). No option is needed. - Trigger. A boost below 0.001 or above 2^63. Such boosts mostly come from code that computes them; a 2019 java-user post shows a client generating
foo:bar^2.77E-4. - Effect. Since 9.0.0 the printed query cannot be parsed again (
ParseException), a loud failure. From 2.9.0 to 8.11.4 it silently re-parsed as a different query (f:ab^9 f:E-4). The fuzzy leg is silent on current releases. - Not affected. Search results: the query is built from the exact float. Lucene's own code never re-parses the text.
- Likelihood: rare. It needs both the print-and-reuse pattern and an unusual boost; it is deterministic when both are present, and no matching public report was found in the recorded searches, although the code dates from 2.9.0 (2009).
One JUnit class with one test method on the public API: parse ab^0.0009 with StandardSyntaxParser, print it with toQueryString, and parse the printed text again expecting boost 0.0009. No index, nothing random; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.flexible.core.nodes;

import org.apache.lucene.queryparser.flexible.core.QueryNodeParseException;
import org.apache.lucene.queryparser.flexible.standard.parser.EscapeQuerySyntaxImpl;
import org.apache.lucene.queryparser.flexible.standard.parser.StandardSyntaxParser;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBoostQueryNodeToQueryString extends LuceneTestCase {

  public void testSmallBoostParsesBack() throws Exception {
    QueryNode node = new StandardSyntaxParser().parse("ab^0.0009", "f");
    String printed = node.toQueryString(new EscapeQuerySyntaxImpl()).toString();
    // expected: text that parses back to boost 0.0009; actual: f:ab^9.0E-4, a ParseException
    try {
      QueryNode back = new StandardSyntaxParser().parse(printed, "f");
      assertEquals(0.0009f, ((BoostQueryNode) back).getValue(), 0f);
    } catch (QueryNodeParseException e) {
      throw new AssertionError("expected text that parses back, got " + printed, e);
    }
  }
}
cd $LUCENE && ./gradlew :lucene:queryparser:test --tests TestBoostQueryNodeToQueryString -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- The printed text parses back to a
BoostQueryNodewith boost 0.0009. - Observed
AssertionError: expected text that parses back, got f:ab^9.0E-4, caused byINVALID_SYNTAX_CANNOT_PARSE, with assertions on and off.
More files, environment, full output298 words
The class sits in BoostQueryNode's package (org.apache.lucene.queryparser.flexible.core.nodes) so it can live next to the class upstream; it uses no package-private access. The seed only satisfies LuceneTestCase. It asserts only the documented round trip (the same boost after re-parsing), not an exact printed string.
Regression test: this same class (or its one method added to the existing TestQueryNode); it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; releases 10.5.2 and 10.6.0: fail; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; plain Float.toString, whose notation switch is in the Java SE API) |
cp $REPRO/TestBoostQueryNodeToQueryString.java $LUCENE/lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/core/nodes/
cd $LUCENE && ./gradlew :lucene:queryparser:test --tests TestBoostQueryNodeToQueryString -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
TestBoostQueryNodeToQueryString > testSmallBoostParsesBack FAILED
    java.lang.AssertionError: expected text that parses back, got f:ab^9.0E-4
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1EF405E732EBE7EA]:0)
        at org.apache.lucene.queryparser.flexible.core.nodes.TestBoostQueryNodeToQueryString.testSmallBoostParsesBack(TestBoostQueryNodeToQueryString.java:34)

        Caused by:
        INVALID_SYNTAX_CANNOT_PARSE: Syntax Error, cannot parse f:ab^9.0E-4:
            at app//org.apache.lucene.queryparser.flexible.standard.parser.StandardSyntaxParser.Boost(StandardSyntaxParser.java:1061)

# standalone runner, seed DEADBEEF: main 645d4fe14a20 fails with -ea and -da; 10.5.2 (-ea, -da) and 10.6.0 fail

# a 15-row boost test on stock main (gradle): printed text and whether it parses back
ab^0.001 -> f:ab^0.001 : ok
ab^0.5 -> f:ab^0.5 : ok
ab^0.0009999999 -> f:ab^9.999999E-4 : does not parse back (ParseException)
ab^0.00090 -> f:ab^9.0E-4 : does not parse back (ParseException)
ab^9223373000000000000 -> f:ab^9.223373E18 : does not parse back (ParseException)
ab^10000000000000000000 -> f:ab^1.0E19 : does not parse back (ParseException)
fieldsBoost 5.0E-4 -> title:lucene^5.0E-4 : does not parse back (ParseException)

# the same mistake in the fuzzy node, stock main (gradle)
java.lang.AssertionError: ab~0.0001 -> f:ab~1.0E-4: q1=f:ab~1 q2=f:ab~2 f:1.0e-4 expected:<0> but was:<1>

# before 9.0 (8.11.4, a public-API probe)
ab^0.0009 -> f:ab^9.0E-4 : parsed back as a different query: f:ab^9 f:E-4 (BooleanQueryNode)- The javadoc promises "a query string understood by the query parser"; the package doc, one that "can be parsed back by the original text parser".
- Upstream fixed the same broken round trip for range nodes as a bug (GITHUB#7865, Lucene 11.0.0).
ab^0.0009is ordinary syntax: the parser accepts it and builds the right boost, then prints text it rejects.
The full argument167 words
- The contract:
QueryNode.java:26("convert to a query string understood by the query parser");core/nodes/package-info.java:42-43("A query node tree can also generate a query string that can be parsed back by the original text parser, at this point only the standard lucene syntax is supported."). Both date from 2.9.0. - Upstream enforces it: GITHUB#7865, fixed by #14697 (merged 2025-05-29): "AbstractRangeQueryNode#toQueryString(EscapeQuerySyntax) now returns a string which can be parsed back into the original node" (
lucene/CHANGES.txt:296-298, 11.0.0 bug fixes), withTestAbstractRangeQueryNodeparsing the printed string back. - Ordinary input:
StandardQueryParser's javadoc documents "a floating-point weight boost" (jones^2 OR smith^0.5) with no lower bound, and 0.0009 is even inside the class javadoc's own (stale) range "0.0 to 1.0". - The grammar was never meant to take exponents (a 2006 java-user reply about the classic parser: scientific notation would be a new feature; for the flexible grammar this is an inference), so the printer is the place to fix.
- Tests: no upstream test references
BoostQueryNodeor asserts its printed form.
The devil's-advocate check272 words
The strongest case for "intended": in a 2017 java-user thread about range queries parsed twice, a committer replied: "There has never been a guarantee that going back and forth between a parsed query and its string representation is idempotent. so this isn't supported." Add that Float.toString is the normal Java rendering, that the grammar has no exponent on purpose, that Lucene uses toQueryString only for messages, that processor-only nodes print unparseable text ([TP[...]]), that the open #8667 (LUCENE-7616) calls the method "a design error" that "could never work as currently designed" (for custom syntaxes), and that BoostQuery.toString prints E-notation too.
Our answer, and its limits: in the same thread a PMC member replied "Why don't we fix this in Lucene? ... Could you open an issue and add a patch?", and the project later fixed exactly that range case as a bug (#7865 / #14697). The written contract says parse-back; Query.toString makes no such promise. #8667 is about custom syntaxes, while this is standard syntax to standard syntax, and StandardSyntaxParser produces BoostQueryNode from input it accepts. A grammar without exponents points at the printer as the fix site. This is a credible case for a bug, not a proof: #7865 concerned range nodes, so it is a precedent rather than a ruling on every node, and the processor-only nodes show the promise is not kept everywhere. Verifiers, the adjudication and a tie-break rejected the intended-behaviour case and a read-only cross-model review rated it weak; a later cross-model fact check rated the intended-behaviour case moderate for the boost leg, strong for boosts above 2^63 only, and weak for the fuzzy leg.
Recommended Print a plain decimal in both nodes (validated)
Print a plain decimal: in BoostQueryNode.getValueString(), replace the Float.toString fallback with new BigDecimal(f.toString()).toPlainString() (Infinity and NaN unchanged), and do the same in FuzzyQueryNode.toQueryString(). 0.0009 then prints 0.00090, which parses back; boosts that printed correctly before are unchanged. It passes the repro and the whole queryparser module.
private CharSequence getValueString() {
  Float f = Float.valueOf(this.value);
  if (f == f.longValue()) return "" + f.longValue();
  // The grammar's NUMBER token has no exponent: print a plain decimal, never Float.toString's
  // E-notation (9.0E-4, 1.0E19), which does not parse back.
  else if (f.isInfinite() || f.isNaN()) return "" + f;
  else return new BigDecimal(f.toString()).toPlainString();
}
All options and trade-offs3 options · 568 words
Two variants of the printer fix were written and validated in a scratch worktree of 645d4fe14a20; the grammar-side alternative is described but not run.
In BoostQueryNode.getValueString() keep the whole-number branch and Float.toString for Infinity and NaN, and otherwise print new BigDecimal(f.toString()).toPlainString(). In FuzzyQueryNode.toQueryString() print new BigDecimal(Float.toString(similarity)).toPlainString() for finite values in both return lines. +14/-3 in the two files, including the imports. The boost half alone fixes this repro; the fuzzy half fixes the merged fuzzy leg.
private CharSequence getValueString() {
  Float f = Float.valueOf(this.value);
  if (f == f.longValue()) return "" + f.longValue();
  // The grammar's NUMBER token has no exponent: print a plain decimal, never Float.toString's
  // E-notation (9.0E-4, 1.0E19), which does not parse back.
  else if (f.isInfinite() || f.isNaN()) return "" + f;
  else return new BigDecimal(f.toString()).toPlainString();
}
Trade-offs
BigDecimal(Float.toString(f))is the exact decimalFloat.toStringchose, so its plain form parses back to the identical float. Text that was already plain is unchanged (0.5,2.0).- Cosmetic:
0.0009prints0.00090and the fuzzy~0.0001prints~0.00010(the trailing zero comes from9.0E-4);1e19prints10000000000000000000. - Printing only; one
BigDecimalper printed non-integral value. Parsing does not change. - Visible output:
toString()shares the helper, so<boost value='9.0E-4'>becomes<boost value='0.00090'>; exact-string tests, snapshots or log parsers that captured the old text see the new one (only for values that printed in E-notation). Very small values become long plain decimals:Float.MIN_VALUEprints as 48 characters (it still parses back). - Out of scope: negative, NaN and infinite boosts. The grammar cannot produce them (no sign after
^) andBoostQueryrejects them (BoostQuery.java:40-41); a hand-built node printsf:ab^-0.5,f:ab^NaNorf:ab^Infinity, which does not parse back with or without the fix.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, OpenJDK 25.0.3, seed DEADBEEF (2026-10-31): stock, the minimal test fails with assertions on and off, the 15-row boost test fails 2 of 2 and the fuzzy leg's test fails 2 of 2. With the fix: the minimal test passes with assertions on and off; the 15-row test passes and every control prints exactly as before; the fuzzy test passes 2 of 2;TestQueryNodepasses; the whole queryparser module passes (30 classes, 533 tests, 0 failures);checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainpass for the module. - Earlier: a model of the boost fix had 0 failures over all 2,139,095,040 non-negative finite floats and caught a lossy mutant; the boost half passed the hunt's, a verifier's and the registration check's tests, and upstream
TestQPHelper,TestAbstractRangeQueryNodeandTestQueryNode(43 of 43).
new BigDecimal(f.toString()).stripTrailingZeros().toPlainString() in getValueString(), so ab^0.0009 prints ab^0.0009, the input back.
Trade-offs
Values already printed plainly are unchanged (a non-integral Float.toString result has no trailing zero). Do not use it in the fuzzy node: it would change today's ~2.0 to ~2.
What the checks validated
Same scratch worktree: the minimal test passes; the 15-row test passes and prints f:ab^0.0009, f:ab^0.0001 and title:lucene^0.0005; the whole queryparser module passes (533 tests, 0 failures).
Not run.
Trade-offs
Old printed text would parse, but it changes accepted syntax and how terms such as 1e5 are tokenized, for a bug in the printer. A 2006 list reply calls scientific notation a new feature.
The query built from the original text is unchanged; only services that log, cache or forward printed node trees as the canonical query and parse them again are hit: they get text their own parser rejects for such boosts, and for the fuzzy node a silently different query.
While verifying the sibling slop-node bug, reviewers noticed that the boost node uses the same printing helper on a real float. A parse, print and re-parse probe over the node printers then showed a^0.0009 printing a^9.0E-4, and an exhaustive check of every non-negative float found exactly two failing ranges.
The method in full132 words
Method: non-formal first signal (a differential round-trip probe), then bounded-exhaustive translation validation of the stock printer and a public-API JUnit.
- Signal. Code reading during the verification of LFV-892 (slop nodes print their int through a float) noted the lead; a planning probe (parse,
toQueryString, re-parse, compare) executed it on stock main. - Exhaustive check. All 2,139,095,040 non-negative finite floats through the real
BoostQueryNodeprinter against a model of theNUMBERtoken (the model agreed with the real parser on 761,082 checks): exactly (0, 0.001) and (2^63, max] fail; 3,515 s on 4 threads. A host-construct grid throughStandardQueryParser(19,620 checks) found only loud failures. - Confirmation. An independent reproducer, a devil's-advocate verifier, read-only cross-model reviews (OpenAI GPT-5.6), an adjudication, the version-history runs, a prior-report search, a current-main reproducer and a tie-break checked it.
No matching public report found in the recorded searches (416 logged queries on 2026-10-31 over GitHub, JIRA, the mailing lists and the web). Related: GITHUB#7865, the same round-trip contract fixed for range nodes.
Searches4 searches
Verdict new, for both the boost and the merged fuzzy leg: in the recorded searches, no issue, PR, JIRA entry or list thread says that BoostQueryNode or FuzzyQueryNode prints numbers in E-notation or that their printed text does not parse back; no open PR touches either node or the grammar. Closest items: #8667 (open design issue on toQueryString for custom syntaxes), #9064 (open proposal to bound boosts to [2^-10, 2^10]; it would not remove the low leg, since 2^-10 prints 9.765625E-4), and java-user posts of 2006 and 2019 about E-notation boosts typed into the classic parser's input. Open PRs #16853 and #16892 change other round trips in this module.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and code (apache/lucene, lucene-solr, lucenenet, solr, two downstream search engines, all of GitHub), plus the scripted prior-report search's list, JIRA and downstream rows | 2026-10-31 | a scripted prior-report search with 5 query variants (255 rows: GitHub, commit, downstream, list, JIRA and web placeholders) plus 73 manual GitHub searches; the file lists of all 409 open apache/lucene PRs; the 53 items updated since 2026-10-28 | no report; related: #7865 / #14697 (range-node round trip), #8667, #9064, #16853, #16892 |
| Mailing lists and JIRA | 2026-10-31 | manual: dev@, java-user@, issues@, commits@ (52 queries) and LUCENE JIRA (12 queries); the tool's own list and JIRA rows are in the first row | no report; java-user threads of 2006 and 2019 (E-notation boosts as input) and 2017 (range round trip) |
| Web | 2026-10-31 | 18 manual queries (they replace the tool's 30 web placeholders, which the tool cannot run) | nothing relevant |
| Earlier search | 2026-10-28 | 278 recorded queries, plus the finder's, a verifier's and the adjudication's searches | nothing |
The printer dates from the flexible parser's first release, 2.9.0 (2009), and never changed. Up to 8.11.4 the printed text silently re-parsed as a different query (f:ab^9 f:E-4); since 9.0.0, after a grammar cleanup, it fails with ParseException.
Versions tested5 rows
Introduced by 343992fcbb4 "LUCENE-1567: New flexible QueryParser framework." (2009-08-03, the original contribution, GitHub #2641), which created BoostQueryNode with this printer, the exponent-free NUMBER token and the parse-back contract. Later commits only changed new Float to Float.valueOf (835de0b44d4) and reformatted it (2cbf261032d). Symptom changed by 3a92e1b93eb (LUCENE-9528 grammar cleanup, #10568, first released in 9.0.0), which removed the lexer's Boost state: before it, 9.0 became the boost and E-4 a new term. That commit is neither the cause nor a fix. A bytecode scan of all 148 final release jars from 2.9.0 to 10.6.0 (4.0.0-ALPHA and 4.0.0-BETA not scanned) finds the same printer in every one.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0; 10.5.2 | fails loudly | minimal repro fails (prints ab^9.0E-4, ParseException on re-parse) |
9.0.0, 9.1.0, 9.12.3, 10.0.0, branch_10_6 | fails loudly | probe or finder's test: ParseException on re-parse |
| 2.9.0, 3.6.2, 4.0.0, 7.7.3, 8.11.4 | silent | probe: prints f:ab^9.0E-4, which re-parses as a different query, f:ab^9 f:E-4 |
| 2.4.1 and earlier | not affected | no flexible query parser |
| main + fix | not affected | every check passes |
An independent reproducer, a devil's-advocate verifier, an adjudication and a tie-break found it real; a read-only cross-model review (OpenAI GPT-5.6) agreed, and a second returned a procedural "not real" because it could not run code. This doc's gradle run reproduced it and validated the fix.
Checks and verdicts376 words
Every executed check ran on stock builds. The earlier cross-model reviewers could only read code, and separate runs re-ran the repro; the cross-model fact check of this doc ran one public-API probe.
| Check | Verdict | What it found |
|---|---|---|
| Finder (probe, exhaustive check, grid, JUnit) | candidate | 2-test JUnit fails 2 of 2 on main with assertions on and off, and on branch_10_6, 10.5.2 and 9.12.3; exactly two failing ranges over every non-negative finite float; fix passes. |
| Reproducer (own JUnit, own package) | real | 5 tests including a plain-decimal control: 4 of 5 fail on main (on and off), 10.5.2 and 9.12.3; the fix passes 5 of 5. |
| Cross-model review (OpenAI GPT-5.6, intended lens) | real, medium confidence | Read-only; rated the works-as-designed case weak; a separate run re-ran the JUnit (2 of 2 fail) and a public-API probe (controls pass, E-notation rows fail). |
| Refute review (OpenAI GPT-5.6) | not real (procedural, low) | Could not run anything and said its verdict is procedural; agreed on the root cause; not counted. |
| Devil's advocate | real | Built the 2017 "isn't supported" argument and showed why it fails; JUnit 2 of 2 fail on main, 10.5.2 and 9.12.3. |
| Adjudication | confirmed, high confidence | Re-ran the independent reproduction's JUnit with a new seed (5 run, 4 fail) and the finder's with assertions off (2 of 2 fail). |
| Current-main reproducer and tie-break | real | Minimal test on 645d4fe14a20, 10.5.2 and 10.6.0; a 15-row test hitting both switch points; probes on 9.0.0, 8.11.4 and 4.0.0; upstream flexible-parser tests pass 43 of 43 with the fix. |
| This doc | reproduced, fix validated | Gradle in a scratch worktree of 645d4fe14a20: stock fails; both fix variants pass the repro and the whole queryparser module. |
| Fact check of this doc (independent) | passed, no errors | Re-ran the minimal test on main (assertions on and off) and 10.6.0, the documented gradle command verbatim (stock fails, the fix passes), and its own public-API probe on main, 9.0.0 and 8.11.4. |
| Cross-model fact check (OpenAI GPT-5.6) | real; wording fixes | Ran a public-API probe on the 645d4fe14a20 jars (ab^0.001 round-trips, ab^0.0009 prints f:ab^9.0E-4 and does not parse). Found one low-severity wording error and asked for narrower claims and more caveats; all are addressed in this version. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 514 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,330 words
- Registry title
- Flexible query parser: BoostQueryNode#toQueryString prints a boost below 0.001 (or above 2^63) in E-notation, e.g. ab^0.0009 prints ab^9.0E-4, which StandardSyntaxParser cannot parse back
- Area
- queryparser / flexible parser node serialization (BoostQueryNode toQueryString/toString)
- Priority
- Low, rank 773: The fuzzy-node leg merged into this finding re-parses silently as a different query; the boost leg has a slightly more plausible trigger, but on 9.0 and later its re-parse fails loudly.
- Impact class
- minor
- Impact note
- A round-trip (contract) defect in a utility method, with no effect on the Query that StandardQueryParser.parse builds: applications that print flexible-parser node trees with toQueryString (trees from StandardSyntaxParser or StandardQueryParser.getSyntaxParser(), processed trees that carry an application-configured setFieldsBoost value, or hand-built BoostQueryNodes) and re-parse or forward that text get a ParseException for every boost below 0.001 or above 2^63 (9.0.0 and later; on 2.9.0 to 8.11.4 the re-parse silently builds a different query, e.g. boost 9 plus an extra term E-4); inside Lucene the output only feeds exception messages; default parser configuration, any scale.
- Summary
- You parse ab^0.0009 with the flexible StandardSyntaxParser, print the node tree with toQueryString, and expect text that parses back to the same boost, since QueryNode#toQueryString is documented as 'convert to a query string understood by the query parser' and the package documentation says the string 'can be parsed back by the original text parser'. Instead BoostQueryNode prints f:ab^9.0E-4, because its getValueString falls back to Float.toString, which uses E-notation below 0.001 and above 2^63 (ab^10000000000000000000 prints ab^1.0E19). The grammar's NUMBER token has no exponent, so re-parsing the printed text throws ParseException; the same happens to a per-field boost such as setFieldsBoost(Map.of("title", 0.0005f)) in the processed tree (title:lucene^5.0E-4).
- Introduced
- 343992fcbb4b31249f07354014723f18d0508d8a (LUCENE-1567 'New flexible query parser', the original contribution of the flexible query parser, svn trunk r800191, no PR; issue migrated as apache/lucene#2641), which created BoostQueryNode with this getValueString ('if (f == f.longValue()) return "" + f.longValue(); else return "" + f;'), its toQueryString, and the grammar whose NUMBER token has no exponent; the printer is unchanged since (835de0b44d4, LUCENE-1833, 2009-10-02, new Float -> Float.valueOf, same behaviour; 2cbf261032d, LUCENE-9570, 2021, reformatting) [read: git log -L and git blame -C -C -M on getValueString, git log -G on the NUMBER token; bytecode: all 147 release jars; exec: 2.9.0 fails, 2.4.1 has no flexible parser]. The symptom changed in 9.0.0 with 3a92e1b93eb (LUCENE-9528 grammar cleanup, apache/lucene#10568, PR apache/lucene-solr#1879), which removed the grammar's Boost lexical state: the printed text no longer re-parses silently into a different query but throws ParseException. That commit is neither a fix nor a regression of the printer; its discussion does not mention exponents or boost printing. (2009-08-03 (343992fcbb4, author date = commit date; the printer defect); 2020-09-18 (3a92e1b93eb author date; symptom change from silent misparse to ParseException, first released in 9.0.0))
- First affected version
- 2.9.0 [exec] (the first release with the API; 2.4.1 has no flexible query parser and no lucene-queryparser artifact). 2.9.0 to 8.11.4: the re-parse silently builds a different query [exec 2.9.0, 3.6.2, 4.0.0, 7.7.3, 8.11.4]; 9.0.0 and later: ParseException [exec].
- Affected versions
- every final lucene-queryparser release from 2.9.0 to 10.5.2 (the last release before 10.6.0; 147 releases, 4.0.0-ALPHA/BETA not checked), plus 10.6.0 (branch_10_6 4ae946e5a9b) and main a9779ef3c193; no fixed release. [exec] the finder's JUnit fails 2 of 2 on main (-ea and -da), branch_10_6, 10.5.2, 10.0.0, 9.12.3 and 9.1.0; the independent reproduction's JUnit fails 4 of 5 (its control passes) on main (-ea and -da), 10.5.2 and 9.12.3; the version-portable main() of the version-history runs (public API only, control ab^0.5 round-trips) fails on 2.9.0, 3.6.2, 4.0.0, 7.7.3 and 8.11.4 (silent misparse: f:ab^9.0E-4 re-parses as f:ab^9 f:E-4, f:ab^1.0E19 as f:ab^1 f:E19) and on 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (ParseException). [bytecode] all 147 SHA-1-verified release jars have the same Float.toString fallback in getValueString. [read] the other releases.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (the prior-report record verdict new, searched read-only 2026-10-28, 278 recorded queries: three scripted prior-report searches (class and method terms; round-trip and symptom terms; setFieldsBoost and toString terms) over GitHub issues, PRs, commits and code, the Elasticsearch, OpenSearch, Solr and Lucene.NET trackers, the JIRA archive, the dev@, java-user@, issues@ and commits@ lists and the web, plus manual searches; the file lists of all 414 open apache/lucene PRs; every issue and PR created or updated in the last 48 h; the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches found nothing either; refreshed at the registration check 2026-10-28: gh search 'BoostQueryNode' (only #6938 and #7660), issues and PRs created since 2026-10-28 (none), upstream main head 645d4fe14a20 and the commits on BoostQueryNode.java (newest f2493e586b11, #14737, author date 2025-06-04, printing unchanged): nothing new). Related, not this bug: #8667 / LUCENE-7616 (open design issue: toQueryString always emits standard syntax, even for custom parsers; no numbers), #7865 / LUCENE-6807 fixed by PR #14697 (2025, range-node toQueryString round trip fixed as a bug; precedent for the parse-back contract), #6938 / LUCENE-5876 and #7660 / LUCENE-6602 (open null-check reports on BoostQueryNodeBuilder and getChild), #6554 / LUCENE-5491 (BoostQueryNodeProcessor exception on the parse side), #5444 / LUCENE-4378 (the boost NUMBER token has no sign), #10568 / LUCENE-9528 (the grammar cleanup that changed the symptom; exponents not discussed), java-user threads of 2006 ('strange behavior 4 query term boost') and 2019 ('Strange lucene parser result in boosted query with decimal in exponential form') about E-notation boosts typed into or generated for the classic parser's input (grammar side), and the 2017 java-user thread 'Range queries get misinterpreted when parsed twice via the "Standard" parsers' (round trip not guaranteed, then an issue and patch were requested). Not fixed upstream: getValueString unchanged on upstream main 645d4fe14a20, branch_11x, branch_10x and branch_10_6; no open PR touches flexible/core/nodes.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, as do a 15-row boost test, the fuzzy leg's test,TestQueryNode, the whole queryparser module (30 classes, 533 tests, 0 failures) and the module's lint. Releases 10.5.2 and 10.6.0 fail the minimal test (standalone runner). The hunt ran on maina9779ef3c193(identical queryparser code); the history probe ran on releases from 2.9.0 to 10.6.0. Upstream main2f424fd428da(2026-10-30),branch_11x603af8703753andbranch_10_67e5aec4370ecarry the same code [read].
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/BoostQueryNode.java:25-40 (class and constructor javadoc '0.0 to 1.0'), :80-84 (getValueString), :86-95 (toString, toQueryString); core/nodes/QueryNode.java:26; core/nodes/package-info.java:42-43; standard/parser/StandardSyntaxParser.jj:160 (NUMBER token) and :689-703 (Boost ::= '^' <NUMBER>); standard/processors/BoostQueryNodeProcessor.java:57; lucene/CHANGES.txt:289-291 (GITHUB#7865 parse-back fix for range nodes)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/StandardSyntaxParser.jj:115-116, :128-134, :160-161, :688-703, :712-729a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/BoostQueryNode.java:33, :80-84, :86-89, :91-95a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/FuzzyQueryNode.java:50-57a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/builders/BoostQueryNodeBuilder.java:48; flexible/core/builders/QueryTreeBuilder.java:161Java SE API, Float.toString(float) (plain notation for magnitudes in [10^-3, 10^7))a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/FuzzyQuery.java:261-271 (floatToEdits); lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/nodes/IntervalQueryNode.java:53-54
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/QueryParserHelper.java:172 (getSyntaxParser); flexible/standard/processors/BoostQueryNodeProcessor.java:57
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QueryNode.java:26; flexible/core/nodes/package-info.java:42-43a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:296-298 (GITHUB#7865); lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/nodes/TestAbstractRangeQueryNode.javaa Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/StandardQueryParser.java:161-174; flexible/core/nodes/BoostQueryNode.java:29, :39, :67a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/test (grep BoostQueryNode: 0 hits)
- TestBoostQueryNodeToQueryString.java (one test class):
repro/LFV-975/src/org/apache/lucene/queryparser/flexible/core/nodes/TestBoostQueryNodeToQueryString.java(37 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the minimal repro's output.
assets/LFV-975/bug.png(514 KB)