A parallel reader takes its index sort from whichever sub-reader declares one, but each field from the first sub-reader that has it. When the sort field comes from a reader that is not sorted by it, the reader claims an order its values do not have, and everything that trusts the claim goes wrong.
- An index sort (
IndexWriterConfig.setIndexSort) keeps a segment's documents in the order of some fields, and a reader announces it ingetMetaData().sort(). Lucene uses it for shortcuts: a sorted top-N search can stop after the first N documents, and a range query on the primary sort field can treat its matches as one block of doc IDs. - A
ParallelLeafReaderglues indexes that hold the same documents in the same order into one reader; for each field it reads the first index that has it. Its javadoc's use case is a sidecar index that re-indexes small, frequently changing fields. IndexWriter.addIndexes(CodecReader...)copies a reader's documents into an index. If the target has an index sort, it only checks that the reader claims the same sort, then copies the documents in the reader's order.
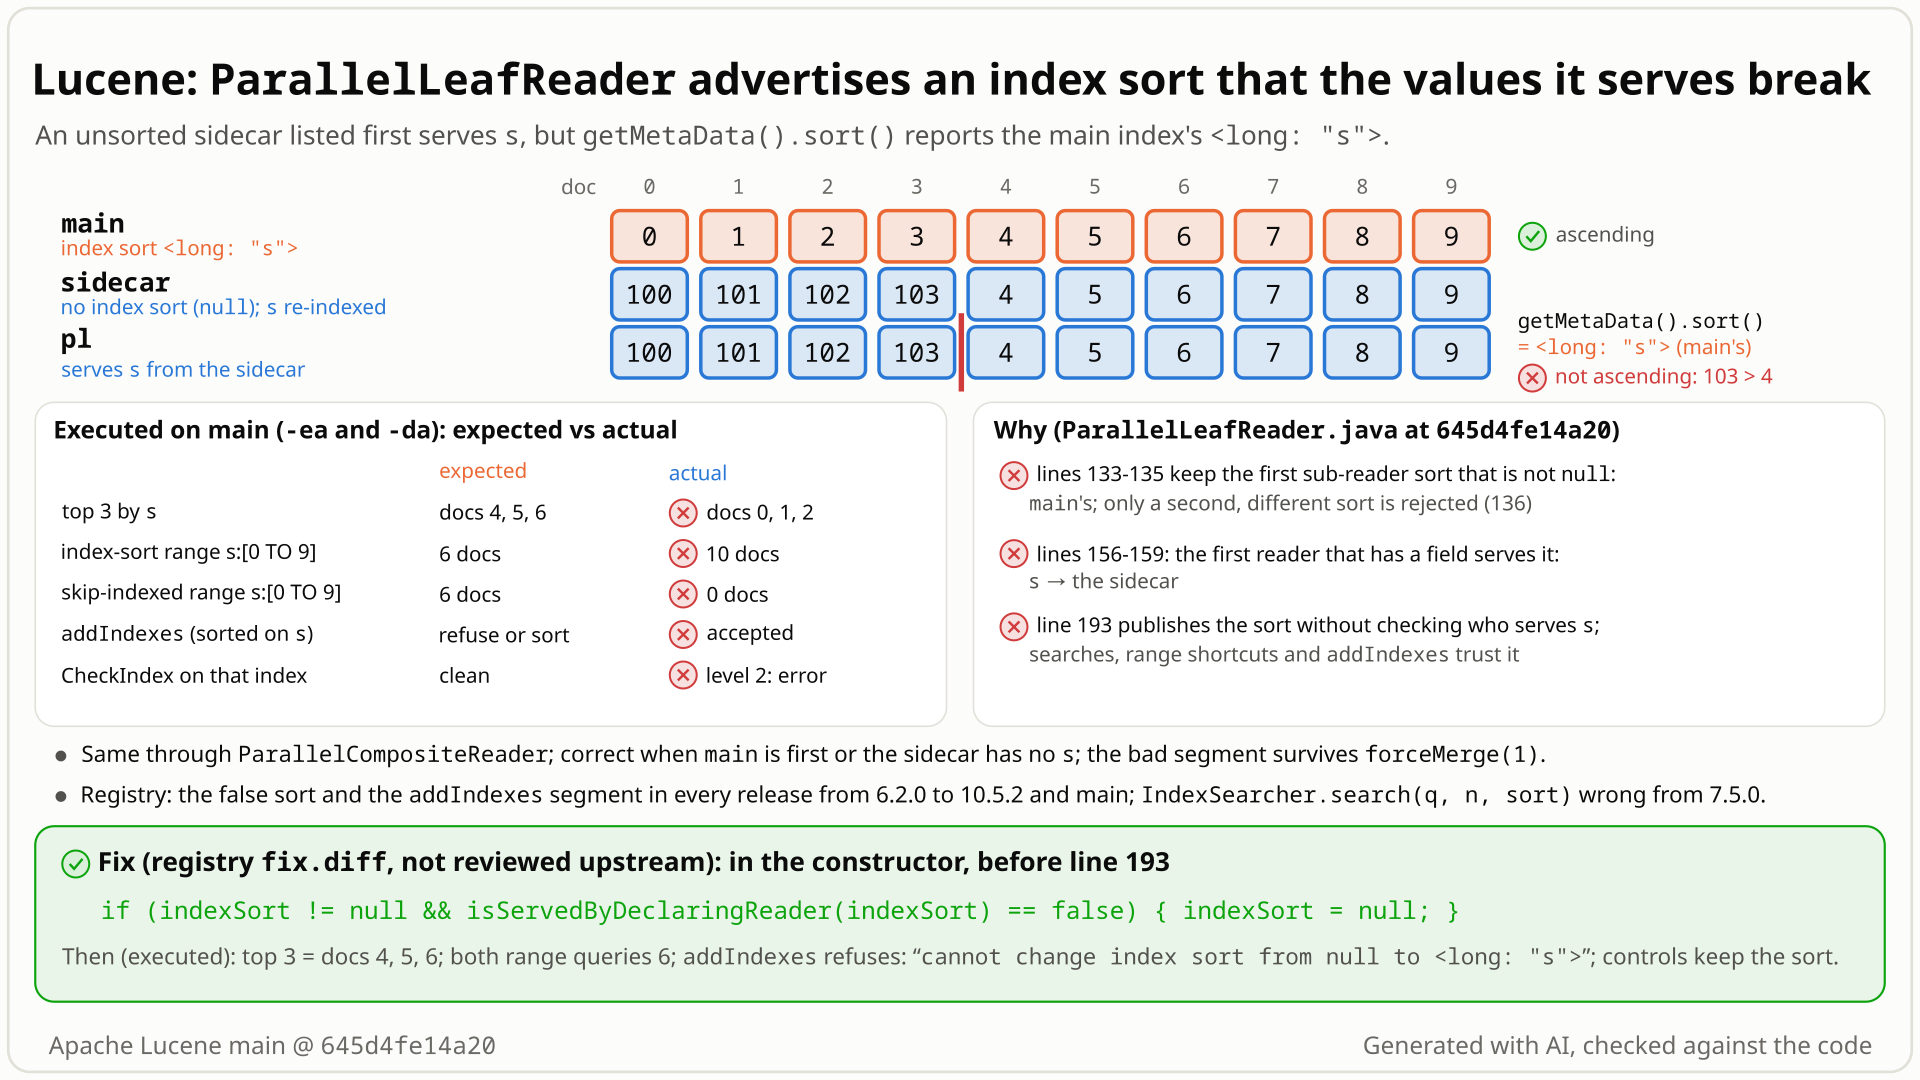
s, the parallel reader that serves the sidecar's values while claiming main's sort, the wrong top 3 and the broken segment addIndexes writes, then the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index 10 documents sorted on a long field
s(doc i has s = i). Index a sidecar with no sort: the same 10 documents in the same order, withsre-indexed so that docs 0-3 now hold 100, 101, 102, 103. - Open
new ParallelLeafReader(false, sidecar, main), sidecar first so that its re-indexed fields win, as in Lucene's own parallel-reader demo. The reader now serves s = 100, 101, 102, 103, 4, 5, ..., 9. - You expect it to stop claiming main's sort, since those values are not in order. Instead
getMetaData().sort()still says<long: "s">: a top-3 search sorted bysreturns docs 0, 1, 2 (s = 100-102) instead of 4, 5, 6, andIndexSortSortedNumericDocValuesRangeQuerys:[0 TO 9] counts 10 hits instead of 6. addIndexes(SlowCodecReaderWrapper.wrap(reader))into an index sorted onstrusts the claim and writes the documents as 100, 101, 102, 103, 4, ... underindexSort=<long: "s">. CheckIndex at its default level calls it clean; level 2 reports "docID=3 sorts after docID=4"; a laterforceMerge(1)keeps the broken order.
Applications with an index sort that open a ParallelLeafReader or ParallelCompositeReader with an unsorted sidecar listed first that re-indexes a field of the sort with other values. Default codec, 10 documents, nothing throws in the repro. Affects 6.2.0 onwards. Rare: the sidecar must also hold a sort field with values in another order, and nobody has reported it since 2016.
Mechanism, terms and numbers711 words
A ParallelLeafReader takes its index sort from the first sub-reader that declares one (ParallelLeafReader.java:126-142 on main 645d4fe14a20) but takes each field from the first sub-reader that has it (:156-159), and publishes the sort (:193) without asking which reader serves the sort fields. When an unsorted sidecar listed first re-indexes a field of the sort, the reader claims an order that its served values break. In the repro (10 documents, a main index sorted on s = 0-9, a sidecar that gives docs 0-3 the values 100-103) it serves 100, 101, 102, 103, 4, ..., 9 under <long: "s">: a top-3 search sorted by s returns docs 0, 1, 2 instead of 4, 5, 6, IndexSortSortedNumericDocValuesRangeQuery s:[0 TO 9] counts 10 instead of 6, a skip-indexed slow range query 0 instead of 6, and ParallelCompositeReader behaves the same. IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)) into an index sorted on s checks only the claimed sort and writes a segment whose documents break it; CheckIndex level 2 rejects it, the default level does not look, and merges keep it. The code is unchanged since 6.2.0 (LUCENE-6766), and every release run from 6.2.0 on is affected. Keeping the sort only when a sub-reader that declares it serves every sort field, and advertising null otherwise, fixes it; addIndexes then refuses the reader with its existing error.
- The sort comes from the first sub-reader that has one.
ParallelLeafReader.java:126-142:if (indexSort == null) { indexSort = leafIndexSort; }; only a second, different non-null sort throws "cannot combine LeafReaders that have different index sorts". The sidecar's sort is null and main's is<long: "s">, so the reader keeps<long: "s">. - Each field comes from the first sub-reader that lists it.
:154-159,// NOTE: first reader having a given field "wins":(fieldToReader.put(fieldInfo.name, reader)), andgetNumericDocValuesreads from that reader (:396-399). With the sidecar first,scomes from the sidecar. - The sort is published without asking who serves its fields.
:193:new LeafMetaData(createdVersionMajor, minVersion, indexSort, hasBlocks).ParallelCompositeReaderbuilds oneParallelLeafReaderper leaf (ParallelCompositeReader.java:132-136), so it does the same. - Consumers trust the claim.
TopFieldCollectordecides per segment whether the search sort is a prefix of the index sort (TopFieldCollector.java:58-59) and then stops comparing once its queue is full.Sort.getPrimarySortField(Sort.java:145-146) feedsIndexSortSortedNumericDocValuesRangeQueryand the skip-index shortcut of the doc-values range queries.IndexWriter.validateMergeReaderonly checks that the claimed sort matches the writer's (IndexWriter.java:3245-3251), soaddIndexescopies the documents in their served order under the declared sort. - CheckIndex looks only from level 2. The index-sort test runs for
level >= MIN_LEVEL_FOR_INTEGRITY_CHECKS(2) (CheckIndex.java:1114,:1146-1149); the default level is 1 (:4748).
| expected | actual | |
|---|---|---|
getMetaData().sort() | null, or the combination rejected | <long: "s"> while serving 100, 101, 102, 103, 4, ..., 9 |
top 3 sorted by s | docs 4, 5, 6 | docs 0, 1, 2 (also through ParallelCompositeReader) |
IndexSortSortedNumericDocValuesRangeQuery s:[0 TO 9] | 6 | 10 |
skip-indexed newSlowRangeQuery s:[0 TO 9] | 6 | 0 |
addIndexes into an index sorted on s | refused, or the documents sorted | accepted; segment holds 100, 101, 102, 103, 4, ... under indexSort=<long: "s"> |
| CheckIndex on that index | clean | level 1 clean; level 2 "segment has indexSort=<long: "s"> but docID=3 sorts after docID=4" |
after 10 more documents and forceMerge(1) | clean, top 3 = docs 4, 5, 6 | still rejected by level 2; top 3 still docs 0, 1, 2 |
Controls that stay right: the sorted reader listed first; a sidecar without the sort field (the usual sidecar); a search sort that is not a prefix of the index sort.
The finder's bounded enumeration of 25,230 compositions of 2 and 3 sub-readers, with Z3 deciding per structure whether legal values can break the claimed sort, found 3,008 violable structures; all 3,008 witnesses replay on the stock jar. Two shapes beyond the sidecar: a two-field sort (s, t) declared by both readers, where the first serves s and the second t (served (0, 0), (1, 1), (1, 0)); and a points-only field with the sort field's name in the sidecar, which hides the sorted reader's doc values (then addIndexes fails loudly with IllegalStateException).
Exposure and likelihood181 words
- Who is hit. An index sort (opt-in) plus a parallel reader (an expert class) whose sidecar, listed first, re-indexes a sort field with values in another order. The javadoc's use case is a sidecar for frequently changing fields (
ParallelLeafReader.java:42-44), and a frequently changing sort key fits it. - Read side. Silent wrong top hits for sorted searches; wrong hit sets from the index-sort range shortcuts, too many (10 instead of 6) or too few (0 instead of 6).
- Write side.
addIndexespersists a segment whose documents break its declared sort. CheckIndex at its default level calls it clean; merges keep it; a sorted search on the merged index is still wrong. - Scale and settings. 10 documents, the default codec and a plain
IndexSearcher(in-memory directories in the repro; the logic does not depend on the directory); the same with assertions on or off. - How likely: rare. The javadoc expects the indexes to "typically" contain different fields (
ParallelLeafReader.java:36-37), the sidecar must hold a field of the sort with values in another order, and no report exists since 6.2.0 (2016).
The test shows that new ParallelLeafReader(sidecar, main) advertises main's index sort while the unsorted sidecar serves the sort field, so IndexWriter.addIndexes writes a segment that breaks its own index sort.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestParallelLeafReaderShadowedIndexSort extends LuceneTestCase {

  private static final Sort SORT = new Sort(new SortField("s", SortField.Type.LONG));

  private static Directory index(IndexWriterConfig config, long... values) throws IOException {
    Directory dir = new ByteBuffersDirectory();
    try (IndexWriter w = new IndexWriter(dir, config)) {
      for (long value : values) {
        Document doc = new Document();
        doc.add(new NumericDocValuesField("s", value));
        w.addDocument(doc);
      }
    }
    return dir;
  }

  public void testAddIndexesOfSidecarFirstReaderKeepsIndexSort() throws IOException {
    try (Directory main = index(new IndexWriterConfig().setIndexSort(SORT), 0, 1);
        Directory sidecar = index(new IndexWriterConfig(), 2, 1);
        Directory target = new ByteBuffersDirectory();
        DirectoryReader mainReader = DirectoryReader.open(main);
        DirectoryReader sidecarReader = DirectoryReader.open(sidecar);
        ParallelLeafReader parallel =
            new ParallelLeafReader(
                false, getOnlyLeafReader(sidecarReader), getOnlyLeafReader(mainReader))) {
      // expected: IAE or a correctly sorted segment; actual: docID=0 sorts after docID=1
      try (IndexWriter w = new IndexWriter(target, new IndexWriterConfig().setIndexSort(SORT))) {
        w.addIndexes(SlowCodecReaderWrapper.wrap(parallel));
      } catch (IllegalArgumentException rejected) {
        return;
      }
      try (CheckIndex checker = new CheckIndex(target)) {
        checker.setLevel(CheckIndex.Level.MIN_LEVEL_FOR_INTEGRITY_CHECKS);
        assertNull(checker.checkIndex().segmentInfos.get(0).indexSortStatus.error);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-981/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestParallelLeafReaderShadowedIndexSort
- Expected vs actual
- Expected:
addIndexesrejects the reader or writes a correctly sorted segment. Actual: CheckIndex level 2 reportssegment has indexSort=<long: "s"> but docID=0 sorts after docID=1.
More files, environment, full output44 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected null, but was:<org.apache.lucene.index.CheckIndex$CheckIndexException: segment has indexSort=<long: "s"> but docID=0 sorts after docID=1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotNull(Assert.java:756)
       org.junit.Assert.assertNull(Assert.java:738)
       org.junit.Assert.assertNull(Assert.java:748)
org.apache.lucene.index.TestParallelLeafReaderShadowedIndexSort.testAddIndexesOfSidecarFirstReaderKeepsIndexSort(TestParallelLeafReaderShadowedIndexSort.java:61)LeafMetaData's sort is "the order in which documents from this index are sorted"; the reader builds it and already rejects two different sorts.- Field overlap is documented; Lucene's own parallel-reader demo puts the re-indexed reader first.
- Lucene blocks doc-values updates of sort fields that "would lead to corruption" (LUCENE-7581); here its writer makes a segment its own CheckIndex rejects.
The full argument202 words
- Contract.
LeafMetaData.java:32-33: the sort is "the order in which documents from this index are sorted, ornullif documents are in no particular order".ParallelLeafReaderbuilds that metadata and already validates sorts (it throws for two different ones,:136-142,testWithIndexSort1). - Overlap is endorsed. The class javadoc: matches come "from the first index added that has the field" (
:38-40).TestDemoParallelLeafReader.java:178-182: "NOTE: important that parallelReader is first, so if there are field name overlaps, because changes to the schema overwrote existing field names, it wins". - Sorted plus unsorted is a tested combination.
testWithIndexSort2("ok to have one leaf w/ index sort and the other with no sort",TestParallelLeafReader.java:375-398), but with field-less documents, so the unsorted reader never held the sort field. - Precedent. LUCENE-7581: "Lucene now prevents updating a doc values field that is used in the index sort, since this would lead to corruption" (
CHANGES.txt:8700-8702); #16565 extended it to binary doc values (:729-730);updateNumericDocValuethrows (IndexWriter.java:1965-1970). The siblingSlowCompositeCodecReaderWrapperpublishes a null sort (:94). - History. LUCENE-6766 (2016) set the rule; its review fixed only the order dependence of null sorts, and nobody discussed which reader serves the sort field.
The devil's-advocate check220 words
The intended-behaviour checker and the adjudication built the strongest case: the class javadoc warns "It is up to you to make sure all indexes are created and modified the same way ... Failure to do so will result in undefined behavior" (ParallelLeafReader.java:46-49), and a sorted main index with an unsorted sidecar that changes the sort key was arguably not "created the same way"; Lucene treats changing sort keys after indexing as unsupported (LUCENE-7581, #16565); delegating wrappers pass metadata through, and addIndexes trusts reader metadata by design; LeafMetaData is @lucene.experimental; the trigger is rare.
Why it fails: the warning's one concrete example is "the same documents in the same order", which the repro meets; the javadoc does not say whether a sidecar may re-index a sort field with other values, but sorted plus unsorted sub-readers are tested as accepted, so "created the same way" cannot require the same index sort; the LUCENE-7581 precedent made Lucene refuse the same outcome, and CHANGES calls it corruption; unlike a delegating wrapper, ParallelLeafReader changes which values are served, by design, and derives the sort itself; @lucene.experimental is about API stability, not a segment that CheckIndex rejects; rarity lowers priority, not validity. Verdict: not intended. A maintainer may still answer "undefined behaviour per the javadoc", or prefer an exception or a javadoc note.
Recommended Advertise the sort only when a reader that declares it serves its fields
Keep the advertised sort only if a sub-reader that declares it also serves every sort field; otherwise advertise null. Searches then compare the served values, and addIndexes into a sorted index refuses the reader with its existing "cannot change index sort" error. Validated: the repro with 10 neighbouring suites, the index package and :lucene:core:check -x test pass.
// ParallelLeafReader constructor, after fieldInfos = builder.finish():
if (indexSort != null && isServedByDeclaringReader(indexSort) == false) {
  indexSort = null;
}
// isServedByDeclaringReader(sort) is true iff some sub-reader whose getMetaData().sort()
// equals sort is, for every SortField, the owner of that field in fieldToReader (or no
// sub-reader has the field); a SortField without a field name makes it false
this.metaData = new LeafMetaData(createdVersionMajor, minVersion, indexSort, hasBlocks);
All options and trade-offs4 options · 757 words
One fix was built and validated; three more options were not built.
Advertise the sort only when a reader that declares it serves its fields (validated by the checks) (recommended)
A change in the ParallelLeafReader constructor (1 file, +28; the finder's sketch, which passes checkGoogleJavaFormat): after the field map is built, keep the sort only if some sub-reader declares exactly this sort and serves every field of it (or no sub-reader has the field); otherwise publish null. In the repro the sidecar owns s and declares no sort, so the reader reports null: the top 3 become docs 4, 5, 6, the range query counts 6, and addIndexes throws "cannot change index sort from null to <long: "s">" (a caller who wants the documents can wrap the reader in SortingCodecReader). The usual sidecar and the sorted reader first keep their sort.
// ParallelLeafReader constructor, after fieldInfos = builder.finish():
if (indexSort != null && isServedByDeclaringReader(indexSort) == false) {
  indexSort = null;
}
// isServedByDeclaringReader(sort) is true iff some sub-reader whose getMetaData().sort()
// equals sort is, for every SortField, the owner of that field in fieldToReader (or no
// sub-reader has the field); a SortField without a field name makes it false
this.metaData = new LeafMetaData(createdVersionMajor, minVersion, indexSort, hasBlocks);
Trade-offs
- Conservative. It also drops a sort that happens to hold: a multi-field sort split across sub-readers that all declare it, a same-named points-only field that shadows the sort field, or a
SortFieldwithout a field name. In the finder's bounded model (2 or 3 sub-readers, fieldssandt, 3 documents, values 0-4) it drops 2,388 of 5,684 always-true structures, never the single-declaring-owner case that covers the javadoc's sidecar use; the patched class matches the intended predicate on 8,692 of 8,692 sort-advertising structures and, within that model, never claims a violable sort. The model does not cover custom readers, otherSortFieldtypes or other codecs. - Test framework.
wrapReadercan split one reader into twoFieldFilterLeafReaderhalves under aParallelLeafReader(LuceneTestCaseParent.java:2402-2404); a multi-field index sort split across the halves would lose its claimed sort there (shortcuts off, results unchanged). - Behaviour change.
addIndexesof such a reader into a sorted index now throws instead of silently writing a broken segment; sorted searches on it lose the early-termination shortcut.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle, OpenJDK 25: the repro test fails on the stock tree and passes with the fix, with assertions on and off. - With the fix:
TestParallel*(5 suites incl. the new test),TestIndexSorting,TestDemoParallelLeafReader,TestAddIndexes,TestSortingCodecReader,TestTopFieldCollectorEarlyTerminationandTestIndexSortSortedNumericDocValuesRangeQuery: 11 suites, 168 tests, 0 failures; the wholeorg.apache.lucene.indexpackage: 215 suites, 1,396 tests, 56 skipped, 0 failures (with the test's earlier revision, which differs only in the name of the unused catch parameter). The logs keep the test counts; the suite counts come from the JUnit XML of the removed worktree, and an independent fact check re-ran both selections with the final test revision and got the same counts. :lucene:core:check -x testpasses: checkGoogleJavaFormat, ecjLintTest, forbiddenApisTest and the license and regeneration checks executed, ecjLintMain and forbiddenApisMain were up to date on the same inputs; errorProne was skipped (off by default outside CI) and eclint not applied (no tool location set).- Earlier, by the hunt: the finder's 9-test JUnit and the split-sort test pass; 86 upstream parallel-reader and index-sorting tests and 352 early-termination and range-query tests over 8 seeds pass stock and fixed; the independent reproducer's JUnit passes 8 of 8.
- Not run: nightly tests, a benchmark, the merge-time
wrapForMergeroute.
Reject the combination, as the constructor already does for two different sorts. Not built.
Trade-offs
Loud and simple, but it rejects every composition in which an unsorted earlier reader holds a sort field, also for users who never sort or call addIndexes; the test framework's split case would need the same ownership rule to avoid throwing on multi-field sorts.
A javadoc sentence on both parallel readers: the claimed index sort is valid only if the sort fields come from a reader sorted by it. Not built.
Trade-offs
Cheap, but alone it leaves the silent corruption for anyone who misses the note.
Have addIndexes(CodecReader...) check the incoming documents against the declared sort, as CheckIndex.testSort does. Not built.
Trade-offs
Also catches other readers that publish a wrong sort, but costs a pass over the sort fields of every added reader, fixes only the write side and leaves the wrong search results.
Relevant downstream only where an application builds parallel readers over a sorted index with a sidecar that re-indexes a sort field; inside such a composition, whoever supplies the sidecar's sort-field values decides whether the claimed order breaks. No downstream report was found.
An outside reviewer from another model family (OpenAI GPT-5.6) suggested, from code reading, that parallel-reader metadata might advertise an unsafe index sort; a planning probe on the stock jars confirmed it. The hunt then enumerated 25,230 reader compositions, let Z3 decide which claimed sorts legal values can break, replayed all 3,008 witnesses and reduced it to a JUnit.
The method in full243 words
Method: non-formal first signal, widened by a formal leg (the hunt's hunt unit for parallel-reader index-sort metadata, 2026-10-28, main a9779ef3c193).
- Lead. Item 7 of an outside reviewer's idea pack (OpenAI GPT-5.6, code reading): "parallel-reader metadata must not advertise an unsafe index sort after a mixed sort declaration". A planning probe on the stock jars showed the sidecar-first composite advertising
<long: "s">with a wrong top 3 and wrong range counts; a second probe extended it toaddIndexes, CheckIndex levels andforceMerge. - Formal leg. A bounded-exhaustive enumeration on the stock jar: 29 legal sub-reader types (combinations of an index sort none, (s), (t), (s, t) or (t, s) with s and t each absent, doc values or points-only) in ordered lists of 2 and 3, 25,230 compositions through the real
ParallelLeafReaderandParallelCompositeReader. For each of the 8,692 structures that advertise a sort, Z3 decided whether legal values (every sorted sub-reader in its own declared order) can make the served values break it: 3,008 can. All 3,008 witnesses were rebuilt as real indexes and violate the claimed sort on the stock jar. A vacuity mutant without the sorted-sub-reader constraint flips the single-owner structures to violable, so the UNSAT answers depend on that constraint. - JUnit. Reduced to a public-API JUnit (9 tests, 2 controls; 7 fail with assertions on and off) and a second test for the split two-field sort; this doc's repro is a one-method version of the
addIndexestest.
No prior report found (searched 2026-10-28 and 2026-10-29, refreshed): GitHub issues, PRs and commits, downstream trackers, the mailing lists, the JIRA archive, the web and the changed files of all 414 open Lucene PRs. Related: open #16809 / #16810 reach a similar broken segment through doc-values updates.
Searches4 searches
Related, not reports of this bug: #16809 and its fix PR #16810 (both open), a segment that claims a sort its documents break, reached through doc-values updates when the writer config has no index sort; #16810 changes only IndexWriter.java and TestIndexSorting.java and does not fix this repro. #14399, fixed by #16434: early termination cached across leaves whose sorts were each true; the per-segment fix still trusts a leaf's false sort. #16857 (open) consolidates sort pruning and still reads getMetaData().sort(). #7824 (LUCENE-6766) introduced the rule; its review discussed only the order of null sorts. Tracking issue #16937 does not list this bug. Gaps: keyword search only; GitHub Discussions and chat channels were not searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and downstream trackers | 2026-10-28 and 2026-10-29 | a scripted prior-report search (867 and 1,606 distinct hits in two runs); 15 manual apache/lucene searches (the class names ParallelLeafReader, ParallelCompositeReader and ParallelAtomicReader, whose 14, 10 and 8 items were all read by title and the plausible ones in full, and 12 other phrasings); 5 downstream-repository searches (Elasticsearch, OpenSearch, Solr and Lucene.NET) | no report; only the related items above |
| Open PRs | 2026-10-29 | the changed files of all 414 open apache/lucene PRs; every PR created since 2026-10-25 | #13342 and #16847 touch ParallelLeafReader.java without changing the sort logic |
| Mailing lists and JIRA archive | 2026-10-29 | dev@, java-user@, issues@ and commits@ queries; JIRA REST searches; three parallel-index threads read | no report; the sidecar use case is real, index sorting is not mentioned |
| GitHub (re-check for this doc) | 2026-10-29 | "ParallelLeafReader sort", "ParallelCompositeReader index sort", "parallel reader index sort", "ParallelLeafReader indexSort", "addIndexes ParallelLeafReader sort"; items updated since 2026-10-28; the file's latest commit | 0 hits; nothing new; ParallelLeafReader.java unchanged since bfe5c847d3c (2026-07-27) |
Introduced in 6.2.0 by LUCENE-6766 (54fa7dfd271, 2016-05-04; rule set by 8361de87bec), which gave the parallel reader an index sort without asking which reader serves the sort field; unchanged since, not a regression. Plain IndexSearcher.search(q, n, sort) calls give wrong top hits from 7.5.0 on, after LUCENE-8432 changed TopFieldCollector.
Versions tested6 rows
Introduced by LUCENE-6766 "Make index sorting a first-class citizen" (JIRA, migrated as #7824; patches, no PR): 54fa7dfd271 "initial patch" (Mike McCandless, 2016-05-04) took the first non-null sub-reader sort; 8361de87bec (2016-05-10) set today's rule after review (null sorts allowed anywhere, two different sorts rejected). Master merge d715210467a; branch_6x backports fdc220eeb42 and 4740056f098, first released in 6.2.0. The "first reader wins" field rule is much older: it dates from ParallelReader (b68ae2ef265, 2005) and was carried into today's class by LUCENE-3736 (6188bc66d7d, 2012); LUCENE-7756 (23b002a0fdf, 7.0) only moved the sort into LeafMetaData.
Symptoms by era. The false metadata, the addIndexes segment and EarlyTerminatingSortingCollector's wrong top hits from 6.2.0; a plain IndexSearcher.search(q, n, sort) only from 7.5.0, when LUCENE-8432 (49979235252) made TopFieldCollector stop comparing once the queue is full for a segment whose sort covers the search sort.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 and a9779ef3c193 | affected | the one-method test fails (gradle and the standalone runner, assertions on and off); the finder's JUnit 7 of 9 |
10.6 RC 4ae946e5a9b, 10.5.2, 10.0.0, 9.12.3, 9.0.0, 8.11.4 | affected | wrong sorted top 3 and the broken addIndexes segment (portable repro); the one-method test fails on 10.5.2 and 9.12.3 |
| 7.5.0, 7.6.0, 7.7.3 | affected | false sort, broken addIndexes segment, wrong top 3 from both the plain sorted search and EarlyTerminatingSortingCollector |
| 6.2.0 (-ea and -da), 6.6.6, 7.0.0 to 7.4.0 | plain search right | false sort, broken addIndexes segment and wrong EarlyTerminatingSortingCollector top 3; a plain sorted search is still right |
| 5.5.5, 6.1.0 | API absent | no index-sort API (compile error) |
| main + fix | not affected | the test passes, as do 10 neighbouring suites (11 suites with the test, 168 tests) and the index package (1,396 tests) |
An independent reproducer, an intended-behaviour devil's advocate and reading-only reviews by another model family (OpenAI GPT-5.6) agree on the root cause; the adjudication re-ran the independent test and confirmed it with high confidence. This doc re-ran the repro on 645d4fe14a20 and validated the fix with gradle.
Checks and verdicts451 words
All cross-model reviews were reading-only: they could not run Java. The refute-lens review returned a procedural "not real, low" while agreeing on the root cause; a separate re-run failed 7 of 9. An executing cross-model review is still open.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate (formal tier) | JUnit 7 of 9 fail (-ea, -da), both controls pass; split test 1 of 1; 3,008 of 3,008 Z3 witnesses replay on the stock jar; the fix passes the repros and the upstream tests. |
| cross-model reviews, intended and refute lenses | real, medium; not real, low (procedural) | OpenAI GPT-5.6, reading-only; both agree on the root cause and the inputs. A separate re-run: 7 of 9 fail. |
| Independent reproducer | real | Own JUnit (a price field, the last document lowered from 80 to 5) fails 4 of 8 on main (-ea, -da), 10.5.2 and 9.12.3; its 4 controls pass; 8 of 8 with the fix. |
| Cross-model review, root-cause lens | uncertain, medium (could not execute) | Root cause agrees: the first bad state is the metadata the reader publishes. Separate runs: 8 of 10 fail on main, 10 of 10 pass with the fix. |
| Intended-behaviour devil's advocate | real | Built the strongest works-as-designed case and showed why it fails; the finder's JUnit fails on main, the portable repro on 10.5.2. |
| adjudication | confirmed, high; data corruption | Re-ran the independent reproduction's JUnit with a new seed (-ea, -da): 4 of 8 fail, the 4 controls pass. |
| Registration check and credibility audit | keep | Fresh seeds: finder 7 of 9, split 1 of 1, the independent reproduction 4 of 8; the finder's JUnit with the fix 9 of 9; audit re-run 7 of 9. |
| brief re-runs | reproduced; fix validated | The one-method test fails on 645d4fe14a20 (gradle and standalone, -ea, -da), 10.5.2 and 9.12.3; with the fix it passes, as do 10 neighbouring suites (11 with the test), the index package and check -x test. |
| fact check of this doc | bug sound; 3 text fixes, applied | Re-ran the documented gradle command (fails as shown, also with assertions off), the fix with the 11-suite selection and the index package on the final test revision, the standalone runner on main, 10.5.2 and 9.12.3, and its own probe: every number of the repro and the fix reproduced. |
| cross-model fact check | real, substantially sound | OpenAI GPT-5.6, reading-only: 4 text errors fixed, 1 rejected (LUCENE-8059 did ship in 7.2.0); its overclaims and missing caveats were addressed. |
| diagram check | pass | Every on-screen value and code row checked against the code at 645d4fe14a20 and a re-run of the diagram's probe (identical output). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 418 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,501 words
- Registry title
- ParallelLeafReader and ParallelCompositeReader advertise a sub-reader's index sort even when an earlier, unsorted sub-reader serves the sort field, so sorted searches and index-sort range shortcuts return wrong hits and IndexWriter.addIndexes writes a segment that breaks its declared index sort
- Area
- core / index (ParallelLeafReader and ParallelCompositeReader index-sort metadata, LeafMetaData.sort; consumers: TopFieldCollector early termination, Sort.getPrimarySortField range shortcuts, IndexWriter.addIndexes(CodecReader...))
- Priority
- Low, rank 285: Needs an index sort plus an earlier unsorted parallel-reader sidecar that re-indexes the sort field, a rare shape.
- Impact class
- data corruption
- Impact note
- Hits applications that use an index sort (opt-in) and open a ParallelLeafReader or ParallelCompositeReader in which an earlier sub-reader that is not sorted by that sort also holds a field of the sort with other values (for example a sidecar index that re-indexes small, changing fields, the class javadoc's own use case, listed first as Lucene's parallel-reader demo recommends): sorted top-N searches and the index-sort range shortcuts silently return wrong hits, and IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)) into an index with that sort persists a segment whose documents break its declared sort, which default CheckIndex (level 1) calls clean, level 2 rejects and later merges keep; default codec, directory and searcher, no large index needed (10 documents), no exception with -ea or -da in that repro.
- Summary
- You keep a main index sorted on a long field s and a sidecar index with the same documents in the same order that re-indexes s with new values (docs 0-3 get 100-103), open them as new ParallelLeafReader(sidecar, main), and expect the reader either to stop claiming the sort or to reject the combination, as it already does for two different sorts, because the first reader that has a field serves it and the sidecar is not sorted. Instead it reports main's sort <long: "s"> in getMetaData() while it serves s = 100, 101, 102, 103, 4, 5, ...: a top-3 search sorted by s returns docs 0, 1, 2 (s = 100-102) instead of 4, 5, 6, IndexSortSortedNumericDocValuesRangeQuery s:[0 TO 9] counts 10 instead of 6, a range query on a skip-indexed s finds 0 instead of 6, and ParallelCompositeReader behaves the same. IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)) into an index sorted on s accepts the reader and writes the documents in that order under indexSort=<long: "s">, a segment that CheckIndex level 2 rejects ('docID=3 sorts after docID=4') and that survives forceMerge.
- Introduced
- 54fa7dfd271f7fe3bc8da2cfcd165e21e76e1804 ('LUCENE-6766: initial patch', Mike McCandless; JIRA LUCENE-6766 'Make index sorting a first-class citizen', migrated as GitHub #7824; patch workflow, no PR) [read: blame and git log -S indexSort in the history clone]: it gave ParallelLeafReader an index sort, the first non-null sub-reader sort, without asking which sub-reader serves the sort field (the 'first reader having a given field wins' rule dates from ParallelReader, b68ae2ef265, 2005, and was carried into today's class by 6188bc66d7d, LUCENE-3736, 2012). Follow-up 8361de87becd ('fix parallel reader's detection of conflicting index sort', 2016-05-10) set today's rule (null sorts allowed anywhere, two different non-null sorts rejected); master merge d715210467a (2016-05-13); branch_6x backports fdc220eeb42 and 4740056f098 (committed 2016-06-11). LUCENE-7756 (23b002a0fdf, 7.0) only moved the sort into LeafMetaData. Not a regression: the logic is unchanged since 2016. (2016-05-04 (initial patch, author date); 2016-05-10 (current combining rule))
- First affected version
- 6.2.0 [exec, -ea and -da] (6.1.0 has neither LUCENE-6766 commit and 6.2.0 has both; 6.1.0 and 5.5.5 lack the index-sort API, compile error [exec])
- Affected versions
- Every release from 6.2.0 through 10.5.2, 10.6.0 (released 2026-10-29; run as its RC 4ae946e5a9b) and main a9779ef3c193; never fixed. [exec] follow-up history runs (follow-up): 6.2.0 (-ea and -da), 6.6.6, 7.0.0, 7.1.0, 7.2.0, 7.3.0, 7.4.0, 7.5.0, 7.6.0, 7.7.3, 8.11.4, 9.12.3, 10.5.2, the 10.6 RC and main (API-adapted ports for 6.x and 7.x, a version-portable main() from 8.11.4 on); the finder also ran 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, the RC and main; the independent reproduction ran its own JUnit on main, 10.5.2 and 9.12.3 (-ea and -da); the intended-behaviour check ran 10.5.2. The false metadata, the addIndexes segment and EarlyTerminatingSortingCollector's wrong top-N exist from 6.2.0; plain IndexSearcher.search(q, n, sort) gives wrong top hits only from 7.5.0 (LUCENE-8432 made TopFieldCollector trust the sort; 7.4.0 passes that check, 7.5.0 fails it) [exec]. [read] upstream main 645d4fe14a20 (2026-10-28): no commit after a9779ef3c193 touches ParallelLeafReader, ParallelCompositeReader or LeafMetaData (last ParallelLeafReader change bfe5c847d3c, authored 2026-07-27, fp16 vectors); #16893 (merged 2026-10-26) adds guards only for segments with blocks or multi-valued fields and does not change this trigger. JDK 25.0.3, aarch64; pure Java logic.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (2026-10-29, read-only; the prior-report record verdict new, plus the finder's search at 2026-10-28, the independent reproduction's and the intended-behaviour check's searches, the adjudication's check and a recheck): a scripted prior-report search over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (867 distinct hits in the follow-up run, 1,606 in the finder's), 15 manual apache/lucene GitHub searches (the class names ParallelLeafReader, ParallelCompositeReader and ParallelAtomicReader, whose 14, 10 and 8 results were read by title and the plausible ones in full, and 12 other phrasings; corrected 2026-10-29 from '37') and 5 downstream-repository searches, JIRA REST searches, three list threads read, 7 web queries, the changed files of all 414 open apache/lucene PRs, all PRs created since 2026-10-25, and the commits API for ParallelLeafReader, ParallelCompositeReader, LeafMetaData and TestParallelLeafReader by author date. Recheck: none of the 12 PRs created since 2026-10-27 nor any issue or PR updated since then concerns parallel readers or a false advertised sort; GitHub search 'ParallelLeafReader sort' and 'ParallelCompositeReader index sort' (issues and PRs): 0 hits; main 645d4fe14a20 has no commit on these files after a9779ef3c193. Related, not this bug: open #16809 with its open fix PR #16810 (a segment that claims a sort its documents violate, reached through doc-values updates of a sort field when the writer config has no index sort; fix site IndexWriter only, does not fix this repro); closed #14399 / #16434 (TopFieldCollector cached the early-termination decision across leaves with different, each true, sorts; the per-segment fix still trusts a leaf's false sort); #7824 / LUCENE-6766 (introduced the rule; its review fixed only the null-order dependence, with field-less test documents); #16857 (merged 2026-10-29 as 70a428b5ba9 on main and 203699279f5 on branch_11x, not on branch_10_6; sort-pruning refactor: FieldValueHitQueue.canEarlyTerminate still trusts getMetaData().sort() and its no-op-leading-field branch widened the reach: a ParallelLeafReader whose first reader serves a constant, skip-indexed leading sort field over a main reader sorted by (a, s) early-terminates a search sorted by s and returns s=1 instead of 0; a repro of it fails on e1faeba08bd with -ea, 10 of 10 iterations, and with -da, and passes on 645d4fe14a2 with -ea and -da and on 10.6.0 with -ea).
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; runs of 2026-10-29) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars. The hunt's earlier runs used maina9779ef3c193(no commit between the two touches the files involved) and the releases 6.2.0 to 10.5.2 and the 10.6 RC. The recommended fix was validated in the scratch worktree: the repro test with 10 neighbouring suites (11 suites, 168 tests), theorg.apache.lucene.indexpackage and:lucene:core:check -x test.
- Finding record
lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java :35-50 (class javadoc: union of fields, first index that has the field, sidecar use case, 'created and modified the same way ... undefined behavior' warning), :126-143 (first non-null sort kept, only a second different non-null sort rejected), :156-159 ('first reader having a given field "wins"'), :193 (new LeafMetaData(..., indexSort, ...))lucene/core/src/java/org/apache/lucene/index/LeafMetaData.java :32-33 ('sort the order in which documents from this index are sorted, or null if documents are in no particular order'); ParallelCompositeReader.java :133 (one ParallelLeafReader per leaf); IndexWriter.java :3228-3252 (validateMergeReader checks only that the advertised sort is congruent) and :1965-1970 (doc-values updates of index-sort fields refused)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:36-49 (at 645d4fe14a20) (class javadoc), :126-142, :154-159, :193, :396-399lucene/core/src/java/org/apache/lucene/index/ParallelCompositeReader.java:132-136; (at 645d4fe14a20) index/LeafMetaData.java:32-33lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:58-59, (at 645d4fe14a20) :151-152; search/Sort.java:145-146; search/IndexSortSortedNumericDocValuesRangeQuery.java:201, :432, :535; document/SortedNumericDocValuesRangeQuery.java:239; document/SortedSetDocValuesRangeQuery.java:290lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3228-3252, (at 645d4fe14a20) :3290; index/CheckIndex.java:1114, :1146-1149, :4742-4754
- Who is affected
lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:42-44 (at 645d4fe14a20)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/LeafMetaData.java:32-33; (at 645d4fe14a20) index/ParallelLeafReader.java:38-49, :136-142; index/IndexWriter.java:1965-1970; index/SlowCompositeCodecReaderWrapper.java:94lucene/core/src/test/org/apache/lucene/index/TestDemoParallelLeafReader.java:178-182; (at 645d4fe14a20) index/TestParallelLeafReader.java:338-398lucene/CHANGES.txt:729-730, (at 645d4fe14a20) :8700-8702
- Suggested fix
lucene/test-framework/src/java/org/apache/lucene/tests/util/LuceneTestCaseParent.java:2402-2404 (at 645d4fe14a20)
- TestParallelLeafReaderShadowedIndexSort.java (JUnit test):
repro/LFV-981/src/org/apache/lucene/index/TestParallelLeafReaderShadowedIndexSort.java(65 lines)
It ends on the summary card that is also the PNG.
assets/LFV-981/bug.png(418 KB)