FreeTextSuggester scores a single word as its count divided by the total number of tokens it was built from. A rebuild sets that total to 0 before it reads the new input, but swaps in the new FST and entry count only at the end. A rebuild that throws therefore leaves the old FST next to a total of 0.
- It stores word counts and word-pair counts in one FST. For
lookup("foo b")it first offers words that followed "foo" (pair count / count of "foo"), then backs off to single words that start with "b", multiplied by 0.4 (ALPHA). - A single word's score is its count divided by
totTokens, the number of tokens in the input it was built from. Lookup values areLong.MAX_VALUEx score. build()replaces the whole model. Since 9.2.0 it installs the new FST and entry count only after it succeeded, so a failed rebuild keeps the previous ones.
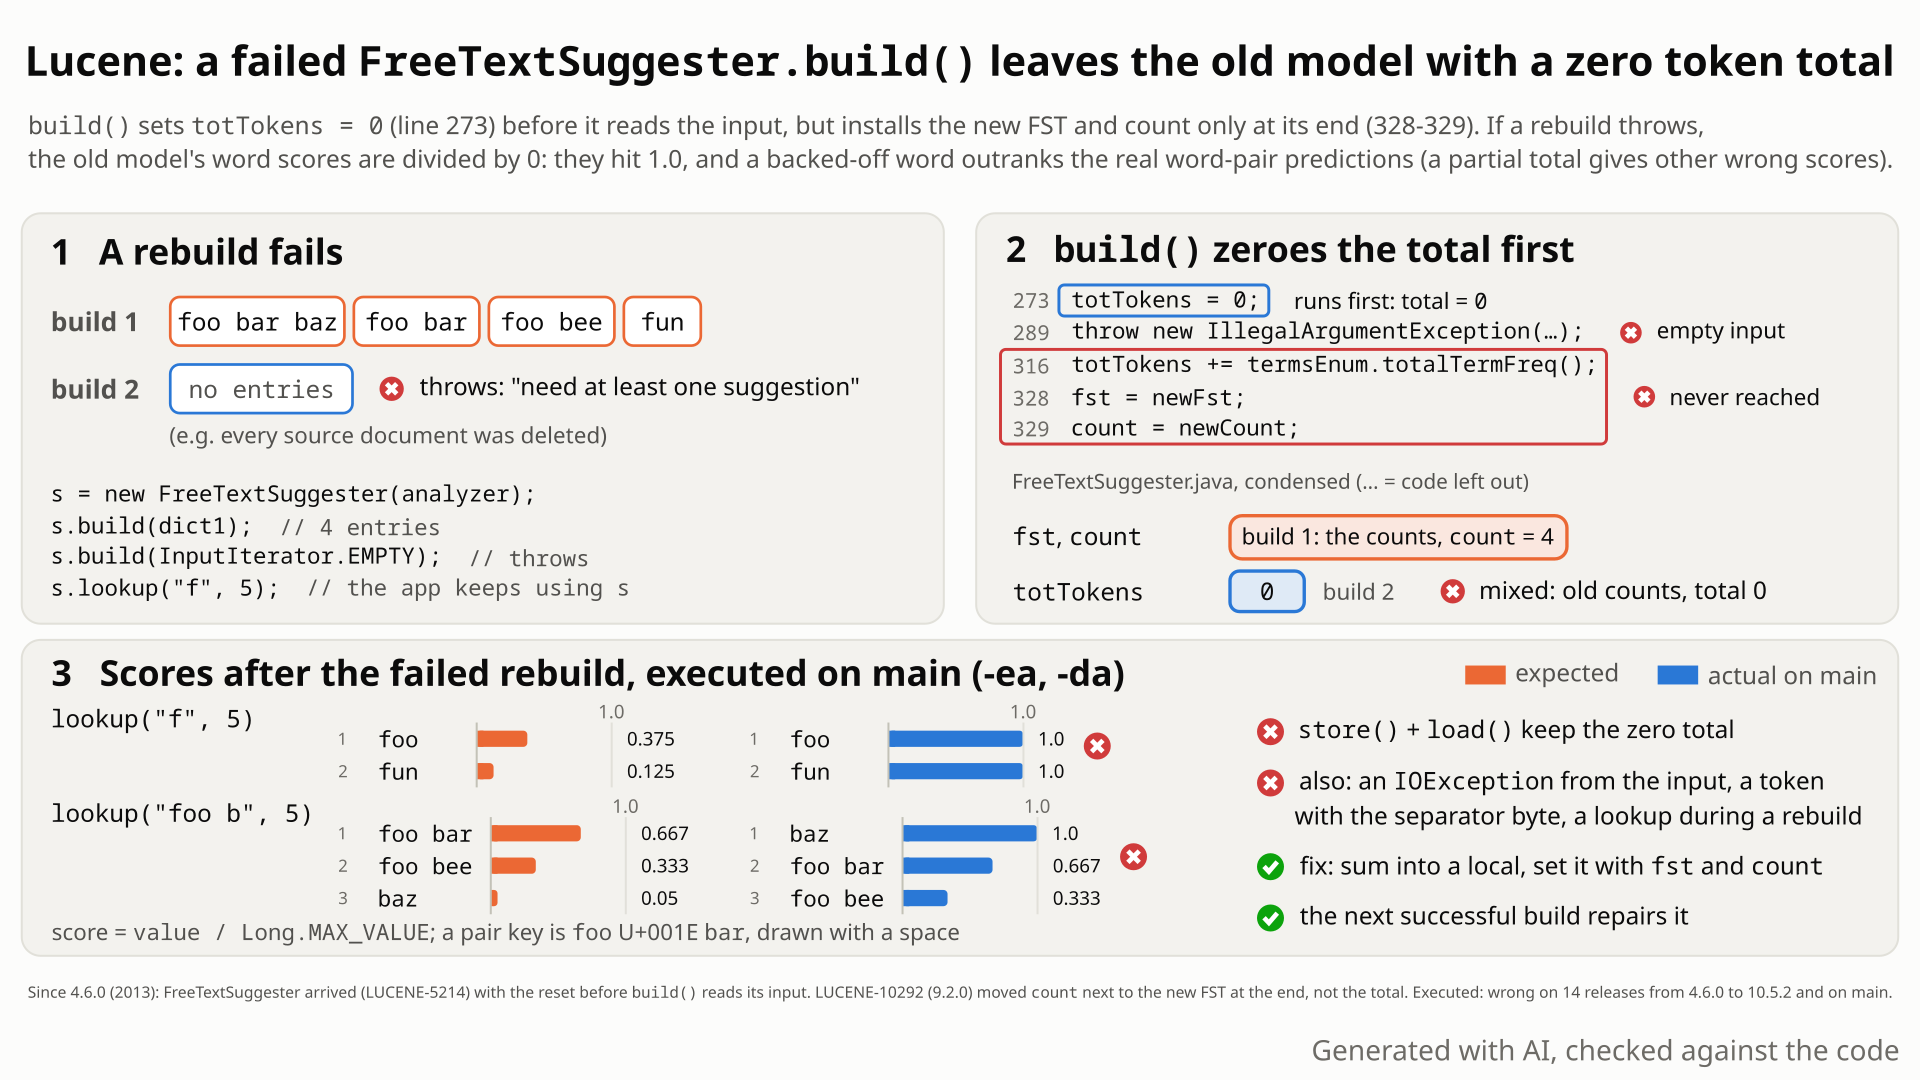
645d4fe14a20: how the scores are made, the rebuild that zeroes the total and fails before the new model is installed, the lookup that divides by 0, expected versus actual, and the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
FreeTextSuggester(default bigrams) from 4 entries: foo bar baz, foo bar, foo bee, fun, 8 tokens in all.lookup("f")gives foo 0.375 (3 of 8 tokens) and fun 0.125;lookup("foo b")gives foo bar 0.667, foo bee 0.333, then the backed-off single word baz 0.05 (0.4 x 1/8). - Rebuild the same instance from an empty dictionary,
build(InputIterator.EMPTY). It throws "need at least one suggestion"; you catch it and keep serving. You expect the old scores: the old model andgetCount()(4) are kept. - Instead
lookup("f")gives foo 1.0 and fun 1.0, andlookup("foo b")puts baz first at 1.0, ahead of foo bar 0.667 and foo bee 0.333. No error. - Why: a single word scores its count divided by the total token count
totTokens.build()sets that total to 0 before it reads the input, but installs the new FST and count only after success. So the old FST is scored against 0: 3 / 0 is infinite and saturates at 1.0.store()saves the zero total too.
Applications that keep serving or storing a FreeTextSuggester after a rebuild of it threw: an empty dictionary, a failing input or analyzer, or a token with the separator byte. Opt-in, experimental class; default settings; any size; deterministic. Rare: the recorded search found no public report of these scores, and the next good build repairs them.
Mechanism, terms and numbers817 words
FreeTextSuggester (lucene/suggest, @lucene.experimental) predicts the next word with an n-gram model and stupid backoff; a single word's score is its count divided by totTokens, the number of tokens the model was built from (FreeTextSuggester.java:568, :680-687 on main 645d4fe14a20). build() sets the field totTokens = 0 (:273) before it reads the first entry and adds to it while it builds the new FST (:315-317), but installs fst and count only after success (:328-329, since LUCENE-10292 in 9.2.0). So a rebuild that throws, on an empty or stop-words-only dictionary ("need at least one suggestion"), an IOException from the input, an analyzer exception or build()'s own rejection of a token with the separator byte, keeps the previous FST and getCount() but scores it against a total of 0 or a partial total. With 0 every single-word suggestion scores Long.MAX_VALUE (1.0) and a backed-off word outranks the real bigram predictions: for the model {foo bar baz, foo bar, foo bee, fun}, lookup("f") goes from foo 0.375, fun 0.125 to 1.0 and 1.0, and lookup("foo b") ranks baz 1.0 first instead of 0.05 last. No error; store() writes the zero total (:355), so a reloaded copy is damaged the same way; the next successful build() repairs it. Every release from 4.6.0 through 10.6.0 and main. Accumulating the total in a local and publishing it next to fst and count fixes it (+3/-3).
- FreeTextSuggester: a
Lookupthat "uses the stupid backoff language model to smooth scores across ngram models" (FreeTextSuggester.java:93-95on main645d4fe14a20); default bigrams (:116-117), default separator byte 0x1e between the words of an n-gram (:147-151),@lucene.experimental(:103). "The value is Long.MAX_VALUE * score ... Divide by Long.MAX_VALUE to get the score back, which ranges from 0.0 to 1.0" (:97-99). - ALPHA: "if a given trigram did not occur, and we backoff to the bigram, the overall score will be 0.4 times what the bigram model would have assigned" (
:121-126). - totTokens: a field (
:134); for single-word predictionslookup()uses it as the denominator,long contextCount = totTokens;(:568); for longer n-grams it uses the context's own count from the FST (:572-581).
build(InputIterator, double)rejects payloads and contexts first (:247-252; those leave the model intact), then setstotTokens = 0;(:273) and reads the input into a temporary index (:276-284).- After that point it can throw: no terms gives "need at least one suggestion" (
:288-290), a term with too many grams gives "tokens must not contain separator byte" (:305-314), and anIOExceptionfromnext()or the analyzer propagates. (The second "need at least one suggestion" check,:325-327, is a defensive guard: once there are terms, every term goes into the FST, andFSTCompiler.compile()returns null only for an FST that accepts nothing,FSTCompiler.java:1002-1005.) - While the terms move into the new FST, single words add to the field:
totTokens += termsEnum.totalTermFreq();(:315-317). Only after success:fst = newFst; count = newCount;(:328-329). - A failure leaves the old FST and count with a total of 0, or with the part of the new input counted before the failure.
- The value is
(long) (Long.MAX_VALUE * backoff * ((double) decodeWeight(completion.output())) / contextCount)(:680-687): the n-gram's count from the FST overcontextCount. WithcontextCount= 0 the double isInfinityand the cast givesLong.MAX_VALUE, so every single word scores 1.0. The backoff factor no longer helps (0.4 xInfinityis stillInfinity), so the backed-off baz scores 1.0 and sorts first for "foo b"; foo and fun tie at 1.0 and come out in key order (:695-705). store()writestotTokens(:355) andload()reads it back (:377), so a copy saved after the failed build keeps the damage. The next successfulbuild()repairs it.
Model {foo bar baz, foo bar, foo bee, fun}: single-word counts foo 3, bar 2, baz 1, bee 1, fun 1 (total 8); pairs foo bar 2, foo bee 1, bar baz 1.
| lookup | before (and expected after) | after build(InputIterator.EMPTY) throws |
|---|---|---|
getCount() | 4 | 4 |
"f" | foo 0.375, fun 0.125 | foo 1.0, fun 1.0 |
"foo b" | foo bar 0.667, foo bee 0.333, baz 0.05 | baz 1.0, foo bar 0.667, foo bee 0.333 |
A separator-byte rejection leaves a partial total that depends on the new input. With the hunt's new input "foo<U+001E>bar baz" the rejection comes after "baz" was counted, so the total is 1: foo and fun still score 1.0, and baz scores 0.4, above foo bee. Other inputs leave other partial totals, which can also lower the scores (an independent reproducer's input doubled its total: cat 0.1 and cow 0.05 instead of 0.2 and 0.1).
Exposure and likelihood216 words
- Who is hit. Code that rebuilds a serving
FreeTextSuggesterin place and keeps using it afterbuild()threw. Solr's suggest component keeps serving after a failed rebuild:SuggestComponent.buildSuggesterIndexcatches the exception, logs it and keeps serving the sameLookup, whichSolrSuggester.buildrebuilt in place. Solr stores the lookup only afterbuild()returned normally, so it shows the serving case, not the persistence case. Solr users have posted this exact "need at least one suggestion" failure, one from a rebuild on commit (Stack Overflow 71582458) and one from a build at startup (solr-user 2018-08-03), without looking at the scores. - Default or opt-in. Opt-in: one
Lookupamong several,@lucene.experimental. Within it, the default bigrams and separator are affected. - Effect. Silent wrong scores and ranking: every single word at 1.0 when the total is 0, a backed-off word first, and with a partial total scores off in either direction. No exception; since 9.2.0
getCount()is unchanged, so nothing tells the application. Assertions on or off make no difference. - Persistence.
store()after the failed build writes the damaged total; the next successfulbuild()repairs it. - Scale. None needed: 4 entries, one thread.
- How likely: rare. It needs a rebuild that throws and continued use of that instance; the recorded 2026-10-29 search found no public report of these scores.
The test shows that FreeTextSuggester.build() resets its unigram token total before it reads the input, so a rebuild that throws (here build(InputIterator.EMPTY), rejected with IllegalArgumentException) leaves the previous model scored against a total of 0.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.analyzing;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.search.suggest.FileDictionary;
import org.apache.lucene.search.suggest.InputIterator;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestFreeTextSuggesterFailedRebuild extends LuceneTestCase {

  public void testRejectedRebuildKeepsUnigramScores() throws Exception {
    FreeTextSuggester suggester = new FreeTextSuggester(new StandardAnalyzer());
    String text = "foo bar baz\nfoo bar\nfoo bee\nfun\n";
    suggester.build(
        new FileDictionary(new ByteArrayInputStream(text.getBytes(StandardCharsets.UTF_8)))
            .getEntryIterator());
    String before = suggester.lookup("f", 2).toString();
    expectThrows(IllegalArgumentException.class, () -> suggester.build(InputIterator.EMPTY));
    // expected: foo 3/8 and fun 1/8 of Long.MAX_VALUE as before; actual: both Long.MAX_VALUE
    assertEquals(before, suggester.lookup("f", 2).toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-982/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.analyzing.TestFreeTextSuggesterFailedRebuild
- Expected vs actual
- Expected: lookup("f") unchanged, [foo/3458764513820540928, fun/1152921504606846976] (3/8 and 1/8 of Long.MAX_VALUE). Actual (-ea and -da): [foo/9223372036854775807, fun/9223372036854775807].
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[foo/[3458764513820540928, fun/1152921504606846976]]> but was:<[foo/[9223372036854775807, fun/9223372036854775807]]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.analyzing.TestFreeTextSuggesterFailedRebuild.testRejectedRebuildKeepsUnigramScores(TestFreeTextSuggesterFailedRebuild.java:37)build()already keeps the previous FST and entry count when it fails (since 9.2.0); only the token total is reset.- The result is a state no n-gram model can produce: two words both at 1.0, a backed-off word above the 0.4 factor.
- The triggers are public:
InputIterator.EMPTY, anIOExceptionfromnext(), orbuild()'s own rejection of the new input.
The full argument290 words
- The method keeps the rest of the previous model.
fstandcountare installed only after success (FreeTextSuggester.java:328-329). LUCENE-10292 made that change: "Fix other FST based suggesters so that getCount() returned results consistent with lookup() during concurrent build()" (lucene/CHANGES.txt:4289-4291, 9.2.0). On #11328 hossman (they) described the other suggesters as having "atomically replaced their internal structures (typically FSTs) at the end of their build() process" and wrote "I evidently overlooked that FreeTextSuggester has this same code pattern" (aboutcount, which their commit then fixed).totTokensbelongs to the same model (store()writes it next tofstandcount) and was not touched. - The model's own semantics break. Stupid backoff (
:93-95) andALPHA(:121-126) cannot give two words 1.0 each for "f" or a backed-off word 1.0. The state is neither the old model, a new one, nor empty. - Public triggers.
InputIterator.EMPTYis a public constant (InputIterator.java:57);next()declaresIOException(BytesRefIterator.java:32-34); the empty and separator rejections come frombuild()itself. In the separator case only the new input is invalid, yet the previous, valid model is damaged. - Tests state the intent but check no scores.
SuggestRebuildTestUtil"confirms that assertions which pass after an initial build will continue to pass during a (slow) rebuild" (SuggestRebuildTestUtil.java:33-35);TestFreeTextSuggester.testLookupsDuringReBuildchecks onlygetCount()and keys (:98-119),testIllegalByteDuringBuildonly that a fresh instance throws (:121-134). Of the tests that useFreeTextSuggester(TestFreeTextSuggesterand the@IgnoredTestLookupBenchmark, by grep), none looks up after a failedbuild(). - History. The early reset is the class's first version (2013), kept through LUCENE-5404, LUCENE-10292 and a 2025 refactor; the commits and discussions inspected record no rationale for it.
The devil's-advocate check263 words
The intended-behaviour checker and a reviewer from another model family (OpenAI GPT-5.6) built the strongest case: no javadoc promises failure atomicity (Lookup.build says only "Builds up a new internal {@link Lookup} representation", Lookup.java:178-182) and the class is @lucene.experimental; the documented 0.0-1.0 range is not broken, because the cast saturates at 1.0; a separator byte in a token is a documented precondition violation ("No input tokens should have this byte, otherwise IllegalArgumentException is thrown", FreeTextSuggester.java:176-181) and an empty dictionary is rejected; maintainers said on #11328 that concurrent build and lookup is not guaranteed (dweiss (they): "Concurrency concerns should be handled by the code that uses Lookups"); and the open #5558 favours building a new instance and swapping it in.
Why it fails: the code does keep the previous fst and count, and Lookup.build still rebuilds in place, so the gap is one field LUCENE-10292 did not cover. The precondition explains the exception, not the damage to the previous valid model, and the empty-input and IOException triggers are not misuse. The concurrency remark applies only to the secondary lookups-during-rebuild symptom; the main case is single-threaded. @lucene.experimental concerns API compatibility, not correctness. The contract question stays open, though: Lookup.build promises no failure atomicity, so a maintainer may treat the fix as an improvement rather than a bug fix. Every check that ran the code found a real bug, and every check that rated priority rated it low; of the reading-only cross-model reviews, one said real (medium confidence), the other returned a procedural "not real" because it could not run the code.
Recommended Accumulate the total in a local and publish it with fst and count
Sum the total into a local newTotTokens and assign it next to fst and count once the new FST is complete (+3/-3 in FreeTextSuggester.java). Validated: the repro passes with assertions on and off, the whole suggest module passes and check passes.
-      totTokens = 0;
-
+      long newTotTokens = 0;
       long newCount = 0;
 ...
-            totTokens += termsEnum.totalTermFreq();
+            newTotTokens += termsEnum.totalTermFreq();
 ...
         fst = newFst;
+        totTokens = newTotTokens;
         count = newCount;
All options and trade-offs4 options · 449 words
One fix was built and validated; three alternatives were considered and not built.
Accumulate the total in a local and publish it with fst and count (validated by the checks) (recommended)
In build(), replace totTokens = 0; with long newTotTokens = 0;, add to the local while the terms move into the FST, and assign totTokens = newTotTokens; between fst = newFst; and count = newCount;. A failed build then leaves all three fields of the previous model as they were.
-      totTokens = 0;
-
+      long newTotTokens = 0;
       long newCount = 0;
 ...
-            totTokens += termsEnum.totalTermFreq();
+            newTotTokens += termsEnum.totalTermFreq();
 ...
         fst = newFst;
+        totTokens = newTotTokens;
         count = newCount;
Trade-offs
- Three plain field writes, as today's
fstandcountpublication: not one atomic snapshot, so a lookup on another thread that races the publication can still pair the new FST with the old total for an instant. - It also fixes lookups made while a rebuild is still reading its input (the hunt's concurrent test passes with it).
- No cost on the lookup path.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle, OpenJDK 25: the repro test fails on the stock tree and passes with the fix, with assertions on and off. These gradle test runs used an earlier copy of the test whose one comment line was longer; it was shortened for google-java-format, with no code change, andcheckand the standalone runs used the final file. - With the fix and the test, the whole
lucene/suggestmodule passes with assertions on and off: 32 suites, 237 tests, 7 skipped, 0 failures (TestFreeTextSuggester: 11 tests, 1 skipped). :lucene:suggest:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Earlier, the hunt's 5 tests (every trigger,
store()+load(), lookups during a rebuild) passed 5 of 5 with the same change, and its bounded-exhaustive fault-injection check found 0 mixed states.
Save totTokens before the reset and put it back in a catch before rethrowing. Not built.
Trade-offs
Same single-threaded result with more code, and lookups during a successful rebuild would still see the reset total.
Hold fst, totTokens and count in one final object published by a single volatile write and read once per lookup() / store(). Not built.
Trade-offs
Also closes the publication race and would cover the load() counterpart, but touches lookup(), store(), load() and getCount(): larger than the bug needs.
Javadoc only. Not recommended.
Trade-offs
Leaves silent wrong scores in place, while the method already keeps the rest of the previous model.
Solr's suggest component logs a failed rebuild and keeps serving the same Lookup, so a Solr FreeTextSuggester whose rebuild meets an empty dictionary serves these scores until its next good build.
An exception-safety planning probe rebuilt a built FreeTextSuggester from inputs that make build() throw and, for the empty and the failing input, saw the single-word scores jump to the maximum. The hunt injected 25 kinds of failure into rebuilds of 3 previous states (44 mixed states in 75 failed builds, 0 with the fix) and reduced it to a JUnit.
The method in full241 words
Method: non-formal first signal, then semi-formal: a planning probe followed by a bounded-exhaustive fault-injection check (the hunt's hunt unit for suggest lookups whose failed build or load leaves mixed state, 2026-10-28, main a9779ef3c193).
- Lead. A planning probe for exception safety rebuilt a built
FreeTextSuggesterfrom an empty input, a separator-byte input and a failing input on the stock jars (assertions on and off): after the empty and the failing input the single-word values turned to 9223372036854775807, andstore()+load(), checked after the failing input, kept them; its separator-byte input was accepted without an exception (a separate bug, LFV-600). The same on thebranch_10_6RC jars. - Exhaustive check. A translation-validation harness on the stock jar: 25 failure kinds (empty and stop-words-only input, an
IOExceptionorRuntimeExceptionfromnext()at each call, a separator token at each position, an analyzerIOExceptionat each input, and 3 controls that throw before any state changes: payloads, contexts, a negative RAM buffer) x 3 previous states (built, loaded from a stored copy, fresh) = 75 failed builds, plus a deterministic hand-off at everynext()call of a concurrent rebuild; 312 checks per assertion mode. All 22 non-control kinds left a mixed state on the built and on the loaded suggester (44 of 75), the controls none, and 4 of 4 hand-off points were mixed; 0 with the fix. - JUnit. Reduced to a public-API JUnit; this doc reduced it further to one test.
No prior report found (searched 2026-10-29): 255 queries over GitHub issues, PRs and commits, downstream trackers, the Lucene and Solr lists, the JIRA archive, Stack Exchange and the web; 18 hits read. Nearest: #11328 (LUCENE-10292), which fixed the entry count in this method and left the token total.
Searches6 searches
Related, not reports of this bug: #11328 / LUCENE-10292 (the count and concurrent-rebuild fix; token total and scores never mentioned) and its dev@ thread of 2022-04-27; #5558 / LUCENE-4492 (open, immutable suggesters, no failure discussion); SOLR-11139 (open since 2017) and solr-user threads of 2017 and 2018 plus Stack Overflow 71582458 (users hitting build()'s separator and empty-dictionary rejections, not the scores left behind); #15134 (the 2025 refactor that moved the line); #13390 (the only open PR on the file: javadoc and shingle filter). Tracking issue #16937 does not mention FreeTextSuggester. Gap: the GitHub search quota ran out during the run; every manual query was retried until it returned.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and downstream trackers | 2026-10-29 | a scripted prior-report search with three specs (failed build, concurrent rebuild, Lookup build atomicity), 38 manual searches over apache/lucene, lucene-solr, solr, lucenenet, Elasticsearch and OpenSearch, 14 full threads read | no report; only the related items below |
| Open PRs | 2026-10-29 | the changed files of all 414 open apache/lucene PRs; every item updated since 2026-10-26 | only #13390 touches FreeTextSuggester.java (javadoc, shingle filter) |
| Mailing lists | 2026-10-29 | 29 queries over dev@, java-user@, issues@, general@ and the Solr lists; 18 mails read in full | no report |
| JIRA archive | 2026-10-29 | 7 JQL queries on LUCENE and SOLR, 8 issues read in full | no report |
| Web and Stack Exchange | 2026-10-29 | 11 web searches; 2 Stack Overflow questions read through the Stack Exchange API | no report |
| GitHub (re-check) | 2026-10-29 | 6 searches (FreeTextSuggester, totTokens, build exception, rebuild failure, the message, score); the 12 PRs created since 2026-10-27 | nothing new; none of those PRs touches lucene/suggest |
Introduced with the class in 4.6.0 (LUCENE-5214, b50a2edbb23, 2013); not a regression. LUCENE-10292 (9.2.0) made the FST and entry count install after success and left the reset. Fails on every executed release from 4.6.0 to 10.5.2, on the 10.6.0 release candidate and on main; unchanged upstream.
Versions tested7 rows
Introduced by b50a2edbb23 on trunk, "LUCENE-5214: add FreeTextSuggester" (Michael McCandless, 2013-10-02; JIRA LUCENE-5214, migrated as #6278, no PR), shipped through the branch_4x backport 9494be7ec2a in 4.6.0. Its first build() already reset totTokens before the input loop and assigned fst at the end.
Later changes to the same method that kept the reset: LUCENE-5404 (b5926da2d67 / fdf4595051a, 4.7.0) added count, also reset early, so from 4.7.0 to 9.1.0 a failed build also reset getCount() (to 0, or to the number of new entries read before the failure); LUCENE-10292 (a8d86ea6e8b / 65f5a3bcc5a, #11328, 9.2.0) installed fst and count after success; #15134 (b85f030c6cc, 2025, main only) moved the line in a refactor. The last upstream commit to the file is 54283150a81 (2026-06-14, typo tooling).
Range. The 14 releases in the table were executed; the releases between them were read at their release tags, and each still resets the total before it reads the input. The history clone has no tags for 8.8.2 to 8.11.3, so that range rests on the unchanged code before and after it and on the executed 8.11.4.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 and a9779ef3c193 | affected | the one-test repro fails (gradle and standalone, assertions on and off); the hunt's 5 tests fail 5 of 5 |
branch_10_6 RC jars | affected | the fault-injection check finds the same mixed states |
| 10.5.2, 10.0.0, 9.12.3, 9.2.0 | affected | scores change, getCount() stays 4; the one-test repro fails on 9.2.0, 9.12.3 and 10.5.2 |
| 9.1.0, 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5, 4.10.4, 4.7.0 | affected | scores change, and getCount() is reset too: 0 after the empty-input rebuild, 1 after the IOException and separator rebuilds (the entries read before the failure) |
| 4.6.1, 4.6.0 | affected | scores change; no getCount() yet |
| 4.5.1 | API absent | no FreeTextSuggester |
| main + fix | not affected | the repro passes; the suggest module passes (32 suites, 237 tests), assertions on and off |
An independent reproducer, an intended-behaviour devil's advocate and reading-only reviews by another model family (OpenAI GPT-5.6) agree on the root cause; an adjudication confirmed it with high confidence and a credibility audit kept it at low priority. This doc re-ran a one-test repro on main and validated the fix with gradle.
Checks and verdicts316 words
The cross-model reviews were reading-only: they could not run Java. The refute-lens review returned a procedural "not real, low" while agreeing on the root cause; a separate re-run failed 5 of 5. An executing cross-model review is still open.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate, priority low | 5-test JUnit fails 5 of 5 on main (assertions on and off), 10.5.2 and 9.12.3; fault-injection check: 44 mixed states in 75 failed builds, 0 with the fix. |
| cross-model review, refute lens | not real (low confidence), procedural | OpenAI GPT-5.6, reading-only, could not run Java; agreed on the root cause and that the inputs are in contract. A separate re-run failed 5 of 5. |
| Independent reproducer | real | Own JUnit fails 5 of 7 on main and 10.5.2, both controls pass; own fix 7 of 7; corrected two overclaims (the 0-1 range; saturation only at a zero total). |
| Cross-model review, works-as-designed lens | real (medium confidence) | OpenAI GPT-5.6, reading-only; cited the LUCENE-10292 CHANGES entry and the rebuild test's invariant. A separate re-run failed 5 of 5. |
| Intended-behaviour devil's advocate | real, priority low | Built the strongest works-as-designed case and refuted it for the single-threaded case; the JUnit fails 5 of 5. |
| adjudication | confirmed (high confidence), priority low | Re-ran the independent reproduction's JUnit with a new seed (assertions on and off): 5 of 7 fail, controls pass. |
| Registration check and credibility audit | keep, priority low | Fresh seeds: the finder's JUnit 5 of 5 fail; with the fix shadowed 5 of 5 pass. Impact 60, low priority, security none. |
| brief re-runs | reproduced; fix validated | The one-test repro on main 645d4fe14a20 (gradle and standalone, assertions on and off), 9.2.0, 9.12.3, 10.5.2; the fix with the repro, the suggest module and check. The gradle test runs used an earlier copy of the test with a longer comment line (no code change). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 432 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,570 words
- Registry title
- FreeTextSuggester.build() resets its unigram token total before it reads the input, so a rebuild that throws (an empty dictionary, an IOException from the input, or build()'s own separator-byte rejection) leaves the previous model scored against a zero or partial total: unigram suggestions get wrong scores (every one Long.MAX_VALUE, i.e. 1.0, when the total is 0), a backed-off unigram outranks the real bigram predictions, and store() persists it
- Area
- suggest / FreeTextSuggester (n-gram suggester; build() failure atomicity of the unigram token total)
- Priority
- Low, rank 492: A failed FreeTextSuggester rebuild silently mis-scores the model it keeps serving and store() persists it, but it is an experimental suggester on an error path that the next good build fixes, and it is easier to trigger than LFV-784.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in, @lucene.experimental FreeTextSuggester (default grams and separator, any size, -ea and -da alike) and keep serving or storing an instance after a rebuild of it threw (an empty or stop-words-only dictionary rejected with 'need at least one suggestion', an IOException or RuntimeException from the InputIterator or the analyzer, or build()'s own rejection of a token that contains the separator byte) get, with no error, unigram predictions of the previous model scored against a zero or partial token total: with a zero total every unigram scores Long.MAX_VALUE (1.0) and a backed-off unigram outranks the real bigram predictions, with a partial total the scores are wrong without necessarily saturating; getCount() and the FST stay those of the previous build, store() writes the damaged total so a reloaded copy keeps it, and the next successful build() repairs it; lookups made while a successful rebuild is still reading its input see the same scores (the weaker, concurrent half, which Lookup does not document); every release from 4.6.0 through 10.5.2 and 10.6.0.
- Summary
- You build a FreeTextSuggester (bigram model) from {foo bar baz, foo bar, foo bee, fun}, so lookup('f') scores foo 3/8 and fun 1/8 and lookup('foo b') ranks 'foo bar' (2/3) and 'foo bee' (1/3) above the backed-off unigram baz (0.4 x 1/8); then you rebuild the same instance from an empty dictionary, or one whose next() throws IOException, catch the exception and keep using it. You expect the previous model to be untouched, as its FST and getCount() are, because build() publishes those only after success. Instead build() has already set the unigram token total to 0, so foo and fun both score Long.MAX_VALUE (1.0), baz jumps to first place at 1.0 ahead of both real bigram predictions, and store() writes the zero total so a reloaded copy is damaged the same way.
- Introduced
- b50a2edbb2389797a7354775414052df91b108f6 (trunk, svn r1528517) and its branch_4x backport 9494be7ec2ae84e88b6fc07046c35cac15e790d2 (svn r1528521, the commit that shipped in 4.6.0): LUCENE-5214 'Add new FreeTextSuggester, to handle "long tail" suggestions' (migrated issue apache/lucene#6278; author Michael McCandless; before GitHub pull requests, so no PR) [read: git log -S 'totTokens = 0', git log -S 'totTokens += termsEnum' and git blame -w at the parents of b85f030c6cc and a8d86ea6e8b in the full-history clone; exec boundary: 4.5.1 has no FreeTextSuggester, 4.6.0 fails]: the class's first build() resets totTokens before it reads the input and replaces fst only at the end. Later changes to the same method that left the reset in place: LUCENE-5404 (b5926da2d67 / branch_4x fdf4595051a, 4.7.0; added count with the same early reset), LUCENE-10292 (a8d86ea6e8b / branch_9x 65f5a3bcc5a, apache/lucene#11328, 9.2.0; published fst and count only after success, left 'totTokens = 0'), #15134 (b85f030c6cc, 2025-10-09, main only; a refactor that moved the line) (2013-10-02 (b50a2edbb23, author and commit date))
- First affected version
- 4.6.0 [exec: the follow-up's portable scores-only check fails on 4.6.0 for the empty-input, IOException and separator-byte rebuilds, and store()+load() keeps the damaged scores], the first release with FreeTextSuggester; 4.5.1 has no FreeTextSuggester class [exec: compile_error]
- Affected versions
- every release from 4.6.0 through 10.5.2, 10.6.0 (released 2026-10-29; branch_10_6 RC 4ae946e5a9b) and main a9779ef3c193; not fixed upstream (upstream main 645d4fe14a20 has no commit to FreeTextSuggester.java after 54283150a81, author date 2026-06-14; main and branch_11x still reset at :273, branch_10x and branch_10_6 at :274 [read]). [exec] the follow-up's portable check FreeTextFailedRebuildHistory (public API, scores only, -da) fails on 4.6.0, 4.6.1, 4.7.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.1.0, 9.2.0, 9.12.3, 10.0.0, 10.5.2 and main and passes on main with the fix shadowed; the finder's JUnit fails 5 of 5 on 9.1.0, 9.2.0, 9.12.3, 10.5.2 and main (-ea and -da on main) and its portable main() fails on 8.11.4 and 5.5.5; the independent reproduction's JUnit fails 5 of 7 (both controls pass) on main and 10.5.2 (-ea and -da) and 9.12.3 (-ea); the finder's translation validation fails on the branch_10_6 RC 4ae946e5a9b jars (-da). From 4.7.0 to 9.1.0 a failed build also reset getCount() (LUCENE-5404; LUCENE-10292 fixed that part in 9.2.0); from 9.2.0 on only the scores are wrong. Releases between the executed ones are inferred from the release tags in the history clone, which all keep the reset before the input loop (8.8.2-8.11.x tags are missing there; 8.11.4 was executed). Executed only on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-29, read-only; the prior-report record verdict new, high confidence, plus the finder's search at 2026-10-28, the independent reproduction's and the intended-behaviour check's searches, the adjudication's check and a recheck): 255 recorded queries (scripted prior-report searches over apache/lucene issues, PRs and commits, downstream repositories, the Lucene and Solr lists and the JIRA archive, plus manual GitHub, JIRA, lists.apache.org, Stack Exchange and web searches and the local full-history git); GitHub full-text search for 'totTokens' returns 0 items; the only open PR that touches FreeTextSuggester.java (#13390, javadoc and ShingleFilter construction) is not a fix; 18 hits assessed, none the same bug. Recheck: GitHub searches 'FreeTextSuggester' (5 hits: #15134, #6278, #11328, #6955, #7264), 'totTokens' (0), 'FreeTextSuggester build exception' (#11328 only), 'suggester rebuild failure' (#11328 only), '"need at least one suggestion"' (0) and 'FreeTextSuggester score' (0), retried after GitHub's search rate limit reset; none of the 12 apache/lucene PRs created since 2026-10-27 changes a file under lucene/suggest (changed-file lists read); by author date the last commit to FreeTextSuggester.java is 54283150a81 (#16255, 2026-06-14, typo checks) and the last under lucene/suggest is b6ca26f1212 (#16281, 2026-06-30, unrelated); upstream main is 645d4fe14a20 (2026-10-28). Related, not this bug: #11328 / LUCENE-10292 (closed, 9.2.0 Bug Fixes: in this same method it published fst and count only after success and left the token-total reset; scores and failed builds are never mentioned) and its dev@ thread of 2022-04-27, #5558 / LUCENE-4492 (open: suggesters should be immutable; no failure discussion), SOLR-11139 (open since 2017: the separator-byte rejection aborts the whole build), solr-user threads of 2017-07-24 and 2018-08-03 and Stack Overflow 71582458 (users hitting the separator-byte and empty-dictionary rejections; none looks at the scores left behind), SOLR-7084, SOLR-11668 and SOLR-17215 (lookups on a never-built suggester), #6467 / LUCENE-5404, #15134 (the 2025 refactor that moved the reset) and the Lucene.NET port (same reset, no report)
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; runs of 2026-10-29) through gradle in a scratch worktree and through a standalone runner, assertions on and off; the 9.2.0, 9.12.3 and 10.5.2 release jars. The hunt ran on maina9779ef3c193, whoselucene/suggestis identical; the follow-up's portable check ran on 14 releases from 4.6.0 to 10.5.2.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:93-99 (at a9779ef3c193) (class javadoc: stupid backoff model; value = Long.MAX_VALUE * score, 'ranges from 0.0 to 1.0'), :103 (@lucene.experimental), :121-126 (ALPHA = 0.4 backoff), :134 (field totTokens)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:176-181 (at a9779ef3c193) (4-arg constructor javadoc: 'No input tokens should have this byte, otherwise IllegalArgumentException is thrown')lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:247-252 (at a9779ef3c193) (payload and context rejections, before the reset), :273 (totTokens = 0 before the first iterator.next()), :289 and :326 ('need at least one suggestion'), :306-313 (separator-byte rejection), :316 (totTokens += totalTermFreq while the FST is built), :328-329 (fst and count published only after success), :355 (store() writes totTokens)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:568 (at a9779ef3c193) (contextCount = totTokens for unigram predictions), :682-692 (value = Long.MAX_VALUE * backoff * count / contextCount; backoff *= ALPHA)lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:171-182 (at a9779ef3c193) (getCount 'the number of entries the lookup was built with'; build 'Builds up a new internal Lookup representation': no failure-atomicity statement)lucene/CHANGES.txt:4272-4274 (at a9779ef3c193) (9.2.0, LUCENE-10292: 'Fix other FST based suggesters so that getCount() returned results consistent with lookup() during concurrent build()')lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestFreeTextSuggester.java:98-119 (at a9779ef3c193) (testLookupsDuringReBuild via SuggestRebuildTestUtil, keys only), :121-134 (testIllegalByteDuringBuild asserts the throw only)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:93-99, (at 645d4fe14a20) :103, :116-117, :121-126, :134, :147-151, :247-329, :349-358, :377, :568, :572-581, :680-692, :695-705
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:93-95, (at 645d4fe14a20) :121-126, :176-181, :328-329, :355lucene/CHANGES.txt:4289-4291; (at 645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/InputIterator.java:57; lucene/core/src/java/org/apache/lucene/util/BytesRefIterator.java:32-34; lucene/suggest/src/test/org/apache/lucene/search/suggest/SuggestRebuildTestUtil.java:33-35lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestFreeTextSuggester.java:98-134; (at 645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:178-182 (at 645d4fe14a20)
- TestFreeTextSuggesterFailedRebuild.java (JUnit test):
repro/LFV-982/src/org/apache/lucene/search/suggest/analyzing/TestFreeTextSuggesterFailedRebuild.java(39 lines)
It is made in parallel with this doc; every on-screen value comes from the code at 645d4fe14a20 or the diagram's executed probe.
assets/LFV-982/bug.png(432 KB)