Two class javadocs name a tokenizer that 8.0.0 removed; one of them builds it in an example.
- An analyzer is a chain: one tokenizer splits text into tokens, then token filters change them.
PorterStemFilterandStempelFilterare stemming filters, and they expect lower-case tokens. - Up to 7.x there were two ways to lower-case: the
LowerCaseFilterfilter, orLowerCaseTokenizer, which split on non-letters and lower-cased in one step. 8.0.0 removedLowerCaseTokenizer; its replacement isLetterTokenizerfollowed byLowerCaseFilter.
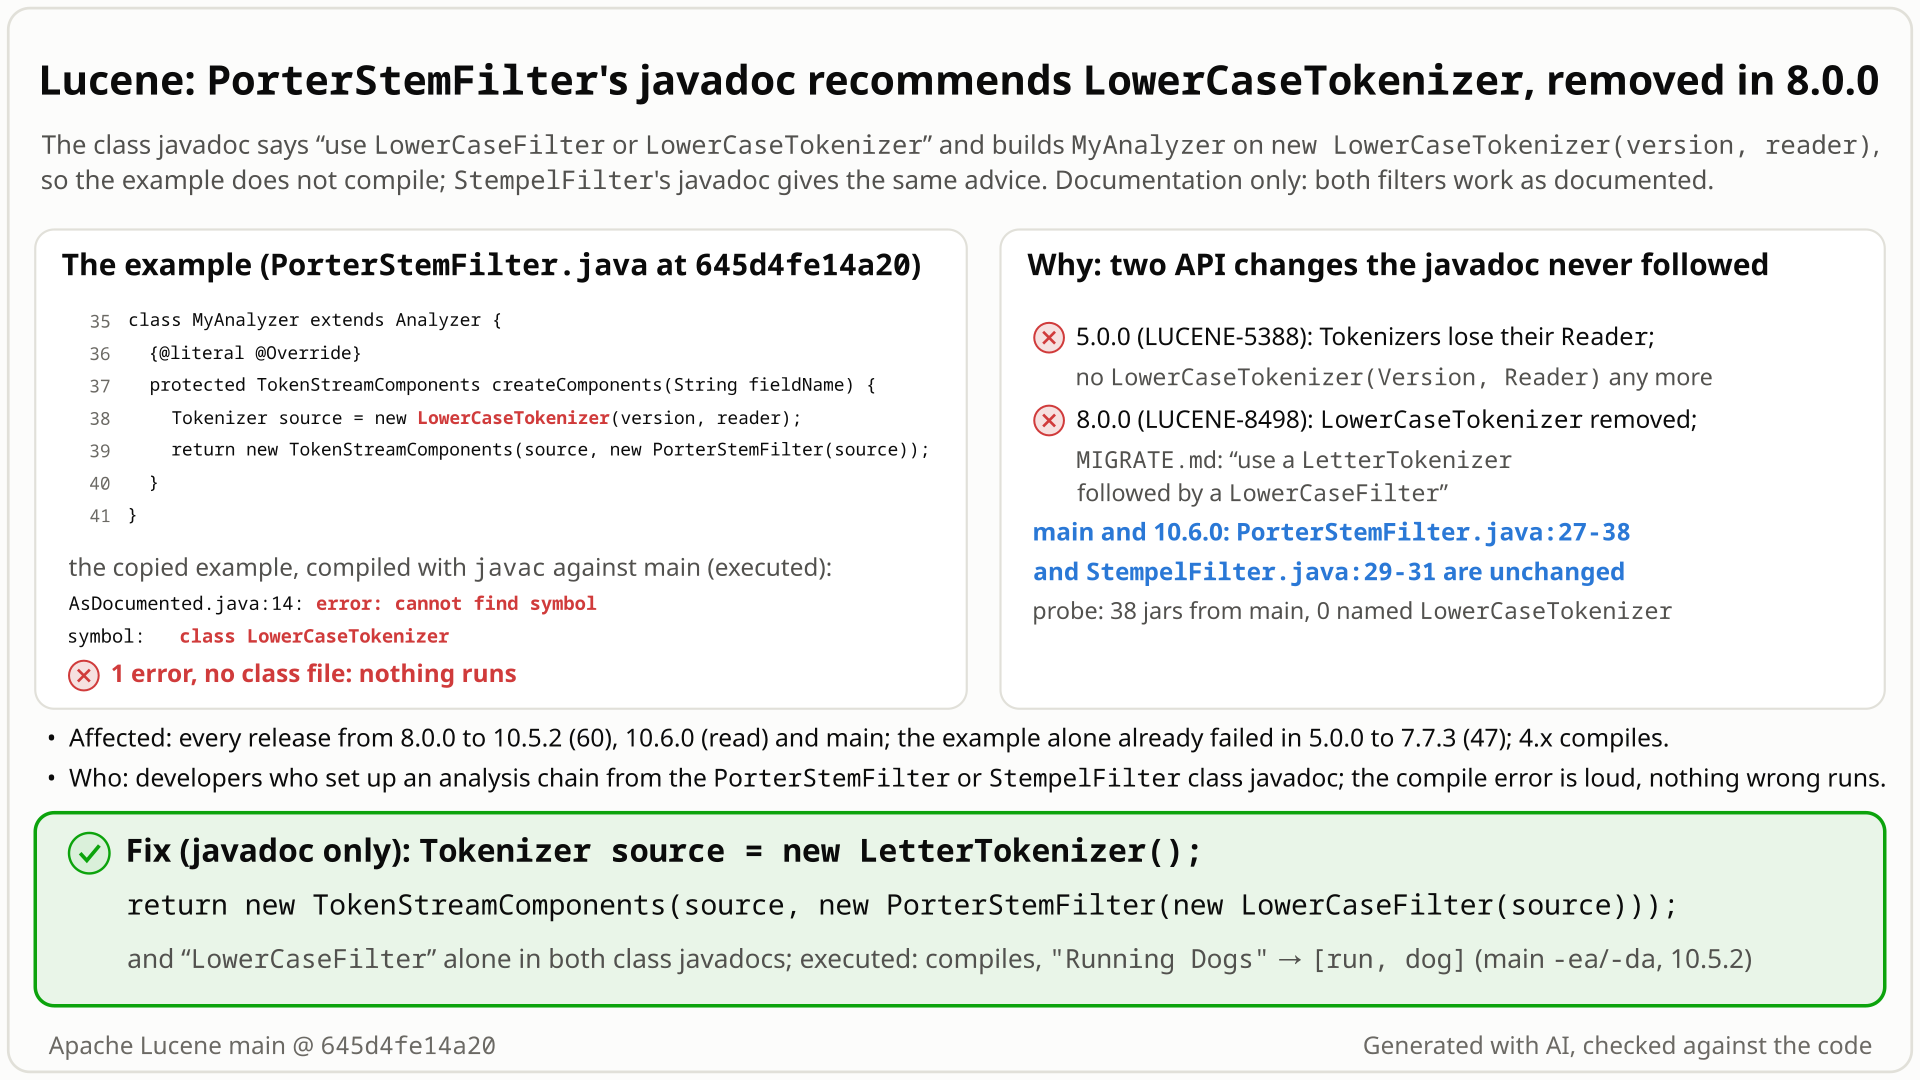
LowerCaseTokenizer, which 8.0.0 removed; the documented chain is LetterTokenizer -> LowerCaseFilter -> stemmer. Select the still to open it at full size. Generated with AI, checked against the code.- You want Porter stemming in your own analyzer.
PorterStemFilter's javadoc says its input must already be lower case, "so you will need to use LowerCaseFilter or LowerCaseTokenizer", and shows a 7-lineMyAnalyzerbuilt onnew LowerCaseTokenizer(version, reader).StempelFilter's javadoc gives the same advice. - You copy the example into a class with the imports it leaves out, declare the
versionandreaderit leaves undeclared, and compile against 10.6.0 or main. You expect it to compile and to stem "Running Dogs" to [run, dog]. - Instead javac stops with one error:
cannot find symbol: class LowerCaseTokenizer. Lucene has not shippedorg.apache.lucene.analysis.core.LowerCaseTokenizersince 8.0.0, and none of the 38 jars built from main has it;Class.forName("org.apache.lucene.analysis.core.LowerCaseTokenizer")throwsClassNotFoundException. - Why: LUCENE-8498 removed
LowerCaseTokenizerin 8.0.0 and told users to "use a LetterTokenizer followed by a LowerCaseFilter", but did not update these two javadocs. The example's(version, reader)constructor was already gone in 5.0.0. - Written with
new LetterTokenizer()andnew PorterStemFilter(new LowerCaseFilter(source)), the same example compiles and gives [run, dog]. Nothing wrong ever runs: it is a documentation fix.
Anyone who builds an analyzer from the PorterStemFilter or StempelFilter javadoc: the advice names a class missing since 8.0.0, and the example fails to compile on every release since 5.0.0. No configuration or input is involved. Nothing wrong ever runs, and the prose also names the valid LowerCaseFilter, so it is a Low documentation fix.
Mechanism, terms and numbers549 words
PorterStemFilter (analysis-common, the classic English stemmer that EnglishAnalyzer uses) and StempelFilter (analysis-stempel, Polish) stem what they are given and do not lower-case it, so both class javadocs tell you to "use LowerCaseFilter or LowerCaseTokenizer farther down the Tokenizer chain". PorterStemFilter's javadoc then shows a 7-line MyAnalyzer whose tokenizer is new LowerCaseTokenizer(version, reader). LUCENE-8498 removed LowerCaseTokenizer in 8.0.0 (MIGRATE: "use a LetterTokenizer followed by a LowerCaseFilter") and missed these two files, so the advice names a class that Lucene has not shipped since, and the example fails with cannot find symbol: class LowerCaseTokenizer on every release from 8.0.0 to 10.6.0 and on main. Its (Version, Reader) constructor call had already stopped compiling in 5.0.0. With LetterTokenizer and LowerCaseFilter the example compiles and stems "Running Dogs" to [run, dog]. Documentation only: no code is wrong and nothing wrong ever runs.
PorterStemFilter.java:26-42:
 * Transforms the token stream as per the Porter stemming algorithm. Note: the input to the stemming
 * filter must already be in lower case, so you will need to use LowerCaseFilter or
 * LowerCaseTokenizer farther down the Tokenizer chain in order for this to work properly!   // :28
 *
 * <p>To use this filter with other analyzers, you'll want to write an Analyzer class that sets up
 * the TokenStream chain as you want it. To use this with LowerCaseTokenizer, for example, you'd  // :31
 * write an analyzer like this: <br>
 *
 * <pre><code class="language-java">
 * class MyAnalyzer extends Analyzer {
 *   {@literal @Override}
 *   protected TokenStreamComponents createComponents(String fieldName) {
 *     Tokenizer source = new LowerCaseTokenizer(version, reader);                             // :38
 *     return new TokenStreamComponents(source, new PorterStemFilter(source));
 *   }
 * }
* </code></pre>StempelFilter.java:29-31: "Note: the input to the stemming filter must already be in lower case, so you will need to use LowerCaseFilter or LowerCaseTokenizer farther down the Tokenizer chain in order for this to work properly!"
- These four lines (
PorterStemFilter.java:28,:31,:38,StempelFilter.java:30) are the only mentions ofLowerCaseTokenizerin any.javafile underlucene/(git grep). MIGRATE.md:1496-1500: "LowerCaseTokenizer and LowerCaseTokenizerFactory have been removed ... Instead, use aLetterTokenizerfollowed by aLowerCaseFilter."CHANGES.txt:6692lists LUCENE-8498 in the "Lucene 8.0.0" section (:6611). (MIGRATE.md has no 7.x-to-8.0 heading, so the entry sits under "Migration from Lucene 8.x to Lucene 9.0".)- The replacement is public:
LetterTokenizer()(LetterTokenizer.java:34),LowerCaseFilter(TokenStream)in core,PorterStemFilter(TokenStream)(PorterStemFilter.java:56). - Nothing in the build checks it: code inside javadoc
<pre>blocks is not compiled.
- 2001 / 2010: the "LowerCaseFilter or LowerCaseTokenizer" sentence enters
PorterStemFilter(initial import) andStempelFilter(LUCENE-2298). Valid. - 2012-09-12:
647b5091697("code snippet improvements: fix out of date api usage ...") writes the example withnew LowerCaseTokenizer(version, reader). Valid; 4.10.4 compiles it. - 2014: LUCENE-5388 (
ab0e85fafed; branch_5x backport55594bad9b0) removesReaderfrom tokenizer constructors and edits this snippet'screateComponentsline, but not its tokenizer line. From 5.0.0 the example does not compile; the class the prose names still exists (deprecated from 7.6.0). - 2018: LUCENE-8498 (
c0d2975970d) deletesLowerCaseTokenizerand updates SimpleAnalyzer, StopAnalyzer, CharTokenizer, MIGRATE and CHANGES, but neither of these files. From 8.0.0 the advice names a missing class. - 2020-2026: later edits keep the stale text. LUCENE-9570 reformats both javadocs (
8ef6a0da568,7f8b7ffbcad), #15573 changes the example's markup, and #16063 removes afinalmodifier fromincrementToken(), outside the javadoc.
Exposure and likelihood128 words
- Who. Readers of the class javadoc of
PorterStemFilter(the classic English stemmer in analysis-common, used byEnglishAnalyzer) orStempelFilter(the Polish stemmer in analysis-stempel, used byPolishAnalyzer). The example is read as usage advice: a 2012 dev@ thread, "tokenizer in porterStemmer", quotes it (while it was still valid). - What they get. Advice naming a Lucene class absent from 61 releases (8.0.0-10.6.0) and main, and an example that does not compile on any release since 5.0.0 (compiled on 5.0.0, 7.7.3, 8.0.0, 9.12.3, 10.5.2, 10.6.0 and main; the same snippet on the others).
- What they do not get. Any runtime effect: both filters behave as their lower-case precondition says, and the compile error is loud.
- Priority. Low; likelihood "plausible" (anyone who copies the example hits it, every time).
One JUnit class, one test, no randomness. It asks PorterStemFilter's class loader for org.apache.lucene.analysis.core.LowerCaseTokenizer, the class the javadoc recommends, at its 4.0-7.x package. Put it in analysis-common's tests and run it with gradle.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.en;

import org.apache.lucene.tests.util.LuceneTestCase;

public class TestPorterStemFilterJavadocTokenizer extends LuceneTestCase {

  public void testRecommendedLowerCaseTokenizerExists() {
    // javadoc: "use LowerCaseFilter or LowerCaseTokenizer"; actual: LowerCaseTokenizer removed in 8.0
    try {
      Class.forName(
          "org.apache.lucene.analysis.core.LowerCaseTokenizer",
          false,
          PorterStemFilter.class.getClassLoader());
    } catch (ClassNotFoundException e) {
      throw new AssertionError("expected the LowerCaseTokenizer the javadoc recommends, but: " + e, e);
    }
  }
}
./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.en.TestPorterStemFilterJavadocTokenizer -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
LowerCaseTokenizer, which the javadoc recommends and its example constructs, exists.- Observed
ClassNotFoundException: org.apache.lucene.analysis.core.LowerCaseTokenizer, with assertions on and off; the copied example fails withcannot find symbol: class LowerCaseTokenizer.
More files, environment, full output290 words
Public API only, single thread. The class check is the smallest form of the defect: compiling the example's lines verbatim inside a wrapper class that supplies the imports and declares version and reader leaves exactly one error, the missing class, on main, 10.6.0, 10.5.2, 9.12.3 and 8.0.0, and a scan of the 38 jars built from main and of the cached 10.5.2 release jars finds no entry of that name.
The same file fails unchanged against the 10.6.0 and 10.5.2 release jars. Pass -Ptests.asserts explicitly: without it the build picks the mode from the seed (on for about 75% of seeds, TestsAndRandomizationPlugin.java:240-248), and for DEADBEEF in analysis-common it is off; the bare command fails the same way.
Regression test: none suggested. The fix stops naming the class rather than bringing it back, so this test keeps failing after the fix (checked), and Lucene does not compile javadoc code.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); 10.6.0 and 10.5.2 fail the same way |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 (the result does not depend on the platform) |
cp $REPRO/TestPorterStemFilterJavadocTokenizer.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/en/
cd $LUCENE
./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.en.TestPorterStemFilterJavadocTokenizer -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false instead (same failure)
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (-Ptests.asserts=false: the same failure)
TestPorterStemFilterJavadocTokenizer > testRecommendedLowerCaseTokenizerExists FAILED
    java.lang.AssertionError: expected the LowerCaseTokenizer the javadoc recommends, but: java.lang.ClassNotFoundException: org.apache.lucene.analysis.core.LowerCaseTokenizer
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:ED6645F24C759196]:0)
        at org.apache.lucene.analysis.en.TestPorterStemFilterJavadocTokenizer.testRecommendedLowerCaseTokenizerExists(TestPorterStemFilterJavadocTokenizer.java:31)

        Caused by:
        java.lang.ClassNotFoundException: org.apache.lucene.analysis.core.LowerCaseTokenizer
            at java.base/jdk.internal.loader.BuiltinClassLoader.loadClass(BuiltinClassLoader.java:580)
            ...
1 test completed, 1 failed

# the example's lines compiled verbatim in a wrapper class with imports, version and reader declared (main 645d4fe14a20):
example does not compile: [example-line-4: cannot find symbol   symbol:   class LowerCaseTokenizer   location: class Outer.MyAnalyzer]
PorterStemFilter prose names LowerCaseTokenizer, which is not in these jars
StempelFilter prose names LowerCaseTokenizer, which is not in these jarsLowerCaseTokenizeris a real class that 8.0.0 removed on purpose, with a documented replacement, yet the two javadocs name it as current advice in four places.- The removal commit updated SimpleAnalyzer, StopAnalyzer, CharTokenizer, MIGRATE and CHANGES, but not these two files.
- Upstream maintains these examples:
647b5091697(2012) rewrote this snippet and LUCENE-5388 (2014) updated its signature; #12693 fixedAnalyzer's.
The full argument126 words
- Removed on purpose, with a replacement. MIGRATE.md:
LowerCaseTokenizer"combined tokenization and filtering in a way that broke token normalization, so they have been removed. Instead, use aLetterTokenizerfollowed by aLowerCaseFilter." It was deprecated in 7.6.0 (99df2bd2f35) and deleted in 8.0.0 (c0d2975970d). - Missed by the removal.
c0d2975970dchanged 32 files;PorterStemFilter.javaandStempelFilter.javaare not among them, and the 10 comments of #9544 never mention them. Both files are byte-identical in 7.7.3 and 8.0.0. - Meant to track the API. A 2012 commit titled "code snippet improvements: fix out of date api usage" (
647b5091697) rewrote this snippet, and LUCENE-5388 (2014) later updated itscreateComponentssignature but left the tokenizer line; #12693 (2023) fixed theAnalyzerclass example, closing #12666.
The devil's-advocate check184 words
The case for "intended": Lucene javadoc snippets are illustrative. This one is a fragment (no imports, no enclosing class) and never declared version or reader, Analyzer.java's javadoc uses fictional FooTokenizer placeholders, the build does not compile <pre> blocks, MIGRATE and CHANGES already document the replacement, and later commits edited the class without changing the advice: LUCENE-9570 reformatted both javadoc blocks (2020-2021), #15573 changed the example's markup, and #16063 removed a final modifier from incrementToken(), outside the javadoc.
Why it fails: missing imports and an undeclared variable are gaps a reader fills in; a class that was deliberately deleted is not, and nothing a reader adds makes new LowerCaseTokenizer(...) compile. The prose names it as the way to meet the filter's precondition. MIGRATE confirms the text is stale rather than excusing it, and the later edits were mechanical sweeps (LUCENE-9570 "code reformatting", #15573 "Replace prettyprint with code tag for prism", #16063 "Remove redundant final modifiers"). Every verifier, the executing cross-model reviewer and the adjudication rejected the argument; what remains true is that the impact is small, which is why it is Low.
Recommended Name only LowerCaseFilter; build the example from LetterTokenizer + LowerCaseFilter (validated)
Javadoc only: in both files say "use LowerCaseFilter" instead of "LowerCaseFilter or LowerCaseTokenizer", and write the example as new LetterTokenizer() + new PorterStemFilter(new LowerCaseFilter(source)). Validated with gradle: the new example compiles and stems "Running Dogs" to [run, dog], the en tests and the stempel module pass, and both modules' javadoc renders.
- * filter must already be in lower case, so you will need to use LowerCaseFilter or
- * LowerCaseTokenizer farther down the Tokenizer chain in order for this to work properly!
+ * filter must already be in lower case, so you will need to use LowerCaseFilter farther down the
+ * Tokenizer chain in order for this to work properly!
- * the TokenStream chain as you want it. To use this with LowerCaseTokenizer, for example, you'd
- * write an analyzer like this: <br>
+ * the TokenStream chain as you want it. To use this with LowerCaseFilter, for example, you'd write
+ * an analyzer like this: <br>
- *     Tokenizer source = new LowerCaseTokenizer(version, reader);
- *     return new TokenStreamComponents(source, new PorterStemFilter(source));
+ *     Tokenizer source = new LetterTokenizer();
+ *     return new TokenStreamComponents(source, new PorterStemFilter(new LowerCaseFilter(source)));
  (StempelFilter.java: "LowerCaseFilter or LowerCaseTokenizer" -> "LowerCaseFilter")
All options and trade-offs4 options · 538 words
One fix was validated with gradle in a scratch worktree of 645d4fe14a20; the alternatives were not run.
Name only LowerCaseFilter; build the example from LetterTokenizer + LowerCaseFilter (validated) (recommended)
Exactly the replacement MIGRATE.md prescribes for LowerCaseTokenizer, so the example keeps its meaning (split on letters, lower-case, stem) and no longer needs the undeclared version or reader. 2 files, +7/-8, comments only.
- * filter must already be in lower case, so you will need to use LowerCaseFilter or
- * LowerCaseTokenizer farther down the Tokenizer chain in order for this to work properly!
+ * filter must already be in lower case, so you will need to use LowerCaseFilter farther down the
+ * Tokenizer chain in order for this to work properly!
- * the TokenStream chain as you want it. To use this with LowerCaseTokenizer, for example, you'd
- * write an analyzer like this: <br>
+ * the TokenStream chain as you want it. To use this with LowerCaseFilter, for example, you'd write
+ * an analyzer like this: <br>
- *     Tokenizer source = new LowerCaseTokenizer(version, reader);
- *     return new TokenStreamComponents(source, new PorterStemFilter(source));
+ *     Tokenizer source = new LetterTokenizer();
+ *     return new TokenStreamComponents(source, new PorterStemFilter(new LowerCaseFilter(source)));
  (StempelFilter.java: "LowerCaseFilter or LowerCaseTokenizer" -> "LowerCaseFilter")
Trade-offs
- No behaviour, API or test change; trivially reviewable.
- Keeps the old "farther down the Tokenizer chain" wording; the chain must be tokenizer ->
LowerCaseFilter-> stemmer, so a reword such as "apply LowerCaseFilter before this filter" is optional. LetterTokenizerandLowerCaseFilterare plain text in the<pre>block, not{@link}s, like the names they replace;renderJavadocaccepts them, and the control test checks the example with its own imports.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle--offline, OpenJDK 25.0.3, seed DEADBEEF. - Stock: the one-test repro fails with assertions on and off.
- With the diff:
git grep LowerCaseTokenizer -- 'lucene/**/*.java'finds nothing; a script confirmed the patched example equals, line for line, theMyAnalyzerof a control test that asserts "Running Dogs" -> [run, dog]. :lucene:analysis:common:test --tests 'org.apache.lucene.analysis.en.*'with the control: 22 tests, 0 failures, 1 skipped (TestKStemmer.testCreateMap,@Ignored sample code), includingTestPorterStemFilter(4) andTestPorterStemFilterFactory(2);:lucene:analysis:stempel:test, the whole module: 19 tests, 0 failures.renderJavadoc,checkGoogleJavaFormatandecjLintMainof both modules pass; the renderedPorterStemFilter.htmlno longer mentionsLowerCaseTokenizer.- The one-test repro still fails after the fix, as expected: only comments change.
- Not run: the whole analysis-common test task or
./gradlew check.
EnglishAnalyzer and PolishAnalyzer build StandardTokenizer -> ... -> LowerCaseFilter -> ... -> the stemmer.
Trade-offs
Closer to today's practice, but it changes the example's tokenizer (Unicode word breaks instead of letters), which the old text never meant.
Keep only the corrected prose.
Trade-offs
Smallest text, but loses the one hand-written chain in the class docs; PorterStemFilterFactory's javadoc already shows a factory-based chain.
For example {@snippet} with compiled sources.
Trade-offs
One systematic way to stop this kind of drift (a resolvable {@link}, an API-name lint or a focused documentation test could also catch a removed class), but a build-tooling change far beyond a three-line fix.
No formal method. A pass compiled the code examples in Lucene's javadocs against the current jars; this one failed with cannot find symbol: class LowerCaseTokenizer, and a grep for the class found the same advice in StempelFilter. Verifiers, reviewers from another model family (OpenAI GPT-5.6) and an adjudication confirmed it.
The method in full87 words
- Hunt. The finder extracted the class-javadoc example verbatim from the source and compiled it with
javax.toolsagainst the stock main jars: errors forLowerCaseTokenizerand the two undeclared namesversionandreader. Declaring those two leaves the class as the only error. An API-presence scan over release tags dated the removal, and a grep over the non-sandbox sources found theStempelFiltersentence. - Minimized to the one-test class check of the repro section.
- Tier. Non-formal: compiling documentation code and scanning jars, not a check against exact semantics.
No matching public report in the recorded searches: GitHub issues, PRs and commits (with the migrated JIRA archive), the dev@, java-user@ and issues@ lists, downstream repositories, Stack Overflow and the web (2026-10-29 and 2026-11-01; GitHub rechecked 2026-11-01). The closest active work, open outside PR #16949 (stale javadoc in 20 other .java files), touches neither file.
Searches6 searches
Closest hits, none this bug: #9544 (LUCENE-8498, the removal; its body and 10 comments discuss CharTokenizer normalization only); #16949 (open, by others, 2026-10-29: the same bug class in 20 other .java files, 8 of them in analysis packages, plus 7 regenerated build files); #6451 (LUCENE-5388, made the constructor call stale); #15573 (the example's markup) and #16063 (a final modifier on incrementToken()); #9241, #8756 and #2878 (earlier LowerCaseTokenizer items); #16904, #16936 and #15225 (the same bug class in other files, and a docs meta issue); a 2012 dev@ thread that quotes the example while it was valid; the open items that mention these class names (#4309, #10052, #8489, #10020, 2011-2019) are about other topics.
| Where | When | How | Found |
|---|---|---|---|
| Scripted searches | 2026-10-29 and 2026-11-01 | about 190 queries (study) and 107 queries (two runs, 2026-11-01; 159 that day with the manual queries below) over GitHub issues, PRs and commits, Elasticsearch, OpenSearch and Solr, dev@, java-user@, issues@ and commits@, the JIRA archive and the web | the only high hits are #9544 (the removal) and #8756 (maxTokenLen); neither is a report |
| GitHub, manual | 2026-11-01 | 42 phrasings: the class names, the javadoc sentences, the constructor call, MyAnalyzer, recent javadoc-fix authors, the Solr, Lucene.NET, Elasticsearch and OpenSearch repositories, all of GitHub; issues and PRs created since 2026-10-28 | no report |
| Open PRs | 2026-11-01 | changed files of all 410 open apache/lucene PRs (REST pagination for the 3 with more than 100 files); the files of #16949 (27: 20 .java, 7 regenerated build files) | none touches PorterStemFilter.java or StempelFilter.java |
| GitHub recheck | 2026-11-01 | the files of #16949; the search API for PorterStemFilter, StempelFilter, LowerCaseTokenizer and MyAnalyzer (created since 2026-10-28, and open items); the changed files of all 409 open PRs, with REST pagination for the 3 with more than 100 files | nothing new: no item created since 2026-10-28; the open items that mention the names (#4309, #10052, #8489, #10020) are about other topics; no open PR touches either file; #16949 is open and touches neither |
| Mailing lists, JIRA, Stack Overflow, web | 2026-11-01 | lists.apache.org per class name, 4 JQL queries, 3 Stack Overflow searches, 11 web searches | a 2012 dev@ thread quoting the example while valid; nothing about these javadocs |
| Upstream main | 2026-11-01 | git show of f815e679bf6c; branch_11x and branch_10_6 read | all four mentions unchanged |
Advice stale since 8.0.0: LUCENE-8498 (c0d2975970d, 2018) removed the class. The example has not compiled since 5.0.0, when LUCENE-5388 removed its (Version, Reader) constructor. 4.10.4 compiles it; every release from 5.0.0 to 10.6.0 and main fail.
Versions tested6 rows
- Introduced by
c0d2975970d"LUCENE-8498: Remove LowerCaseTokenizer" (Alan Woodward, authored 2018-09-15, committed 2018-09-20; a JIRA patch, migrated as #9544). It is an ancestor of the 8.0.0 tag and not of 7.7.3, so 8.0.0 is the first release whose advice names a missing class: the Lucene classorg.apache.lucene.analysis.core.LowerCaseTokenizer(Solr's separateorg.apache.solr.analysis.LowerCaseTokenizeris in the 8.0.0 to 8.8.1 tags, in solr-core). - Earlier layer:
ab0e85fafed"LUCENE-5388: remove Reader from Tokenizer ctor" (Robert Muir, 2014-01-09; in 5.0.0 through the branch_5x backport55594bad9b0) edited the snippet'screateComponentsline and removedLowerCaseTokenizer(Version, Reader)in the same diff, but left the tokenizer line. - Totals: headline 8.0.0-10.6.0 (61 releases) and main; example only 5.0.0-7.7.3 (47 releases); not affected 4.0.0-4.10.4 (23 releases). A scan of all 124 release tags of the history clone shows the same text on each.
- Not fixed upstream: upstream main
f815e679bf6c(2026-11-01), branch_11x and branch_10_6 still carry all four mentions.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; upstream main f815e679bf6c | affected | repro fails with -ea and -da (standalone and gradle); the verbatim example fails with cannot find symbol; upstream read: same text |
| 10.6.0, 10.5.2 | affected | repro fails with -ea and -da (release jars); 10.6.0's own example fails to compile |
| 9.12.3 | affected | the finder's and the independent reproduction's tests fail (cannot find symbol) |
| 8.0.0, 8.8.2-8.11.4 | affected | class absent (ClassNotFoundException); 8.0.0's own example fails to compile |
| 5.0.0, 7.7.3 | example only | the example fails to compile (no (Version, Reader) constructor); the class the prose names still exists (deprecated from 7.6.0) |
| 4.10.4 | not affected | the example compiles (its lines verbatim, in a wrapper class with imports, version and reader declared) |
Every valid check agrees it is real and documentation-only: the finder, verifiers (one from another model family, OpenAI GPT-5.6), an executing cross-model refute review, the adjudication and a credibility audit. An earlier refute review that could only read was not valid. The brief re-ran the repro with gradle and validated the fix; the doc's fact checks agree.
Checks and verdicts302 words
Each check ran separately. Earlier cross-model reviews could only read; an executing one ran on 2026-11-01.
| Check | Verdict | What it found |
|---|---|---|
| Finder | reproduced (doc) | The verbatim example fails on main (-ea, -da), 10.5.2 and 9.12.3; controls pass. |
| Independent reproducer | real | Own test: the example's only error is the missing class on main (-ea, -da), 10.5.2, 9.12.3; the MIGRATE replacement compiles and gives [run, dog]. |
| Intended lens (OpenAI GPT-5.6) | real, medium (reading only) | The "pseudo-code" defence fails for a real class removed with a documented replacement. |
| Devil's advocate | real, high (doc) | Argued "illustrative snippet" and rejected it; corrected the removal release to 8.0.0. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test (fails, controls pass); impact minor. |
| Refute lens, executing (OpenAI GPT-5.6) | real, high | Own javax.tools test fails with cannot find symbol (-ea, -da); its LetterTokenizer + LowerCaseFilter control compiles; a separate run re-ran it on 645d4fe14a20 (fails). |
| Credibility audit and re-verification | real | The one-test repro fails on main 645d4fe14a20 (-ea, -da) and 10.5.2; the fix's control passes. |
| Doc fact check (independent, executing) | real; 6 wording errors, fixed | Re-ran the repro on main (-ea, -da), 10.6.0 and 9.12.3, the documented gradle command three ways and the fix. Found the command's assertions mode, one history detail, two counts, a test-scope phrase and a 'last fixed' phrase wrong; all fixed. |
| Doc fact check, cross-model (OpenAI GPT-5.6) | real; errors and overclaims, fixed (one item rejected) | Found the same history detail, the missing imports behind 'compiled verbatim', the unqualified class name and several overclaims; fixed, except a lint remark that mixed up the EditorConfig lint and the ECJ lint. |
| Diagram check | pass | Every value, line and release in the PNG matches the code and the runs; the javac output was re-run independently. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 457 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,194 words
- Registry title
- PorterStemFilter's and StempelFilter's class javadocs still tell readers to use LowerCaseTokenizer, which was removed in 8.0.0 (LUCENE-8498), and PorterStemFilter's MyAnalyzer example calls new LowerCaseTokenizer(version, reader), a constructor form gone since 5.0.0, so the example does not compile; the documented replacement is LetterTokenizer followed by LowerCaseFilter (documentation defect)
- Area
- analysis / stemming filters (PorterStemFilter and StempelFilter class javadoc)
- Priority
- Low, rank 1246: The PorterStemFilter and StempelFilter class javadocs recommend the removed LowerCaseTokenizer in an example that fails to compile with no runtime effect, and PorterStemFilter is widely read.
- Impact class
- minor
- Impact note
- Documentation only, with no runtime effect: a developer who follows the class javadoc of PorterStemFilter (the mainstream English stemmer in analysis-common) or of StempelFilter (analysis-stempel) is told to use a class that has not existed since 8.0.0, and copying the MyAnalyzer example gives a compile error on every release from 5.0.0 to 10.6.0 and on main; the other option the prose names, LowerCaseFilter, is valid, and no configuration, scale or special input is involved.
- Summary
- PorterStemFilter's javadoc says its input must already be lower case, tells you to use LowerCaseFilter or LowerCaseTokenizer, and shows a MyAnalyzer built on new LowerCaseTokenizer(version, reader); StempelFilter's javadoc gives the same advice. LowerCaseTokenizer was removed in Lucene 8.0.0 (the migration notes say to use LetterTokenizer followed by LowerCaseFilter) and its (Version, Reader) constructor was already gone in 5.0.0, so the example does not compile and the advice names a class that no longer exists. Written with LetterTokenizer and LowerCaseFilter, the example compiles and stems 'Running Dogs' to [run, dog], so only the documentation is wrong.
- Introduced
- c0d2975970d (LUCENE-8498 'Remove LowerCaseTokenizer', migrated as #9544, by Alan Woodward (romseygeek), author date 2018-09-15, committed 2018-09-20, a JIRA patch, not a GitHub PR; first in 8.0.0) for the headline: it deleted LowerCaseTokenizer and LowerCaseTokenizerFactory and updated SimpleAnalyzer, StopAnalyzer, CharTokenizer, MIGRATE and CHANGES, but not these two class javadocs. The example's tokenizer line was stale earlier: ab0e85fafed (LUCENE-5388 'remove Reader from Tokenizer ctor', migrated as #6451, by Robert Muir (rmuir), author date 2014-01-09; it reached 5.0.0 through the branch_5x backport 55594bad9b0, 2014-09-18) changed this snippet's createComponents signature in the same diff that removed the LowerCaseTokenizer(Version, Reader) constructor, and left the tokenizer line. The prose dates from the initial import (bd3948c539e, 2001) and LUCENE-2298 (98c47c57e0a, 2010), the example from 647b5091697 (2012-09-12), all valid when written [read: git log and git show in the full-history clone; exec: release sweep, see affected_versions] (2018-09-15 (c0d2975970d author date; committed 2018-09-20) for the headline; 2014-01-09 (ab0e85fafed, trunk) and 2014-09-18 (backport 55594bad9b0, branch_5x) for the example's constructor call)
- First affected version
- 8.0.0 [exec] for the headline (LowerCaseTokenizer absent, while the prose of both files names it); 5.0.0 [exec] for the example alone (no (Version, Reader) constructor; the prose was still accurate then, and the class was deprecated from 7.6.0)
- Affected versions
- Headline (stale advice and example): every release from 8.0.0 to 10.6.0 (61 releases; 10.6.0 [exec 2026-11-01]: its own example fails to compile and the minimal repro fails with -ea and -da) and main a9779ef3c193; example only (it does not compile, the advice is still accurate): 5.0.0 to 7.7.3 (47 releases). Not affected: 4.0.0 to 4.10.4 (executed on 4.10.4: the example compiles); 3.6.2 and earlier use another layout (read only). Not fixed upstream: main 645d4fe14a20, branch_11x, branch_10x and branch_10_6 still carry the text (read 2026-10-29). [exec: the finder's JUnit fails on main (-ea and -da), 10.5.2, 9.12.3 and 9.1.0; the independent reproduction's JUnit fails on main (-ea and -da), 10.5.2 and 9.12.3; the per-release history check, which compiles each release's own javadoc text against that release's jars, passes on 4.10.4 and fails on 5.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and main, its control passing on all of them] [read: every other release from a scan of all release tags; 8.8.2 to 8.11.3 from their release jars]. Caveat: all runs used JDK 25 on Linux aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-29; recheck 2026-10-29): three scripted search runs (51 + 51 + 46 queries over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@ and issues@ lists, the JIRA archive and the web; the only high hit is #9544, the removal itself), 38 manual GitHub search phrasings (the class names, the example's constructor call, the prose sentences, MyAnalyzer, the recent javadoc-fix authors, and the Solr, Elasticsearch, OpenSearch and Lucene.NET repositories), the changed files of all 414 open apache/lucene PRs (only #16911 'Decommission branch 10x', which deletes the whole branch_10x tree, lists PorterStemFilter.java), the 200 most recently merged and 100 most recently closed PRs, lists.apache.org and 12 web searches. Read but not the same bug: #9544 and its commit c0d2975970d (LUCENE-8498, the removal that left both javadocs stale; none of its 10 comments mentions them), #9241 (LUCENE-8193, an earlier removal proposal), #6451 (LUCENE-5388, made the constructor call stale), #12693 and 647b5091697 (precedents for fixing stale examples), #16904 (collation package-info) and #16821 / #16936 (highlight package-info), the same bug class in other files, #15225 (docs meta issue, names no class), and the 2012 dev@ thread 'tokenizer in porterStemmer' (it quotes the example while it was still valid). Recheck: the 35 issues and PRs updated since 2026-10-28 name none of the classes and none of their 27 PRs touches either file; searches for PorterStemFilter and StempelFilter created since 2026-10-01 return 0; main 645d4fe14a20, branch_11x, branch_10x and branch_10_6 still carry the text. Tracking issue #16937 does not name it.
- Lucene commit tested
- main
645d4fe14a20(2026-11-01): the one-test repro fails with assertions on and off (standalone, and gradle with the file in analysis-common's tests); it fails against the 10.6.0 and 10.5.2 release jars; the version-history runs compiled each release's own example on 4.10.4 (compiles), 5.0.0, 7.7.3, 8.0.0, 10.6.0 and main (fail); the fix was validated with gradle in a scratch worktree of645d4fe14a20. Upstream mainf815e679bf6c(2026-11-01) was read, not run: all four mentions are unchanged.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/en/PorterStemFilter.java:26-42 (:27-28 'LowerCaseFilter or LowerCaseTokenizer', :31 'To use this with LowerCaseTokenizer', :38 'new LowerCaseTokenizer(version, reader)') and lucene/analysis/stempel/src/java/org/apache/lucene/analysis/stempel/StempelFilter.java:29-31 (LowerCaseTokenizer on :30); no LowerCaseTokenizer class anywhere under lucene/ on main
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/en/PorterStemFilter.java:26-42, :56lucene/analysis/stempel/src/java/org/apache/lucene/analysis/stempel/StempelFilter.java:29-31lucene/MIGRATE.md:1154, :1496-1500lucene/CHANGES.txt:6611, :6692-6693lucene/analysis/common/src/java/org/apache/lucene/analysis/core/LetterTokenizer.java:34lucene/core/src/java/org/apache/lucene/analysis/LowerCaseFilter.java:31
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/en/EnglishAnalyzer.java:102-110lucene/analysis/stempel/src/java/org/apache/lucene/analysis/pl/PolishAnalyzer.java:135-142
- Minimal repro
build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:240-248 (default tests.asserts from the project seed)
- Why it looks unintended
lucene/MIGRATE.md:1496-1500
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/en/EnglishAnalyzer.java:102-110lucene/analysis/stempel/src/java/org/apache/lucene/analysis/pl/PolishAnalyzer.java:135-142lucene/analysis/common/src/java/org/apache/lucene/analysis/en/PorterStemFilterFactory.java:23-33
- History
a Lucene clone: tag dates releases/lucene-solr/5.0.0, 8.0.0, releases/lucene/10.6.0
- TestPorterStemFilterJavadocTokenizer.java (one test, analysis-common tests):
repro/LFV-987/src/org/apache/lucene/analysis/en/TestPorterStemFilterJavadocTokenizer.java(34 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-987/bug.png(457 KB)