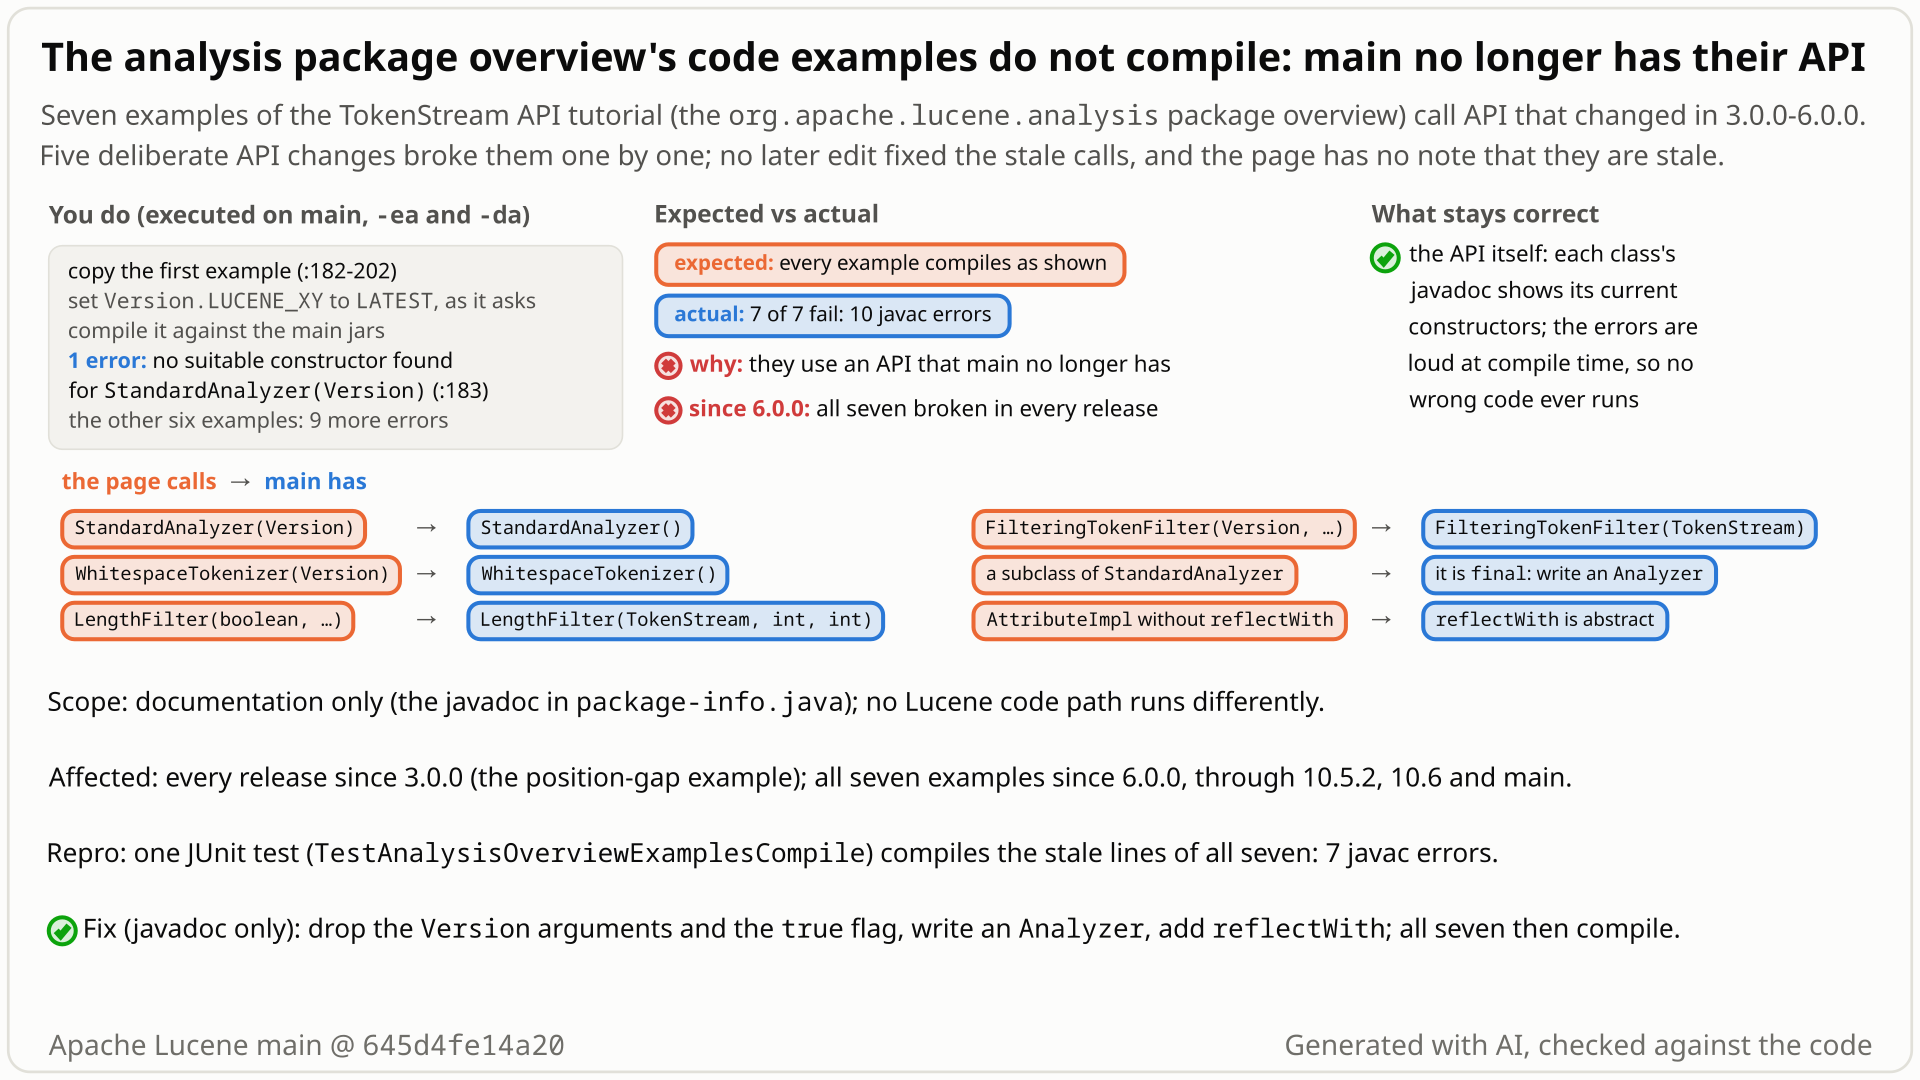
Lucene's core analysis package overview teaches the TokenStream API with code you are meant to copy. Most of it dates from Lucene 3 and 4; later API changes broke seven examples, and no edit since has fixed the stale calls.
- An
Analyzerturns text into tokens: aTokenizersplits the text (WhitespaceTokenizersplits at spaces) andTokenFilters change or drop tokens (LengthFilter(source, 3, Integer.MAX_VALUE)drops tokens shorter than 3 characters). Each token carries attributes, such as its text, implemented byAttributeImplclasses. - Until 4.x most of these constructors took a
Versionargument. Lucene 5.0 removed it (LUCENE-5859), and since 6.0 everyAttributeImplmust implementreflectWith(LUCENE-6651).
- You open the
org.apache.lucene.analysispackage overview, whereTokenStream's javadoc sends you for example code, and copy its "Adding a LengthFilter" step:new WhitespaceTokenizer(matchVersion)andnew LengthFilter(true, source, 3, Integer.MAX_VALUE). - You expect it to compile and print what the page shows: the input "This is a demo of the TokenStream API" without the words of 2 or fewer characters.
- Instead javac rejects both lines:
WhitespaceTokenizerlost itsVersionconstructor in 5.0, andLengthFilter's only constructor is now(TokenStream, int, int); the page's(true, source, ...)form went in 4.4. - All seven examples fail to compile: besides these two calls,
StandardAnalyzer(Version)is gone,StandardAnalyzeris final, the LengthFilter listing calls the removedsuper(version, in), and the custom attribute does not implementreflectWith. Every release since 6.0.0 ships all seven broken. - Rewritten against today's API (no
Versionargument, a smallAnalyzerinstead of aStandardAnalyzersubclass,reflectWith, afinaltagging filter), all seven compile, and the tutorial prints its outputs, such asThis demo the TokenStream API.
Everyone who learns to write an Analyzer, TokenFilter or Attribute from this page and copies an example: javac rejects it, with no setting involved. A 2016 Stack Overflow question shows a user hitting example 1. The errors are loud and at compile time, and no Lucene code behaves differently; the cost is developer time.
Mechanism, terms and numbers505 words
The org.apache.lucene.analysis package overview (core package-info.java) is Lucene's tutorial for writing analyzers, token filters and attributes, and TokenStream's javadoc points readers to it for example code. Seven of its examples do not compile on main or on any release since 6.0.0: they call StandardAnalyzer(Version), WhitespaceTokenizer(Version) and FilteringTokenFilter(Version, TokenStream), removed in 5.0, and new LengthFilter(true, source, 3, Integer.MAX_VALUE), a signature gone since 4.4; one subclasses StandardAnalyzer, which is final; and the custom PartOfSpeechAttributeImpl lacks reflectWith(AttributeReflector), abstract since 6.0. The APIs changed on purpose, and no edit of the page since has fixed the stale calls. Written against the current API (no Version argument, new LengthFilter(source, 3, Integer.MAX_VALUE), a small Analyzer instead of a StandardAnalyzer subclass, a reflectWith method, and a final tagging filter so the tutorial also runs with assertions on), every example compiles and the tutorial prints the page's outputs.
| # | example | stale code | javac says | broken since |
|---|---|---|---|---|
| 1 | Invoking the Analyzer, :181-203 | new StandardAnalyzer(matchVersion) (:183) | no suitable constructor found for StandardAnalyzer(Version) | 5.0.0 |
| 2 | position gap, :265-272 | new StandardAnalyzer(matchVersion) { getPositionIncrementGap ... } (:267) | the same, and cannot inherit from final StandardAnalyzer | 3.0.0 |
| 3 | whitespace tokenization, :606-645 | new WhitespaceTokenizer(matchVersion) (:617) | no suitable constructor found for WhitespaceTokenizer(Version) | 5.0.0 |
| 4 | adding a LengthFilter, :669-676 | :672 as #3; new LengthFilter(true, source, 3, Integer.MAX_VALUE) (:673) | constructor LengthFilter cannot be applied to given types (required: TokenStream,int,int) | 4.4.0 |
| 5 | how LengthFilter is implemented, :691-721 | super(version, in) (:709) | constructor FilteringTokenFilter cannot be applied to given types (required: TokenStream) | 5.0.0 |
| 6 | a custom attribute, :808-832 | PartOfSpeechAttributeImpl with only clear() and copyTo() (:809) | is not abstract and does not override abstract method reflectWith(AttributeReflector) | 6.0.0 |
| 7 | the final chain, :873-881 | the two lines of #4 (:876-877) | as #4 | 4.4.0 |
Errors that come only from the page's placeholders (Version.LUCENE_XY, which the page asks you to substitute, and names it leaves undeclared) are not counted.
StandardAnalyzer.java:34:public final class StandardAnalyzer, constructors(CharArraySet):46,():51,(Reader):61.WhitespaceTokenizer.java:34-66(analysis-common):(),(AttributeFactory),(int),(AttributeFactory, int).LengthFilter.java:44(analysis-common): only(TokenStream in, int min, int max).FilteringTokenFilter.java:38: only(TokenStream in).AttributeImpl.java:34,:93,:99:clear(),reflectWith(AttributeReflector)andcopyTo(AttributeImpl)are abstract.Analyzerhas noVersionAPI left.
MyAnalyzertakes aVersion(:609-613), but the last step callsnew MyAnalyzer()(:903).:834-836says the attribute "implements its abstract methodsclear()andcopyTo()".public static class PartOfSpeechTaggingFilter(:842) is not final.TokenStreamrequires final subclasses or a finalincrementToken(), "checked when Java assertions are enabled" (TokenStream.java:74-76), so even the compile-fixed tutorial throwsAssertionErrorunder-ea.- The four printed outputs list a token
new(:658,:684,:889,:934) that the input text (:622,:901) does not contain.
Exposure and likelihood177 words
- Who. Developers learning the TokenStream API from Lucene's own tutorial, the page
TokenStream's javadoc points to ("You can find some example code for the new API in the analysis package level Javadoc",TokenStream.java:68). - Evidence of use. Stack Overflow question 40052828 (2016-10-14): a 6.2.1 user quoted example 1 and asked why it does not compile; the answer explained that the
Versionargument was removed in 5.0. - Default vs opt-in. No configuration: it is the page as published in the core module's javadoc.
- Scale. Seven of the page's example blocks (the others are fragments, illustrative classes with undefined names, or compile as they are; the last step's
main,:898-925, fails in the assembled tutorial only because it callsnew MyAnalyzer()against the page's ownMyAnalyzer(Version), a knock-on of example 3). All seven are broken in every release from 6.0.0 to 10.6.0 and main; at least one since 3.0.0. - Severity. Documentation only, loud, compile time. Once the compile errors are fixed, the part-of-speech steps also fail under
-eabecause the tagging filter is not final.
One JUnit test, one method: it compiles the page's stale lines, copied from the page (the placeholder LUCENE_XY replaced by LATEST), with the JDK compiler against the core and analysis-common jars, and asserts no errors. Deterministic, single thread, about 1 s.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis;

import java.net.URI;
import java.util.List;
import java.util.Locale;
import javax.tools.Diagnostic;
import javax.tools.DiagnosticCollector;
import javax.tools.JavaFileObject;
import javax.tools.SimpleJavaFileObject;
import javax.tools.ToolProvider;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestAnalysisOverviewExamplesCompile extends LuceneTestCase {

  private static final String EXAMPLES =
      """
      import org.apache.lucene.analysis.Analyzer;
      import org.apache.lucene.analysis.FilteringTokenFilter;
      import org.apache.lucene.analysis.TokenStream;
      import org.apache.lucene.analysis.Tokenizer;
      import org.apache.lucene.analysis.core.WhitespaceTokenizer;
      import org.apache.lucene.analysis.miscellaneous.LengthFilter;
      import org.apache.lucene.analysis.standard.StandardAnalyzer;
      import org.apache.lucene.util.AttributeImpl;
      import org.apache.lucene.util.Version;

      abstract class Examples extends Analyzer {
        Version matchVersion = Version.LATEST;
        Analyzer analyzer = new StandardAnalyzer(matchVersion);
        Analyzer myAnalyzer = new StandardAnalyzer(matchVersion) {
          public int getPositionIncrementGap(String fieldName) {
            return 10;
          }
        };

        @Override
        protected TokenStreamComponents createComponents(String fieldName) {
          final Tokenizer source = new WhitespaceTokenizer(matchVersion);
          TokenStream result = new LengthFilter(true, source, 3, Integer.MAX_VALUE);
          return new TokenStreamComponents(source, result);
        }
      }

      class Listing {
        abstract class LengthFilter extends FilteringTokenFilter {
          public LengthFilter(Version version, TokenStream in, int min, int max) {
            super(version, in);
          }
        }
      }

      final class PartOfSpeechAttributeImpl extends AttributeImpl {
        @Override
        public void clear() {}

        @Override
        public void copyTo(AttributeImpl target) {}
      }
      """;

  public void testExamplesCompile() throws Exception {
    JavaFileObject source =
        new SimpleJavaFileObject(URI.create("string:///Examples.java"), JavaFileObject.Kind.SOURCE) {
          @Override
          public CharSequence getCharContent(boolean ignoreEncodingErrors) {
            return EXAMPLES;
          }
        };
    DiagnosticCollector<JavaFileObject> diagnostics = new DiagnosticCollector<>();
    List<String> options = List.of("-proc:none", "-d", createTempDir().toString());
    ToolProvider.getSystemJavaCompiler()
        .getTask(null, null, diagnostics, options, null, List.of(source))
        .call();
    List<String> errors =
        diagnostics.getDiagnostics().stream()
            .filter(d -> d.getKind() == Diagnostic.Kind.ERROR)
            .map(d -> "line " + d.getLineNumber() + ": " + d.getMessage(Locale.ROOT))
            .toList();
    // lines copied from the analysis package-info.java examples (LUCENE_XY -> LATEST) must compile
    assertEquals(List.of(), errors);
  }
}
# build the jars (any build that produces them, for example ./gradlew assemble)
L=$LUCENE/lucene
CP=$L/core/build/libs/lucene-core-11.0.0-SNAPSHOT.jar:$L/codecs/build/libs/lucene-codecs-11.0.0-SNAPSHOT.jar
CP=$CP:$L/analysis/common/build/libs/lucene-analysis-common-11.0.0-SNAPSHOT.jar
CP=$CP:$L/test-framework/build/libs/lucene-test-framework-11.0.0-SNAPSHOT.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # from the Gradle cache
mkdir -p $REPRO/classes
javac -d $REPRO/classes -cp $CP $REPRO/TestAnalysisOverviewExamplesCompile.java
java -ea -Dtests.seed=DEADBEEF -cp $REPRO/classes:$CP org.junit.runner.JUnitCore org.apache.lucene.analysis.TestAnalysisOverviewExamplesCompile
# assertions off: -da instead of -ea (the same 7 errors)
- Expected
- javac reports no errors: the seven examples compile.
- Observed
- 7 javac errors, among them
no suitable constructor found for StandardAnalyzer(Version),cannot inherit from final StandardAnalyzerandPartOfSpeechAttributeImpl is not abstract and does not override abstract method reflectWith(AttributeReflector); the same with-da.
More files, environment, full output402 words
Source line 13 of the in-memory file is package-info.java:183; 14-18 are :267-271; 22-23 are :672-673 (also :617 and :876-877); 31 is :709; 36-41 are :809-831 reduced to its two overrides. The 7 errors cover the seven examples: two StandardAnalyzer(Version) calls, the final class, WhitespaceTokenizer(Version), LengthFilter(true, ...), super(version, in) and the missing reflectWith.
Why a plain JUnit run and not ./gradlew test: the in-process compiler reads the test JVM's class path, which must hold both lucene-core and lucene-analysis-common. In :lucene:analysis:common Lucene is on the module path, so the compiler sees neither jar; :lucene:core tests lack analysis-common.
The test is not needed to show the defect: one javac error per example does that. As a regression test (optional for a javadoc fix): the same method with EXAMPLES holding the fixed lines passes with assertions on and off; it cannot see the page itself, so it only guards the new lines against a future API change.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the verifiers' tests fail the same way on 10.5.2 and 9.12.3 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# build the jars (any build that produces them, for example ./gradlew assemble)
L=$LUCENE/lucene
CP=$L/core/build/libs/lucene-core-11.0.0-SNAPSHOT.jar:$L/codecs/build/libs/lucene-codecs-11.0.0-SNAPSHOT.jar
CP=$CP:$L/analysis/common/build/libs/lucene-analysis-common-11.0.0-SNAPSHOT.jar
CP=$CP:$L/test-framework/build/libs/lucene-test-framework-11.0.0-SNAPSHOT.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # from the Gradle cache
mkdir -p $REPRO/classes
javac -d $REPRO/classes -cp $CP $REPRO/TestAnalysisOverviewExamplesCompile.java
java -ea -Dtests.seed=DEADBEEF -cp $REPRO/classes:$CP org.junit.runner.JUnitCore org.apache.lucene.analysis.TestAnalysisOverviewExamplesCompile
# assertions off: -da instead of -ea (the same 7 errors)
# plain JUnit run, main 645d4fe14a20, seed DEADBEEF, -ea (the same with -da); abridged: the JUnit version, NOTE,
# WARNING and timing lines and most stack frames omitted, javac's lists of non-applicable candidate constructors
# shortened to [...]
There was 1 failure:
1) testExamplesCompile(org.apache.lucene.analysis.TestAnalysisOverviewExamplesCompile)
java.lang.AssertionError: expected:<[]> but was:<[line 13: no suitable constructor found for StandardAnalyzer(org.apache.lucene.util.Version)
    [...], line 14: no suitable constructor found for StandardAnalyzer(org.apache.lucene.util.Version)
    [...], line 14: cannot inherit from final org.apache.lucene.analysis.standard.StandardAnalyzer, line 22: no suitable constructor found for WhitespaceTokenizer(org.apache.lucene.util.Version)
    [...], line 23: constructor LengthFilter in class org.apache.lucene.analysis.miscellaneous.LengthFilter cannot be applied to given types;
  required: org.apache.lucene.analysis.TokenStream,int,int
  found:    boolean,org.apache.lucene.analysis.Tokenizer,int,int
  reason: actual and formal argument lists differ in length, line 31: constructor FilteringTokenFilter in class org.apache.lucene.analysis.FilteringTokenFilter cannot be applied to given types;
  required: org.apache.lucene.analysis.TokenStream
  found:    org.apache.lucene.util.Version,org.apache.lucene.analysis.TokenStream
  reason: actual and formal argument lists differ in length, line 36: PartOfSpeechAttributeImpl is not abstract and does not override abstract method reflectWith(org.apache.lucene.util.AttributeReflector) in org.apache.lucene.util.AttributeImpl]>
	at __randomizedtesting.SeedInfo.seed([DEADBEEF:456DAE84982F4242]:0)
	at org.junit.Assert.fail(Assert.java:89)
	...
	at org.apache.lucene.analysis.TestAnalysisOverviewExamplesCompile.testExamplesCompile(TestAnalysisOverviewExamplesCompile.java:96)

FAILURES!!!
Tests run: 1, Failures: 1- The page presents runnable code ("In this example we will create a WhiteSpaceTokenizer ...") and prints each step's output; there is no disclaimer.
- Each break is a deliberate API change that left the calls stale: LUCENE-1987/2372 (3.x), LUCENE-4963, LUCENE-5859, LUCENE-6651 (its MIGRATE note requires
reflectWith). - No
Versionvalue makes the removed constructors exist, and nobody can subclass a final class.
The full argument274 words
- The page presents working code. "In this example we will create a WhiteSpaceTokenizer and use a LengthFilter to suppress all words that have only two or fewer characters" (
package-info.java:597-598); "In this easy example a simple white space tokenization is performed. ... Here is the output:" (:647-649); "Now let's take a look at how the LengthFilter is implemented:" (:689). No "pseudo-code" or "illustrative" disclaimer anywhere on the page. - Deliberate API changes that left the example calls stale. LUCENE-5859 (
9938a39a872, 2014, "Remove Version from Analyzer constructors") did not touch it. LUCENE-4963 (8a7f2b6cc45, 2013) edited the page's listings but left bothLengthFilter(true, ...)calls. LUCENE-6651 (4accc254774, 2015) madereflectWithabstract; its MIGRATE entry: "If you have implemented your own attribute, make sure to add the required method sigature [sic]. See the Javadocs for an example." - No later edit fixed the stale calls. LUCENE-5392 (
2b822c846a8, 2014-01-10) rewrote the three whitespace calls tonew WhitespaceTokenizer(matchVersion), which matched trunk's API at the time, before LUCENE-5859 removed that constructor; later commits such as LUCENE-7318 (2016, the page'sStandardAnalyzerlink), #36 (2021, anenummodifier in the custom-attribute example) and LUCENE-9570 (reformatting) left the stale calls as they were; the last three (#14199, #14734, #15573, the last on 2026-01-15) are typo, grammar and markup fixes. - Precedent. Upstream fixes stale javadoc examples: LUCENE-9046 (
TermInSetQuery) and #16385 (per its CHANGES entry, the grouping package info) were merged; #16821 and #16823 (open issues) and #16904 (an open PR) report the same kind of defect in other package docs; LUCENE-8488 (#9534, open) asks for javadoc examples to be compiled.
The devil's-advocate check132 words
The strongest case: these are illustrative fragments without imports; Version.LUCENE_XY is an explicit placeholder that tells the reader to adapt the code; and in 2012, on #4740 (LUCENE-3666), Uwe Schindler (in an IRC log posted there) advised leaving reflectWith out to keep the attribute example minimal ("too much information", "a minimum example would be ideal").
Why it fails: a reader adds missing imports and the code compiles, but no import and no Version value makes the removed constructors exist, and a final class cannot be subclassed. reflectWith was optional only while AttributeImpl had a reflection-based default; LUCENE-6651, also by Uwe Schindler, removed it, and its MIGRATE note requires the method. The page prints the output its code should produce. All verifiers and the adjudication rejected the intended-behaviour case. Verdict: a documentation defect.
Recommended A. Rewrite the seven examples against the current API (javadoc only)
Rewrite the seven examples against today's API: drop Version; new StandardAnalyzer(), new WhitespaceTokenizer(), new LengthFilter(source, 3, Integer.MAX_VALUE); a small Analyzer for the gap example; super(in); add reflectWith; make the tagging filter final. Validated: the fixed page compiles, runs with -ea and prints its outputs; format, lint, javadoc and the core analysis tests pass.
All options and trade-offs3 options · 1,371 words
One option was validated in a scratch worktree of 645d4fe14a20: A, a javadoc-only rewrite of the one file. B is a variant for the position-gap example; C lists optional text cleanups.
A. Rewrite the seven examples against the current API (javadoc only) (validated by the checks) (recommended)
- Drop every
Version matchVersion = Version.LUCENE_XYline and theMyAnalyzer(Version)field and constructor. new StandardAnalyzer()(#1);new WhitespaceTokenizer()(#3, #4, #7);new LengthFilter(source, 3, Integer.MAX_VALUE)(#4, #7).- #2:
StandardAnalyzeris final, so a smallAnalyzerwithStandardTokenizerandLowerCaseFilter(the chainStandardAnalyzer()builds; its stop set is empty) that overridesgetPositionIncrementGap, as the text above the example says. - #5:
LengthFilter(TokenStream in, int min, int max) { super(in); ... }without the@param versionline; the FilteringTokenFilter listing's constructor becomesFilteringTokenFilter(TokenStream in). - #6: add
reflectWith(AttributeReflector)and name it in the sentence after the example. - Make
PartOfSpeechTaggingFilterfinal, and drop the straynewfrom the four printed outputs.
diff --git a/lucene/core/src/java/org/apache/lucene/analysis/package-info.java b/lucene/core/src/java/org/apache/lucene/analysis/package-info.java
index 4dfe81038f4..28a52a3abcd 100644
--- a/lucene/core/src/java/org/apache/lucene/analysis/package-info.java
+++ b/lucene/core/src/java/org/apache/lucene/analysis/package-info.java
@@ -179,8 +179,7 @@
* something like:
*
* <pre id="analysis-workflow"><code class="language-java">
- * Version matchVersion = Version.LUCENE_XY; // Substitute desired Lucene version for XY
- * Analyzer analyzer = new StandardAnalyzer(matchVersion); // or any other analyzer
+ * Analyzer analyzer = new StandardAnalyzer(); // or any other analyzer
* TokenStream ts = analyzer.tokenStream("myfield", new StringReader("some text goes here"));
* // The Analyzer class will construct the Tokenizer, TokenFilter(s), and CharFilter(s),
* // and pass the resulting Reader to the Tokenizer.
@@ -263,8 +262,14 @@
* Analyzer.getPositionIncrementGap(fieldName)}:
*
* <pre><code class="language-java">
- * Version matchVersion = Version.LUCENE_XY; // Substitute desired Lucene version for XY
- * Analyzer myAnalyzer = new StandardAnalyzer(matchVersion) {
+ * Analyzer myAnalyzer = new Analyzer() {
+ * {@literal @Override}
+ * protected TokenStreamComponents createComponents(String fieldName) {
+ * Tokenizer source = new StandardTokenizer();
+ * return new TokenStreamComponents(source, new LowerCaseFilter(source));
+ * }
+ *
+ * {@literal @Override}
* public int getPositionIncrementGap(String fieldName) {
* return 10;
* }
@@ -606,23 +611,16 @@
* <pre><code class="language-java">
* public class MyAnalyzer extends Analyzer {
*
- * private Version matchVersion;
- *
- * public MyAnalyzer(Version matchVersion) {
- * this.matchVersion = matchVersion;
- * }
- *
* {@literal @Override}
* protected TokenStreamComponents createComponents(String fieldName) {
- * return new TokenStreamComponents(new WhitespaceTokenizer(matchVersion));
+ * return new TokenStreamComponents(new WhitespaceTokenizer());
* }
*
* public static void main(String[] args) throws IOException {
* // text to tokenize
* final String text = "This is a demo of the TokenStream API";
*
- * Version matchVersion = Version.LUCENE_XY; // Substitute desired Lucene version for XY
- * MyAnalyzer analyzer = new MyAnalyzer(matchVersion);
+ * MyAnalyzer analyzer = new MyAnalyzer();
* TokenStream stream = analyzer.tokenStream("field", new StringReader(text));
*
* // get the CharTermAttribute from the TokenStream
@@ -655,7 +653,6 @@
* demo
* of
* the
- * new
* TokenStream
* API
* </pre>
@@ -669,8 +666,8 @@
* <pre><code class="language-java">
* {@literal @Override}
* protected TokenStreamComponents createComponents(String fieldName) {
- * final Tokenizer source = new WhitespaceTokenizer(matchVersion);
- * TokenStream result = new LengthFilter(true, source, 3, Integer.MAX_VALUE);
+ * final Tokenizer source = new WhitespaceTokenizer();
+ * TokenStream result = new LengthFilter(source, 3, Integer.MAX_VALUE);
* return new TokenStreamComponents(source, result);
* }
* </code></pre>
@@ -681,7 +678,6 @@
* This
* demo
* the
- * new
* TokenStream
* API
* </pre>
@@ -700,13 +696,12 @@
* * Create a new LengthFilter. This will filter out tokens whose
* * CharTermAttribute is either too short
* * (< min) or too long (> max).
- * * {@literal @param} version the Lucene match version
* * {@literal @param} in the TokenStream to consume
* * {@literal @param} min the minimum length
* * {@literal @param} max the maximum length
* */
- * public LengthFilter(Version version, TokenStream in, int min, int max) {
- * super(version, in);
+ * public LengthFilter(TokenStream in, int min, int max) {
+ * super(in);
* this.min = min;
* this.max = max;
* }
@@ -743,7 +738,7 @@
* * Create a new FilteringTokenFilter.
* * {@literal @param} in the TokenStream to consume
* */
- * public FilteringTokenFilter(Version version, TokenStream in) {
+ * public FilteringTokenFilter(TokenStream in) {
* super(in);
* }
*
@@ -828,18 +823,23 @@
* public void copyTo(AttributeImpl target) {
* ((PartOfSpeechAttribute) target).setPartOfSpeech(pos);
* }
+ *
+ * {@literal @Override}
+ * public void reflectWith(AttributeReflector reflector) {
+ * reflector.reflect(PartOfSpeechAttribute.class, "partOfSpeech", pos);
+ * }
* }
* </code></pre>
*
* <p>This is a simple Attribute implementation has only a single variable that stores the
* part-of-speech of a token. It extends the <code>AttributeImpl</code> class and therefore
- * implements its abstract methods <code>clear()</code> and <code>copyTo()</code>. Now we need a
- * TokenFilter that can set this new PartOfSpeechAttribute for each token. In this example we show a
- * very naive filter that tags every word with a leading upper-case letter as a 'Noun' and all other
- * words as 'Unknown'.
+ * implements its abstract methods <code>clear()</code>, <code>copyTo()</code> and <code>
+ * reflectWith()</code>. Now we need a TokenFilter that can set this new PartOfSpeechAttribute for
+ * each token. In this example we show a very naive filter that tags every word with a leading
+ * upper-case letter as a 'Noun' and all other words as 'Unknown'.
*
* <pre><code class="language-java">
- * public static class PartOfSpeechTaggingFilter extends TokenFilter {
+ * public static final class PartOfSpeechTaggingFilter extends TokenFilter {
* PartOfSpeechAttribute posAtt = addAttribute(PartOfSpeechAttribute.class);
* CharTermAttribute termAtt = addAttribute(CharTermAttribute.class);
*
@@ -873,8 +873,8 @@
* <pre><code class="language-java">
* {@literal @Override}
* protected TokenStreamComponents createComponents(String fieldName) {
- * final Tokenizer source = new WhitespaceTokenizer(matchVersion);
- * TokenStream result = new LengthFilter(true, source, 3, Integer.MAX_VALUE);
+ * final Tokenizer source = new WhitespaceTokenizer();
+ * TokenStream result = new LengthFilter(source, 3, Integer.MAX_VALUE);
* result = new PartOfSpeechTaggingFilter(result);
* return new TokenStreamComponents(source, result);
* }
@@ -886,7 +886,6 @@
* This
* demo
* the
- * new
* TokenStream
* API
* </pre>
@@ -931,7 +930,6 @@
* This: Noun
* demo: Unknown
* the: Unknown
- * new: Unknown
* TokenStream: Noun
* API: Noun
* </pre>Trade-offs
- Javadoc only, so no Lucene code changes.
- The gap example no longer shows
StandardAnalyzeritself. With the default settings its index-time tokens are the same asStandardAnalyzer()'s, but it is not the same class: nosetMaxTokenLength(both default to 255), noStopFilter(the default stop set is empty) and nonormalizeoverride, which matters only for query-time normalization. Replies on LUCENE-3055 (#4128) by Robert Muir and Uwe Schindler recommend writing your own Analyzer instead of subclassingStandardAnalyzer.
What the checks validated
- Page text (a checker builds nine units from eleven of the page's Java blocks, taken verbatim and assembled as the page describes; it adds imports, packages, a
mainfor the two fragments, the attribute's own files, the tagging filter nested inMyAnalyzer, and gap and token prints for the gap unit; it compiles each unit with javac against the645d4fe14a20jars, runs the six with amainunder-eaand compares four outputs with the page): stock page 8 of 9 units fail to compile; fixed page 9 of 9 compile, the six run, and all four printed outputs match exactly (This is a demo of the TokenStream API;This demo the TokenStream APItwice;This: Noun demo: Unknown the: Unknown TokenStream: Noun API: Noun); the gap analyzer returns 10. Withoutfinal, the two part-of-speech units throwAssertionError: TokenStream implementation classes or at least their incrementToken() implementation must be final. - Build:
:lucene:core:checkGoogleJavaFormat,ecjLintMainandrenderJavadocpass (the fixed source has nomatchVersionleft);./gradlew :lucene:core:test --tests "org.apache.lucene.analysis.*"with seed DEADBEEF passes (168 tests, 0 failures). The repro's fixed-lines variant passes with-eaand-da.
AnalyzerWrapper.getPositionIncrementGap delegates to the wrapped analyzer (AnalyzerWrapper.java:130-131); overriding it in the wrapper gives 10 (the devil's advocate ran this).
Analyzer standard = new StandardAnalyzer();
Analyzer myAnalyzer = new AnalyzerWrapper(Analyzer.PER_FIELD_REUSE_STRATEGY) {
  @Override protected Analyzer getWrappedAnalyzer(String fieldName) { return standard; }
  @Override public int getPositionIncrementGap(String fieldName) { return 10; }
};
Trade-offs
Keeps the exact StandardAnalyzer chain, but adds a second concept (wrapping, a reuse strategy) to a section about overriding one method; A matches the text better.
What the checks validated
Compiled and run by the devil's advocate: "control L266 gap=10".
- "The LengthFilter is part of the Lucene core" (
:598): it is in analysis-common. - The FilteringTokenFilter listing (
:737-775) lacks the real class'send()/skippedPositionshandling: a filter built on it reportsend()position increment 0 where the realLengthFilterreports 1 (input "demo of", min length 3; the devil's advocate ran this). Show the realend()or point to the source. - The "could begin" hint
FirstTokenOfSentenceAttributeImpl(:948-968) could mentionreflectWithtoo.
Trade-offs
Outside the compile claim; each is a one-line text change.
What the checks validated
Not run (a text change; the devil's advocate ran the end-position check only).
Non-formal: a sweep compiled every Java code block in Lucene's non-sandbox javadoc (186 blocks in 107 files) against the main jars and flagged six blocks of this page; a targeted test reproduced them. The independent reproducer, the devil's advocate and a cross-model reviewer each found the seventh, which the sweep's pattern skipped.
The method in full107 words
Method: non-formal (a compile check of documentation code). On 2026-10-28 the hunt unit for javadoc package and overview examples (siblings of #16904) compiled all 186 <pre><code class="language-java"> blocks of the 107 non-sandbox lucene/**/src/java files that have one against the stock main a9779ef3c193 jars with the JDK compiler, and flagged six blocks of the analysis package overview with API-level errors. A targeted public-API JUnit then compiled them verbatim (6 of 7 tests fail). The seventh example, a <pre id="analysis-workflow"> block the sweep's pattern skips, was found independently by the reproducer, the devil's advocate and the intended-lens cross-model reviewer. The verifiers' tests were later cut to the one-method repro.
No Lucene report: 183 queries over GitHub issues and PRs (incl. the JIRA archive), the mailing lists, downstream projects, Stack Overflow and the web (2026-10-29), rechecked on 2026-11-01. A 2016 Stack Overflow question hit example 1 and never reached the tracker.
Searches3 searches
Closest items, none a Lucene report of this defect: Stack Overflow 40052828 (2016, one of the seven examples); #4740 (LUCENE-3666, closed 2012, an earlier rewrite of this page, before every breaking change); #9534 (LUCENE-8488, open, compile javadoc examples, names no file); #16821, #16823, #16904, #16936 (the same kind of defect in other package docs); LUCENE-3055 (#4128, open, objects to final analyzers); lucenenet#1522 (the Lucene.NET port of this page, other project). Limits: keyword search only; GitHub search does not index PR diffs.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, incl. the migrated JIRA archive) | 2026-10-29 | 32 searches, open and closed (StandardAnalyzer(matchVersion), PartOfSpeechAttributeImpl, LengthFilter, reflectWith, package-info, LUCENE-5859 and others); file lists of 124 of the 300 newest open PRs; the 100 most recently updated closed PRs; the file's commits on main, branch_11x, branch_10_6, branch_10x | no report; closest #4740, #9534, and the sibling package-doc items |
| JIRA, mailing lists, downstream, Stack Overflow, web | 2026-10-29 | 13 JIRA queries; 43 list queries (dev@, java-user@, issues@, commits@); 7 downstream; 9 Stack Overflow; 10 web | Stack Overflow 40052828 (one example, 2016); nothing on the Lucene tracker or lists |
| Upstream recheck | 2026-11-01 | the file's commits on main (latest still 378ca8d1bbf, #15573, 2026-01-15); the changed files of the 60 newest PRs (#16873 to #16959); search "PartOfSpeechAttributeImpl" | nothing new; only #4740 and the unrelated #9616 |
No single commit: five API changes broke the examples one by one (LUCENE-1987 and LUCENE-2372 in 3.0/3.1, LUCENE-4963 in 4.4, LUCENE-5859 in 5.0, LUCENE-6651 in 6.0), and none updated the calls. All seven are broken in every release from 6.0.0 to 10.6.0 and main; not fixed upstream.
Versions tested6 rows
- 3.0.0, example 2: LUCENE-1987 (
1ae5f89cfb3, 2009-10-21) removedStandardAnalyzer(), which the gap example subclassed; LUCENE-2372 (d02cbfe3c16, 2010) made the class final in 3.1, so the 2012Versionform of the example (branch_3x1cfd251f02b, shipped in 3.6.0; trunke825015535e, first in 4.0.0) never compiled in a release that shipped it. - 4.4.0, examples 4 and 7: LUCENE-4963 (
8a7f2b6cc45, 2013-05-04) replacedLengthFilter(boolean, TokenStream, int, int); it edited the page and left both calls. - 5.0.0, examples 1, 3 and 5: LUCENE-5859 (
9938a39a872, 2014-08-08; branch_5x55594bad9b0). The primary change: it also broke theWhitespaceTokenizerline of 4 and 7. Thatnew WhitespaceTokenizer(matchVersion)text came from a 2014 trunk docs update (LUCENE-5392,2b822c846a8) that matched trunk's API at the time; it reached 5.0.0 in the same backport as the removal, so it never compiled in a release. - 6.0.0, example 6: LUCENE-6651 (
4accc254774, 2015-07-02). - No later commit fixed the stale calls (e.g. LUCENE-7318 in 2016, #36 in 2021, LUCENE-9570 reformatting); the last three are typo, grammar and markup changes, the latest
378ca8d1bbf(#15573, 2026-01-15). - The release ranges below count only today's seven stale calls. Older page texts had other errors, long fixed: the 3.0.0-3.5.x workflow example called the removed
new StandardAnalyzer(), and the 4.0.0 part-of-speech chain calledLengthFilter(source, 3, ...), which 4.0.0 lacks.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | one-test repro fails with assertions on and off; the page check: 8 of 9 units fail to compile, 9 of 9 with fix A |
| 6.0.0, 7.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, the 10.6 branch head | affected | all seven examples fail; every control compiles (history probe; 8.11.4's jars with main's page text, as the 8.9-8.11 page text was not read); verifiers' JUnit on 10.5.2 and 9.12.3 |
| 5.0.0, 5.5.5 | six of seven | the custom attribute still compiles (reflectWith had a default) |
| 4.4.0, 4.10.4 | three of seven | the gap example and both LengthFilter(true, ...) calls fail |
| 3.0.0 to 4.3.1 (executed 3.0.0, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.1.0, 4.3.1) | first affected 3.0.0 | counting only today's seven stale calls, only the gap example fails (older page texts had other errors there, long fixed) |
| 2.9.4 | not affected | counting only today's seven stale calls: the gap example of the time compiles; the other six did not exist in their current form |
Confirmed, high confidence: the finder, an independent reproducer, an intended-behaviour devil's advocate and the adjudication reproduced it; a cross-model reviewer reading the code rated it real; the other cross-model review was not valid (it could not run code). A credibility audit confirmed it.
Checks and verdicts283 words
Everyone agrees on the cause: deliberate API changes that left the example calls stale. All runs used JDK 25 on Linux aarch64.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced (six examples) | The compile sweep flagged six blocks; its JUnit fails 6 of 7 on main (-ea, -da), 10.5.2 and 9.12.3. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not a valid review | It could not write or run anything, so its "not real" is procedural; its reading evidence (8 items) supports real. |
| independent reproducer | real | Own 15-test JUnit (7 examples verbatim, 8 corrected controls): 7 of 15 fail on main (-ea, -da), 10.5.2 and 9.12.3; found example 1. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium | The intended-behaviour argument is weak (working code, printed output, no disclaimer); also found example 1. A separate re-run of the finder's test and a javac check of the code backed it. |
| intended-behaviour devil's advocate | real | Rejected the fragment, placeholder and "minimal example" arguments; a corrected tutorial compiles and runs, and needs a final tagging filter under -ea. |
| adjudication | confirmed, high | Widened the claim to seven examples; re-ran the independent reproduction's test with a new seed: 7 of 15 fail, -ea and -da. |
| Follow-up, registration check, credibility audit | reproduces | History probe on 35 runs from 2.9.4 to main; no prior report found; re-runs 7 of 15 and 6 of 7. |
| minimal repro and this doc | reproduced; fix validated | The one-method test fails on main 645d4fe14a20 with -ea and -da; fix A compiles, runs and passes format, lint, javadoc and the core analysis tests. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 446 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,488 words
- Registry title
- The org.apache.lucene.analysis package overview (the TokenStream API tutorial) has seven code examples that do not compile on any release since 6.0: they call StandardAnalyzer(Version), WhitespaceTokenizer(Version) and FilteringTokenFilter(Version, TokenStream), removed in 5.0, and LengthFilter(boolean, TokenStream, int, int), gone since 4.4, subclass the final StandardAnalyzer, and define a custom AttributeImpl without reflectWith, abstract since 6.0 (documentation defect)
- Area
- core / analysis (org.apache.lucene.analysis package overview, package-info.java: the TokenStream API tutorial)
- Priority
- Low, rank 1237: The core analysis tutorial's seven examples fail loudly at compile time with no runtime effect, and it is the most-read of the pages with broken examples.
- Impact class
- minor
- Impact note
- Documentation only, with no runtime effect: anyone who learns the TokenStream API from the core analysis package overview and copies one of its examples (the analysis workflow, the position-gap analyzer, the whitespace analyzer, adding a LengthFilter, the LengthFilter listing, the custom part-of-speech attribute, the final part-of-speech chain) gets compile errors and has to rewrite it against the current constructors; no configuration, scale or special input is involved, and all seven examples have been broken together in every release since 6.0.0 (the oldest one since 3.0.0).
- Summary
- You open the org.apache.lucene.analysis package overview, Lucene's tutorial for writing analyzers, token filters and attributes, and copy one of its examples, expecting it to compile as shown (the page even prints the output the code should produce). Seven examples do not compile on main or on any release since 6.0.0: they call StandardAnalyzer(Version), WhitespaceTokenizer(Version) and FilteringTokenFilter(Version, TokenStream), all removed in 5.0, and new LengthFilter(true, source, 3, Integer.MAX_VALUE), a signature gone since 4.4; one subclasses StandardAnalyzer, which is final; and the custom PartOfSpeechAttributeImpl lacks reflectWith(AttributeReflector), which has been abstract since 6.0. The APIs changed on purpose and the page was never updated: written against the current API (no Version argument, LengthFilter(source, 3, Integer.MAX_VALUE), a custom Analyzer or AnalyzerWrapper instead of a StandardAnalyzer subclass, and a reflectWith method) every example compiles.
- Introduced
- No single commit: the seven examples went stale at five API changes, and only one of them (LUCENE-4963) edited this page, leaving its stale calls in place [read: git log -S and git show --stat on the page under its three historical paths and on the API classes, in the full-history clone; exec: release boundary runs, see affected_versions]. Oldest: 1ae5f89cfb3 (LUCENE-1987 = #3062, uschindler, 2009-10-21, first in 3.0.0) removed StandardAnalyzer(), which the position-gap example then subclassed, and d02cbfe3c16 (LUCENE-2372 = #3448, uschindler, 2010-04-10; branch_3x merge 379c5fd00d4, 2010-05-04; 3.1) made StandardAnalyzer final, so the 2012 Version form of that example (e825015535e, sarowe, 3.6.0) never compiled in any release that shipped it. 8a7f2b6cc45 (LUCENE-4963 = #6027, jpountz, 2013-05-04; branch_4x ddf2a47e3ef; 4.4.0) replaced LengthFilter(boolean, TokenStream, int, int) with Version-first constructors and rewrote this page's LengthFilter and FilteringTokenFilter listings, but left both LengthFilter(true, ...) calls. Primary: 9938a39a872 (LUCENE-5859 = #6921, rjernst, 2014-08-08; branch_5x backport 55594bad9b0, LUCENE-5944, rmuir, 2014-09-18; 5.0.0) removed StandardAnalyzer(Version), WhitespaceTokenizer(Version) and FilteringTokenFilter(Version, TokenStream) without touching the page, breaking five of the seven groups. 4accc254774 (LUCENE-6651 = #7709, uschindler, 2015-07-02; 6.0.0) made AttributeImpl.reflectWith abstract, breaking the custom-attribute example (its MIGRATE entry tells custom attributes to implement it). (2009-10-21 (1ae5f89cfb3, the oldest break: the position-gap example); 2010-04-10 (d02cbfe3c16, StandardAnalyzer final); 2013-05-04 (8a7f2b6cc45, the LengthFilter calls); 2014-08-08 (9938a39a872, primary: the Version constructors, five groups); 2015-07-02 (4accc254774, the custom attribute); author dates)
- First affected version
- 3.0.0 [exec] for the position-gap example (its text of the time compiles on 2.9.4 and fails on 3.0.0); 4.4.0 [exec] for the two LengthFilter(true, ...) calls; 5.0.0 [exec] for the Version constructors (five groups); 6.0.0 [exec] for the custom attribute, so every release from 6.0.0 on has all seven examples broken
- Affected versions
- every release from 3.0.0 to 10.5.2, 10.6.0 (released 2026-10-29; branch_10_6 4ae946e5a9b) and main a9779ef3c193; not fixed upstream. 3.0.0-4.3.1: the position-gap example only; 4.4.0-4.10.4: the gap example and both LengthFilter calls; 5.0.0-5.5.x: six of the seven (all but the custom attribute); 6.0.0 to 10.5.2, 10.6.0 and main: all seven. Not affected: 2.2.0-2.9.x (the gap example compiles on 2.9.4; the other six did not exist in their current form). [exec: the follow-up's history probe compiles each release's own published page text against that release's jars, each stale example with a control that changes only the stale call and compiles, on 2.9.4, 3.0.0, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.1.0, 4.3.1, 4.4.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 7.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, the 10.6 branch head (core and analysis-common jars only) and main (-ea and -da); the finder's JUnit fails 6 of 7 and the independent reproduction's 7 of 15 on main (-ea and -da), 10.5.2 and 9.12.3] [read: the releases in between carry the same page text (per-tag text hashes) and the same constructors at the boundaries (javap); the 8.9-8.11 page text was not read (those tags are not in the history clone; the 8.11.4 jars were executed with the main text); upstream main 645d4fe14a2, branch_11x and branch_10_6 still carry the same example text]. Caveat: all runs used JDK 25 on Linux aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-29, 183 recorded queries): 32 GitHub issue and PR searches (open and closed, apache/lucene, incl. the migrated JIRA archive), the file lists of 124 of the 300 newest open PRs (incl. every PR opened in the last 48 h), the 100 most recently updated closed PRs, the file's commit history on main, branch_11x, branch_10_6 and branch_10x, 13 JIRA queries, 43 mailing-list queries (dev@, java-user@, issues@, commits@), downstream projects (7 queries), Stack Overflow (9) and the web (10). Closest items: Stack Overflow question 40052828 (2016-10-14), where a 6.2.1 user found that this page's new StandardAnalyzer(matchVersion) example (the analysis-workflow block, 1 of the 7 groups) does not compile and the answer explained the Version argument was removed in 5.0; it was never raised on the Lucene tracker or lists. #4740 (LUCENE-3666, closed 2012) is an earlier rewrite of this page that predates every API change that broke today's text; #9534 (LUCENE-8488, open) is a generic wish to compile javadoc examples and names no file; #16821, #16823, #16904 and #16936 report or fix the same kind of defect in other package docs (highlight, charfilter, collation); lucenenet#1522 (2026-10-28) is the Lucene.NET port of this page, with different defects in a different project; #6921, #6027 and #7709 are the API changes themselves and do not mention the page. Recheck (2026-10-29): the file's latest upstream commit on main and branch_11x is still 378ca8d1bbf (#15573, author date 2026-01-15, formatting only) and on branch_10_6 and branch_10x 0124a2e17ab (#14734 backport); no issue or PR was created after #16937 (2026-10-28); the newest PRs #16936 and #16904 touch other files; searches for "StandardAnalyzer(matchVersion)", "PartOfSpeechAttributeImpl", 'analysis package-info LengthFilter' and '"TokenStream API" tutorial javadoc' return only the items above or unrelated ones; tracking issue #16937 does not name this page.
- Lucene commit tested
- main
645d4fe14a20(2026-11-01): the one-test repro fails with assertions on and off, standalone and as a plain JUnit run; in a scratch worktree the fixed page compiles and runs (all four printed outputs match) and passes format, lint, javadoc and the core analysis tests. Earlier, on maina9779ef3c193(same page text): the verifiers' tests on main, 10.5.2 and 9.12.3, and a history probe that compiles each release's own page text, from 2.9.4 to the 10.6 branch head.
- Finding record
lucene/core/src/java/org/apache/lucene/analysis/package-info.java:181-183 (analysis-workflow block, new StandardAnalyzer(matchVersion)), :266-267 (anonymous StandardAnalyzer subclass), :617, :672-673, :876-877 (WhitespaceTokenizer(matchVersion), LengthFilter(true, ...)), :709 (super(version, in)), :809 (PartOfSpeechAttributeImpl without reflectWith), :836 (text naming only clear() and copyTo() as abstract), :842 (non-final PartOfSpeechTaggingFilter); identical at Lucene main ea57360912edlucene/core/src/java/org/apache/lucene/analysis/standard/StandardAnalyzer.java:34, :46, :51, :61 (public final class; constructors (CharArraySet), (), (Reader)); lucene/analysis/common/src/java/org/apache/lucene/analysis/core/WhitespaceTokenizer.java:34-66 (no Version constructor); lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LengthFilter.java:44 (only (TokenStream, int, int)); lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:38 (only (TokenStream)); lucene/core/src/java/org/apache/lucene/util/AttributeImpl.java:93 (abstract reflectWith)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/package-info.java:181-203, 265-272, 597-599, 606-661, 669-721, 737-775, 808-842, 873-937a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/standard/StandardAnalyzer.java:34, 46, 51, 61; lucene/analysis/common/src/java/org/apache/lucene/analysis/core/WhitespaceTokenizer.java:34-66; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LengthFilter.java:44; lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:38; lucene/core/src/java/org/apache/lucene/util/AttributeImpl.java:34, 93, 99; lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:68, 74-76, 107-112
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:68, 74-76
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/package-info.java:597-599, 647-649, 678, 689GitHub, read 2026-11-01: #16821 and #16823 open issues, #16904 open PR, #16385 merged 2026-08-12
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/standard/StandardAnalyzer.java:51-53, 85-96; lucene/core/src/java/org/apache/lucene/analysis/AnalyzerWrapper.java:130-131
- TestAnalysisOverviewExamplesCompile.java (JUnit, one test):
repro/LFV-989/src/org/apache/lucene/analysis/TestAnalysisOverviewExamplesCompile.java(98 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and executed probe runs on main.
assets/LFV-989/bug.png(446 KB)