Four public constructors decode the dictionary file as UTF-8 themselves. Java's decoder turns a leading byte order mark into the character U+FEFF, and nothing removes it, so it sticks to the first entry. Lucene's word-list line loader drops the mark on purpose; these dictionaries do not.
- A byte order mark (BOM) is the three bytes
EF BB BFthat some editors write at the start of a UTF-8 file. Java's UTF-8 decoder turns them into one invisible character, U+FEFF (ZERO WIDTH NO-BREAK SPACE); it does not drop them. FileDictionaryfeeds a suggester from a text file with one entry per line,suggestion<TAB>weight.PlainTextDictionaryfeeds aSpellCheckerwith one word per line.
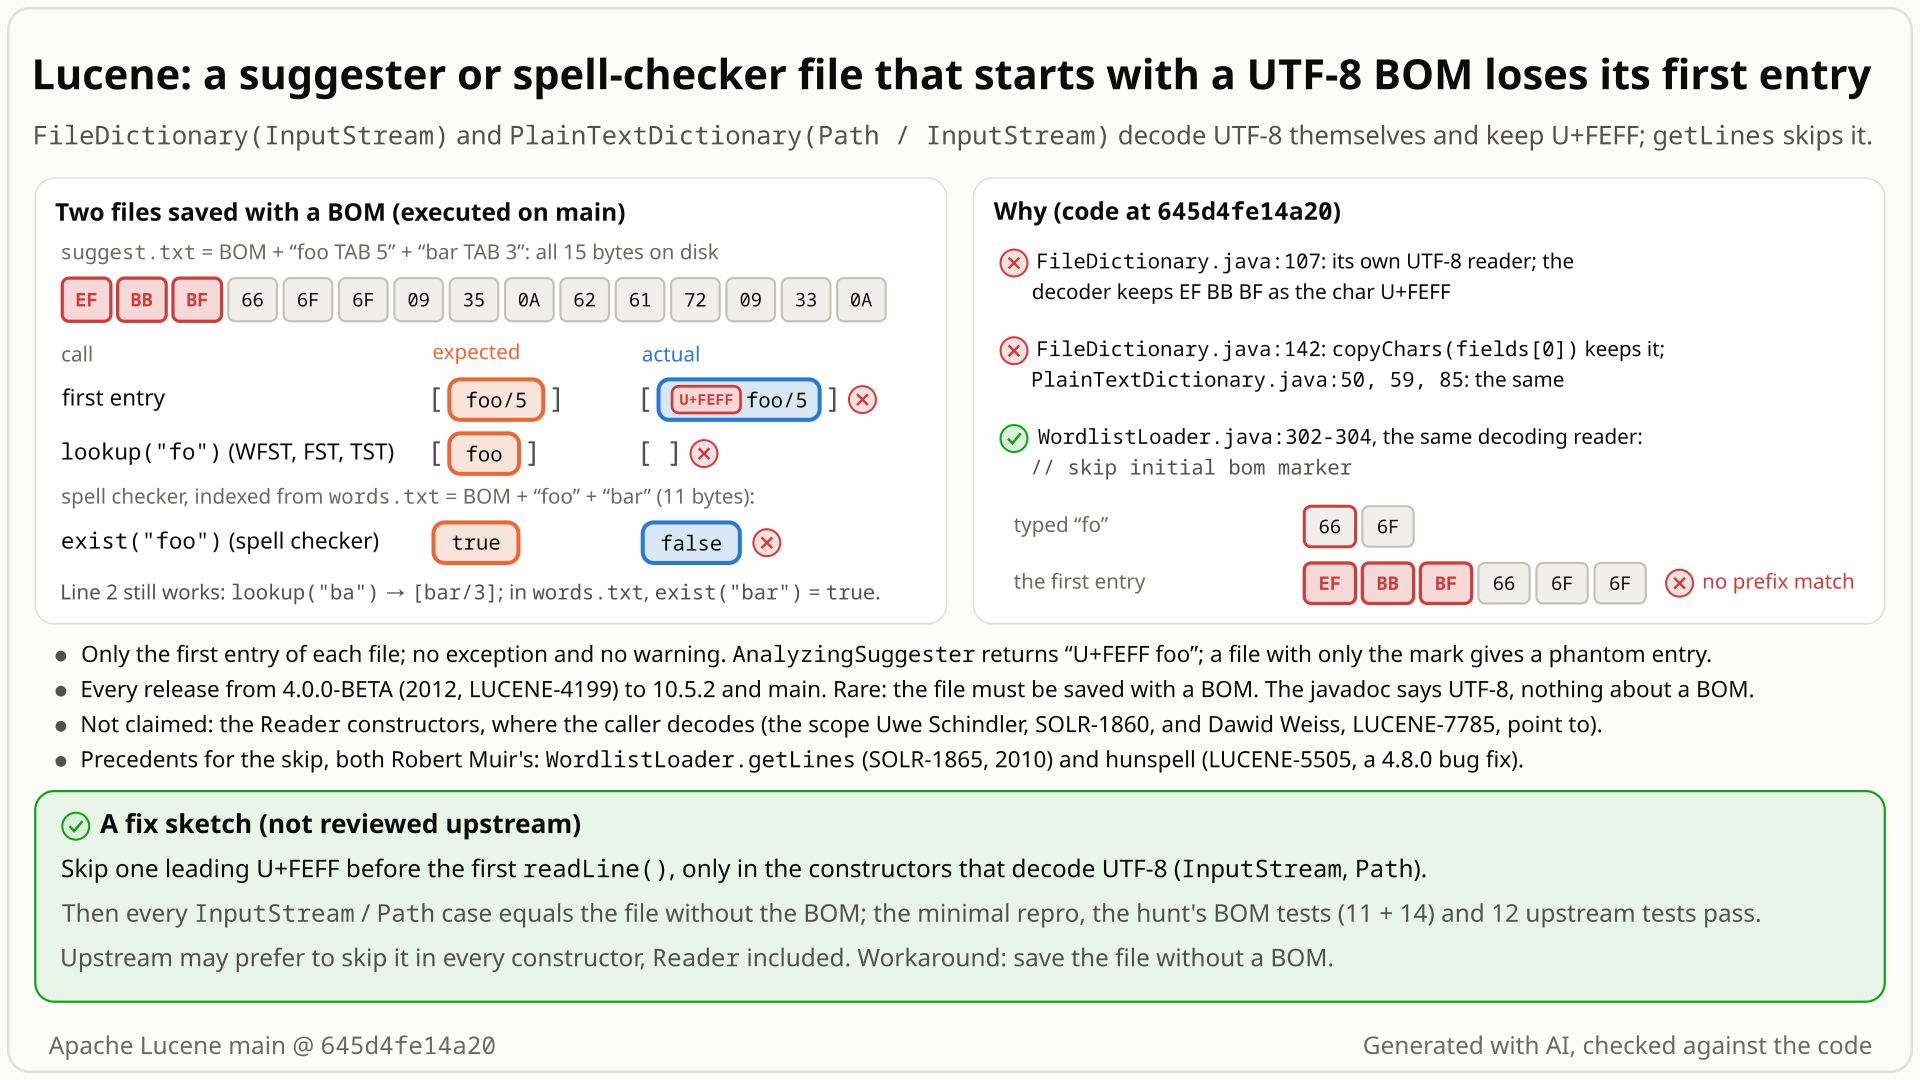
EF BB BF then foo<TAB>5 and bar<TAB>3, the decoder keeps the mark as U+FEFF on line 1, so the first entry is \uFEFFfoo and lookup("fo") finds nothing; a spell checker indexed from the word file EF BB BF + foo / bar says foo does not exist. Select the still to open it at full size. Generated with AI, checked against the code.- You save
dict.txtwith two lines,foo<TAB>5andbar<TAB>3, in an editor that writes UTF-8 with a byte order mark: the file starts with the bytesEF BB BF, which Java decodes to one invisible character, U+FEFF. - You build a suggester from
new FileDictionary(inputStream), whose javadoc says "content is treated as UTF-8", and expect what the same file without the mark gives: entriesfoo/5andbar/3, andlookup("fo")returnsfoo. - You get the first entry as
\uFEFFfoo(bytesef bb bf 66 6f 6finstead of66 6f 6f):WFSTCompletionLookup,FSTCompletionLookupandTSTLookupreturn nothing forlookup("fo"), andAnalyzingSuggesterreturns\uFEFFfoo, which prints likefoo.barstill works. No error. - The spell checker is hit the same way: indexed from
PlainTextDictionaryover the word file<BOM>foo/bar,SpellChecker.exist("foo")is false andsuggestSimilar("fooo", 3)returns\uFEFFfoo. - Why: these constructors decode the bytes as UTF-8 themselves, Java's decoder keeps the mark, and nothing in the suggest module drops it. Lucene's word-list line loader (
WordlistLoader.getLines, "skip initial bom marker") and hunspell skip it on purpose.
Applications that build a suggester from FileDictionary(InputStream) or index a SpellChecker from PlainTextDictionary(Path/InputStream) with a file saved as UTF-8 with a byte order mark. No special setting is needed. The first entry of each such file is lost, silently. The suggest module is opt-in; rare in practice.
Mechanism, terms and numbers611 words
FileDictionary (the text-file source for Lookup.build) and PlainTextDictionary (the word-list source for SpellChecker.indexDictionary) have constructors that take an InputStream (and, for PlainTextDictionary, a Path) and decode it as UTF-8 themselves; their javadoc says "NOTE: content is treated as UTF-8". Some editors and export tools save UTF-8 with a byte order mark, the bytes EF BB BF. Java's UTF-8 decoder returns them as the invisible character U+FEFF, and the iterators copy the first line's text unchanged, so the first entry becomes \uFEFF + word. For a file <BOM>foo<TAB>5 / bar<TAB>3, the WFST, FST and TST suggesters return nothing for lookup("fo"), AnalyzingSuggester returns \uFEFFfoo, and a SpellChecker indexed from the word file <BOM>foo / bar says exist("foo") is false. A file that holds only the mark gives one phantom entry. No error is raised, and only the first line of each file is affected. Lucene's line loader WordlistLoader.getLines and hunspell skip the mark. Every release from 4.0.0-BETA (2012) to 10.6.0, and main, is affected. Skipping one leading U+FEFF in the four decoding constructors fixes it.
- The decoding constructors:
FileDictionary(InputStream),FileDictionary(InputStream, String fieldDelimiter),PlainTextDictionary(Path)andPlainTextDictionary(InputStream). Each says "NOTE: content is treated as UTF-8" (FileDictionary.java:77, 104,PlainTextDictionary.java:47, 56). TheReaderconstructors, where the caller decodes the bytes, are not part of this report. - Byte order mark (BOM): the bytes
EF BB BFat the start of a UTF-8 file, an encoding signature, not text. Java's UTF-8 decoder returns them as U+FEFF (JDK-4508058, closed Won't Fix: application code must skip the mark itself).
FileDictionary(InputStream)delegates toFileDictionary(InputStream, String)(FileDictionary.java:79-81), which doesin = new BufferedReader(IOUtils.getDecodingReader(dictFile, StandardCharsets.UTF_8));(:107).PlainTextDictionary(Path)usesFiles.newBufferedReader(path, StandardCharsets.UTF_8)(PlainTextDictionary.java:50) andPlainTextDictionary(InputStream)the samegetDecodingReadercall (:59).IOUtils.getDecodingReaderbuilds a strict decoder and anInputStreamReader(IOUtils.java:192-199); it has no BOM handling.FileDictionary.FileIterator()reads line 1 (FileDictionary.java:128), splits it on the delimiter (:133) and copiesfields[0]unchanged (:138,:142,:145).PlainTextDictionary's iterator copies each whole line (PlainTextDictionary.java:84-86). Neither class nor its upstream tests handles U+FEFF or a BOM.- So the first entry is
\uFEFFfoo. The WFST, FST and TST suggesters index that key, so no prefix offooreaches it;AnalyzingSuggesterwithStandardAnalyzermatches it but returns the stored key with the mark;SpellChecker.indexDictionaryindexes the word\uFEFFfoo, soexist("foo")is false. - Lucene's other text-file loaders skip the mark:
WordlistLoader.getLines(// skip initial bom marker,WordlistLoader.java:302-304) and hunspell (Dictionary.java:246,:351-354, "ignore any BOM marker on first line"). Not uniform:WordlistLoader.getWordSet(InputStream)keeps it too (an independent reviewer from another model family, OpenAI GPT-5.6, pointed this out);WordlistLoaderis@lucene.internal.
Only line 1 is affected: a U+FEFF at the start of a later line is a real character and is kept. (getLines differs slightly: it strips U+FEFF from the first line it keeps, which can be a later line when comment or blank lines come first.)
What happens (stock main, file EF BB BF + foo<TAB>5 / bar<TAB>3, or the word file EF BB BF + foo / bar)
| use | without the mark | with the mark |
|---|---|---|
FileDictionary(InputStream) entries, and FileDictionary(InputStream, String) with a custom delimiter | [foo/5, bar/3] | [\uFEFFfoo/5, bar/3] |
WFSTCompletionLookup, FSTCompletionLookup, TSTLookup: lookup("fo") | [foo] | [] |
AnalyzingSuggester (StandardAnalyzer): lookup("fo") | [foo] | [\uFEFFfoo] |
PlainTextDictionary(Path) and (InputStream) words | [foo, bar] | [\uFEFFfoo, bar] |
SpellChecker indexed from PlainTextDictionary(Path) or (InputStream): exist("foo") | true | false |
same, from PlainTextDictionary(InputStream): suggestSimilar("fooo", 3) | [foo] | [\uFEFFfoo] |
| a file that holds only the mark | no entry | one entry \uFEFF, weight 1 |
Exposure and likelihood258 words
- Who is exposed. Applications that build a suggester from
FileDictionary(InputStream)orFileDictionary(InputStream, String), or index aSpellCheckerfromPlainTextDictionary(Path)orPlainTextDictionary(InputStream). These are the public constructors with no special setting; the suggest module itself is opt-in. - What it takes. A dictionary file saved as UTF-8 with a byte order mark, which the 2010 CHANGES entry for the line loader's skip (SOLR-1865) describes as "often created by editors such as Windows Notepad". No scale, no concurrency, no unusual setting.
- What happens. The first suggestion can never be found by typing its prefix (WFST, FST, TST);
AnalyzingSuggesterreturns it with an invisible character that breaks equality checks downstream; the spell checker reports the first word as misspelled and suggests the marked form; an empty file saved with a mark gives one phantom entry. No error or warning, and printed output looks right. - Scale. Deterministic and independent of dictionary size: one entry per file.
- Versions. Every release from 4.0.0-BETA (2012) to 10.6.0, and main (14 releases and pre-releases from 4.0.0-BETA to 10.5.2 executed, plus
4ae946e5a9b9, the commit 10.6.0 was released from, and main; the rest read). The(InputStream, String)andPathconstructors arrived in 4.7.0 and 5.0.0; before themFileDictionary(InputStream),PlainTextDictionary(InputStream)andPlainTextDictionary(File)showed the same defect. - How likely. Rare: it needs a marked file, only its first entry goes wrong, and no public report was found since 4.0.0.
- Workarounds. Save the file without a mark, start it with a throwaway first line, or decode the file yourself, strip a leading U+FEFF and pass a
Reader.
One JUnit test for the suggest module, public API only: it feeds the nine bytes EF BB BF f o o TAB 5 LF to FileDictionary(InputStream) and checks that the first entry is foo. Comparing BytesRefs shows the invisible U+FEFF as its bytes ef bb bf in the failure message.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest;

import java.io.ByteArrayInputStream;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestFileDictionaryUtf8Bom extends LuceneTestCase {

  public void testFirstEntryAfterByteOrderMark() throws Exception {
    byte[] file = {(byte) 0xEF, (byte) 0xBB, (byte) 0xBF, 'f', 'o', 'o', '\t', '5', '\n'};
    InputIterator it = new FileDictionary(new ByteArrayInputStream(file)).getEntryIterator();
    // expected: "foo" ([66 6f 6f]); actual: the UTF-8 mark is kept as U+FEFF ([ef bb bf 66 6f 6f])
    assertEquals(new BytesRef("foo"), it.next());
  }
}
./gradlew :lucene:suggest:test --tests "org.apache.lucene.search.suggest.TestFileDictionaryUtf8Bom" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
- Expected
- The first entry of
EF BB BF+foo<TAB>5isfoo, bytes[66 6f 6f]. - Observed
- It is
\uFEFFfoo:expected:<[66 6f 6f]> but was:<[ef bb bf 66 6f 6f]>, with assertions on and off.
More files, environment, full output155 words
Copy the file into lucene/suggest/src/test/org/apache/lucene/search/suggest/ and run the command. The test body is deterministic (no random(), no Directory, no analyzer), though it runs under Lucene's randomized test framework; pass -Ptests.asserts explicitly, because by default the build picks it from the seed. With the file added, :lucene:suggest:check -x test passes. PlainTextDictionary(Path/InputStream) has the same defect and the same fix; this repro shows the FileDictionary entry point only. The test is the suggested regression test as it stands.
| lucene | main 645d4fe14a20 (gradle); the same defect in every release since 4.0.0-BETA |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
./gradlew :lucene:suggest:test --tests "org.apache.lucene.search.suggest.TestFileDictionaryUtf8Bom" -Ptests.seed=DEADBEEF -Ptests.asserts=true
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true (the same with false)
TestFileDictionaryUtf8Bom > testFirstEntryAfterByteOrderMark FAILED
    java.lang.AssertionError: expected:<[66 6f 6f]> but was:<[ef bb bf 66 6f 6f]>
        at org.apache.lucene.search.suggest.TestFileDictionaryUtf8Bom.testFirstEntryAfterByteOrderMark(TestFileDictionaryUtf8Bom.java:29)
1 test completed, 1 failed

# with the recommended fix, assertions on and off:
:lucene:suggest:test (SUCCESS): 1 test
BUILD SUCCESSFUL- These constructors decode the bytes themselves, so the caller cannot drop the mark inside them.
- Lucene's word-list line loader has skipped a leading mark on purpose since 2010, and the hunspell equivalent was filed under Bug fixes.
- No javadoc, test or CHANGES entry says these dictionaries keep a mark (the javadoc makes no promise either way).
The full argument212 words
- The constructors own the decoding. With the
InputStreamandPathconstructors the caller never sees characters: Lucene picks the charset (FileDictionary.java:107,PlainTextDictionary.java:50, 59). Dawid Weiss's view on LUCENE-7785 (2017, about a char-filter mapping) points to exactly that step: "if you have a byte order mark in your character input (reader) then your conversion from bytes is screwed up somewhere before". A caller can only work around it outside these constructors: skip the three bytes on the stream first, or decode the file and use aReaderconstructor. - Lucene's other user-file loaders skip it on purpose. SOLR-1865 (2010, Robert Muir's patch) added the skip with the CHANGES entry "SolrResourceLoader.getLines ignores Byte Order Markers (BOMs) at the beginning of input files, these are often created by editors such as Windows Notepad"; it now lives in
WordlistLoader.getLines(WordlistLoader.java:302-304). "LUCENE-5505: HunspellStemFilter ignores BOM markers in dictionaries" is listed under Bug fixes in 4.8.0. - Valid input, no documented exclusion. A file with a signature is valid UTF-8, and the strict decoder accepts it. The Unicode BOM FAQ calls an initial BOM a signature. No javadoc, test, CHANGES or MIGRATE entry says these dictionaries keep a mark; upstream
TestFileDictionaryandTestPlainTextDictionarynever feed one. - Silent. Nothing is raised, and printed suggestions look right.
The devil's-advocate check265 words
The checkers built the strongest case for "intended": (a) the javadoc literally holds, because the code does decode UTF-8 and Java's decoder keeps U+FEFF, for compatibility (JDK-4508058, Won't Fix); this "literal UTF-8 contract" reading is the independent GPT-5.6 reviewer's, and its refute pass rated the case strong. (b) The Unicode BOM FAQ advises producers not to write a BOM where the data type is known; in the same spirit Uwe Schindler wrote on SOLR-1860 (2010) "If it's documented to be UTF-8, its clear what you have to provide". (c) Michael Busch closed LUCENE-1413 (2009, PlainTextDictionary and UTF-8 files) as Invalid with the advice to pass a decoding Reader. (d) In the 2010 solr-user thread behind SOLR-1865, Chris Hostetter asked whether such files should be considered a bug; Robert Muir answered "No.", then proposed ignoring the mark on the first line "to be more user-friendly" (typed Improvement); Jan Høydahl resolved a FileDictionary format question (SOLR-9368, 2016) with a reference-guide change. (e) Lucene is not uniform: WordlistLoader.getWordSet(InputStream) keeps the mark.
Why we think it fails: (a) to (c) are about who supplies the characters; with these constructors Lucene owns the bytes-to-chars step, so the caller cannot drop the mark inside them. (d) shows the project then chose to skip marks in its loaders (Yonik Seeley in the same thread: "we should fix if it's practical to do so, rather than passing the buck"), and LUCENE-5505 filed the hunspell equivalent as a bug fix. (e) shows an inconsistency, not an intent to keep marks. Verdict: a real, low-priority defect; expect "improvement" or a javadoc note as possible answers.
Recommended A. Skip one leading U+FEFF in the four constructors that decode UTF-8 themselves
Skip one leading U+FEFF in the four constructors that decode UTF-8 themselves: on the first read, mark(1), read one character, and reset() unless it was U+FEFF (WordlistLoader.getLines skips a leading mark too). Reader constructors are unchanged. Validated: the repro, the closest suites and all of :lucene:suggest:test pass, and so does the module's format and lint check.
     private FileIterator() throws IOException {
+      if (skipBom) {
+        // skip an initial UTF-8 byte order mark, as WordlistLoader.getLines does
+        skipBom = false;
+        in.mark(1);
+        if (in.read() != '\uFEFF') {
+          in.reset();
+        }
+      }
       line = in.readLine();
All options and trade-offs3 options · 684 words
Option A was applied in a scratch worktree of main 645d4fe14a20 and run through gradle with assertions on and off; the stock runs used a second scratch worktree of the same commit, and both were removed afterwards. Options B and C were not run.
A. Skip one leading U+FEFF in the four constructors that decode UTF-8 themselves (validated by the checks) (recommended)
A skipBom flag is set only by FileDictionary(InputStream, String) (which FileDictionary(InputStream) delegates to), PlainTextDictionary(Path) and PlainTextDictionary(InputStream). On the first iteration the reader does in.mark(1), reads one character, calls in.reset() unless it was U+FEFF, and clears the flag. +23 lines over the two files; the snippet shows the FileDictionary half, and PlainTextDictionary.FileIterator.next() gets the same block.
The skip happens at the first iteration, not in the constructor, because FileDictionary(InputStream) and PlainTextDictionary(InputStream) do not declare IOException. Files without a mark, and every Reader constructor, behave as before; a file that holds only the mark gives no entry. This is the hunt's fix sketch with one behavioural change: the FileDictionary flag is cleared after the first skip (the sketch kept it final), so a second getEntryIterator() on a partly read dictionary cannot drop a U+FEFF that starts a later line. It also drops the sketch's explicit this.skipBom = false; in FileDictionary(Reader, String), redundant once the field is not final. The one-test repro exercises only the FileDictionary half; the PlainTextDictionary half was validated with the hunt's 4-test check.
     private FileIterator() throws IOException {
+      if (skipBom) {
+        // skip an initial UTF-8 byte order mark, as WordlistLoader.getLines does
+        skipBom = false;
+        in.mark(1);
+        if (in.read() != '\uFEFF') {
+          in.reset();
+        }
+      }
       line = in.readLine();
Trade-offs
- A caller that decodes the file itself and passes a
Readerstill gets the glued mark. That is in line with Dawid Weiss's remark on LUCENE-7785 that a mark in aReadermeans the conversion from bytes went wrong before, and with Uwe Schindler's note on SOLR-1860 that Lucene'sReader-level stopword parser "does not care about encodings at all"; but it leaves Solr'scharacterEncoding-without-fieldTypepath and itsFileDictionaryFactory, which pass aReader, uncovered. - Like
getLines, it cannot tell a byte order mark from a file whose first character is meant as ZERO WIDTH NO-BREAK SPACE (not a realistic dictionary entry). - The four javadoc notes could add "a leading byte order mark is skipped". No CHANGES entry is drafted.
What the checks validated
- Gradle in a scratch worktree of main
645d4fe14a20, seed DEADBEEF, assertions on and off: the repro alone fails stock and passes with the fix. - The repro, a 4-test
PlainTextDictionarycheck from the hunt (thePathandInputStreamconstructors, aSpellChecker, a no-mark control; not part of the repro) and the upstreamTestFileDictionary,TestPlainTextDictionaryandTestSpellChecker: 5 classes, 17 tests; stock 4 failures, with the fix 0, each way. - All of
:lucene:suggest:testwith the fix, assertions on: 33 classes (31 upstream), 241 tests, 7 skipped, 0 failures. :lucene:suggest:check -x test(google-java-format, ecjLint, forbiddenApis) passes with the fix and the repro added.- Earlier, the hunt's sketch in the repro harness: the finder's 11 tests, an independent 14-test JUnit and the 12 upstream tests pass, and the bounded-exhaustive sweep reports 0 mismatches.
Set the flag in the Reader constructors too. WordlistLoader.getLines is no precedent for this: it takes an InputStream and decodes it itself (WordlistLoader.java:297-299), and WordlistLoader's Reader methods do not skip a mark.
Trade-offs
Also covers Solr's characterEncoding path and FileDictionaryFactory, but a Reader whose text really starts with U+FEFF loses it, against the committers' remarks that Reader-level parsers do not deal with encodings; the Reader behaviour is outside this report's claim.
Add to the four "content is treated as UTF-8" notes: "supply UTF-8 without a byte order mark".
Trade-offs
The smallest change and a plausible maintainer answer (SOLR-9368 was resolved with a documentation change), but files that editors save with a mark still lose their first entry silently.
Solr's file-based spell checker reaches PlainTextDictionary(InputStream) only when neither fieldType nor characterEncoding is set. Its documented example sets fieldType, so it reads the file with WordlistLoader.getLines, which skips the mark; characterEncoding alone takes the Reader constructor, which this report does not claim (read, not run).
A bounded-exhaustive metamorphic sweep of the public dictionary API: every file of 1 to 3 lines over a small alphabet must load the same with and without a leading byte order mark. On the decoding constructors 81,080 of 81,080 checks differed; all 158,732 controls held, and with the fix none differed.
The method in full203 words
- First signal. The hunt's round-14 planner carried the kept-BOM hypothesis of four earlier findings (word lists, ICU rule files, Japanese and Korean user dictionaries, synonyms files) over to the suggest dictionaries by reading the code: constructors that decode UTF-8 themselves versus
WordlistLoader.getLines. Its executed differential probe failed 8 of 16 checks, every row with a mark. - Method (semi-formal): bounded-exhaustive metamorphic sweep on the stock main jars, public API only. Law: loading
EF BB BF+ F gives the same entries (and lookups) as loading F. Inputs: every file of 1 to 3 lines over 21FileDictionaryand 7PlainTextDictionaryline kinds with 1- to 4-byte characters, LF and CRLF, with and without a trailing line end, plus lookups through WFST, FST, TST andAnalyzingSuggester. - Signal. 81,080 of 81,080 checks on the decoding constructors mismatch (entries 80,976, mark-only files 4, lookups 100); all 158,732 controls hold (CRLF vs LF, trailing line end, InputStream vs Reader without a mark); with the fix shadowed, 0 mismatches. The same on branch_10_6. The
Readerconstructors also differ (79,383 checks) and are not claimed. - The finder then wrote a public-API JUnit (11 tests), traced the history to 2012, and the repro was later minimized to one test.
No prior report found (searched 2026-10-28 and 2026-10-29: GitHub issues, PRs and commits, JIRA, the Lucene and Solr lists, downstream trackers, Stack Exchange, the web and the changed files of all 414 open PRs). Closest: SOLR-1865 (2010), which made the line loader skip the mark.
Searches5 searches
Read and not this bug: LUCENE-1413 / #2487 (2008, a platform-charset request for PlainTextDictionary, no BOM, closed Invalid before these constructors decoded UTF-8); LUCENE-763 / #1838 (a first-word loss in LuceneDictionary from an iterator off-by-one, fixed 2007); a 2023 users@solr thread and Stack Overflow 79252187 (2024), spelling complaints whose reported output does not fit a BOM (a local check of the 2023 case gives the opposite pattern with a mark; their file was not available); SOLR-9368 (2016, a FileDictionary format question answered with a reference-guide change). Lucene.NET #1027 says the port's decoding reader ignores a BOM (Paul Irwin's statement, not run here). Tracking issue #16937 and the dev@ thread do not mention it, and no maintainer has triaged it. Gaps: keyword search only (GitHub does not index U+FEFF itself), Stack Overflow read through its API, the list archive stores only the start of each mail, private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (the finder's run and three follow-up variants) | 2026-10-28 and 2026-10-29 | classes + BOM terms, symptoms, Solr word-list loaders: 224 distinct hits in the finder's run (0 high) and 153 queries in the variants, over GitHub issues, PRs and commits, downstream repositories, the Lucene and Solr lists and the JIRA archive | no report |
| GitHub (manual) | 2026-10-29 | apache/lucene, lucene-solr, solr, lucenenet, elasticsearch, OpenSearch and all of GitHub (FileDictionary, PlainTextDictionary, "byte order mark", FEFF, BOM); the changed files of all 414 open apache/lucene PRs; 12 PRs created and 60 issues and PRs updated since 2026-10-27 | no report; no open PR touches either file |
| JIRA (LUCENE, SOLR, LUCENENET) and JDK-4508058 | 2026-10-29 | JQL queries; SOLR-1865, SOLR-1860, LUCENE-1413, LUCENE-5337, LUCENE-6486, LUCENE-5505 read in full | only precedents (SOLR-1865, LUCENE-5505) and the 2008 platform-charset issue |
| Mailing lists | 2026-10-29 | solr-user@, users@solr, dev@solr, java-user@, dev@lucene, issues@; threads read | only the 2010 solr-user thread behind SOLR-1865 and a non-matching 2023 users@solr thread |
| Web and Stack Exchange | 2026-10-29 | web searches and the Stack Exchange API (search and question reads) | no report; one non-matching spell-checker question |
Since 4.0.0-BETA (2012): LUCENE-4199 (d69c73c0277) made these constructors decode UTF-8 themselves, with no BOM skip. Before, they used the platform charset, which showed the same mark on a UTF-8 platform, so no release ever skipped it. Executed on 16 releases from 3.6.2 to 10.5.2, the 10.6.0 release commit and main. Never fixed.
Versions tested8 rows
Introduced by LUCENE-4199, the project-wide removal of default-charset APIs (commit d69c73c0277 "LUCENE-4199: fix more default charset uses", Robert Muir, 2012-07-07; merged to trunk as e3813f80300 and to branch_4x as f7941ee03a3 by Uwe Schindler on 2012-07-09; migrated issue #5271; Subversion era, no PR). It replaced new InputStreamReader(dictFile) and new FileReader(file) with IOUtils.getDecodingReader(..., UTF_8) in FileDictionary(InputStream), PlainTextDictionary(InputStream) and PlainTextDictionary(File), and added no BOM skip; the issue's 32 comments never mention a BOM. The javadoc "NOTE: content is treated as UTF-8" followed in d4aace10381 (Robert Muir, 2012-09-21, first in 4.0.0).
Later constructors, same decoding. FileDictionary(InputStream, String) (LUCENE-5337, 4.7.0); PlainTextDictionary(Path) replaced (File) (LUCENE-5945, 5.0.0).
Before. 4.0.0-ALPHA and 3.x used the JVM default charset: with a UTF-8 default they show the same U+FEFF, with ISO-8859-1 they misdecode the whole file. LUCENE-4199 made the kept mark independent of the platform; it is not a regression of the symptom.
Never fixed. git log --all -G 'FEFF|BOM|byte order' over every path these files ever had returns nothing. The last commits on them, ae82130c71b (#15115, 2025-08-22) and b85f030c6cc (#15134, 2025-10-09), are cleanups.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the one-test repro fails through gradle, assertions on and off |
main a9779ef3c193 | affected | the finder's JUnit fails 9 of 11 and an independent JUnit 8 of 14 (assertions on and off); the sweep: 81,080 of 81,080 checks differ |
branch_10_6 4ae946e5a9b9 (10.6.0) | affected | the sweep: 81,080 of 81,080 checks differ (assertions off); the probe on the 10.6 RC jars too; 10.6.0 was released from this commit |
| 10.5.2, 9.12.3 | affected | both JUnits fail the same (assertions off) |
| 10.0.0, 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5, 5.0.0, 4.10.4, 4.7.0, 4.6.1, 4.0.0 | affected | main() probe: every decoding constructor keeps the mark (4.7.0 adds FileDictionary(InputStream, String), 5.0.0 PlainTextDictionary(Path)) |
| 4.0.0-BETA | first | the first release that decodes UTF-8 itself: keeps the mark, also with ISO-8859-1 as the platform charset |
| 4.0.0-ALPHA, 3.6.2 | platform charset | the same U+FEFF with a UTF-8 platform default; with ISO-8859-1 the whole file is misdecoded instead |
the fix on main 645d4fe14a20 | not affected | the repro and the closest suites pass (assertions on and off), and all 241 tests of :lucene:suggest:test |
An independent reproducer, reviews by a reviewer from another model family, a devil's advocate, an adjudication, a re-run and a credibility audit all re-ran or re-read it; every executed check reproduced it. This doc re-ran the one-test repro through gradle on 645d4fe14a20 and validated the fix.
Checks and verdicts474 words
The cross-model reviews were reading-only (they could not run code); every claim they read was executed by the other checks. The hunt's checks ran on main a9779ef3c193, whose suggest module equals 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model review, intended lens | real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: root cause agrees, inputs in contract, intended-behaviour case moderate. It pointed out that WordlistLoader.getWordSet(InputStream) keeps a mark too, which the finder confirmed by execution. A separate re-run failed 9 of 11. |
| Independent reproducer | real | Own 14-test JUnit with other words, weights, delimiter and lookups: 8 of 14 fail on main (assertions on and off), 10.5.2 and 9.12.3, including a mark-only file that gives one entry; all 6 no-mark controls pass. |
| Cross-model review, refute lens | not real (medium), partly procedural | The same OpenAI GPT-5.6 reviewer, reading only: "not real" partly because it could not run anything; it agreed with the root cause and found the inputs legal, and rated the intended-behaviour case strong (the javadoc promises only UTF-8 decoding). A separate run and a verifier re-ran the finder's JUnit: 9 of 11 fail. |
| Intended-behaviour devil's advocate | real (Low, medium) | Built the strongest works-as-designed case and rejected it; raised Solr's documented example as a caveat (its reason was corrected later: the example takes the getLines branch). The finder's JUnit fails 9 of 11 on main (assertions on and off) and 10.5.2. |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's JUnit with a new seed on a clean checkout: 8 of 14 fail with assertions on and off, exactly the tests fed a mark. |
| Registration check and credibility audit | reproduces; keep | Fresh seeds: the finder's JUnit 9 of 11 fail, the independent reproduction's 8 of 14; with the fix sketch shadowed 11 of 11 and 14 of 14 pass. The audit re-ran both again and re-read the code: keep. |
| Repro minimization | one test, fails | Reduced to one FileDictionary(InputStream) test on 645d4fe14a20: fails with assertions on and off (two seeds), passes with the fix shadowed. |
| Fix validation (this doc) | fix validated | Gradle in a scratch worktree of 645d4fe14a20: the repro fails stock and passes with option A, assertions on and off; with the fix the closest suites and all 241 tests of :lucene:suggest:test pass, and :lucene:suggest:check -x test passes. |
| Fact checks of this doc | reproduces; text corrected | An independent fact check re-ran the doc's gradle command on 645d4fe14a20 (fails with assertions on and off and with a second seed) and its own probe, which reproduces every row of the table and, with the fix, makes every marked row match its no-mark control. A reviewer from another model family (OpenAI GPT-5.6, reading only) checked the text, and a diagram check read the frames. Their corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 471 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,431 words
- Registry title
- FileDictionary(InputStream) and PlainTextDictionary(Path/InputStream) decode the file as UTF-8 themselves but keep a leading byte order mark, so the file's first entry carries an invisible U+FEFF: prefix suggesters never suggest it and SpellChecker.exist() does not find it
- Area
- suggest / text-file dictionaries (FileDictionary feeding Lookup.build, PlainTextDictionary feeding SpellChecker.indexDictionary)
- Priority
- Low, rank 501: A suggester or spell-checker file saved with a BOM silently loses its first entry in the opt-in suggest module, which is loaded more often than snowball-format word files.
- Impact class
- silent wrong results
- Impact note
- Hits applications that build a suggester from FileDictionary(InputStream[, String]) or index a SpellChecker from PlainTextDictionary(Path) or PlainTextDictionary(InputStream) with a text file that an editor or export tool saved as UTF-8 with a byte order mark: only the first entry of each such file goes wrong, silently (the prefix suggesters never return it, AnalyzingSuggester returns it with an invisible U+FEFF, SpellChecker.exist() says the first word is missing, and a file that holds only the mark yields one phantom entry); the public constructors are used with no special setting, no scale is needed, and every release since 4.0.0 has it; the Reader constructors, where the caller decodes, are not claimed, and Solr's documented file-based spell checker example sets characterEncoding and so takes that Reader path.
- Summary
- You build a suggester or a spell checker from a UTF-8 text file whose first line is 'foo<TAB>5' (or just 'foo') but which an editor saved with a byte order mark (the bytes EF BB BF), passing it to FileDictionary(InputStream) or PlainTextDictionary(Path or InputStream), whose javadoc says 'NOTE: content is treated as UTF-8', and you expect the same entries as from the same file without the mark, because the mark is only an encoding signature and Lucene's own line loaders skip it (WordlistLoader.getLines, SOLR-1865; hunspell, LUCENE-5505). Instead these constructors decode the bytes with Java's UTF-8 decoder, which returns the mark as the character U+FEFF, and nothing removes it, so the first entry becomes '\uFEFFfoo': WFSTCompletionLookup, FSTCompletionLookup and TSTLookup return nothing for lookup("fo"), AnalyzingSuggester returns '\uFEFFfoo', and a SpellChecker reports exist("foo") = false. No error is raised and only the first line is affected.
- Introduced
- d69c73c0277acc00ed5f220b46070ee1996c09d7 (LUCENE-4199 'fix more default charset uses', svn r1358555 on the lucene4199 work branch, author Robert Muir; merged to trunk as e3813f80300b (r1359202) and to branch_4x as f7941ee03a3a (r1359229) by Uwe Schindler on 2012-07-09; migrated issue apache/lucene#5271 'Add ANT tool to track/disallow forbidden method invocations'; Subversion era, no pull request) [read: full-history clone; boundary executed]. It replaced the platform-charset readers in FileDictionary(InputStream), PlainTextDictionary(InputStream) and PlainTextDictionary(File) with IOUtils.getDecodingReader(..., UTF-8), so from then on Lucene itself decodes UTF-8 but nothing skips the UTF-8 signature; the issue's 32 comments never mention a BOM. Later constructors carry the same decoding: FileDictionary(InputStream, String) (LUCENE-5337, 4.7.0) and PlainTextDictionary(Path) (LUCENE-5945, 5.0.0). The javadoc 'NOTE: content is treated as UTF-8' came with d4aace10381 / 73693e1a9f7 (Robert Muir, 2012-09-21, first in 4.0.0). Not a regression of the symptom: before LUCENE-4199 the constructors used the JVM default charset, which showed the same U+FEFF when that default was UTF-8 and misdecoded the whole file otherwise (the platform-charset problem of LUCENE-1413). (2012-07-07 (author date of d69c73c0277 on the work branch; trunk and branch_4x merges 2012-07-09))
- First affected version
- 4.0.0-BETA [exec] (pre-release, tag 2012-08-10; with file.encoding=ISO-8859-1 it still keeps U+FEFF and decodes an e-acute correctly, so the defect no longer depends on the platform); first final release 4.0.0 [exec]. Last unaffected as claimed: 4.0.0-ALPHA and the 3.x line (3.6.2) [exec], which used the JVM default charset: with a UTF-8 default they show the same U+FEFF, with ISO-8859-1 they misdecode the whole file instead.
- Affected versions
- Every release from 4.0.0-BETA to 10.5.2, 10.6.0 (released 2026-10-29; branch_10_6 4ae946e5a9b9) and main a9779ef3c193 [exec: the follow-up's main() probe on 4.0.0-BETA, 4.0.0, 4.6.1, 4.7.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, the 10.6 RC jars and main (4.0.0-BETA, 4.0.0, 10.5.2 and main also with ISO-8859-1 as the platform charset); the finder's JUnit fails 9 of 11 on main (-ea and -da), 10.5.2 and 9.12.3 (-da); the independent reproduction's JUnit fails 8 of 14 on main (-ea and -da), 10.5.2 and 9.12.3 (-da); the finder's sweep on branch_10_6 (-da); releases in between read: code unchanged]. Upstream main 645d4fe14a20 (2026-10-28) has no commit on either file after ae82130c71b1 (2025-08-22) and b85f030c6cce (2025-10-09).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-28, read-only; the prior-report record, verdict new): scripted prior-report searches (224 distinct hits in the finder's run, 0 high) and the follow-up's three query sets over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, solr-user@ and users@solr, the LUCENE, SOLR and LUCENENET JIRA archives and the web; manual GitHub searches over apache/lucene, apache/lucene-solr, apache/solr, Lucene.NET and all of GitHub ('FileDictionary', 'PlainTextDictionary', 'byte order mark', FEFF, BOM); Stack Exchange; the changed files of all 414 open apache/lucene PRs (none touches either file); an adjudication refresh and a recheck (12 apache/lucene PRs created since 2026-10-27: none changes a file under lucene/suggest; 60 issues and PRs updated since then: none names a BOM or these classes; 'repo:apache/lucene BOM updated:>=2026-10-27' 0 hits; upstream main 645d4fe14a20 is 6 commits ahead and touches no suggest file). Related only: SOLR-1865 (2010, the getLines BOM skip; the precedent), LUCENE-5505 / #6568 (hunspell BOM skip, 4.8.0 Bug fixes), LUCENE-1413 / #2487 (2008, platform-charset PlainTextDictionary; closed Invalid with the advice to pass a decoding Reader), LUCENE-4199 / #5271 (the introducing change; no BOM discussion), #5553 and #9020 (open SpellChecker javadoc issues), #12937 (build check against BOMs in Lucene's own sources), and two Solr user reports of first-word or correctlySpelled problems (users@solr 2023-01-12, Stack Overflow 79252187) whose reported output does not fit a BOM.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28) through gradle in scratch worktrees (removed afterwards), seed DEADBEEF, assertions on and off: stock, the one-test repro fails; with the recommended fix it passes, together with a 4-testPlainTextDictionarycheck and the upstreamTestFileDictionary,TestPlainTextDictionaryandTestSpellChecker(17 tests), all of:lucene:suggest:test(241 tests, assertions on) and:lucene:suggest:check -x test. Through the repro harness: the one-test repro on645d4fe14a20(assertions on and off, fix shadowed); the finder's 11-test JUnit and an independent 14-test JUnit on maina9779ef3c193(assertions on and off), 10.5.2 and 9.12.3; a bounded-exhaustive sweep ona9779ef3c193and branch_10_64ae946e5a9b9(the commit 10.6.0 was released from); a portablemain()probe on 16 releases and pre-releases from 3.6.2 to 10.5.2, the 10.6 RC jars and main (some also with ISO-8859-1 as the platform charset). The suggest module,WordlistLoader,IOUtilsand hunspell'sDictionaryare identical ata9779ef3c193and645d4fe14a20. OpenJDK 25.0.3, Linux aarch64 (the only platform run).
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:73-81 (FileDictionary(InputStream), 'NOTE: content is treated as UTF-8', delegates with DEFAULT_FIELD_DELIMITER), :100-109 (FileDictionary(InputStream, String): same note; new BufferedReader(IOUtils.getDecodingReader(dictFile, StandardCharsets.UTF_8))), :127-150 (FileIterator(): line = in.readLine(); fields[0] of the first line copied unchanged), :83-98 (Reader constructors, context, not claimed)lucene/suggest/src/java/org/apache/lucene/search/spell/PlainTextDictionary.java:44-60 (PlainTextDictionary(Path): Files.newBufferedReader(path, UTF_8); PlainTextDictionary(InputStream): IOUtils.getDecodingReader(dictFile, UTF_8); both 'NOTE: content is treated as UTF-8'), :62-65 (Reader constructor, context), :76-90 (next(): every line, the first included, copied unchanged)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304 (getLines: '// skip initial bom marker')lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:246 (affix stream: maybeConsume(affixStream, BOM_UTF8)) and :351-352 ('ignore any BOM marker on first line')
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:73-81, 100-109 (decoding constructors, 'NOTE: content is treated as UTF-8' at :77, :104), :127-149 (FileIterator: readLine :128, split :133, copyChars(fields[0]) :138/:142/:145) @ 645d4fe14a20lucene/suggest/src/java/org/apache/lucene/search/spell/PlainTextDictionary.java:44-60 (Path and InputStream constructors, notes :47, :56, decoding :50, :59), :76-97 (next(): readLine and copyChars :84-86) @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/util/IOUtils.java:192-199 (getDecodingReader) @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:33 (@lucene.internal), :88, :102-103 (getWordSet(InputStream)), :297-314 and :302-304 (getLines, 'skip initial bom marker') @ 645d4fe14a20lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:246, :351-354 @ 645d4fe14a20git diff a9779ef3c193 645d4fe14a20 over lucene/suggest, WordlistLoader.java, IOUtils.java and hunspell Dictionary.java: empty (this doc's step)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304 @ 645d4fe14a20
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:79, 106 (constructors without throws IOException) @ 645d4fe14a20; PlainTextDictionary.java:58 @ 645d4fe14a20
- TestFileDictionaryUtf8Bom.java (one test):
repro/LFV-990/src/org/apache/lucene/search/suggest/TestFileDictionaryUtf8Bom.java(31 lines)
It is made separately from this text; its numbers come from the executed repro and probe runs on main.
assets/LFV-990/bug.png(471 KB)