The page's "Example Usages" are plain code blocks in the module's javadoc overview; no build step compiles them, so API removals elsewhere never broke the build.
- You copy the "Danish Sorting" example from the analysis-icu overview into a project on Lucene 10.6.0. It indexes
HAT,HUT,HÅT,HØTandHOTand should list them in Danish order. - You expect it to compile, as the page's short token-filter examples (NFC, case folding, accents, Traditional-Simplified) do.
- Instead javac reports 7 errors on 6 lines:
Field.Index(removed in 6.0),new IndexSearcher(dir, true)and theintSortField.STRING(4.0),sort.setSort(9.0),search(query, null, 1000, sort)(6.0) andsearcher.doc(int)(10.0). - The tokenizer, Farsi range and Turkish case examples fail the same way: 4 of 10 blocks and 14 error lines on 10.6.0. On main the Serbian example's comment became a bare sentence, so 5 of 10 blocks and 16 lines fail.
- Renaming alone is not enough: with current names the Danish example compiles but throws
IllegalStateException: unexpected docvalues type NONE, because sorting needs doc values. Rewritten with the current API plus anICUCollationDocValuesField, all 10 blocks compile and the 3 collation examples pass their own checks.
Developers who adopt the opt-in analysis-icu module and copy an example from its overview. Every release since 4.0.0-ALPHA (2012) ships at least 3 broken examples, 4 since 5.0.0. Documentation only: nothing in Lucene runs differently, and the errors are loud at compile time.
Mechanism, terms and numbers574 words
The analysis-icu module overview, the first page of the module's javadoc, shows ten Java blocks under "Example Usages". Four of them call APIs that Lucene removed between 4.0 and 10.0: the tokenizer example (new ICUTokenizer(reader)) and the Farsi range, Danish sort and Turkish case collation examples (Field.Index.ANALYZED, new IndexSearcher(dir, true), QueryParser.setAnalyzeRangeTerms, the Filter-taking search(query, null, n[, sort]), Sort.setSort (new Sort() itself still exists), the int SortField.STRING, IndexSearcher.doc(int)). On main a fifth is broken: a 2025 editorconfig re-indent (#14832) left the Serbian transliteration example's comment as // followed by a bare sentence. Compiled verbatim with the imports and the page's two undeclared names supplied, the page gives 16 error lines in 5 of 10 blocks on main and 14 lines in 4 blocks on 10.6.0; the other blocks compile. The examples were last current on trunk in 2011, so every release since 4.0.0-ALPHA has shipped at least three broken ones. Rewritten with the current API, and with doc values for the Danish sort, all ten compile and the three collation examples pass their own assertions. Nothing in Lucene behaves wrongly; only the page is stale.
lucene/analysis/icu/src/java/overview.html is passed to javadoc as the module overview (RenderJavadocPlugin.java:452-462). Seven sections end with an "Example Usages" heading (overview.html:71, :110, :242, :277, :302, :330, :351) and hold ten Java blocks. Nothing compiles them.
| page line | stale call | gone since | current API |
|---|---|---|---|
| 75 | new ICUTokenizer(reader) | 5.0.0 (LUCENE-5388) | new ICUTokenizer() (ICUTokenizer.java:69) + setReader(reader) |
| 121, 151, 152, 176 | new Field(name, value, Store, Index), Field.Index.ANALYZED / NO | 6.0.0 (LUCENE-4095; deprecated in 4.0) | TextField, StoredField |
| 124, 156, 179 | new IndexSearcher(dir, true) | 4.0.0-ALPHA (LUCENE-3571) | new IndexSearcher(DirectoryReader.open(dir)) (IndexSearcher.java:189) |
| 127 | aqp.setAnalyzeRangeTerms(true) | 7.0.0 (LUCENE-7355) | none: QueryParser builds range bounds with Analyzer.normalize (QueryParserBase.java:550, :556) |
| 135, 160, 182 | search(query, null, n[, sort]) (Filter overloads) | 6.0.0 (deprecated in 5.1, LUCENE-6286) | search(Query, int) (IndexSearcher.java:623), search(Query, int, Sort) (:677) |
| 158 | sort.setSort(...) (the new Sort() on line 157 still exists, Sort.java:54, and compiles) | 9.0.0 (LUCENE-9325) | new Sort(SortField...) (Sort.java:63) |
| 158 | int SortField.STRING | 4.0.0-ALPHA (LUCENE-3219) | SortField.Type.STRING (SortField.java:74) |
| 162 | searcher.doc(int) | 10.0.0 (#11998) | searcher.storedFields().document(int) (IndexSearcher.java:472) |
| 338-339 | //, then the sentence "This filter will map Serbian Cyrillic to Serbian Latin according to BGN rules" as code | main only (#14832) | one // ... line |
The other five blocks (NFC normalization, case folding, search folding, Traditional-Simplified, the Unicode 5.0 filter) compile; on 10.6.0 the Serbian block compiles too.
Sorting by SortField.Type.STRING reads SORTED doc values, and the example indexes the values only as TextField terms. With the names updated and nothing else, it compiles and throws IllegalStateException: unexpected docvalues type NONE for field 'contents' (expected=SORTED). The module's ICUCollationDocValuesField(String, Collator) (ICUCollationDocValuesField.java:50) stores the collation key as a sorted doc value; with it the sort gives the Danish order the example asserts (tracers A, E, B, D, C). vsop-479 made the same doc-values point on #16904 for the java.text copy of this example.
A current-API Farsi range written with the classic QueryParser gets its bounds from Analyzer.normalize, which for ICUCollationKeyAnalyzer returns UTF-8 bytes instead of collation keys: that is the separate code bug LFV-1053. The suggested fix builds the range as a TermRangeQuery over collation keys, as TestICUCollationKeyAnalyzer.java:44-50 does.
Exposure and likelihood132 words
- Who. Readers of the analysis-icu javadoc overview who copy an example. No query, document or index file reaches the page, and the page is not in the runtime jar.
- Default vs opt-in. analysis-icu is an optional module. No configuration or special input is involved.
- Scale. Every example on the page that indexes or searches is broken: the three collation examples in every release since 4.0.0-ALPHA, the tokenizer example since 5.0.0, the Serbian example on main.
- Not obvious to repair. The Danish sort also needs doc values (otherwise an
IllegalStateExceptionat run time), and the QueryParser form of the Farsi range is affected by the separate bug LFV-1053. - Not claimed. Any runtime defect in Lucene. The page leaves
readerandtokenizerundeclared; that is normal for fragments and not part of the claim.
One JUnit class with one test. It holds the 5 failing blocks copied verbatim from the page, compiles each with javax.tools behind a fixed import list and the two names the page leaves undeclared (reader, tokenizer), and lists each error by page line. Nothing in Lucene runs, and nothing is random.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu;

import java.net.URI;
import java.util.LinkedHashSet;
import java.util.List;
import java.util.Locale;
import java.util.Set;
import javax.tools.Diagnostic;
import javax.tools.DiagnosticCollector;
import javax.tools.JavaCompiler;
import javax.tools.JavaFileObject;
import javax.tools.JavaFileObject.Kind;
import javax.tools.SimpleJavaFileObject;
import javax.tools.ToolProvider;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIcuOverviewExamplesCompile extends LuceneTestCase {

  private static final String HEADER =
      """
      import com.ibm.icu.text.*;
      import com.ibm.icu.util.ULocale;
      import java.nio.file.*;
      import org.apache.lucene.analysis.*;
      import org.apache.lucene.analysis.icu.*;
      import org.apache.lucene.analysis.icu.segmentation.ICUTokenizer;
      import org.apache.lucene.document.*;
      import org.apache.lucene.index.*;
      import org.apache.lucene.queryparser.classic.QueryParser;
      import org.apache.lucene.search.*;
      import org.apache.lucene.store.*;
      import static org.junit.Assert.assertEquals;
      class Example {
        java.io.Reader reader;
        Tokenizer tokenizer;
        void example() throws Exception {
      """;

  private static final int[] OVERVIEW_HTML_FIRST_LINE = {74, 114, 141, 169, 338};
  private static final String[] OVERVIEW_HTML_BLOCK = {
    """
      // This tokenizer will work well in general for most languages.
      Tokenizer tokenizer = new ICUTokenizer(reader);
    """,
    """
      Collator collator = Collator.getInstance(new ULocale("ar"));
      ICUCollationKeyAnalyzer analyzer = new ICUCollationKeyAnalyzer(collator);
      Path indexPath = Files.createTempDirectory("tempIndex");
      Directory dir = FSDirectory.open(indexPath);
      IndexWriter writer = new IndexWriter(dir, new IndexWriterConfig(analyzer));
      Document doc = new Document();
      doc.add(new Field("content", "\\u0633\\u0627\\u0628",
                        Field.Store.YES, Field.Index.ANALYZED));
      writer.addDocument(doc);
      writer.close();
      IndexSearcher is = new IndexSearcher(dir, true);

      QueryParser aqp = new QueryParser("content", analyzer);
      aqp.setAnalyzeRangeTerms(true);

      // Unicode order would include U+0633 in [ U+062F - U+0698 ], but Farsi
      // orders the U+0698 character before the U+0633 character, so the single
      // indexed Term above should NOT be returned by a ConstantScoreRangeQuery
      // with a Farsi Collator (or an Arabic one for the case when Farsi is not
      // supported).
      ScoreDoc[] result
        = is.search(aqp.parse("[ \\u062F TO \\u0698 ]"), null, 1000).scoreDocs;
      assertEquals("The index Term should not be included.", 0, result.length);
    """,
    """
      Analyzer analyzer
        = new ICUCollationKeyAnalyzer(Collator.getInstance(new ULocale("da", "dk")));
      Path indexPath = Files.createTempDirectory("tempIndex");
      Directory dir = FSDirectory.open(indexPath);
      IndexWriter writer = new IndexWriter(dir, new IndexWriterConfig(analyzer));
      String[] tracer = new String[] { "A", "B", "C", "D", "E" };
      String[] data = new String[] { "HAT", "HUT", "H\\u00C5T", "H\\u00D8T", "HOT" };
      String[] sortedTracerOrder = new String[] { "A", "E", "B", "D", "C" };
      for (int i = 0 ; i < data.length ; ++i) {
        Document doc = new Document();
        doc.add(new Field("tracer", tracer[i], Field.Store.YES, Field.Index.NO));
        doc.add(new Field("contents", data[i], Field.Store.NO, Field.Index.ANALYZED));
        writer.addDocument(doc);
      }
      writer.close();
      IndexSearcher searcher = new IndexSearcher(dir, true);
      Sort sort = new Sort();
      sort.setSort(new SortField("contents", SortField.STRING));
      Query query = new MatchAllDocsQuery();
      ScoreDoc[] result = searcher.search(query, null, 1000, sort).scoreDocs;
      for (int i = 0 ; i < result.length ; ++i) {
        Document doc = searcher.doc(result[i].doc);
        assertEquals(sortedTracerOrder[i], doc.getValues("tracer")[0]);
      }
    """,
    """
      Collator collator = Collator.getInstance(new ULocale("tr", "TR"));
      collator.setStrength(Collator.PRIMARY);
      Analyzer analyzer = new ICUCollationKeyAnalyzer(collator);
      Path indexPath = Files.createTempDirectory("tempIndex");
      Directory dir = FSDirectory.open(indexPath);
      IndexWriter writer = new IndexWriter(dir, new IndexWriterConfig(analyzer));
      Document doc = new Document();
      doc.add(new Field("contents", "DIGY", Field.Store.NO, Field.Index.ANALYZED));
      writer.addDocument(doc);
      writer.close();
      IndexSearcher is = new IndexSearcher(dir, true);
      QueryParser parser = new QueryParser("contents", analyzer);
      Query query = parser.parse("d\\u0131gy");   // U+0131: dotless i
      ScoreDoc[] result = is.search(query, null, 1000).scoreDocs;
      assertEquals("The index Term should be included.", 1, result.length);
    """,
    """
      //
      This filter will map Serbian Cyrillic to Serbian Latin according to BGN rules
      TokenStream tokenstream = new ICUTransformFilter(tokenizer, Transliterator.getInstance("Serbian-Latin/BGN"));
    """
  };

  public void testOverviewExamplesCompile() throws Exception {
    JavaCompiler javac = ToolProvider.getSystemJavaCompiler();
    String classpath = System.getProperty("java.class.path");
    List<String> opts = List.of("-cp", classpath, "-d", createTempDir().toString(), "-proc:none");
    int headerLines = (int) HEADER.lines().count();
    Set<String> errors = new LinkedHashSet<>();
    for (int b = 0; b < OVERVIEW_HTML_BLOCK.length; b++) {
      String unit = HEADER + OVERVIEW_HTML_BLOCK[b] + "  }\n}\n";
      JavaFileObject src =
          new SimpleJavaFileObject(URI.create("string:///Example.java"), Kind.SOURCE) {
            @Override
            public CharSequence getCharContent(boolean ignoreEncodingErrors) {
              return unit;
            }
          };
      DiagnosticCollector<JavaFileObject> diags = new DiagnosticCollector<>();
      javac.getTask(null, null, diags, opts, null, List.of(src)).call();
      for (Diagnostic<? extends JavaFileObject> d : diags.getDiagnostics()) {
        if (d.getKind() == Diagnostic.Kind.ERROR) {
          long line = d.getLineNumber() - headerLines - 1;
          String where =
              line < 0 ? "test header" : "overview.html:" + (OVERVIEW_HTML_FIRST_LINE[b] + line);
          errors.add(where + ": " + d.getMessage(Locale.ROOT).lines().limit(2).toList());
        }
      }
    }
    // expected: the overview.html "Example Usages" blocks copied above compile; actual: errors
    assertTrue(
        "overview.html examples fail to compile:\n" + String.join("\n", errors),
        errors.isEmpty());
  }
}
# $LUCENE: a built checkout; $REPRO: the test's source root; $DEPS: icu4j 78.3, junit 4.13.2, randomizedtesting-runner 2.9.2, hamcrest 3.0
V=11.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar:$LUCENE/lucene/analysis/icu/build/libs/lucene-analysis-icu-$V.jar:$LUCENE/lucene/queryparser/build/libs/lucene-queryparser-$V.jar:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar:$LUCENE/lucene/sandbox/build/libs/lucene-sandbox-$V.jar:$DEPS
javac -nowarn -d out -cp "$CP" $REPRO/org/apache/lucene/analysis/icu/TestIcuOverviewExamplesCompile.java
java -ea -Dtests.seed=DEADBEEF -cp "out:$CP" org.junit.runner.JUnitCore org.apache.lucene.analysis.icu.TestIcuOverviewExamplesCompile
# assertions off, same result: java -da -Dtests.asserts=false ...
- Expected
- Every copied example compiles, like the page's other 5 examples.
- Observed
- 17 compile errors on 16 page lines (
overview.html:75, 121, 124, 127, 135, 151, 152, 156, 158, 160, 162, 176, 179, 182, 339, 340), with assertions on and off, on main and on the 10.6.0 jars.
More files, environment, full output387 words
The blocks were checked line by line against 645d4fe14a20 (only < is rendered as <). Each block is compiled on its own, because javac skips attribution of a unit with a syntax error (the Serbian block).
The command runs outside gradle because the analysis-icu test classpath has no queryparser, which the Farsi and Turkish blocks use. $DEPS is icu4j 78.3, junit 4.13.2, randomizedtesting-runner 2.9.2 and hamcrest 3.0 (the versions in gradle/libs.versions.toml).
10.6.0's own page (byte-identical to 10.5.2's), compiled against the 10.6.0 jars, fails 4 of 10 blocks with 14 error lines; its Serbian block is the older, valid /** */ form.
No separate regression test is suggested: Lucene has no harness that compiles overview examples (open LUCENE-8488, #9534, asks for one in general). To check a fixed page, compile its blocks the same way (see Suggested fix).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the 10.6.0 release jars give the same 16 lines |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (a compile-only check; the platform cannot change the result) |
# the command above, main 645d4fe14a20, seed DEADBEEF, -ea (-da identical)
java.lang.AssertionError: overview.html examples fail to compile:
overview.html:75: [incompatible types: java.io.Reader cannot be converted to org.apache.lucene.analysis.icu.segmentation.ICUTokenizerConfig]
overview.html:121: [cannot find symbol,   symbol:   variable Index]
overview.html:124: [no suitable constructor found for IndexSearcher(org.apache.lucene.store.Directory,boolean), ...]
overview.html:127: [cannot find symbol,   symbol:   method setAnalyzeRangeTerms(boolean)]
overview.html:135: [no suitable method found for search(org.apache.lucene.search.Query,<nulltype>,int), ...]
overview.html:151: [cannot find symbol,   symbol:   variable Index]
overview.html:152: [cannot find symbol,   symbol:   variable Index]
overview.html:156: [no suitable constructor found for IndexSearcher(org.apache.lucene.store.Directory,boolean), ...]
overview.html:158: [cannot find symbol,   symbol:   variable STRING]
overview.html:158: [cannot find symbol,   symbol:   method setSort(org.apache.lucene.search.SortField)]
overview.html:160: [no suitable method found for search(org.apache.lucene.search.Query,<nulltype>,int,org.apache.lucene.search.Sort), ...]
overview.html:162: [cannot find symbol,   symbol:   method doc(int)]
overview.html:176: [cannot find symbol,   symbol:   variable Index]
overview.html:179: [no suitable constructor found for IndexSearcher(org.apache.lucene.store.Directory,boolean), ...]
overview.html:182: [no suitable method found for search(org.apache.lucene.search.Query,<nulltype>,int), ...]
overview.html:339: [';' expected]
overview.html:340: [';' expected]
FAILURES!!!
Tests run: 1,  Failures: 1
("..." stands for javac's second message line, which names the first candidate javac lists as not applicable)

# 10.6.0's own page against the 10.6.0 jars
BLOCK L73 [Tokenizing multilanguage text]: FAIL (1 errors)
BLOCK L115 [Farsi Range Queries]: FAIL (4 errors)
BLOCK L142 [Danish Sorting]: FAIL (7 errors)
BLOCK L170 [Turkish Case Normalization]: FAIL (3 errors)
BLOCK L246 ... L366 (NFC, lowercasing, accents, Traditional-Simplified, Serbian, Unicode 5.0): compiles
SUMMARY label=own-10.6.0 blocks=10 compile=6 fail=4- The page offers them as "Example Usages", with no note that they target an old release.
- Each failing line calls a removed API, except the main-only Serbian lines (a 2025 re-indent slip); the other 5 examples compile.
- Maintainers fix such snippets: a 2012 commit fixed the java.text copy of these examples, and open PR #16904 is fixing it again.
The full argument204 words
- Offered as working code. Each section heads its code with "Example Usages" (
overview.html:71,:110, ...); nothing on the page says the code targets an old release or is pseudocode. - Drift, not design.
308e0bd4a9d(LUCENE-2514/LUCENE-2551, 2011-02-28) last rewrote the collation examples for the then trunk API, and every API they call existed then. Each later removal left the page alone, and none of the removing issues mentions it. - Precedent.
647b5091697(2012-09-12, "code snippet improvements: fix out of date api usage ...") fixedIndexSearcher(dir, true)andField.Indexin the java.text twin of these examples and left this page as it was. On LUCENE-8481 (#9527, 2018), which named this file as a RAMDirectory user, Dawid Weiss wrote "I agree we should fix javadocs too, they're stale" and Adrien Grand "+1 to address consistency issues as a follow-up?". LUCENE-6112 fixed a non-compiling package example as a documentation bug. Open PR #16904 is fixing the java.text twin again. - The Serbian break is a slip. #14832 ("style: fix indents inconsistent with editorconfig and validate in CI", 129 files) turned the page's 8
/** ... */comments into//comments; 7 came out valid, only the Serbian one became an empty//followed by the sentence as code.
The devil's-advocate check150 words
Strongest case for "not a bug": the blocks are fragments without imports that Lucene never promises to compile; the removals were deliberate and documented in CHANGES and MIGRATE; and ICUTokenizer is @lucene.experimental (ICUTokenizer.java:38), so its API may change. A cross-model reviewer (OpenAI GPT-5.6) rated this case "moderate".
Why it fails: with the imports and the two undeclared names supplied, the page's other five blocks and current-API rewrites of the failing ones compile, so the failures come from the page text. Apart from the main-only Serbian lines (a 2025 re-indent slip, #14832), they are calls to APIs that no longer exist, which no reader can fix by adding context. @lucene.experimental allows the API to change; it does not make the shipped example current, and the collation examples use core and queryparser API that is not experimental. Every verifier and the adjudication rejected the case: a documentation defect, minor.
Recommended Rewrite the five blocks with the current API (validated)
One file, +27/-25: ICUTokenizer() + setReader, TextField/StoredField, IndexSearcher(DirectoryReader.open(dir)), search(query, n[, sort]), SortField.Type.STRING plus an ICUCollationDocValuesField for the Danish sort, a TermRangeQuery over collation keys for Farsi, one // line for Serbian. Then all 10 blocks compile, the 3 collation examples pass, and renderJavadoc and the module tests pass.
  ICUCollationDocValuesField sortKey = new ICUCollationDocValuesField("contents", collator);
  for (int i = 0 ; i < data.length ; ++i) {
    Document doc = new Document();
    doc.add(new StoredField("tracer", tracer[i]));
    doc.add(new TextField("contents", data[i], Field.Store.NO));
    sortKey.setStringValue(data[i]);
    doc.add(sortKey);
    writer.addDocument(doc);
  }
  writer.close();
  IndexSearcher searcher = new IndexSearcher(DirectoryReader.open(dir));
  Sort sort = new Sort(new SortField("contents", SortField.Type.STRING));
  ScoreDoc[] result = searcher.search(MatchAllDocsQuery.INSTANCE, 1000, sort).scoreDocs;
All options and trade-offs4 options · 446 words
One fix was validated in a scratch worktree of 645d4fe14a20; the alternatives were not run.
Javadoc only, lucene/analysis/icu/src/java/overview.html, +27/-25:
- tokenizer:
new ICUTokenizer(), thentokenizer.setReader(reader); - the three collation examples:
TextField/StoredFieldinstead ofField.Index,new IndexSearcher(DirectoryReader.open(dir)),search(query, 1000[, sort]); - Farsi:
new TermRangeQuery("content", lower, upper, true, true)with boundsnew BytesRef(collator.getCollationKey(...).toByteArray()), asTestICUCollationKeyAnalyzerdoes (not QueryParser, because of LFV-1053); - Danish:
new Sort(new SortField("contents", SortField.Type.STRING)), anICUCollationDocValuesField("contents", collator)per document (as vsop-479 pointed out on #16904 for the java.text copy),searcher.storedFields().document(...); - Serbian: one line,
// This filter will map Serbian Cyrillic to Serbian Latin according to BGN rules.
  ICUCollationDocValuesField sortKey = new ICUCollationDocValuesField("contents", collator);
  for (int i = 0 ; i < data.length ; ++i) {
    Document doc = new Document();
    doc.add(new StoredField("tracer", tracer[i]));
    doc.add(new TextField("contents", data[i], Field.Store.NO));
    sortKey.setStringValue(data[i]);
    doc.add(sortKey);
    writer.addDocument(doc);
  }
  writer.close();
  IndexSearcher searcher = new IndexSearcher(DirectoryReader.open(dir));
  Sort sort = new Sort(new SortField("contents", SortField.Type.STRING));
  ScoreDoc[] result = searcher.search(MatchAllDocsQuery.INSTANCE, 1000, sort).scoreDocs;
Trade-offs
None for users: documentation only, and no CHANGES entry is strictly needed. The Farsi example no longer shows QueryParser; that is deliberate until LFV-1053 is fixed. Updating the names without the doc values is not enough: the Danish example then throws IllegalStateException at run time.
What the checks validated
- A fix-check test extracts every Java block from the patched page and compiles it the same way as the minimal test: 10 of 10 compile, and the Farsi (0 hits), Danish (order
A, E, B, D, C) and Turkish (1 hit) examples run and pass their own assertions, with assertions on and off. On the stock page the same check fails 5 of 10 with the same 16 lines. - Without the doc-values lines the Danish block compiles and throws
IllegalStateException: unexpected docvalues type NONE for field 'contents' (expected=SORTED). ./gradlew :lucene:analysis:icu:renderJavadocsucceeds on the patched page, and the rendered overview shows the new example../gradlew :lucene:analysis:icu:test -Ptests.seed=DEADBEEF: 16 classes, 158 tests, 10 skipped, 0 failures.
Keep the Farsi example on QueryParser, only drop setAnalyzeRangeTerms (not recommended now, not run)
Closest to the original text.
Trade-offs
The bounds then come from Analyzer.normalize, which for ICUCollationKeyAnalyzer returns UTF-8 bytes (LFV-1053), so the example would compare UTF-8 bounds against collation keys. Revisit once LFV-1053 is fixed.
A smaller change.
Trade-offs
Drops the only worked examples of ICUCollationKeyAnalyzer for range, sort and case-insensitive search.
The generic wish in LUCENE-8488 (#9534, open since 2018).
Trade-offs
Would stop recurrence, but it is a build-infrastructure change, not part of this fix.
No formal method. A static scan of documentation code first flagged the collation examples; a test then compiled every Java block on the page verbatim against the main jars, which added the tokenizer, setAnalyzeRangeTerms, setSort and Serbian lines. Verifiers reproduced it with their own compilers.
The method in full115 words
- First signal. A regex scan of javadoc and overview code for removed APIs flagged
overview.html:121, 151, 152, 160, 162, 176, 182(Field.Index, the Filter search overloads,searcher.doc). - Compile check. A hunt unit for stale examples (a sibling of open PR #16904) extracted every Java block of the page and compiled it verbatim with
javax.toolsagainst the stock main jars, supplying imports and the two undeclared names. It added lines 75, 127, 158 and 338-340, and the five other blocks compiled as controls. - History. An API-presence scan over 15 release tags, then the own page of 16 releases compiled against their own jars, dated every row.
- Tier. Non-formal: it only compiles documentation code.
No prior report: GitHub issues and PRs (with the migrated JIRA archive), commits, the dev@, java-user@, issues@ and commits@ lists, downstream repositories and the web were searched on 2026-10-29 (150 logged queries and reads); re-checked 2026-11-01. Nearest: open PR #16904, which fixes the java.text copy in another module.
Searches4 searches
Context, not reports: LUCENE-8481 (#9527) named this file for RAMDirectory only; LUCENE-8488 (#9534) is a generic wish to compile examples; #15225 is a docs meta issue; #16821 is the same defect class in the highlighter docs; #14832 introduced the Serbian break and nobody commented on it. The .NET port rewrote its own copy of the page in 2021 without reporting upstream.
Others are filing stale-javadoc fixes this month (#16904, #16949).
| Where | When | How | Found |
|---|---|---|---|
| Scripted searches, 2 runs | 2026-10-28 and 2026-10-29 | 51 queries each over GitHub issues, PRs and commits, downstream repositories, dev@, java-user@, issues@, commits@, the JIRA archive and the web | 0 high hits; one medium hit (LUCENE-4254, Thai tokenization) is unrelated |
| GitHub, manual | 2026-10-29 | 43 issue and PR searches (apache/lucene, the archived lucene-solr, solr, lucenenet, two downstream search engines, authors of recent javadoc fixes); changed files of all 414 open PRs | only #16904 (the java.text twin, another file) and #16911 (deletes the branch_10x tree) |
| JIRA archive, mailing lists, web | 2026-10-29 | 5 JQL queries and 9 issue reads; 28 list queries; 11 web searches | no report |
| Re-check: open PR #16904, new PRs and issues, upstream main | 2026-11-01 | #16904's files; the changed files of the 16 PRs and the 6 issues created since 2026-10-29; the file's commit history on main | #16904 still open, still only collation/package-info.java; #16949 (stale javadoc fixes, 27 files) does not touch analysis-icu; the page is unchanged since 378ca8d1bbf (2026-01-15) |
The examples compiled on trunk only from 2011-02-28 to 2011-06-22. LUCENE-3219 (f9ed2c19cd7, 2011) broke the Danish sort and LUCENE-3571 (598920d7bde, 2011) all three collation examples; both first shipped in 4.0.0-ALPHA (2012). Later removals broke more lines in 5.0, 6.0, 7.0, 9.0 and 10.0; #14832 (2025) broke the Serbian example on main.
Versions tested6 rows
- Origin. The collation text came from the contrib/collation docs (
a02eb9ee42b, LUCENE-1876, 2009); LUCENE-2124 (cc619905c4e, 2009) copied it into this page;308e0bd4a9d(LUCENE-2514/LUCENE-2551, 2011-02-28) rewrote it for the then trunk API. - First breaks.
f9ed2c19cd7"LUCENE-3219: Moved SortField types to Enum" (2011-06-22) and598920d7bde"LUCENE-3571: nuke IndexSearcher(Directory)" (2011-11-16; it updated the coreoverview.htmlbut not this page). Neither touched this page. - Later removals:
ICUTokenizer(Reader)in 5.0.0 (LUCENE-5388),Field.Indexand the Filter search overloads in 6.0.0 (LUCENE-4095, LUCENE-6286),setAnalyzeRangeTermsin 7.0.0 (LUCENE-7355),Sort.setSortin 9.0.0 (LUCENE-9325),IndexSearcher.doc(int)in 10.0.0 (#11998). - Edits that kept the stale calls: LUCENE-5364, LUCENE-5632 and LUCENE-5900 (Version arguments), LUCENE-8481 (
922295a94d5, 2018:ramDirre-typed asdir), LUCENE-9126 (<escaping), #15573 (2026, markup). - Main only:
95d019bd881(#14832, 2025-06-22) broke the Serbian comment. - Method: each release's own page compiled against that release's own jars for 17 releases (3.1.0, 3.2.0, 3.6.2, 4.0.0-ALPHA, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, 10.6.0). The releases in between hold by reading: every 3.x tag has the same page text, as does every 10.x tag; every page from 4.0.0-ALPHA to 9.12.3 keeps the three
new IndexSearcher(..., true)lines andSortField.STRING, both removed in 4.0.0-ALPHA; no 10.x tag declares any of the removed APIs.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; upstream main f815e679bf6c | affected | 5 of 10 blocks fail, 16 error lines, -ea and -da (upstream main read, not run: page unchanged) |
| 10.6.0 | affected | own page: 4 of 10 blocks, 14 error lines; the Serbian block is valid there |
| 10.0.0 to 10.5.2 | affected | 4 of 10, 14 error lines (+ doc(int)); run on 10.0.0 and 10.5.2, the releases in between have the same page |
| 5.0.0 to 9.12.3 | affected | 4 of 10; the failing lines grow with each removal (Field.Index and Filter overloads in 6.0, setAnalyzeRangeTerms in 7.0, setSort in 9.0); run on 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 8.11.4, 9.0.0 and 9.12.3, the others by reading |
| 4.0.0-ALPHA to 4.10.4 | 3 of 10 | the three collation examples (IndexSearcher(Directory, boolean), int SortField.STRING); run on 4.0.0-ALPHA, 4.0.0 and 4.10.4, the others by reading |
| 3.1.0 to 3.6.2 | other stale call | none of these rows; 2 blocks failed for another reason (QueryParser without the Version argument that 3.0 made mandatory); run on 3.1.0, 3.2.0 and 3.6.2, the others have the same page |
Independent reproducers, a reviewer from another model family (OpenAI GPT-5.6) with lenses, a devil's-advocate check, an adjudication and an audit looked at it. All executing checks reproduced it; the refute lens could not run anything, so its "not real" is procedural. Adjudication: confirmed, high confidence, a minor documentation defect.
Checks and verdicts234 words
Each check ran separately; the cross-model reviews were reading-only (a separate run re-ran the repro). No executing cross-model review exists.
| Check | Verdict | What it found |
|---|---|---|
| Finder | reproduced (doc) | 10-test class: 5 fail on main (-ea, -da), 10.5.2 and 9.12.3; fix check 5 of 5 pass, 3 of 3 assertion mutants fail. |
| Refute lens (OpenAI GPT-5.6) | not a valid review (procedural) | Could not run anything; 8 reading items supported real, 2 for not real: one procedural (it could not run), one weak counterpoint (fragments and @lucene.experimental together); a separate run re-ran the repro on 10.5.2: fail. |
| Reproducer | real | Own extractor and compiler: 5 of 6 fail on main with -ea and -da, controls pass; the 10.5.2 page fails 4 of 6 on 10.5.2 and 9.12.3. |
| Intended lens (OpenAI GPT-5.6) | real (medium) | Rated the "illustrative fragments" case moderate and rejected it. |
| Devil's advocate | real, documentation defect | Rejected the fragments, tolerated-staleness and experimental arguments; re-ran 5 of 10 fail on main and 10.5.2. |
| Adjudication and audit | confirmed (high), minor | Re-ran with new seeds: 5 of 6 and 5 of 10 fail; read each removed API on main. |
| Minimal repro and brief | verified; fix validated | One-test class fails on 645d4fe14a20 (-ea, -da) and on the 10.6.0 jars; the fixed page compiles 10 of 10 and its collation examples pass; renderJavadoc and the module tests pass. |
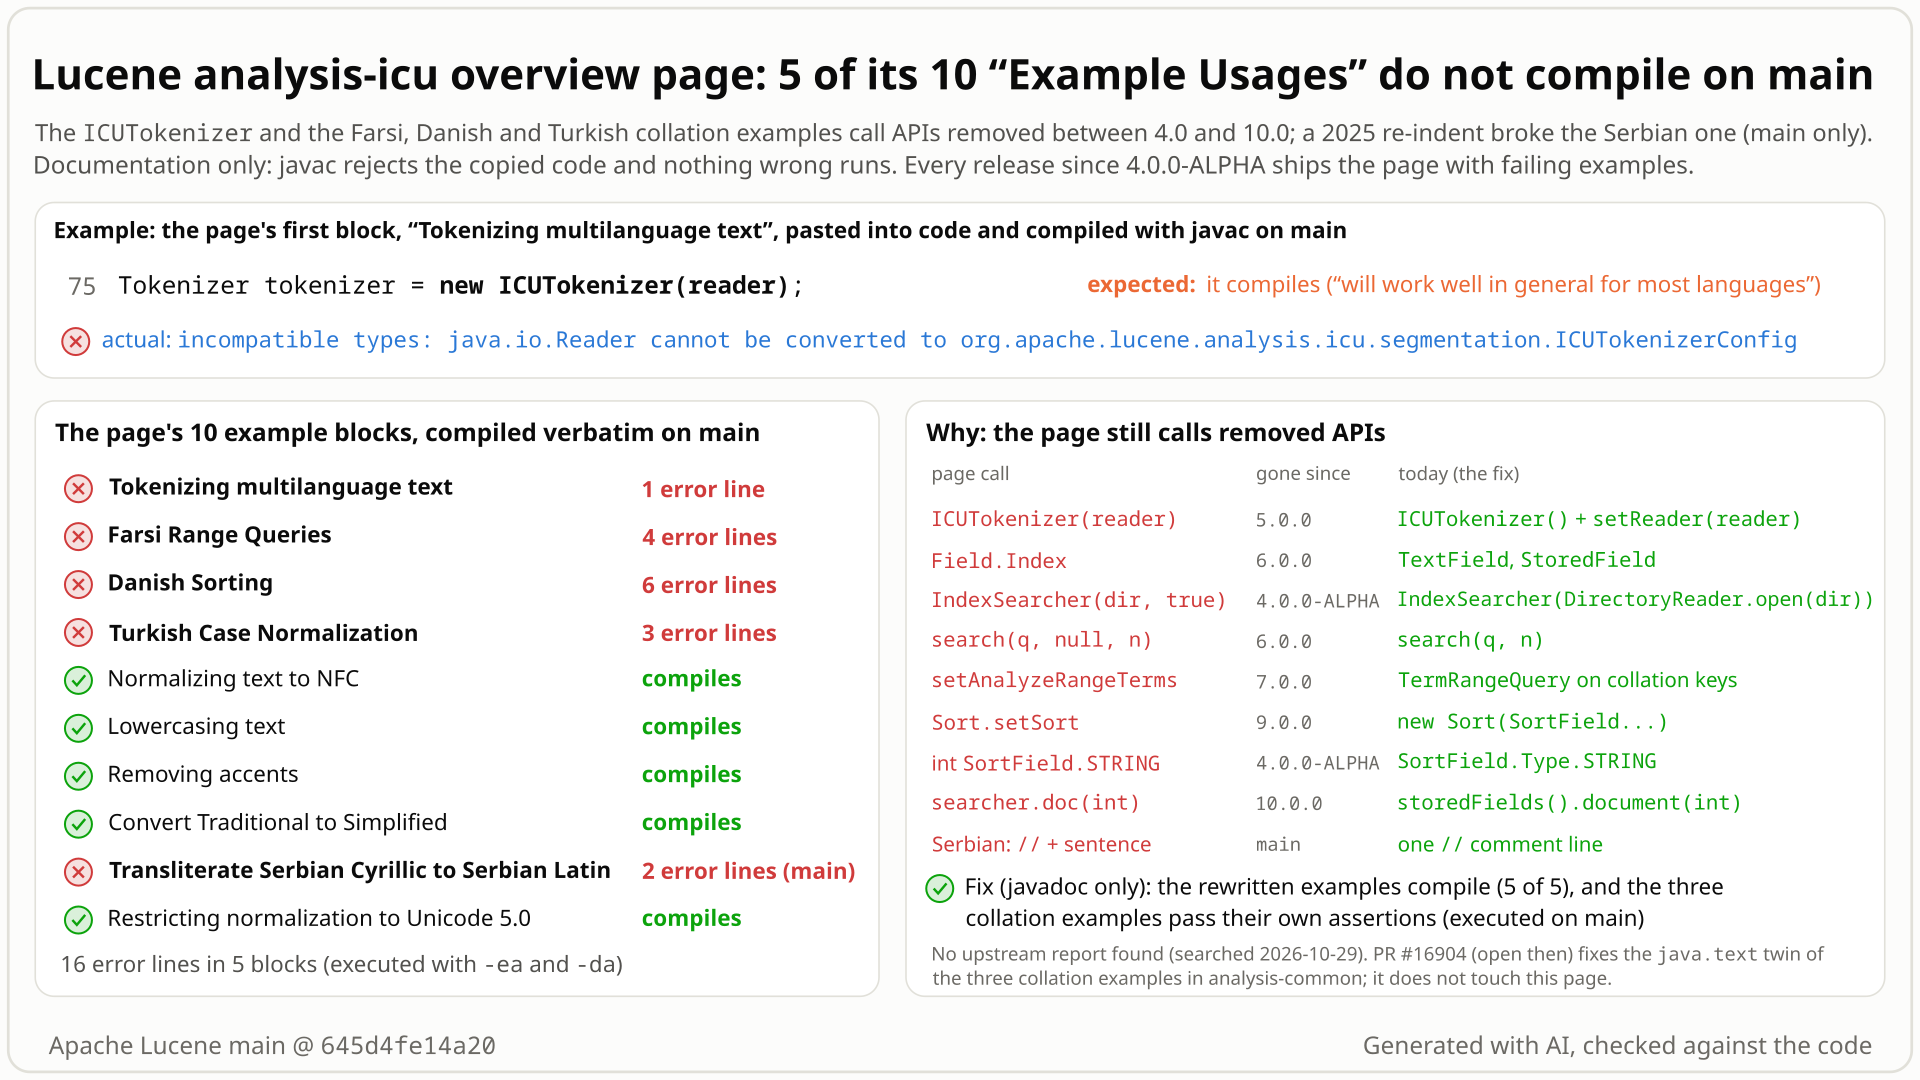
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 470 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,574 words
- Registry title
- analysis-icu overview page: the ICUTokenizer example and the three collation examples (Farsi range, Danish sort, Turkish case) call APIs removed between Lucene 4.0 and 10.0, and on main the Serbian transliteration example is not valid Java (documentation defect)
- Area
- analysis-icu / module overview documentation (overview.html 'Example Usages')
- Priority
- Low, rank 1240: The analysis-icu overview's broken examples are a loud compile-time documentation defect with no runtime effect, on a module page with a small audience, so it is Low.
- Impact class
- minor
- Impact note
- Documentation only, with no runtime effect: a developer who adopts the opt-in analysis-icu module by copying the examples on its overview page gets compile errors in 3 of the page's 10 example blocks in 4.0.0-ALPHA to 4.10.4, in 4 blocks from 5.0.0 to 10.6.0 (14 error lines from 10.0.0 on) and in 5 blocks (16 error lines) on main, where a 2025 re-indent also broke the Serbian block's comment; the page's other 5 blocks compile, and no configuration, scale or special input is involved.
- Summary
- You read the analysis-icu module overview, which offers 'Example Usages' for ICU tokenization, collation and transliteration, and copy one into your code. The tokenizer example and the Farsi range, Danish sort and Turkish case collation examples do not compile on any current release, because they call APIs Lucene removed between 4.0 and 10.0 (new ICUTokenizer(reader), Field.Index.ANALYZED, new IndexSearcher(dir, true), QueryParser.setAnalyzeRangeTerms, the Filter-taking search methods, Sort.setSort, IndexSearcher.doc(int)), and on main the Serbian transliteration example has a bare, uncommented sentence in its code. Rewritten with the current API (and, for the Danish sort, doc values) the examples compile and do what the page says, so only the page is wrong.
- Introduced
- f9ed2c19cd7 (trunk, LUCENE-3219 'Moved SortField types to Enum', #4292, author date = commit date 2011-06-22): the first API removal that broke a page line that still fails on main (line 158, the int SortField.STRING); then 598920d7bde (trunk, LUCENE-3571 'nuke IndexSearcher(Directory)', #4645, 2011-11-16, rmuir) broke all three collation examples (lines 124, 156, 179, new IndexSearcher(dir, true)). Neither commit touched this page (LUCENE-3571 updated the core overview.html's call, not this module's page), and both reached a release only in 4.0.0-ALPHA. Later removals broke more lines, each without touching the page: ab0e85fafed (LUCENE-5388, 2014-01-09; ICUTokenizer(Reader), gone in 5.0.0), bc3a3dc5d47 (LUCENE-4095, 2012-05-31; Field.Index, gone in 6.0.0), 2cd3fb807da (LUCENE-6286, 2015-02-24; the Filter search overloads, deprecated in 5.1, gone in 6.0.0), e92a38af90d (LUCENE-7355, author date 2016-06-28; setAnalyzeRangeTerms, gone in 7.0.0), 9e9c3bd249e (LUCENE-9325, #338, 2021-10-06, romseygeek; Sort.setSort, gone in 9.0.0), 9eeab8c4a69 (#11998, 2022-12-13, rmuir; IndexSearcher.doc(int), gone in 10.0.0). Main-only Serbian row: 95d019bd881 (#14832 'style: fix indents inconsistent with editorconfig', rmuir, 2025-06-22) turned the block's valid /** ... */ comment into '//' followed by a bare sentence [read: git log, git blame -w -M -C and git show in the full-history clone; exec: per-release sweep, see affected_versions] (2011-06-22 (f9ed2c19cd7, LUCENE-3219, author date = commit date) and 2011-11-16 (598920d7bde, LUCENE-3571, author date = commit date); 2025-06-22 (95d019bd881, #14832, author and merge date: the main-only Serbian row))
- First affected version
- 4.0.0-ALPHA [exec] (tag 2012-06-29, the first release with both 2011 commits; its shipped page fails against its own jars in the Farsi, Danish and Turkish examples); first GA 4.0.0 [exec], the same; the Serbian row is unreleased (main only)
- Affected versions
- every release from 4.0.0-ALPHA to 10.5.2, 10.6.0 [exec 2026-11-01: its own page against the 10.6.0 release jars fails 4 of 10 blocks with 14 error lines] and main a9779ef3c193; not fixed upstream (upstream main 645d4fe14a20 and branch_10_6 still carry every stale call, read 2026-10-29). The set of failing calls grew release by release [exec: each release's own page compiled against its own jars]: 4.0.0-ALPHA, 4.0.0 and 4.10.4: 3 blocks (IndexSearcher(Directory, boolean), the int SortField.STRING); 5.0.0 and 5.5.5: 4 blocks (+ ICUTokenizer(Reader)); 6.0.0 and 6.6.6: + Field.Index and the Filter search overloads; 7.0.0 and 8.11.4: + setAnalyzeRangeTerms; 9.0.0 and 9.12.3: + Sort.setSort (13 error lines); 10.0.0 and 10.5.2: + IndexSearcher.doc(int) (14 error lines, 4 blocks); main: + the Serbian syntax error (16 error lines, 5 blocks). Main's page against the 4.10.4 to 10.5.2 jars agrees row by row. The branch_10x head 657014b3c57 and the branch_10_6 head 4ae946e5a9b have a page byte-identical to 10.5.2's [read]. Before 4.0: 3.1.0, 3.2.0 and 3.6.2 [exec] show none of these rows, but their page failed 2 of 10 blocks for another reason (QueryParser constructors without the Version argument that 3.0 made mandatory), so no release ever shipped all three collation examples in a form that compiles against it [exec]; they compiled only on trunk from 2011-02-28 to 2011-06-22 [read]. The finder's JUnit (main's text) fails 5 of 10 on main (-ea and -da), 10.5.2, 10.0.0 and 9.12.3. Caveat: all runs used JDK 25 on Linux aarch64; the check only compiles, so the JDK cannot change the outcome.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-29; recheck 2026-10-29): two scripted search runs (51 queries each over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 0 high hits; the one medium hit, LUCENE-4254 on Thai tokenization, is unrelated), 43 manual GitHub issue and PR searches (apache/lucene, the archived apache/lucene-solr, apache/solr, apache/lucenenet, two downstream search-engine repositories, and the authors of this week's javadoc-fix items), the changed files of all 414 open apache/lucene PRs (only #16911, which deletes the branch_10x tree, lists the file), 5 JQL queries and 9 JIRA issue reads, 28 list queries and 11 web searches. Nearest item, not the same bug: PR #16904 (Deepcodr, created 2026-10-24, commits authored 2026-10-24 to 2026-10-28, head 74b8a94f687d; approved by vsop-479 2026-10-29 and merged by them on main 2026-11-02 as e1faeba08bd; not on branch_11x da3ea39fa59 or branch_10_6 91eaab4fb29) updated the java.text twin of the same three collation examples in lucene/analysis/common/src/java/org/apache/lucene/collation/package-info.java, its only file; its review (vsop-479) raises SortField.Type.STRING, doc values for the Danish sort and setAnalyzeRangeTerms for that file; it never touches or mentions the ICU page, the ICUTokenizer line or the Serbian block. Context, not reports: LUCENE-8481 (#9527, 2018) named this file only as a RAMDirectory user, and its fix re-typed new IndexSearcher(ramDir, true) as new IndexSearcher(dir, true), leaving the removed calls; LUCENE-8488 (#9534, open) is a generic wish to compile javadoc examples; #15225 is a generic docs meta issue; #16821 (hidingmyname) is the same defect class in the highlighter package docs; #14832 introduced the Serbian break and nobody commented on it; 647b5091697 (2012) fixed the java.text twin only; the Lucene.NET port rewrote its own copy of the page in 2021 (apache/lucenenet c8a0f00f0c) without reporting anything upstream. Not fixed upstream: the file is unchanged since 378ca8d1bbf (#15573, 2026-01-15) and byte-identical to a9779ef3c193 on upstream main 645d4fe14a20. Tracking issue #16937 does not name it. Update 2026-11-02: the merged #16904 Danish example still calls the removed Sort.setSort (collation/package-info.java:91 on e1faeba08bd; listed here as LFV-1085), and #16904 never mentions this page; overview.html is unchanged since 378ca8d1bbf (#15573, 2026-01-15) and its blob is identical on main e1faeba08bd and 645d4fe14a2. For the Farsi range on this page the collation-key TermRangeQuery rewrite is still needed: ICUCollationKeyAnalyzer has no attributeFactory override, so QueryParser range normalization does not apply as it does for CollationKeyAnalyzer (executed on e1faeba08bd).
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off (standalone, with a plainjavac/javacommand); the 10.6.0 release jars give the same 16 lines, and 10.6.0's own page fails 4 of 10 blocks against them; 16 older releases from 3.1.0 to 10.5.2 had their own page compiled against their own jars in the version-history runs, and the releases in between hold by reading (each keeps the stale calls on its page, and the removed APIs stay removed); the fix was checked in a scratch worktree of645d4fe14a20(every block compiles, the collation examples run,renderJavadocand the analysis-icu tests pass). Upstream mainf815e679bf6c(2026-11-01) was read, not run: the page is unchanged.
- Finding record
lucene/analysis/icu/src/java/overview.html:71-76 (tokenizer 'Example Usages'), :110-184 (collation 'Example Usages': Farsi :112, Danish :139, Turkish :167) and :336-341 (Serbian block: '//' then the bare sentence at :339); byte-identical to upstream main 645d4fe14a20 (cmp, 2026-10-29)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/analysis/icu/src/java/overview.html:71-184, :242, :277, :302, :330-341, :351a Lucene main checkout (645d4fe14a20) build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:452-462a Lucene main checkout (645d4fe14a20) lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:38, :69-92; lucene/core/src/java/org/apache/lucene/analysis/Tokenizer.java:89a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:189, :472, :623, :677; Sort.java:54-63; SortField.java:74a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:550, :556a Lucene main checkout (645d4fe14a20) lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUCollationDocValuesField.java:50; lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/TestICUCollationKeyAnalyzer.java:44-50
- Minimal repro
a Lucene main checkout (645d4fe14a20) lucene/analysis/icu/build.gradle (test dependencies: test-framework only); gradle/libs.versions.toml (dependency versions)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/analysis/icu/src/java/overview.html:71, :110, :242, :277, :302, :330, :351
- History
a Lucene clone: releases/lucene/10.6.0 (tag commit 4ae946e5a9b)
- TestIcuOverviewExamplesCompile.java (one test, public API):
repro/LFV-992/src/org/apache/lucene/analysis/icu/TestIcuOverviewExamplesCompile.java(167 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-992/bug.png(470 KB)