The classic n-gram SpellChecker fetches ten times as many candidate words as the suggestions you ask for and computes that budget in a Java int. A huge count wraps the budget negative, and the search underneath rejects it.
SpellCheckerkeeps a separate spell index with one document per dictionary word, split into n-grams.suggestSimilar(word, numSug)searches that index for words sharing n-grams withword, takes the top10 * numSughits (n-gram overlap is only a rough guide), ranks them by edit distance and returns the bestnumSug.- The search it calls,
IndexSearcher.search(query, n), capsnat the index size, so theren = Integer.MAX_VALUEsimply means "all hits"; a Lucene test requires that it not throw.
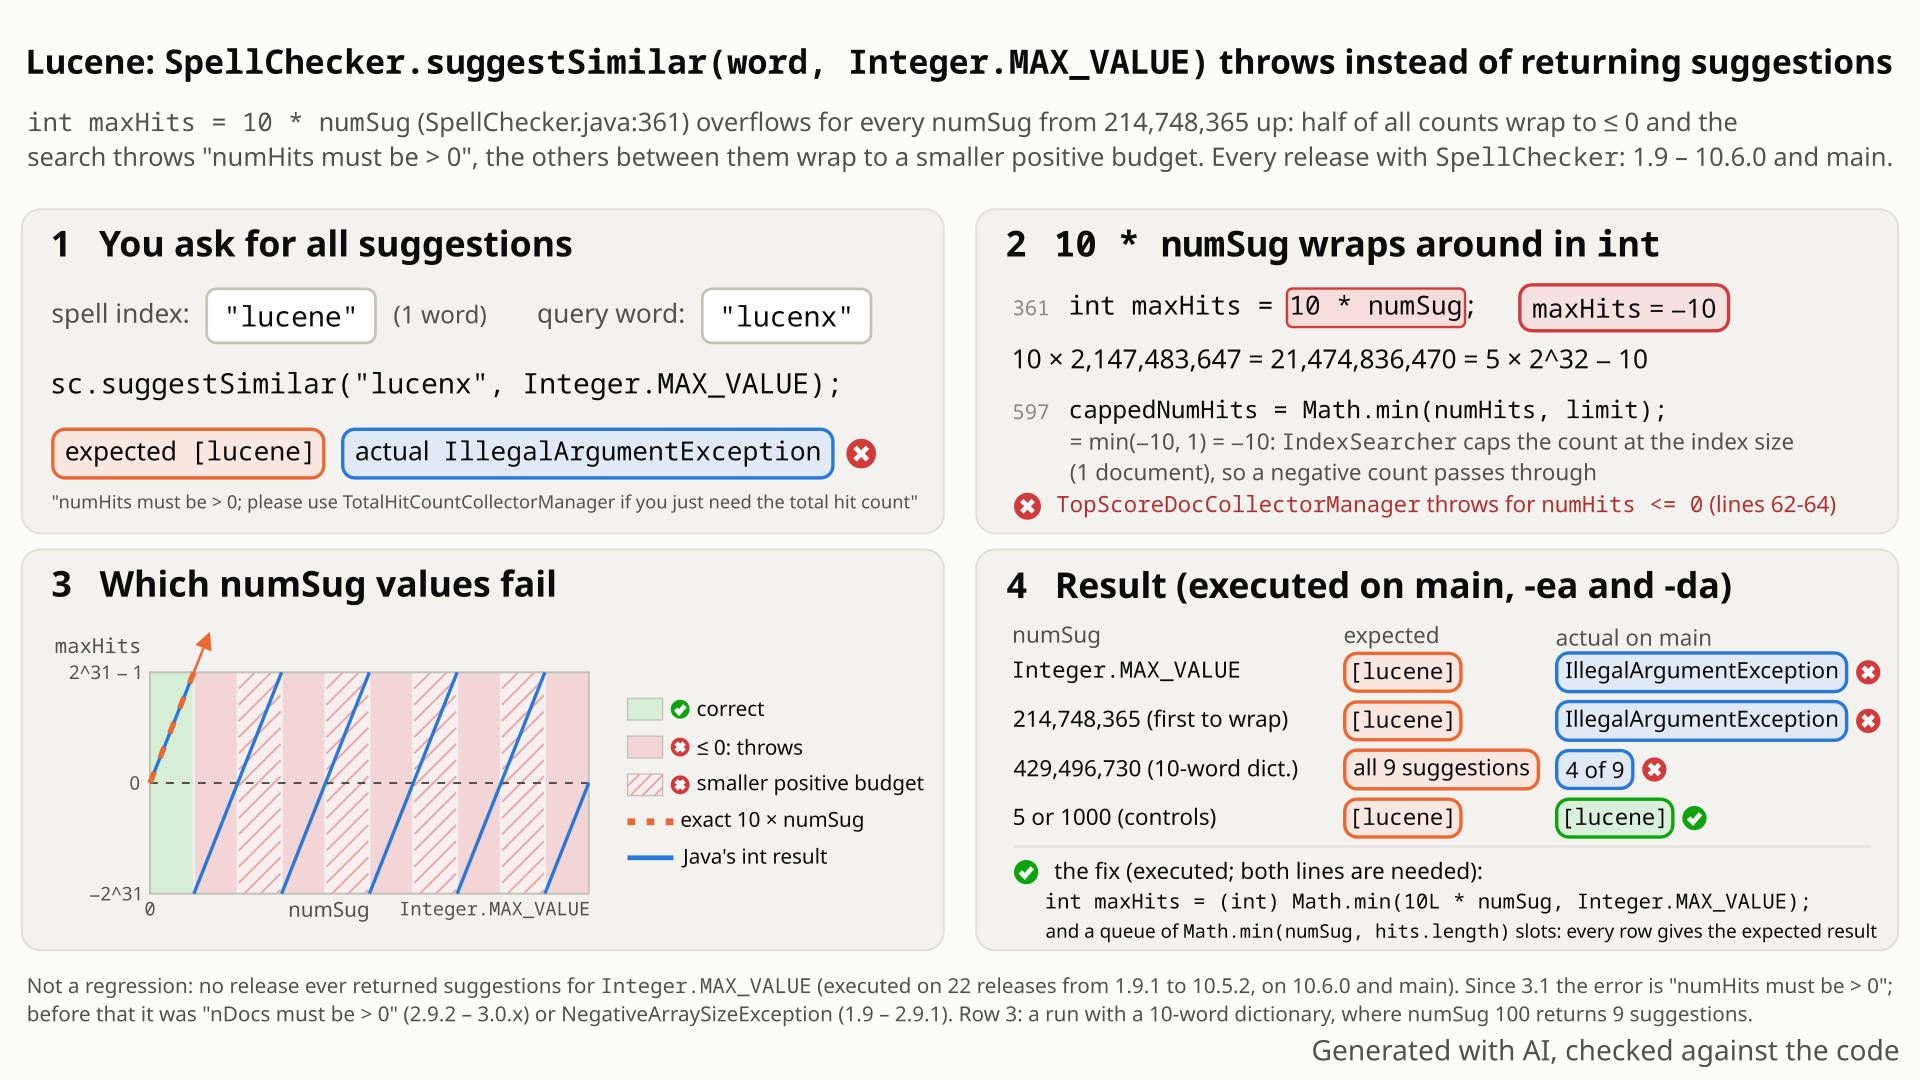
Integer.MAX_VALUE on a one-word index; how 10 * numSug wraps to -10 and slips past the search's index-size cap; which counts wrap to zero or below (throw) or to a smaller budget; and the results, with the two-line fix. Select the still to open it at full size. Generated with AI, checked against the code.- You build a spell index from a one-word dictionary,
lucene, and callsuggestSimilar("lucenx", Integer.MAX_VALUE)to get every suggestion. - You expect
[lucene]. Counts of 5, 1,000 and 214,748,364 return exactly that on the same index (run with a 3 GiB heap: at 214,748,364 the queue alone is about 0.8 GiB), and the javadoc sets no upper bound onnumSug. - You get
IllegalArgumentException: numHits must be > 0; please use TotalHitCountCollectorManager if you just need the total hit count, about a parameter you never passed. 214,748,365 fails the same way. - Why: the spell checker asks the search for
10 * numSughits, computed inint, and 10 x 2,147,483,647 wraps to -10. The search caps itsnat the index size,min(n, maxDoc), which keeps -10, and rejects it. Every count whose product wraps to zero or below fails: 1,073,741,824 values in five blocks. - Where the product wraps to a small positive number, the call silently returns fewer: on a 10-word dictionary
numSug= 429,496,730 (budget 4) returns 4 of the 9 suggestions, after reserving a 1.6 GiB queue.
Applications that call the classic SpellChecker.suggestSimilar (default settings, any dictionary) with a huge count: most naturally Integer.MAX_VALUE for "all suggestions", or a user-chosen count with no upper bound. Ordinary counts, up to 214,748,364, are unaffected. The failure is loud on the first call; the silent short result needs a count above 429 million.
Mechanism, terms and numbers718 words
SpellChecker.suggestSimilar(word, numSug), Lucene's classic n-gram spell checker, fetches ten times as many candidate words from its spell index as the suggestions requested and computes that budget as int maxHits = 10 * numSug. For numSug = Integer.MAX_VALUE ("all suggestions") the product wraps to -10; IndexSearcher.search(query, n) caps n with min(n, max(1, maxDoc)), which keeps the negative value, and TopScoreDocCollectorManager throws IllegalArgumentException: numHits must be > 0; please use TotalHitCountCollectorManager if you just need the total hit count, naming a parameter the caller never passed. The javadoc sets no upper bound on numSug and nothing validates it, while the search below is tested to accept Integer.MAX_VALUE. Every count whose product wraps to zero or below fails (1,073,741,824 values in five blocks, the first at 214,748,365); where it wraps to a small positive number the call silently returns fewer suggestions (numSug = 429,496,730: 4 of 9). A second line sizes the result queue by numSug, so the fix has two lines: compute the budget in long and saturate it, and size the queue by min(numSug, hits.length). Every release from 1.9 to 10.6.0 and main is affected; it is not a regression (Integer.MAX_VALUE never worked, only the exception changed), no index data or search results are affected, and ordinary counts up to 214,748,364 work.
- Contract.
SpellChecker.java:224-241: "you should set this value to <b>at least</b> 5 for a good suggestion" (:232-233) and "@param numSug the number of suggested words" (:236; the same on:258,:293);:303-305return "the sorted list of the suggest words". No upper bound, no@throwsfor a large count; the overloads:242,:266,:275reach:307, which never checksnumSug. - The product.
:361int maxHits = 10 * numSug;:10 * 2147483647= -10,10 * 214748365= -2147483646,10 * 429496730= 4. - The search.
:364indexSearcher.search(query.build(), maxHits).IndexSearcher.search(IndexSearcher.java:623-625) callssearchAfter, which caps withMath.min(numHits, Math.max(1, reader.maxDoc()))(:588,:597): a negative value passes the cap, andnew TopScoreDocCollectorManager(...)(:598-599) throws fornumHits <= 0(TopScoreDocCollectorManager.java:62-64). - The queue.
:366new SuggestWordQueue(numSug, comparator), aPriorityQueuethat "pre-allocates an array of length maxSize+1" (PriorityQueue.java:34-35,@lucene.internal) and refusesmaxSize >= 2147483631(:121-124), sized bynumSugwhatever the hit count. - The loop.
:369int stop = Math.min(hits.length, maxHits);inspects at moststophits, so a small positive wrapped budget looks at only that many candidates; the result is visibly short only when more viable candidates exist than that budget. - Scope. The 2-argument overload always reaches
:361. The 6-argument method can return earlier: with a user index and field inSUGGEST_WHEN_NOT_IN_INDEXmode, a word present in that index returns[word]at:332-334before the product is computed. - Both lines matter. With only
:361fixed,Integer.MAX_VALUEfails at:366withIllegalArgumentException: maxSize must be >= 0 and < 2147483631; got: 2147483647, and 214,748,365 ends inOutOfMemoryErrorat-Xmx512m. - The layer below.
TestIndexSearcher.java:78-79// should not throw exception/testHugeN()callssearcher.search(query, Integer.MAX_VALUE)(:101).
| call | result |
|---|---|
one-word dictionary lucene, suggestSimilar("lucenx", n), n = 5, 1,000, 214,748,364 | [lucene] |
the same, n = 214,748,365 or Integer.MAX_VALUE | IllegalArgumentException: numHits must be > 0; ... |
10-word dictionary, query rangex, n = 100 and 214,748,364 | 9 suggestions |
the same, n = 214,748,365 or Integer.MAX_VALUE | the same IllegalArgumentException |
| the same, n = 429,496,730 (budget wraps to 4) | 4 suggestions, no error |
DirectSpellChecker.suggestSimilar(term, Integer.MAX_VALUE, reader) (control) | 5 suggestions, as with 100, only because its own product numSug * maxInspections wraps to a positive value (other large counts fail there: LFV-986) |
fix A, every count above (-Xmx512m) | the full result |
Below the threshold each call allocates in proportion to numSug, because the queue has numSug + 1 slots whatever the hit count. Measured for the whole call (always 7 suggestions on a 10-word dictionary; a9779ef3c193, same SpellChecker.java): about 0.2 MiB at 10 and at 1,000 (of which the queue is about 4 KB at 1,000), and 381.7 MiB at 10^8, almost all of it the queue. The wrap blocks with a product of zero or below are 214,748,365-429,496,729, 644,245,095-858,993,459, 1,073,741,824-1,288,490,188, 1,503,238,554-1,717,986,918 and 1,932,735,284-2,147,483,647.
Exposure and likelihood252 words
- Who is hit. Code that passes a huge
numSugto anysuggestSimilaroverload. No setting is needed, and the dictionary size does not matter: a one-word dictionary fails. - What goes wrong. For 1,073,741,824 counts the call throws an exception that names
numHitsand recommendsTotalHitCountCollectorManager, neither of which the caller used. Where the product wraps to a small positive budget, the call can return fewer suggestions with no error; that needs a count of at least 429,496,730 and a queue of about 1.6 GiB first. Below the threshold results are right, but memory follows the count (381.7 MiB at 10^8). - Not a regression.
Integer.MAX_VALUEhas never worked:NegativeArraySizeExceptionin 1.9 to 2.9.1, "nDocs must be > 0" in 2.9.2 to 3.0.3, "numHits must be > 0" since 3.1. - Workaround. Cap the count before calling, for example at the number of words in the spell index; any count up to 214,748,364 works, given a heap large enough for the
numSug-sized queue (about 0.8 GiB at 214,748,364). - How likely. Rare: usual counts (the javadoc asks for "at least 5"; upstream tests use 1 to 10) never come near the threshold, and the recorded searches found no earlier report.
- Downstream (read, not executed). By default, Solr's index- and file-based spell checkers pass
max(spellcheck.count, 5)tosuggestSimilar(with a non-zeroalternativeTermCountthey pass that count instead for a word that is in the index), and Solr readsspellcheck.countwith no upper bound; Lucene.NET's port has the same two lines (SpellChecker.cs:364,:369).
One JUnit test, public API: a one-word dictionary and suggestSimilar("lucenx", Integer.MAX_VALUE). One thread, deterministic; it fails with assertions on and off on main, 10.5.2 and 10.6.0. With the fix it passes unchanged, so it doubles as the regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.spell;

import java.io.StringReader;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSpellCheckerNumSugOverflow extends LuceneTestCase {

  public void testNumSugIntegerMaxValue() throws Exception {
    try (Directory dir = newDirectory();
        SpellChecker sc = new SpellChecker(dir)) {
      sc.indexDictionary(
          new PlainTextDictionary(new StringReader("lucene\n")), new IndexWriterConfig(), false);
      try {
        assertArrayEquals(new String[] {"lucene"}, sc.suggestSimilar("lucenx", Integer.MAX_VALUE));
      } catch (IllegalArgumentException e) {
        fail("expected [lucene] for numSug = Integer.MAX_VALUE; actual: " + e.getMessage());
      }
    }
  }
}
cp $REPRO/TestSpellCheckerNumSugOverflow.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/spell/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.spell.TestSpellCheckerNumSugOverflow -Ptests.seed=DEADBEEF
# add -Ptests.asserts=true or -Ptests.asserts=false to choose the assertion mode; it fails both ways
- Expected
suggestSimilar("lucenx", Integer.MAX_VALUE)returns[lucene].- Observed
IllegalArgumentException: numHits must be > 0; please use TotalHitCountCollectorManager if you just need the total hit count.
More files, environment, full output296 words
Copy the test into lucene/suggest/src/test/org/apache/lucene/search/spell/ of a Lucene checkout and run the command below. It sits in that package only because the module's tests live there; it uses no package-private member. The result does not depend on the seed (newDirectory() is the only randomised part).
Lucene's build picks assertions per seed (about 75% of seeds run with them; DEADBEEF runs without), so add -Ptests.asserts=true or -Ptests.asserts=false to choose; it fails both ways. The catch only turns the exception into an assertion failure that states expected vs actual; pass e as the cause if you want the stack trace in the failure. The test passes the module's format check as is.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on the 10.5.2 and 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform it ran on) |
cp $REPRO/TestSpellCheckerNumSugOverflow.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/spell/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.spell.TestSpellCheckerNumSugOverflow -Ptests.seed=DEADBEEF
# add -Ptests.asserts=true or -Ptests.asserts=false to choose the assertion mode; it fails both ways
# gradle, fresh worktree at main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (module prefixes trimmed)
TestSpellCheckerNumSugOverflow > testNumSugIntegerMaxValue FAILED
    java.lang.AssertionError: expected [lucene] for numSug = Integer.MAX_VALUE; actual: numHits must be > 0; please use TotalHitCountCollectorManager if you just need the total hit count
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:599EE7562846F7E3]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at org.apache.lucene.search.spell.TestSpellCheckerNumSugOverflow.testNumSugIntegerMaxValue(TestSpellCheckerNumSugOverflow.java:34)
1 test completed, 1 failed
# the same with -Ptests.asserts=false and with the seed's default

# the throwing frames (a probe that keeps the exception; main 645d4fe14a20, -ea and -da)
java.lang.IllegalArgumentException: numHits must be > 0; please use TotalHitCountCollectorManager if you just need the total hit count
    at org.apache.lucene.search.TopScoreDocCollectorManager.<init>(TopScoreDocCollectorManager.java:63)
    at org.apache.lucene.search.IndexSearcher.searchAfter(IndexSearcher.java:598)
    at org.apache.lucene.search.IndexSearcher.search(IndexSearcher.java:624)
    at org.apache.lucene.search.spell.SpellChecker.suggestSimilar(SpellChecker.java:364)
    at org.apache.lucene.search.spell.SpellChecker.suggestSimilar(SpellChecker.java:278)
    at org.apache.lucene.search.spell.SpellChecker.suggestSimilar(SpellChecker.java:243)

# standalone runner, the minimal test (tests_run=1 failures=1 each)
main 645d4fe14a20, 10.6.0, 10.5.2 -ea and -da, seed DEADBEEF the same AssertionError- The javadoc calls
numSug"the number of suggested words", with no upper bound and no check; the error namesnumHits, which the caller never passed. - The search below fixed this failure as a bug (LUCENE-2119) by capping
nat the index size; theintproduct wraps before that cap. - Asking for more can return fewer: 429,496,730 gives 4 of 9.
The full argument321 words
- The exception is an overflow artifact, not a check. It fires at 214,748,365, the point where
10 * numSugpassesInteger.MAX_VALUE; no comment, test, CHANGES entry or commit chooses that threshold. The pre-allocation note sits on the@lucene.internalPriorityQueue(PriorityQueue.java:34-35,:39), which thesuggestSimilarjavadoc does not reference. Nothing documentsInteger.MAX_VALUEas an "all suggestions" value either: it is a request for more suggestions than exist, which the contract does not forbid. - LUCENE-2119 (#3195, reported by Michael McCandless,
type:bug, fixed in 2.9.3, 3.0.2 and 3.1): "If you pass Integer.MAX_VALUE as 2nd param to search(Query, int) you hit unexpected NegativeArraySizeException"; "This trips users up fairly often because they assume our PQ doesn't statically pre-allocate (a reasonable assumption...)"; "in IndexSearcher, if that n is ever > maxDoc(), set it to maxDoc()". That cap isIndexSearcher.java:597. This is context for the search's own contract, not proof thatSpellCheckerpromises the same. - Precedent in this file. LUCENE-10533 (#11569, Kevin Risden,
type:bug, fixed in 9.2), a missing bounds check inSpellChecker.formGramsreached from Solr: "There is an argument that the caller should not be invalid, but a simple bounds check would prevent this in Lucene". - The sibling spell checkers are no counter-example.
WordBreakSpellCheckerreturns an empty result below 1 and caps its initial queue capacity at 10 (WordBreakSpellChecker.java:81-83,:91).DirectSpellCheckeris no evidence that large counts are supported: it returns its full result forInteger.MAX_VALUEonly because its ownintproductnumSug * maxInspections(DirectSpellChecker.java:359, default 5 at:67) happens to wrap to the positive 2,147,483,643; with default settings 500,000,000 throwsNullPointerExceptionthere and 858,993,460 returns 4 of 10 (executed first-signal probe), which is the sibling LFV-986. - History. The factor 10 is a recall heuristic (LUCENE-786, Karl Wettin: "I suppose that number (10) was something the original author came up with when testing");
:361came from the mechanical LUCENE-1856 "Remove Hits" migration. Nothing discusses bounds.
The devil's-advocate check219 words
The strongest case for "works as designed" (built by an intended-behaviour devil's advocate; reading-only reviewers from another model family, OpenAI GPT-5.6, rated it "moderate" and "weak"): a spell checker asked for hundreds of millions of suggestions is an odd request, and the javadoc's only guidance is small ("at least 5"; DirectSpellChecker adds "typically a low value for numSug will work very well"); PriorityQueue documents its up-front allocation, and SuggestWordQueue(int size, ...) takes "the size of the queue", so sizing it by numSug is designed use; in LUCENE-2119 the reporter called n = Integer.MAX_VALUE "a nonsense value to pass in, since our PQ impl allocates the array up front"; Integer.MAX_VALUE has never worked in any SpellChecker release, and a reviewer argued that "a clear validation exception would still be preferable".
Why it fails: LUCENE-2119 was still fixed as a bug, in the very search SpellChecker calls, and testHugeN keeps that contract; the request is feasible (with the fix every count, Integer.MAX_VALUE included, returns the full result at -Xmx512m); today's behaviour is not a clear validation exception but an overflow artifact about another parameter, plus a silent short result in other blocks. The argument does bear on priority (Low) and on the likely reply: a maintainer may prefer a bound check (option B) over saturation, and either resolves the bug.
Recommended Compute the budget in long and saturate it; size the queue by min(numSug, hits.length)
Compute the budget in long and cap it at Integer.MAX_VALUE (the search then caps it at the index size), and size the result queue by min(numSug, hits.length). Both lines are needed. Counts that do not overflow give the same results; silently short positive-wrap counts now get the full result. The test and the suggest module's 237 tests pass.
// saturate: 10 * numSug overflows int for numSug >= 214748365 (e.g. Integer.MAX_VALUE)
int maxHits = (int) Math.min(10L * numSug, Integer.MAX_VALUE); // was: 10 * numSug

ScoreDoc[] hits = indexSearcher.search(query.build(), maxHits).scoreDocs;
// size the queue by what the search can return, not by numSug
SuggestWordQueue sugQueue =
    new SuggestWordQueue(Math.min(numSug, hits.length), comparator); // was: numSug
All options and trade-offs3 options · 670 words
Three options; A was validated with gradle in a fresh scratch worktree at 645d4fe14a20, B and C were not executed. A maintainer may prefer B, a clear bound check; either resolves the bug. Separate choice: numSug = 0 also throws "numHits must be > 0" today (not claimed), while WordBreakSpellChecker returns an empty result for counts below 1; one change could handle both ends.
Compute the budget in long and saturate it; size the queue by min(numSug, hits.length) (validated by the checks) (recommended)
In SpellChecker.suggestSimilar, :361 becomes int maxHits = (int) Math.min(10L * numSug, Integer.MAX_VALUE); and :366 becomes new SuggestWordQueue(Math.min(numSug, hits.length), comparator). +4/-2 lines in one file, two of them comments.
// saturate: 10 * numSug overflows int for numSug >= 214748365 (e.g. Integer.MAX_VALUE)
int maxHits = (int) Math.min(10L * numSug, Integer.MAX_VALUE); // was: 10 * numSug

ScoreDoc[] hits = indexSearcher.search(query.build(), maxHits).scoreDocs;
// size the queue by what the search can return, not by numSug
SuggestWordQueue sugQueue =
    new SuggestWordQueue(Math.min(numSug, hits.length), comparator); // was: numSug
Trade-offs
- No change in results for counts that do not overflow. Up to 214,748,364 the product is exact, and the queue size is
numSugwhenevernumSug <= hits.length. WhennumSug > hits.length, a queue ofhits.lengthslots holds every inspected hit (at moststop <= hits.lengthinserts,:369), as the larger queue did; the "queue full" accuracy raise (:396-399) cannot fire in either version, because the queue never reachesnumSugentries. - Positive-wrap counts change on purpose. Today they can return a silently short result (429,496,730: 4 of 9); with the fix they return the full 9.
- Allocations are bounded by the spell index, not by the count. With the saturated budget
IndexSearchercapsnatmaxDoc, the pathtestHugeNcovers, and the queue getshits.length <= maxDocslots (a large spell index still means large allocations). - For
numSug <= 0the fix computes exactly today'smaxHitsand queue size, so behaviour there does not change. - Both lines are needed: with only the first,
Integer.MAX_VALUEfails inPriorityQueue("maxSize must be >= 0 and < 2147483631") and 214,748,365 runs out of memory at-Xmx512m. - The minimal test, as the regression test, covers only
Integer.MAX_VALUE; the positive-wrap leg was checked only with the tie-breaker's probe, and counts <= 0 are not tested.
What the checks validated
- Fresh scratch worktree at
645d4fe14a20, JDK 25.0.3, gradle with-Ptests.seed=DEADBEEF(2026-10-30): without the fix the minimal test fails with the seed's default,-Ptests.asserts=trueand-Ptests.asserts=false;git applyof the diff succeeds; with it,:lucene:suggest:checkGoogleJavaFormatand the minimal test pass (assertions on and off). --tests 'org.apache.lucene.search.spell.*': 9 suites, 32 tests, 0 failures, includingTestSpellChecker(6),TestDirectSpellChecker(6),TestWordBreakSpellChecker(5) andTestLuceneDictionary(6). The whole:lucene:suggest:test: 32 suites, 237 tests, 7 skipped, 0 failures.- Earlier, with the same fix shadowed onto the main jars: a 5-test probe passes at
-Xmx512m(Integer.MAX_VALUE, 214,748,365, 214,748,364 and 429,496,730 all return the 9 suggestions;-eaand-da), and upstreamTestSpellCheckerpassed 6 of 6.
For example if (numSug < 1 || numSug > Integer.MAX_VALUE / 10) throw new IllegalArgumentException(...) at the top of the 6-argument suggestSimilar. Not executed.
Trade-offs
Replaces the misleading exception and the silent short result with a clear error and needs no change at :366, but keeps "all suggestions" an error (unlike the search below, which accepts Integer.MAX_VALUE) and keeps the numSug-sized pre-allocation for large legal counts (381.7 MiB at 10^8).
The spell index holds one document per indexed word (SpellChecker.java:534-535; indexDictionary skips words shorter than 3 characters and words already in the spell index, :521-530), so at most maxDoc suggestions exist: clamp numSug to it, then compute the budget in long. Not executed.
Trade-offs
Same effect as A in one place, but it changes the numSug that the "queue full" check (:396) compares against, so it needs the same reasoning about unchanged results.
By code reading, Solr's index- and file-based spell checkers by default pass max(spellcheck.count, 5) to suggestSimilar and read spellcheck.count with no upper bound, so a huge count there would reach this exception (not executed).
A planning probe of numeric limits on public API arguments called suggestSimilar with Integer.MAX_VALUE and 214,748,365 on the stock jars and got "numHits must be > 0". A finder wrote the JUnit; a Z3 bit-vector model and an exact enumeration gave the boundaries and predicted the silent short-result leg, which an independent reproducer then ran.
The method in full183 words
Method: executed differential testing, then SMT modelling (the hunt's non-formal tier: the first signal was an executed probe, not a model).
- First signal. In a round on numeric limits of public API arguments, a planning probe ran
SpellChecker.suggestSimilaron a 10-word dictionary withInteger.MAX_VALUE, 214,748,365 and 10^8 on the stock jars of maina9779ef3c193, 10.5.2, 9.12.3 and the 10.6 release candidate (2026-10-28): the first two threw "numHits must be > 0", the third returned after a 381 MiB allocation. - Hunt. A finder wrote a public-API JUnit (2 of 2 fail with
-eaand-da), a Z3 bit-vector model of the budget (properties S1-S4, 18 checks, 0 unexpected) and an exact enumeration of the wrap blocks, located both lines by reading the code, and wrote and checked the two-line fix (and showed that a one-line fix only moves the failure). Found 2026-10-28. - Checks. An independent reproducer executed the modelled silent leg (4 of 7 suggestions); an intended-behaviour devil's advocate, an adjudication, a credibility audit, a current-main re-check and a tie-breaker confirmed it; the single test shown here is the audited reduction.
No earlier report found (searched 2026-10-29 and 2026-10-30, re-checked 2026-10-30). Closest: LUCENE-2119, the same failure class fixed in IndexSearcher, which never mentions SpellChecker.
Searches5 searches
Related, not this bug: #3195 (LUCENE-2119, the IndexSearcher cap), #11569 (LUCENE-10533, a different SpellChecker bounds check), #1861 (LUCENE-786) and SOLR-1676 (the factor 10 for small counts only), #9195 (LUCENE-8147, open: DirectSpellChecker parameter checks, numSug = 0 example; does not mention this class), #16847 and #13951 (the only open PRs touching SpellChecker.java; neither touches lines 361-369), and #8544, elastic/elasticsearch#57644 and OrchardCore#5983 (the same "numHits must be > 0" text from other code). Lucene.NET's port has the same two lines and no report. The sibling LFV-986 (DirectSpellChecker, numSug * maxInspections) is another fix site in the same module. No maintainer has commented on this bug.
| Where | When | How | Found |
|---|---|---|---|
| Search tool, three runs (GitHub issues/PRs/commits incl. the migrated JIRA archive; dev@ and java-user@; downstream repositories; web) | 2026-10-30 | class, method and overflow terms; the error texts across versions, spellcheck.count, OutOfMemoryError and NegativeArraySizeException; 16 GitHub variants incl. items updated since 2026-10-28 | no report of this bug |
| GitHub (apache/lucene, apache/solr, apache/lucene-solr, apache/lucenenet, Elasticsearch, OpenSearch, global), LUCENE/SOLR/LUCENENET JIRA, dev@, java-user@, solr-user@, users@solr, dev@solr | 2026-10-30 | manual searches; 201 recorded queries in all, 167 distinct | related items only (above) |
| Recent apache/lucene activity | 2026-10-30 | the file lists of 431 PRs (all 408 open plus every PR updated since 2026-10-28); bodies and comments of the 55 PRs and 16 issues updated since then | only #16847 and #13951 touch SpellChecker.java, not the fix site |
| Study search and recheck | 2026-10-29 | 163 queries over GitHub, JIRA, the lists and the web | verdict new |
| GitHub, re-check | 2026-10-30 | issues and PRs matching SpellChecker, suggestSimilar or numSug updated on 2026-10-30; #9195 read; the newest commit on the file | nothing new; the file unchanged on upstream main 2f424fd428da |
No regression: both halves were in the class as first written (2004), so every release from 1.9 to 10.6.0 fails. Only the exception changed: NegativeArraySizeException up to 2.9.1, "nDocs must be > 0" in 2.9.2 to 3.0.3, "numHits must be > 0" since 3.1.
Versions tested7 rows
Introduced with the class: 57cd0765650 (2004-11-02, "prelim checking of spellchecker, v1.1", committed by David Spencer; the class's @author tag names Nicolas Maisonneuve; SVN sandbox, no JIRA key) already had new SuggestWordQueue(num_sug) and Math.min(hits.length(), 10*num_sug) as the loop bound. d7d9241ef7b (LUCENE-1856 "Remove Hits", #2931, Michael Busch, 2009-10-07) made the product the searcher's top-N, int maxHits = 10 * numSug; (line 361 blames to it with git blame -w -M -C); first release 3.0.0, and on the 2.9 line 2.9.2 via the LUCENE-2108 backport be65c5c2e26. Since 3.1 the check sits in the top-N collector (LUCENE-2785), and the LUCENE-2119 cap at maxDoc keeps a negative n. 1.4.3 has no SpellChecker.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle and the standalone runner, -ea and -da): "numHits must be > 0" |
| 10.6.0, 10.5.2 (release jars) | affected | the minimal test fails, -ea and -da |
| 3.1.0 to 10.6.0 | 13 releases | a release-portable twin fails on 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and 10.6.0: "numHits must be > 0" |
| 2.9.2 to 3.0.3 | 5 releases | the twin fails on 2.9.2, 2.9.4, 3.0.0, 3.0.1 and 3.0.3: "nDocs must be > 0" |
| 1.9 to 2.9.1 | 6 releases | the twin fails on 1.9 (built from the tag), 1.9.1, 2.0.0, 2.4.1, 2.9.0 and 2.9.1: NegativeArraySizeException for Integer.MAX_VALUE, a silent [] for 214,748,365 |
| 1.4.3 | not affected | no SpellChecker |
fix A (scratch worktree at 645d4fe14a20) | not affected | the minimal test and the suggest module's 237 tests pass |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication, a credibility audit, a current-main re-check, a tie-breaker and a history sweep confirm it. Reading-only reviews by another model family agree on the root cause or could not run code. This doc re-ran the test and validated the fix with gradle.
Checks and verdicts324 words
Every cross-model review ran reading only and could not run Java; no executing cross-model review exists.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | 2-test JUnit fails 2 of 2 (-ea, -da); Z3 model and wrap enumeration; fix passes, half fix fails. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | procedural "not real" (low) | Could not run anything ("not a substantive refutation"); root cause agreed; a separate re-run fails 2 of 2. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Rated the works-as-designed case weak. |
| independent reproducer | real | Own 4-test JUnit fails 3 of 4 on main, 10.5.2 and 9.12.3; executed the silent leg (4 of 7) on main and 10.5.2; measured 381.7 MiB at 10^8. |
| intended-behaviour devil's advocate | real (medium-high) | Built the strongest intended case and rejected it; 214,748,364 returns the full result. |
| adjudication | confirmed (high); wrong error; Low | Re-ran the reproducer's tests (-ea, -da) and the silent-leg test. |
| credibility audit | keep | Fresh seed: 2 of 2 fail. |
| minimal-repro audit | verified | The one test fails on main (-ea, -da, two seeds) and passes with the fix. |
| current-main re-check | real | The test fails on main and 10.5.2 (-ea, -da); the fix passes. |
| second refute review (OpenAI GPT-5.6, reading only) | procedural "not real" | Two attempts; neither could run Java. |
| tie-breaker | real | The test fails on main, 10.5.2 and 10.6.0 (-ea, -da); own 5-test probe: exact threshold, frames, 4 of 9, DirectSpellChecker control; fix and half fix. |
| history sweep | not a regression | Twin fails on 24 releases from 1.9 to 10.6.0, the 10.6 release candidate and main. |
| this doc | reproduced, fix validated | Gradle in a fresh 645d4fe14a20 worktree: fails without the fix (assertions on and off), passes with fix A, with the spell package and the whole suggest module; ordinary-count control. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 512 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,407 words
- Registry title
- SpellChecker.suggestSimilar computes its hit budget 10 * numSug in int, so numSug = Integer.MAX_VALUE ('all suggestions'), 214748365 and every other count whose product wraps to <= 0 throw IllegalArgumentException 'numHits must be > 0' instead of returning the suggestions, and counts whose product wraps to a small positive value silently return fewer suggestions
- Area
- suggest / spell checking (SpellChecker.suggestSimilar hit budget 10 * numSug and SuggestWordQueue size)
- Priority
- Low, rank 628: The legacy SpellChecker throws a misleading IAE for numSug = Integer.MAX_VALUE and only truncates above about 429M, the same loud MAX_VALUE pre-size class as the SearchGroup.merge and MoreLikeThis rows.
- Impact class
- wrong error
- Impact note
- Applications on every release from 1.9 to 10.6.0 and main that call the n-gram SpellChecker.suggestSimilar (default settings suffice) with a huge suggestion count, most naturally Integer.MAX_VALUE as 'all suggestions', get IllegalArgumentException 'numHits must be > 0; please use TotalHitCountCollectorManager if you just need the total hit count' (since 3.1; 'nDocs must be > 0' in 2.9.2-3.0.x; NegativeArraySizeException or a silently empty result in 1.9-2.9.1) for every numSug whose 10 * numSug wraps to <= 0 (1,073,741,824 of the positive ints, the first being 214,748,365), at any dictionary size; in the positive-wrap blocks (the first being 429,496,730) the call silently inspects too few hits (4 instead of 7 suggestions on a 10-word dictionary), but only after pre-allocating a numSug-slot queue of at least 1.6 GiB, and every large legal count costs heap in proportion to numSug (about 381 MiB per call for 10^8); counts up to 214,748,364 give the right answer, and no index data or search results are affected.
- Summary
- You build an n-gram spell index with SpellChecker and call suggestSimilar(word, Integer.MAX_VALUE) to get all suggestions; you expect the same 9 suggestions that numSug 1000 returns on a 10-word dictionary. Instead SpellChecker multiplies numSug by 10 in int to size its search, the product wraps to -10, and the search throws IllegalArgumentException 'numHits must be > 0; please use TotalHitCountCollectorManager ...', naming a parameter the caller never passed; the same happens for half of all counts from 214,748,365 up, and in the blocks between (for example 429,496,730, whose product wraps to 4) the call silently returns fewer suggestions after allocating a queue of numSug slots. The fix is two lines: compute the budget in long and saturate it at Integer.MAX_VALUE, and size the queue by min(numSug, hits.length).
- Introduced
- 57cd0765650 (the initial SpellChecker contribution 'prelim checking of spellchecker, v1.1', committed by David Spencer; the class's @author tag names Nicolas Maisonneuve; svn r151014, sandbox, no JIRA key and no pull request): the class as first written already had both halves of the defect, the int product as loop bound 'int stop=Math.min(hits.length(), 10*num_sug)' and the count-sized 'new SuggestWordQueue(num_sug)'. The current exception symptom dates from d7d9241ef7b (LUCENE-1856 'Remove Hits', migrated as #2931, Michael Busch, 2009-10-07, svn r822587), which made 'int maxHits = 10 * numSug' the searcher's top-N (line 361 on main blames to it); the 2.9 line got the same code through the LUCENE-2108 backport be65c5c2e26 (2009-12-06) [read: git blame -w -M -C and git log on the history clone; exec: release sweep, see affected_versions] (2004-11-02 (author and commit date of 57cd0765650); current IllegalArgumentException symptom since 2009-10-07 (d7d9241ef7b, author and commit date))
- First affected version
- 1.9 (tag 2006-02-27) [read: the first release that contains SpellChecker, in contrib/spellchecker; the 1.4.3 tree has no SpellChecker.java]; oldest executed: 1.9.1 [exec]. The current IllegalArgumentException symptom starts at 3.0.0 (trunk) and 2.9.2 (2.9 line)
- Affected versions
- Every release that has SpellChecker: 1.9 to 10.5.2, 10.6.0 (released 2026-10-29; run as its RC, branch_10_6 4ae946e5a9b9) and main a9779ef3c193. Executed with -da on 22 releases plus the 10.6 RC and main, all failing [exec]: 1.9.1, 2.0.0, 2.4.1, 2.9.0, 2.9.1 (Integer.MAX_VALUE -> NegativeArraySizeException from the numSug + 1 queue; 214748365 -> silently [] instead of 9 suggestions), 2.9.2, 2.9.4, 3.0.0, 3.0.1, 3.0.3 ('nDocs must be > 0'), 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0 ('numHits must be > 0; please use TotalHitCountCollector ...'), 9.12.3, 10.0.0, 10.5.2, the 10.6 RC and main ('... TotalHitCountCollectorManager ...'); also the finder's main() twin on 8.0.0 and its JUnit on 9.12.3 and 10.5.2 (-ea). The rest by reading: the product line has not changed since d7d9241ef7b, and before it the same product was the loop bound since 57cd0765650. The positive-wrap truncation leg was executed on main and 10.5.2 (-da, -Xmx4g) and applies to the other releases by reading. Not fixed upstream: upstream main 645d4fe14a20 still has lines 361, 364 and 366 (read 2026-10-29), and the newest commit on SpellChecker.java on upstream main is 378ca8d1bbf3 (2026-01-15, javadoc tags) (recheck 2026-10-29). Caveat: all runs used JDK 25.0.3 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-29, read-only; recheck 2026-10-29): three scripted prior-report searches (a-core 58 queries, b-symptom 56, c-manual-gh 16 GitHub variants including PRs created or updated since 2026-10-26) plus manual searches, 163 queries in total, over apache/lucene issues and PRs (open and closed, including the migrated JIRA archive), the LUCENE and SOLR JIRA archives (8 JQL queries), the dev@, java-user@, issues@ and commits@ Lucene lists and solr-user@ / users@solr, apache/solr, apache/lucene-solr, apache/lucenenet, elastic/elasticsearch, opensearch-project/OpenSearch and the web, and the file lists of all 72 apache/lucene PRs updated since 2026-10-26 (none touches SpellChecker, SuggestWordQueue, IndexSearcher, TopScoreDocCollectorManager or PriorityQueue). Related, not the same bug: LUCENE-2119 (#3195, 2009) fixed the same failure class in IndexSearcher by capping n at maxDoc and never mentions SpellChecker (SpellChecker's int product wraps before that cap); LUCENE-786 (#1861) and SOLR-1676 discuss the factor 10 for small counts only; LUCENE-10533 (#11569) is a different SpellChecker bounds bug (formGrams). Lucene.NET's port has the same two lines and no report. Recheck: no apache/lucene PR mentioning SpellChecker and no issue mentioning suggestSimilar was updated since 2026-10-27; 'numSug' finds only the issues #3581, #2376 and #1861 and no PR; upstream main still has 'int maxHits = 10 * numSug;' and 'new SuggestWordQueue(numSug, comparator)'.
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT): the minimal test with gradle in a fresh scratch worktree, 2026-10-30 (fails without the fix with assertions on and off; with fix A it passes, together with the spell package's 32 tests, the suggest module's 237 tests and the format check), and with the standalone runner (-ea,-da); an ordinary-count control (5, 1,000 and 214,748,364 return[lucene]); the 10.5.2 and 10.6.0 release jars (the minimal test fails). The hunt ran on maina9779ef3c193, whereSpellChecker.javais the same blob; the history sweep ran a release-portable twin on 24 releases from 1.9 to 10.6.0, the 10.6 release candidate and main.SpellChecker.javais unchanged on upstream main2f424fd428da(2026-10-30).
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/spell/SpellChecker.java:232-236 and :289-293 (javadoc: 'at least 5', '@param numSug the number of suggested words'), :361 (int maxHits = 10 * numSug), :364 (indexSearcher.search(query.build(), maxHits)), :366 (new SuggestWordQueue(numSug, comparator)), :369 (loop bound min(hits.length, maxHits)); lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:587-599 (cappedNumHits = min(numHits, max(1, maxDoc))); TopScoreDocCollectorManager.java:62-64 ('numHits must be > 0'); lucene/core/src/test/org/apache/lucene/search/TestIndexSearcher.java:78 (testHugeN, '// should not throw exception')
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/spell/SpellChecker.java:224-243, :254-269, :275-279, :289-307, :332-334, :361, :364, :366, :369, :372-401a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:587-602, :623-625; lucene/core/src/java/org/apache/lucene/search/TopScoreDocCollectorManager.java:62-65a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/spell/SuggestWordQueue.java:51-53; lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:34-35, :39, :121-134a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/search/TestIndexSearcher.java:78-79, :101
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/spell/SpellChecker.java:227-236, :303-305; lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:34-35, :39; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:597a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/spell/DirectSpellChecker.java:25, :67, :311, :314, :359, :426; lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java:81-83, :91github.com/apache/lucene/issues/3195 (LUCENE-2119, read with gh issue view, 2026-10-30); github.com/apache/lucene/issues/11569 (LUCENE-10533, read with gh issue view, 2026-10-30)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/spell/SpellChecker.java:361, :366, :369, :396-399, :521-535; lucene/suggest/src/java/org/apache/lucene/search/spell/WordBreakSpellChecker.java:81-83
- TestSpellCheckerNumSugOverflow.java (lucene/suggest, package org.apache.lucene.search.spell, 1 test):
repro/LFV-996/src/org/apache/lucene/search/spell/TestSpellCheckerNumSugOverflow.java(38 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro, the tie-break runs and an executed probe on the stock main jars (one-word index, -ea and -da, with and without the fix).
assets/LFV-996/bug.png(512 KB)