SortRescorer re-sorts a list of hits it is given, so it can never return more than that many. Yet it sizes its sort collector by topN, and the collector reserves arrays of length topN up front. Ask for Integer.MAX_VALUE ("all of them") and it tries to reserve about 2 billion slots for 5 hits.
- A first-pass search returns the best hits as
TopDocs, for example the top 1,000 by BM25. - A
Rescorerre-orders those hits:rescore(searcher, firstPassTopDocs, topN)returns at mosttopNof them.QueryRescorermixes in a second query,DoubleValuesSourceRescorera per-document value, andSortRescorer(andExpression#getRescorer) re-sorts them by aSort. - Lucene's top-N collectors reserve their N slots up front:
TopFieldCollectorManagerdocuments that its collectors "pre-allocate a full array of length numHits".
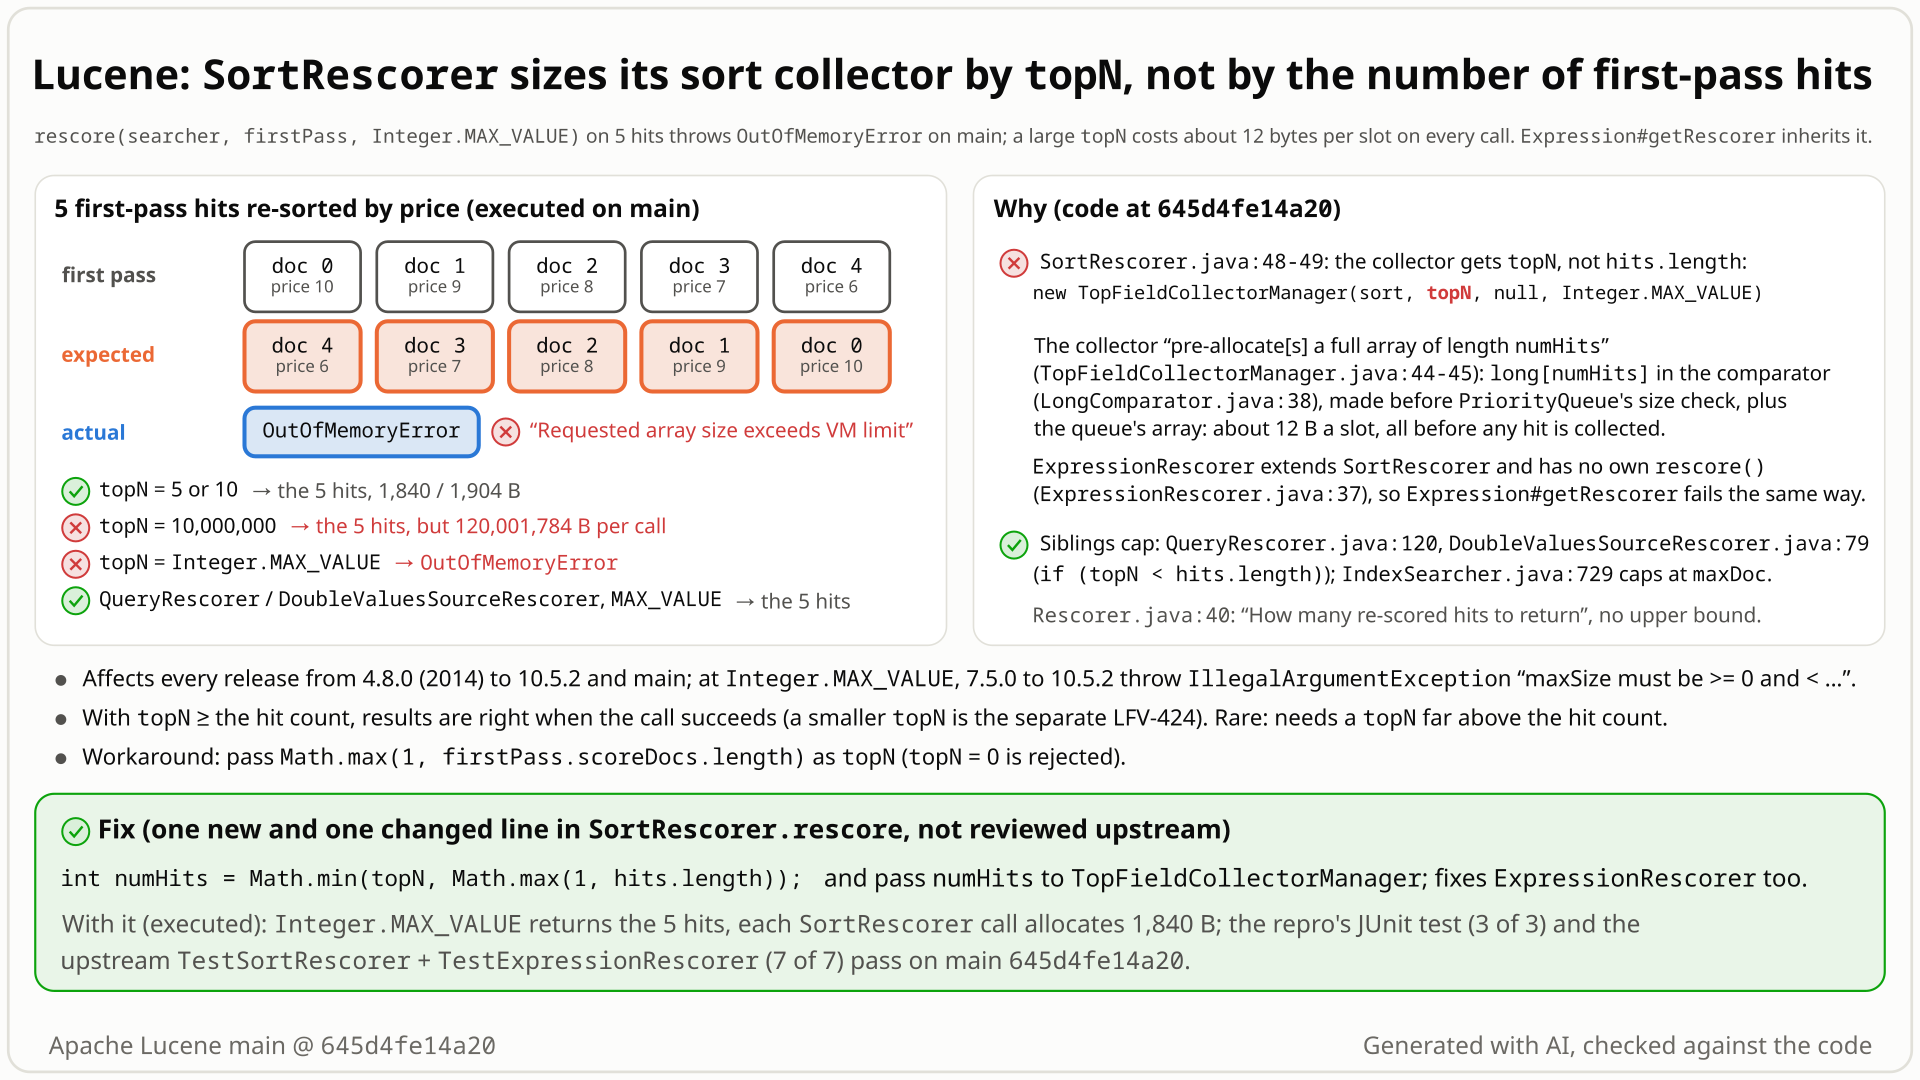
645d4fe14a20: the first pass, the collector sized by topN, the OutOfMemoryError, the memory of one call against topN, and the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index 5 documents with a
pricedoc value (10, 9, 8, 7, 6) and run a first-pass search that returns all 5. - Re-sort them by price with
new SortRescorer(sort).rescore(searcher, firstPass, Integer.MAX_VALUE), meaning "all of them". You expect the 5 hits, prices [6, 7, 8, 9, 10]: whattopN= 5 or 10 returns, and whatQueryRescorerandDoubleValuesSourceRescorerreturn for anytopN >= 0. - Instead main throws
OutOfMemoryError: Requested array size exceeds VM limit, and 7.5.0 to 10.6.0 throwIllegalArgumentException: maxSize must be >= 0 and < 2147483631. - Why:
rescorebuilds its sort collector fortopNhits (SortRescorer.java:48-49), and the collector reserves arrays of that length up front, although it only ever receives the 5 hits it is given. - Below the array limit the call can succeed but pays for
topN(about 12 bytes per slot): 1,840 bytes attopN= 5, 120,001,784 bytes (120 MB) attopN= 10^7, for the same 5 hits.Expression#getRescorerinherits the same code.
Applications that re-sort first-pass hits with SortRescorer or Expression#getRescorer and pass a topN far above the hit count, typically Integer.MAX_VALUE for "all". No setting needed, any index size, every release since 4.8.0. Loud at the extremes; below them, silent memory in proportion to topN. Rare: the documented use keeps topN below the hit count.
Mechanism, terms and numbers755 words
SortRescorer.rescore(searcher, firstPassTopDocs, topN) re-sorts the hits it is given, so it can never return more than firstPassTopDocs.scoreDocs.length of them. It still builds its TopFieldCollector with numHits = topN (SortRescorer.java:48-49 on main 645d4fe14a20), and that collector pre-allocates arrays of length numHits (TopFieldCollectorManager.java:44-45). So topN = Integer.MAX_VALUE, a common way to say "re-sort all of them" (it works with the sibling rescorers and IndexSearcher), throws on 5 hits: OutOfMemoryError: Requested array size exceeds VM limit on main, IllegalArgumentException: maxSize must be >= 0 and < 2147483631 in 7.5.0 to 10.6.0 (NegativeArraySizeException in 4.9.1 to 7.4.0). A topN that fits the array limit but not the heap throws OutOfMemoryError: Java heap space, and below that every call allocates about 12 bytes per topN slot for one long sort field, whatever the hit count: 120 MB for 5 hits at topN = 10^7. QueryRescorer and DoubleValuesSourceRescorer return min(topN, hits) for any topN >= 0, and IndexSearcher caps numHits at maxDoc. Expression#getRescorer returns a subclass that inherits rescore(). Every release since 4.8.0 (2014) has it. In these topN >= hits.length calls the returned hits, order and sort values are correct whenever the call succeeds (a smaller topN hits the separate LFV-424). Fix (one new line, one changed line): size the collector with Math.min(topN, Math.max(1, hits.length)).
- Rescorer:
Rescorer#rescore(IndexSearcher searcher, TopDocs firstPassTopDocs, int topN), documented as "@param topN How many re-scored hits to return" (Rescorer.java:40), with no bound.Rescoreris@lucene.experimental(:30). - SortRescorer: "A Rescorer that re-sorts according to a provided Sort" (
SortRescorer.java:27).Expression#getRescorer(bindings)returns anExpressionRescorer(Expression.java:112-114), which extendsSortRescorer, never overridesrescore()and is documented as "Functionally ... the same as SortRescorer" (ExpressionRescorer.java:30-37). - Pre-allocation: "The instances returned by this method pre-allocate a full array of length
numHits" (TopFieldCollectorManager.java:44-45). For a long sort field that isnew long[numHits](LongComparator.java:38), plus the queue'snew Object[maxSize + 1](PriorityQueue.java:129-134).
rescoreclones the first-pass hits and sorts them by doc id (SortRescorer.java:42-44), sohits.lengthis known.- It then builds
new TopFieldCollectorManager(sort, topN, null, Integer.MAX_VALUE).newCollector()(SortRescorer.java:48-49): the size is the caller'stopN. newCollector()callsFieldValueHitQueue.create(sort.getSort(), numHits)(TopFieldCollectorManager.java:112-114), which builds one comparator of that size per sort field (FieldValueHitQueue.java:139-151) and then the queue (:153), whose guard rejectsmaxSize >= ArrayUtil.MAX_ARRAY_LENGTHwithIllegalArgumentException(PriorityQueue.java:121-124, "Throw exception to prevent confusing OOME").- The loop then feeds only the
hits.lengthhits (SortRescorer.java:60-82);:86even assertshits.length == rescoredDocs.scoreDocs.length. Every slot beyondhits.lengthis never used. - On main, #14873 (unreleased) builds the comparators before the queue's guard runs, so
new long[Integer.MAX_VALUE]fails first withOutOfMemoryError; that ordering is the separate bug LFV-993 (different fix site). Releases reach the guard and throwIllegalArgumentException.
5 hits, prices 10, 9, 8, 7, 6, one long sort field, main 645d4fe14a20, -Xmx1g. Bytes allocated by one SortRescorer.rescore call: 1,840 at topN = 5; 1,904 at 10; 13,784 at 1,000; 12,001,784 at 10^6; 120,001,784 at 10^7: about 12 bytes per topN slot (in this probe exactly 1,784 + 12 x topN for even topN, 4 bytes less for odd topN such as 5, from the 8-byte alignment of the queue's Object[topN + 1]; the constant depends on the index, and the figures are for one JVM with compressed references). topN = 2,147,483,630 throws OutOfMemoryError: Java heap space; Integer.MAX_VALUE throws OutOfMemoryError: Requested array size exceeds VM limit. With the fix: 1,840 bytes at every topN, the 5 hits always returned. QueryRescorer (12,856 bytes) and DoubleValuesSourceRescorer (3,744 bytes) allocate the same at topN = 10^7 and at Integer.MAX_VALUE and return the 5 hits, as does IndexSearcher.search(q, Integer.MAX_VALUE, sort).
- Needs:
SortRescorerorExpression#getRescorerwith atopNfar above the number of first-pass hits. AnySort, any index size, no setting. - Not affected:
QueryRescorer,DoubleValuesSourceRescorerandIndexSearcher.search(q, n, sort)(which capsnatmaxDoc,IndexSearcher.java:721,:729). - What stays right: in these
topN >= hits.lengthcalls, whenever the call succeeds, the hits, their order and their sort values are correct. - Not claimed:
topN <= 0(attopN= 0SortRescorerthrows "numHits must be > 0", likeIndexSearcher.search(q, 0); a negativetopNthrowsIllegalArgumentExceptionin all three rescorers). - Same method, different bug: with
topNbelow the hit count, returned hits get another hit's score (LFV-424).
Exposure and likelihood236 words
- Who is hit. Code that re-sorts collected hits with
SortRescoreror an expression and asks for all of them. That use is real: on java-user (2021-11-30, "How to change sorting after getting search results") Michael Sokolov pointed a user who collects all hits and re-sorts them to the Rescorers, and the user pickedSortRescorer(credit: Michael Sokolov). - Default or opt-in. No setting is needed; any
Sort, any index size. The API itself is opt-in and@lucene.experimental. - Effect. At
Integer.MAX_VALUE:OutOfMemoryErroron main (anError, which code catchingRuntimeExceptionfor bad arguments does not see, and which makes a JVM run with-XX:+ExitOnOutOfMemoryErrorexit),IllegalArgumentExceptionnaming an internalmaxSizein 7.5.0 to 10.6.0,NegativeArraySizeExceptionin 4.9.1 to 7.4.0. AtopNthat fits the array limit:OutOfMemoryError: Java heap space. Below that: no error, about 12 bytes pertopNslot on every call. The heapOutOfMemoryErrordepends on the heap (runs used-Xmx1g). - Gradle detail. Lucene's test task runs with
-XX:+HeapDumpOnOutOfMemoryError, so on main the repro also writes a heap dump of about 50 MB intolucene/core/build/tests-cwd/. - How likely: rare. The package docs describe
topNbelow the hit count ("the best 1,000 hits by BM25 score may be sorted by descending popularity in order to compute the final top-100 hits"); the failure is loud at the extremes, so a developer meets it in testing; no matching public report was found.
The test shows that SortRescorer.rescore with topN = Integer.MAX_VALUE ('re-sort all hits') fails on 2 first-pass hits, because it sizes its TopFieldCollector by topN instead of by the hit count.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.util.List;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSortRescorerMaxTopN extends LuceneTestCase {

  public void testTopNIntegerMaxValue() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (int i = 0; i < 2; i++) {
          w.addDocument(List.of(new NumericDocValuesField("price", i)));
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        TopDocs firstPass = searcher.search(new MatchAllDocsQuery(), 10);
        Rescorer rescorer = new SortRescorer(new Sort(new SortField("price", SortField.Type.LONG)));
        try {
          TopDocs rescored = rescorer.rescore(searcher, firstPass, Integer.MAX_VALUE);
          assertEquals(2, rescored.scoreDocs.length);
        } catch (OutOfMemoryError | IllegalArgumentException e) {
          // Expected: the 2 hits come back re-sorted (as with topN = 2); actual: rescore throws.
          throw new AssertionError("expected 2 re-sorted hits, but rescore threw " + e, e);
        }
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-997/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestSortRescorerMaxTopN
- Expected vs actual
- Expected: the 2 hits come back re-sorted (as with topN = 2). Actual (-ea and -da): OutOfMemoryError 'Requested array size exceeds VM limit' at SortRescorer.rescore:49 (IllegalArgumentException in 10.x/9.x releases).
More files, environment, full output56 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected 2 re-sorted hits, but rescore threw java.lang.OutOfMemoryError: Requested array size exceeds VM limit
       org.apache.lucene.search.TestSortRescorerMaxTopN.testTopNIntegerMaxValue(TestSortRescorerMaxTopN.java:46)
     Caused by: java.lang.OutOfMemoryError: Requested array size exceeds VM limit
       org.apache.lucene.search.comparators.LongComparator.<init>(LongComparator.java:38)
       org.apache.lucene.search.SortField.getComparator(SortField.java:503)
       org.apache.lucene.search.FieldValueHitQueue.create(FieldValueHitQueue.java:146)
       org.apache.lucene.search.TopFieldCollectorManager.newCollector(TopFieldCollectorManager.java:114)
       org.apache.lucene.search.SortRescorer.rescore(SortRescorer.java:49)
[...]Rescorer#rescoredocuments only "@param topN How many re-scored hits to return";QueryRescorerandDoubleValuesSourceRescorerreturn min(topN, hits) under that same contract.- Upstream
TestSortRescorerandTestExpressionRescoreralready callrescore(..., 10)on 3 hits. IndexSearchercapsnumHitsatmaxDocfor exactly this case (LUCENE-2119: "Don't throw ... if you pass Integer.MAX_VALUE as nDocs"), andTestIndexSearcher.testHugeNchecks it.
The full argument284 words
- Contract.
Rescorer.java:40: "@param topN How many re-scored hits to return", no bound and no cost note. The pre-allocation NOTE sits onTopFieldCollectorManager(:44-45), an implementation detail the caller ofSortRescorernever sees. - Siblings.
QueryRescorer.java:120-123andDoubleValuesSourceRescorer.java:79-82:if (topN < hits.length)selecttopN, otherwise return every hit. The same call returns the hits for two rescorers and throws for the third.ExpressionRescoreris documented as "Functionally ... the same as SortRescorer". - Tests.
TestSortRescorer.java:96,:134andTestExpressionRescorer.java:106callrescore(searcher, hits, 10)on 3 hits; the assert atSortRescorer.java:86(hits.length == rescoredDocs.scoreDocs.length) holds only whentopNis at least the hit count. - Precedent. LUCENE-2119: "Don't throw NegativeArraySizeException if you pass Integer.MAX_VALUE as nDocs to IndexSearcher search methods"; LUCENE-4938: "Don't use an unnecessarily large priority queue in IndexSearcher methods that take top-N" (
lucene/CHANGES.txt:18439-18441,:13901-13902).IndexSearchercaps atmax(1, maxDoc)(IndexSearcher.java:721,:729) andTestIndexSearcher.testHugeN("should not throw exception") callssearch/searchAfterwithInteger.MAX_VALUE, with and without aSort. As Michael McCandless wrote on SOLR-5661: "Lucene's IndexSearcher tries to prevent this, when you ask for Integer.MAX_VALUE as the topN hits to the search method, it drops that to the maxDoc for the reader" (the precedent and its framing are theirs).testHugeNas precedent was first pointed out by an independent reviewer from another model family (OpenAI GPT-5.6), in its review of a sibling candidate of the same hunt (RescoreTopNQueryand theLatLonPointnearest queues). - History. The line has passed
topNsince the class was written (LUCENE-5545, 2014); the 8 later commits that changed it are API migrations that keeptopN(e.g.38ca8d3e42cLUCENE-10002,bc18828fccc#13977), and the issue thread never discusses sizing.
The devil's-advocate check289 words
The intended-behaviour checker, the reviewers from another model family (OpenAI GPT-5.6) and the adjudication built the strongest case: the pre-allocation is documented, the caller chooses topN, Rescorer is @lucene.experimental, the documented use keeps topN below the hit count, and the LUCENE-2119 description (2009) even called Integer.MAX_VALUE "a nonsense value to pass in, since our PQ impl allocates the array up front". Direct users of TopFieldCollectorManager and TopScoreDocCollectorManager choose N and get an N-sized collector by design. So the answer could be "pass scoreDocs.length". The cross-model fact check rates this case moderate. On the related open #9588 (LUCENE-8542), Adrien Grand wrote that Lucene computes "the top-k matches of a query for some reasonable value of k" (credit them if this framing is used).
Why it fails: the NOTE is on the collector manager, not on SortRescorer or Rescorer; the same LUCENE-2119 text goes on "This trips users up fairly often because they assume our PQ doesn't statically pre-allocate (a reasonable assumption...)", and that issue was resolved by capping, not by rejecting the input (Michael McCandless, who on #9588 also called full-topN pre-allocation "really unexpected behavior"); the sibling rescorers in the same API cap; upstream tests use topN above the hit count; @lucene.experimental permits changing the API, which a cap does not need; and a topN that passes the queue's guard still fails on the heap, while a smaller one silently costs 120 MB for 5 hits. Sizing by N fits a collector that cannot know how many hits will arrive; SortRescorer already holds the finite hit list, so the exact bound, hits.length, is in hand. Verdict: not intended; expect the "pass scoreDocs.length" reply and answer it with the siblings and the IndexSearcher precedent.
Recommended Cap the collector at the number of first-pass hits
Size the collector by the hits it can actually return: int numHits = Math.min(topN, Math.max(1, hits.length)); in SortRescorer.rescore, one new line and one changed line. It fixes Expression#getRescorer too. Validated on main: the repro passes, as do the rescorer tests of core and expressions, the org.apache.lucene.search test package and check.
// The collector pre-allocates numHits slots, and at most hits.length hits can come back:
int numHits = Math.min(topN, Math.max(1, hits.length));
TopFieldCollector collector =
    new TopFieldCollectorManager(sort, numHits, null, Integer.MAX_VALUE).newCollector();
All options and trade-offs3 options · 421 words
One fix was built and validated; two alternatives were not built. LFV-993's fix (the allocation order in FieldValueHitQueue on main) is separate: it would turn main's OutOfMemoryError back into the release IllegalArgumentException, but this call would still fail and still allocate by topN.
In SortRescorer.rescore, before the collector is built (1 file, +3/-1). The finder and the independent reproducer each wrote the same expression; a Z3 check of the hunt shows the size stays in [1, MAX_ARRAY_LENGTH) and that min(size, hits) == min(topN, hits) for every topN >= 1.
// The collector pre-allocates numHits slots, and at most hits.length hits can come back:
int numHits = Math.min(topN, Math.max(1, hits.length));
TopFieldCollector collector =
    new TopFieldCollectorManager(sort, numHits, null, Integer.MAX_VALUE).newCollector();
Trade-offs
- Same results for every
topN >= 1: the collector never holds more thanhits.lengthentries anyway.max(1, ...)keeps an empty first pass legal (TopFieldCollectorManagerrejectsnumHits <= 0);topN <= 0is still rejected, as today. - Fixes
Expression#getRescorer(inherited). MatchesQueryRescorer,DoubleValuesSourceRescorerandIndexSearcher's cap. - Leaves LFV-424 (
topNbelow the hit count) and LFV-993 (main's allocation order) as they are.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle, JDK 25.0.3. Stock + the repro test: 1 test, 1 failed (OutOfMemoryError), assertions on and off. - Fix + the repro test:
TestSortRescorerTopN,TestSortRescorer,TestQueryRescorerandTestDoubleValuesSourceRescorer15 tests,TestExpressionRescorer4 tests, 0 failed, with-Ptests.asserts=trueandfalse. - Fix: the whole
org.apache.lucene.search.*test package oflucene/core: 215 suites, 2,340 tests, 49 skipped, 0 failed;:lucene:core:check -x test(google-java-format, ecjLint, forbiddenApis): passes. The full Lucene suite was not run. - The finder's 3-test JUnit (
SortRescoreratInteger.MAX_VALUEand attopN= 2,147,483,630,Expression#getRescoreratInteger.MAX_VALUE) with the fixed class: 3 of 3 pass. With the fix one call allocates 1,840 bytes at everytopNfor 5 hits.
Math.min(topN, Math.max(1, searcher.getIndexReader().maxDoc())). Not built.
Trade-offs
Consistent with IndexSearcher.java:721, but still allocates in proportion to the index size for a handful of hits; hits.length is the exact bound and is already in hand.
A javadoc NOTE on SortRescorer/Rescorer, or an IllegalArgumentException for topN > hits.length. Not built.
Trade-offs
Rejecting breaks the upstream tests that call rescore(..., 10) on 3 hits and makes SortRescorer stricter than its siblings; a NOTE alone leaves the Integer.MAX_VALUE idiom broken.
Solr's re-ranking passes topN equal to the hit count, so it does not reach this path (as Christine Poerschke noted in apache/solr#478); for Elasticsearch and OpenSearch the prior-art search ran keyword queries, but whether they call SortRescorer with a large topN was not analysed.
A planning probe looking for unbounded size arguments ran SortRescorer and Expression#getRescorer with topN = Integer.MAX_VALUE on 5 hits and got OutOfMemoryError where the other rescorers returned the hits. The hunt confirmed it with a bounded differential harness and a JUnit, and checked the one-line cap with Z3.
The method in full188 words
Method: non-formal first signal, then a differential harness (the hunt's hunt unit for rescorers and other top-N queues pre-sized by an unbounded topN, 2026-10-28, main a9779ef3c193).
- Lead. A planning probe of a numeric-limits round read the code and ran
SortRescorerandExpression#getRescorerattopN=Integer.MAX_VALUE, 10^8 and 10^7 on 5 hits:OutOfMemoryError, a heapOutOfMemoryErrorafter 762 MiB under a 1 GiB heap, and 114 MiB allocated, while theQueryRescorerandDoubleValuesSourceRescorercontrols returned the 5 hits. - Harness. A bounded-exhaustive differential harness on the stock jar: 39 index layouts of 1 to 3 segments x 11
topNvalues, with oracles for the prefix property, the exact hit count, a reference sort model and an O(hits) memory bound. 234SortRescorer/ExpressionRescorerfailures (every layout at the two largesttopNvalues, plus the memory oracle), 0 for the controls, 0 with the fix. - Z3. Bit-vector obligations show the cap
Math.min(topN, Math.max(1, hits.length))stays in[1, MAX_ARRAY_LENGTH)and keepsmin(size, hits) == min(topN, hits); two mutants are caught. - JUnit. Reduced to a public-API JUnit; this doc then reduced it to the one-method test above.
No prior report found (searched 2026-10-29, refreshed): 59 tool queries over GitHub, commits, downstream trackers, four mailing lists, the JIRA archive and the web, 17 own GitHub searches and the changed files of 201 PRs. Closest: open #9588, the same pre-allocation pattern in IndexSearcher's per-slice collectors.
Searches6 searches
Related, not reports of this bug: open #9588 (LUCENE-8542), the same pre-allocation class at a different fix site, with no mention of rescorers; #3195 (LUCENE-2119) and #6002 (LUCENE-4938), where IndexSearcher started capping numHits at maxDoc; SOLR-5661, which added the PriorityQueue size guard; #9999 (LUCENE-8956), QueryRescorer only (Adrien Grand suggested checking rescorers against topN = numDocs there); #6608 (LUCENE-5545), the origin, which never discusses sizing; apache/solr#478. Open PRs: only #16847 (draft, long doc ids) edits SortRescorer.java, and it keeps topN; #16857 edits TopFieldCollectorManager/FieldValueHitQueue for Sort pruning without a size cap. Tracking issue #16937 does not mention rescorers. Gaps: GitHub search returns at most 50 results per query; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and downstream trackers | 2026-10-29 | a scripted prior-report search (24 GitHub issue/PR queries on apache/lucene with class names, topN/numHits phrasings and the error texts, 3 commit, 2 downstream); 17 own searches incl. Solr, Elasticsearch, OpenSearch | no report; the related items above |
| Open and recently closed PRs | 2026-10-29 | the changed files of 201 PRs (open PRs updated since 2026-09-29, closed PRs updated since 2026-10-14); rechecks of all 47 PRs updated since 2026-10-27 and of every PR updated since a recent cutoff | only #16847 edits SortRescorer.java (doc-id types only); none caps topN |
| Mailing lists | 2026-10-29 | 20 tool queries over dev@, java-user@, issues@ and commits@, plus lists.apache.org queries | no report; the 2021-11-30 java-user thread shows the re-sort-all use case |
| JIRA archive | 2026-10-29 | 4 tool queries and JIRA REST queries, incl. the SOLR project | no report; LUCENE-2119, LUCENE-4938 and SOLR-5661 are precedents |
| Web | 2026-10-29 | 6 tool queries and 7 web searches | no report |
| Upstream fix status | 2026-10-29 | upstream main head and the newest commits on SortRescorer.java | main is 645d4fe14a20; the newest commit on the file is e5eb7e763ac (2025-06-30, a rename) |
Introduced with the class in 4.8.0 (LUCENE-5545, cbd8cacc50c9, 2014); not a regression. All 16 executed versions from 4.8.0 to main fail with the controls passing. Only the exception at Integer.MAX_VALUE changed over time, through PriorityQueue changes elsewhere.
Versions tested6 rows
Introduced by cbd8cacc50c9 on trunk, "LUCENE-5545: add SortRescorer and Expression.getRescorer" (Michael McCandless, 2014-03-23, svn r1580490; CHANGES credits Simon Willnauer, Robert Muir, Mike McCandless; migrated as #6608, no PR), shipped through the branch_4x port 6970ada1746a (svn r1580491, the same day) in 4.8.0, the release that added the Rescorer API. The first version already called TopFieldCollector.create(sort, topN, ...); all 23 revisions of the file create the collector from topN, and the 8 later commits that changed the line are API migrations only (e.g. 38ca8d3e42c LUCENE-10002, bc18828fccc #13977).
The exception changed, the bug did not: SOLR-5661 (4.7.0) gave PriorityQueue its size guard (IllegalArgumentException in 4.8.0); LUCENE-5844 (4.9.1, 4.10.0) moved it after maxSize + 1, which wraps at Integer.MAX_VALUE (NegativeArraySizeException until 7.4.0); 154952f47d8 (7.5.0) restored the IllegalArgumentException; #14873 (main only) allocates the comparators first (OutOfMemoryError, LFV-993).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 and a9779ef3c193 | affected | OutOfMemoryError "Requested array size exceeds VM limit" at Integer.MAX_VALUE; heap OOM below; 120 MB per call at topN = 10^7 |
7.5.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 4ae946e5a9b9 | affected | IllegalArgumentException "maxSize must be >= 0 and < 2147483631"; heap OOM below; about 120 MB at 10^7 |
| 4.9.1, 4.10.0, 4.10.4, 5.5.5, 6.6.6, 7.4.0 | affected | NegativeArraySizeException at Integer.MAX_VALUE; heap OOM below |
| 4.8.0 | affected | IllegalArgumentException "maxSize must be <= 2147483391"; heap OOM below; 120 MB at 10^7 |
| 4.7.2 | API absent | no Rescorer API (compile error) |
| main + fix | not affected | the 5 hits at every topN, 1,840 bytes per call; rescorer suites and the search test package pass |
An independent reproducer, an intended-behaviour devil's advocate and reading-only reviews by another model family (OpenAI GPT-5.6) agree on the root cause; the adjudication re-ran the independent test and confirmed it with high confidence. This doc re-ran a one-method repro on 645d4fe14a20 and validated the fix with gradle.
Checks and verdicts383 words
The cross-model reviews were reading-only: they could not run Java. The refute-lens review returned a procedural "not real, low" while agreeing on the root cause; a separate re-run failed 3 of 3. An executing cross-model review is still open.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit 3 of 3 fail on main (-ea, -da), the 10.6 RC, 10.5.2 and 9.12.3; harness 234 failures for the two classes, 0 for the controls, 0 with the fix. |
| cross-model review, intended lens | real, medium | OpenAI GPT-5.6, reading-only; judged the intended-behaviour case weak and pointed to IndexSearcher's maxDoc cap and LUCENE-2119 (the testHugeN pointer came from the same reviewer's review of a sibling candidate). A separate run re-ran the repro: 3 of 3 fail. |
| Independent reproducer | real | Own public-API JUnit (4 docs in 2 segments) fails 3 of 5 on main, 10.5.2 and 9.12.3, controls pass; 120,003,312 bytes at topN = 10^7; own one-line fix passes 5 of 5. |
| Cross-model review, refute lens | not real, low (procedural) | OpenAI GPT-5.6, reading-only, could not run anything; its notes call the verdict "a procedural default rather than a substantive refutation"; root cause agreed, intended case weak. |
| Intended-behaviour devil's advocate | real, low impact | Argued the documented pre-allocation, @lucene.experimental, caller choice and the LUCENE-2119 remark, and rejected each; re-ran the repro: 3 of 3 fail. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test with a new seed on main, -ea and -da: 3 of 5 fail each, same frames. Class wrong error. |
| credibility audit | keep | Re-ran the repro on main: 3 of 3 fail; not a merge with LFV-424 or LFV-993. |
| this doc | confirmed on 645d4fe14a20 | The one-method repro fails through gradle and the standalone runner, assertions on and off, and on 10.5.2; the fix validated. |
| fact check | substantively correct; 4 fixes applied | Re-ran the repro through gradle (the doc's command and a new seed) and the standalone runner, -ea and -da, on main and on 10.5.2, and the fix suites; 4 wording and citation errors, fixed. |
| cross-model fact check | 5 factual errors, fixed; intended case moderate | OpenAI GPT-5.6, reading only: core mechanism, runs and fix verified; 5 factual errors (fixed), 5 overclaims and 4 missing caveats (addressed). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 523 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,163 words
- Registry title
- SortRescorer and Expression#getRescorer size their sort collector by topN instead of by the number of first-pass hits, so a topN far above the hit count (such as Integer.MAX_VALUE for 're-sort them all') throws (OutOfMemoryError on main, IllegalArgumentException in current releases) or allocates memory in proportion to topN, while QueryRescorer and DoubleValuesSourceRescorer return the hits
- Area
- search / rescoring (SortRescorer; expressions ExpressionRescorer inherits rescore())
- Priority
- Low, rank 391: The core SortRescorer and Expression#getRescorer fail loudly on the topN = Integer.MAX_VALUE 're-sort all' idiom and use memory in proportion to topN, but results are always correct when the call succeeds, which is the same core MAX_VALUE pre-size profile as the kNN row LFV-454 with a less common API.
- Impact class
- wrong error
- Impact note
- Applications that call SortRescorer.rescore, or the Rescorer returned by Expression#getRescorer, with a topN far above the first-pass hit count (typically Integer.MAX_VALUE to mean 're-sort all hits') get an OutOfMemoryError 'Requested array size exceeds VM limit' on main, an IllegalArgumentException naming an internal maxSize in 4.8.0 and 7.5.0-10.6.0 (NegativeArraySizeException in 4.9.1-7.4.0), a heap OutOfMemoryError at very large legal topN, and below that a per-call allocation of about 12 bytes per topN slot for a single long sort whatever the hit count (about 120 MB for 4 hits at topN = 10^7); default settings, any index size; the failure is loud and results are correct whenever the call succeeds.
- Summary
- You run a first-pass search that returns 5 hits and re-sort them with new SortRescorer(sort).rescore(searcher, firstPass, Integer.MAX_VALUE), meaning 're-sort all of them'; you expect the 5 hits back in sort order, as topN = 5 or 10 give and as QueryRescorer and DoubleValuesSourceRescorer give for any topN. Instead the call throws OutOfMemoryError 'Requested array size exceeds VM limit' on main (IllegalArgumentException 'maxSize must be >= 0 and < 2147483631' in 10.x and 9.x), because SortRescorer sizes its TopFieldCollector, which pre-allocates its arrays, by topN instead of by the number of hits it was given. Smaller large values succeed but cost memory in proportion to topN (about 120 MB for 4 hits at topN = 10^7), and Expression#getRescorer inherits the same code.
- Introduced
- cbd8cacc50c9 (LUCENE-5545 'add SortRescorer and Expression.getRescorer', migrated as GitHub issue #6608; Michael McCandless; svn r1580490 on trunk, shipped through the branch_4x port 6970ada1746a, r1580491, same day; Subversion-era patch, no PR) [read: git log --follow over all 23 revisions of SortRescorer.java and all 11 of ExpressionRescorer.java; every revision creates the collector from topN; later changes to the line are API migrations only (LUCENE-8059, LUCENE-8405/8411/8412/8430/8431, LUCENE-10002 38ca8d3e42c, #13977 bc18828fccc); exec: 4.7.2 lacks the API, 4.8.0 fails] (2014-03-23)
- First affected version
- 4.8.0 [exec] (the release that introduced the Rescorer API; 4.7.2 does not have it: the portable check does not compile there [exec])
- Affected versions
- every release from 4.8.0 through 10.5.2, 10.6.0 (released 2026-10-29; branch_10_6 head 4ae946e5a9b9) and main a9779ef3c193; executed on 4.8.0, 4.9.1, 4.10.0, 4.10.4, 5.5.5, 6.6.6, 7.4.0, 7.5.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 and main (all fail) [exec], the releases in between by reading (every revision of SortRescorer.java passes topN unchanged) [read]. Only the error at topN = Integer.MAX_VALUE changed over time: IllegalArgumentException 'maxSize must be <= 2147483391' in 4.8.0, NegativeArraySizeException in 4.9.1-7.4.0, IllegalArgumentException 'maxSize must be >= 0 and < 2147483631' in 7.5.0-10.5.2 and 10.6.0 (branch_10_6), OutOfMemoryError 'Requested array size exceeds VM limit' on main only (#14873, unreleased); a heap OutOfMemoryError at MAX_ARRAY_LENGTH - 1 (-Xmx1g) and about 120 MB per call at topN = 10^7 in every executed version [exec]. Not fixed upstream: SortRescorer.java:48-49 unchanged on upstream main (checked 2026-10-29, newest commit on the file e5eb7e763ac, author date 2025-06-30) and on branch_11x, branch_10x and branch_10_6 [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-29, read-only; recheck 2026-10-29): a scripted prior-report search of 59 queries (24 GitHub issue/PR on apache/lucene, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA, 6 web; 145 hits, 0 high) plus retries, 14 manual GitHub searches (SortRescorer, ExpressionRescorer, getRescorer, TopFieldCollectorManager/FieldValueHitQueue with Integer.MAX_VALUE or OutOfMemoryError, recent rescore items, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch), the changed files of 201 open and recently closed apache/lucene PRs (only #16847, long doc ids, edits SortRescorer.java, and keeps topN), JIRA REST and lists.apache.org queries, 7 web searches; the recheck repeated six GitHub searches and scanned the files of all 47 PRs updated since 2026-10-27 (none touches SortRescorer, ExpressionRescorer or Rescorer; #16857 edits TopFieldCollectorManager/FieldValueHitQueue for Sort pruning without a numHits cap), and tracking issue #16937 does not mention rescorers. Related, not the same bug: open #9588 (LUCENE-8542, the same pre-allocation class at IndexSearcher's per-slice collectors); precedents #3195 (LUCENE-2119) and #6002 (LUCENE-4938), where IndexSearcher caps numHits at maxDoc, and SOLR-5661 (PriorityQueue maxSize guard); #9999 (LUCENE-8956, QueryRescorer only); #6608 (LUCENE-5545, origin, never discusses sizing); apache/solr#478 notes that Solr's re-ranking passes topN equal to the hit count, so Solr does not reach this path
- Lucene commit tested
- main
645d4fe14a20(runs of 2026-10-29) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 release jars. Earlier hunt runs: 16 versions from 4.8.0 to main (14 releases,branch_10_64ae946e5a9b9and maina9779ef3c193, where the files involved are identical to645d4fe14a20). The fix was validated in the scratch worktree: the repro, the rescorer suites of core and expressions, theorg.apache.lucene.search.*test package and:lucene:core:check -x test.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/SortRescorer.java:42 (hits = firstPassTopDocs.scoreDocs.clone()), :48-49 (new TopFieldCollectorManager(sort, topN, null, Integer.MAX_VALUE).newCollector()); Rescorer.java:30 (@lucene.experimental), :40 ('@param topN How many re-scored hits to return'); TopFieldCollectorManager.java:44-45 (NOTE: pre-allocate a full array of length numHits); QueryRescorer.java:119-122 and DoubleValuesSourceRescorer.java:79-82 (select min(topN, hits.length)); IndexSearcher.java:721-733 (caps numHits at max(1, maxDoc)); lucene/expressions/.../ExpressionRescorer.java:30-37 ('Functionally this is the same as SortRescorer'), Expression.java:112-114 (getRescorer)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/SortRescorer.java:27, (at 645d4fe14a20) :42-49, :60-86lucene/core/src/java/org/apache/lucene/search/Rescorer.java:30, (at 645d4fe14a20) :40; TopFieldCollectorManager.java:44-45, :62-65, :112-114; FieldValueHitQueue.java:139-153; comparators/LongComparator.java:38; lucene/core/src/java/org/apache/lucene/util/PriorityQueue.java:121-134; IndexSearcher.java:721, :729lucene/expressions/src/java/org/apache/lucene/expressions/ExpressionRescorer.java:30-37; (at 645d4fe14a20) Expression.java:112-114
- Who is affected
lucene/core/src/java/org/apache/lucene/search/package-info.java:371-373; (at 645d4fe14a20) Rescorer.java:30
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/Rescorer.java:40; (at 645d4fe14a20) TopFieldCollectorManager.java:44-45; QueryRescorer.java:120-123; DoubleValuesSourceRescorer.java:79-82; SortRescorer.java:86; IndexSearcher.java:721, :729lucene/core/src/test/org/apache/lucene/search/TestSortRescorer.java:96, (at 645d4fe14a20) :134; TestIndexSearcher.java:78-79; lucene/expressions/src/test/org/apache/lucene/expressions/TestExpressionRescorer.java:106lucene/CHANGES.txt:12467-12469 (at 645d4fe14a20) (LUCENE-5545), :13901-13902 (LUCENE-4938), :18439-18441 (LUCENE-2119)
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/TopFieldCollectorManager.java:62-65; (at 645d4fe14a20) IndexSearcher.java:721
- TestSortRescorerMaxTopN.java (JUnit test):
repro/LFV-997/src/org/apache/lucene/search/TestSortRescorerMaxTopN.java(51 lines)
It is made in parallel with this doc; every on-screen value comes from the code at 645d4fe14a20 or the diagram's executed probe.
assets/LFV-997/bug.png(523 KB)