To make sure every matching context can contribute, NRTSuggester sizes its FST search as num x (number of prefix paths) and lets the collector stop at num. The product is an int: past Integer.MAX_VALUE it wraps, and a negative size means the search does not run at all.
- The document suggester stores a segment's suggestions in an FST.
ContextSuggestFieldwrites the context in front of the suggestion:lucenein contextctx7is stored asctx7, a separator,lucene. - A
ContextQuerythat names no context matches any context: its automaton is "any context, the separator, then the prefix". Intersected with the FST it gives one partial match, a prefix path, per distinct context in the segment: 100,000 contexts, 100,000 prefix paths. - A top-N search over the FST starts from all prefix paths and walks to complete suggestions in score order until it has topN results or runs out; the collector stops it earlier once it has num.
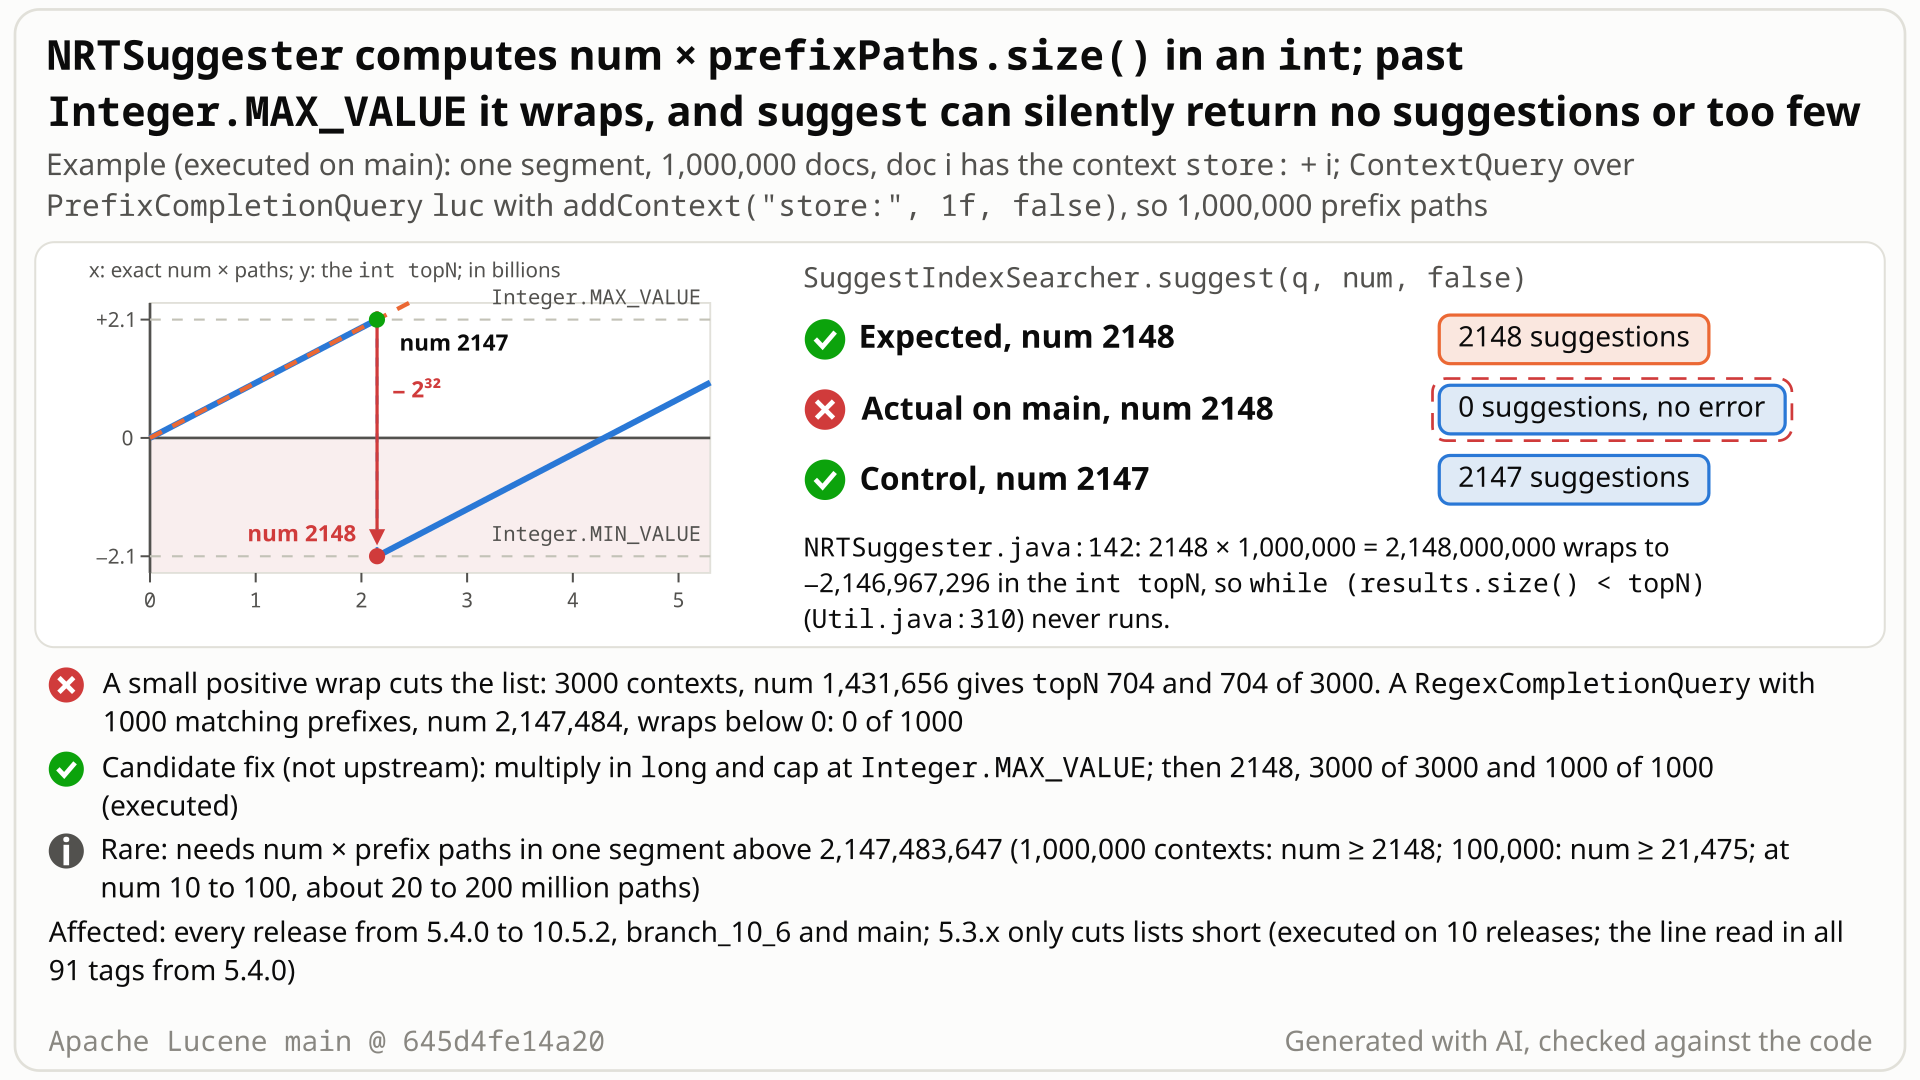
int at num 2147 and wraps at num 2148, where the search returns nothing; then where the wrapped value lands (empty, short or harmless) and the saturating fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index 100,000 documents into one segment, each with the suggestion
lucenein its own context (ctx0toctx99999), throughContextSuggestFieldand the completion postings format. - Query
lucwith aContextQuerythat names no context, which its javadoc defines as "suggest across all contexts".suggest(query, 21474, true)returns the one distinct suggestion,lucene. You expect the same for num = 21475. - Instead num = 21475 returns 0 suggestions and no error. To reach every context,
NRTSuggesterasks its FST search for up to num x (one prefix path per context) results, computed in anint: 21,475 x 100,000 = 2,147,500,000, more thanInteger.MAX_VALUE(2,147,483,647), wraps to -2,147,467,296. - The search loop
while (results.size() < topN)never runs for a negative topN. A small positive wrap truncates instead: 3,000 contexts and num 1,431,656 give 704 of 3,000. With 10^6 contexts the cliff is at num 2148, while num 2147 returns 2147 suggestions.
Applications that use the document suggester (completion postings format) and query across many contexts (the ContextQuery default, addAllContexts() or a shared context prefix), or run regex or fuzzy completion queries matching many prefixes. It needs num x prefix paths in one segment above 2^31: num >= 2148 at 10^6 contexts, >= 21475 at 10^5. Rare at usual num.
Mechanism, terms and numbers879 words
The document (NRT) suggester stores each ContextSuggestField suggestion in the segment's FST behind its context. A ContextQuery that names no context "suggest[s] across all contexts", so its automaton matches one FST prefix, a prefix path, per distinct context. To make sure every path can contribute, NRTSuggester.lookup asks its Util.TopNSearcher for up to num x prefixPaths.size() results, an upper bound by design (the collector stops at num), but computes it in int (NRTSuggester.java:142 on main 645d4fe14a20). With 100,000 contexts in one segment, suggest(query, 21474, true) returns the one distinct suggestion and suggest(query, 21475, true) returns none, with no error: the product wraps to -2,147,467,296 and while (results.size() < topN) (Util.java:310) never runs. With 10^6 contexts num 2147 returns 2147 suggestions and num 2148 none. A small positive wrap truncates instead (3000 contexts, num 1,431,656: 704 of 3000), and regex or fuzzy completion queries with many matching prefixes hit the same line. A negative wrap also removes the search queue's 5000-entry bound. Truncation since 5.3.0 (LUCENE-6459), empty lists since 5.4.0 (LUCENE-6858), through 10.5.2, 10.6.0 and main. Computing the product in long and saturating it at Integer.MAX_VALUE fixes it; the neighbouring queue-size product was already made long by #11923.
- Document (NRT) suggester:
SuggestField/ContextSuggestFieldindexed with a completion postings format, queried with aCompletionQuery(PrefixCompletionQuery,RegexCompletionQuery,FuzzyCompletionQuery,ContextQuery) throughSuggestIndexSearcher.suggest(query, num, skipDuplicates), which "Returns top n completion hits for query" (SuggestIndexSearcher.java:49) and runs one lookup per segment (:64-76). - Contexts:
ContextSuggestFieldprepends each context and the separator'\u001D'to the input (ContextSuggestField.java:49,:79-101). AContextQuerywith no context, oraddAllContexts(), uses "any string, then the separator" (ContextQuery.java:228-233, concatenated with the inner automaton at:197-200); "When no context is added, the default behaviour is to suggest across all contexts" (:62-63).addContext(prefix, boost, false)matches every context with that prefix (:64-66). - Prefix paths:
FSTUtil.intersectPrefixPaths"Enumerates all minimal prefix paths in the automaton that also intersect the FST" (FSTUtil.java:48-52): one per distinct matching context, or one per matching prefix for regex and fuzzy completion queries.
NRTSuggester.lookupcomputesprefixPaths(NRTSuggester.java:131-132) and thenfinal int topN = collector.getCountToCollect() * prefixPaths.size();(:142). The comment above (:133-141, from LUCENE-6858) says the factor is there "to ensure search admissibility", that collectors "will early terminate as soon as enough suggestions have been collected", and that "This value is the maximum number of suggestions that can be collected".topNgoes straight intonew Util.TopNSearcher<>(fst, topN, queueSize, ...)(:148-154), whose constructor does not check it (Util.java:193-206).search()loopswhile (results.size() < topN)(Util.java:310): fortopN <= 0it never runs, so the segment contributes nothing; a small positive wrap stops it after that many results. The lookup ignores the outcome ("search admissibility is not guaranteed",NRTSuggester.java:256-259).- The same wrapped value sizes the queue:
getMaxTopNSearcherQueueSize(topN, ...)(:143-144) multiplies inlongbut from the wrapped int and returnsmin(5000, ...)(:292-301), here negative. The queue is pruned only when its size equals the depth (Util.java:215,:248-249), which never happens for a negative depth, so, by code reading, every prefix path stays queued instead of at most 5000.
- 100,000 contexts,
skipDuplicates=true, one surface form: num 21474 -> 1 hit, num 21475 -> 0 (21,475 x 100,000 = 2,147,500,000, as an int -2,147,467,296). Without dedup: 5000 (the private queue cap) -> 0. - 10^6 contexts, no dedup, match-all (this doc's probe on
645d4fe14a20) oraddContext("store:", 1f, false)(the devil's advocate's run): num 2147 -> 2147, num 2148 -> 0. Each lookup takes about 2.4 s. - 3000 contexts: num 715827 -> 3000, num 715828 -> 0, num 1,431,656 (wraps to 704) -> 704 of 3000. 1000 regex prefixes: num 2,147,484 -> 0 of 1000.
- First failing num for P paths:
floor(Integer.MAX_VALUE / P) + 1(2148 for 10^6, 21475 for 10^5, 214749 for 10^4). The int wraps modulo 2^32, so a large positive wrap is harmless: num 2,000,000 with 2500 paths returns all 2500.
- Per segment: the count is each segment's own. Two segments of 50,000 contexts: num 42949 -> 10000 hits, num 42950 -> 0. Segments whose own product does not wrap still contribute (one lookup per leaf into one shared collector,
SuggestIndexSearcher.java:69-85), so a multi-segment index returns an empty list only when every segment with matches wraps to 0 or below; otherwise it silently lacks the wrapped segments' suggestions. skipDuplicatesdoes not help; no deletions or filter are needed.- Only results are dropped: the contexts, the filter and the live docs are applied as before, so nothing they exclude is returned.
- Side effect of a negative wrap: by code reading, every prefix path stays queued. At 10^6 contexts and a 512 MB heap, the num 2148 lookup ran out of memory (
OutOfMemoryError) where num 2147 completed in 2.6 s, and with the saturating fix both lookups completed (one run each). With 3 GB, the wholesuggest()call allocated about 2.1 GB at num 2148 against 1.85 GB at num 2147 (cumulative allocation; no per-phase breakdown was collected).
Exposure and likelihood204 words
- Who is hit. Users of
SuggestIndexSearcher.suggestwith aContextQueryacross all contexts (no context,addAllContexts()) or across a shared non-exact context prefix, over many distinct contexts per segment; or with regex or fuzzy completion queries that match very many prefixes. - Default or opt-in. The document suggester and its completion postings format are opt-in; within it, the trigger is
ContextQuery's documented default. - Effect. An empty or truncated suggestion list with no error. By code reading, a negative wrap also leaves the search queue unbounded; at 10^6 contexts and a 512 MB heap the wrapping lookup ran out of memory and the fixed one did not. Nothing the query, contexts, filter or live docs exclude is returned.
- Scale. num x (prefix paths in one segment) > 2^31. At the usual autocomplete num of 10 to 100 that is about 2 x 10^7 to 2 x 10^8 prefix paths in one segment, and a 10^6-path lookup already takes about 2.4 s. Queries over about 900 contexts are reported in practice (elasticsearch#119966, d2a-raudenaerde; its performance was fixed by Mayya Sharipova in #14169).
- Releases. Truncation from 5.3.0, empty lists from 5.4.0, through 10.5.2, 10.6.0 (released 2026-10-29; branch_10_6) and main.
- How likely: rare (registry likelihood rare, priority low).
The test shows that a ContextQuery over all contexts on one segment with 10^6 distinct contexts returns nothing for num 2148, because NRTSuggester.lookup's int topN = 2148 x 10^6 wraps negative (TestContextQueryManyContextsTopN#testAllContextsQueryOnOneMillionContexts, about 15-18 s).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestContextQueryManyContextsTopN extends LuceneTestCase {

  public void testAllContextsQueryOnOneMillionContexts() throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    IndexWriterConfig iwc = new IndexWriterConfig(analyzer).setRAMBufferSizeMB(256);
    iwc.setCodec(TestUtil.alwaysPostingsFormat(new Completion104PostingsFormat()));
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      for (int i = 0; i < 1_000_000; i++) {
        Document doc = new Document();
        doc.add(new ContextSuggestField("suggest", "lucene", 1, "ctx" + i));
        w.addDocument(doc);
      }
      w.forceMerge(1);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        SuggestIndexSearcher searcher = new SuggestIndexSearcher(reader);
        ContextQuery query =
            new ContextQuery(new PrefixCompletionQuery(analyzer, new Term("suggest", "luc")));
        // expected 2148 hits, actual 0: topN = 2148 * 10^6 prefix paths wraps negative in int
        assertEquals(2148, searcher.suggest(query, 2148, false).scoreLookupDocs().length);
      }
    }
    analyzer.close();
  }
}
# in a copy of this finding's repro folder (repro/LFV-999/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed 5EED0999
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=5EED0999 \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.document.TestContextQueryManyContextsTopN
- Expected vs actual
- Expected 2148 suggestions (num is below maxDoc and below the 5000 queue cap); actual 0, with -ea and -da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed 5EED0999: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<2148> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.search.suggest.document.TestContextQueryManyContextsTopN.testAllContextsQueryOnOneMillionContexts(TestContextQueryManyContextsTopN.java:50)suggest"Returns top n completion hits"; aContextQuerywith no context is documented to "suggest across all contexts"; num has no upper limit.- The code calls the product "the maximum number of suggestions that can be collected": an upper bound (Areek Zillur's design).
- One more requested suggestion turns 1 (or 2147) hits into 0, without deletions or a filter.
The full argument184 words
- Contract.
SuggestIndexSearcher.java:49: "Returns top n completion hits for query".ContextQuery.java:62-63: "When no context is added, the default behaviour is to suggest across all contexts".TopSuggestDocsCollectorrejects onlynum <= 0(TopSuggestDocsCollector.java:77-78); no javadoc, CHANGES or MIGRATE entry gives an upper limit. - Design intent. The comment at
NRTSuggester.java:133-141(LUCENE-6858) calls the product the maximum number of suggestions that can be collected. Areek Zillur explained on LUCENE-6459 (#7518, 2015-05-26) that each prefix path gets n expansions and that the search "will early terminate", and on LUCENE-6858 (#7916) that the bigger topN is there "to ensure search admissibility in case of suggestions with multiple contexts". A negative bound that switches the search off contradicts their design. - Overflow-safety was asked for here. Reviewing LUCENE-6339 (#7400, 2015-03-26), Michael McCandless asked whether the queue-size computation from the same num "could possibly overflow int? Maybe use long". Robert Muir's #11923 (2022, after Kevin Risden's error-prone run #11921) made that product
long(NRTSuggester.java:294) and left:142as it was. - Tests. No upstream document-suggester test asserts large-num or overflow behaviour (the devil's advocate's grep of
lucene/suggest/src/test).
The devil's-advocate check239 words
The intended-behaviour checker built the strongest case (first raised by the finder's reviewer from another model family, OpenAI GPT-5.6, which itself rated it weak): the document suggester is @lucene.experimental; the class NOTE says the search can be "inadmissible due to over-pruning" (NRTSuggester.java:55-65); the queue is capped at MAX_TOP_N_QUEUE_SIZE = 5000 (:92), so a huge num is already approximate; the collector "Collects at most num completions" (TopSuggestDocsCollector.java:74); and a huge num is the application's business (SECURITY.md:38 leaves limits on "unbounded, unfiltered input" to the application; Michael McCandless called Integer.MAX_VALUE for search(Query, n) "a nonsense value" on LUCENE-2119, #3195).
Why it fails: the NOTE covers "too many deletions or using a very restrictive filter", and the repro has neither. The 5000 cap is private, and without deletions or a restrictive filter (the NOTE's conditions for over-pruning) it gives min(5000, available), never 0: with 10^6 contexts num 2147 returns exactly 2147 and num 2148 returns 0, both below the cap and below maxDoc. "At most num" does not license 0 when one fewer returns the full list. The threshold depends on a per-segment, data-dependent path count the caller cannot see. In the same LUCENE-2119 thread Michael McCandless also wrote "We should bounds check it", and IndexSearcher.searchAfter caps numHits at maxDoc (IndexSearcher.java:588, :597) instead of failing. Experimental allows API changes, not silent wrong results. Verdict: not intended (adjudication: confirmed, high confidence).
Recommended Compute num x prefix paths in long and saturate at Integer.MAX_VALUE
Compute the product in long and saturate it at Integer.MAX_VALUE (one file, +3/-1, in NRTSuggester.lookup), as #11923 did for the queue-size product next to it. Validated: the repro passes, and the whole suggest module (237 tests) and check pass, with assertions on and off.
// The product can exceed Integer.MAX_VALUE, so compute it in long and saturate.
final long maxTopN = (long) collector.getCountToCollect() * prefixPaths.size();
final int topN = (int) Math.min(maxTopN, Integer.MAX_VALUE);
All options and trade-offs3 options · 445 words
One fix was built and validated; two alternatives were considered and not built.
Compute num x prefix paths in long and saturate at Integer.MAX_VALUE (validated by the checks) (recommended)
A change in NRTSuggester.lookup (1 file, +3/-1), the same as the finder's fix sketch and the independent reproducer's patch, split over two lines to stay within 100 columns. The product is meant as an upper bound that the collector undercuts anyway; the search can never return more than Integer.MAX_VALUE results, so saturating keeps that meaning exactly. The queue size then comes back to min(5000, ...), which also restores the queue bound.
// The product can exceed Integer.MAX_VALUE, so compute it in long and saturate.
final long maxTopN = (long) collector.getCountToCollect() * prefixPaths.size();
final int topN = (int) Math.min(maxTopN, Integer.MAX_VALUE);
Trade-offs
- Scope: saturation removes this overflow and restores the queue cap. It does not make the document suggester exhaustive in general: the over-pruning the class NOTE allows with deletions or a restrictive filter (
NRTSuggester.java:55-65) and the private 5000-entry queue cap stay as they are. - No change below the threshold: the value is identical there.
- With
topN = Integer.MAX_VALUE,TopNSearcher'srejectCount + topN <= maxQueueDepth(Util.java:409) can itself overflow, but it only setsTopResults.isComplete, whichNRTSuggesterignores (NRTSuggester.java:256-259); noted by the devil's advocate, not a blocker. - Open PR #16847 edits the next statement, so the fix may need a trivial rebase.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle, OpenJDK 25: the repro fails on the stock tree and passes with the fix, with assertions on and off. - With the fix and the repro test, the whole
lucene/suggestmodule passes with assertions on and off: 32 suites (31 upstream + the test), 237 tests, 7 skipped, 0 failures; the 6 upstreamsuggest.documentsuites (58 tests) among them. :lucene:suggest:check -x test(checkGoogleJavaFormat, ecjLint, forbiddenApis) passes.- Earlier, by the hunt: the finder's 4 tests and the independent reproducer's 8 pass with the same saturation; the 12 upstream suggest test classes (144 tests) pass with all of the hunt unit's fix sketches.
- Not run: nightly tests, a benchmark (one multiply per segment lookup).
Throw ArithmeticException instead of returning nothing.
Trade-offs
Honest, but it turns a legitimate request (the javadoc's default across all contexts) into an exception, where the saturating fix answers it correctly.
Cap or reject large num in TopSuggestDocsCollector or SuggestIndexSearcher, as IndexSearcher caps numHits at maxDoc.
Trade-offs
Does not fix it on its own: the overflow depends on the per-segment prefix-path count, and with 10^6 contexts num 2148 is far below maxDoc.
Code reading of every int product of a suggest num found the line. A 32-bit SMT bit-vector model and an exhaustive enumeration gave the first failing num for each prefix-path count (2148 for 10^6, 21475 for 10^5), and each point was then executed on the stock jars.
The method in full103 words
Method: non-formal first signal, then a small formal model (the hunt's hunt unit for suggester num sizes, 2026-10-28, main a9779ef3c193).
- Lead. A sweep over every
intproduct of a suggestnumfoundNRTSuggester.java:142. - Model. A Z3 32-bit bit-vector model and an exhaustive enumeration over every int num gave the tight wrap-free bound per prefix-path count: 2148 for 10^6, 21475 for 10^5, 214749 for 10^4, 715828 for 3000, 2147484 for 1000.
- Execution. Each operating point was run on the stock main jars (3000 contexts, 1000 regex prefixes, 100,000 contexts), then reduced to a JUnit; this doc reduced it again to one method.
No prior report found (2026-10-29): 239 queries over GitHub, commits, downstream trackers, the mailing lists, the JIRA archive and the web, plus the changed files of all 414 open Lucene PRs. Closest: a 2015 review question about overflow in the neighbouring queue-size product (LUCENE-6339), later made long in #11923.
Searches6 searches
Related, not reports of this bug: LUCENE-6339 (#7400), Michael McCandless's review question about int overflow in the queue-size product, written before this product existed; #11923 (Robert Muir, after Kevin Risden's error-prone run #11921), which made that product long and left :142; LUCENE-6459 (#7518) and LUCENE-6858 (#7916), the introducing issues, with no overflow discussion; LUCENE-10607 (#11643, fixed in 9.3), an index-time int overflow elsewhere in the module; LUCENE-8995 (#10038) and Elasticsearch reports (#23012, #47269 and others), fewer suggestions than asked at small sizes from other causes; #14169 / elasticsearch#119966, a ContextQuery with about 900 contexts (performance only). Open PR #16847 keeps :142 unchanged. Tracking issue #16937 does not mention this bug; no maintainer has commented on it. Gaps: GitHub search returns at most 100 items per query; inline PR review comments are not searchable.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and downstream trackers (Elasticsearch, OpenSearch, Solr, Lucene.NET) | 2026-10-29 | three scripted prior-report search variants (153 queries) and 38 manual GitHub searches over six repositories | no report; only the related items below |
| Open and recent PRs | 2026-10-29 | the changed files of all 414 open apache/lucene PRs, the 46 closed PRs updated since 2026-10-15 and the 93 issues and PRs updated since 2026-10-26 with their comments | only #16847, which keeps the line unchanged |
| JIRA archive | 2026-10-29 | 20 JQL queries and issue reads | no report |
| Mailing lists | 2026-10-29 | 13 searches over dev@, java-user@ and issues@ | no report |
| Web | 2026-10-29 | 7 web searches | no report |
| GitHub (re-checks) | 2026-10-29 and at the audit | issues and PRs updated since 2026-10-28, the newest commits on NRTSuggester.java and Util.java, the line on upstream main | nothing new; the line is unchanged on main 645d4fe14a20 |
Introduced in 5.3.0 by LUCENE-6459 (be4d58c7740, 2015), where the product only sized the queue (truncated lists); LUCENE-6858 (4e2d9deff4a, 5.4.0) made it the search's topN (empty lists). Executed on ten releases from 5.3.0 to 10.5.2, branch_10_6 at the revision released as 10.6.0 and main; unchanged on main.
Versions tested6 rows
Stage 1: be4d58c7740 (trunk) / 380bb29f395 (branch_5x), LUCENE-6459 "add common suggest API for document based NRT suggester" (#7518; Areek Zillur's patch, committed by Michael McCandless, 2015-05-28), added ContextQuery, RegexCompletionQuery and FuzzyCompletionQuery (the queries that can yield many prefix paths) and the int product getCountToCollect() * prefixPaths.size(), which it passed only to the queue-size computation (prefix paths themselves are older: 5.1.0 and 5.2.1 already intersect into prefixPaths with topN = num, from LUCENE-6339, b7adb6ac770): in 5.3.x a small positive wrap truncates (704 of 3000), a negative one is harmless.
Stage 2: 4e2d9deff4a (trunk) / 714017f5743 (branch_5x), LUCENE-6858 (#7916, Areek Zillur, 2015-10-28), made the same product the TopNSearcher topN "to ensure search admissibility in case of suggestions with multiple contexts", which adds the empty-result leg (5.4.0). The line is in all 91 release tags from 5.4.0 to 10.5.2; the newest commit on the file, fe86094f2f4 (#14364, 2025-03-19), does not touch it.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 and a9779ef3c193 | affected | this doc's repro fails (gradle, assertions on and off); the finder's, the reproducer's and the audit's tests fail |
branch_10_6 4ae946e5a9b9 (10.6.0, released 2026-10-29), 10.5.2, 9.12.3 | affected | empty and truncated lists; this doc's repro fails on 10.5.2 |
| 5.4.0, 6.4.2, 6.5.0, 6.6.6, 7.7.3, 8.11.4 | affected | both legs: 0 and 704 of 3000, 0 of 1000 regex prefixes |
| 5.3.0, 5.3.2 | truncation only | 704 of 3000; a negative wrap is harmless |
| 5.2.1 | API absent | no ContextQuery, regex or fuzzy completion query and no num x prefix-paths product (prefix paths with topN = num) |
| main + fix | not affected | the repro passes; the suggest module (32 suites, 237 tests) passes, assertions on and off |
An independent reproducer, a devil's advocate, reading-only reviews by another model family (OpenAI GPT-5.6), an adjudication and a credibility audit agree on the root cause; the adjudication confirmed it with high confidence. This doc re-ran a one-method repro on 645d4fe14a20 and validated the fix with gradle.
Checks and verdicts368 words
The cross-model reviews were reading-only: they could not run Java. The refute-lens review returned a procedural "not real, low" while agreeing on the mechanism; a separate re-run failed 3 of 4.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit 3 of 4 fail on main (-ea, -da), 10.5.2, 9.12.3 and branch_10_6 (the 10.6.0 release revision); the control passes; model thresholds; 10^5-context probe (21474 -> 7, 21475 -> 0). |
| cross-model review, refute lens | not real, low (procedural) | OpenAI GPT-5.6, reading-only; agreed on the mechanism and rated the intended argument weak. A separate re-run failed 3 of 4. |
| Independent reproducer | real | Own JUnit fails 5 of 8 on main, 10.5.2 and 9.12.3; scale test at 10^5 and 10^6 contexts; modulo-wrap correction; own saturating patch passes 8 of 8. |
| Cross-model review, intended lens | real, medium | OpenAI GPT-5.6, reading-only; intended argument weak. The step re-ran the repro (3 of 4 fail), the 10^5 probe and the fix check (4 of 4 pass). |
| Intended-behaviour devil's advocate | real (Low) | Six intended or misuse arguments rejected; repro on main and 10.5.2; the context-prefix probe at 10^5 and 10^6 contexts. |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit with a new seed (-ea, -da): 5 of 8 fail, the controls pass. |
| Registration check and credibility audit | keep | The finder's JUnit re-run with three seeds (-ea, -da); own probe incl. the two-segment threshold. |
| brief re-runs | reproduced on 645d4fe14a20 | The one-method repro through gradle (-ea, -da) and on 10.5.2; the fix with the suggest module and check; the queue side-effect probe. |
| fact check of this doc | bug real; wording errors fixed | Separate AI tool: re-ran the repro on 645d4fe14a20 (gradle, three seeds, -ea, -da) and the 10.5.2 jars, the fix with the suggest module and check, and a rebuilt 10^6-context draft at 512 MB (stock: out of memory in the num 2148 lookup; fixed: 2147 and 2148 hits). Five wording errors, fixed. |
| cross-model fact check | bug real; wording fixes | OpenAI GPT-5.6, reading-only: the core report is sound; wording errors, overclaims and missing caveats, fixed or answered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 444 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,506 words
- Registry title
- Document suggester: NRTSuggester computes topN = num * prefixPaths.size() in int, so when the product passes Integer.MAX_VALUE it wraps and SuggestIndexSearcher.suggest can silently return no suggestions or a truncated list (10^6 contexts in a segment: num 2147 returns 2147 suggestions, num 2148 returns none)
- Area
- suggest / document (NRT) suggester: NRTSuggester.lookup topN = num x prefix paths (SuggestIndexSearcher.suggest with ContextQuery, RegexCompletionQuery or FuzzyCompletionQuery; Util.TopNSearcher)
- Priority
- Low, rank 452: The document suggester silently returns an empty or short list since 5.3, but only when num times the prefix paths in one segment passes 2^31, the same int-product suggest-budget overflow as its DirectSpellChecker sibling LFV-986.
- Impact class
- silent wrong results
- Impact note
- Applications that use the document suggester (SuggestField or ContextSuggestField with a completion postings format) on any release from 5.3.0 through 10.5.2, 10.6.0 (released 2026-10-29) or main get an empty or truncated suggestion list, with no error, when num times the number of prefix paths the query matches in one segment exceeds Integer.MAX_VALUE: for a ContextQuery with no contexts (documented as 'suggest across all contexts'), addAllContexts() or a context prefix, that is the number of distinct matching contexts (num >= 2148 with 10^6 contexts, num >= 21475 with 10^5), for regex and fuzzy completion queries the number of matching prefixes; the usual num of 10 to 100 would need about 2 x 10^7 to 2 x 10^8 prefix paths in one segment, and 5.3.x has only the truncation leg.
- Summary
- You index suggestions with ContextSuggestField, one context each, so that one segment holds 10^6 distinct contexts, and call SuggestIndexSearcher.suggest(query, num, false) with a ContextQuery over a PrefixCompletionQuery that matches every context (no contexts added, which ContextQuery documents as 'suggest across all contexts', or a shared context prefix via addContext(prefix, boost, false)); you expect the top num completions, and num = 2147 does return 2147. With num = 2148 you get no suggestions and no error: NRTSuggester.lookup computes topN = num * prefixPaths.size() in int (NRTSuggester.java:142), 2148 x 10^6 wraps to -2146967296, and Util.TopNSearcher's loop 'while (results.size() < topN)' never runs. When the product wraps to a small positive value the list is silently cut to that many (3000 contexts and num = 1431656 return 704 of 3000), and a RegexCompletionQuery or FuzzyCompletionQuery with many matching prefixes behaves the same (1000 regex prefixes and num = 2147484 return none).
- Introduced
- Two stages, both by Areek Zillur [read: git log -S'prefixPaths.size()' and git blame in the full-history clone; exec: release runs below]. Stage 1: be4d58c7740bea4e797eb1acff6355eb260e7c93 (trunk, svn r1682158) and 380bb29f39595de1c3947075296d1d0a36f02fd8 (branch_5x, r1682170), LUCENE-6459 'add common suggest API for document based NRT suggester' (#7518; Areek Zillur's patch, committed by Michael McCandless; Subversion era, no pull request) added ContextQuery, RegexCompletionQuery, FuzzyCompletionQuery and prefix paths, and passed the int product getCountToCollect() * prefixPaths.size() to getMaxTopNSearcherQueueSize only, so a small positive wrap bounds the queue and truncates the list (5.3.0). Stage 2: 4e2d9deff4a0251ea5f30d4f380f6f98d7411f2f (trunk, r1711158) and 714017f57430ede8820edb59ca7794a2583bf831 (branch_5x, r1711159), LUCENE-6858 (#7916, author and committer Areek Zillur) made the same int product the TopNSearcher topN ('final int topN = ...', blame on main NRTSuggester.java:133-142), which adds the empty-result leg (5.4.0) (2015-05-28 (stage 1, LUCENE-6459); 2015-10-28 (stage 2, LUCENE-6858))
- First affected version
- 5.3.0 [exec] for the truncation leg (704 of 3000; the product fed only the queue size); 5.4.0 [exec] for the empty-result leg; 5.2.1 has no ContextQuery, RegexCompletionQuery or prefix paths, so the repro does not compile [exec]
- Affected versions
- 5.3.0-5.3.2: truncation leg only [exec on 5.3.0 and 5.3.2: 704 of 3000, while the negative wraps return the full list]; every release from 5.4.0 to 10.5.2: both legs [exec with the follow-up's portable public-API driver on 5.4.0 (-ea and -da), 6.4.2, 6.5.0, 6.6.6, 7.7.3, 8.11.4, 9.12.3 and 10.5.2; the finder's JUnit fails on 9.12.3, 10.5.2, the RC and main, the independent reproduction's on 9.12.3, 10.5.2 and main, the intended-behaviour check's run on 10.5.2]; the int product is the TopNSearcher topN in all 91 local release tags from 5.4.0 to 10.5.2 [read]; 10.6.0 (released 2026-10-29; branch_10_6 4ae946e5a9b9) [exec]; main a9779ef3c193 [exec, -ea and -da]. A saturating shadow patch restores every count on 5.3.2 (on the queue-size argument) and 5.4.0 (on topN) [exec]. Not fixed: upstream main 645d4fe14a20 (2026-10-28) still has 'final int topN = collector.getCountToCollect() * prefixPaths.size();' at line 142, and the newest commit on NRTSuggester.java is fe86094f2f4 on main and 9ca6ca0dba6 on branch_10x and branch_10_6 (#14364, author date 2025-03-19), which does not touch it [read, recheck 2026-10-29]. Caveat: all runs used JDK 25.0.3 on Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (follow-up search 2026-10-29, files written, plus the finder's searches of 2026-10-28 and the independent reproduction's, the intended-behaviour check's and the adjudication's, all read-only; the prior-report record, verdict new): 239 queries, namely three fresh scripted prior-report search variants (153 queries over GitHub issues and PRs, commits, Elasticsearch, OpenSearch and Solr, the mailing lists and the JIRA archive), 38 manual GitHub searches over apache/lucene, apache/lucene-solr, apache/lucenenet, apache/solr, Elasticsearch and OpenSearch, 20 JIRA queries and issue reads, 13 mailing-list searches and 7 web searches, plus scans of the changed files of all 414 open apache/lucene PRs, the 46 closed PRs updated since 2026-10-15 and the 93 issues and PRs updated since 2026-10-26 with their 224 comments; recheck 2026-10-29 (the 36 issues and PRs updated since 2026-10-28 with their PR file lists, the newest commits on NRTSuggester.java and Util.java per branch, line 142 on upstream main 645d4fe14a20, 4 searches): nothing new. Related, not this bug: LUCENE-6339 (#7400), where Michael McCandless asked in review whether the queue-size computation 'could possibly overflow int? Maybe use long' (a different product, num x maxAnalyzedPathsPerOutput, written before this one existed); #11923 (Robert Muir, after Kevin Risden's error-prone run #11921), which made that queue-size product long and left line 142 unchanged; LUCENE-10607 (#11643, fixed in 9.3 by #970), an index-time int overflow in NRTSuggesterBuilder; LUCENE-8995 (#10038), fewer completions than requested from a different cause at small num; Elasticsearch reports of fewer suggestions than size (#23012, #47269 and others), all at small sizes with other causes. Open PR #16847 (long global doc ids) keeps line 142 as an unchanged context line. Gaps: GitHub search returns at most 100 items per query, and inline PR review comments are not searchable.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; runs of 2026-10-29) through gradle in a scratch worktree, with assertions on and off, and the 10.5.2 release jars through a standalone runner; the recommended fix was validated there (the repro, the wholelucene/suggestmodule with assertions on and off,:lucene:suggest:check -x test). The hunt's earlier runs used maina9779ef3c193(the suggest module andUtil.javaare identical),branch_10_64ae946e5a9b9and the releases 10.5.2, 9.12.3, 8.11.4, 7.7.3, 6.6.6, 6.5.0, 6.4.2, 5.4.0, 5.3.2, 5.3.0 and 5.2.1.
- Finding record
a Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:55-67 (class NOTE: over-pruning with many deletions or a very restrictive filter; @lucene.experimental), :92 (MAX_TOP_N_QUEUE_SIZE = 5000), :131-132 (prefixPaths = FSTUtil.intersectPrefixPaths), :133-141 (comment: 'to ensure search admissibility', 'the maximum number of suggestions that can be collected'), :142 ('final int topN = collector.getCountToCollect() * prefixPaths.size();'), :143-144 (queue size from topN), :148-154 (Util.TopNSearcher with topN), :292-302 (getMaxTopNSearcherQueueSize: long product, capped at 5000); identical in Lucene main ea57360912eda Lucene main checkout lucene/core/src/java/org/apache/lucene/util/fst/Util.java:310 ('while (results.size() < topN)'), :409 (isComplete = rejectCount + topN <= maxQueueDepth); lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:49 ('Returns top n completion hits for query'); ContextQuery.java:62-63 ('When no context is added, the default behaviour is to suggest across all contexts'), :64-66 (context prefix with exact=false); TopSuggestDocsCollector.java:77-78 (only 'num' must be > 0)GitHub apache/lucene #7518 (LUCENE-6459, Areek Zillur's comment of 2015-05-26 on the n * num_prefix_paths sizing), #7916 (LUCENE-6858), #7400 (LUCENE-6339 review by Michael McCandless, 2015-03-26), #11923 and #11921, #3195 (LUCENE-2119, Michael McCandless: 'a nonsense value ... We should bounds check it'), #14169 and elastic/elasticsearch#119966 (a ContextQuery with about 900 contexts), #16847 (open, line 142 unchanged), #16937 (the tracking issue, 0 comments), as cited in the follow-up and the verdicts
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:55-67, (at 645d4fe14a20) :92, :111-122, :131-154, :230-259, :281-303lucene/core/src/java/org/apache/lucene/util/fst/Util.java:193-206, (at 645d4fe14a20) :209-251, :310, :409lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:37, (at 645d4fe14a20) :49-55, :64-85; ContextQuery.java:57-71, :197-200, :228-233; ContextSuggestField.java:49, :79-101; TopSuggestDocsCollector.java:71-79, :97-99; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FSTUtil.java:48-52
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:37, (at 645d4fe14a20) :49; ContextQuery.java:62-63, :71; TopSuggestDocsCollector.java:49, :74, :77-78; NRTSuggester.java:55-67, :92, :133-142, :294lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:588, (at 645d4fe14a20) :597Lucene main 645d4fe14a20 SECURITY.md:38
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/fst/Util.java:409; (at 645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:256-259, :292-301; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:588, :597
- TestContextQueryManyContextsTopN.java (JUnit test):
repro/LFV-999/src/org/apache/lucene/search/suggest/document/TestContextQueryManyContextsTopN.java(55 lines)
Its values come from the code at 645d4fe14a20 and a probe executed on that commit.
assets/LFV-999/bug.png(444 KB)