Since 10.6.0 development, the codec's bulk range check for numeric doc values compares the stored form v - min against shifted query bounds instead of decoding each value. That breaks when the stored form has wrapped to a negative long, which happens when a segment's values span more than Long.MAX_VALUE (with more than 256 distinct values and no block encoding).
- Doc values keep one number per document, column-wise. The default codec stores each value as
v - min(divided by a common divisor, the gcd, when there is one) with just enough bits per value; reading a value addsminback. - Doubles are indexed as sortable longs (
NumericUtils.doubleToSortableLong): positive doubles become large positive longs and negative doubles large negative longs. A segment with values of -2 or less and +2 or more spans more thanLong.MAX_VALUE; so do random 64-bit hashes. - With the opt-in skip index (
indexedField), a doc-values range query first checks each block's min and max: blocks fully inside the range match, blocks outside are skipped, and the rest are checked document by document with the codec's bulkrangeIntoBitSet.
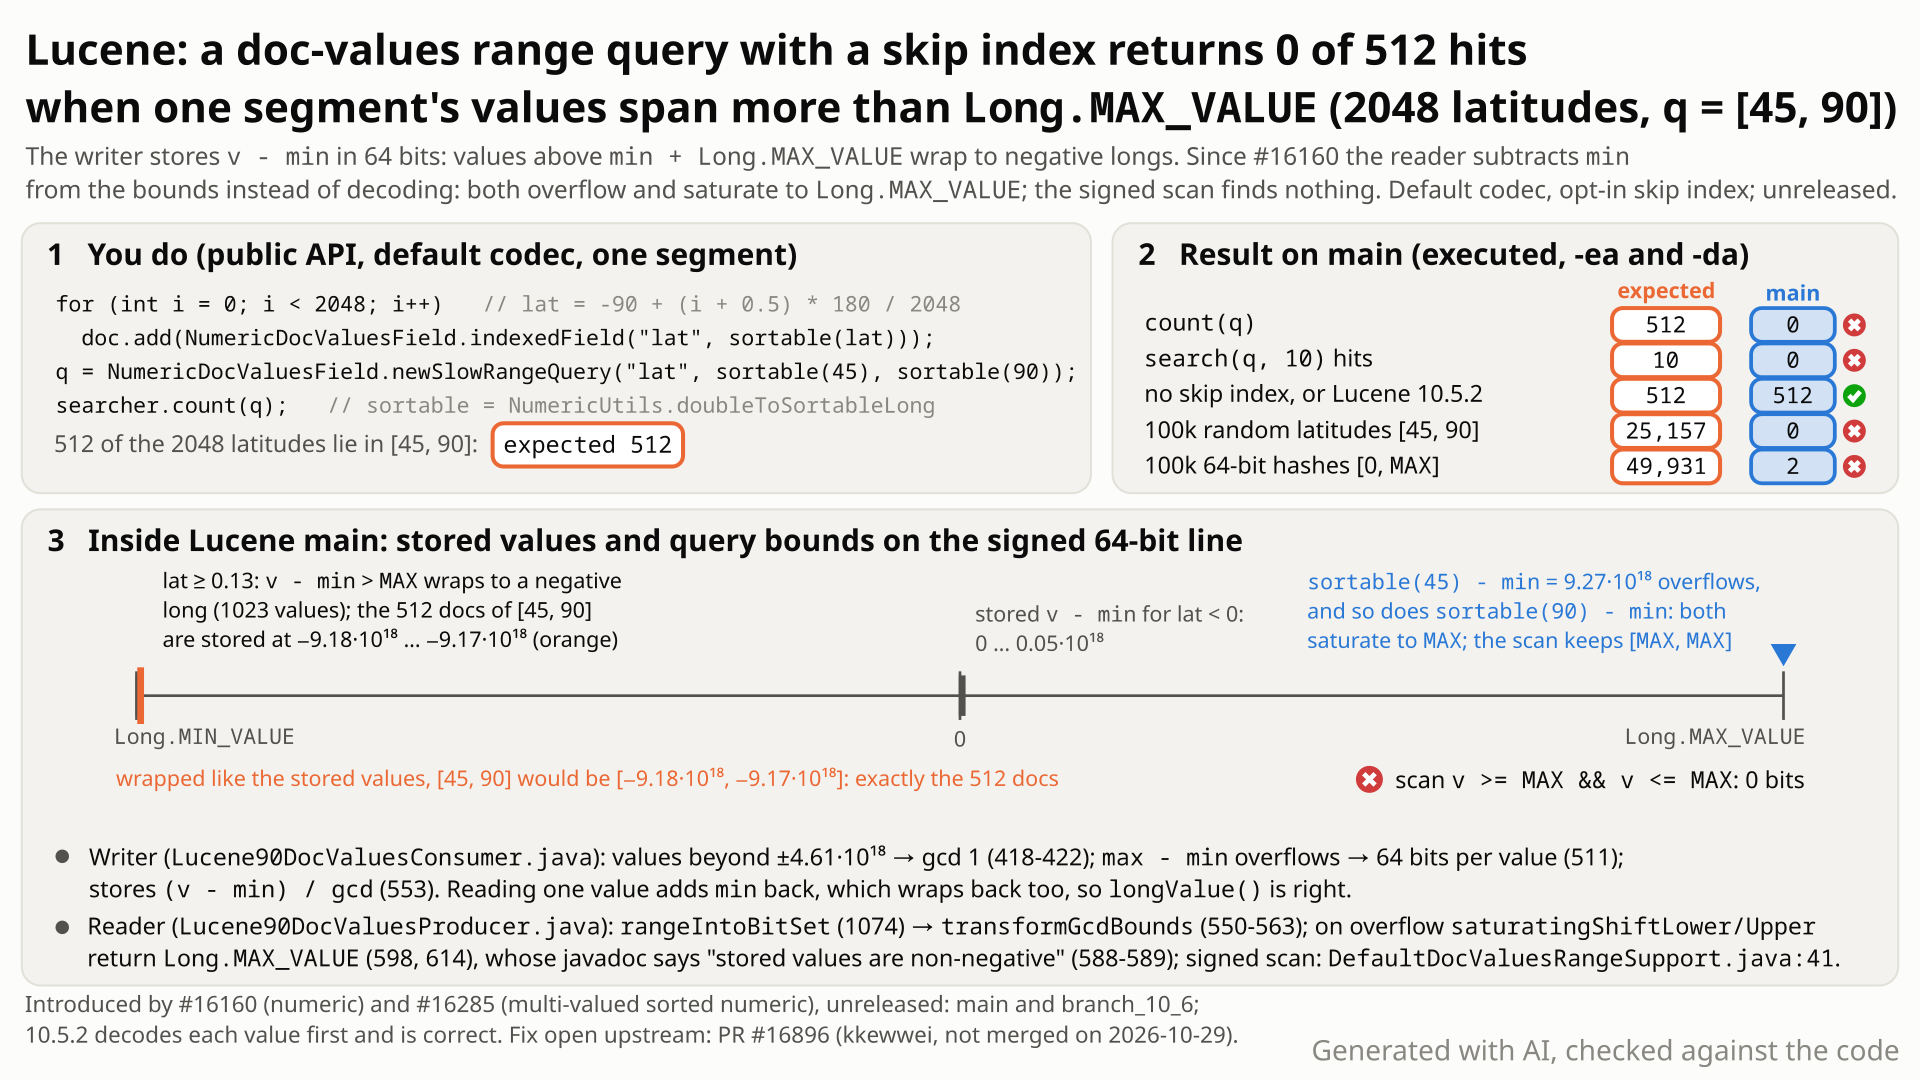
- Index 2,048 latitudes evenly spaced from -89.96 to +89.96 as
NumericDocValuesField.indexedField("lat", NumericUtils.doubleToSortableLong(lat)), the field type with a doc-values skip index; default codec, one segment. 512 of them lie in [45, 90]. - Run
NumericDocValuesField.newSlowRangeQuery("lat", sortable(45), sortable(90)). You expectcount= 512 and 10 hits fromsearch(q, 10): 10.5.2 gives that, and so does the same field without a skip index. - Instead
count= 0 andsearch(q, 10)returns 0 hits, with no error. On 100,000 random latitudes [45, 90] gives 0 of 25,157; on 64-bit hashes [0,Long.MAX_VALUE] gives 2 of 49,931. - Why: the codec stores each value as
v - min. Here the values span about 9.27e18, more thanLong.MAX_VALUE(9.22e18), so the stored value of every latitude above about +0.05 degrees wraps to a negative long (1,023 of 2,048). Reading one value addsminback and is right. - Since #16160 the bulk range check behind skip-indexed queries compares stored values directly:
sortable(45) - minoverflows, both bounds saturate toLong.MAX_VALUE, and the range [Long.MAX_VALUE,Long.MAX_VALUE] matches nothing. 10.5.2 decoded each value first.
Users of the opt-in doc-values skip index (indexedField or DocValuesSkipIndexType.RANGE) whose range-queried numeric field has a segment with more than 256 distinct values spanning more than Long.MAX_VALUE: signed doubles past +/-2 (latitudes, longitudes, signed scores) or full-range 64-bit hashes and ids. Non-negative longs and epoch timestamps of realistic dates span far less.
Mechanism, terms and numbers880 words
The default codec stores a numeric doc value as (v - min) / gcd. When one segment's values span more than Long.MAX_VALUE and the segment is neither table- nor block-encoded, it uses gcd 1 and 64 bits per value, and the stored v - min of the upper values wraps to negative longs; reading one value wraps back and is right. #16160 and #16285 (10.6.0 development) changed the bulk rangeIntoBitSet of the Lucene90 doc-values producer to compare stored values with signed comparisons against shifted query bounds, saturating a shift above Long.MAX_VALUE to Long.MAX_VALUE. Wrapped values then never match, and Long.MAX_VALUE can itself be a stored value. With the opt-in doc-values skip index (NumericDocValuesField.indexedField, SortedNumericDocValuesField.indexedField), newSlowRangeQuery routes every block the skip index cannot decide through that method, so count, search(q, n) and FILTER clauses return wrong hits: 2,048 evenly spaced latitudes, [45, 90], count 0 instead of 512; 100,000 random latitudes, 0 instead of 25,157; 100,000 random 64-bit hashes, [0, Long.MAX_VALUE], 2 instead of 49,931; hand-picked values add hits. No error, and CheckIndex is clean. 10.5.2 decoded before comparing and is right; an index written by 10.5.2 returns 0 once opened with the 10.6.0 RC1 commit. kkewwei reported and fixed it publicly in open PR #16896 (2026-10-23); costin, who wrote the two introducing PRs, commented on it and suggested gating on the encoding. The study's three-part fix does that and also removes the Long.MAX_VALUE sentinel for an overflowing lower bound; it passes the test and 14 doc-values suites.
- Stored value: what the codec writes per document,
(v - min) / gcdpacked in a fixed number of bits per value (Lucene90DocValuesConsumer.java:553). With 64 bits per value and gcd 1 it is a plain 64-bit subtraction that can wrap. - Encoded-domain range check: since #16160,
rangeIntoBitSetmaps the query bounds into the stored domain once (transformGcdBounds,Lucene90DocValuesProducer.java:550-563) and compares stored values directly, which lets a SIMD kernel run without decoding. - Skip index: per-block min/max values (
DocValuesSkipper), enabled byNumericDocValuesField.indexedField,SortedNumericDocValuesField.indexedFieldorDocValuesSkipIndexType.RANGE.
- Writer.
Lucene90DocValuesConsumer.java:417-422resets gcd to 1 for values outside [MIN/2,MAX/2];:511usesDirectWriter.unsignedBitsRequired((max - min) / gcd), which is 64 whenmax - minoverflows;:553writes(v - min) / gcd. Needs more than 256 distinct values (:434-435, else table encoding) and no block split (:505-507). - Per-value read is right.
mul * values.get(doc) + delta(Lucene90DocValuesProducer.java:1040) wraps back tov. - Bulk read. The dense gcd/delta override (
:1066-1076) callsrangeGcdDeltaIntoBitSet(:569-583) ->transformGcdBounds(:550-563):saturatingShiftLower/Upper(:585-616) returnLong.MAX_VALUEwhen the shifted bound would be above it (needsdelta< 0, as with latitudes) andLong.MIN_VALUEwhen it would be belowLong.MIN_VALUE(:598,:614), the lower bound is clamped to 0, and the kernels compare signed (DefaultDocValuesRangeSupport.java:39-41;PanamaDocValuesRangeSupport.java:57, 106-107). The helpers' javadoc: "Stored values are non-negative" (:588-589). - Both directions. A wrapped (negative) stored value never passes the lower bound (>= 0): missing hits. An overflowing lower bound becomes
Long.MAX_VALUE(orceilDiv(Long.MAX_VALUE, gcd)), and a document stored exactly there matches: extra hits. - Sorted numeric.
hasGcdEncoding(:2019-2023) sends dense (:2095-2105, SIMD:2116) and sparse (:2226-2240) sorted-numeric fields to the same transform. - Queries. With a skipper,
DocValuesRangeIterator.forRangebuilds a bulk iterator (DocValuesRangeIterator.java:49-60) whose MAYBE blocks callrangeIntoBitSet(:355-367,:447-453, sorted numeric:478-484).countcollects through it at any size,search(q, n)frommaxDoc >= 2048(ConstantScoreScorerSupplier.java:81-92);nextDoc()iteration of the same query is right.
The minimal repro in numbers (executed probe on main): min = sortable(-89.956), max = sortable(+89.956), span about 9.27e18; 64 bits per value, gcd 1; 1,023 stored values are negative, including all 512 in [45, 90]; the skip index has one MAYBE block; transformGcdBounds returns [Long.MAX_VALUE, Long.MAX_VALUE]; no stored value equals it; 0 hits.
Variants (executed). In the tested latitude grids count is first wrong at 257 distinct values (256 or fewer use table encoding) and search(q, 10) first loses its hits at 2,048 docs per segment; at 5,000 docs count is 904 of 1,247 because the second 4,096-doc skip block lies fully inside [45, 90], while search(q, 10) still returns 10 hits and only count and totalHits are wrong. Values {-10, MAX - 10, MAX, 3000, ...} with [MAX - 5, MAX - 1] count 1 instead of 0. SortedNumericDocValuesField is affected single-valued (dense) and multi-valued (dense and sparse). Not affected: sparse single-valued numeric fields (per-doc default), and so sparse single-valued sorted numeric, which the producer wraps as a singleton of numeric values and the query unwraps (Lucene90DocValuesProducer.java:2002-2003, SortedNumericDocValuesRangeQuery.java:138; by reading); table- or block-encoded fields; spans below Long.MAX_VALUE; fields without a skip index at query level (direct rangeIntoBitSet callers are still wrong). At a span of exactly Long.MAX_VALUE only direct rangeIntoBitSet calls go wrong: the top stored value equals the saturated lower bound, so a range above the segment's max sets one spurious bit (study tests testDenseNumericSentinelApiOnly and testDenseNumericGcdSentinel), while the skip index prunes the block at query level.
Exposure and likelihood252 words
- Default or opt-in. Default codec; the skip index is opt-in.
LongField,DoubleFieldand plainNumericDocValuesFielddo not enable it. Direct callers of the publicNumericDocValues#rangeIntoBitSetget wrong bits even without a skip index (executed);SortedNumericDocValues#rangeIntoBitSetruns the same transform with or without one (by reading). - Effect. Silent wrong results, mostly missing hits (0 of 512, 0 of 25,157, 2 of 49,931), occasionally extra hits on hand-picked values.
count,search(q, n)and FILTER clauses are all affected. No exception; the index is not corrupt, soCheckIndexcannot see it. - Data shape. For a symmetric range +/-x of sortable doubles the span exceeds
Long.MAX_VALUEexactly when x >= 2; ordinary latitudes and longitudes qualify. Float fields (sortable ints) cannot. Non-negative longs never span more thanLong.MAX_VALUE, and epoch timestamps of realistic dates span far less (epoch nanoseconds would need values more than about 292 years apart); nothing in the code exempts timestamps. - Scale. In the tested latitude grids,
countwas first wrong at 257 distinct values per segment andsearch(q, 10)first lost its hits at 2,048 documents; a segment also needs the wide span, the 64-bit gcd/delta encoding, a dense field if single-valued, and a skip block only partly inside the range. - Existing indexes. The defect is in the reader: an index written by 10.5.2 counts 0 instead of 25,157 when opened with the 10.6.0 RC1 commit, with no reindex.
- Releases. 10.6.0 was released on 2026-10-29 from RC1, which has the bug. Priority high because the released 10.6.0 has it.
One JUnit test method in lucene/core (package org.apache.lucene.search) that uses the public indexing and search API and Lucene's test framework: 2,048 evenly spaced latitudes, default codec, one segment, one range query. Deterministic, one thread; it fails the same way with assertions on and off and passes on 10.5.2.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.NumericUtils;

/**
 * A doc-values range query on a skip-indexed field must match every document whose value is in the
 * range, also when the values of one segment span more than {@link Long#MAX_VALUE}. Signed doubles
 * stored as {@link NumericUtils#doubleToSortableLong} sortable longs do that as soon as they reach
 * past +/-2 on both sides of zero, for example latitudes.
 */
public class TestSkipIndexedDocValuesRangeWideSpan extends LuceneTestCase {

  public void testLatitudeRangeQuery() throws Exception {
    // 2048 latitudes evenly spaced from pole to pole (exact binary fractions): a quarter of them,
    // 512, lie in [45, 90]. 2048 docs is the smallest segment for which search(q, 10) uses the
    // dense window-by-window bulk scorer; count(q) is already wrong from 257 distinct values on.
    int numDocs = 2048;
    int expected = 0;
    try (Directory dir = newDirectory()) {
      IndexWriterConfig iwc = new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (int i = 0; i < numDocs; i++) {
          double lat = -90 + (i + 0.5) * (180.0 / numDocs);
          if (lat >= 45 && lat <= 90) {
            expected++;
          }
          Document doc = new Document();
          doc.add(
              NumericDocValuesField.indexedField("lat", NumericUtils.doubleToSortableLong(lat)));
          w.addDocument(doc);
        }
        w.forceMerge(1);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query =
            NumericDocValuesField.newSlowRangeQuery(
                "lat",
                NumericUtils.doubleToSortableLong(45),
                NumericUtils.doubleToSortableLong(90));
        assertEquals(512, expected);
        int count = searcher.count(query);
        int hits = searcher.search(query, 10).scoreDocs.length;
        assertEquals("count(q); search(q, 10) returned " + hits + " hits", expected, count);
        assertEquals("search(q, 10) hits", 10, hits);
      }
    }
  }
}
cp $REPRO/TestSkipIndexedDocValuesRangeWideSpan.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestSkipIndexedDocValuesRangeWideSpan -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
- Expected
count(q)= 512 andsearch(q, 10)returns 10 hits, as on 10.5.2 and on the same data without a skip index.- Observed
count(q)= 0 andsearch(q, 10)returns 0 hits:AssertionError: count(q); search(q, 10) returned 0 hits expected:<512> but was:<0>.
More files, environment, full output209 words
The data, codec and query are fixed; the seed only picks the test framework's random directory, locale and settings, which the test does not depend on (seeds 1 and 2 and 10 iterations also fail). It fails with the Panama and the scalar vector provider, and compiles unchanged against 10.5.2, where it passes. 2,048 documents is the smallest segment for which search(q, 10) goes wrong too; count alone is wrong from 257 distinct values.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also branch_10_6 4ae946e5a9b (the 10.6.0 RC1 commit; jars built from it); passes on 10.5.2 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the root cause is Java bound arithmetic upstream of vectorization, and it fails with both the Panama and the scalar vector provider) |
cp $REPRO/TestSkipIndexedDocValuesRangeWideSpan.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.search.TestSkipIndexedDocValuesRangeWideSpan -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
TestSkipIndexedDocValuesRangeWideSpan > testLatitudeRangeQuery FAILED
    java.lang.AssertionError: count(q); search(q, 10) returned 0 hits expected:<512> but was:<0>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:65FF88D8F9C7AA0]:0)
        ...
        at org.apache.lucene.search.TestSkipIndexedDocValuesRangeWideSpan.testLatitudeRangeQuery(TestSkipIndexedDocValuesRangeWideSpan.java:68)
:lucene:core:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false; standalone runner on main and on the 10.6.0 RC1 commit with -ea and -da
# 10.5.2: 1 test, 0 failures (-ea, -da)
# with the recommended fix: :lucene:core:test (SUCCESS): 1 testnewSlowRangeQuery"matches all documents whose value is between lowerValue and upperValue included", andindexedFieldtakes any 64-bit long.- On a 100k-latitude index
countis 0 while iterating the query's matches finds 25,062; 10.5.2 and the field without a skip index are right. - costin, who wrote the change, wrote on #16896: "Stored values only go negative when bitsPerValue == 64".
The full argument173 words
- Contracts.
NumericDocValuesField.java:91-92(newSlowRangeQuery),:51-58(indexedField, "the specified 64-bit long value");NumericDocValues.java:113-140(rangeIntoBitSet: "the doc IDs in[fromDoc, toDoc)whose values are in[minValue, maxValue]", default per-docadvanceExact/longValue);IndexSearcher.java:491(count). - Regression. 10.5.2 runs the same skip-index query path but decodes first ("Per-doc evaluation for gcd/delta encoded fields",
Lucene90DocValuesProducer.java:966-972at 10.5.2) and passes. - An unstated premise that fails at 64 bits. The writer lines that produce wrapped 64-bit stored values are unchanged in 10.0.0, 10.5.2, RC1 and main; the gcd reset dates from LUCENE-4936 (2013). The helpers assume "Stored values are non-negative" (
Lucene90DocValuesProducer.java:588-589). - The authors treat it as a bug. kkewwei filed #16896 as a fix; costin commented on it on 2026-10-28: "Stored values only go negative when bitsPerValue == 64 so keep the saturating helpers for narrower fields and use the decoded path only for 64-bit ones."
- Why tests missed it. Existing tests use small positive deltas or values from
[0, domain]; 260 nearby tests pass on unpatched main.
The devil's-advocate check136 words
Strongest case: the helper javadoc states its assumption ("Stored values are non-negative"), and in the #16160 review costin wrote that with the saturating helpers "the per-doc decoded fallback is provably unreachable, so I removed it" (2026-06-15, answering salvatore-campagna's question about open bounds). So spans over Long.MAX_VALUE could be read as knowingly outside the optimisation's design; the skip index is opt-in and the code new in 10.6.0.
Why it fails: that proof covered bound overflow under an unstated premise, that stored values are non-negative, which fails for 64-bit packed values. No javadoc limits users to spans of Long.MAX_VALUE, the writer produces such segments for ordinary latitudes, the same query was right in 10.5.2, and the introducing author suggested an encoding-based gate for the fix in a comment on #16896. Opt-in lowers the priority, not the bug.
Recommended Decode for 64-bit fields, and no Long.MAX_VALUE sentinel for an empty lower bound
For fields stored with 64 bits per value, compare decoded values as 10.5.2 did (dense numeric and sorted numeric), and return an empty range instead of the Long.MAX_VALUE sentinel when the lower bound overflows (+18 lines in Lucene90DocValuesProducer). The test and 14 doc-values suites (738 tests) pass, assertions on and off.
All options and trade-offs3 options · 770 words
Two fixes were built and run in a scratch worktree of 645d4fe14a20; a third (revert) was not built. Option A follows the encoding gate costin suggested on #16896; option B is that PR.
Decode for 64-bit fields, and no Long.MAX_VALUE sentinel for an empty lower bound (validated by the checks) (recommended)
The study's three-part fix: (a) transformGcdBounds returns null (empty) when minValue - delta overflows upward; (b) the dense numeric gcd/delta rangeIntoBitSet runs the 10.5.2 decoded loop when bitsPerValue == 64; (c) hasGcdEncoding also requires bitsPerValue < 64, so sorted numeric uses decoded values. (b) and (c) are the gate costin suggested in a comment on #16896; (a) closes a narrower collision on gcd > 1 fields stored with fewer than 64 bits per value, where ceilDiv(Long.MAX_VALUE, gcd) can be a stored value. At query level the skip index prunes that case, so it shows only through direct rangeIntoBitSet calls.
   private static long[] transformGcdBounds(long minValue, long maxValue, long mul, long delta) {
     assert mul > 0;
+    if (delta < 0 && minValue > Long.MAX_VALUE + delta) {
+      // minValue - delta overflows: no stored value can reach the lower bound. Do not saturate to
+      // Long.MAX_VALUE here, since Long.MAX_VALUE (or ceilDiv(Long.MAX_VALUE, mul)) can itself be
+      // a stored value.
+      return null;
+    }
@@ ... @@
+                if (entry.bitsPerValue == 64) {
+                  // with 64 bits per value, the stored v - min can exceed Long.MAX_VALUE and read
+                  // back as a negative long: compare decoded values instead
+                  for (int d = fromDoc; d < toDoc; d++) {
+                    long v = mul * values.get(d) + delta;
+                    if (v >= minValue && v <= maxValue) {
+                      bitSet.set(d - offset);
+                    }
+                  }
+                  return;
+                }
                 Lucene90DocValuesProducer.rangeGcdDeltaIntoBitSet(
@@ ... @@
             && entry.table == null
+            && entry.bitsPerValue < 64 // 64-bit stored values can wrap: compare decoded values
             && (entry.gcd != 1 || entry.minValue != 0);
Trade-offs
DirectWriterrounds 57-64 required bits up to 64 (DirectWriter.java:230-235), so every field whose stored values need more than 56 bits (with gcd 1, a span of 2^56 or more), not only spans overLong.MAX_VALUE, goes back to the 10.5.x decoded loop and loses the #16160/#16285 speedup. Narrower fields keep the encoded path, including saturated open bounds such as [Long.MIN_VALUE, t] on timestamps, #16160's stated goal. No benchmark was run.- A variant could keep the SIMD kernel for 64-bit fields by running it on a decoding
LongValueswrapper, as #16896 does (not built).
What the checks validated
- Stock + test: fails with assertions on and off; + fix: passes with assertions on and off.
- + fix: 14 suites, 738 tests (66 skipped), 0 failures, assertions on and off:
TestSkipIndexedDocValuesRangeWideSpan,TestSkipBlockRangeIteratorBitSetOperations,TestDocValuesRangeIteratorIntoBitSet,TestDocValuesRangeIterator,TestSortedNumericDocValuesRangeIterator,TestDocValuesQueries,TestIndexSortSortedNumericDocValuesRangeQuery,TestIndexOrDocValuesQuery,TestBulkScorerConsistency,TestSortedSkipperScorerSupplier, the threeTestLucene90DocValuesFormat*suites,TestCheckIndex;:lucene:core:check -x testpasses. - With the patched file shadowed, the study's 11 tests (false-positive sentinels, gcd 7 and 454279, sorted numeric dense, sparse and variable cardinality, 100k latitudes and hashes) pass with assertions on and off; 10 of 11 fail without it.
- Earlier, on branch_10_6
d04ee73177, the same three changes passed 5 regression tests and 3,803 package tests; removing (a) leaves the gcd = 454279 test failing. Z3 shows the transform with (a) correct for gcd == 1 at up to 63 bits per value and for gcd > 1 (a model, not the Java). Not run: the full test suite, nightly tests, benchmarks.
Removes the saturating helpers; if minValue - delta or maxValue - delta overflows, runs the kernel on decoded values, else uses exact encoded bounds (+30/-40, head ab6a77d35e94, applies cleanly to 645d4fe14a20). Built and run: the test and the same 14 suites (738 tests) pass with assertions on.
Trade-offs
Correct, but, as costin pointed out on #16896, the check is per query: common open-ended ranges such as ts <= x ([Long.MIN_VALUE, x] on a field with a positive minimum) also leave the encoded path. Its test covers the API only, not query-level count, the false-positive sentinels or sparse sorted numeric.
What the checks validated
- Test and 14 suites pass (gradle, assertions on); the candidate's standalone shadow run passes with assertions on and off.
Restores the 10.5.x per-document decoded check on branch_10_6.
Trade-offs
Simplest to reason about under release pressure, but drops the speedup for every gcd/delta field.
Already reported, with a fix, in open PR #16896 by kkewwei (2026-10-23); it is not merged, has no milestone and lists itself under 10.7.0. costin commented on it on 2026-10-28. 10.6.0 RC1 contains the bug; the vote passed and 10.6.0 was released from it on 2026-10-29. The repro passes with the PR's change.
- #16896
- Open, unmerged, no milestone, no approval; head
ab6a77d35e94unchanged since 2026-10-23 (checked 2026-10-29; unchanged). - Comment
- costin (2026-10-28, a conversation comment; the PR has no formal review): gate on the encoding (decoded path only when
bitsPerValue == 64) instead of a per-query overflow check, and add open-bound and sparse sorted-numeric tests. No reply yet. - Release
- 10.6.0 RC1 (
4ae946e5a9b, still the branch_10_6 head) fails the repro; its dev@ vote passed and 10.6.0 was released from it on 2026-10-29. Open #16930 removes 10.7.0, where #16896's CHANGES entry sits. - Repro on the PR
- The test and 14 doc-values suites pass with #16896's production change applied to main
645d4fe14a20.
Applications that use a skip-indexed doc-values range query as a filter, for example to restrict results, would get wrong match sets on 10.6.0, mostly missing documents; this depends on downstream use, not on a Lucene guarantee for untrusted input.
By reading the code: a survey that checked SIMD kernels against their scalar meaning followed the bound transform in front of the range kernel. Z3 on 64-bit bit-vectors then characterised exactly when it fails and checked a three-part fix, and an independent verifier reproduced it with its own tests on the stock jars.
The method in full172 words
Method: code reading (non-formal), during the study's SIMD translation-validation survey (run 3): the whole pipeline around DocValuesRangeSupport was translated, including the bound transform transformGcdBounds and the writer's encoding. Z3 (QF_BV 64-bit and NIA) then showed that with gcd 1 a false negative exists exactly when a stored value is negative (wrapped) and hi - min overflows, and a false positive needs a stored value equal to Long.MAX_VALUE (with gcd > 1, ceilDiv(Long.MAX_VALUE, gcd)); it found the fix's two rules correct on the model. Six JUnit tests failed on main and passed on 10.5.2.
- A separate verifier wrote its own 11-case API and query matrix: 10 of 11 fail on main in both vector modes, all pass on 10.5.2 and with the fix; it showed that query-level false positives are reachable with 64 bits per value.
- A 10.6 fact sheet and an independent review reproduced it on branch_10_6 and main, checked cross-version reads and validated a port of #16896.
- This doc's test is a one-method, 2,048-document form of the verifier's latitude tests.
Known: open PR #16896 (kkewwei, 2026-10-23) reports the same mechanism and fixes it. 216 logged queries on 2026-10-29 (GitHub, mailing lists, downstream repositories, the web) and the files of all 415 open PRs found no other report; refreshed the same morning.
Searches5 searches
#16896 ("fix long overflow in GCD-encoded DocValues range transform") describes the encoded range becoming [Long.MAX_VALUE, Long.MAX_VALUE] for the range [-1, 1]. It predates any public report from this hunt, so the bug is classed known. Related, not reports: #16160 and #16285 (introducing; the #16160 review discussed open bounds, not wrapped stored values); #16897 (same author, depends on #16896; alone it would extend the bug to fields without a skip index); #16917 (same kernel, does not fix it); #16835 (table encoding, not affected); #16884-#16886 (doc-values range wrong results on index-sorted or skip-indexed fields with document blocks or multi-valued fields, a different root cause; the issues have milestone 10.6.0 and were closed by #16893); the dev@ RC1 vote thread (nobody mentions #16896).
What this evidence adds to #16896: it is a 10.6.0 regression (10.5.2 correct, RC1 wrong); plain query-level count and search on ordinary latitudes fail (0 of 25,157); 10.5.2-written indexes read wrong without a reindex; tests for query-level count, false-positive sentinels and sparse and variable-cardinality sorted numeric, which costin asked for; and a fix that already follows costin's encoding gate.
| Where | When | How | Found |
|---|---|---|---|
| GitHub (apache/lucene issues, PRs, commits; downstream repositories) | 2026-10-29 | a scripted prior-report search (144 queries, #16896 found at rank 2), 20 more GitHub queries and manual searches: transformGcdBounds, saturatingShiftLower, rangeGcdDeltaIntoBitSet, "GCD-encoded DocValues range", "doc values range overflow", "rangeIntoBitSet overflow" | #16896 (same bug); #16160, #16285 (introducing); #16897, #16917, #16835 related |
| Open apache/lucene PRs | 2026-10-29 | changed-file lists of all 415 open PRs | only #16896 changes transformGcdBounds or the saturating helpers |
| Mailing lists | 2026-10-29 | dev@ (incl. the 10.6.0 RC1 vote and feature-freeze threads), java-user@, issues@, commits@ | no report; the vote thread does not mention #16896 |
| JIRA archive | 2026-10-29 | a scripted prior-report search, 6 JQL queries (the code dates from 2026, after the migration) | only unrelated issues |
| Refresh | 2026-10-29 | branch heads, Maven Central, #16896 state and conversation | #16896 still open, no milestone, head unchanged; costin's comment unanswered |
Introduced in 10.6.0 development by #16160 (merged 2026-07-02, numeric and single-valued sorted numeric) and #16285 (2026-07-13, multi-valued sorted numeric). All releases 10.0.0 to 10.5.2 are correct; main and 10.6.0 RC1 are affected.
Versions tested8 rows
#16160 "Optimize encoded numeric range bitsets" and #16285 "Apply GCD bound transform to sorted numeric rangeIntoBitSet" are by costin, both milestone 10.6.0 (9b68f633fdd6 and 263c3a4765f0 on main; cherry-picks 75f6e5deced and baa5f743f30 on branch_10x, ancestors of branch_10_6). Single-valued sorted numeric breaks with #16160 already because the query unwraps it to NumericDocValues. #16295 in between changes no result. Before 10.0.0 there is no doc-values skip index.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the test fails, assertions on and off (gradle and standalone, both vector providers); study tests 10 of 11 fail |
branch_10_6 4ae946e5a9b (10.6.0 RC1) | affected | the test fails, assertions on and off; history probe 0 / 0 / 0 of 512 |
| 10.0.0 to 10.5.2 (12 releases) | not affected | history probe 512 / 512 / 512; the test passes on 10.5.2, assertions on and off |
9b68f633fdd6 (#16160) vs parent a7e1f014bc5 | bisect | numeric and single-valued sorted numeric 512 -> 0; two-valued sorted numeric still 512 (same on branch_10x 75f6e5deced) |
263c3a4765f0 (#16285) vs parent 4b982fffe24 | bisect | two-valued sorted numeric 512 -> 0 (same on branch_10x baa5f743f30) |
| index written by 10.5.2, read by RC1 | cross-version | 100k latitudes [45, 90]: 25,157 under 10.5.2, 0 under RC1 |
| 9.12.3 | no skip index | no doc-values skip index or indexedField (by reading) |
with the recommended fix (main 645d4fe14a20) | not affected | the test, 14 doc-values suites and the study's 11 tests pass |
Reproduced by the finder, an independent verifier with its own tests, a 10.6 fact sheet and its review, a reviewer from another model family with its own test, and runs of the minimal test on main and RC1. Both fixes pass the same tests.
Checks and verdicts306 words
Every check re-ran a repro on the stock jars. The cross-model review (OpenAI GPT-5.6) could not run any command in its first two attempts; the third ran its own test and found the bug real, with high confidence, on the single-valued numeric count path.
| Check | Verdict | What it found |
|---|---|---|
| finder (study run 3) | candidate | Code reading; Z3 characterisation; 6 JUnit tests fail on main and pass on 10.5.2. |
| study verifier | reproduced | Own 11-case matrix: 10 of 11 fail on main in both vector modes, 0 on 10.5.2 and with the fix; query-level false positives shown reachable. |
| 10.6 fact sheet and review | reproduced on branch_10_6 and main | 5 regression tests, a 25-check standalone repro, the cross-version read, a validated #16896 port; a 20,000-query differential check found 0 wrong with #16896 and 5,494 without. |
| candidate packaging | real | The minimal test fails on 645d4fe14a20 with -ea and -da, both vector providers, 3 seeds; passes on 10.5.2; both fixes pass. |
| cross-model review, refute lens | real (high confidence) | Attempts 1 and 2 could not start any command and ended procedurally. Attempt 3 wrote its own test (257 raw longs near Long.MIN_VALUE plus 257 in [0, 256], skip-indexed, one segment): count 0 instead of 257 on main ea57360912ed with -ea and -da; the no-skip and narrow-span controls give 257; the study fix and #16896's change pass. Intended-behaviour argument: weak. Scope: the single-valued numeric count path only. |
| Follow-up | known (#16896) | Release matrix 10.0.0-10.5.2, RC1 and main; bisect of #16160 and #16285 on main and branch_10x; cross-version read; prior-report search. |
| this doc's runs | reproduced, fix validated | The one-method test through gradle on 645d4fe14a20 (-ea, -da); fix A with 14 suites and check; #16896's change with 14 suites; the study's 11 tests with fix A shadowed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 561 KB
Finding record, Lucene and upstream sources, repro files and diagram notes819 words
- Registry title
- Doc-values range queries with a skip index return wrong hits when a segment's values span more than Long.MAX_VALUE
- Area
- codecs / doc values
- Priority
- High, rank 3: A 10.6.0 regression that returns badly wrong range hits on ordinary signed-double or hash data with the opt-in skip index, and the outside fix is still unmerged.
- Impact class
- silent wrong results
- Impact note
- Default codec plus the opt-in doc-values skip index (indexedField) on ordinary data whose segment values span more than Long.MAX_VALUE (sign-crossing doubles of magnitude >= 2, 64-bit ids/hashes); 10.6.0 regression (released 2026-10-29) that also misreads indexes written by 10.5.2.
- Summary
- You index numeric doc values with a skip index (NumericDocValuesField.indexedField) where one segment's values span more than Long.MAX_VALUE, and run a doc-values range query. You expect the same hits as 10.5.2. Instead the encoded-domain bound transform wraps: 100k random latitudes queried for [45, 90] gave 0 hits instead of 25,157, 64-bit hashes gave 2 instead of 49,931, and some cases add wrong hits.
- Introduced
- #16160 (9b68f633fdd6) and #16285 (263c3a4765f0) (2026-07-02 (#16160); 2026-07-13 (#16285))
- First affected version
- 10.6.0 (released 2026-10-29) and unreleased main
- Affected versions
- main b83101cdd2 and branch_10_6 d04ee73177 [exec]; 10.5.2 correct [exec]; main 645d4fe14a2 [exec 2026-10-29, -ea and -da: 10 of 11 fail]; branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b (10.6.0 RC1) have the identical Lucene90DocValuesProducer blob c9e4bc13f1c [read]; 10.6.0 release jars (rev 4ae946e5a9b) [exec 2026-11-02, seed DEADBEEF: minimal TestSkipIndexedDocValuesRangeWideSpan 1 of 1 and the two TestVerify classes 10 of 11 fail with -ea and -da]; main e1faeba08bd [exec 2026-11-02, -ea and -da: the TestVerify classes 10 of 11 fail]; branch_11x da3ea39fa59 (same producer blob dd67e555e5e as main) and branch_10_6 91eaab4fb29 (the 10.6.1 work; still the 10.6.0 blob c9e4bc13f1c) [read]; not targeted for 10.6.1 as of 2026-11-02 (#16896 has no milestone and files its CHANGES entry under 11.0.0); branch_10x was decommissioned on 2026-10-29 (#16911)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed in the earlier formal verification study by independent AI checks and a rerun on Lucene main; also a cross-model review that agreed; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by Z3
- Upstream and prior reports
- outside open PR #16896 (kkewwei, opened 2026-10-23, 'fix long overflow in GCD-encoded DocValues range transform', no milestone); a port of its original 2026-10-23 version to branch_10_6 passed all its regression tests; costin reviewed #16896 on 2026-10-28: the per-query overflow check also drops the encoded path for open-ended ranges; they suggested gating on the encoding instead (decoded path only for 64-bit fields) and asked for open-bound and sparse sorted-numeric tests; kkewwei answered that review on 2026-10-29 with a refined per-query bounds check (canTransformGcdBounds, which keeps the encoded path when the transform cannot overflow and otherwise scans decoded values) and added rangeIntoBitSet-level open-bound and sparse sorted-numeric tests; head db2d783e394 (a merge of main, 2026-11-02) is still open and unmerged, with no milestone and no committer review; its CHANGES entry is under 11.0.0 Bug Fixes; main e1faeba08bd, branch_11x da3ea39fa59 and branch_10_6 91eaab4fb29 still have the old code (recheck 2026-11-02)
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28, upstream main on 2026-10-29): the repro test through gradle in a scratch worktree, assertions on and off, stock, with the recommended fix and with the production change of #16896; the standalone runner on main (both vector providers, three seeds), on jars built from the 10.6.0 RC1 commit4ae946e5a9band on the 10.5.2 release jars; the study's 11 tests on main with and without the recommended fix. Earlier runs: the study tests on mainb83101cdd2anda9779ef3c193(10 of 11 fail); the 10.6 fact sheet's 5 regression tests, 25-check repro and 20,000-query differential check on branch_10_6d04ee73177.
- Finding record
SECURITY.md:28, 54 (threat model)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:417-422, 434-435, 505-507, 511, 553a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java:550-563, 569-616, 1040, 1066-1076, 2002-2003, 2019-2023, 2095-2116, 2226-2240; document/SortedNumericDocValuesRangeQuery.java:138a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/internal/vectorization/DefaultDocValuesRangeSupport.java:39-41; lucene/core/src/java25/.../PanamaDocValuesRangeSupport.java:57, 106-107a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/DocValuesRangeIterator.java:49-60, 355-367, 447-453, 478-484; search/ConstantScoreScorerSupplier.java:81-92
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/document/ (only NumericDocValuesField, SortedNumericDocValuesField, SortedDocValuesField and SortedSetDocValuesField reference DocValuesSkipIndexType.RANGE)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java:2080-2105 (sorted-numeric rangeIntoBitSet, no skipper check)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/document/NumericDocValuesField.java:51-58, 91-92; index/NumericDocValues.java:113-140; search/IndexSearcher.java:491a Lucene clone: git show releases/lucene/10.5.2:lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java (lines 966-972)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java:585-616
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/packed/DirectWriter.java:230-235
- TestSkipIndexedDocValuesRangeWideSpan.java (lucene/core, one test):
repro/LFV-044/TestSkipIndexedDocValuesRangeWideSpan.java(73 lines)
Made in parallel with this doc from the minimal repro and an executed probe of it on main 645d4fe14a20.
assets/LFV-044/bug.png(561 KB)