add(min, max) walks the range one 65,536-doc block at a time and ends each step at Math.min(max, (block + 1) << 16), in int. For the last block, 32,767, the shift gives 2^31, which wraps to -2,147,483,648. The step's end is negative: Lucene's assertion fires, and with assertions off the builder either writes past the last block's bit set or moves on to a nonexistent block 32,768.
RoaringDocIdSetstores a set of doc ids in blocks of 65,536 (2^16): doc d is in block d >>> 16. Each block is kept as a short list of docs, a bit set, the inverse list, a single range, or the shared all-docs set.Builder.add(int)adds one doc.Builder.add(min, max), new in 10.5.0, adds the range [min, max) at once and is documented as equivalent to adding each doc.LRUQueryCacheuses this builder for cached queries that match fewer than 1% of a segment's docs. Scorers that find whole runs of matching docs report them withcollectRange(min, max), which the cache passes toadd(min, max).- A Java
intholds at most 2,147,483,647 (2^31 - 1). A segment may hold up toIndexWriter.MAX_DOCS= 2,147,483,519 docs, so the last block, 32,767, runs up to 2^31, which does not fit.
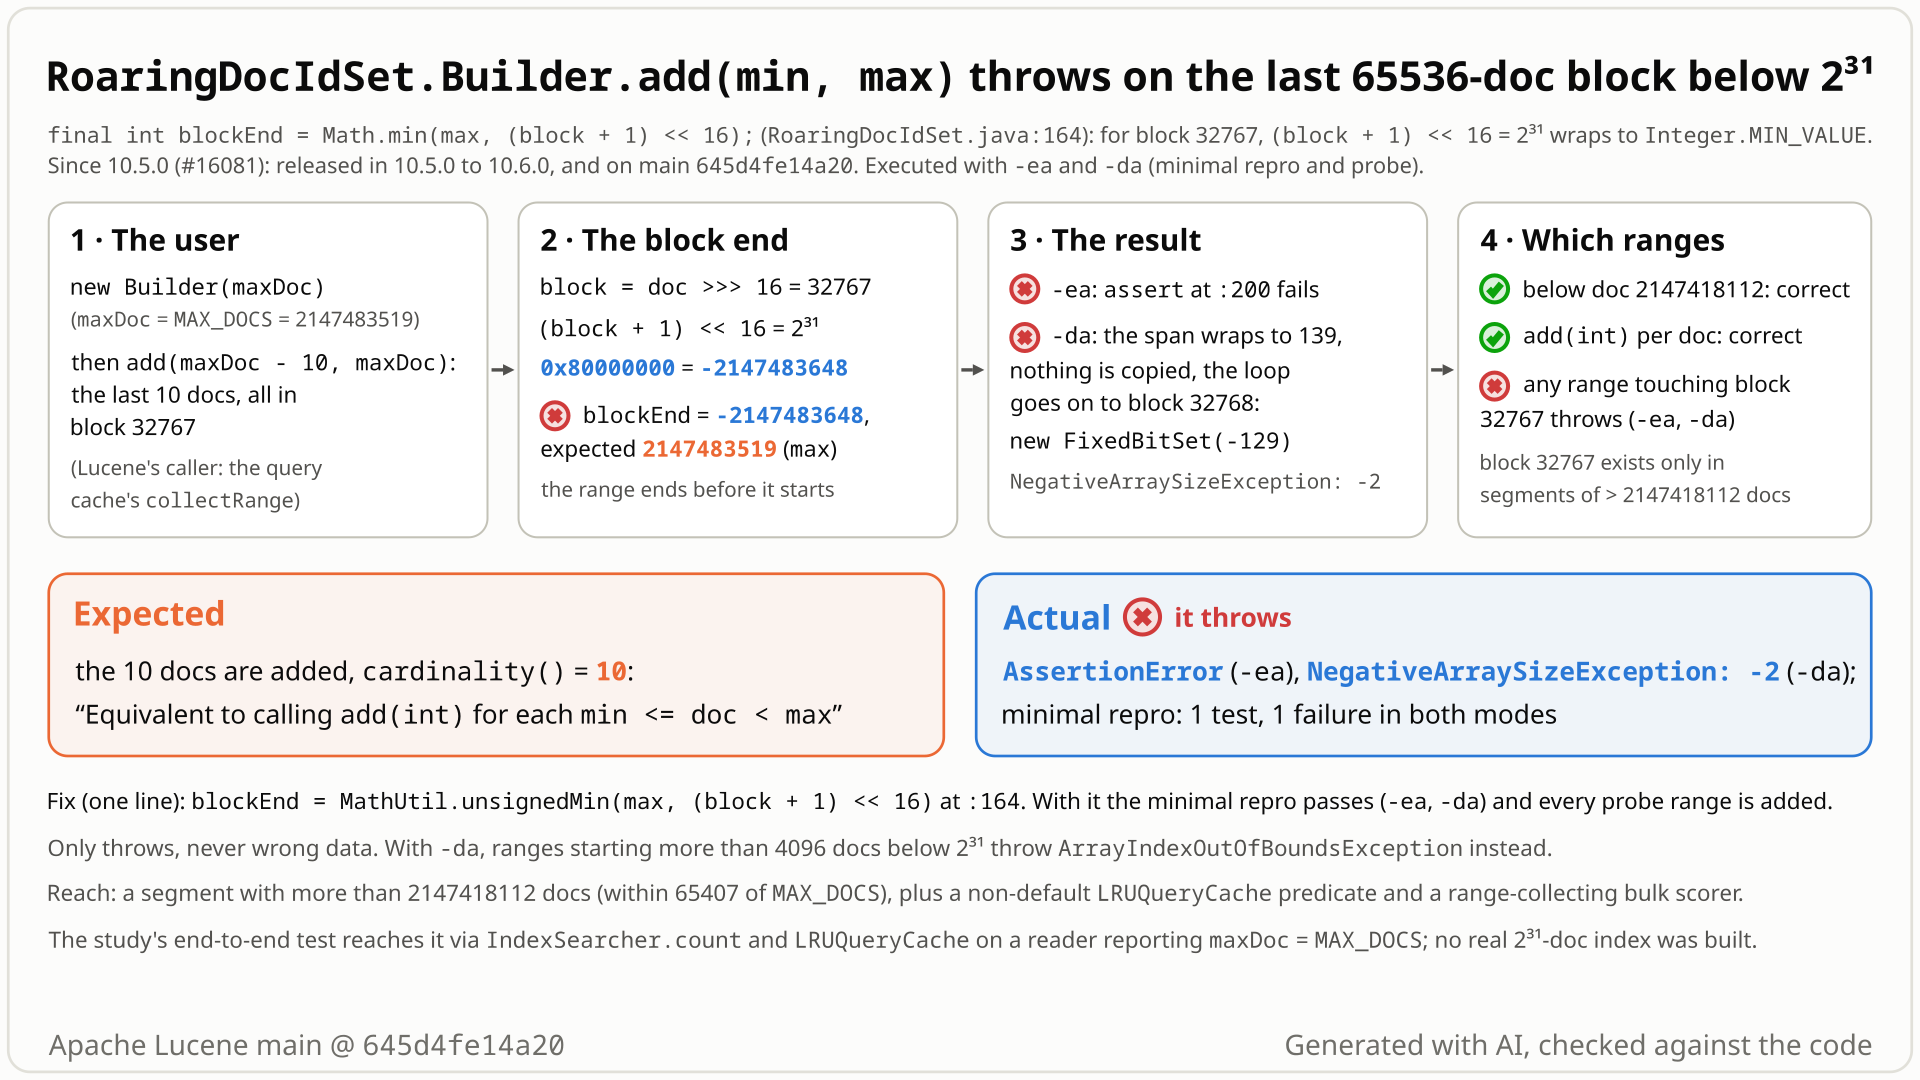
add(min, max) throws instead of adding the last 10 docs. Select the still to open it at full size. Generated with AI, checked against the code.- Make a builder for the largest legal segment,
new RoaringDocIdSet.Builder(IndexWriter.MAX_DOCS): 2,147,483,519 docs. Doc ids are grouped in blocks of 65,536; the last block, number 32,767, starts at doc 2,147,418,112. - Add the segment's last 10 docs in one call,
add(2147483509, 2147483519). You expect what tenadd(int)calls give: a set of 10 docs. - The method stops each block at its end,
(block + 1) << 16. For block 32,767 that is 2^31 = 2,147,483,648, one more than anintholds, so it wraps to -2,147,483,648 and the block end is negative. - You get an exception: Lucene's own
AssertionErrorwith assertions on,NegativeArraySizeException: -2with them off. Every range that touches this block throws; none returns a wrong set. - In search, only the query cache's sparse path adds ranges. It needs such a segment, a custom leaf predicate, a cache over 1.34 GB per partition and an index-sorted range query, so default setups never get there.
Only segments of more than 2,147,418,112 docs, the 65,407 largest legal sizes. In search, only the query cache's sparse path adds ranges, and only with a non-default leaf predicate (the default never caches segments of 2^30+ docs), a cache over 1.34 GB per partition and an index-sorted doc-values range query. It throws; it never returns wrong data.
Mechanism, terms and numbers732 words
RoaringDocIdSet splits doc ids into blocks of 65,536 (2^16). #16081 (10.5.0) added Builder.add(int min, int max) so that LRUQueryCache can cache range-collecting scorers cheaply. It walks the range block by block and caps each step at Math.min(max, (block + 1) << 16), in int. For block 32,767, the last one an int doc id can be in (docs 2,147,418,112 and up), the shift gives 2^31, which wraps to Integer.MIN_VALUE. Lucene's own assertion then fires. With assertions off it throws either a NegativeArraySizeException (the loop moves on to a block 32,768 that does not exist) or an ArrayIndexOutOfBoundsException (a write past the last block's bit set), depending on where the range starts.
So new RoaringDocIdSet.Builder(IndexWriter.MAX_DOCS).add(MAX_DOCS - 10, MAX_DOCS) throws instead of adding 10 docs, although the javadoc calls it equivalent to adding each doc, and add(int) handles the same docs correctly. It only throws; no case returns a wrong set. In an index this needs one segment of more than 2,147,418,112 docs (fewer than 65,407 short of IndexWriter.MAX_DOCS), and in search a non-default LRUQueryCache setup (the default leaf predicate never caches such segments). The fix is one line.
int doc = min;
while (doc < max) {
  final int block = doc >>> 16;                            // 2147483509 >>> 16 = 32767
  final int blockEnd = Math.min(max, (block + 1) << 16);   // :164  32768 << 16 = 2^31 wraps to Integer.MIN_VALUE
  if (block != currentBlock) { flush(); currentBlock = block; firstDocId = doc; }
  appendRangeInCurrentBlock(doc, blockEnd, block);         // :170  toDocExclusive = Integer.MIN_VALUE
  doc = blockEnd;                                          // :171  Integer.MIN_VALUE is still < max
}- When. Block 32,767 starts at 32,767 << 16 = 2,147,418,112. Segments with
maxDocin (2,147,418,112, 2,147,483,519] have it, with up to 65,407 docs in it. Any range that touches it fails; ranges below it are exact (Z3 proof A1s in the study). - Assertions on.
:199repeats the same wrapped expression and passes;:200,assert fromDoc < toDocExclusive, fires. - Assertions off.
span = toDocExclusive - fromDoc(:201) wraps back to a positive number, but it is the distance fromfromDocto 2^31, not tomax(139 for the repro), and:202takes the sparse branch whencurrentBlockCardinality + span <= 4096. So the branch depends on where the range starts, not on its size. Sparse branch (:202-206; for a range that starts the block: it starts within 4,096 doc ids of 2^31, the last 3,967 docs of aMAX_DOCSsegment, like the repro): the copy loopd < toDocExclusiveruns zero times, andlastDocIdbecomesInteger.MAX_VALUE. The loop goes round again withblock = Integer.MIN_VALUE >>> 16 = 32768; therenumBits = Math.min(1 << 16, maxDoc - (32768 << 16))(:208-211) is -129, andnew FixedBitSet(-129)throwsNegativeArraySizeException: -2. - Dense branch (
:207-218): any earlier start in block 32,767, whatever the range's size (10 docs at 2,147,418,112, a range that crosses in from block 32,766, or the entire populated last block). The bit set is sized for the real block (at most 65,407 bits, 1,022 words), anddenseBuffer.set(fromDoc - offset, Integer.MIN_VALUE - offset)(:216), that isset(..., 65536), writes past it:Arrays.fillinFixedBitSet.set(FixedBitSet.java:793) throwsArrayIndexOutOfBoundsException: Array index out of range: 1023. - Why
add(int)is fine. The per-doc path (:114-130,:176-194) never computes(block + 1) << 16; the constructor's block count(maxDoc + (1 << 16) - 1) >>> 16(:63) is unsigned and correct for everymaxDoc >= 0(Z3 proof A2).
cacheIntoRoaringDocIdSet (:656-685) forwards LeafCollector.collectRange(min, max) to builder.add(min, max) (:672); the default cacheImpl takes this path when the scorer's cost is below 1% of maxDoc (:580-592). The shipped range-reporting scorer that fits that density is RangeBulkScorer (RangeBulkScorer.java:79), built by SortedSkipperScorerSupplier for doc-values range queries (SortedNumericDocValuesRangeQuery, SortedSetDocValuesRangeQuery) on the primary index-sort field when that field is dense, has a skip index and the segment has no blocks (SortedNumericDocValuesRangeQuery.java:237-253). The study verifier ran this path end to end: IndexSearcher.count(NumericDocValuesField.newSlowRangeQuery(...)) with an accept-all LRUQueryCache throws from RangeBulkScorer.score -> collectRange -> Builder.add(int, int). Its segment is a real 1-doc index seen through a FilterLeafReader that reports maxDoc = MAX_DOCS; no 2^31-doc index was built.
Exposure and likelihood402 words
- Direct users of the public,
@lucene.internalRoaringDocIdSet.Builder#add(int, int)withmaxDocabove 2,147,418,112: every range that touches the last block throws. - Through search, all of these must hold (the study verifier checked each, by execution where noted):
- Scale. One segment with more than 2,147,418,112 docs, up to
MAX_DOCS= 2,147,483,519. No segment this large was built: the search-path test fakes the size with aFilterLeafReader, so it shows the code route, not that such a segment is practical to build, merge and search. - A query cache. Main has none by default since #14187 (
IndexSearcher.java:82-84); 10.5.x and 10.6.0 installLRUQueryCache(1000, min(32 MB, heap / 20))by default. - A non-default leaf predicate. The default
MinSegmentSizePredicatecomputesmaxDoc * 2, which overflows formaxDoc >= 2^30, so it never accepts such a segment (a separate bug, LFV-081; executed by the study verifier). The expert constructors accept anyPredicate<LeafReaderContext>. - A large cache. The worst-case-size gate (
LRUQueryCache.java:792-801, called fromshouldCacheat:804-808with the top-level reader'smaxDoc) needsmaxDoc / 8 * 5bytes per partition. A reader over such a segment has a top-levelmaxDocbetween 2,147,418,113 andMAX_DOCS(BaseCompositeReader.java:89-106), so that is about 1.34 GB. On main the 4-argument expert constructor uses 16 partitions (about 21.5 GB in total); 10.5.x and 10.6.0 have no partitions. The default 32 MB cache never passes. - A sparse, range-collecting query (cost below 1% of
maxDoc, about 21 million docs) whose matching docs reach the last 65,536 docs of the segment, for example a "latest docs" filter on a time-sorted index, and the caching policy deciding to cache it.
- Scale. One segment with more than 2,147,418,112 docs, up to
- Effect. The search fails with an unchecked exception while the cache is filled. Nothing is cached, no index data is touched, and no wrong result is returned; only the cache's bookkeeping has run (the lookup counted a miss and the caching policy was told the query was used,
LRUQueryCache.java:812-814,:1060-1082). It repeats whenever the policy tries to cache that query on that segment. - Never silent. The study verifier's sweep compared
add(min, max)with the per-doc reference over 4,512 cases: the 2,943 ranges below block 32,767 were exact, and all 1,569 that touch it threw. With the fix all 4,512 are exact. This is not only a sample: both assertions-off branches end in an exception for everymaxDocup toMAX_DOCS(the verifier's case analysis, confirmed againstRoaringDocIdSet.java:201-218andFixedBitSet.java:773-795).
One JUnit test, one method, deterministic, single thread, public API: a builder for IndexWriter.MAX_DOCS docs, add(MAX_DOCS - 10, MAX_DOCS), and cardinality() must be 10. It allocates a 32,768-slot array and a 4,096-entry buffer, the test itself runs in about 1.5 s, and it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.util;

import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestRoaringDocIdSetLastBlock extends LuceneTestCase {

  public void testAddRangeInLastBlock() {
    int maxDoc = IndexWriter.MAX_DOCS;
    RoaringDocIdSet.Builder builder = new RoaringDocIdSet.Builder(maxDoc);
    // expected: adds the 10 docs; actual: throws, the block end (block + 1) << 16 overflows
    try {
      builder.add(maxDoc - 10, maxDoc);
    } catch (Throwable t) {
      throw new AssertionError("expected add(maxDoc - 10, maxDoc) to add 10 docs, got " + t, t);
    }
    assertEquals(10, builder.build().cardinality());
  }
}
cp $REPRO/TestRoaringDocIdSetLastBlock.java $LUCENE/lucene/core/src/test/org/apache/lucene/util/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.util.TestRoaringDocIdSetLastBlock -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (fails with NegativeArraySizeException instead)
- Expected
add(2147483509, 2147483519)adds the segment's last 10 docs, andbuild().cardinality()is 10.- Observed
- It throws: Lucene's own
AssertionError(fromDoc < toDocExclusive) with assertions on,NegativeArraySizeException: -2with them off.
More files, environment, full output274 words
- Smallest input. No index is needed: the builder alone shows it, and 10 docs are the smallest range that reads naturally (any range in the last block fails).
RoaringDocIdSet.Builderandadd(int, int)are public (the class is@lucene.internal); the test sits inorg.apache.lucene.utilonly to matchTestRoaringDocIdSet. - The
try/catchonly makes the failure say "expected vs got" in both assertion modes. - As the regression test: this same method, for example in
TestRoaringDocIdSet. - Versions. The same file fails on 10.5.0, 10.5.1, 10.5.2 and 10.6.0 with assertions on and off; on 10.4.0 it does not compile, because
add(int, int)does not exist yet.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on 10.5.0, 10.5.1, 10.5.2 and 10.6.0 (assertions on and off) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp $REPRO/TestRoaringDocIdSetLastBlock.java $LUCENE/lucene/core/src/test/org/apache/lucene/util/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.util.TestRoaringDocIdSetLastBlock -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (fails with NegativeArraySizeException instead)
# gradle, main 645d4fe14a20, seed DEADBEEF, assertions on
TestRoaringDocIdSetLastBlock > testAddRangeInLastBlock FAILED
    java.lang.AssertionError: expected add(maxDoc - 10, maxDoc) to add 10 docs, got java.lang.AssertionError
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:61B00FCE11EC79BB]:0)
        at org.apache.lucene.util.TestRoaringDocIdSetLastBlock.testAddRangeInLastBlock(TestRoaringDocIdSetLastBlock.java:31)
        Caused by:
        java.lang.AssertionError
            at org.apache.lucene.util.RoaringDocIdSet$Builder.appendRangeInCurrentBlock(RoaringDocIdSet.java:200)
            at org.apache.lucene.util.RoaringDocIdSet$Builder.add(RoaringDocIdSet.java:170)
            at org.apache.lucene.util.TestRoaringDocIdSetLastBlock.testAddRangeInLastBlock(TestRoaringDocIdSetLastBlock.java:29)
1 test completed, 1 failed
# gradle, assertions off (-Ptests.asserts=false)
    java.lang.AssertionError: expected add(maxDoc - 10, maxDoc) to add 10 docs, got java.lang.NegativeArraySizeException: -2
        Caused by:
        java.lang.NegativeArraySizeException: -2
            at org.apache.lucene.util.FixedBitSet.<init>(FixedBitSet.java:148)
            at org.apache.lucene.util.RoaringDocIdSet$Builder.appendRangeInCurrentBlock(RoaringDocIdSet.java:211)
            at org.apache.lucene.util.RoaringDocIdSet$Builder.add(RoaringDocIdSet.java:170)
1 test completed, 1 failed
# 10.5.0, 10.5.1, 10.5.2, 10.6.0: the same, with assertions on and off (FixedBitSet.java:150 there)
# with fix A (assertions on and off) or fix C (assertions off): BUILD SUCCESSFUL, 1 test
# with fix C, assertions on, together with TestRoaringDocIdSet: BUILD SUCCESSFUL, 24 tests- The javadoc calls
add(min, max)"Equivalent to calling add(int) for each min <= doc < max", with onlyIllegalArgumentExceptionfor bad bounds; the same 10 docs added one by one work. IndexWriter.MAX_DOCS(2,147,483,519) makes such segments legal, and the builder accepts anymaxDoc.- Lucene's own assertion rejects the wrapped value; its scorers guard the same window-end pattern with
MathUtil.unsignedMin.
The full argument216 words
- Contract.
RoaringDocIdSet.java:132-142: "Add a contiguous half-open range[min, max)of doc ids. ... Equivalent to callingadd(int)for eachmin <= doc < max, but uses a more efficient implementation for dense ranges." It documentsIllegalArgumentException"ifmin > max, ifmin <= lastDocId, or ifmaxexceedsmaxDoc" as the only failures; none holds here. - Legal sizes.
IndexWriter.java:201-208:MAX_DOCS = Integer.MAX_VALUE - 128, the "Hard limit on the maximum number of documents that may be added to the index".Builder(int maxDoc)(:61-67) accepts any size. - The code means to stop at the block end.
Math.min(max, (block + 1) << 16)exists to cap the step at the block end; the wrap defeats it, andassert fromDoc < toDocExclusive(:200) rejects the result. - The same pattern is guarded elsewhere.
MathUtil.unsignedMin(MathUtil.java:196-199) caps window ends in the search package, for exampleDenseConjunctionBulkScorer.java:198and:214,MaxScoreBulkScorer.java:216,ConstantScoreBulkScorer.java:132,DisjunctionMaxBulkScorer.java:90,TimeLimitingBulkScorer.java:73andRangeDocIdStream.java:68. - Why tests miss it.
TestRoaringDocIdSetand its base classBaseDocIdSetTestCaseuse sets of at most 2^20 (1,048,576) docs. - History. The line came with the method in #16081; neither the PR nor its review mentions large doc ids, and later edits to the method (#16084, #16256) did not touch it.
The devil's-advocate check171 words
Strongest case for "not a bug" (a cross-model reviewer, OpenAI GPT-5.6, refute lens, which reproduced it with its own tests and rated this argument "moderate"): RoaringDocIdSet is @lucene.internal and the util package is "primarily internal", so direct callers cannot rely on it; and the default leaf predicate never selects a segment this large, so an ordinary deployment cannot reach it.
Why it fails: Lucene's own LRUQueryCache reaches the method through the public LeafCollector.collectRange contract ("max is guaranteed to be greater than min") and a public expert constructor that accepts any leaf predicate; the reviewer showed that with its own test of the default cacheImpl. @lucene.internal limits API stability, not correctness. Unlikely is not intended: a custom predicate and a large cache are documented expert settings, and the default predicate rejects these segments only through another overflow (LFV-081). The reviewer's verdict: real, high confidence. The failure is loud, but the input is not absurd: the sizes are within MAX_DOCS, and the same docs work one at a time.
Recommended A. MathUtil.unsignedMin for the block end
Compute the block end with MathUtil.unsignedMin(max, (block + 1) << 16): one line, the idiom Lucene's scorers already use for window ends. Validated: the test fails before and passes after, with assertions on and off, and 80 tests of the roaring, query-cache and doc-id-set suites pass.
// RoaringDocIdSet.Builder.add(int, int)
-        final int blockEnd = Math.min(max, (block + 1) << 16);
+        final int blockEnd = MathUtil.unsignedMin(max, (block + 1) << 16);
All options and trade-offs3 options · 461 words
Two options were applied in a scratch worktree of main 645d4fe14a20 and run with gradle; a third is correct by reasoning but was not run. All change only line :164.
max is a non-negative int, so read as unsigned it is below 2^31. For block 32,767 the wrapped value Integer.MIN_VALUE reads as 2^31 unsigned, and unsignedMin returns max; for every other block both values are non-negative and unsignedMin equals Math.min. MathUtil is in the same package, so no import is needed.
// RoaringDocIdSet.Builder.add(int, int)
-        final int blockEnd = Math.min(max, (block + 1) << 16);
+        final int blockEnd = MathUtil.unsignedMin(max, (block + 1) << 16);
Trade-offs
- One line, no extra work on the hot path, and the idiom
DenseConjunctionBulkScorer,MaxScoreBulkScorerand others already use for window ends. unsignedMintakes a moment to read. The assertion at:199keeps its wrapped second operand but stays correct, because its first operand is then true for the last block.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seed DEADBEEF: the minimal test fails before the change (assertions on:AssertionErrorat:200; off:NegativeArraySizeException: -2) and passes after it, with assertions on and off. - With the change, seed DEADBEEF: the minimal test,
TestRoaringDocIdSet,TestLRUQueryCache,TestDocIdSetBuilderandTestRangeDocIdStream: 80 tests, 3 skipped, 0 failures. - In the study verifier's own JUnit runs (main
7cecf79523, the sameRoaringDocIdSet.javablob): its 16 tests, including the end-to-endIndexSearcher.counttest and the 4,512-case sweep, pass with this line patched. - Standalone on
645d4fe14a20: the cross-model reviewer's own tests pass, andTestRoaringDocIdSetpasses (23 tests). - Not run: the whole
:lucene:core:testorcheck.
final int blockEnd = (int) Math.min(max, ((long) block + 1) << 16);
-        final int blockEnd = Math.min(max, (block + 1) << 16);
+        final int blockEnd = (int) Math.min(max, ((long) block + 1) << 16);
Trade-offs
Reads as plain arithmetic; the same results as A; one widening and one narrowing cast per block.
What the checks validated
Gradle, scratch worktree of 645d4fe14a20, seed DEADBEEF: the minimal test and TestRoaringDocIdSet, 24 tests, 0 failures, with assertions on; the minimal test passes with assertions off.
final int blockEnd = doc + Math.min(max - doc, (1 << 16) - (doc & 0xFFFF)); cannot overflow: the step is at most 65,536 and the sum is at most max.
Trade-offs
Correct by the same reasoning, but harder to read than A or C.
What the checks validated
Not run (only the fact check's plain-arithmetic probe: the same block ends as A and C on 5 cases).
Downstream servers that keep Lucene's default leaf predicate never cache such segments; one that lets operators cache every segment and holds a near-2^31-doc, index-sorted segment, with a large enough cache and a range filter that reaches the last block, would see failed searches, not wrong results.
Formal. A CodeQL inventory of int shifts and window additions, triaged with git blame, listed this line; a Z3 bit-vector query with Lucene's documented limits as preconditions found the smallest failing doc, 2,147,418,112, in 0.02 s and proved the line exact below it. An independent verifier reproduced it, end to end through IndexSearcher.
The method in full151 words
- Sweep. The study's overflow-at-scale experiment (main
7cecf79523, 2026-10-22) used CodeQL to list every non-constantintmultiplication, left shift and "x + C" window or block addition in the target packages (602 + 63 rows), then triaged them with git blame;RoaringDocIdSet.java:164was one of them. - Solver. The expression was transcribed into Z3 bit-vector logic with Java wraparound and the documented limits (
MAX_DOCS) as preconditions: obligation A1 returned a counterexample (doc 2,147,418,112, max 2,147,470,450, maxDoc 2,147,470,604) in 0.021 s, and A1s proved the expression exact whenever doc < 2^31 - 2^16. JBMC on the real bytecode ran out of memory on this harness. - Verification. An independent study verifier wrote its own 16 tests (Builder,
LRUQueryCache.cacheImpl, end-to-endIndexSearcher.count, and a 4,512-case sweep), reproduced it, found that it only throws, and found the default leaf-predicate overflow (LFV-081) on the way; the hunt then reduced it to the one-test repro.
No prior report found (2026-10-22 and 2026-11-01): GitHub issues and PRs incl. the JIRA archive, mailing lists, downstream projects, the web, and the changed files of all 409 open PRs. Closest: #16256, a different bug (the 4,096-doc hand-off) in the same method.
Searches4 searches
Closest, none this bug: #16256 (the sparse/dense hand-off at exactly 4,096 docs in the same method, fixed); #16081 (introduced the code; its review never mentions overflow or the last block); #16250 / #16252 (an NPE in Iterator#intoBitSet, same cache path); #16084 (edited the method, not the line); #16546 / #16547 (RangeBulkScorer sending an empty range); #16893 (narrows the index-sort shortcut on segments with blocks; does not cover this route); open #16952 (changes the upper bound cacheIntoRoaringDocIdSet passes, not Builder.add); open draft #16847 (long global doc ids; per-segment int ids stay). Gaps: GitHub search returns at most 50 results per query, and one manual query did not complete.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, incl. migrated JIRA) | 2026-10-22 and 2026-11-01 | the study's keyword searches; 26 scripted queries plus 4 extra; 14 manual searches (for example 2147418112, unsignedMin RoaringDocIdSet); 3 commit-message queries | no report; 136 distinct hits of the scripted queries, 0 with high overlap |
| Open PRs | 2026-11-01 | the changed files of all 409 open apache/lucene PRs | none touches RoaringDocIdSet.java; the 3 that touch LRUQueryCache.java were read and do not fix it |
| Mailing lists (dev@, java-user@, issues@, commits@) and the JIRA archive | 2026-11-01 | 20 scripted and 20 manual list queries; 4 scripted and 4 manual JIRA queries | no report; the 18 RoaringDocIdSet JIRA items date from 2013 to 2021, before add(int, int) existed |
| Downstream projects and the web | 2026-11-01 | 3 downstream and 7 web queries | nothing relevant |
Introduced by #16081 (33d6115c384, 2026-05-18), which added add(min, max); first released in 10.5.0 (tagged 2026-06-25). Fails on 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main; 10.4.0 has no such method, and a public-API cache probe passes there. Not fixed upstream.
Versions tested4 rows
- Introduced:
33d6115c384"Implement LeafCollector#collectRange in the collectors used in LRUCache (#16081)" (iverase, approved by romseygeek, merged 2026-05-18), backported the same day as8c7f58534e8with the sameRoaringDocIdSet.javapatch. It addedBuilder.add(int, int)with the overflowing line and thecollectRangeoverride in the cache's roaring collector. In a full-history clone,git log --all -S '(block + 1) << 16'finds only these two commits (a shallow clone that also has the retiredbranch_10xadds its shallow root and the commit that deleted that branch's tree);git blameputs:164,:199and:208-211on33d6115c384. - Later: #16084 (range encoding), #16256 (the 4,096-doc hand-off) and #16252 (an iterator NPE) changed the file but not the line.
- Before 10.5.0: the builder had only
add(int)andadd(DocIdSetIterator), and the cache's collector inherited the defaultcollectRange, which reaches the builder one doc at a time. - Upstream:
RoaringDocIdSet.javaon upstream mainf815e679bf6c(2026-11-01) is the same blob as at645d4fe14a20;branch_10_6and the 10.5.0 to 10.6.0 tags still have the line.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | fails loudly | minimal test throws with assertions on and off (gradle and standalone); passes with fix A or C |
| 10.6.0 | fails loudly | throws with assertions on and off |
| 10.5.0, 10.5.1, 10.5.2 | fails loudly | throw with assertions on and off |
| 10.4.0, 10.3.2 | not affected | no add(int, int); a public-API cache probe that reports one range counts 10 docs and caches |
The study verifier, re-runs on three main commits, the minimal repro, current-main verification, a cross-model reviewer (OpenAI GPT-5.6, refute lens: real, high confidence) and this doc's gradle runs agree: it throws on the last block, never returns wrong data, and the one-line fix works.
Checks and verdicts151 words
The cross-model reviewer ran on main ea57360912ed; its tests were re-run on 645d4fe14a20 with the same results.
| Check | Verdict | What it found |
|---|---|---|
| study verifier | real | Own 16 tests, one of them a 4,512-case sweep; throw-only; end-to-end IndexSearcher.count; the patched class passes all 16. |
| main re-runs | still reproduces | b83101cdd2 (2026-10-23), a9779ef3c193 (2026-10-26) and 645d4fe14a20: 16 run, the same 6 bug tests fail. |
| minimal repro | verified | Fails on main with assertions on and off; the fix passes. |
| current-main verification | real | Main, 10.5.2 and 10.6.0 executed with assertions on and off. |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6: own Builder and cacheImpl tests with controls; root cause and fix agreed; strongest objection: internal API and default-config reach. |
| doc gradle runs | fails before, passes with A and C | Scratch worktree of 645d4fe14a20; 80 tests of five related suites pass with A. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 455 KB
Finding record, Lucene and upstream sources, repro files and diagram notes470 words
- Registry title
- RoaringDocIdSet.Builder.add(min, max) throws on the last 2^16-doc block
- Area
- util / bitsets
- Priority
- Low, rank 1188: RoaringDocIdSet.Builder.add(min, max) throws on the last 2^16-doc block, which needs a segment within 65k docs of MAX_DOCS and a non-default cache predicate, and it is loud only.
- Impact class
- crash
- Impact note
- Only segments with more than 2,147,418,112 docs plus the opt-in query cache with a non-default caching predicate; throw-only, never silent; released 10.5.0 to 10.6.0.
- Summary
- You add a doc-ID range that falls in the last 65,536-doc block below 2^31 to a RoaringDocIdSet.Builder. You expect the range to be added. Instead (block+1)<<16 wraps and the call throws; it never returns wrong data.
- Introduced
- #16081 (33d6115c384) (2026-05-18)
- First affected version
- 10.5.0
- Affected versions
- 10.5.0, 10.5.1, 10.5.2 and 10.6.0 [exec, -ea and -da]; main 645d4fe14a2 [exec 2026-10-29: 6 of 16 study tests fail, -ea and -da; 2026-11-01: the minimal test fails, -ea and -da]; 10.3.2 and 10.4.0 not affected (no add(int, int)) [exec]; branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b (10.6.0 RC1) have the same defect line RoaringDocIdSet.java:164 [read 2026-10-29]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed in the earlier formal verification study by independent AI checks and a rerun on Lucene main; also a cross-model review that agreed; not yet triaged by a person.
- Found by
- formal: Z3
- Upstream and prior reports
- none found (study searches 2026-10-22); #16256 is a different bug in the same method
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test through gradle with assertions on and off, before and after fixes A and C, in a scratch worktree (2026-11-01), and standalone (2026-10-29 and 2026-11-01); releases 10.5.0, 10.5.1, 10.5.2 and 10.6.0 with assertions on and off; 10.3.2 and 10.4.0 with a public-API cache probe; the study verifier's end-to-endIndexSearchertest on main and 10.5.0. Upstream mainf815e679bf6c(2026-11-01) has the same file.
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/util/RoaringDocIdSet.java:61-67, :114-130, :161-174, :176-194, :196-220 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:580-592, :656-685 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/document/RangeBulkScorer.java:79; SortedSkipperScorerSupplier.java:99; SortedNumericDocValuesRangeQuery.java:197-199, :237-253 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/FixedBitSet.java:773-795 (at 645d4fe14a20)
- Who is affected
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:137-175, :278-295, :580-592, :792-801 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-84 (at 645d4fe14a20); releases/lucene/10.6.0 IndexSearcher.java:95-100lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:804-808, :812-814, :1060-1082; index/BaseCompositeReader.java:89-106 (at 645d4fe14a20)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/RoaringDocIdSet.java:32, :61-67, :132-142, :200 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/MathUtil.java:196-199; search/DenseConjunctionBulkScorer.java:198, :214; search/MaxScoreBulkScorer.java:216; search/ConstantScoreBulkScorer.java:132; search/TimeLimitingBulkScorer.java:73; search/RangeDocIdStream.java:68; search/DisjunctionMaxBulkScorer.java:90 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/LeafCollector.java:87-106; search/LRUQueryCache.java:137-175 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/util/TestRoaringDocIdSet.java; lucene/test-framework/src/java/org/apache/lucene/tests/util/BaseDocIdSetTestCase.java:67 (at 645d4fe14a20)
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/MathUtil.java:196-199; RoaringDocIdSet.java:199 (at 645d4fe14a20)
- Diagrams
lucene/core/src/java/org/apache/lucene/util/RoaringDocIdSet.java:161-172 (at 645d4fe14a20)
- TestRoaringDocIdSetLastBlock.java:
repro/LFV-066/src/org/apache/lucene/util/TestRoaringDocIdSetLastBlock.java(35 lines)
assets/LFV-066/bug.png(455 KB)