Each shard sees only its own documents, so its BM25 statistics differ from the whole collection's. IndexSearcher#termStats and #fieldStats exist so an application can score a shard with whole-collection statistics instead; their javadoc names exactly this use.
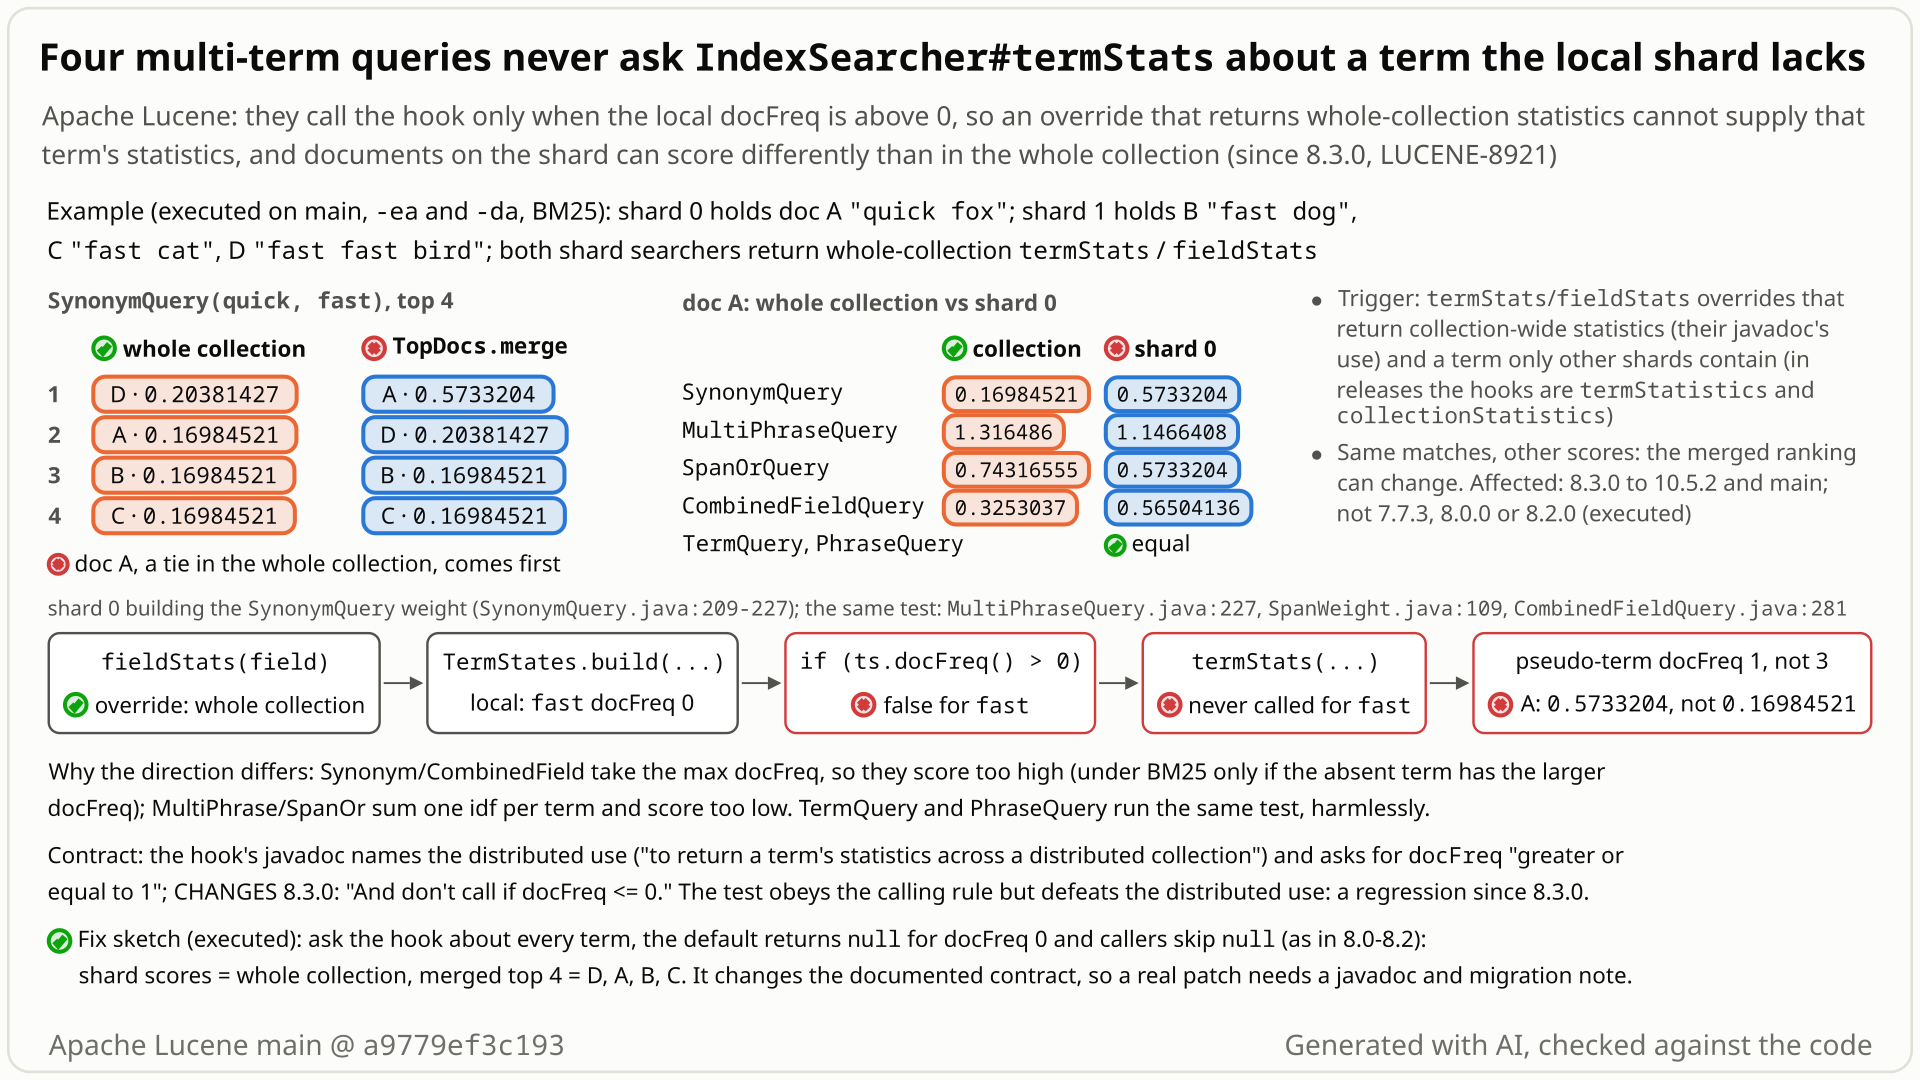
- Split four documents into two shards: shard 0 holds A "quick fox"; shard 1 holds B "fast dog", C "fast cat" and D "fast fast bird". Search shard 0 with an
IndexSearcherwhosetermStatsandfieldStatsoverrides return the sums over both shards. - Run
SynonymQuery(quick, fast). It scores the two words as one term whose docFreq is the larger of the two: max(quick 1, fast 3) = 3. You expect A to score 0.170, as it does in one index that holds all four documents. - You get 0.573, 3.4 times too high. Shard 0 has no "fast", and the query only asks the override about terms whose docFreq on the shard is above 0, so it never learns that "fast" is in 3 documents and uses docFreq 1.
- Merged across the two shards, A comes first (0.573), ahead of D (0.204), which ranks first in the whole collection, and of B and C, which tie with A there (0.170).
- The same skip hits
CombinedFieldQuery(0.565 instead of 0.325),MultiPhraseQuery"(quick|fast) fox" (1.147 instead of 1.316) andSpanOrQuery(0.573 instead of 0.743), silently.TermQueryandBooleanQueryare correct. Up to 8.2 these queries asked the override about every term.
Only applications that override termStats/fieldStats to inject whole-collection statistics (two-phase distributed scoring); a plain IndexSearcher is unaffected. For them ordinary data triggers it: a synonym, phrase alternative or per-field term missing from one shard. Scores, and with them the merged ranking, can drift silently; the set of matching documents does not change.
Mechanism, terms and numbers748 words
IndexSearcher#termStats and #fieldStats "can be overridden for example, to return a term's [field's] statistics across a distributed collection". For a query over a fixed set of terms, an application that searches one shard with such overrides expects each document to get the score the same query gives it in one index holding the whole collection (the javadoc does not promise this for every query), and TermQuery and PhraseQuery deliver that. SynonymQuery, MultiPhraseQuery, CombinedFieldQuery and span queries (through SpanWeight.buildSimWeight, so SpanOrQuery and enclosing span queries that score through it, such as spanNear over spanOr) instead build TermStates on the local reader and call the hook only if (ts.docFreq() > 0). A query term that occurs only on other shards is not offered to the override, so its collection statistics are silently left out of the similarity's input. In the repro, SynonymQuery(quick, fast) on a shard without "fast" scores doc A 0.5733204 instead of 0.16984521, and a merged top-k puts A first although it ties for second in the whole collection. SynonymQuery and CombinedFieldQuery over-score (under BM25 only when the missing term is the more frequent one), MultiPhraseQuery and span-or under-score when a term is missing locally but present elsewhere and a document still matches through another alternative. Matching never changes. The checks came with LUCENE-8921 (8.3.0), an API cleanup that replaced the callers' "the hook returned null" test with "the local docFreq is 0"; in 8.0-8.2 the hook was asked about every term and the shard scores were right (executed).
- Distributed statistics: two-phase scoring of a sharded collection. The application first gathers each query term's docFreq and totalTermFreq and each field's statistics from all shards, then searches every shard with an
IndexSearchersubclass whosetermStats(Term, int docFreq, long totalTermFreq)andfieldStats(String)return the collection-wide values. In-tree, the test mockShardSearchingTestBasedoes this ("Matches docs in the local shard but scores based on aggregated stats"). - Combining queries:
SynonymQueryandCombinedFieldQueryscore their terms as one pseudo-term whose docFreq is the largest docFreq of the terms;MultiPhraseQueryand span queries pass every term's statistics to the similarity, which for BM25 sums their idf.
- The weight builds
TermStatesfor each term on the local reader (SynonymQuery.java:215,MultiPhraseQuery.java:224,CombinedFieldQuery.java:279, span queries when the weight is created). - It calls
searcher.termStats(...)onlyif (ts.docFreq() > 0):SynonymQuery.java:217,MultiPhraseQuery.java:227,CombinedFieldQuery.java:281,queries/spans/SpanWeight.java:109. - A term that occurs only on other shards has local docFreq 0, so the override is never asked about it, and the ordinary weight path has no other per-term statistics callback (overriding
IndexSearcher#createWeight, or expert constructors with caller-builtTermStates, are heavier workarounds). Its collection statistics are missing from the max (SynonymQuery,CombinedFieldQuery) or from the idf sum (MultiPhraseQuery, span-or). TermQuery(TermQuery.java:65) andPhraseQuery(:479) have the same check but cannot go wrong: a term missing from the shard cannot make a local document match.
Shard 0: A "quick fox" (title "red"). Shard 1: B "fast dog", C "fast cat", D "fast fast bird" (titles "fox", "fox", "bird"). Whole collection: N = 4, docFreq quick 1, fast 3, body:fox 1, title:fox 2.
| query | doc A on shard 0 | doc A in the whole collection | why |
|---|---|---|---|
SynonymQuery(quick, fast) | 0.5733204 | 0.16984521 | docFreq max(1) = 1 instead of max(1, 3) = 3: idf 1.204 instead of 0.357 |
| merged top-4 of both shards | A 0.573, D 0.204, B 0.170, C 0.170 | D 0.204, then A, B, C tied at 0.170 | |
CombinedFieldQuery(fox; body, title) | 0.56504136 | 0.3253037 | title:fox (docFreq 2) only on shard 1 |
MultiPhraseQuery "(quick fast) fox" | 1.1466408 | 1.316486 | the idf of fast is missing from the sum |
spanOr(quick, fast) | 0.5733204 | 0.74316555 | the same |
spanNear([spanOr(quick, fast), fox]) | 1.1466408 | 1.316486 | the same, inside another span query |
controls: TermQuery quick, BooleanQuery quick OR fast, SynonymQuery(quick, speedy), spanNear([quick, fox]) | equal | equal |
Under BM25 SynonymQuery and CombinedFieldQuery change only when the missing term has the larger collection docFreq (BM25 ignores totalTermFreq; with equal docFreqs the independent reproducer saw equal scores). MultiPhraseQuery and span-or change when a term is missing locally but present elsewhere and a local document still matches through another alternative. Shard 1, which lacks quick, is wrong for span-or too: B and C score 0.16984521 instead of 0.74316555, D 0.20381427 instead of 0.89179873. For SynonymQuery and CombinedFieldQuery shard 1 is right, because the term it lacks has the smaller collection docFreq.
Exposure and likelihood300 words
- Who. Applications that subclass
IndexSearcherand override the@lucene.experimentalhookstermStats/fieldStatswith collection-wide values. In-tree the only override of both hooks with collection-wide values is the test mockShardSearchingTestBase; the core and sandboxTestCombinedFieldQueryalso subclassIndexSearcherbut override onlyfieldStats, with synthetic other-shard values. Search servers' distributed-statistics (global IDF) modes answer through this hook, and the 2019 change moved Solr's distributed-IDF overrides to the new signature; that downstream reach comes from reading code, nothing downstream was run. - Opt-in. Without an override the default hook returns local statistics, and a locally missing term contributes nothing either way, so single-index search is correct.
- Trigger. Ordinary data once the override exists: any query-time synonym, phrase alternative, span-or clause or
CombinedFieldQueryfield term that is missing from the shard being searched but present on another. No scale is needed; small, routed or time-partitioned shards and rare terms make it more frequent. - Effect. Wrong scores on every shard that lacks one of the terms, and with them possibly a wrong merged ranking: in the repro a document that ties for second in the whole collection is ranked first (the merged order changes for
SynonymQueryand span-or, not forMultiPhraseQueryorCombinedFieldQuery). Matching, filters and deleted documents are unaffected, though which matches make a merged top-k can change. The runs saw finite scores and no error with assertions on or off (BM25 in the repro, 16 core similarities in the harness). - How often in random data. The finder's harness (random 8-40 document collections split into two shards, 20 query families x 16 similarities, 600 cases) recorded 10,739 mismatches in 175,837 checks of the five affected families, and none for
TermQuery,PhraseQueryor the other span queries. - Easy to miss. The visible symptom is ranking drift between shards; nothing fails.
The test shows that SynonymQuery never asks an IndexSearcher#termStats override about a synonym that is absent from the local shard, so a shard searcher that supplies whole-collection statistics scores SynonymQuery(quick, fast) differently from the collection (shard 0 = {quick}, shard 1 = {fast, fast}).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.MultiReader;
import org.apache.lucene.index.Term;
import org.apache.lucene.index.TermStates;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSynonymQueryDistributedStats extends LuceneTestCase {

  public void testSynonymOnlyOnOtherShard() throws IOException {
    try (Directory d0 = new ByteBuffersDirectory();
        Directory d1 = new ByteBuffersDirectory()) {
      index(d0, "quick");
      index(d1, "fast", "fast");
      try (DirectoryReader r0 = DirectoryReader.open(d0);
          DirectoryReader r1 = DirectoryReader.open(d1)) {
        IndexSearcher collection = new IndexSearcher(new MultiReader(r0, r1));
        IndexSearcher shard0 =
            new IndexSearcher(r0) {
              @Override
              public TermStats termStats(Term term, int docFreq, long totalTermFreq)
                  throws IOException {
                TermStates ts = TermStates.build(collection, term, true);
                return new TermStats(term.bytes(), ts.docFreq(), ts.totalTermFreq());
              }

              @Override
              public FieldStats fieldStats(String field) throws IOException {
                return collection.fieldStats(field);
              }
            };
        Query q =
            new SynonymQuery.Builder("f")
                .addTerm(new Term("f", "quick"))
                .addTerm(new Term("f", "fast"))
                .build();
        // expected: doc 0 scores as in the collection (all 3 docs tie there); actual: higher
        assertEquals(
            "score of doc 0 on shard 0 vs. in the whole collection",
            collection.search(q, 1).scoreDocs[0].score,
            shard0.search(q, 1).scoreDocs[0].score,
            0f);
      }
    }
  }

  private static void index(Directory dir, String... values) throws IOException {
    try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      for (String value : values) {
        Document doc = new Document();
        doc.add(new TextField("f", value, Field.Store.NO));
        w.addDocument(doc);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-582/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestSynonymQueryDistributedStats
- Expected vs actual
- Expected doc 0's score on shard 0 to equal its score in the whole collection,
0.21363801; actual0.44583148(the statistics offastare left out), with-eaand-da.
More files, environment, full output45 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: score of doc 0 on shard 0 vs. in the whole collection expected:<0.21363801> but was:<0.44583148>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
org.apache.lucene.search.TestSynonymQueryDistributedStats.testSynonymOnlyOnOtherShard(TestSynonymQueryDistributedStats.java:63)- The hooks' javadoc names this use: they "can be overridden ... to return a term's statistics across a distributed collection".
- Up to 8.2.0 it worked (executed). The 2019 cleanup replaced "the hook returned null" with "local docFreq is 0", reviewed as equivalent for the default hook.
- LUCENE-6789, which created
SynonymQuery, faultedBlendedTermQuerybecause it "doesn't consult indexsearcher for stats".
The full argument417 words
- The hooks' purpose (
IndexSearcher.java:1122-1123,:1139-1140): "This can be overridden for example, to return a term's statistics across a distributed collection" (field's, forfieldStats). - The queries' own promise:
SynonymQuery"tries to score the terms as if you had indexed them as one term" (SynonymQuery.java:47-49);CombinedFieldQueryscores terms "as if they had been indexed in a single field whose values would be the union of the values of the provided fields" (CombinedFieldQuery.java:47-49). - Upstream tests:
TestShardSearchingasserts shard results equal whole-collection results withShardSearchingTestBase's override, but only forTermQueryandPrefixQuery; its TODO lists "other queries besides PrefixQuery & TermQuery" (TestShardSearching.java:35-41).TestCombinedFieldQuery.testOverrideFieldStats(:488-563) checksCombinedFieldQueryunder an overriddenfieldStats(nottermStats).TermQueryis the real scoring precedent:PrefixQueryrewrites to a constant score by default (PrefixQuery.java:27-34), so its scores do not depend on term statistics. - 8.0-8.2 (LUCENE-8020,
e0bde579815): callers asked the hook about every term and skipped anullresult, so the overridable hook decided whether a term exists. On 8.0.0 and 8.2.0 the shard scores equal the whole-collection scores and the call log shows the hook asked aboutbody:fast(executed). - LUCENE-8921 (8.3.0; issue #9964, PR apache/lucene-solr#797, by @bruno-roustant, committed by @dsmiley): an API cleanup, because the hook "requires a TermStates param although it only cares about the docFreq and totalTermFreq". In review @romseygeek wrote "I think all callers are already doing this work, it's just that they're checking if the returned
TermStatisticsobject is null after the call", and @bruno-roustant: "Previously all callers checked if the returned TermStatistics was null before doing something. So I replaced the null check by a check if docFreq is 0. I tried to remove the 0 check and ran TestShardSearching ... It failed with the exception because docFreq was 0." Compatibility was discussed for the method signature only (@jpountz: it "might not only be used internally but also by Lucene users"); nobody discussed overrides that answer for locally absent terms. - The mock changed with it: the same commit turned
ShardSearchingTestBase's "local null ->continue; // term not found, sum the other nodes" intoassert distributedDocFreq > 0(ShardSearchingTestBase.java:289today), so no in-tree test could notice. - Earlier design discussion: when LUCENE-6789 (#7847) created
SynonymQuery, its author wrote thatBlendedTermQueryhas "problems like not working with distributed scoring (doesn't consult indexsearcher for stats)". LUCENE-10582 (#11618),CombinedFieldQuerymishandling overridden statistics, was fixed under Bug Fixes in 9.3 (lucene/CHANGES.txt:4119).
The devil's-advocate check344 words
Strongest case for "intended" (an OpenAI GPT-5.6 reviewer, reading only, and the GPT-5.6 fact check of this doc both rated it strong; a devil's-advocate verifier built the same case): the hook is @lucene.experimental; its javadoc says docFreq "must be greater or equal to 1" and the result is "never null" (IndexSearcher.java:1125-1127); the 8.3.0 CHANGES entry says "And don't call if docFreq <= 0" (lucene/CHANGES.txt:6164-6166), so the rule was written down on purpose; in the PR #797 review the check was moved before the call deliberately (@romseygeek: "maybe we should move this check up a level and make this throw an Exception if somebody passes in an empty docFreq?"); LUCENE-8020 deliberately stopped passing non-existent terms to similarities (:6710-6713); a committer wrote in PR #910 that "Lucene doesn't really have a native concept of 'distributed collection statistics'"; Lucene does not promise exact cross-shard equality for every query (per-shard prefix, fuzzy and wildcard expansion already differ); heavier workarounds exist (overriding createWeight, expert constructors with caller-built TermStates); and any fix changes a documented calling convention that existing overrides may rely on. So this may be a documented limitation of an experimental extension point.
Why we still lean towards a bug, and where that is weaker: those texts say how the hook is called, not that multi-term queries lose the distributed statistics the same javadoc offers. Nothing documents, tests or discusses that loss; 8.0-8.2 supported it (the hook's own null result decided absence, so an override could answer for a locally absent term); the reviewers treated the new check as equivalent to the old null check for the existing callers and the default implementation, and did not consider overrides that answer for locally absent terms; and upstream fixed a sibling overridden-statistics problem in CombinedFieldQuery as a bug. This is strongest for SynonymQuery and CombinedFieldQuery, whose design history considered distributed statistics; for MultiPhraseQuery and spans (whose idf summing is itself disputed), "an enhancement that restores cross-shard parity" is arguably the more defensible framing. Upstream may still label it an enhancement.
Recommended Ask the hook about every term; null only for a term that is nowhere (recommended for main / 11.0)
Recommended for main: the four queries ask termStats about every term and skip null. The default returns null only for docFreq 0; the javadoc forbids null for docFreq 1 or more. Validated: new tests pass; 2,338 core search, 515 queries and 114 sandbox search tests, no failures. It changes an experimental contract: needs a migration note.
All options and trade-offs3 options · 810 words
Option A was run through gradle in a scratch worktree at a9779ef3c193 (commands in the fix folder's commands.txt); options B and C are untested design alternatives. Either way, the same check in sandbox TermAutomatonQuery, PhraseWildcardQuery and the sandbox CombinedFieldQuery is a follow-up, and a TestShardSearching case with a SynonymQuery would make the in-tree mock cover the bug.
Ask the hook about every term; null only for a term that is nowhere (recommended for main / 11.0) (validated by the checks)
The change is +36/-16 lines in 6 files. SynonymQuery, MultiPhraseQuery, CombinedFieldQuery and SpanWeight.buildSimWeight call searcher.termStats(term, ts.docFreq(), ts.totalTermFreq()) for every term and skip a null result. The default termStats returns null when docFreq == 0; its javadoc now says that multi-term queries also call it with docFreq 0, that the result is never null when docFreq is at least 1 (callers that only pass a positive docFreq, such as PhraseQuery and BM25Similarity, do not check for null), and that for docFreq 0 null means the term does not occur in the collection. ShardSearchingTestBase skips a null node result and returns null when no node has the term, instead of assert distributedDocFreq > 0. This restores the 8.0-8.2 behaviour (the hook decides absence) without bringing back TermStates in the signature.
// SynonymQuery (CombinedFieldQuery, MultiPhraseQuery and SpanWeight alike)
TermStats termStats = searcher.termStats(term, ts.docFreq(), ts.totalTermFreq());
if (termStats != null) {
  docFreq = Math.max(termStats.docFreq(), docFreq);
  totalTermFreq += termStats.totalTermFreq();
}

// IndexSearcher#termStats, the default; its javadoc:
//   @return A {@link TermStats}, never null if {@code docFreq} is at least 1. If {@code docFreq} is
//       0, {@code null} means that the term does not occur in the collection; the default
//       implementation returns {@code null} if, and only if, {@code docFreq} is 0.
if (docFreq == 0) {
  return null;
}
return new TermStats(term.bytes(), docFreq, totalTermFreq);
Trade-offs
- Contract change. The hook is documented today as "docFreq ... must be greater or equal to 1" and "never null". An override written for that contract which builds
new TermStats(term.bytes(), df, ttf)from a sum that can be 0 throwsIllegalArgumentException: docFreq must be positivefor a query term that is on no shard, which any user can type (executed with the metamorphic harness's own override under the finder's sketch: in the five affected families and also in plainSpanTermQuery,SpanNearQuery,SpanFirstQueryandSpanNotQuery, because every scoring span weight goes throughSpanWeight.buildSimWeight). So it needs a CHANGES/MIGRATE note ("return null when the term exists nowhere") and fits main (11.0) better than a 10.x backport. - Cost. One extra hook call per locally absent term at weight creation; the default is a branch.
- Pending work. Open draft PR #16847 ("Support more than 2^31 documents per index (long global doc ids)", 438 changed files) also widens
termStats' docFreq from int to long; whichever lands second needs a small rebase.
What the checks validated
Scratch worktree at a9779ef3c193, gradle, seed DEADBEEF: the new tests 7/7 (core) and 3/3 (queries) with assertions on and off; :lucene:core:test --tests 'org.apache.lucene.search.*' 2,338 tests in 215 classes (including the 7 new ones, TestShardSearching, TestSynonymQuery, TestMultiPhraseQuery, TestCombinedFieldQuery) and :lucene:queries:test 515 tests (including the 3 new ones), assertions on and off, 0 failures; :lucene:sandbox:test --tests 'org.apache.lucene.sandbox.search.*' 114 tests, assertions off (and on, in the fact check), 0 failures. Skipped: core 49 (assertions on) / 51 (off), queries 5 / 6, sandbox 5. Tidy, ecjLint, forbiddenApis and core renderJavadoc pass. The sandbox's own copies of the check are not changed by the patch, and no targeted sandbox repro was run. After the fact checks the @return javadoc was tightened (the first wording allowed null for a positive docFreq); the code is byte-identical, and the tightened patch passed tidy, the new tests (assertions on and off), TestShardSearching, TestSynonymQuery, TestMultiPhraseQuery and TestCombinedFieldQuery (41 tests, 2 skipped), and core ecjLint, forbiddenApis, renderJavadoc and the Google Java Format check. Earlier the finder's 5-file sketch of the same change (IndexSearcher and the four callers) took the harness's mismatches in the five affected families from 10,739 to 0; mismatches in unrelated families remained, as on stock main.
Keep termStats(Term, int, long) exactly as documented and add, for example, public TermStats absentTermStats(Term term) returning null by default, which the four callers call when the local docFreq is 0.
Trade-offs
No existing override can break, so it can go into 10.x. But distributed implementations must opt in by overriding a second method, the two hooks must agree, and until they do the bug stays.
State on termStats that multi-term queries skip terms missing from the searcher's reader.
Trade-offs
No code risk, but the distributed use the javadoc offers stays broken for exactly the queries recommended for distributed scoring (synonyms, combined fields).
Search servers that offer distributed (global-IDF) scoring through this hook could show the same cross-shard ranking drift (by code reading; nothing downstream was run).
Randomized metamorphic testing: random small collections were split into two shards, and a shard searcher with whole-collection statistics injected through termStats/fieldStats had to give every document its whole-collection score, for 20 query families and 16 similarities. Every mismatch was in five multi-term families and involved a term missing from the shard; reading the code found the check.
The method in full234 words
Method: randomized metamorphic testing (a hunt unit, 2026-10-26, main a9779ef3c193). No model checker, SMT solver or prover was involved.
- The relation: statistics injection == whole collection. The harness builds a random collection of 8-40 documents with two text fields, deletions and one or more segments, splits it into two shards, and searches one shard with an
IndexSearcherwhosetermStats/fieldStatsreturn the whole collection's statistics (two override styles: replace with the collection value, and the mock's local-plus-other-shards sum). Each live shard document must get exactly the score and explanation value it gets in the whole collection. - 600 random cases (3 seeds x 200), 20 query families x 16 core similarities: 10,739 of 175,837 checks in
MultiPhraseQuery,SynonymQuery,CombinedFieldQuery,SpanOrQueryand span-near over span-or mismatched, every one with a query term whose local docFreq is 0 and collection docFreq above 0; 0 mismatches forTermQuery,PhraseQueryand the other span queries. All mismatches were score values; no document matched on one side only. - The finder (an AI tool) then read the
docFreq() > 0checks in the four weights, traced them to LUCENE-8921 with the git history, wrote a public-API JUnit and bracketed the releases; a sketch of the fix took the five affected families to 0 mismatches. - Then a cross-model review, independent verifiers, an adjudication, a release sweep, a prior-report search and a security screen (see Independent checks).
No prior report: 269 recorded queries and reads (256 completed) over Lucene issues, PRs, commits, JIRA, the mailing lists, downstream trackers and the web, plus the changed files of all 406 open PRs (2026-10-26). The closest item is the 2019 change that introduced the check; its review did not discuss overrides that answer for locally absent terms.
Searches4 searches
None of the searched items reports that these queries skip IndexSearcher#termStats for locally absent terms, or that a distributed-statistics override therefore cannot supply their statistics. The nearest items are the introducing change (LUCENE-8921), the earlier null-for-absent contract (LUCENE-8020), and other defects in the same queries or the same feature. Word-based searches show what was found, not that no report exists anywhere; some searches were rate-limited.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/lucene-solr) | 2026-10-26 | a scripted prior-report search in three runs (code identifiers, symptoms/distributed statistics, history keys; 157 queries with JIRA, list and web sources, 12 of the web queries left pending) and 13 direct reads of the plausible items; the finder's (51 queries) and a verifier's (19) earlier runs were read as well, outside the 269 | no report; #9964 / lucene-solr#797 (LUCENE-8921, the introducing change), #9068 (LUCENE-8020), #9986 (LUCENE-8943, idf combination), #13796 + open PR #15819 (SpanOrQuery adds the idf of non-matching clauses; would hide only the standalone SpanOrQuery symptom), #11618 / PR #910 (LUCENE-10582, a different overridden-statistics bug, fixed 9.3), #7847 (LUCENE-6789) |
| Open PRs | 2026-10-26 | the changed files of all 406 open apache/lucene PRs; diffs of the 11 that touch the gated files, IndexSearcher, TermStates or ShardSearchingTestBase | none changes the docFreq > 0 check; #16847 (draft, termStats int to long) would need a rebase |
| JIRA archive and mailing lists | 2026-10-26 | 26 JIRA searches (LUCENE, SOLR), 18 Solr list searches, the dev@, java-user@, issues@ and commits@ lists | no report; SOLR-7756, SOLR-7818, SOLR-9122 concern terms missing on a shard in Solr's stats-cache layer, before 8.3 |
| Downstream and web | 2026-10-26 | 40 GitHub searches on Elasticsearch, OpenSearch, Solr and Lucene; 15 web queries (one throttled) | no report; elastic/elasticsearch#50577 (similar cross-shard symptom, different mechanism), #42957 and #10346 (recommend SynonymQuery / CombinedFieldQuery for distributed scoring) |
Introduced by LUCENE-8921 (2019-09-17) and first released in 8.3.0. Executed: 7.7.3, 8.0.0 and 8.2.0 score correctly; 8.3.0, 8.11.4, 9.0.0, 9.12.3, 10.2.0, 10.5.2 and main do not. Not fixed upstream.
Versions tested8 rows
Introduced by LUCENE-8921 "IndexSearcher.termStatistics API change" (issue #9964, PR apache/lucene-solr#797; @bruno-roustant, committed by @dsmiley, 2019-09-17): a80534a589d on branch_8x (an ancestor of the 8.3.0 tag, not of 8.2.0) and fd0c8b9e810 on master (first in 9.0.0; git blame -w -M -C -C credits it directly with the SynonymQuery, MultiPhraseQuery and SpanWeight checks, and the core CombinedFieldQuery check blames to #14236, the 2025 move of the sandbox class into core, whose sandbox check blames to it under the old name BM25FQuery). It replaced the callers' "skip if the hook returned null" (LUCENE-8020, 8.0.0) with "skip if the local docFreq is 0", and kept the old 8.x method only as deprecated and final, so from 8.3.0 no override is asked about locally absent terms on these queries' ordinary paths. The hook itself dates from LUCENE-3555 (b19a207c866, 4.0.0). A regression.
The core CombinedFieldQuery exists from 10.2.0; before that the sandbox BM25FQuery/CombinedFieldQuery had the same check from 8.3.0. For that sandbox query the 8.3.0 regression is shown by its call log only (it already skips title:fox on 8.3.0): before 9.3.0 overridden statistics made it throw (LUCENE-10582, a different, fixed bug), so its scores can be compared only from 9.3.0. Releases between the executed ones are inferred by commit containment; 8.1.x and releases before 7.7.3 were not run. 8.11.4 ran from its published release jars; the local history clones have no late 8.x tags. 8.3.0 was released on 2019-11-02 (its tag is dated 2019-10-31). Not fixed upstream: no commit since fd0c8b9e810 has changed the four checks. In a clone fetched on 2026-10-26, origin/main (a95c754ee003) is two commits past a9779ef3c193 and touches none of the four files, and origin/branch_10x (1309534296e3, 2026-10-24) still has all four checks.
| Version or commit | Verdict | Result |
|---|---|---|
| 7.7.3 | not affected | shard score == whole-collection score in all 4 families; the hook is asked about body:fast (absolute BM25 values 2.2x larger: the k1+1 factor removed in 8.0) |
| 8.0.0 | not affected | equal (0.16984521 / 0.16984521); hook asked about body:fast |
| 8.2.0 | last unaffected | equal; hook asked about body:fast |
| 8.3.0 | first affected | 4 of 4 families differ (SynonymQuery 0.5733204 / 0.16984521); the hook is never asked about body:fast |
| 8.11.4, 9.0.0 | affected | 4 of 4 families differ |
| 9.12.3, 10.2.0, 10.5.2 | affected | 5 of 5 families differ (with CombinedFieldQuery) |
| main a9779ef3c193 | affected | this doc's tests fail 4 of 7 (core) and 2 of 3 (spans) through gradle, assertions on and off; earlier JUnits fail with -ea and -da |
| main with fix option A | not affected | new tests 10 of 10; core search 2,338, queries 515 and sandbox search 114 tests, 0 failures (some skipped); re-checked after its javadoc was tightened |
An independent reproducer, a devil's advocate, an adjudication and an audit said real and re-ran it with new seeds and data. OpenAI GPT-5.6 reviews, reading only, agreed on the root cause but argued "documented limitation". This doc's tests and fix ran through gradle.
Checks and verdicts439 words
All checks ran on main a9779ef3c193 unless noted. The GPT-5.6 reviews could read code but not run it, so their "not real" verdicts rest on documentation reading; both agreed with the mechanism.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | Harness: 10,739 mismatches, all with a locally absent term, 0 in those families after the fix sketch. JUnit fails 5 of 7 with -ea and -da (2 controls pass); release checks fail on 8.3.0-10.5.2, pass on 8.0.0 and 8.2.0. |
| Cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real, low (procedural: could not run code); root cause agreed | Its main point, the documented docFreq >= 1 calling convention, is carried as the framing caveat. A separate run re-ran the repro: it fails. |
| Independent reproducer | real | Own JUnit (different data, a call log of every hook call) fails 5 of 8 on main (-ea, -da), 10.5.2 and 9.12.3, controls pass; 8.2.0 equal vs 8.3.0 different; found the BM25 max-docFreq condition. |
| Intended-behaviour review (OpenAI GPT-5.6, reading only) | not real, medium (documented limitation); root cause agreed | Argued the experimental hook's documented convention. The verifier's own runs reproduce on main and 10.5.2, pass on 8.2.0 and with the fix. |
| Devil's advocate | real | Built the strongest intended reading and found that the texts document the calling convention, not the loss; re-ran the finder's JUnit (5 of 7 fail, -ea and -da). |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's JUnit at seed 5EED1176: 5 of 8 fail with -ea and -da; 8 of 8 pass with the fix sketch. Medium because of framing, not facts. |
| Follow-up, registry re-runs and audit | reproduced | Release bracket over 10 versions; re-runs on main with seeds DEADBEEF and 0DD5EED5 and the fix check; the audit's re-run at seed A0D17004 (5 of 7 fail) kept the row. |
| This doc's tests and fix validation | reproduced; fix validated | Stock: 4 of 7 and 2 of 3 fail through gradle, assertions on and off. Option A: 10 of 10 pass; 2,338 core search, 515 queries and 114 sandbox search tests, 0 failures (some skipped); static checks pass. Re-checked after its javadoc was tightened. |
| Independent fact and diagram checks | errors fixed | A fact check re-ran the repro and fix A through gradle (assertions on and off) and re-read every citation; a cross-model fact check (OpenAI GPT-5.6) re-read the code and history; a diagram check compared every frame with the code and the probe. Their errors (one blame line, the sketch's file count, a too-loose null rule in fix A's javadoc, several absolute wordings, the prior-art tally) are fixed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 598 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,663 words
- Registry title
- SynonymQuery, MultiPhraseQuery, CombinedFieldQuery and SpanOrQuery ask IndexSearcher#termStats only about terms that occur in the local reader, so an override that supplies distributed (whole-collection) statistics is never asked about a query term that occurs only on other shards, and documents on those shards score differently than in the whole collection (since 8.3.0, LUCENE-8921)
- Area
- search / IndexSearcher#termStats distributed-statistics hook (SynonymQuery, MultiPhraseQuery, CombinedFieldQuery, SpanWeight)
- Priority
- Medium, rank 59: Released since 8.3, distributed-statistics scoring silently mis-ranks SynonymQuery, MultiPhraseQuery, CombinedFieldQuery and SpanOr on ordinary sharded data while the matches stay the same, so it opens the core scoring-error rows right after the rescorer wrong-score row.
- Impact class
- silent wrong results
- Impact note
- Hits applications that score a sharded collection by overriding the @lucene.experimental IndexSearcher#termStats/#fieldStats hooks (termStatistics/collectionStatistics in releases) to inject collection-wide statistics, the use their javadoc names (in-tree only the ShardSearchingTestBase test mock; distributed-statistics modes of downstream search servers are plausible users by code reading only, not executed); whenever a SynonymQuery, MultiPhraseQuery, CombinedFieldQuery or SpanOrQuery (alone or inside another span query) has a term that is missing from the shard being searched but present on another, that term's statistics are silently left out, so documents get scores that differ from whole-collection scoring and the merged cross-shard ranking is wrong (SynonymQuery and CombinedFieldQuery over-score, under BM25 only when the absent term is the more frequent one collection-wide; MultiPhraseQuery and SpanOr under-score whenever a term is absent); the set of matching documents is unchanged, no scale is needed, default BM25, -ea and -da, every release from 8.3.0 to 10.6.0 (10.6.0 by reading) and main.
- Summary
- You search one shard of a collection with an IndexSearcher whose termStats and fieldStats overrides return the statistics of the whole collection, as their javadoc suggests, and run SynonymQuery(quick, fast) where 'fast' occurs only on another shard. You expect each document to get the score it gets when you search the whole collection, as TermQuery and PhraseQuery do. Instead the query asks the override only about 'quick', because it calls termStats only for terms whose local docFreq is above 0, so it scores the document 0.573 instead of 0.170 and ranks it above an equally relevant document on the other shard; MultiPhraseQuery, CombinedFieldQuery and SpanOrQuery are off the same way.
- Introduced
- a80534a589d20b9aacdcc8677b5b30747f3b893a (branch_8x backport, shipped in 8.3.0) and the master original fd0c8b9e810737a119868b8d18d4ed55d5e9c607 (first released in 9.0.0; git blame on main credits it with all four docFreq > 0 checks): LUCENE-8921 'IndexSearcher.termStatistics API change' (issue apache/lucene#9964, PR apache/lucene-solr#797, committed directly with 'Closes #797'; author bruno-roustant, committer dsmiley, 2019-09-17), which replaced the callers' 'termStats != null' checks (the LUCENE-8020 contract of 8.0-8.2, where the overridable hook itself decided that a term is absent by returning null) with 'if (ts.docFreq() > 0)' on the local TermStates before calling the hook [read: blame and git log -S 'docFreq() > 0' in the full-history clone; exec at release granularity: 8.2.0 equal, 8.3.0 different]. The hook itself dates from LUCENE-3555 'add support for distributed stats' (b19a207c866, 2011-11-04, 4.0.0). (2019-09-17)
- First affected version
- 8.3.0 [exec] (tagged 2019-10-31); last unaffected 8.2.0 [exec]. For the core CombinedFieldQuery class, 10.2.0, its first core release [exec]; the same check was in the sandbox BM25FQuery/CombinedFieldQuery from 8.3.0, whose score cannot be compared before 9.3.0 because overridden statistics made it throw (LUCENE-10582, a different, fixed bug), but its hook call log already loses title:fox on 8.3.0 [exec]
- Affected versions
- every release from 8.3.0 through 10.6.0 (10.6.0 by reading) and main a9779ef3c193 (and the previous hunt main ea57360912ed: the gated files are byte-identical, checked by the cross-model review); the branch_10_6 head (2026-10-24, the line released as 10.6.0) and the unreleased branch_10x head (2026-10-24) have the same checks [read]. [exec, the follow-up's version-matched main() check, one override per API era, -ea, JDK 25] pass (shard score == whole-collection score, hook asked about the locally absent term) on 7.7.3, 8.0.0 and 8.2.0; fail (hook never asked) on 8.3.0, 8.11.4 and 9.0.0 (4 of 4 comparable families), 9.12.3, 10.2.0, 10.5.2 and main (5 of 5, with CombinedFieldQuery). [exec, JUnits] the finder's JUnit fails 5 of 7 on main with -ea and -da (its 2 controls pass); the independent reproduction's JUnit fails 5 of 8 on main (-ea, -da), 10.5.2 and 9.12.3 (its 3 controls pass); the finder's release main() fails on 8.3.0, 8.11.4, 9.12.3 and 10.5.2 and passes on 8.0.0 and 8.2.0 with the pre-8.3 hook; separate runs: main -ea/-da and 10.5.2 fail, 8.2.0 passes. Not run: 8.1.x, releases before 7.7.3, and the 8.3.0-10.5.2 releases between the executed ones (inferred by commit containment). The hook did not exist before 4.0.0. The candidate's JUnit uses the main-only names termStats/fieldStats (#15929), so release runs use main() checks with each version's own hook signature. Executed only on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new; 269 queries and reads): three scripted prior-report searches (code identifiers, symptoms/dfs, history keys; 157 queries over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web), the finder's (51) and the intended-behaviour check's (19) runs, 40 GitHub searches on Elasticsearch, OpenSearch, Solr and Lucene, 26 JIRA searches, 18 Solr list searches, 15 web queries, and the touched files of all 406 open apache/lucene PRs (11 touch the gated files, IndexSearcher, TermStates or ShardSearchingTestBase; none changes the check). Related, not reports: #9964 / lucene-solr#797 / fd0c8b9e810 LUCENE-8921 (the change that introduced the check; its review treated it as behaviour-preserving and never discussed overrides); #9068 LUCENE-8020 (the earlier null-for-absent contract); #9986 LUCENE-8943 (open; how MultiPhraseQuery and SpanOrQuery combine idf, a different defect in the same queries); #13796 and open PR #15819 (SpanOrQuery adds the idf of non-matching clauses; a different root cause; if merged it would hide only the standalone SpanOrQuery manifestation, and SpanWeight keeps the check); #11618 / PR #910 LUCENE-10582 (fixed 9.3; a different overridden-statistics bug in CombinedFieldQuery); elastic/elasticsearch#50577 (similar cross-shard symptom, different mechanism: per-shard prefix expansion plus summed idf); elastic/elasticsearch#42957 and #10346 (BlendedTermQuery ignores distributed statistics; they point to SynonymQuery and CombinedFieldQuery, the queries affected here); SOLR-7756, SOLR-7818 and SOLR-9122 (terms missing on a shard in Solr's stats-cache layer, before 8.3); OpenSearch #23364 and #23413 (the reverse case); #16847 (open draft, termStats signature int to long). Not fixed on main or branch_10x (no commit after a9779ef3c193 touches the gated files) [read]
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-26 and 2026-10-27), seed DEADBEEF unless noted: this doc's two tests through gradle with-Ptests.asserts=trueand=false, on stock main and with fix option A; the finder's JUnit, the independent reproducer's JUnit (seeds 5EED1176, 0DD5EED5) and the audit's re-run (seed A0D17004) through a standalone JUnit harness with-eaand-da; release checks on 7.7.3, 8.0.0, 8.2.0, 8.3.0, 8.11.4, 9.0.0, 9.12.3, 10.2.0 and 10.5.2; after the fact checks (2026-10-27), fix option A with its tightened javadoc re-checked through gradle (the new tests with assertions on and off, four key core test classes, static checks). OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:1119-1133 (at a9779ef3c193) (termStats javadoc: 'This can be overridden for example, to return a term's statistics across a distributed collection' at :1122-1123; '@param docFreq ... It must be greater or equal to 1'; '@return ... (never null)'; @lucene.experimental), :1135-1144 (fieldStats: the same distributed-collection sentence at :1139-1140)lucene/core/src/java/org/apache/lucene/search/SynonymQuery.java:217-221 (at a9779ef3c193) ('if (ts.docFreq() > 0)' before searcher.termStats; df = max, ttf = sum over the terms that pass), :47 (class javadoc: scores the terms 'as if you had indexed them as one term')lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:227-229 (at a9779ef3c193) ('scoreMode.needsScores() && ts.docFreq() > 0' before searcher.termStats; the list feeds similarity.scorer at :235-236)lucene/core/src/java/org/apache/lucene/search/CombinedFieldQuery.java:281-285 (at a9779ef3c193) (same check; df = max, ttf = weighted sum), :47-49 (class javadoc: scores terms 'as if they had been indexed in a single field whose values would be the union'), :77 (@lucene.experimental)lucene/queries/src/java/org/apache/lucene/queries/spans/SpanWeight.java:101-120 (at a9779ef3c193) (buildSimWeight: same check at :109; affects SpanOrQuery and every span query containing one)lucene/test-framework/src/java/org/apache/lucene/tests/search/ShardSearchingTestBase.java:211-212 (at a9779ef3c193) ('Matches docs in the local shard but scores based on aggregated stats ("mock distributed scoring")'), :264-290 (termStats sums local and remote statistics; 'assert distributedDocFreq > 0' at :289)lucene/core/src/test/org/apache/lucene/search/TestShardSearching.java:35-41 (at a9779ef3c193) (TODO: 'other queries besides PrefixQuery & TermQuery')lucene/CHANGES.txt:6164-6166 (at a9779ef3c193) (8.3.0 API Changes, LUCENE-8921: 'And don't call if docFreq <= 0'), :6710-6713 (8.0.0, LUCENE-8020: termStatistics returns null for a non-existent term), :4119 (9.3.0 Bug Fixes, LUCENE-10582: overridden statistics in CombinedFieldQuery)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:1119-1144 (termStats/fieldStats javadoc and default)lucene/core/src/java/org/apache/lucene/search/SynonymQuery.java:209-229, MultiPhraseQuery.java:219-236, CombinedFieldQuery.java:274-292, TermQuery.java:65, PhraseQuery.java:479lucene/queries/src/java/org/apache/lucene/queries/spans/SpanWeight.java:101-120lucene/test-framework/src/java/org/apache/lucene/tests/search/ShardSearchingTestBase.java:211-212, 264-292lucene/queries/src/java/org/apache/lucene/queries/spans/SpanNotQuery.java:110-120 (the exclude clause is built with COMPLETE_NO_SCORES and left out of the scoring term states)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:871, 976 (rewrite, createWeight); TermQuery.java:281; lucene/queries/src/java/org/apache/lucene/queries/spans/SpanTermQuery.java:56; lucene/core/src/java/org/apache/lucene/index/TermStates.java:158 (expert workarounds)
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:1122-1123, 1128, 1139-1140, 1142 (distributed use; @lucene.experimental)lucene/test-framework/src/java/org/apache/lucene/tests/search/ShardSearchingTestBase.java:211-212lucene/core/src/test/org/apache/lucene/search/TestCombinedFieldQuery.java:535; lucene/sandbox/src/test/org/apache/lucene/sandbox/search/TestCombinedFieldQuery.java:641 (fieldStats-only overrides)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:1119-1133, 1135-1144lucene/core/src/java/org/apache/lucene/search/SynonymQuery.java:45-50; CombinedFieldQuery.java:46-50lucene/core/src/test/org/apache/lucene/search/TestShardSearching.java:35-41lucene/core/src/test/org/apache/lucene/search/TestCombinedFieldQuery.java:488-563 (testOverrideFieldStats)lucene/test-framework/src/java/org/apache/lucene/tests/search/ShardSearchingTestBase.java:264-292lucene/CHANGES.txt:4119 (LUCENE-10582), 6164-6166 (LUCENE-8921), 6710-6713 (LUCENE-8020)lucene/core/src/java/org/apache/lucene/search/PrefixQuery.java:27-34 (constant-score rewrite by default)
- Suggested fix
lucene/sandbox/src/java/org/apache/lucene/sandbox/search/TermAutomatonQuery.java:383, PhraseWildcardQuery.java:407, CombinedFieldQuery.java:316lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:479-486; lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:198-203 (callers that do not check for null)
- History
a Lucene clone: releases/lucene-solr/8.3.0 contains a80534a589d, 8.2.0 does nota Lucene clone: origin/main a95c754ee003 (2 commits past a9779ef3c193, none touching the four files), origin/branch_10x 1309534296e3 (all four docFreq() > 0 checks present)dev-tools/doap/lucene.rdf:457-459 (8.3.0 released 2019-11-02)
- TestSynonymQueryDistributedStats.java (JUnit test):
repro/LFV-582/src/org/apache/lucene/search/TestSynonymQueryDistributedStats.java(81 lines)
A picture of the two shards, the skipped hook call and the scores of an executed run on main; made in parallel with this doc from the diagram probe's trace.
assets/LFV-582/bug.png(598 KB)